Conjunto de datos DOTA con OBB
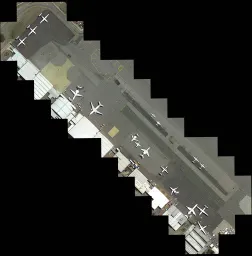
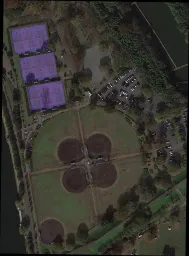
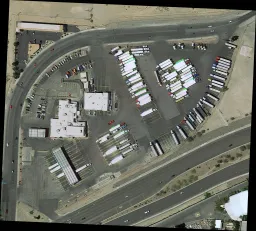
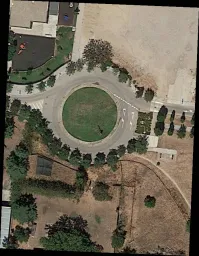
El conjunto de datos DOTA es un benchmark a gran escala para la detección de objetos en imágenes aéreas. Se publicó en tres versiones (v1.0, v1.5 y v2.0) e incluye hasta 1,7 millones de anotaciones de cajas delimitadoras orientadas (OBB) en 18 categorías, capturadas con diversos sensores y plataformas aéreas.
Explora los conjuntos de datos oficiales DOTA v1.5 y DOTA v1.0, alojados en Ultralytics Platform, para previsualizar sus anotaciones orientadas, consultar estadísticas y clonarlos para entrenar.
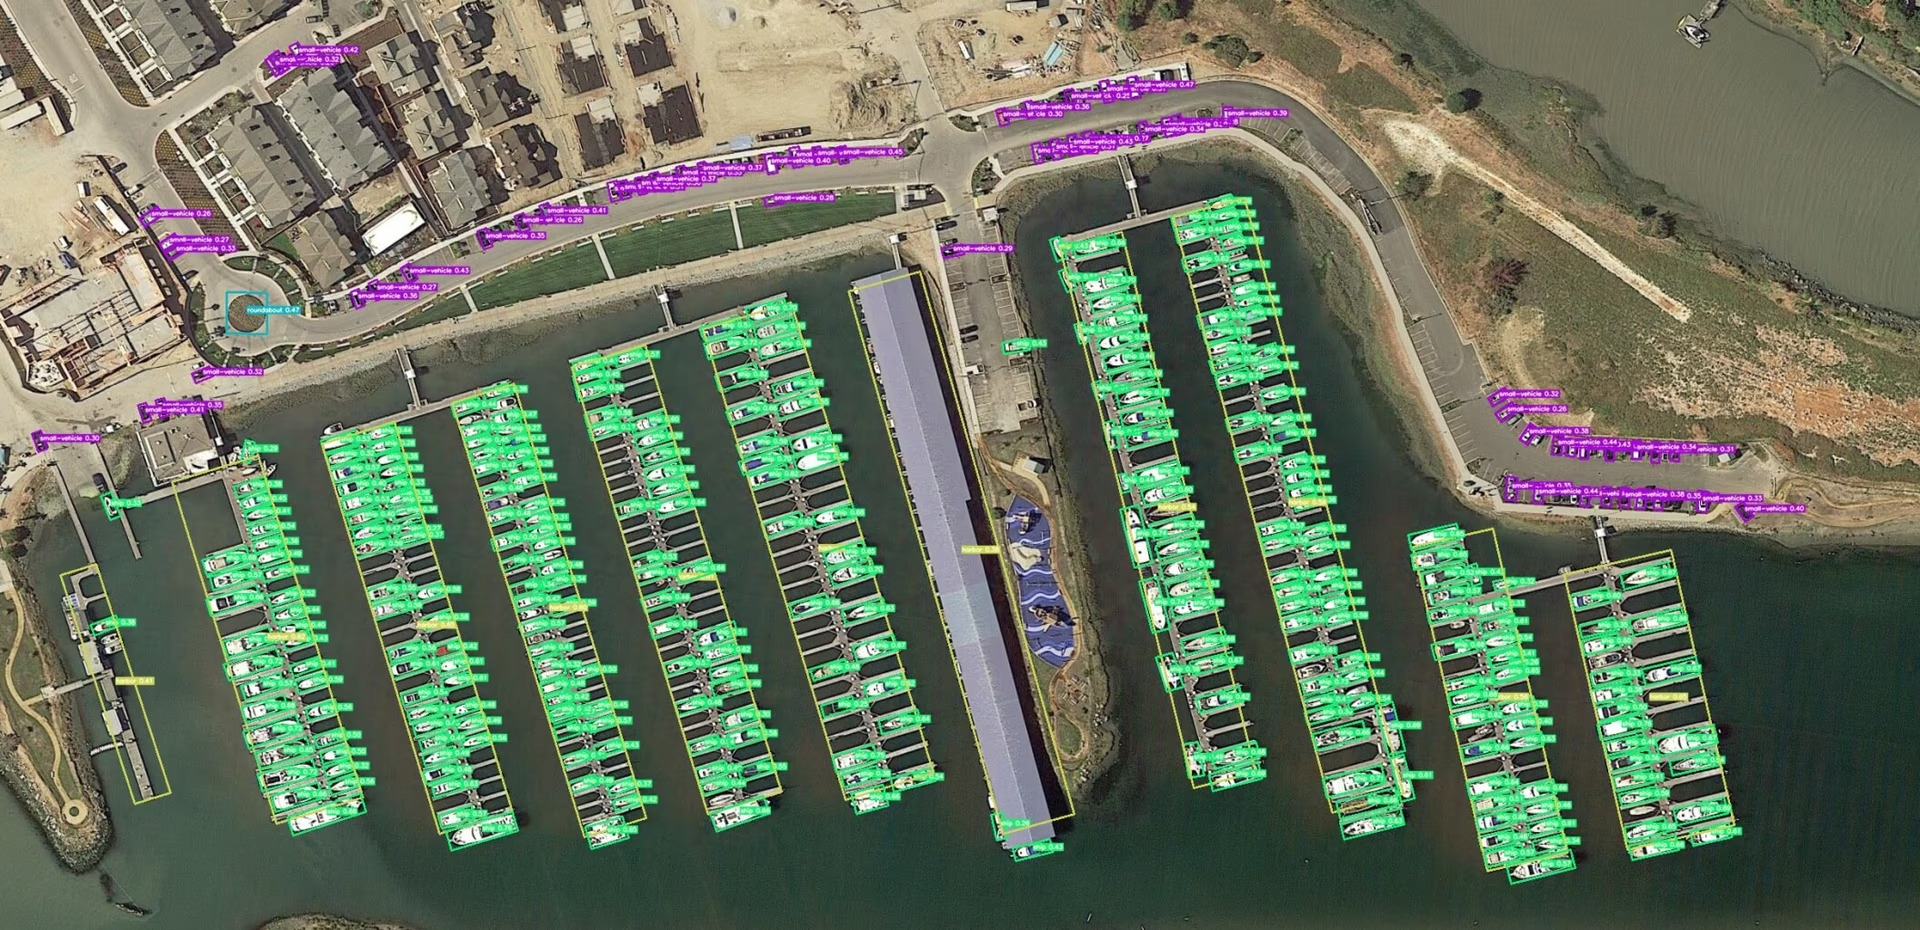
Características principales#
Ver: Cómo entrenar Ultralytics YOLO con el conjunto de datos DOTA para detectar cajas delimitadoras orientadas en Google Colab
- Recopilación realizada con distintos sensores y plataformas, con tamaños de imagen de entre 800 × 800 y 20 000 × 20 000 píxeles.
- Incluye más de 1,7 millones de cajas delimitadoras orientadas en 18 categorías.
- Permite la detección de objetos a varias escalas gracias a la amplia variedad de tamaños de objetos en cada imagen.
- Expertos anotan las instancias mediante cuadriláteros arbitrarios (8 grados de libertad), que representan objetos de distintas escalas, orientaciones y formas.
Versiones del conjunto de datos#
DOTA-v1.0#
- Contiene 15 categorías habituales.
- Consta de 2806 imágenes con 188 282 instancias.
- Proporciones de la división: 1/2 para entrenamiento (1411 imágenes), 1/6 para validación (458 imágenes) y 1/3 para pruebas (937 imágenes).
DOTA-v1.5#
- Incluye las mismas imágenes que DOTA-v1.0.
- También se anotan las instancias muy pequeñas (de menos de 10 píxeles).
- Se añade una categoría nueva: «grúa de contenedores».
- Un total de 403 318 instancias.
- Publicado para el Desafío DOAI 2019 sobre detección de objetos en imágenes aéreas.
DOTA-v2.0#
- Recopilaciones de Google Earth, el satélite GF-2 y otras imágenes aéreas.
- Contiene 18 categorías habituales.
- Incluye 11.268 imágenes con 1.793.658 instancias.
- Se introducen dos categorías nuevas: «aeropuerto» y «helipuerto».
- Divisiones de las imágenes:
- Entrenamiento: 1.830 imágenes con 268.627 instancias.
- Validación: 593 imágenes con 81.048 instancias.
- Prueba-dev: 2.792 imágenes con 353.346 instancias.
- Prueba-desafío: 6.053 imágenes con 1.090.637 instancias.
Estructura del conjunto de datos#
DOTA presenta una estructura diseñada para los desafíos de detección de objetos con OBB:
- Imágenes: Una amplia colección de imágenes aéreas de alta resolución que capturan terrenos y estructuras variados.
- Cajas delimitadoras orientadas: Anotaciones en forma de rectángulos girados que delimitan objetos independientemente de su orientación, ideales para capturar objetos como aviones, barcos y edificios.
Aplicaciones#
DOTA sirve como benchmark para entrenar y evaluar modelos diseñados para el análisis de imágenes aéreas. Sus anotaciones de cuadros delimitadores orientados lo convierten en una prueba exigente para los modelos de detección de objetos aplicados a objetivos aéreos girados y muy próximos entre sí. El conjunto de datos se utiliza ampliamente en teledetección, vigilancia y supervisión medioambiental.
YAML del conjunto de datos#
Un archivo YAML del conjunto de datos especifica las rutas de las imágenes y las etiquetas, los nombres de las clases y otros metadatos importantes. Ultralytics mantiene archivos YAML oficiales para las dos versiones más utilizadas:
Usa el YAML que corresponda a la versión que has descargado, o crea un YAML personalizado si trabajas con DOTA-v2 u otra variante. Ambas versiones se descargan automáticamente (2 GB) desde los recursos de Ultralytics GitHub la primera vez que entrenas.
# Ultralytics 🚀 AGPL-3.0 License - https://ultralytics.com/license

# DOTA 1.0 dataset https://captain-whu.github.io/DOTA/index.html for object detection in aerial images by Wuhan University
# Documentation: https://docs.ultralytics.com/datasets/obb/dota-v2
# Example usage: yolo train model=yolov8n-obb.pt data=DOTAv1.yaml
# parent
# ├── ultralytics
# └── datasets
#     └── DOTAv1 ← downloads here (2 GB)

# Train/val/test sets as 1) dir: path/to/imgs, 2) file: path/to/imgs.txt, or 3) list: [path/to/imgs1, path/to/imgs2, ..]
path: DOTAv1 # dataset root dir
train: images/train # train images (relative to 'path') 1411 images
val: images/val # val images (relative to 'path') 458 images
test: images/test # test images (optional) 937 images

# Classes for DOTA 1.0
names:
  0: plane
  1: ship
  2: storage tank
  3: baseball diamond
  4: tennis court
  5: basketball court
  6: ground track field
  7: harbor
  8: bridge
  9: large vehicle
  10: small vehicle
  11: helicopter
  12: roundabout
  13: soccer ball field
  14: swimming pool

# Download script/URL (optional)
download: https://github.com/ultralytics/assets/releases/download/v0.0.0/DOTAv1.zip
Dividir las imágenes de DOTA#
Las imágenes originales suelen superar los 10.000 píxeles por lado, por lo que se recomienda dividirlas en fragmentos antes de introducir los datos en YOLO. Usa la función auxiliar siguiente para dividir las imágenes originales en recortes solapados de 1024 × 1024 a varias escalas, manteniendo las anotaciones sincronizadas.
from ultralytics.data.split_dota import split_test, split_trainval

# Divide los conjuntos de entrenamiento y validación, con etiquetas.
split_trainval(
    data_root="path/to/DOTAv1.0/",
    save_dir="path/to/DOTAv1.0-split/",
    rates=[0.5, 1.0, 1.5],  # multiscale
    gap=500,
)
# Divide el conjunto de prueba, sin etiquetas.
split_test(
    data_root="path/to/DOTAv1.0/",
    save_dir="path/to/DOTAv1.0-split/",
    rates=[0.5, 1.0, 1.5],  # multiscale
    gap=500,
)Mantén el directorio de salida organizado con la estructura estándar de YOLO (images/train, labels/train, etc.) para poder hacer referencia a él directamente desde el YAML del conjunto de datos.
Uso#
Para entrenar un modelo YOLO26n-obb con el conjunto de datos DOTA v1, utiliza los siguientes fragmentos de código. Consulta siempre la documentación de tu modelo para ver una lista completa de los argumentos disponibles. Si quieres experimentar primero con un subconjunto más pequeño, considera usar el conjunto de datos DOTA8, que solo contiene 8 imágenes para realizar pruebas rápidas y se puede explorar en la plataforma Ultralytics.
Todas las imágenes y anotaciones asociadas del conjunto de datos DOTAv1 solo pueden utilizarse con fines académicos; el uso comercial está prohibido. Ultralytics interpreta que estas restricciones se aplican al conjunto de datos de origen, no a los pesos de modelos preentrenados o ajustados. Revisa las condiciones de DOTA para el uso que tengas previsto.
from ultralytics import YOLO

# Cargar un modelo YOLO26n-OBB preentrenado
model = YOLO("yolo26n-obb.pt")

# Entrenar el modelo con el conjunto de datos DOTAv1
results = model.train(data="DOTAv1.yaml", epochs=100, imgsz=1024)
Datos de ejemplo y anotaciones#
El ejemplo siguiente muestra escenas y anotaciones típicas de DOTA:
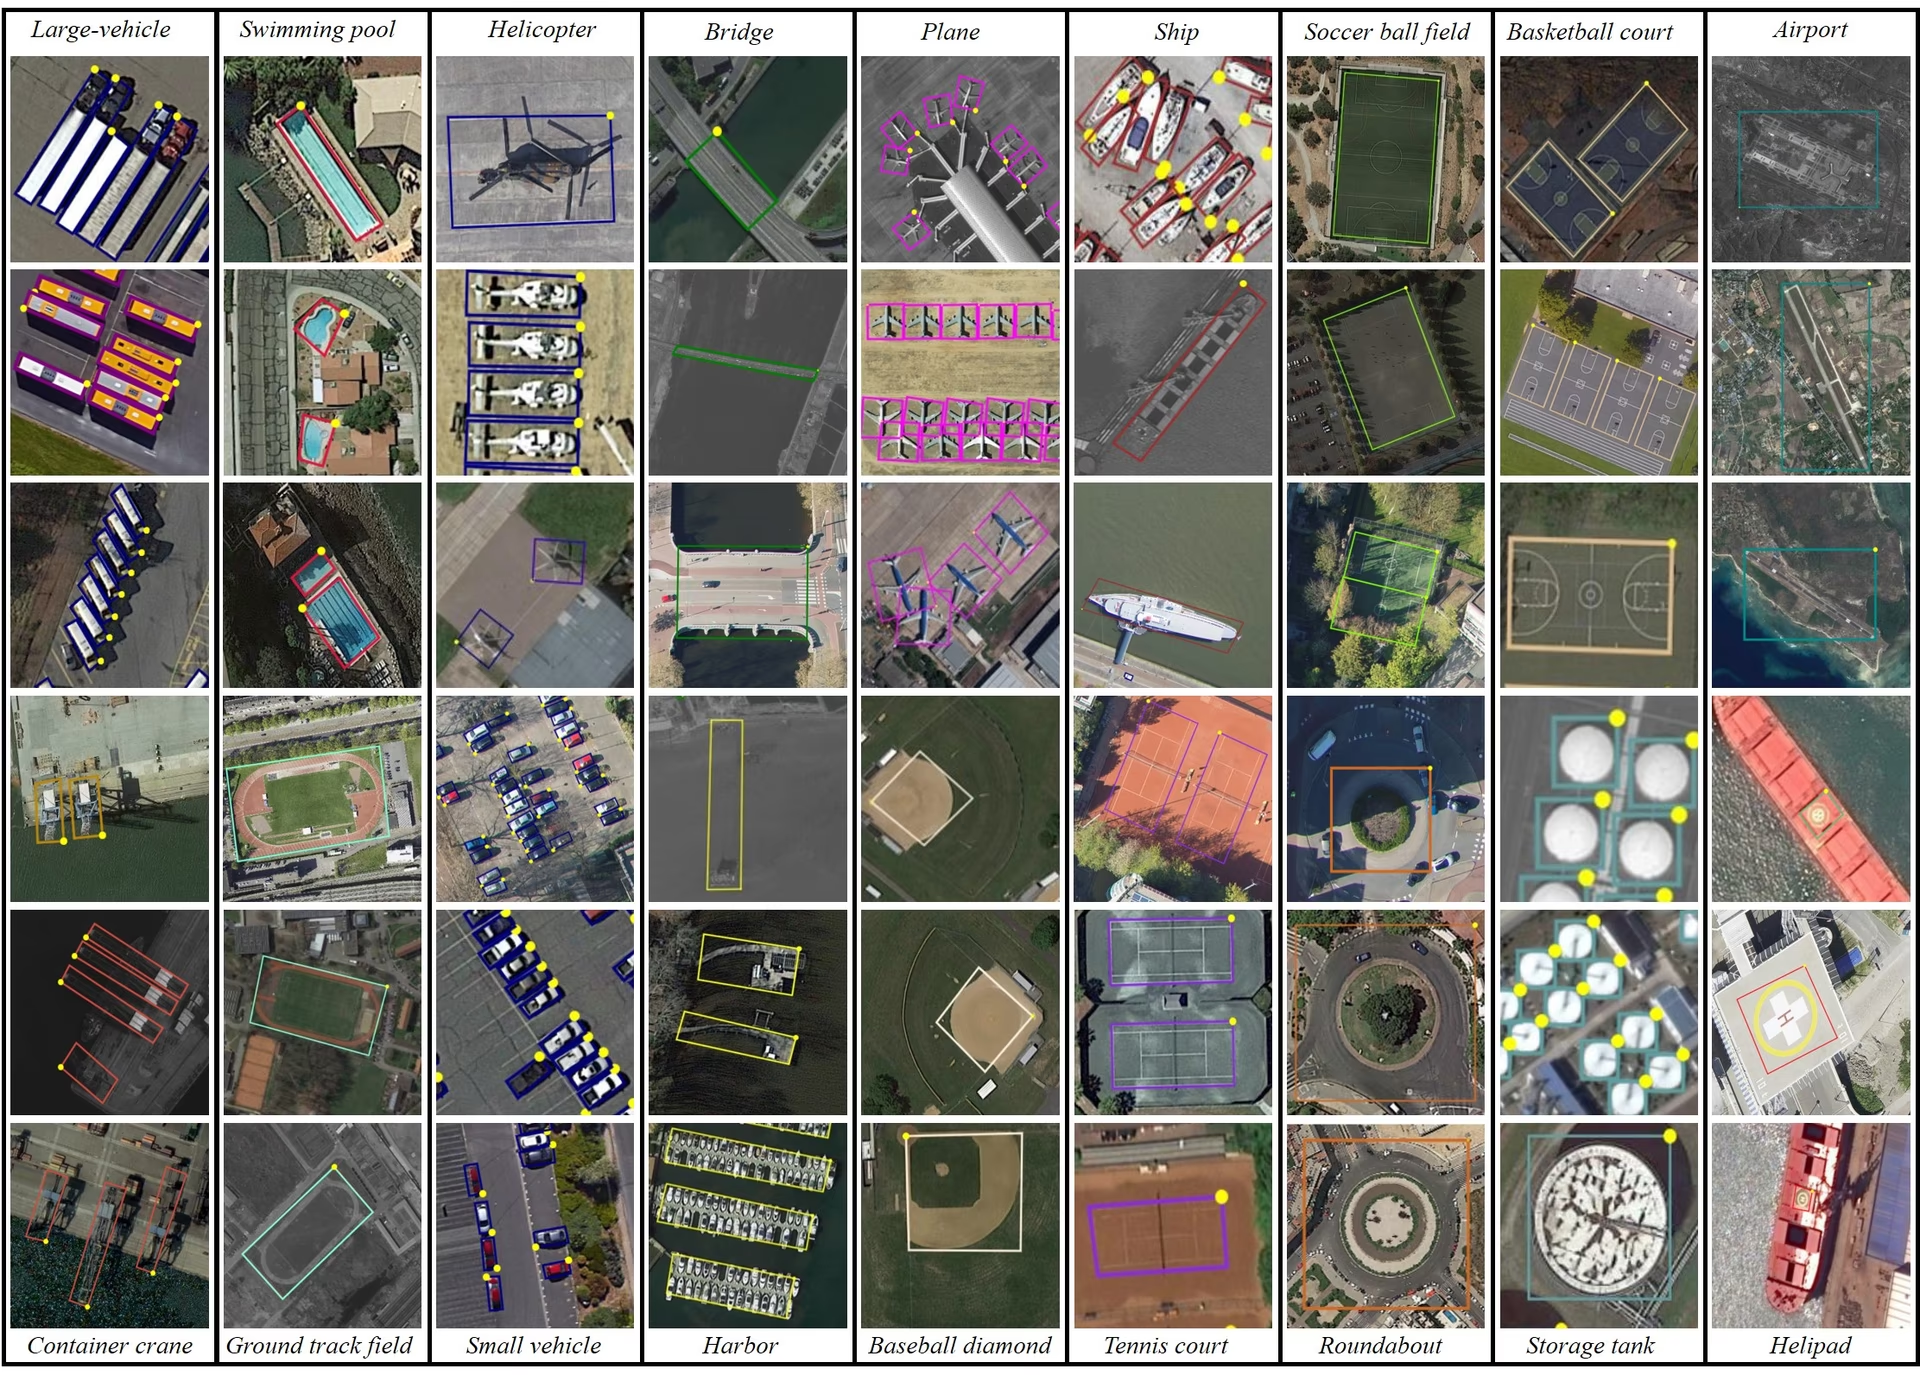
- Ejemplos de DOTA: Esta instantánea pone de relieve la complejidad de las escenas aéreas y la importancia de las anotaciones de cajas delimitadoras orientadas, que capturan los objetos en su orientación natural.
Estas escenas ponen de relieve los retos de detección específicos de las imágenes aéreas. DOTA-v2.0 se utiliza ampliamente en proyectos de teledetección y vigilancia aérea gracias a sus anotaciones exhaustivas y a la diversidad de categorías de objetos.
Citas y agradecimientos#
Si utilizas DOTA en tu trabajo, cita los artículos de investigación pertinentes:
@article{9560031,
  author={Ding, Jian and Xue, Nan and Xia, Gui-Song and Bai, Xiang and Yang, Wen and Yang, Michael and Belongie, Serge and Luo, Jiebo and Datcu, Mihai and Pelillo, Marcello and Zhang, Liangpei},
  journal={IEEE Transactions on Pattern Analysis and Machine Intelligence},
  title={Object Detection in Aerial Images: A Large-Scale Benchmark and Challenges},
  year={2022},
  volume={44},
  number={11},
  pages={7778-7796},
  doi={10.1109/TPAMI.2021.3117983}
}
Damos las gracias al equipo responsable de los conjuntos de datos DOTA por recopilarlos. Para consultar todos los detalles del conjunto de datos, visita el sitio web oficial de DOTA.
Preguntas frecuentes#
El conjunto de datos DOTA está especializado en la detección de objetos en imágenes aéreas. Incluye cajas delimitadoras orientadas (OBB) y ofrece imágenes anotadas de diversas escenas aéreas. La diversidad de orientaciones, escalas y formas de los objetos de DOTA, con sus 1,7 M de anotaciones y 18 categorías, lo convierte en una opción ideal para desarrollar y evaluar modelos adaptados al análisis de imágenes aéreas, como los utilizados en vigilancia, monitorización medioambiental y gestión de catástrofes.
DOTA utiliza cuadros delimitadores orientados (OBB) para las anotaciones, representados mediante rectángulos girados que abarcan los objetos independientemente de su orientación. Este método garantiza una captura precisa de los objetos, tanto si son pequeños como si aparecen en distintos ángulos. Las imágenes multiescala del conjunto de datos, que van de 800 × 800 a 20.000 × 20.000 píxeles, también permiten detectar eficazmente objetos pequeños y grandes. Este enfoque resulta especialmente útil para las imágenes aéreas, donde los objetos aparecen en distintos ángulos y escalas.
Para entrenar un modelo con el conjunto de datos DOTA, puedes usar el siguiente ejemplo con Ultralytics YOLO:
Ejemplo de entrenamientofrom ultralytics import YOLO # Cargar un modelo YOLO26n-OBB preentrenado model = YOLO("yolo26n-obb.pt") # Entrenar el modelo con el conjunto de datos DOTAv1 results = model.train(data="DOTAv1.yaml", epochs=100, imgsz=1024)Para obtener más información sobre cómo dividir y preprocesar las imágenes de DOTA, consulta la sección sobre cómo dividir las imágenes de DOTA.
- DOTA-v1.0: Incluye 15 categorías habituales distribuidas en 2.806 imágenes con 188.282 instancias. El conjunto de datos se divide en conjuntos de entrenamiento, validación y prueba.
- DOTA-v1.5: Amplía DOTA-v1.0 al anotar instancias muy pequeñas (de menos de 10 píxeles) y añadir una nueva categoría, «grúa portacontenedores», hasta alcanzar un total de 403.318 instancias.
- DOTA-v2.0: Se amplía aún más con anotaciones de Google Earth y del satélite GF-2, e incluye 11.268 imágenes y 1.793.658 instancias. Añade categorías como «aeropuerto» y «helipuerto».
Para una comparación detallada y más información, consulta la sección sobre las versiones del conjunto de datos.
Las imágenes de DOTA, que pueden ser muy grandes, se dividen en otras de menor resolución para facilitar el entrenamiento. Aquí tienes un fragmento de Python para dividir las imágenes:
Ejemplofrom ultralytics.data.split_dota import split_test, split_trainval # Divide los conjuntos de entrenamiento y validación, con etiquetas. split_trainval( data_root="path/to/DOTAv1.0/", save_dir="path/to/DOTAv1.0-split/", rates=[0.5, 1.0, 1.5], # multiscale gap=500, ) # Divide el conjunto de prueba, sin etiquetas. split_test( data_root="path/to/DOTAv1.0/", save_dir="path/to/DOTAv1.0-split/", rates=[0.5, 1.0, 1.5], # multiscale gap=500, )Este proceso mejora la eficiencia del entrenamiento y el rendimiento del modelo. Para obtener instrucciones detalladas, visita la sección sobre cómo dividir las imágenes de DOTA.


Comentarios17
Haz una pregunta, comparte tus resultados o ayuda a otra persona.
XWP-PPP
May I ask how you converted the inference results from YOLOV8 OBB into inference results that can be uploaded to DOTA's Task 1 server? I saved the final inference results of the model in the form of xyxyxy and uploaded them via email. However, the mAP results provided on YOLO's official website differ significantly. I would like to know the reason for this. Can you provide me with a conversion code to convert the test image set into a result that can be uploaded to DOTA's Task 1 server? Thank you very much for your help!
1 Paula DerrengerUltralytics(editado)
@XWP-PPP hi there!
DOTA's Task 1 server expects a zip of one text file per class (
Task1_plane.txt,Task1_storage-tank.txt, ...), where each line isimgname score x1 y1 x2 y2 x3 y3 x4 y4, with the image name given without extension. OBB results are stored inresult.obb, notresult.boxes. Here is a snippet that builds those files:import shutil from collections import defaultdict from pathlib import Path from ultralytics import YOLO # Load your trained YOLO26-OBB model model = YOLO("path/to/your/yolo26n-obb.pt") # Collect one DOTA Task1 line per detection: imgname score x1 y1 x2 y2 x3 y3 x4 y4 (pixels) category_results = defaultdict(list) for r in model.predict(source="path/to/test/images", stream=True): img_name = Path(r.path).stem for cls, conf, pts in zip(r.obb.cls.int().tolist(), r.obb.conf.tolist(), r.obb.xyxyxyxy.flatten(1).tolist()): coords = " ".join(f"{p:.1f}" for p in pts) category_results[f"Task1_{model.names[cls].replace(' ', '-')}.txt"].append(f"{img_name} {conf:.6f} {coords}\n") # Save one file per category and zip the submission folder output_dir = Path("submission") output_dir.mkdir(exist_ok=True) for category_file, lines in category_results.items(): (output_dir / category_file).write_text("".join(lines)) shutil.make_archive("submission", "zip", output_dir)Upload
submission.zipto the DOTA Task 1 server. If your mAP differs from your local validation, check that image names match the test set and that the coordinates are in pixels of the original (unsplit) images. For more details, see the DOTA Dataset Documentation. Happy coding! 😊
Taufiq-Ahmed-pranto
Hi, I want to use the DOTA dataset only for YOLOv11 Nano. I don't want to use the model with oriented bounding boxes (OBB). What is the procedure?
 Jie Liu
I have download dotav1 form
https://github.com/ultralytics/assets/releases/download/v0.0.0/DOTAv1.zipand use script split dataset.from ultralytics.data.split_dota import split_test, split_trainval # split train and val set, with labels. split_trainval( data_root="/dataset/coco/DOTAv1", save_dir="/dataset/coco/DOTAv1.0-split/", rates=[0.5, 1.0, 1.5], # multiscale gap=500, ) # split test set, without labels. split_test( data_root="/dataset/coco/DOTAv1/", save_dir="/dataset/coco/DOTAv1.0-split/", rates=[0.5, 1.0, 1.5], # multiscale gap=500, )how to reproduce yolov11 obb result, please show me the command like
yolo train model=ultralytics-8.3.13/ultralytics/cfg/models/11/yolo11n-obb.yaml data=DOTAv1/DOTAv1.yaml epochs=500 batch=32*4 imgsz=640 device=4,5,6,7 cache=disk amp=True Glenn JocherUltralytics(editado)
@keeper-jie for training YOLO26-OBB on DOTAv1 after splitting, use this command with your 4 GPUs:
yolo obb train data=DOTAv1.yaml model=yolo26n-obb.pt epochs=500 imgsz=1024 batch=128 device=4,5,6,7Key parameters from our DOTA documentation:
imgsz=1024(matches dataset's multiscale split)- Use official model name
yolo26n-obb.ptrather than YAML path - Batch size 128 (32*4 GPUs) via
batch=128
Ensure your dataset YAML paths point to the split images directory.
huynhkhoa44
I have labeled data in YOLOv8 object detection format, our label data format is already rotated rectangles to the correct angle of the object, however since it is in YOLOv8 object detection format, the "angle" parameter is missing. I no longer keep the label folder on CVAT so I cannot export to a different label format. Is there a way to add the angle value from the 4 pre-existing <x_center> <y_center> values?
- Glenn JocherUltralytics
To add the angle value from your existing YOLOv8 labels, you'll need to calculate it based on the coordinates. Unfortunately, without the original CVAT labels, this requires manual computation or using a tool that supports angle annotations. For guidance on datasets with oriented bounding boxes, you can refer to the DOTA dataset documentation at https://docs.ultralytics.com/datasets/obb/dota-v2/.
jack-ready
Recently, I've been using YOLOv8 to train the DOTAv1 dataset and encountered some issues. I was wondering if I could seek advice. 1.To train the DOTA dataset, we split the original DOTA images with high-resolution into images with 1024x1024. I noticed that the provided segmentation code provides three sizes, rates=[0.5, 1.0, 1.5]. In order to obtain 1024×1024 images, it seems that we should choose rates=1, but I noticed that some images in the segmentation results of the validation set are smaller than 1024×1024, such as 1024×1023, 824*1024, etc. What is the reason for this?Will it affect the experiment? 2.Another issue arises during the training process. I noticed that the training process conducts validation after each epoch. I attempted to disable validation by setting val=False, but it seems to have no effect. What could be the reason for this? The training code snippet is as follows: results = model.train(data="DOTAv1.yaml", epochs=100, imgsz=640, batch=10, workers=0, val=False). Additionally, during validation, it seems that the images are not being resized to 640. Printing the results in the code yields torch.Size([10, 3, 672, 672]), whereas during the training process, images are correctly resized to 640. Could someone help me understand this?
- Glenn JocherUltralytics(editado)
@jack-ready hi there!
Thank you for reaching out with your questions regarding training the DOTA dataset with YOLOv8. Let's address each of your concerns:
-
Image Splitting and Sizes: When splitting high-resolution DOTA images into 1024x1024 segments using
rates=[0.5, 1.0, 1.5], you might notice some resulting images are slightly smaller than 1024x1024 (e.g., 1024x1023 or 824x1024). This occurs due to the way the splitting algorithm handles the edges of the original images. If the original image dimensions are not perfectly divisible by 1024, the last segment in each row or column might be smaller. This should not significantly affect your experiment as long as the majority of your data maintains the expected size. However, you can ensure consistency by padding these smaller images to 1024x1024 if necessary. -
Disabling Validation: The
val=Falseargument should indeed disable validation during training. If it doesn't seem to work, please ensure you are using the latest version of the Ultralytics package. You can update it using:pip install --upgrade ultralyticsIf the issue persists, providing a minimum reproducible example would be very helpful for us to diagnose the problem. You can find guidance on creating one here: Minimum Reproducible Example.
-
Image Resizing During Validation: The discrepancy in image sizes during validation (e.g.,
torch.Size([10, 3, 672, 672])instead of 640) might be due to the model's internal resizing logic. Ensure that theimgszparameter is correctly set for both training and validation. Validation uses the sameimgszas training, so set it explicitly in your training script:results = model.train(data="DOTAv1.yaml", epochs=100, imgsz=640, batch=10, workers=0, val=True)
I hope this helps! If you have any further questions or need additional assistance, feel free to ask. Happy training! 🚀
-
Thank you very much for your help. I have another question regarding the YOLOV8 training on the DOTA v1.0 dataset. I would like to know how to set the training parameters, such as learning rate, optimizer, and loss function. When I try to reproduce the results, my mAP50 is about 74%, but it does not reach 78%. I would greatly appreciate any assistance you can provide.Below is my training code. from ultralytics import YOLO model = YOLO("yolov8n-obb.yaml") model.load("yolov8n-obb.pt") model = YOLO("yolov8n-obb.yaml").load("yolov8n.pt") results = model.train(data="DOTAv1.yaml", epochs=100, imgsz=640, batch=48, workers=0,project="runs/DOTAV1.0",val=True,resume=True)
- Glenn JocherUltralytics(editado)
Hi there! Glad to help with your training setup. To fine-tune your training parameters for better mAP50 results, you can adjust the learning rate, optimizer, and loss function. For instance, you might try a lower learning rate or switch to a different optimizer like Adam. Here's a quick example:
from ultralytics import YOLO

model = YOLO("yolo26n-obb.yaml").load("yolo26n-obb.pt")
results = model.train(
    data="DOTAv1.yaml",
    epochs=100,
    imgsz=640,
    batch=48,
    workers=0,
    project="runs/DOTAV1.0",
    val=True,
    lr0=0.001,  # Adjust learning rate
    optimizer='Adam'  # Change optimizer
)
Ensure you're using the latest version of the Ultralytics package to avoid any bugs. If you still face issues, feel free to share more details. Happy training! 🚀
Tintin26100
How can I find the number of instances per class in DOTA v1.5 ? I've been searching for this information for a moment and I can't find any answers
- Paula DerrengerUltralytics
@Tintin26100 hello!
The number of instances per class in DOTA v1.5 isn't directly listed in the dataset's summary. However, you can obtain this information by analyzing the annotation files provided with the dataset. Each object instance in these files is labeled with a class, and you can count the number of times each class appears.
If you need further guidance on how to process these annotation files or any other assistance with the DOTA dataset, feel free to ask!
Happy coding! 😊
Hi, thanks for your quick answer, I will gladly accept your help because I don't really know what to do to extract those informations, where do you find the annotation files ? Is it on the github ? If it is what's it's path ? Thanks for the time you spend helping
- Paula DerrengerUltralytics
@Tintin26100 hello!
The annotation files for the DOTA dataset are typically included within the dataset download itself. These files contain the details for each instance, including class labels and oriented bounding box coordinates.
For the DOTA v1.5 dataset, you can find these files in the dataset directory after you download it from the official DOTA dataset page or the provided download link in the dataset's YAML configuration file. The path to the annotations will usually be structured under the
labelsorannotationsdirectory within the main dataset folder.If you've already downloaded the dataset, you should look for
.txtor.jsonfiles corresponding to each image in the dataset, which contain the annotations. If you need further assistance navigating these files or extracting specific data, feel free to ask!Thank you for reaching out, and happy analyzing! 😊
hencai
how to test DOTA datatests online using YOLOv8-obb? somebody help me ?
- Glenn JocherUltralytics(editado)
Hey there! 😊 Testing the DOTA dataset online using YOLO26-obb is quite straightforward. If you've already prepared your dataset according to the Ultralytics guidelines and split the images, here's a simple example to get you started with training:
# Train a YOLO26n-OBB model on the DOTA v1 dataset
yolo obb train data=DOTAv1.yaml model=yolo26n-obb.pt epochs=100 imgsz=640
This command uses DOTA v1 and the corresponding
.yamlfile (DOTAv1.yaml) describing your dataset paths and classes. Adjustepochsandimgszbased on your needs.Just make sure to check out the DOTA dataset page on Ultralytics docs for more info on dataset preparation and additional configurations! Happy detecting! 🚀