Computer Vision Tasks Supported by Ultralytics YOLO26#
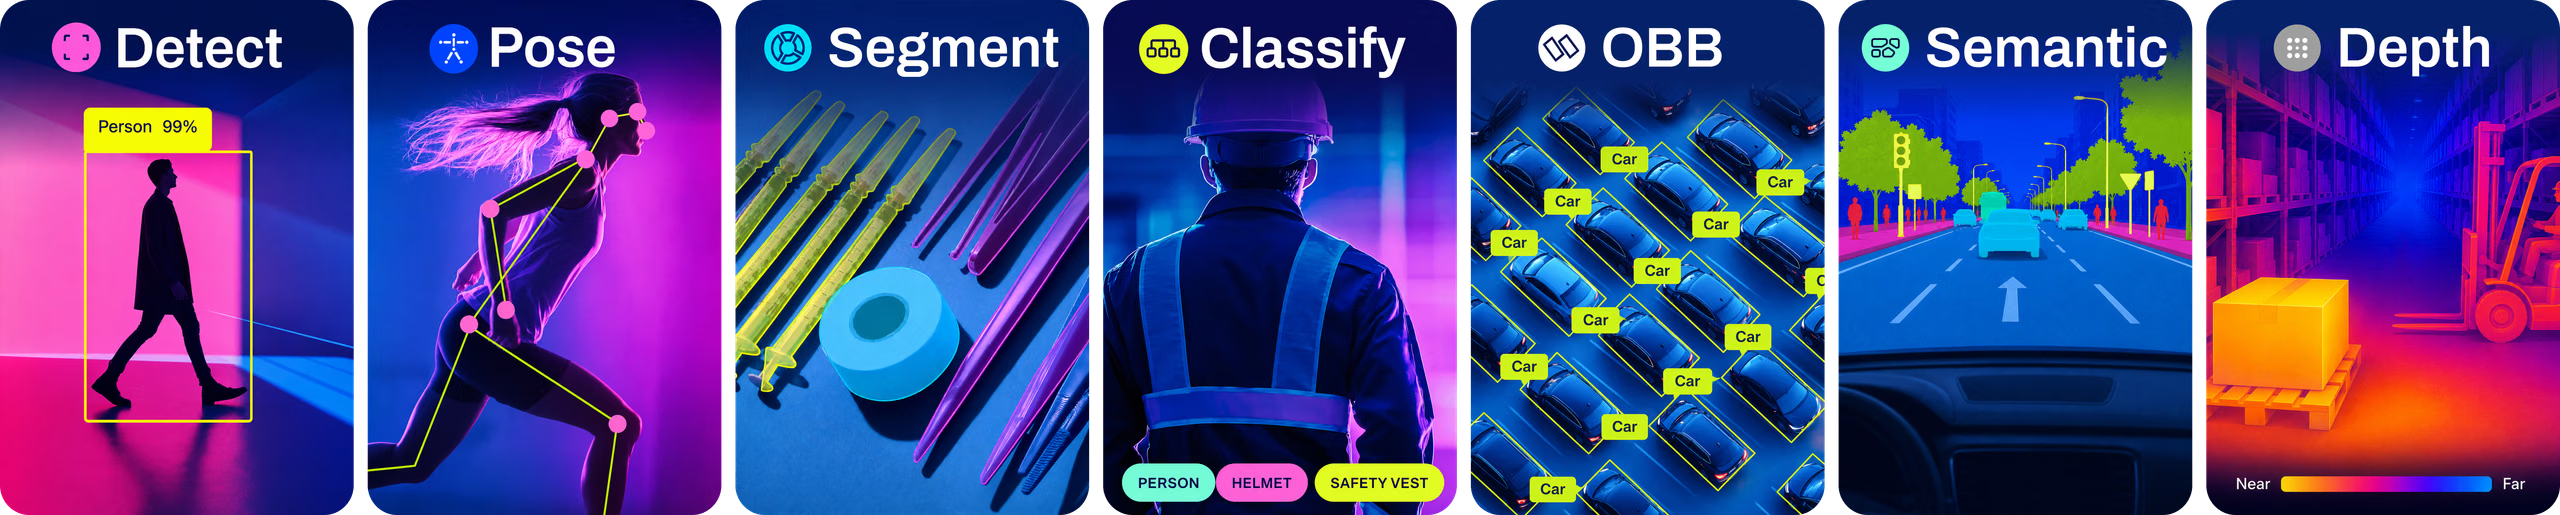
Ultralytics YOLO26 supports multiple computer vision tasks: detection, segmentation, semantic segmentation, depth estimation, classification, pose estimation, and OBB. Each task has a different objective and use case, so you can address a range of computer vision problems with a single framework.
For planned YOLO27 support, see the YOLO27 preview. YOLO27 is coming soon and is not yet available; this guide uses released YOLO26 models.
Watch: Explore Ultralytics YOLO26 Tasks: Object Detection, Instance Segmentation, Semantic Segmentation, Depth Estimation, Classification, Pose Estimation, and OBB.
Detection#
Object detection is the primary task supported by YOLO26. It involves identifying objects in an image or video frame and drawing bounding boxes around them. The detected objects are classified into different categories based on their features. YOLO26 detects multiple objects in a single image or video frame quickly enough for real-time applications like surveillance systems and autonomous vehicles.
Instance Segmentation#
Instance segmentation takes object detection further by producing pixel-level masks for each object. This precision is useful for applications such as medical imaging, agricultural analysis, and manufacturing quality control.
Semantic Segmentation#
Semantic segmentation assigns a class label to every pixel in an image, producing a dense class map of the entire scene. Unlike instance segmentation, it does not distinguish between individual objects of the same class. This makes it well-suited for autonomous driving, scene parsing, and land-cover mapping where understanding the full spatial layout matters more than identifying individual objects.
Semantic Segmentation Examples
Depth Estimation#
Monocular depth estimation predicts a per-pixel depth map in meters from a single RGB image. The output is a dense float map aligned to the input image, making it suitable for 3D scene reconstruction, robot navigation, and AR/VR applications where spatial layout must be inferred from a single camera.
Classification#
Image classification involves categorizing entire images based on their content. This task is useful for applications like product categorization in e-commerce, content moderation, and wildlife monitoring.
Pose Estimation#
Pose estimation detects specific keypoints in images or video frames to track movements or estimate poses. These keypoints can represent human joints, facial features, or other significant points of interest. YOLO26 pose models detect keypoints in real time, which makes them useful for fitness applications, sports analytics, and human-computer interaction.
OBB#
Oriented Bounding Box (OBB) detection enhances traditional object detection by adding an orientation angle to better locate rotated objects. This capability is particularly valuable for aerial imagery analysis, document processing, and industrial applications where objects appear at various angles. YOLO26 OBB models are pretrained on the DOTAv1 aerial imagery dataset.
What's Next#
Picked a task? Format your data for it with the Datasets guide, then train on your own images.
FAQ#
Ultralytics YOLO26 supports the following computer vision tasks:
- Object Detection: Identifying and localizing objects in images or video frames by drawing bounding boxes around them.
- Instance Segmentation: Producing a pixel-level mask for each detected object, useful for applications like medical imaging.
- Semantic Segmentation: Assigning a class label to every pixel in an image for dense scene understanding.
- Depth Estimation: Predicting a per-pixel depth map in meters from a single RGB image.
- Classification: Categorizing entire images based on their content.
- Pose Estimation: Detecting specific keypoints in an image or video frame to track movements or poses.
- Oriented Object Detection (OBB): Detecting rotated objects with an added orientation angle for enhanced accuracy.
To use Ultralytics YOLO26 for object detection, follow these steps:
- Prepare your dataset in the appropriate format.
- Train the YOLO26 model using the detection task.
- Use the model to make predictions by feeding in new images or video frames.
Examplefrom ultralytics import YOLO # Load a pretrained YOLO model (adjust model type as needed) model = YOLO("yolo26n.pt") # n, s, m, l, x versions available # Perform object detection on an image results = model.predict(source="image.jpg") # Can also use video, directory, URL, etc. # Display the results results[0].show() # Show the first image resultsFor more detailed instructions, check out our detection examples.
Using YOLO26 for segmentation tasks provides several advantages:
- High Accuracy: The segmentation task provides precise, pixel-level masks.
- Speed: YOLO26 is optimized for real-time applications, offering quick processing even for high-resolution images.
- Multiple Applications: It is ideal for medical imaging, autonomous driving, and other applications requiring detailed image segmentation.
Learn more about the benefits and use cases of YOLO26 for segmentation in the image segmentation section.
Yes. YOLO26 pose models detect keypoints, such as human joints, in images and video frames, and connect them into poses. This is useful for tracking movements in sports analytics, healthcare, and human-computer interaction applications.
For more details and implementation tips, visit our pose estimation examples.
Oriented Object Detection (OBB) with YOLO26 predicts an additional angle parameter for each box, so rotated objects are localized more tightly than with axis-aligned boxes. This is beneficial for applications requiring accurate localization of rotated objects, such as aerial imagery analysis and warehouse automation.
- Tighter Boxes: Rotated boxes include less background, which helps separate densely packed or angled objects.
- Versatile Applications: Useful for tasks in geospatial analysis, robotics, etc.
Check out the Oriented Object Detection section for more details and examples.
Comments15
Ask a question, share your results, or help someone else.
adhinajay
I quantized a YOLOv8 model. Now I want to fine tune it, so how can I convert the ONNX file back to a .pt file?
DukeZacharia
Yes, you can utilize Explainable AI (XAI) with YOLOv9 or YOLOv11,
even though these versions are unofficial or experimental extensions beyond YOLOv8.
YOLO is fundamentally a convolutional neural network (CNN),
which means that many XAI techniques applicable to CNNs or object detection models can be adapted for use with these versions.
On Thu, 12 Jun 2025 at 17:27, Md Saimul Haque Shanto < @.***> wrote:
Can I use XAI with YOLOv11 or YOLOv9 ? If so, how can I apply it to an object detection task?
— Reply to this email directly, view it on GitHub https://github.com/orgs/ultralytics/discussions/16241#discussioncomment-13443327, or unsubscribe https://github.com/notifications/unsubscribe-auth/AGZSZVZYSGD2CDV75M5O7KD3DE2XNAVCNFSM6AAAAABOCSRMJGVHI2DSMVQWIX3LMV43URDJONRXK43TNFXW4Q3PNVWWK3TUHMYTGNBUGMZTENY . You are receiving this because you were mentioned.Message ID: @.*** com>
Saimul-Shanto
Can I use XAI with YOLOv11 or YOLOv9 ? If so, how can I apply it to an object detection task?
AashishThakur1321
how can I provide different object ids in videos to same types of objects like there are 5 persons in a video frame, then how to provide different ids to these persons such that it tracks these objects with same id throughout the videos
 Glenn JocherUltralytics(edited)
@AashishThakur1321 to track multiple persons with unique IDs in videos using YOLO, utilize the built-in tracking mode with
tracker=botsort.yamlortracker=bytetrack.yamlconfiguration. Example CLI command:
yolo track model=yolo26n.pt source=video.mp4
This automatically assigns unique IDs to each person and maintains them across frames. For customization, see our tracking documentation.
Good, Afternoon, does Yolo work for Human Action Detection in realtime?
- Glenn JocherUltralytics
@DukeZacharia good afternoon! YOLO can be used for real-time human action detection through pose estimation. For more details, please explore the pose estimation section in the Ultralytics documentation.
1
NasserAlqeifi
Hi there! Could anyone point me to the papers for YOLOv8 and YOLOv11 Instance Segmentation? Thank you!
- Glenn JocherUltralytics(edited)
@NasserAlqeifi hello! Ultralytics has not published formal research papers for YOLOv8 and YOLO11. YOLO26 does have a paper, see the YOLO26 docs. For detailed information on segmentation, please refer to the Ultralytics documentation. If you have further questions, feel free to ask!
1 Hi @glenn-jocher ,
Thank you for the information! I'm a master's student currently using the YOLOv8 Instance Segmentation model for my thesis. I've also tried using YOLOv11 and noticed that the documentation mentions it utilizes a variant of the U-Net architecture for segmentation.
I would love to know more about how segmentation and object detection work in YOLOv11, as well as the key differences between YOLOv8 and YOLOv11 in these tasks. Any additional insights would be greatly appreciated!
Thank you!
- Glenn JocherUltralytics(edited)
Thank you for your interest! Instance segmentation in YOLOv8 and YOLO11 is not based on U-Net. It uses the YOLO detection head with an additional prototype-mask branch that produces the masks. For more details, please refer to the segmentation docs; for new projects we recommend YOLO26.
hrbjoern
Would be nice to have examples for tracking, too ...
- Glenn JocherUltralytics
@hrbjoern thank you for your suggestion! We currently have tracking examples in our documentation. You can explore them for more insights on implementing tracking with YOLOv8.
OK, thanks. I just figured that since it's mentioned in the beginning of the page (photo), it should also be explained ...
- Glenn JocherUltralytics
Yes sorry for the confusion. We've placed the Tracking docs under Modes rather than Tasks here: https://docs.ultralytics.com/modes/track/
1