Oriented Bounding Box Detection with Ultralytics YOLO
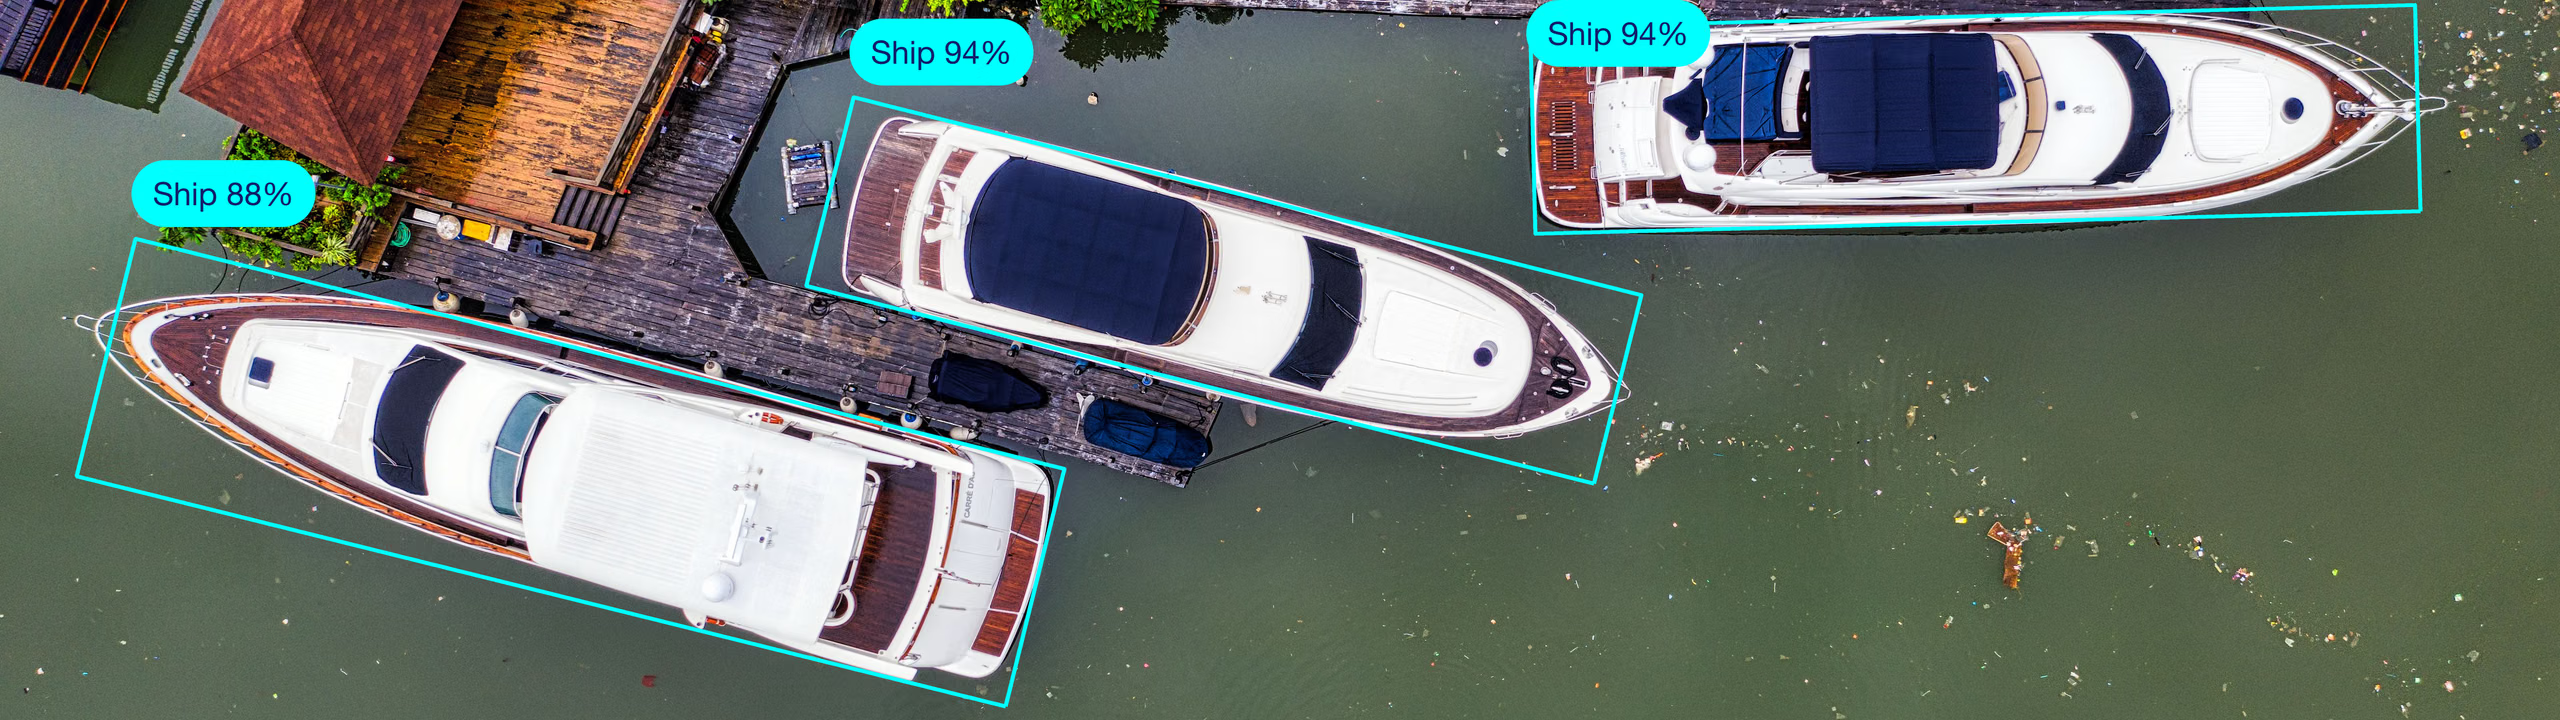
Oriented object detection goes a step further than standard object detection by introducing an extra angle to locate objects more accurately in an image.
The output of an oriented object detector is a set of rotated bounding boxes that precisely enclose the objects in the image, along with class labels and confidence scores for each box. Oriented bounding boxes are particularly useful when objects appear at various angles, such as in aerial imagery, where traditional axis-aligned bounding boxes may include unnecessary background. Typical uses are ship and vehicle detection from satellites and drones, building and infrastructure analysis for urban planning, crop monitoring, and solar panel or wind turbine inspection.
Watch: How to Detect & Track Objects with Ultralytics YOLO26 Oriented Bounding Boxes (OBB) | Ship Tracking 🚢
YOLO26 OBB models use the -obb suffix, e.g., yolo26n-obb.pt, and are pretrained on DOTAv1.
| Ships Detection using OBB | Vehicle Detection using OBB |
|---|---|
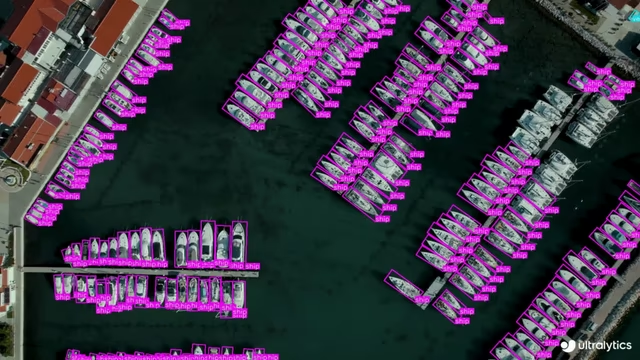 | 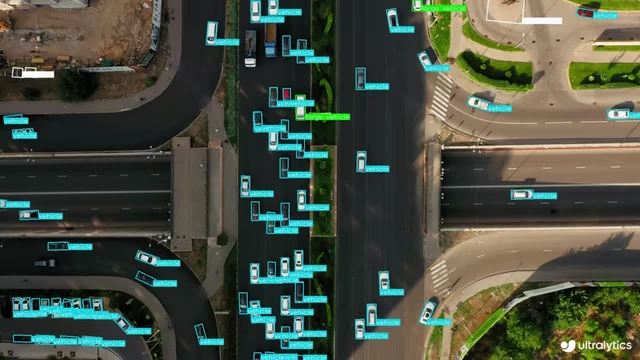 |
Models#
YOLO26 OBB models pretrained on the DOTAv1 dataset are shown below.
Models download automatically from the latest Ultralytics release on first use.
| Model | size (pixels) | mAPtest50-95 (e2e) | mAPtest50 (e2e) | Speed CPU ONNX (ms) | Speed T4 TensorRT10 (ms) | params (M) | FLOPs (B) |
|---|---|---|---|---|---|---|---|
| YOLO26n-obb | 1024 | 52.4 | 78.9 | 97.7 ± 0.9 | 2.8 ± 0.0 | 2.4 | 14.8 |
| YOLO26s-obb | 1024 | 54.8 | 80.9 | 218.0 ± 1.4 | 4.9 ± 0.1 | 9.8 | 56.7 |
| YOLO26m-obb | 1024 | 55.3 | 81.0 | 579.2 ± 3.8 | 10.2 ± 0.3 | 21.2 | 184.9 |
| YOLO26l-obb | 1024 | 56.2 | 81.6 | 735.6 ± 3.1 | 13.0 ± 0.2 | 25.6 | 232.4 |
| YOLO26x-obb | 1024 | 56.7 | 81.7 | 1485.7 ± 11.5 | 30.5 ± 0.9 | 57.6 | 520.1 |
- mAPtest values are for single-model multiscale on DOTAv1 dataset.
Reproduce withyolo obb val data=DOTAv1.yaml device=0 split=test nms=False save_json=Trueand submit merged results to DOTA evaluation. - Speed averaged over DOTAv1 val images with ONNX on CPU and TensorRT10 on an NVIDIA T4 GPU.
Reproduce withyolo obb val data=DOTAv1.yaml batch=1 device=0|cpu nms=False - Params and FLOPs values are for fused models after Conv/BatchNorm folding and removal of the unused detection branch. Pretrained checkpoints retain the full training architecture and may show higher counts.
See the unreleased YOLO27 preview for preliminary DOTAv1 results.
Train#
Train a YOLO26n-obb model on the DOTA8 dataset for 100 epochs at image size 640.
An OBB and its 180° rotation are identical, so rotation is defined modulo 180° and the box has no direction. Training labels are canonicalized to a long-edge form: the box width w is the longer side, the angle is measured clockwise from the positive x-axis to the orientation of the w edge, and it is stored in radians in [-π/4, 3π/4) ([-45°, 135°)). Predictions are not canonicalized, so a predicted box may report the short edge as w; see Results Output. The [0°, 90°) form is the regularized DOTA-style convention and is not applied at training or inference.
from ultralytics import YOLO

# Load a model
model = YOLO("yolo26n-obb.yaml")  # build a new model from YAML
model = YOLO("yolo26n-obb.pt")  # load a pretrained model (recommended for training)
model = YOLO("yolo26n-obb.yaml").load("yolo26n-obb.pt")  # build from YAML and transfer weights

# Train the model
results = model.train(data="dota8.yaml", epochs=100, imgsz=640)
Watch: How to Train Ultralytics YOLO-OBB (Oriented Bounding Boxes) Models on DOTA Dataset using Ultralytics Platform
See full train mode details in the Train page. OBB models can also be trained with Ultralytics Platform cloud training.
Dataset format#
OBB dataset format can be found in detail in the Dataset Guide. The YOLO OBB format designates bounding boxes by their four corner points with coordinates normalized between 0 and 1, following this structure. Ultralytics Platform annotation supports OBB labels with a dedicated oriented bounding box drawing tool:
class_index x1 y1 x2 y2 x3 y3 x4 y4Internally, YOLO processes losses and outputs in the xywhr format, which represents the bounding box's center point (xy), width, height, and rotation.
Val#
Validate trained YOLO26n-obb model accuracy, measured as mean average precision (mAP), on the DOTA8 dataset. Pass data explicitly so validation uses the intended dataset YAML.
from ultralytics import YOLO

# Load a model
model = YOLO("yolo26n-obb.pt")  # load an official model
model = YOLO("path/to/best.pt")  # load a custom model

# Validate the model
metrics = model.val(data="dota8.yaml")  # validate on the DOTA8 dataset
metrics.box.map  # map50-95(B)
metrics.box.map50  # map50(B)
metrics.box.map75  # map75(B)
metrics.box.maps  # mAP50-95(B) per class; classes absent from the val set hold the overall mAP(B)
metrics.box.ap_class_index  # class indices that were actually evaluated
metrics.box.image_metrics # per-image metrics dictionary with precision, recall, F1, TP, FP, and FNPredict#
Use a trained YOLO26n-obb model to run predictions on images.
from ultralytics import YOLO

# Load a model
model = YOLO("yolo26n-obb.pt")  # load an official model
model = YOLO("path/to/best.pt")  # load a custom model

# Predict with the model
results = model("https://ultralytics.com/images/boats.jpg")  # predict on an image

# Access the results
for result in results:
    xywhr = result.obb.xywhr  # center-x, center-y, width, height, angle (radians)
    xyxyxyxy = result.obb.xyxyxyxy  # polygon format with 4-points
    names = [result.names[cls.item()] for cls in result.obb.cls.int()]  # class name of each box
    confs = result.obb.conf  # confidence score of each box
See full predict mode details in the Predict page.
Pass save_crop=True to save a rotation-aligned crop of each OBB at its box size, as ObjectCropper also does.
Results Output#
Oriented bounding box detection returns one Results object per image. The primary prediction field is result.obb,
which contains rotated boxes, class IDs, and confidence scores for each detected object.
| Attribute | Type | Shape | Description |
|---|---|---|---|
result.obb | OBB | (N) | Oriented boxes. |
result.obb.data | torch.float32 | (N,7/8) | Raw rotated boxes with confidence/class. |
result.obb.xywhr | torch.float32 | (N,5) | xywhr rotated boxes. |
result.obb.xyxyxyxy | torch.float32 | (N,4,2) | Four corner points. |
result.obb.conf | torch.float32 | (N,) | Confidence scores. |
Labels are canonicalized to the long-edge convention but predictions are not, so result.obb.xywhr may report w smaller than h with the rotation measured from the short edge. Both forms describe the same rectangle, so result.obb.xyxyxyxy is correct either way. When tracking, each track keeps the half-turn form (θ or θ ± π) nearest its previous angle, so track angles do not flip by π between frames and may leave [-π/4, 3π/4). Convert the corners back when downstream code needs the long-edge form, keeping in mind that rewriting the box parameters may cyclically shift the corner order:
from ultralytics.utils.ops import xyxyxyxy2xywhr

xywhr = xyxyxyxy2xywhr(result.obb.xyxyxyxy)  # w >= h, rotation in [-pi/4, 3pi/4)
For task-specific Results fields across every task, see the Predict Results by Task section.
Export#
Export a YOLO26n-obb model to a different format like ONNX, CoreML, etc.
from ultralytics import YOLO

# Load a model
model = YOLO("yolo26n-obb.pt")  # load an official model
model = YOLO("path/to/best.pt")  # load a custom model

# Export the model
model.export(format="onnx")
Available YOLO26-obb export formats are in the table below. You can export to any format using the format argument, e.g., format='onnx' or format='engine'. You can predict or validate directly on exported models, e.g., yolo predict model=yolo26n-obb.onnx. Usage examples are shown for your model after export completes.
| Format | format Argument | Model | Metadata | Arguments |
|---|---|---|---|---|
| PyTorch | - | yolo26n-obb.pt | ✅ | - |
| TorchScript | torchscript | yolo26n-obb.torchscript | ✅ | imgsz, quantize, dynamic, nms, batch, device |
| ONNX | onnx | yolo26n-obb.onnx | ✅ | imgsz, quantize, dynamic, simplify, opset, nms, batch, data, fraction, device |
| OpenVINO | openvino | yolo26n-obb_openvino_model/ | ✅ | imgsz, quantize, dynamic, nms, batch, data, fraction, device |
| TensorRT | engine | yolo26n-obb.engine | ✅ | imgsz, quantize, dynamic, simplify, opset, workspace, nms, batch, data, fraction, device |
| CoreML | coreml | yolo26n-obb.mlpackage | ✅ | imgsz, dynamic, quantize, nms, batch, device |
| Apple Core AI | coreai | yolo26n-obb.aimodel | ✅ | imgsz, batch, quantize |
| TF SavedModel | saved_model | yolo26n-obb_saved_model/ | ✅ | imgsz, quantize, opset, nms, batch, data, fraction, device |
| TF GraphDef | pb | yolo26n-obb.pb | ❌ | imgsz, opset, batch, device |
| TF Edge TPU | edgetpu | yolo26n-obb_edgetpu.tflite | ✅ | imgsz, quantize, opset, data, fraction, device |
| LiteRT | litert | yolo26n-obb.tflite | ✅ | imgsz, quantize, batch, data, fraction, device |
| PaddlePaddle | paddle | yolo26n-obb_paddle_model/ | ✅ | imgsz, batch, device |
| MNN | mnn | yolo26n-obb.mnn | ✅ | imgsz, batch, dynamic, quantize, simplify, opset, nms, device |
| NCNN | ncnn | yolo26n-obb_ncnn_model/ | ✅ | imgsz, quantize, batch, device |
| IMX500 | imx | yolo11n_imx_model/ | ✅ | imgsz, quantize, data, fraction, nms, device |
| RKNN | rknn | yolo26n-obb_rknn_model/ | ✅ | imgsz, batch, name, quantize, simplify, opset, data, fraction, device |
| ExecuTorch | executorch | yolo26n-obb_executorch_model/ | ✅ | imgsz, batch, device |
| Axelera | axelera | yolo26n-obb_axelera_model/ | ✅ | imgsz, batch, quantize, data, fraction, device |
| DEEPX | deepx | yolo26n-obb_deepx_model/ | ✅ | imgsz, quantize, simplify, opset, data, optimize, device |
| Qualcomm QNN | qnn | yolo26n-obb_qnn.onnx | ✅ | imgsz, batch, name, quantize, simplify, opset, data, fraction, device |
| Hailo | hailo | yolo26n-obb_hailo_model/ | ✅ | imgsz, name, quantize, data, fraction, simplify, conf, iou, device |
| Huawei Ascend | ascend | yolo26n-obb_ascend_model/ | ✅ | imgsz, batch, name, quantize, opset, simplify, nms, device |
| AMD Xilinx | xilinx | yolo26n-obb_xilinx_model/ | ✅ | imgsz, name, quantize, data, fraction, opset, simplify, device |
nms=None defaults to raw outputs for external NMS (YOLO26 keeps its NMS-free head on Axelera). Set nms=False to select an available NMS-free head; unsupported formats fall back to their native output path. The nms entries above identify formats that can embed NMS with nms=True.
See full export details in the Export page.
FAQ#
Oriented Bounding Boxes (OBB) include an additional angle to enhance object localization accuracy in images. Unlike regular bounding boxes, which are axis-aligned rectangles, OBBs can rotate to fit the orientation of the object better. This is particularly useful for applications requiring precise object placement, such as aerial or satellite imagery (Dataset Guide).
To train a YOLO26n-obb model with a custom dataset, follow the example below using Python or CLI:
Examplefrom ultralytics import YOLO # Load a pretrained model model = YOLO("yolo26n-obb.pt") # Train the model results = model.train(data="path/to/custom_dataset.yaml", epochs=100, imgsz=640)For more training arguments, check the Configuration section.
YOLO26-OBB models are pretrained on datasets like DOTAv1 but you can use any dataset formatted for OBB. Detailed information on OBB dataset formats can be found in the Dataset Guide.
To validate a YOLO26n-obb model, you can use Python or CLI commands as shown below:
Examplefrom ultralytics import YOLO # Load a model model = YOLO("yolo26n-obb.pt") # Validate the model metrics = model.val(data="dota8.yaml")See full validation details in the Val section.
Exporting a YOLO26-OBB model to ONNX format is straightforward using either Python or CLI:
Examplefrom ultralytics import YOLO # Load a model model = YOLO("yolo26n-obb.pt") # Export the model model.export(format="onnx")For more export formats and details, refer to the Export page.


Comments252
Ask a question, share your results, or help someone else.
zhouyizhuo
how to do Model Ensembling on yolov8-obb models?
2 Paula DerrengerUltralytics(edited)
Model ensembling with YOLOv8-obb models involves combining the predictions from multiple trained models to improve the accuracy of your oriented objects detection. Currently, direct support for model ensembling within Ultralytics YOLO isn't provided out-of-the-box. However, you can manually implement ensembling by running predictions with each model separately and then combining these predictions.
One common approach is to average the bounding box coordinates and confidence scores of the same object detected by multiple models. Ensure to consider the rotating angle parameter unique to OBB models in your ensembling logic. Here's a basic conceptual example to get you started:
from ultralytics import YOLO

models = [
    YOLO('path/to/first_obb_model.pt'),
    YOLO('path/to/second_obb_model.pt'),
    # Add more models as needed
]

# Assuming you have a method to read your images/videos
image = 'path/to/image.jpg'

# List to store results from all models
all_preds = []

for model in models:
    results = model(image)
    all_preds.append(results[0].obb)  # Extracting OBB predictions (xywhr, conf, cls)

# Assuming you have a method `combine_predictions(all_preds)`
# that combines predictions from all models
final_predictions = combine_predictions(all_preds)

# Process `final_predictions`...
This example loads each model, runs predictions on the same image, and stores the results. You'd then need to implement
combine_predictions(all_preds)to handle the logic for combining these predictions based on criteria like IoU, confidence scores, etc., taking into account the angle for rotated bounding boxes.Remember, ensembling may increase inference time due to processing with multiple models. Always weigh the benefits of improved accuracy against potential increases in computational cost. Happy coding! 😊
windzu
if you want draw predict results to img and save , you can ref below easy code :
# you predict code #

import cv2

image = cv2.imread(test_img_path)
for r in results:
    xyxyxyxy = r.obb.xyxyxyxy.cpu().numpy()

    for box in xyxyxyxy:
        points = box.reshape(4, 2).astype(int)
        cv2.polylines(image, [points], isClosed=True, color=(0, 255, 0), thickness=2)

cv2.imwrite("detected_image.jpg", image)
1 Glenn JocherUltralytics
@windzu thank you for sharing the code example. For more details on using YOLOv8 Oriented Bounding Boxes, please refer to our documentation on training, validation, and exporting models. If you have further questions, feel free to ask here.
krialm
Hi, when I am using yolov8_obb model in results I always have boxes: None keypoints: None masks: None
even when the model makes prediction. Did someone faced with this problem and if yes, what was the solution? Thank you.🙂
1RizwanMunawar
@krialm In the case of OBB, you can get bounding box data, using the mentioned code below.
model = YOLO("yolov8n-obb.pt")
results = model.predict(im0)
pred_boxes = results[0].obb
I hope this helps! Let me know if you have any additional questions.
Thanks and Regards Ultralytics Team!
1kedardg
Is there a way for me to train OBB models from scratch let's say the P2 or RTDETR models which are not available pre-trained?
- Paula DerrengerUltralytics
@kedardg absolutely, you can train OBB models like P2 or RTDETR from scratch even if they're not available pre-trained. You'd start by creating a new model from a YAML file, which defines the model architecture. Here's a quick example of how you might do it:
yolo obb train data=your_dataset.yaml model=your_model.yaml epochs=100 imgsz=640Just replace
your_dataset.yamlwith your dataset configuration file andyour_model.yamlwith your model configuration file. Make sure your dataset is properly formatted for OBB tasks. Happy training! 😊🚀 RumaisaIlyas
model = YOLO("yolov8n-obb.pt") results = model.predict(im0) pred_boxes = results[0].obb
i did this but i want to draw bounding boxes on the test image and return it. how to do that?
my function is:
def count_detection(image): if image is not None: # Load the YOLO model model = YOLO('bestobbv8s.pt')
# Check the shape of the input image print("Input image shape:", image.shape) # Use the model to predict the wheat spikes in image results = model(image, save=True) # Count count = sum(len(result) for result in results) print("count", count) # Draw bounding boxes for detected wheat heads for result in results: boxes = result.obb #here? return image- Paula DerrengerUltralytics
@RumaisaIlyas hey there! 😊 To draw bounding boxes on your test image and return it, you can use the
plot()method available in theResultsobject. Here's how you can modify your function:def count_detection(image): if image is not None: # Load the YOLO model model = YOLO('bestobbv8s.pt') # Check the shape of the input image print("Input image shape:", image.shape) # Use the model to predict results = model.predict(image) # Draw bounding boxes and return the annotated image annotated_image = results[0].plot() # Count detections count = len(results[0].obb) print("count", count) return annotated_imageIn this updated function, after making predictions with
model.predict(image), we useresults[0].plot()to draw bounding boxes on the image. This method returns the annotated image, which we then return from the function. This should give you the visual feedback you're looking for! 🚀Let me know if you need further assistance!
thankyou so much for your assistance. i am facing a problem that my runs folder is not created after i run the code provided. why is that? what should i do in code so that i get the runs folder with my predicted image
- Paula DerrengerUltralytics(edited)
Hey there! 😊 It sounds like you're doing everything right, but if the
runsfolder isn't being created, it might be due to a small oversight. Here's a quick checklist:- Ensure you're using the latest version of the Ultralytics YOLO library. Sometimes, updates fix these kinds of issues.
- Double-check your command and make sure it's complete. For predictions, it should look something like this:
from ultralytics import YOLO # Load your model model = YOLO('bestobbv8s.pt') # Run prediction # save=True writes the annotated image to the 'runs' folder results = model.predict('path/to/your/image.jpg', save=True)- If you're still not seeing the
runsfolder, try specifying the output directory explicitly in your code:
results = model.predict('path/to/your/image.jpg', save=True, project='runs/detect') # Adjust the path as needed- Lastly, ensure you have the necessary write permissions in your working directory. Sometimes, permission issues can prevent the creation of new folders.
If you've checked all these and the issue persists, it might be helpful to share more details about your environment (like your operating system) or any error messages you're seeing. That way, the community can offer more targeted advice. 🚀
Hope this helps, and happy detecting!
Ci-ne
I also face the same problem. I tried using the code provided but it still says NoneType
ncnn_model = YOLO("./my_ncnn_model", task='detect') results = ncnn_model.predict(image_path)
if results[0] is not None: # Ensure results is not None obb_boxes = results[0].obb # For OBB models print(f"OBB Box: {obb_boxes}") else: print("No detections.")
This is what I get
Speed: 4.1ms preprocess, 93.1ms inference, 1.2ms postprocess per image at shape (1, 3, 640, 640) OBB Box: None
Any help?
1chengz
The document notes that 'OBB angles are constrained to the range 0–90 degrees (exclusive of 90). Angles of 90 degrees or greater are not supported.' So what is the normal radian range for an OBB, [-π/4, 3π/4) or something else?
 Murat Raimbekov
the radian range is
[-π/4, 3π/4), i.e.[-45°, 135°), not[0°, 90°). that docs note was inaccurate and is fixed in #24534.ground-truth angles are normalized in
xyxyxyxy2xywhr(ultralytics/utils/ops.py) by two loops,while theta >= 3*pi/4: theta -= piandwhile theta < -pi/4: theta += pi, withwswapped to the longer side. sweeping a rectangle through physical 0->180°:0° -> 0.0000 45° -> 0.7854 (π/4) 90° -> 1.5708 (π/2) 120° -> 2.0944 135° -> -0.7854 (-π/4) 165° -> -0.2618so the span is exactly π wide, half-open at
3π/4.the heads match this:
OBB(yolov8/yolo11):angle = (sigmoid(raw) - 0.25) * π, hard-bounded to[-π/4, 3π/4].OBB26(yolo26): raw output, no sigmoid, trained on targets already in[-π/4, 3π/4).
[0, π/2)is the regularized DOTA-style form produced byregularize_rboxesinops.py. that function is defined but has no callers anywhere inultralytics/, so it is not applied at training or inference. predicted boxes reach you unregularized:result.obb.xywhrreturns the angle in[-π/4, 3π/4)(verified by feeding angles like-0.70and2.30through the predict path and reading them back unchanged).one consequence, which is what the original note was really about: an OBB and its 180° rotation encode to the same
xywhr, so rotation is defined only modulo 180° and the box has no direction. θ and θ+180° are indistinguishable, so you cannot recover a fixed corner ordering from the predicted angle.
 User
mAPtest values are for single-model multiscale on DOTAv1 dataset. Reproduce by yolo val obb data=DOTAv1.yaml device=0 split=test and submit merged results to DOTA evaluation. This mentions that the test results are submitted to the DOTAv1 server through a multiscale approach. I would like to ask, what does this "multiscale" mean? How is it specifically implemented? Is it trained at scales like 512512 and 10241024, and then tested on the test dataset? How are the final results obtained? I am not quite clear on what this multiscale refers to. Please help me with this.
- Glenn JocherUltralytics
Here, “multiscale” means evaluating the same trained model on multiple resized/split versions of each DOTA image tile, then merging those detections back into the original image for final submission; in Ultralytics this is tied to the DOTA split pipeline with scales like
rates=[0.5, 1.0, 1.5]in the DOTA dataset guide and the merged-result export inOBBValidator.eval_json(), so it is usually multi-scale test-time inference with one model rather than separately training 512 and 1024 models. - Murat Raimbekov
it is one model, trained once. there is no separate 512 and 1024 model, and no separate training runs per scale. the "multiscale" lives entirely in the dota tiling step, not inside
yolo val.where it comes from. dota images are huge (800x800 up to ~20000x20000), so they are cut into overlapping tiles before training/val using
split_trainval/split_testfromultralytics/data/split_dota.py. the multiscale variant passesrates=[0.5, 1.0, 1.5](this is exactly what the dota dataset guide shows). for each raterthe code usescrop_size / randgap / r, so with the defaultscrop_size=1024, gap=200you get tiles of:rate 0.5 -> 2048 px tiles (gap 400) rate 1.0 -> 1024 px tiles (gap 200) rate 1.5 -> 682 px tiles (gap 133)every original image is therefore cut into overlapping windows at all three crop sizes. each window is later resized to
imgszat inference, so the same content is effectively seen at three resolutions. concretely, a single 4000x4000 image produces ~98 tiles spread across those three sizes.training. the model is trained once on the multiscale-split trainval tiles (same
rates=[0.5, 1.0, 1.5]). it is not "trained at 512 then at 1024" as separate models.test / how the final number is obtained.
yolo val obb data=DOTAv1.yaml split=testruns that single model over every test tile. each tile filename encodes the source image id and crop offset (name__cropsize__xstart___ystart).OBBValidator.eval_json()parses that, shifts each tile's rotated boxes back into the original full-image coordinates, concatenates detections from all tiles and all scales, then runs a rotated probiou NMS (fast_nms, iou 0.3) to remove the overlap introduced by tiling. the merged per-image results are written as dotaTask1_*.txt, which is what you submit to the dota evaluation server.one practical caveat.
yolo val ... split=testdoes not create the multiscale tiles for you. you have to runsplit_test(rates=[0.5, 1.0, 1.5])first (andsplit_trainvalwith the same rates for training). running val on the raw full dota images is single-scale and will not reproduce themAPtestnumber in the table.so in short: multiscale = offline multi-scale tiling + per-tile single-scale inference + merge-back-and-NMS, all with one model. it is test-time multi-scale through the tiling, not test-time augmentation inside
val.
kssion
WARNING ⚠️ CoreML: 'nms=True' is only available for Detect models like 'yolo11n.pt'.
yolo export model=best.pt format=coreml nms=True conf=0.25 iou=0.45Ultralytics 8.3.232 🚀 Python-3.11.11 torch-2.9.1 CPU (Apple M1) YOLO11n-obb summary (fused): 109 layers, 2,653,918 parameters, 0 gradients, 6.6 GFLOPs
PyTorch: starting from 'best.pt' with input shape (1, 3, 640, 640) BCHW and output shape(s) (1, 6, 8400) (5.5 MB) Torch version 2.9.1 has not been tested with coremltools. You may run into unexpected errors. Torch 2.7.0 is the most recent version that has been tested.
CoreML: starting export with coremltools 9.0... WARNING ⚠️ CoreML: 'nms=True' is only available for Detect models like 'yolo11n.pt'. Converting PyTorch Frontend ==> MIL Ops: 100%|██████████████▉| 867/868 [00:00<00:00, 8975.73 ops/s] Running MIL frontend_pytorch pipeline: 100%|███████████████████| 5/5 [00:00<00:00, 166.58 passes/s] Running MIL default pipeline: 100%|███████████████████████████| 95/95 [00:00<00:00, 99.61 passes/s] Running MIL backend_mlprogram pipeline: 100%|████████████████| 12/12 [00:00<00:00, 176.60 passes/s] CoreML: export success ✅ 4.8s, saved as 'best.mlpackage' (5.3 MB)
Export complete (5.0s)
- Glenn JocherUltralytics
That warning is expected for OBB models: CoreML
nms=Trueis only supported for axis-aligned Detect heads, so export your*-obbmodel without NMS and do confidence/IoU (rotated NMS) post-processing on the app side (export success ✅ means you’re fine). See the Ultralytics YOLO OBB task docs for the OBB output formats.yolo export model=best.pt format=coreml
wang18382140151-hub
你好,请问你们未来的工作计划中是否有将rtdetr用于obb检测呢,最近我正在基于贵司源码做改进
AbhisekRao
I'm currently working with the YOLOv11 Oriented Bounding Box (OBB) model exported in TensorRT format, and deploying it on an NVIDIA Jetson device (AGX Orin). While the model works in standard inference pipelines (.pt) , I’m facing challenges integrating it into a DeepStream-based application to process live RTSP video streams.
There seems to be no existing reference implementation or sample Python code that demonstrates how to use the OBB variant of the model with DeepStream. Specifically, I'm looking for guidance on:
1- Integrating the YOLOv11 OBB TensorRT model with DeepStream (preferably using Python bindings). 2- Proper parsing and visualization of oriented bounding boxes from the model output. 3- Any custom parser or config file changes required in the DeepStream pipeline.
Any support, documentation, or examples from the team or community would be greatly appreciated.
cripsgreen
Hello, could you please share some insights on how to train the hyperparameters for YOLOv11-OBB, as well as the pre-trained weights? Thank you.
ziishuo
May I ask if the OBB model can be used to detect subjects in a normal perspective (such as a level shot)? I noticed that most of the examples are from a top-down angle. Thank you!