Gestión de colas con Ultralytics YOLO26
¿Qué es la gestión de colas?#

La gestión de colas con Ultralytics YOLO26 consiste en supervisar filas de personas o vehículos para reducir los tiempos de espera y mejorar la eficiencia. YOLO26 detecta y sigue a todas las personas de una zona de espera e informa de la longitud de la cola en directo, lo que ayuda a mejorar la satisfacción del cliente y las operaciones en establecimientos como tiendas, bancos, aeropuertos y centros sanitarios.
Ver: Cómo crear un sistema de gestión de colas con Ultralytics YOLO26 | Análisis de colas en tiempo real 🚀
Ventajas de la gestión de colas#
- Reducción de los tiempos de espera: Los sistemas de gestión de colas organizan las filas de forma eficiente y minimizan los tiempos de espera de los clientes. Esto mejora su satisfacción, ya que pasan menos tiempo esperando y más tiempo interactuando con los productos o servicios.
- Mayor eficiencia: La implantación de la gestión de colas permite a las empresas asignar los recursos de forma más eficaz. Al analizar los datos de las colas y optimizar la distribución del personal, las empresas pueden agilizar las operaciones, reducir los costes y mejorar la productividad general.
- Información en tiempo real: La gestión de colas basada en YOLO26 proporciona datos instantáneos sobre la longitud de las colas y los tiempos de espera, lo que permite a los responsables tomar decisiones fundamentadas con rapidez.
- Mejora de la experiencia del cliente: Al reducir la frustración asociada a las largas esperas, las empresas pueden mejorar la satisfacción y la fidelidad de sus clientes.
Aplicaciones en el mundo real#
| Logística | Comercio minorista |
|---|---|
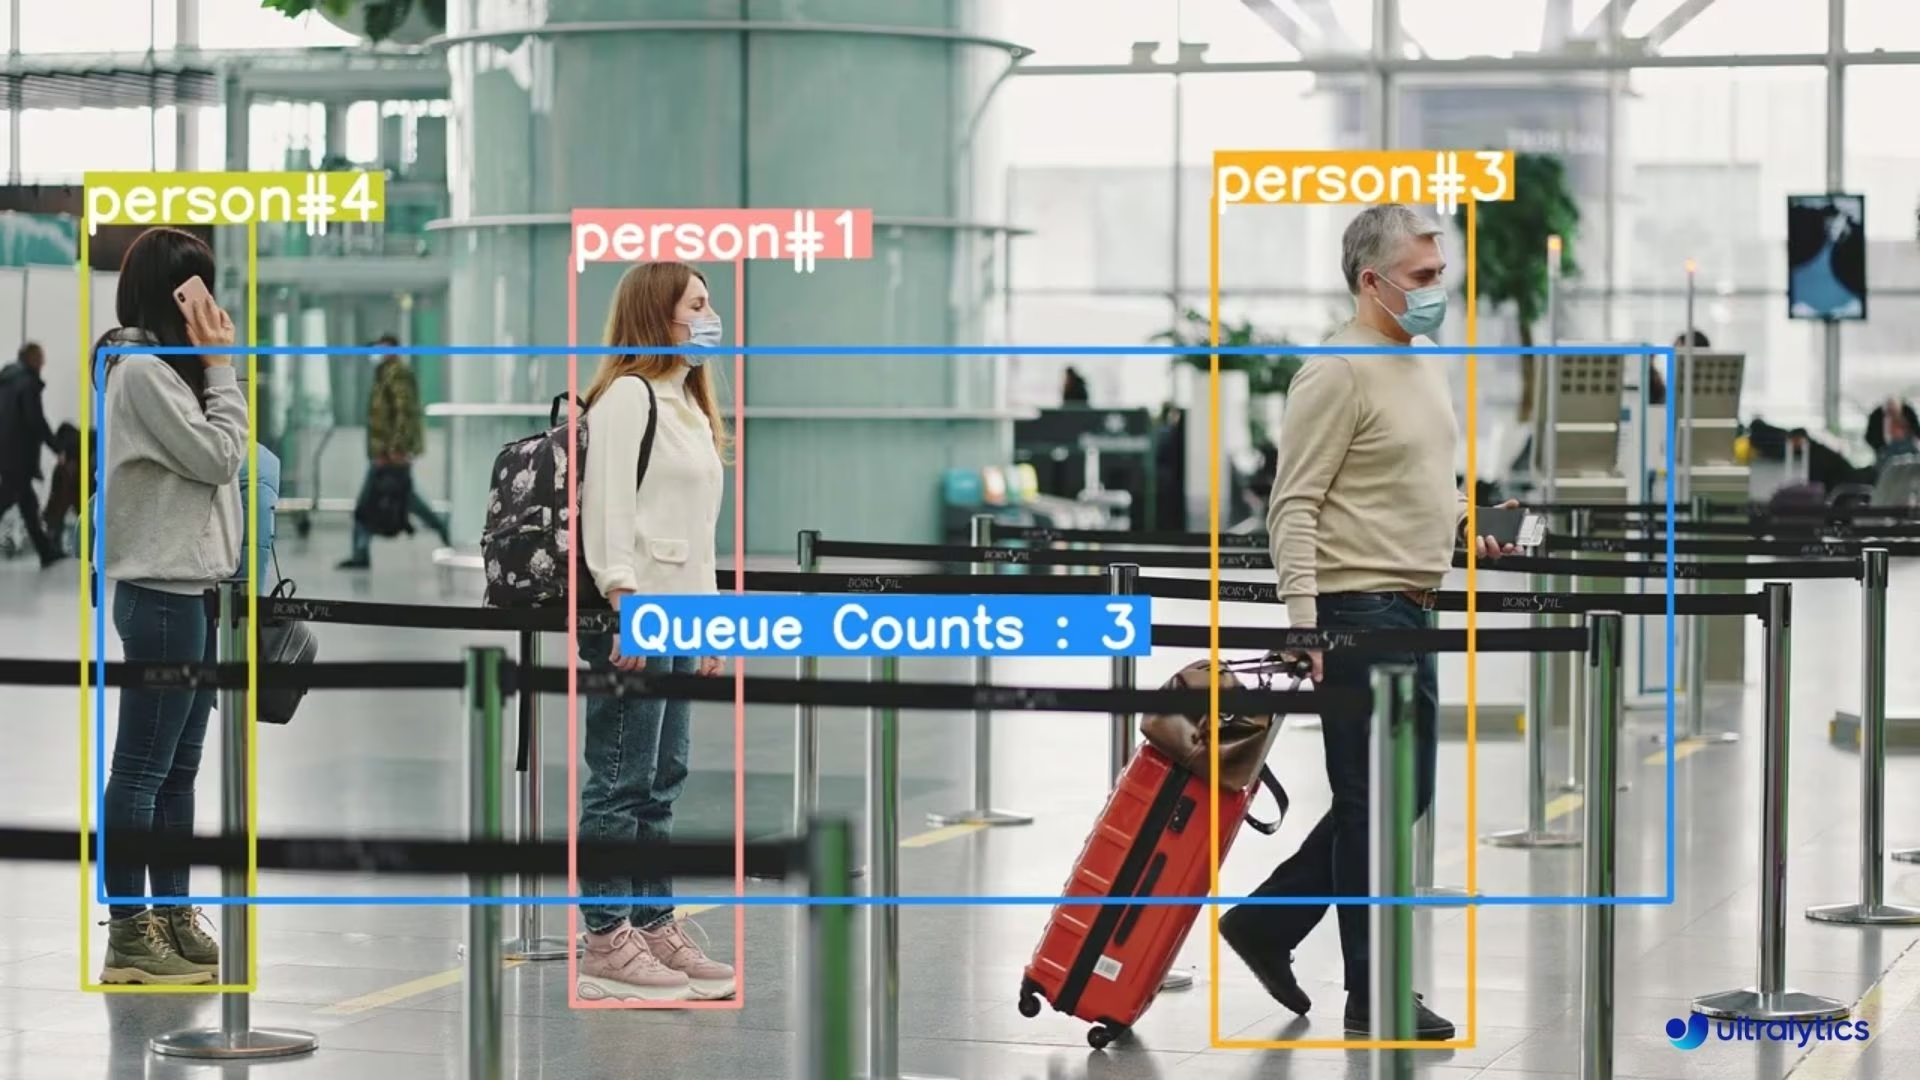 | 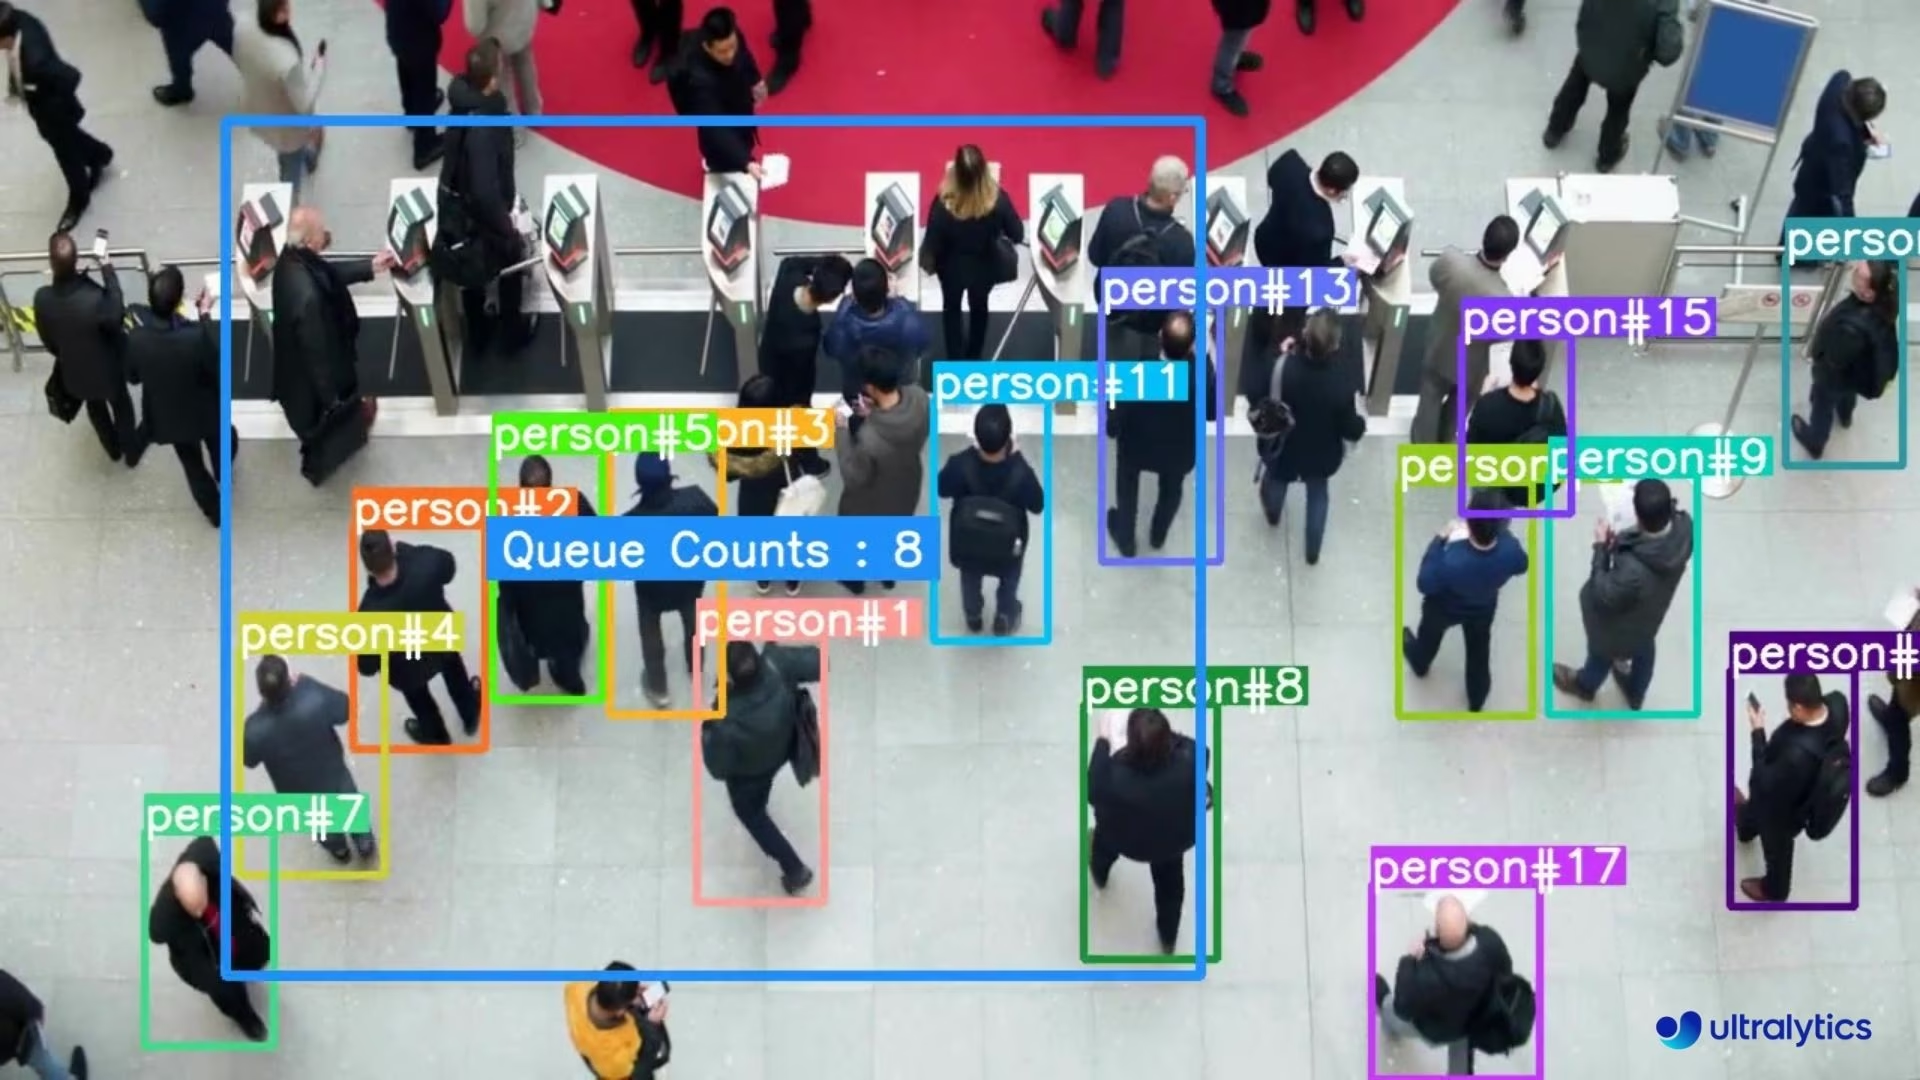 |
| Gestión de colas en el mostrador de venta de billetes de un aeropuerto con Ultralytics YOLO26 | Supervisión de una cola en una multitud con Ultralytics YOLO26 |
Gestiona las colas con YOLO26#
La solución QueueManager cuenta los objetos seguidos dentro de una región definida en cada fotograma y proporciona la longitud de la cola en directo, que puedes incluir en un vídeo de salida. Pasa un polígono que cubra la zona de espera y ejecútala sobre la fuente de vídeo con la API de Python o la CLI.
# Run a queue example
yolo solutions queue show=True

# Pass a source video
yolo solutions queue source="path/to/video.mp4"

# Pass queue coordinates
yolo solutions queue region="[(20, 400), (1080, 400), (1080, 360), (20, 360)]"
Argumentos de QueueManager#
Aquí tienes una tabla con los argumentos de QueueManager:
| Argumento | Tipo | Predeterminado | Descripción |
|---|---|---|---|
model | str | None | Ruta a un archivo de modelo Ultralytics YOLO. |
region | list o dict | None | Puntos que definen la región de interés, ya sea una lista de tuplas (x, y) o un diccionario que asigna nombres de región a listas de puntos para varias regiones (solo RegionCounter). Si None, las soluciones que requieren una región usan una región predeterminada predefinida. |
line_width | int | 2 | Grosor de línea de los cuadros, puntos clave y recuentos que dibuja la solución. |
verbose | bool | True | Activa el registro por fotograma de la forma de entrada, los recuentos por clase y la velocidad de procesamiento de la solución. La llamada de seguimiento en sí siempre es silenciosa. |
La solución QueueManager también admite los argumentos track:
| Argumento | Tipo | Predeterminado | Descripción |
|---|---|---|---|
tracker | str | 'tracktrack.yaml' | Especifica el algoritmo de seguimiento que se va a usar. Opciones integradas: botsort.yaml, bytetrack.yaml, ocsort.yaml, deepocsort.yaml, fasttrack.yaml, tracktrack.yaml. |
conf | float | 0.25 | Establece el umbral de confianza de las detecciones; los valores más bajos permiten seguir más objetos, pero pueden incluir falsos positivos. |
iou | float | 0.5 | Establece el umbral de intersección sobre unión (IoU) para filtrar las detecciones solapadas. |
classes | list | None | Filtra los resultados por índice de clase. Por ejemplo, classes=[0, 2, 3] solo sigue las clases especificadas. |
device | str | None | Especifica el dispositivo para la inferencia (p. ej., cpu, cuda:0 o 0). Permite elegir entre CPU, una GPU concreta u otros dispositivos de cálculo para ejecutar el modelo. |
imgsz | int or tuple | 640 | Tamaño de imagen de destino para la inferencia: un entero para una imagen cuadrada o una pareja (height, width). Las dimensiones se ajustan al stride del modelo. |
max_det | int | 300 | Número máximo de detecciones que se conservan por fotograma antes del seguimiento, lo que limita los objetos que procesa una solución en escenas densas. |
quantize | int or str | None | Precisión de inferencia: 16 (FP16) o 32/unset (FP32) para los modelos PyTorch y TorchScript fuera de CPU; los demás formatos usan la precisión que seleccionen el artefacto y el entorno de ejecución. Sustituye al argumento obsoleto half. |
Además, están disponibles los siguientes parámetros de visualización:
| Argumento | Tipo | Predeterminado | Descripción |
|---|---|---|---|
show | bool | False | Si True, muestra las imágenes o los vídeos anotados en una ventana. Es útil para obtener información visual inmediata durante el desarrollo o las pruebas. |
show_conf | bool | True | Muestra la puntuación de confianza de cada detección junto a su etiqueta. Permite conocer el grado de certeza del modelo para cada detección. |
show_labels | bool | True | Muestra etiquetas para cada detección en la salida visual. Facilita la identificación inmediata de los objetos detectados. |
Estrategias de implementación#
Al implementar la gestión de colas con YOLO26, ten en cuenta estas prácticas recomendadas:
- Colocación estratégica de las cámaras: Coloca las cámaras de forma que capten toda la zona de la cola sin obstáculos.
- Define las regiones de cola adecuadas: Establece cuidadosamente los límites de la cola en función de la distribución física de tu espacio.
- Ajusta la confianza de detección: Ajusta el umbral de confianza según las condiciones de iluminación y la densidad de la multitud.
- Intégrala con los sistemas existentes: Conecta tu solución de gestión de colas con sistemas de señalización digital o de notificación al personal para automatizar las respuestas.
Preguntas frecuentes#
Para usar Ultralytics YOLO26 para gestionar colas en tiempo real, sigue estos pasos:
- Captura la señal de vídeo con
cv2.VideoCapture. - Define la región de interés (ROI) para la gestión de colas.
- Inicializa
solutions.QueueManagercon un modelo YOLO26, comoyolo26n.pt, y la región. - Procesa los fotogramas para detectar objetos y gestionar las colas.
Aquí tienes un ejemplo mínimo:
import cv2

from ultralytics import solutions

cap = cv2.VideoCapture("path/to/video.mp4")
queue_region = [(20, 400), (1080, 400), (1080, 360), (20, 360)]

queuemanager = solutions.QueueManager(
    model="yolo26n.pt",
    region=queue_region,
    line_width=3,
    show=True,
)

while cap.isOpened():
    success, im0 = cap.read()
    if not success:
        break
    results = queuemanager(im0)

cap.release()
cv2.destroyAllWindows()
Puedes entrenar e implementar los modelos de tu solución de gestión de colas en Ultralytics Platform.
- Captura la señal de vídeo con
Usar Ultralytics YOLO26 para gestionar colas ofrece varias ventajas:
- Reducción de los tiempos de espera: Organiza las colas de forma eficiente, reduce los tiempos de espera de los clientes y aumenta su satisfacción.
- Mayor eficiencia: Analiza los datos de las colas para optimizar la asignación del personal y las operaciones, reduciendo así los costes.
- Información en tiempo real: Proporciona el recuento de personas en la cola en directo para cada fotograma, lo que permite intervenir rápidamente cuando las filas crecen.
- Escalabilidad: Se adapta fácilmente a distintos entornos, como tiendas, aeropuertos y centros sanitarios.
Ultralytics YOLO26 ofrece varias ventajas frente a los detectores basados en TensorFlow y Detectron2 para la gestión de colas:
- Rendimiento en tiempo real: YOLO26 está diseñado para la detección en tiempo real y procesa los fotogramas rápidamente.
- Facilidad de uso: Ultralytics cubre todo el flujo de trabajo, desde el entrenamiento hasta la implementación, con Python o Ultralytics Platform.
- Modelos preentrenados: Accede a una variedad de modelos preentrenados y reduce el tiempo necesario para la configuración.
- Apoyo de la comunidad: La amplia documentación y el apoyo activo de la comunidad facilitan la resolución de problemas.
Descubre cómo empezar con Ultralytics YOLO.
Sí, Ultralytics YOLO26 puede gestionar distintos tipos de colas, incluidas las de aeropuertos y establecimientos comerciales. Al configurar QueueManager con regiones y ajustes específicos, YOLO26 puede adaptarse a distintas distribuciones y densidades de las colas.
Ejemplo para aeropuertos:
queue_region_airport = [(50, 600), (1200, 600), (1200, 550), (50, 550)] queue_airport = solutions.QueueManager( model="yolo26n.pt", region=queue_region_airport, line_width=3, )Ultralytics YOLO26 se utiliza en diversas aplicaciones reales para la gestión de colas:
- Comercio minorista: Supervisa las colas de caja para reducir los tiempos de espera y mejorar la satisfacción de los clientes.
- Aeropuertos: Gestiona las colas en los mostradores de venta de billetes y los controles de seguridad para que la experiencia de los pasajeros sea más fluida.
- Sanidad: Optimiza el flujo de pacientes en clínicas y hospitales.
- Bancos: Mejora la atención al cliente mediante una gestión eficiente de las colas en los bancos.
Consulta nuestro artículo del blog sobre la gestión de colas en el mundo real para descubrir cómo la visión artificial está transformando la supervisión de colas en distintos sectores.


Comentarios18
Haz una pregunta, comparte tus resultados o ayuda a otra persona.
CharanPrasadK
Like in_counts and out_counts methods in objectCounter class, I want get Queue Count in real time to print and use on out side but the method you provided 'counts' in QueueManager class is refreshing to 0, so I made some changes in code in my local system used private variable to get the count out side in real time. How can I make it better?
 Glenn JocherUltralytics(editado)
@TechWolf21 to get the real-time queue count, read it from the results returned for each frame (
queue_count) instead of modifyingQueueManager:results = queue(im0) print(results.queue_count)For details, please refer to the Queue Management documentation.
Alexts166
Have a nice day. I made several queue areas, but I can't find the code to get a separate counter to count the total number of people who passed through these areas.
- Glenn JocherUltralytics(editado)
@Alexts166 hello!
Thank you for your question.
QueueManagercounts the people currently inside its region on each frame (results.queue_countorqueue.counts), so with several queue areas you can create oneQueueManagerper region and sum their counts:import cv2 from ultralytics import solutions cap = cv2.VideoCapture("path/to/video/file.mp4") assert cap.isOpened(), "Error reading video file" w, h, fps = (int(cap.get(x)) for x in (cv2.CAP_PROP_FRAME_WIDTH, cv2.CAP_PROP_FRAME_HEIGHT, cv2.CAP_PROP_FPS)) video_writer = cv2.VideoWriter("queue_management.avi", cv2.VideoWriter_fourcc(*"mp4v"), fps, (w, h)) # Define multiple queue regions queue_regions = [ [(20, 400), (1080, 404), (1080, 360), (20, 360)], [(30, 300), (1070, 304), (1070, 260), (30, 260)], ] # Initialize a QueueManager for each region (person class only) queues = [solutions.QueueManager(model="yolo26n.pt", region=region, classes=[0], show=False) for region in queue_regions] while cap.isOpened(): success, im0 = cap.read() if not success: print("Video frame is empty or video processing has been successfully completed.") break for queue in queues: queue(im0) # draws on im0 total_in_queues = sum(queue.counts for queue in queues) # people currently inside all queue regions print(f"People currently in the queue areas: {total_in_queues}") video_writer.write(im0) cap.release() video_writer.release() cv2.destroyAllWindows()Note this is a per-frame count of people currently in the regions, not a running total of everyone who has passed through. For cumulative in/out crossing counts, use
solutions.ObjectCounterinstead.For more details on queue management and additional examples, you can refer to our Queue Management Guide.
If you encounter any issues or have further questions, please provide a reproducible example, and ensure you are using the latest version of the packages. This will help us assist you more effectively.
Thanks for the code. I tweaked it a little to fit my needs. There is no summation of objects in queues. Maybe where is the error?
import cv2 from ultralytics import YOLO, solutions # Load the YOLOv8 model model = YOLO("best.pt") cap = cv2.VideoCapture("gf.mp4") assert cap.isOpened(), "Error reading video file" w, h, fps = (int(cap.get(x)) for x in (cv2.CAP_PROP_FRAME_WIDTH, cv2.CAP_PROP_FRAME_HEIGHT, cv2.CAP_PROP_FPS)) video_writer = cv2.VideoWriter("queue_management.avi", cv2.VideoWriter_fourcc(*"mp4v"), fps, (w, h)) # Define multiple queue regions queue_regions = [ [(20, 200), (1200, 200), (1200, 150), (20, 150)], [(20, 600), (1200, 600), (1200, 550), (20, 550)] ] # Initialize QueueManager for each region queues = [solutions.QueueManager( classes_names=model.names, reg_pts=region, line_thickness=3, fontsize=1.0, region_color=(255, 144, 31) ) for region in queue_regions] total_count = 0 while cap.isOpened(): success, im0 = cap.read() if success: tracks = model.track(im0, show=False, persist=True, verbose=False) for queue in queues: out = queue.process_queue(im0, tracks) total_count += queue.counts # Accumulate the count from each queue region color_black = (0, 0, 0) cv2.rectangle(im0, (15, 25), (250, 110), (0, 255, 255), -15) cv2.putText(im0, ('Summ - ') + str(total_count), (20, 50), cv2.FONT_HERSHEY_DUPLEX, 0.8, color_black, 2, cv2.LINE_AA) video_writer.write(im0) if cv2.waitKey(1) & 0xFF == ord("q"): break continue print("Video frame is empty or video processing has been successfully completed.") break cap.release() cv2.destroyAllWindows()- Glenn JocherUltralytics
Hi! It looks like the issue might be with how the counts are being accumulated. Ensure that
queue.countsis correctly accessed and reset after each frame. Also, make sure you're using the latest version of the packages. If the problem persists, please provide more details. Happy coding!
QuifaAbas
Despite multiple attempts, I'm still facing the same problem. The code isn't generating the expected results. Even with the provided inputs, the results aren't found. Additionally, when trying to generate a video file, the output turns out to be empty. I input a 2.3 MB video file, and it is not an empty file. The code snippet I've been using is,
Install required packages
!pip install opencv-python torch
Import necessary libraries
from ultralytics import YOLO from ultralytics.solutions import distance_calculation import cv2
Load YOLO model
model = YOLO("/content/drive/MyDrive/YOLOv8_1/Distance/yolov8s.pt") # Update the path to yolov8s.pt names = model.model.names
Load video file
video_path = "/content/drive/MyDrive/YOLOv8_1/Distance/vid2.mp4" # Update the path to your video file cap = cv2.VideoCapture(video_path) assert cap.isOpened(), "Error reading video file" w, h, fps = (int(cap.get(x)) for x in (cv2.CAP_PROP_FRAME_WIDTH, cv2.CAP_PROP_FRAME_HEIGHT, cv2.CAP_PROP_FPS))
Video writer
output_video_path = "/content/drive/MyDrive/YOLOv8_1/Distance/distance_calculation.mp4" video_writer = cv2.VideoWriter(output_video_path, cv2.VideoWriter_fourcc(*'MP4V'), # Or try 'MP4V' for .mp4 files fps, (w, h))
Init distance-calculation obj
dist_obj = distance_calculation.DistanceCalculation() dist_obj.set_args(names=names, view_img=False) # Change view_img to False
while cap.isOpened(): success, im0 = cap.read() if not success: print("End of video or read error encountered.") break
tracks = model.track(im0, persist=True, show=False)

# Check if any tracks were found
if len(tracks) > 0:  # Using len() to get the count of elements
    im0 = dist_obj.start_process(im0, tracks)

    # Debugging: Save frame only if it's not empty
    if im0 is not None and im0.any():
        cv2.imwrite('/content/drive/MyDrive/YOLOv8_1/Distance/Copy of Copy of DJI_0083.JPG', im0)  # Save a frame as an image for debugging
        video_writer.write(im0)
    else:
        print("Empty frame detected. Skipping saving to file.")
else:
    print("No tracks found. Skipping frame processing.")
Release resources
video_writer.release() cap.release()
Provide the download link for the output video
output_video_path
The specific error message I'm receiving is "Empty frame detected. Skipping saving to file. End of video or read error encountered.". Strangely, the resulting video file is only 258 bytes in size, indicating an issue with its generation.
In my pursuit to find a solution, I came across your YouTube video [YouTube Video Link: "https://www.youtube.com/watch?v=LE8am1QoVn4&ab_channel=Ultralytics", where the results showcased are exactly what I'm aiming for. Specifically, I'm keen on measuring the distance between two bounded boxes in both photos and videos.
Could you please provide a YOLOv8 Google Colab code for both video files and image files that addresses these issues and ensures error-free execution?Specifically, I would need two separate codes: one for processing video files and another for processing image files. Could you include instructions on what file paths I should replace in each code?
I've made several attempts to correct and run the code, but unfortunately, I keep encountering the same issue. It seems to persist despite my efforts. I hope you understand my actual problem and can provide a solution that resolves the issue. Could you please provide the complete code along with a detailed explanation to help me better understand and address the problem?
[ I want to attach your comment to my screenshot. How can I do that?I would like to include your comment in my screenshot for reference. Could you please provide guidance on how to attach your comment to the screenshot? ]
- Glenn JocherUltralytics(editado)
It looks like you're encountering a common issue with video processing where no tracks are found and your output frames are empty. Let's try a couple of things to resolve this:
-
Check Video Input: Confirm the video path and contents to ensure it's being read correctly. You have already done this, but double-check if the path is accessible and the video is not corrupted.
-
Model Loading: Verify the model path for loading the YOLO model. Ensure that
yolov8s.ptis the correct model file and path. -
Debugging Output: Try increasing the verbosity of your video processing to get more details:
tracks = model.track(im0, persist=True, show=True, verbose=True) -
Update Your Installation: Ensure your
ultralyticspackage is up to date as fixes are frequently released. Use:pip install --upgrade ultralytics -
Modify Export Code: If the issue persists, simplify the frame processing code to check if any frames are being written to the file at all:
while cap.isOpened(): ret, frame = cap.read() if not ret: break video_writer.write(frame) # write raw frames to see if writing is the issue -
Permissions and Path: Ensure that the output path for your video file is correct and your environment has write permissions for that directory.
Try these steps and see if the issue persists. If it does, you might want to check out a Colab example: Ultralytics YOLO Example Colab.
Regarding attaching a comment to a screenshot, if you're using screenshot tools like Snipping Tool or Snagit, you can usually add text directly on the image. Alternatively, you can use image editing software like Photoshop or free tools like GIMP to add text annotations.
Please let me know if these suggestions help resolve your issues or if there’s anything else I can assist you with!
-
I've attempted to run the code multiple times, but I'm consistently encountering errors. I ran the code that you provided with the suggested changes, but unfortunately, the issue persists. The code I've been using is,
Install required packages
!pip install opencv-python torch !pip install --upgrade ultralytics
Import necessary libraries
from ultralytics import YOLO from ultralytics.solutions import distance_calculation import cv2
Load YOLO model
model = YOLO("/content/drive/MyDrive/YOLOv8_1/Distance/yolov8s.pt") # Update the path to yolov8s.pt names = model.model.names
Load video file
video_path = "/content/drive/MyDrive/YOLOv8_1/Distance/vid2.mp4" # Update the path to your video file cap = cv2.VideoCapture(video_path) assert cap.isOpened(), "Error reading video file" w, h, fps = (int(cap.get(x)) for x in (cv2.CAP_PROP_FRAME_WIDTH, cv2.CAP_PROP_FRAME_HEIGHT, cv2.CAP_PROP_FPS))
Video writer
output_video_path = "/content/drive/MyDrive/YOLOv8_1/Distance/distance_calculation.mp4" video_writer = cv2.VideoWriter(output_video_path, cv2.VideoWriter_fourcc(*'MP4V'), # Or try 'MP4V' for .mp4 files fps, (w, h))
Init distance-calculation obj
dist_obj = distance_calculation.DistanceCalculation() dist_obj.set_args(names=names, view_img=False) # Change view_img to False
while cap.isOpened(): ret, frame = cap.read() if not ret: break video_writer.write(frame) # write raw frames to see if writing is the issue
tracks = model.track(im0, persist=True, show=True, verbose=True)

# Check if any tracks were found
if len(tracks) > 0:  # Using len() to get the count of elements
    im0 = dist_obj.start_process(im0, tracks)

    # Debugging: Save frame only if it's not empty
    if im0 is not None and im0.any():
        cv2.imwrite('/content/drive/MyDrive/YOLOv8_1/Distance/Copy of Copy of DJI_0083.JPG', im0)  # Save a frame as an image for debugging
        video_writer.write(im0)
    else:
        print("Empty frame detected. Skipping saving to file.")
else:
    print("No tracks found. Skipping frame processing.")
Release resources
video_writer.release() cap.release()
Provide the download link for the output video
output_video_path
and the resulting output is,
Requirement already satisfied: torchvision>=0.9.0 in /usr/local/lib/python3.10/dist-packages (from ultralytics) (0.17.1+cu121) Requirement already satisfied: tqdm>=4.64.0 in /usr/local/lib/python3.10/dist-packages (from ultralytics) (4.66.2) Requirement already satisfied: psutil in /usr/local/lib/python3.10/dist-packages (from ultralytics) (5.9.5) Requirement already satisfied: py-cpuinfo in /usr/local/lib/python3.10/dist-packages (from ultralytics) (9.0.0) Requirement already satisfied: thop>=0.1.1 in /usr/local/lib/python3.10/dist-packages (from ultralytics) (0.1.1.post2209072238) Requirement already satisfied: pandas>=1.1.4 in /usr/local/lib/python3.10/dist-packages (from ultralytics) (2.0.3) Requirement already satisfied: seaborn>=0.11.0 in /usr/local/lib/python3.10/dist-packages (from ultralytics) (0.13.1) Requirement already satisfied: contourpy>=1.0.1 in /usr/local/lib/python3.10/dist-packages (from matplotlib>=3.3.0->ultralytics) (1.2.1) Requirement already satisfied: cycler>=0.10 in /usr/local/lib/python3.10/dist-packages (from matplotlib>=3.3.0->ultralytics) (0.12.1) Requirement already satisfied: fonttools>=4.22.0 in /usr/local/lib/python3.10/dist-packages (from matplotlib>=3.3.0->ultralytics) (4.51.0) Requirement already satisfied: kiwisolver>=1.0.1 in /usr/local/lib/python3.10/dist-packages (from matplotlib>=3.3.0->ultralytics) (1.4.5) Requirement already satisfied: numpy>=1.20 in /usr/local/lib/python3.10/dist-packages (from matplotlib>=3.3.0->ultralytics) (1.25.2) Requirement already satisfied: packaging>=20.0 in /usr/local/lib/python3.10/dist-packages (from matplotlib>=3.3.0->ultralytics) (24.0) Requirement already satisfied: pyparsing>=2.3.1 in /usr/local/lib/python3.10/dist-packages (from matplotlib>=3.3.0->ultralytics) (3.1.2) Requirement already satisfied: python-dateutil>=2.7 in /usr/local/lib/python3.10/dist-packages (from matplotlib>=3.3.0->ultralytics) (2.8.2) Requirement already satisfied: pytz>=2020.1 in /usr/local/lib/python3.10/dist-packages (from pandas>=1.1.4->ultralytics) (2023.4) Requirement already satisfied: tzdata>=2022.1 in /usr/local/lib/python3.10/dist-packages (from pandas>=1.1.4->ultralytics) (2024.1) Requirement already satisfied: charset-normalizer<4,>=2 in /usr/local/lib/python3.10/dist-packages (from requests>=2.23.0->ultralytics) (3.3.2) Requirement already satisfied: idna<4,>=2.5 in /usr/local/lib/python3.10/dist-packages (from requests>=2.23.0->ultralytics) (3.7) Requirement already satisfied: urllib3<3,>=1.21.1 in /usr/local/lib/python3.10/dist-packages (from requests>=2.23.0->ultralytics) (2.0.7) Requirement already satisfied: certifi>=2017.4.17 in /usr/local/lib/python3.10/dist-packages (from requests>=2.23.0->ultralytics) (2024.2.2) Requirement already satisfied: filelock in /usr/local/lib/python3.10/dist-packages (from torch>=1.8.0->ultralytics) (3.14.0) Requirement already satisfied: typing-extensions>=4.8.0 in /usr/local/lib/python3.10/dist-packages (from torch>=1.8.0->ultralytics) (4.11.0) Requirement already satisfied: sympy in /usr/local/lib/python3.10/dist-packages (from torch>=1.8.0->ultralytics) (1.12) Requirement already satisfied: networkx in /usr/local/lib/python3.10/dist-packages (from torch>=1.8.0->ultralytics) (3.3) Requirement already satisfied: jinja2 in /usr/local/lib/python3.10/dist-packages (from torch>=1.8.0->ultralytics) (3.1.3) Requirement already satisfied: fsspec in /usr/local/lib/python3.10/dist-packages (from torch>=1.8.0->ultralytics) (2023.6.0) Requirement already satisfied: nvidia-cuda-nvrtc-cu12==12.1.105 in /usr/local/lib/python3.10/dist-packages (from torch>=1.8.0->ultralytics) (12.1.105) Requirement already satisfied: nvidia-cuda-runtime-cu12==12.1.105 in /usr/local/lib/python3.10/dist-packages (from torch>=1.8.0->ultralytics) (12.1.105) Requirement already satisfied: nvidia-cuda-cupti-cu12==12.1.105 in /usr/local/lib/python3.10/dist-packages (from torch>=1.8.0->ultralytics) (12.1.105) Requirement already satisfied: nvidia-cudnn-cu12==8.9.2.26 in /usr/local/lib/python3.10/dist-packages (from torch>=1.8.0->ultralytics) (8.9.2.26) Requirement already satisfied: nvidia-cublas-cu12==12.1.3.1 in /usr/local/lib/python3.10/dist-packages (from torch>=1.8.0->ultralytics) (12.1.3.1) Requirement already satisfied: nvidia-cufft-cu12==11.0.2.54 in /usr/local/lib/python3.10/dist-packages (from torch>=1.8.0->ultralytics) (11.0.2.54) Requirement already satisfied: nvidia-curand-cu12==10.3.2.106 in /usr/local/lib/python3.10/dist-packages (from torch>=1.8.0->ultralytics) (10.3.2.106) Requirement already satisfied: nvidia-cusolver-cu12==11.4.5.107 in /usr/local/lib/python3.10/dist-packages (from torch>=1.8.0->ultralytics) (11.4.5.107) Requirement already satisfied: nvidia-cusparse-cu12==12.1.0.106 in /usr/local/lib/python3.10/dist-packages (from torch>=1.8.0->ultralytics) (12.1.0.106) Requirement already satisfied: nvidia-nccl-cu12==2.19.3 in /usr/local/lib/python3.10/dist-packages (from torch>=1.8.0->ultralytics) (2.19.3) Requirement already satisfied: nvidia-nvtx-cu12==12.1.105 in /usr/local/lib/python3.10/dist-packages (from torch>=1.8.0->ultralytics) (12.1.105) Requirement already satisfied: triton==2.2.0 in /usr/local/lib/python3.10/dist-packages (from torch>=1.8.0->ultralytics) (2.2.0) Requirement already satisfied: nvidia-nvjitlink-cu12 in /usr/local/lib/python3.10/dist-packages (from nvidia-cusolver-cu12==11.4.5.107->torch>=1.8.0->ultralytics) (12.4.127) Requirement already satisfied: six>=1.5 in /usr/local/lib/python3.10/dist-packages (from python-dateutil>=2.7->matplotlib>=3.3.0->ultralytics) (1.16.0) Requirement already satisfied: MarkupSafe>=2.0 in /usr/local/lib/python3.10/dist-packages (from jinja2->torch>=1.8.0->ultralytics) (2.1.5) Requirement already satisfied: mpmath>=0.19 in /usr/local/lib/python3.10/dist-packages (from sympy->torch>=1.8.0->ultralytics) (1.3.0) WARNING ⚠️ Environment does not support cv2.imshow() or PIL Image.show()
NameError Traceback (most recent call last) in <cell line: 31>() 35 video_writer.write(frame) # write raw frames to see if writing is the issue 36 ---> 37 tracks = model.track(im0, persist=True, show=True, verbose=True) 38 39 # Check if any tracks were found
NameError: name 'im0' is not defined
Unfortunately, I'm unable to attach a screenshot directly. Could you please provide the complete code to resolve this issue?
I did try my older code, which is,
Install required packages
!pip install opencv-python torch
Import necessary libraries
from ultralytics import YOLO from ultralytics.solutions import distance_calculation import cv2
Load YOLO model
model = YOLO("/content/drive/MyDrive/YOLOv8_1/Distance/yolov8s.pt") # Update the path to yolov8s.pt names = model.model.names
Load video file
video_path = "/content/drive/MyDrive/YOLOv8_1/Distance/vid2.mp4" # Update the path to your video file cap = cv2.VideoCapture(video_path) assert cap.isOpened(), "Error reading video file" w, h, fps = (int(cap.get(x)) for x in (cv2.CAP_PROP_FRAME_WIDTH, cv2.CAP_PROP_FRAME_HEIGHT, cv2.CAP_PROP_FPS))
Video writer
output_video_path = "/content/drive/MyDrive/YOLOv8_1/Distance/distance_calculation.mp4" video_writer = cv2.VideoWriter(output_video_path, cv2.VideoWriter_fourcc(*'MP4V'), # Or try 'MP4V' for .mp4 files fps, (w, h))
Init distance-calculation obj
dist_obj = distance_calculation.DistanceCalculation() dist_obj.set_args(names=names, view_img=False) # Change view_img to False
while cap.isOpened(): success, im0 = cap.read() if not success: print("End of video or read error encountered.") break
tracks = model.track(im0, persist=True, show=False)

# Check if any tracks were found
if len(tracks) > 0:  # Using len() to get the count of elements
    im0 = dist_obj.start_process(im0, tracks)

    # Debugging: Save frame only if it's not empty
    if im0 is not None and im0.any():
        cv2.imwrite('/content/drive/MyDrive/YOLOv8_1/Distance/Copy of Copy of DJI_0083.JPG', im0)  # Save a frame as an image for debugging
        video_writer.write(im0)
    else:
        print("Empty frame detected. Skipping saving to file.")
else:
    print("No tracks found. Skipping frame processing.")
Release resources
video_writer.release() cap.release()
Provide the download link for the output video
output_video_path
and the resulting output was ,
Requirement already satisfied: nvidia-nccl-cu12==2.19.3 in /usr/local/lib/python3.10/dist-packages (from torch) (2.19.3) Requirement already satisfied: nvidia-nvtx-cu12==12.1.105 in /usr/local/lib/python3.10/dist-packages (from torch) (12.1.105) Requirement already satisfied: triton==2.2.0 in /usr/local/lib/python3.10/dist-packages (from torch) (2.2.0) Requirement already satisfied: nvidia-nvjitlink-cu12 in /usr/local/lib/python3.10/dist-packages (from nvidia-cusolver-cu12==11.4.5.107->torch) (12.4.127) Requirement already satisfied: MarkupSafe>=2.0 in /usr/local/lib/python3.10/dist-packages (from jinja2->torch) (2.1.5) Requirement already satisfied: mpmath>=0.19 in /usr/local/lib/python3.10/dist-packages (from sympy->torch) (1.3.0) WARNING ⚠️ Environment does not support cv2.imshow() or PIL Image.show()
requirements: Ultralytics requirement ['lapx>=0.5.2'] not found, attempting AutoUpdate... Collecting lapx>=0.5.2 Downloading lapx-0.5.8-cp310-cp310-manylinux_2_5_x86_64.manylinux1_x86_64.manylinux_2_17_x86_64.manylinux2014_x86_64.whl (1.7 MB) ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━ 1.7/1.7 MB 14.6 MB/s eta 0:00:00 Requirement already satisfied: Cython>=0.29.32 in /usr/local/lib/python3.10/dist-packages (from lapx>=0.5.2) (3.0.10) Requirement already satisfied: numpy>=1.21.6 in /usr/local/lib/python3.10/dist-packages (from lapx>=0.5.2) (1.25.2) Installing collected packages: lapx Successfully installed lapx-0.5.8
requirements: AutoUpdate success ✅ 8.7s, installed 1 package: ['lapx>=0.5.2'] requirements: ⚠️ Restart runtime or rerun command for updates to take effect
0: 384x640 (no detections), 566.5ms Speed: 29.6ms preprocess, 566.5ms inference, 4702.4ms postprocess per image at shape (1, 3, 384, 640) Empty frame detected. Skipping saving to file.
0: 384x640 (no detections), 436.2ms Speed: 3.1ms preprocess, 436.2ms inference, 0.9ms postprocess per image at shape (1, 3, 384, 640) Empty frame detected. Skipping saving to file.
0: 384x640 (no detections), 410.8ms Speed: 3.4ms preprocess, 410.8ms inference, 1.5ms postprocess per image at shape (1, 3, 384, 640) Empty frame detected. Skipping saving to file.
0: 384x640 1 potted plant, 412.6ms Speed: 3.1ms preprocess, 412.6ms inference, 15.0ms postprocess per image at shape (1, 3, 384, 640) Empty frame detected. Skipping saving to file.
0: 384x640 1 potted plant, 428.9ms Speed: 3.2ms preprocess, 428.9ms inference, 1.3ms postprocess per image at shape (1, 3, 384, 640) Empty frame detected. Skipping saving to file.
0: 384x640 1 potted plant, 545.6ms Speed: 3.8ms preprocess, 545.6ms inference, 1.9ms postprocess per image at shape (1, 3, 384, 640) Empty frame detected. Skipping saving to file.
0: 384x640 (no detections), 546.6ms Speed: 3.0ms preprocess, 546.6ms inference, 1.3ms postprocess per image at shape (1, 3, 384, 640) Empty frame detected. Skipping saving to file.
0: 384x640 (no detections), 626.9ms Speed: 3.6ms preprocess, 626.9ms inference, 1.2ms postprocess per image at shape (1, 3, 384, 640) Empty frame detected. Skipping saving to file.
0: 384x640 (no detections), 631.8ms Speed: 3.4ms preprocess, 631.8ms inference, 1.2ms postprocess per image at shape (1, 3, 384, 640) Empty frame detected. Skipping saving to file. End of video or read error encountered. /content/drive/MyDrive/YOLOv8_1/Distance/distance_calculation.mp4
The specific error message I'm receiving is "Empty frame detected. Skipping saving to file. End of video or read error encountered.". Strangely, the resulting video file is only 258 bytes in size, indicating an issue with its generation.
- Glenn JocherUltralytics(editado)
Hi there! 👋 It seems like you're encountering a persistent issue with detecting objects in your video file. Let's try a couple of adjustments:
-
Ensure Correct Model Load: Double-check if the path to your model (yolov8s.pt) is correct and the model is appropriately loaded.
-
Verify Video Content: Sometimes, if the video does not include the objects the model is trained to detect, it may not find any tracks. Confirm that the target objects are present in the video.
-
Frame Handling: Right before calling the solution (
distancecalculator(frame)), ensure thatframeis your actual frame variable fromret, frame = cap.read(). -
Debugging Output: Increase logging for each step and verify each component's output, such as the captured frames and the model's response.
Here's a simplified snippet to recheck each part:
from ultralytics import solutions

distancecalculator = solutions.DistanceCalculation(model="yolo26n.pt", show=True)  # tracking is handled internally

while cap.isOpened():
    ret, frame = cap.read()
    if not ret:
        print("Failed to read frame.")
        break

    # Debugging: Show frame dimension
    print(f"Frame dimensions: {frame.shape}")

    results = distancecalculator(frame)
    video_writer.write(results.plot_im)

# Cleanup
cap.release()
video_writer.release()
print("Released all resources.")
Adjust the debugging prints as necessary to check the outputs directly. Let me know how it goes, and if there's anything else I can help with! 🚀
-
I have zero knowledge in YOLOv8, as I'm an undergraduate student in Electrical Engineering. My final year project topic is 'Unmanned Aerial Systems (UAS) for Enhanced Vegetation Management in Electric Distribution Networks'. Initially, I aimed to detect vegetation and power lines in single frames. I successfully achieved this using YOLOv8 in Google Colab for images. However, I encountered difficulties when applying the same approach to videos, particularly in detecting power lines accurately.
To enhance the accuracy of power line detection, I plan to collect more photos using a drone. Additionally, I aim to measure the distance between vegetation and power lines. Despite my efforts, I've faced repeated challenges in implementing these tasks.
I have shared a link to my Google Drive , which contains my files. Within this folder, I've included one of the best detection images, the detected video, the final output, and my code.
I kindly request two separate complete codes—one for image tracking and another for video tracking. As I have minimal knowledge about where to make changes in the code, it would greatly assist me if you could run the code using my data and provide the necessary adjustments.
- Glenn JocherUltralytics(editado)
Hello! 🚀 It's great to see you using YOLOv8 for your project on unmanned aerial systems for vegetation management. Since you're encountering issues with power line detection in videos, here are a few suggestions:
-
Data Collection: Collecting more diverse images of power lines and vegetation at different times and conditions will definitely help in improving the model's accuracy.
-
Annotation Quality: Ensure that your additional images are accurately annotated to improve learning during training.
-
Model Training for Video: Although you've successfully used YOLOv8 for single frame detections, video processing can be trickier due to motion and different angles. Consider using techniques like temporal smoothing or frame-to-frame tracking to enhance accuracy.
Here's a basic outline on how you could set up your code for video processing using your own data:
import cv2
from ultralytics import YOLO

# Load your pre-trained model
model = YOLO("/path/to/your/model.pt")

# Setup the video capture
cap = cv2.VideoCapture("/path/to/your/video.mp4")
while cap.isOpened():
    ret, frame = cap.read()
    if not ret:
        break

    # Detect objects in the frame
    results = model.predict(frame)

    # Optionally, visualize the results
    annotated_frame = results[0].plot()  # frame with the detections drawn
    cv2.imshow('YOLO Detections', annotated_frame)
    if cv2.waitKey(1) & 0xFF == ord('q'):
        break

cap.release()
cv2.destroyAllWindows()
For measuring distances between detected objects like vegetation and power lines, you'd have to post-process the detection bounding boxes from YOLOv8. Calculating distances could be based on known scales or additional sensors like LiDAR data if your drone setup permits.
If you have any more questions or need further assistance with your code, feel free to ask. Best of luck with your exciting project! 🌿⚡
-
I've tried multiple times, but I haven't been successful in getting the distance calculation code to work properly.
-
Could you please ensure that the distance calculation code is implemented correctly for both my image and video files? [I have asked multiple times for you in providing separate code for processing my image and video files. However, you have only provided code for the video file. As I have zero knowledge in YOLOv8 coding, it's challenging for me to adapt the provided code for my image files. I kindly request your understanding of my situation and would greatly appreciate separate code for both image and video files.]
-
Once you've done so, Could you please provide the results for both my video and image files, which I have attached in the Google Drive folder?
-
Can you share these results with me via your Google Drive link?
I have a tight deadline to complete my project within this week, and your assistance would be immensely valuable. Thank you for understanding my situation. I am seeking results that accurately measure the distance between the vegetation bounded box and powerline bounded box in both my input image and input video. The desired outcome is to achieve results that closely resemble the accuracy and presentation demonstrated in your YouTube video (https://www.youtube.com/watch?v=LE8am1QoVn4&t=5s&ab_channel=Ultralytics).
I have clearly articulated my problem and outlined my specific requests. I kindly request your attention to my three requests and urge you to help me resolve my problem. 🥰
-
- Glenn JocherUltralytics(editado)
Hello! Thanks for sharing the details and your Google Drive link. It sounds like you're facing a challenge with adapting the distance calculation code specifically for images, along with your existing video processing.
For processing images separately, you can follow a similar approach as with videos but adapted for single-frame use. Here is a simplified code snippet that processes individual images:
from ultralytics import YOLO
import cv2

# Load the model
model = YOLO('path/to/your/model.pt')

# Load an image
image_path = 'path/to/your/image.jpg'
image = cv2.imread(image_path)

# Predict using the model
results = model.predict(image)

# Display detected objects with bounding boxes
results[0].show()
For the videos, if the provided code doesn't meet expectations, it helps to first manually check a few frames to understand what's missing or incorrect. This could be due to various factors such as the model's sensitivity, training data, or the quality/resolution of the video frame.
I've noticed your tight deadline and understand the importance of precise and timely responses. Please check the code above, and let's ensure it aligns with your project's requirements. If you need adjustments or further assistance, feel free to let me know! 🌟
Once again, I am encountering a problem. I have attached a screenshot of the error I'm facing, along with the image for which I want to measure the distance between the vegetation and powerline. Initially, could you please provide me with the tracked image? Subsequently, I will require the results image corresponding to the attached image. Following that, kindly provide the code necessary to achieve this task.
- Glenn JocherUltralytics(editado)
@QuifaAbas hello! Thanks for reaching out and sharing the details and your screenshot. It seems like you're looking to measure distances between detected objects in an image, which is a great application of YOLOv8.
For measuring distances, we would typically process the output of the detection model to obtain bounding boxes, and then calculate the distances based on these coordinates.
Here's a simplified approach to get you started with the image processing:
from ultralytics import YOLO
import cv2

# Load your pre-trained model
model = YOLO('path/to/your/model.pt')

# Load your image
image = cv2.imread('path/to/your/image.jpg')

# Perform detection
results = model.predict(image)

# Extract bounding boxes (for example, for vegetation and power lines)
result = results[0]
for box in result.boxes:
    name = result.names[int(box.cls)]
    if name == 'vegetation':  # replace with your actual class
        veg_box = box.xyxy[0].tolist()  # x1, y1, x2, y2
    elif name == 'power line':  # replace with your actual class
        pline_box = box.xyxy[0].tolist()  # x1, y1, x2, y2

# Calculate distances between objects (simplified Euclidean distance)
distance = ((veg_box[0] - pline_box[0])**2 + (veg_box[1] - pline_box[1])**2)**0.5

# Draw results on image
annotated_image = result.plot()

# Save or display the annotated image
cv2.imwrite('output.jpg', annotated_image)
cv2.imshow('Distance Detection', annotated_image)
cv2.waitKey(0)
cv2.destroyAllWindows()
For video files, you can follow a similar approach by processing each frame for detections and computing distances as outlined above.
If you need further customization or assistance, we're here to help! 🚀
Once again, I am encountering a problem. I have attached a screenshot of the error I'm facing, along with the image for which I want to measure the distance between the vegetation and powerline. My objective is to detect and measure distances between power lines and vegetation. Initially, could you please provide me with the tracked image? Subsequently, I will require the results image corresponding to the attached image. Following that, kindly provide the code necessary to achieve this task.
- Glenn JocherUltralytics(editado)
Hello! 🚀 It looks like you've run into some challenges with error handling and distance measurements between detected objects in your images. Let's tackle this step by step.
To help you measure the distances between detected vegetation and power lines in the image, you can utilize the coordinates of the bounding boxes provided by the YOLOv8 detections. Here's a simple code snippet to get you started:
from ultralytics import YOLO
import cv2

# Load your model
model = YOLO('path/to/your/yolov8-model.pt')

# Load your image
image = cv2.imread('path/to/your/image.jpg')

# Detect objects
results = model.predict(image)

# Draw boxes and labels on the image
results[0].show()

# Save or display the image
cv2.imwrite('tracked_image.jpg', results[0].plot())

# Extract bounding boxes for specific classes
veg_boxes = [b.xyxy[0].tolist() for b in results[0].boxes if results[0].names[int(b.cls)] == 'Vegetation']
pline_boxes = [b.xyxy[0].tolist() for b in results[0].boxes if results[0].names[int(b.cls)] == 'Power Line']

# Assuming you want the distance between the closest points, calculate Euclidean distance
from scipy.spatial import distance
if veg_boxes and pline_boxes:
    veg_point = veg_boxes[0][:2]  # Example: top-left corner of the first vegetation box
    pline_point = pline_boxes[0][:2]  # Example: top-left corner of the first powerline box
    dist = distance.euclidean(veg_point, pline_point)
    print(f"Distance between closest points: {dist} pixels")
Make sure to modify the
path/to/your/yolov8-model.ptandpath/to/your/image.jpgaccording to your files. This code will print the Euclidean distance between the top left corners of the first detected vegetation and power line boxes.I hope this helps! Start with this basic functionality and you can tune further based on your project needs. Let me know if there are specific aspects you want to adjust or if you encounter further issues! 🌿⚡