Exportação para Tencent NCNN
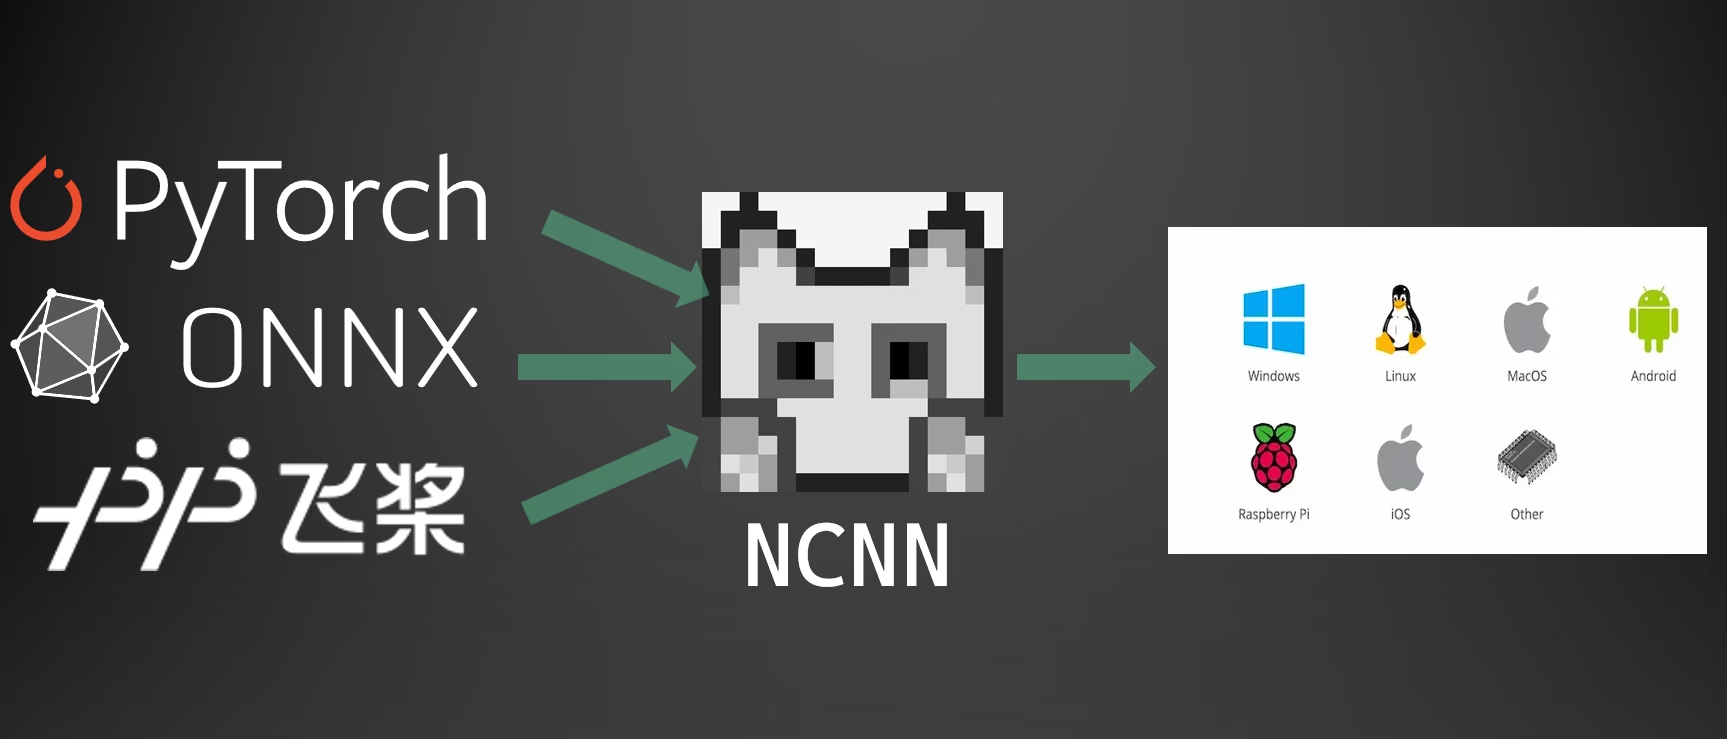
NCNN é uma estrutura de inferência de redes neurais de código aberto da Tencent para telemóveis, placas integradas e computadores de secretária. Exportar um modelo Ultralytics YOLO26 com format="ncnn" cria um diretório yolo26n_ncnn_model/ que contém a rede como um par de ficheiros .param e .bin, com pesos FP32 ou FP16.
Visão geral#
| Propriedade | Detalhes |
|---|---|
Argumento format | ncnn |
| Saída | yolo26n_ncnn_model/, um diretório com model.ncnn.param, model.ncnn.bin, model_ncnn.py e metadata.yaml |
| Funciona em | CPUs ARM e x86-64, e GPUs com um controlador Vulkan: telemóveis, computadores de placa única como o Raspberry Pi e computadores de secretária |
| Ambiente de execução | NCNN: o pacote Python ncnn ou a biblioteca C++ NCNN em aplicações Android, iOS e integradas |
| Precisão | Pesos FP32 ou FP16; não existe exportação INT8. O YOLO26n tem 9.8 MB em FP32 e 5.0 MB com pesos FP16 |
| Máquina de exportação | Linux x86-64 ou ARM64, macOS ou Windows x64, as plataformas para as quais pnnx disponibiliza compilações. A exportação não precisa de GPU |
A Ultralytics Platform pode exportar um modelo treinado para NCNN por ti, por isso não precisas de um ambiente de exportação local.
Início rápido#
Instale o pacote Ultralytics:
pip install ultralyticsA primeira exportação instala os pacotes ncnn e pnnx se estiverem em falta, e a primeira previsão com um modelo exportado instala ncnn se estiver em falta. Um ambiente novo não precisa de mais nada: a primeira exportação é concluída na mesma execução, depois de registar Restart runtime or rerun command for updates to take effect. A exportação tem estes requisitos de versão:
| Pacote | Versão necessária |
|---|---|
pnnx | Exatamente 20260526. A exportação instala esta versão e substitui qualquer outra |
ncnn | Qualquer versão |
torch | 2.0 ou posterior: a exportação não verifica a versão, e os testes da Ultralytics ignoram NCNN em versões anteriores porque a inferência falhava |
Para outros métodos de instalação, consulta o guia de instalação. Depois, exporta o teu modelo e carrega o diretório exportado para executar inferência ou validar a sua precisão.
from ultralytics import YOLO

# Carrega um modelo YOLO26
model = YOLO("yolo26n.pt")

# Exportar o modelo para o formato NCNN
model.export(format="ncnn")  # creates 'yolo26n_ncnn_model/'

# Ou exporta com pesos FP16, o que reduz o tamanho do ficheiro para metade
model.export(format="ncnn", quantize=16)  # creates 'yolo26n_ncnn_model/'
Ambas as exportações gravam o mesmo diretório yolo26n_ncnn_model/, por isso a segunda substitui a primeira.
from ultralytics import YOLO

# Carregar o modelo NCNN exportado
model = YOLO("yolo26n_ncnn_model")

# Executar inferência
results = model("https://ultralytics.com/images/bus.jpg")from ultralytics import YOLO
# Carregar o modelo NCNN exportado
model = YOLO("yolo26n_ncnn_model")
# Validar a precisão no conjunto de dados COCO8
metrics = model.val(data="coco8.yaml")Tarefas suportadas#
A exportação para NCNN suporta todas as sete tarefas da Ultralytics com modelos YOLOv8, YOLO11 e YOLO26: deteção, segmentação, segmentação semântica, estimativa de profundidade, classificação, estimativa de pose e OBB. A segmentação semântica e a estimativa de profundidade só estão disponíveis com YOLO26, a única família que inclui essas cabeças. Também é possível exportar modelos de deteção YOLOv5u, YOLOv9, YOLOv10 e YOLO12. Os modelos RT-DETR, YOLO-World e YOLOE com prompt de texto não são convertidos; consulta Limitações e resolução de problemas.
Argumentos de exportação#
| Argumento | Tipo | Padrão | Descrição |
|---|---|---|---|
format | str | 'ncnn' | Formato de destino do modelo exportado, que define a compatibilidade com vários ambientes de implantação. |
imgsz | int ou tuple | 640 | Tamanho da imagem de entrada do modelo, fixado no modelo exportado: um número inteiro para imagens quadradas ou uma tupla (height, width). Se não for especificado, a exportação utiliza o tamanho com que o checkpoint foi treinado. Os checkpoints oficiais YOLO26 utilizam 640 para modelos de deteção, segmentação e pose e para modelos semânticos pré-treinados no ADE20K, 1024 para modelos OBB e modelos semânticos pré-treinados no Cityscapes, 768 para profundidade e 224 para classificação. |
quantize | int ou str | None | Precisão dos pesos armazenados: 16 (FP16) reduz para metade o tamanho do ficheiro; 32/não definido corresponde a FP32. 8 gera um erro, e não é possível exportar para NCNN um checkpoint treinado com quantize=8; consulta Limitações e resolução de problemas. Substitui a opção obsoleta half. |
nms | bool, opcional | None | Os modelos NCNN devolvem sempre previsões em bruto para aplicar NMS externamente. A cabeça sem NMS (False) e a NMS incorporada (True) não estão disponíveis; consulta Limitações e resolução de problemas. |
device | str | None | Dispositivo que rastreia o modelo durante a conversão: cpu (a predefinição, também numa máquina com GPU), 0 para uma GPU CUDA ou mps para Apple silicon. |
Dos argumentos de exportação específicos do formato, o NCNN só aceita estes. Para os argumentos comuns a todos os formatos, consulta a documentação do modo de exportação.
Precisão#
quantize define como os pesos são armazenados em model.ncnn.bin. Os tamanhos correspondem a um modelo de deteção YOLO26n exportado em imgsz=640:
quantize | Pesos | Tamanho do YOLO26n |
|---|---|---|
omitido ou 32 | FP32 | 9.8 MB |
16 | FP16 | 5.0 MB |
- Pesos FP16:
quantize=16armazena os pesos em precisão de meia e não precisa de dados de calibração. A entrada e as saídas continuam a serfloat32, pelo que o código de inferência escrito para o modelo FP32 funciona sem alterações. - Precisão: no COCO val2017, numa CPU de servidor x86-64, os modelos NCNN FP32 e FP16 do YOLO26n, o modelo ONNX e o modelo PyTorch (
rect=False) atingiram todos 40.9 mAPval 50-95 com a mesma entrada de 640x640. - Cálculo FP16: o NCNN também pode efetuar cálculos em precisão de meia, independentemente da precisão dos pesos armazenados. Num Apple M4, fê-lo por predefinição em ambas as exportações: numa imagem de teste, as coordenadas brutas das caixas da exportação FP32 diferiram no máximo cerca de 2.1 píxeis do modelo ONNX para âncoras com confiança superior a 0.25, e a saída completa correspondeu à do modelo com uma diferença inferior a 0.01 quando
net.opt.use_fp16_storage = Falseestava definido no pacote ncnn. Numa CPU de servidor x86-64, as saídas brutas da exportação FP32 diferiram menos de 0.03 do modelo ONNX na mesma imagem, para modelos de deteção, segmentação, profundidade, classificação, pose e OBB. Com pesos FP16, as coordenadas das caixas dessas âncoras diferiram das do ONNX cerca de 0.3 píxeis no servidor e 1.6 píxeis no M4. No M4, estas diferenças alteraram a precisão em menos de 0.1: no COCO128, o validador da Ultralytics obteve 47.7 mAP 50-95 para a exportação FP32 e 47.7 com pesos FP16, face a 47.7 para o modelo PyTorch (rect=False) com a mesma entrada de 640x640.
Formato de saída#
A exportação grava um diretório:
| Ficheiro | Conteúdo |
|---|---|
model.ncnn.param | O grafo da rede num ficheiro de texto |
model.ncnn.bin | Os pesos |
model_ncnn.py | Um script Python escrito pelo PNNX que executa o modelo com uma entrada aleatória utilizando o pacote ncnn |
metadata.yaml | Nomes das classes, tarefa, tamanho da imagem, tamanho do lote, stride e argumentos de exportação, que Ultralytics lê ao carregar o modelo |
A exportação também deixa uma pasta __pycache__ no diretório, que podes eliminar. O modelo recebe uma entrada chamada in0 com a forma (3, height, width): uma imagem RGB, canais primeiro, float32, escalada para 0-1. Não existe dimensão de lote, e as saídas também não a têm. As formas abaixo correspondem aos checkpoints oficiais YOLO26n com o tamanho de exportação predefinido, usando o checkpoint Cityscapes yolo26n-sem.pt para segmentação semântica:
| Tarefa | imgsz padrão | Saídas |
|---|---|---|
| Detecção | 640 | out0 (84, 8400) |
| Segmentação | 640 | out0 (116, 8400) e out1 (32, 160, 160) |
| Semântica | 1024 | out0 (19, 1024, 1024), uma pontuação para cada classe e píxel |
| Profundidade | 768 | out0 (1, 768, 768), mapa de profundidade |
| Classificação | 224 | out0 (1000,), probabilidades das classes |
| Pose | 640 | out0 (56, 8400) |
| OBB | 1024 | out0 (20, 21504) |
- Previsões em bruto: os modelos de deteção, segmentação, pose e OBB devolvem as mesmas previsões em bruto que uma exportação ONNX predefinida, sem a dimensão de lote: para cada âncora, o centro x da caixa, o centro y, a largura e a altura em píxeis da entrada, seguidos pelas pontuações das classes e pelos valores da tarefa (32 coeficientes de máscara, 17 x 3 valores de pontos-chave ou o ângulo OBB em radianos). Aplica NMS por tua conta.
- Segmentação:
out0contém as previsões eout1os protótipos das máscaras. - Segmentação semântica: a saída contém uma pontuação para cada classe e píxel, não o mapa de classes da exportação ONNX; por isso, calcule o argmax no eixo das classes no seu próprio código.
- NMS: não há saída sem NMS nem com NMS incorporada; consulte Limitações e resolução de problemas.
YOLO("yolo26n_ncnn_model") lê o esquema de metadata.yaml, adiciona a dimensão de lote e aplica NMS, pelo que só precisas destes detalhes se executares o modelo no teu próprio código. As chaves de metadata.yaml incluem names, task, imgsz, stride, batch, end2end, args e, para modelos de pose, kpt_shape.
Executar com o pacote ncnn#
Para executar o modelo fora do pacote Ultralytics, carrega os dois ficheiros com o pacote Python ncnn. Os mesmos ficheiros .param e .bin podem ser carregados na biblioteca NCNN C++ em Android, iOS e Linux incorporado.
# Exporta primeiro: yolo export model=yolo26n.pt format=ncnn
import ncnn
import numpy as np

net = ncnn.Net()
net.opt.num_threads = 4  # define as opções antes de carregar o modelo
assert net.load_param("yolo26n_ncnn_model/model.ncnn.param") == 0
assert net.load_model("yolo26n_ncnn_model/model.ncnn.bin") == 0

image = np.zeros((3, 640, 640), dtype=np.float32)  # a tua imagem com letterbox: RGB, CHW, 0-1
with net.create_extractor() as ex:
    ex.input("in0", ncnn.Mat(image).clone())
    _, out0 = ex.extract("out0")
predictions = np.array(out0)  # forma (84, 8400), previsões em bruto que precisam de NMS
assert predictions.shape == (84, 8400), "export a detection model at imgsz=640"
ncnn.Mat(image) lê a memória do array NumPy sem a copiar, por isso passa um array float32 contíguo em C e mantém-no ativo até a extração terminar, ou copia-o com .clone(), como acima. Um array criado com transpose não é contíguo, e astype ou uma divisão aplicada depois mantém esse esquema; por isso, termina o pré-processamento com np.ascontiguousarray(x, dtype=np.float32). Num teste com este modelo, um array não contíguo foi executado sem erro e devolveu previsões incorretas, e um array float64 fez o Python falhar.
Implantar#
No dispositivo de destino, instala o pacote com pip install ultralytics e copia para lá o diretório yolo26n_ncnn_model/. Em seguida, YOLO("yolo26n_ncnn_model") executa o modelo com o pacote Python ncnn, que a Ultralytics instala na primeira utilização. O argumento device seleciona onde o NCNN é executado:
device | Onde o modelo é executado |
|---|---|
omitido ou cpu | NCNN na CPU |
vulkan:0, vulkan:1, ... | NCNN no dispositivo Vulkan com esse índice; consulta Inferência de GPU com Vulkan |
0 numa máquina com uma GPU CUDA | NCNN na CPU: o NCNN não tem backend CUDA |
mps em Apple silicon | NCNN na CPU, enquanto a Ultralytics efetua o pré-processamento e o pós-processamento na GPU Apple. Num M4, isto acrescentou cerca de 0.6 s à primeira imagem e não acelerou a inferência; por isso, deixa device sem definir |
- Forma de entrada fixa: o modelo é sempre executado com
imgszda exportação, que a Ultralytics lê demetadata.yaml. Umimgszpassado apredictouvalé ignorado. Volta a exportar para alterar o tamanho da imagem. - Lotes: o modelo recebe uma imagem e a Ultralytics executa as imagens de um lote uma a uma, pelo que funciona com qualquer número de imagens.
valdefinebatch=1, independentemente do valor que passes. - Threads da CPU: O próprio NCNN escolhe o número de threads: 4 num Apple M4, o número de núcleos de desempenho do processador. No Linux, a Ultralytics limita esse número a 8 e às CPUs que o processo pode usar: a afinidade da CPU (
taskset, Docker--cpuset-cpus) e uma quota de CPU do cgroup v2 (Docker--cpus). Consulta Limitações e resolução de problemas para usar um número diferente.
Inferência de GPU com Vulkan#
O NCNN é executado em GPUs através de Vulkan, que funciona com fabricantes de GPU como AMD, Intel, ARM, Qualcomm e Apple, sem CUDA. Passa device="vulkan:0" para o primeiro dispositivo Vulkan ou vulkan:1 para o segundo:
from ultralytics import YOLO

# Carregar o modelo NCNN exportado
model = YOLO("yolo26n_ncnn_model")

# Executa a inferência no primeiro dispositivo Vulkan
results = model("https://ultralytics.com/images/bus.jpg", device="vulkan:0")
A GPU precisa de um controlador Vulkan, incluído na maioria dos controladores de GPU atuais; no Linux, vulkaninfo lista os controladores instalados. O índice conta os dispositivos Vulkan encontrados pelo NCNN, que não têm necessariamente de ser GPUs de hardware. Lista-os antes de confiares no resultado:
import ncnn

for i in range(ncnn.get_gpu_count()):
    print(i, ncnn.get_gpu_info(i).device_name())
Vulkan nem sempre é mais rápido do que a CPU. Num Apple M4, o YOLO26n demorou cerca de 31 ms por imagem no dispositivo Vulkan e cerca de 12 ms na CPU. Mede o desempenho no teu dispositivo.
Guias de implantação#
- Raspberry Pi: configura a Ultralytics em placas Raspberry Pi; o guia exporta para NCNN diretamente na placa.
- NVIDIA Jetson: NCNN na CPU ARM dos dispositivos Jetson, além do TensorRT na GPU.
- Instruções de compilação do NCNN: compila a biblioteca NCNN C++ para Android, iOS, Linux, macOS, Windows e outros destinos.
- NCNN no GitHub: o código-fonte, o pacote Python e exemplos C++.
- Exemplo de interface de acompanhamento interativa: um exemplo da Ultralytics que executa modelos NCNN em dispositivos que só têm CPU.
- Opções de implementação de modelos: compara o NCNN com os outros formatos de exportação.
Limitações e solução de problemas#
- INT8:
quantize=8falha comquantize=8 (INT8) is not supported; format='ncnn' supports quantize=16 (FP16), 32 or None (FP32).. Usa FP16 para reduzir o tamanho do ficheiro ou um formato com exportação INT8, como LiteRT ou MNN. - Checkpoints treinados com
quantize=8: um checkpoint ajustado com treino com consciência da quantização falha comformat='ncnn' cannot export a QAT model: its Q/DQ ranges are only read by the 'onnx' and 'engine' backends. Em vez disso, exporta o checkpoint usado para iniciar o ajuste fino ou exporta o checkpoint ajustado para ONNX ou TensorRT. - Cabeça sem NMS: os modelos NCNN devolvem sempre previsões em bruto que precisam de NMS. Com
nms=False, a exportação de um modelo YOLO26 ou YOLOv10 registaThis export format does not support end2end models, disabling the end2end branch.e utiliza a cabeça um-para-muitos; para outros modelos de deteção, segmentação, pose e OBB, como o YOLO11, registaThis model has no one-to-one head; using one-to-many outputs. - NMS incorporada:
nms=Trueregistaformat=ncnn does not support embedded NMS; exporting native outputs for external NMS.e grava a saída bruta. - Forma de entrada e tamanho do lote fixos:
dynamic=Truefalha comargument 'dynamic' is not supported for format='ncnn', e umbatchdiferente de 1 falha comargument 'batch' is not supported for format='ncnn'. Volta a exportar para alterar o tamanho da imagem. - Modelos que não são convertidos: a exportação de modelos RT-DETR (
rtdetr-l.pt), YOLO-Worldv2 (yolov8s-worldv2.pt) e YOLOE com prompt de texto (yoloe-26s-seg.pt) falha comNCNN failed to load the exported model, it may contain layers NCNN does not support.. Um modelo YOLOE com prompt de texto pode ser exportado depois de corrigires as classes comset_classes(), e o modeloyoloe-26s-seg-pf.ptsem prompt pode ser exportado tal como está. - Versão do PNNX: a exportação requer
pnnx20260526 e substitui uma versão mais recente, porque os modelos convertidos com PNNX 20260704 falham durante a inferência. - Instalação automática desativada: com
YOLO_AUTOINSTALL=false, a exportação falha comNo module named 'ncnn'num ambiente sem os pacotes. Instala-os compip install --no-deps ncnnepip install pnnx==20260526. - Número de threads:
predictevalnão têm um argumento para definir o número de threads do NCNN, e a variávelOMP_NUM_THREADSnão o altera. No Linux, a Ultralytics usa no máximo 8 threads, e os modelos maiores podem ser executados mais rapidamente com mais threads em máquinas com mais núcleos: ao executar com o pacote ncnn em 16 núcleos de um AMD EPYC 9655, o YOLO26x levou cerca de 177 ms por imagem com 8 threads e cerca de 154 ms com 16, enquanto o YOLO26n levou cerca de 23 ms com qualquer uma das configurações. Para escolher o número de threads, executa o modelo com o pacote ncnn e definenet.opt.num_threadsantes de o modelo carregar. Alterarnum_threadsdepois de o modelo ter carregado tornou a inferência mais lenta. - Diretório de modelo incompleto: se
model.ncnn.binestiver em falta ou incompleto, por exemplo, após uma cópia interrompida para o dispositivo, o Python termina com uma falha de segmentação e sem traceback. As últimas linhas da saída indicam a causa:fopen yolo26n_ncnn_model/model.ncnn.bin failedouModelBin read weight_data failed. Um diretório semmodel.ncnn.paramfalha comStopIteration. Copia novamente o diretório. device="vulkan"sem índice: falha comIndexError: list index out of range. Escreve o índice, como emdevice="vulkan:0".- O dispositivo Vulkan não é uma GPU: no servidor Linux utilizado nesta página, o único dispositivo Vulkan listado pelo NCNN era
llvmpipe, um renderizador de software executado na CPU.device="vulkan:0"é então executado sem erro e sem GPU. Um índice inexistente, comovulkan:9numa máquina com um dispositivo, também não gera erro. - Diretório de saída: cada exportação de um checkpoint grava o mesmo diretório
yolo26n_ncnn_model/, independentemente dequantizeouimgsz; por isso, a exportação seguinte substitui a anterior. Muda o nome do diretório para manter ambos e inclui_ncnn_modelno nome, por exemployolo26n_fp16_ncnn_model/, porque a Ultralytics identifica o formato através desse nome. Um diretório sem esse elemento, ou o caminho do ficheiro.param, falha comis not a supported model format.
Para outros erros, consulte o guia de problemas comuns.
Benchmarks#
A Ultralytics publica benchmarks NCNN para duas plataformas ARM. Os benchmarks do Raspberry Pi 5 comparam o NCNN com outros sete formatos para YOLO26n e YOLO26s, e os benchmarks do NVIDIA Jetson incluem o NCNN para os cinco modelos de deteção YOLO26. A página do modelo YOLO26 apresenta a precisão dos checkpoints PyTorch.
Os tamanhos dos modelos de deteção YOLO26 exportados, calculados como a soma de model.ncnn.param e model.ncnn.bin em MB (10^6 bytes) em imgsz=640. O registo da exportação apresenta o tamanho do diretório completo em MiB: 9.4 MB e 4.8 MB para YOLO26n:
| Modelo | PyTorch | NCNN FP32 | NCNN FP16 |
|---|---|---|---|
| YOLO26n | 5.5 | 9.8 | 5.0 |
| YOLO26s | 20.4 | 38.1 | 19.2 |
| YOLO26m | 44.3 | 81.8 | 41.0 |
| YOLO26l | 53.2 | 99.4 | 49.8 |
| YOLO26x | 118.7 | 223.0 | 111.7 |
Exportado com ultralytics 8.4.215, NCNN 1.0.20261020 e PNNX 20260526, a 16 de novembro de 2026.
Sobre o NCNN#
O NCNN é desenvolvido pela Tencent e utilizado em aplicações da Tencent, como QQ e WeChat. Não tem dependências de runtime de terceiros, funciona em CPUs e em GPUs através de Vulkan e converte modelos PyTorch com a ferramenta PNNX, utilizada pela exportação da Ultralytics. Para consultar a referência completa, vê a documentação do NCNN.
Perguntas frequentes#
Usa FP16 (
quantize=16) quando o tamanho do modelo for importante: o YOLO26n ocupa 5.0 MB com pesos FP16, em comparação com 9.8 MB em FP32, e não precisa de dados de calibração. No COCO val2017, o YOLO26n atingiu os mesmos 40.9 mAPval 50-95 com pesos FP16 e FP32. Os pesos FP16 reduzem o tamanho do ficheiro, mas não tornam o modelo mais rápido: o NCNN escolhe a precisão de cálculo com base no hardware; consulta Precisão. Valida o modelo exportado com os teus próprios dados e dispositivo antes de o implementar.Os pacotes
pnnxencnntêm compilações para Linux ARM de 64 bits, e o guia do Raspberry Pi explica como exportar na placa com o mesmo comandoformat="ncnn". Também podes exportar num PC e copiar o diretórioyolo26n_ncnn_model/para a placa. Num sistema ARM de 32 bits,pnnxnão tem uma compilação, por isso exporta noutra máquina;ncnntem compilações para esse sistema, mas a Ultralytics não o testou.Compila ou transfere a biblioteca NCNN para a tua plataforma, conforme descrito nas instruções de compilação do NCNN, adiciona
model.ncnn.paramemodel.ncnn.binà aplicação e fornece a entradain0conforme descrito em Formato de saída. O teu código tem de aplicar letterbox à imagem, descodificar as previsões em bruto e aplicar NMS. Se preferires um componente de aplicação pronto a utilizar, o plugin Ultralytics YOLO para Flutter executa exportações LiteRT em Android e exportações Core ML em iOS.O NCNN foi desenvolvido para CPUs ARM de telemóveis e placas integradas. Num servidor com dois processadores AMD EPYC 9655 de 96 núcleos, o YOLO26n levou cerca de 30 ms por imagem com o NCNN em 8 threads, em comparação com cerca de 13 ms tanto com PyTorch como com ONNX Runtime; num Apple M4, onde o NCNN escolhe 4 threads, levou cerca de 12 ms. Para servidores x86-64, OpenVINO e ONNX são os formatos que a Ultralytics compara em benchmarks.


Comentários37
Faz uma pergunta, partilha os teus resultados ou ajuda alguém.
gpsamt(editado)
I'm testing the use of ncnn on android. I converted a yolov11 model. I've tried every way to adjust the code, but I can't. The detections are not coming out correctly. The ncnn model on windows works as can be seen in the image. I'm sharing my native code in c++. If anyone can help me I'd really appreciate it.
Image detected with yolo predict model=C:\Users\guips\Downloads\best_ncnn_model source="C:\Users\guips\Downloads\brasil\test822.jpg" save_txt=true
#include <jni.h> #include <android/log.h> #include #include #include #include <opencv2/opencv.hpp> #include <ncnn/net.h> // #include <stb_image.h> // Uncomment if using stb_image
#define LOG_TAG "NCNN_DETECTOR" #define LOGD(...) __android_log_print(ANDROID_LOG_DEBUG, LOG_TAG, VA_ARGS) #define LOGI(...) __android_log_print(ANDROID_LOG_INFO, LOG_TAG, VA_ARGS) #define LOGE(...) __android_log_print(ANDROID_LOG_ERROR, LOG_TAG, VA_ARGS)
static ncnn::Net g_net; static std::vectorstd::string g_labels; static bool g_model_loaded = false;
struct Detection { float x, y, width, height; int label; float prob; };
static float sigmoid(float x) { return 1.0f / (1.0f + std::exp(-x)); }
static float calculate_iou(const Detection& a, const Detection& b) { float x1 = std::max(a.x, b.x); float y1 = std::max(a.y, b.y); float x2 = std::min(a.x + a.width, b.x + b.width); float y2 = std::min(a.y + a.height, b.y + b.height);
float inter_area = std::max(0.0f, x2 - x1) * std::max(0.0f, y2 - y1);
float union_area = a.width * a.height + b.width * b.height - inter_area;

return union_area > 0 ? inter_area / union_area : 0.0f;
}
extern "C" JNIEXPORT jboolean JNICALL Java_com_example_ncnnmy_1ok_MainActivity_loadModel( JNIEnv* env, jobject thiz, jstring param_path, jstring bin_path, jstring labels_path) {
const char* param_path_str = env->GetStringUTFChars(param_path, nullptr);
const char* bin_path_str = env->GetStringUTFChars(bin_path, nullptr);
const char* labels_path_str = env->GetStringUTFChars(labels_path, nullptr);

LOGI("Starting model loading...");
LOGD("Param path: %s", param_path_str);
LOGD("Bin path: %s", bin_path_str);
LOGD("Labels path: %s", labels_path_str);

g_net.clear();
g_labels.clear();
g_model_loaded = false;

g_net.opt.num_threads = 4;
g_net.opt.use_vulkan_compute = false;
g_net.opt.use_fp16_packed = false;
g_net.opt.use_fp16_storage = false;
g_net.opt.use_fp16_arithmetic = false;

int ret = g_net.load_param(param_path_str);
if (ret != 0) {
    LOGE("Failed to load .param file (%d)", ret);
    env->ReleaseStringUTFChars(param_path, param_path_str);
    env->ReleaseStringUTFChars(bin_path, bin_path_str);
    env->ReleaseStringUTFChars(labels_path, labels_path_str);
    return JNI_FALSE;
}

ret = g_net.load_model(bin_path_str);
if (ret != 0) {
    LOGE("Failed to load .bin file (%d)", ret);
    env->ReleaseStringUTFChars(param_path, param_path_str);
    env->ReleaseStringUTFChars(bin_path, bin_path_str);
    env->ReleaseStringUTFChars(labels_path, labels_path_str);
    return JNI_FALSE;
}

FILE* fp = fopen(labels_path_str, "r");
if (!fp) {
    LOGE("Failed to open labels file: %s", labels_path_str);
    env->ReleaseStringUTFChars(param_path, param_path_str);
    env->ReleaseStringUTFChars(bin_path, bin_path_str);
    env->ReleaseStringUTFChars(labels_path, labels_path_str);
    return JNI_FALSE;
}

char buffer[256];
while (fgets(buffer, sizeof(buffer), fp) != nullptr) {
    std::string label(buffer);
    label.erase(std::remove(label.begin(), label.end(), '\n'), label.end());
    label.erase(std::remove(label.begin(), label.end(), '\r'), label.end());
    if (!label.empty()) {
        g_labels.push_back(label);
    }
}
fclose(fp);

if (g_labels.empty()) {
    LOGE("No labels loaded from %s", labels_path_str);
    env->ReleaseStringUTFChars(param_path, param_path_str);
    env->ReleaseStringUTFChars(bin_path, bin_path_str);
    env->ReleaseStringUTFChars(labels_path, labels_path_str);
    return JNI_FALSE;
}

LOGI("Model loaded successfully");
LOGI("Total labels loaded: %zu", g_labels.size());
g_model_loaded = true;

env->ReleaseStringUTFChars(param_path, param_path_str);
env->ReleaseStringUTFChars(bin_path, bin_path_str);
env->ReleaseStringUTFChars(labels_path, labels_path_str);
return JNI_TRUE;
}
extern "C" JNIEXPORT jstring JNICALL Java_com_example_ncnnmy_1ok_MainActivity_detect( JNIEnv* env, jobject thiz, jstring image_path, jdouble conf_threshold, jdouble nms_threshold) {
LOGI("Running updated detect method (no debug image)");

if (!g_model_loaded) {
    LOGE("Model not loaded");
    return env->NewStringUTF("error:model_not_loaded");
}

const char* image_path_str = env->GetStringUTFChars(image_path, nullptr);
LOGI("Processing image: %s", image_path_str);

// Option 1: Use OpenCV (current)
cv::Mat image = cv::imread(image_path_str, cv::IMREAD_COLOR);
env->ReleaseStringUTFChars(image_path, image_path_str);

/*
// Option 2: Use stb_image (uncomment to test)
int width, height, channels;
unsigned char* image_data = stbi_load(image_path_str, &width, &height, &channels, 3);
env->ReleaseStringUTFChars(image_path, image_path_str);
if (!image_data) {
    LOGE("Failed to load image with stb_image");
    return env->NewStringUTF("error:image_load_failed");
}
cv::Mat image(height, width, CV_8UC3, image_data);
*/

if (image.empty()) {
    LOGE("Failed to load image");
    // stbi_image_free(image_data); // Uncomment if using stb_image
    return env->NewStringUTF("error:image_load_failed");
}

LOGD("Input image: %dx%d, channels=%d", image.cols, image.rows, image.channels());

const int target_size = 640;
int img_w = image.cols;
int img_h = image.rows;

float scale = std::min((float)target_size / img_w, (float)target_size / img_h);
int new_w = static_cast<int>(img_w * scale);
int new_h = static_cast<int>(img_h * scale);
int dx = (target_size - new_w) / 2;
int dy = (target_size - new_h) / 2;

cv::Mat resized;
cv::resize(image, resized, cv::Size(new_w, new_h));
cv::Mat input_mat(target_size, target_size, CV_8UC3, cv::Scalar(114, 114, 114));
resized.copyTo(input_mat(cv::Rect(dx, dy, new_w, new_h)));

cv::cvtColor(input_mat, input_mat, cv::COLOR_BGR2RGB);
input_mat.convertTo(input_mat, CV_32FC3, 1.0 / 255.0);

ncnn::Mat in = ncnn::Mat::from_pixels(input_mat.data, ncnn::Mat::PIXEL_RGB, target_size, target_size);

// stbi_image_free(image_data); // Uncomment if using stb_image

ncnn::Extractor ex = g_net.create_extractor();
ex.input("in0", in);
ncnn::Mat out;
ex.extract("out0", out);

if (out.empty()) {
    LOGE("Empty output from model");
    return env->NewStringUTF("error:empty_model_output");
}

LOGD("Output dimensions: w=%d, h=%d, c=%d", out.w, out.h, out.c);

int num_preds, num_classes;
bool is_decoupled = false;

if (out.c == 1) {
    LOGD("Possible decoupled heads detected, checking for additional outputs...");
    ncnn::Mat boxes, scores, classes;
    ex.extract("boxes", boxes);
    ex.extract("scores", scores);
    ex.extract("classes", classes);
    if (!boxes.empty() && !scores.empty() && !classes.empty()) {
        is_decoupled = true;
        LOGD("Decoupled heads detected: boxes=%dx%d, scores=%dx%d, classes=%dx%d",
             boxes.w, boxes.c, scores.w, scores.c, classes.w, classes.c);
        return env->NewStringUTF("error:decoupled_heads_not_implemented");
    }
}

if (!is_decoupled) {
    if (out.c >= 5) {
        num_preds = out.h * out.w;
        num_classes = out.c - 5;
        LOGD("Interpreting as [1, num_predictions, 5 + num_classes]: num_preds=%d, num_classes=%d",
             num_preds, num_classes);
    } else if (out.h >= 5) {
        num_preds = out.w;
        num_classes = out.h - 5;
        LOGD("Interpreting as [1, 5 + num_classes, num_predictions]: num_preds=%d, num_classes=%d",
             num_preds, num_classes);
    } else {
        LOGE("Invalid output dimensions: w=%d, h=%d, c=%d", out.w, out.h, out.c);
        return env->NewStringUTF("error:invalid_output_dimensions");
    }
}

if (num_classes != g_labels.size()) {
    LOGE("Mismatch between model outputs (%d) and labels (%zu)",
         num_classes, g_labels.size());
    return env->NewStringUTF("error:model_labels_mismatch");
}

std::vector<Detection> detections;
int stride = (out.c >= 5) ? out.c : out.h;
const float* data = (float*)out.data;

// Log raw outputs
if (num_preds > 0) {
    LOGD("Raw output sample: x=%.3f, y=%.3f, w=%.3f, h=%.3f, obj=%.3f",
         data[0], data[1], data[2], data[3], data[4]);
    // Log first class score
    if (num_classes > 0) {
        LOGD("Raw class score sample: class_0=%.3f", data[5]);
    }
}

for (int i = 0; i < num_preds; i++) {
    const float* pred = data + i * stride;

    float obj_score = sigmoid(pred[4]);
    if (obj_score < conf_threshold) continue;

    int class_id = 0;
    float max_score = sigmoid(pred[5]);
    for (int j = 1; j < num_classes; j++) {
        float score = sigmoid(pred[5 + j]);
        if (score > max_score) {
            max_score = score;
            class_id = j;
        }
    }

    float confidence = obj_score * max_score;
    if (confidence < conf_threshold) continue;

    // Normalize coordinates with sigmoid (assuming logits)
    float x_center = sigmoid(pred[0]) * target_size;
    float y_center = sigmoid(pred[1]) * target_size;
    float width = sigmoid(pred[2]) * target_size;
    float height = sigmoid(pred[3]) * target_size;

    // Adjust for letterbox
    float x = (x_center - width / 2 - dx) / scale;
    float y = (y_center - height / 2 - dy) / scale;
    width /= scale;
    height /= scale;

    LOGD("Prediction %d: x_center=%.2f, y_center=%.2f, width=%.2f, height=%.2f",
         i, x_center, y_center, width, height);
    LOGD("Transformed %d: x=%.2f, y=%.2f, width=%.2f, height=%.2f",
         i, x, y, width, height);

    // Validate coordinates
    if (x < 0 || y < 0 || width <= 0 || height <= 0 || x + width > img_w || y + height > img_h) {
        LOGD("Skipping invalid detection %d: x=%.2f, y=%.2f, w=%.2f, h=%.2f",
             i, x, y, width, height);
        continue;
    }

    // Minimum size filter
    if (width < 50 || height < 50) {
        LOGD("Skipping small detection %d: w=%.2f, h=%.2f", i, width, height);
        continue;
    }

    detections.push_back({x, y, width, height, class_id, confidence});
}

// NMS
std::sort(detections.begin(), detections.end(), [](const Detection& a, const Detection& b) {
    return a.prob > b.prob;
});

std::vector<bool> suppressed(detections.size(), false);
std::vector<Detection> final_detections;

for (size_t i = 0; i < detections.size(); i++) {
    if (suppressed[i]) continue;
    final_detections.push_back(detections[i]);

    for (size_t j = i + 1; j < detections.size(); j++) {
        if (suppressed[j]) continue;
        float iou = calculate_iou(detections[i], detections[j]);
        if (iou > nms_threshold) {
            suppressed[j] = true;
        }
    }
}

LOGD("Detections after NMS: %zu", final_detections.size());

// Format results
std::string result_str;
for (const auto& det : final_detections) {
    if (!result_str.empty()) result_str += ";";
    char buf[256];
    snprintf(buf, sizeof(buf), "%s:%.2f,%.0f,%.0f,%.0f,%.0f",
             g_labels[det.label].c_str(), det.prob,
             det.x, det.y, det.width, det.height);
    result_str += buf;
}

return env->NewStringUTF(result_str.empty() ? "none" : result_str.c_str());
}
Here is a log of the output of the flutter application.
[ ] D/NCNN_DETECTOR( 9180): Prediction 3730: x_center=640.00, y_center=640.00, width=640.00, height=640.00 [ ] D/NCNN_DETECTOR( 9180): Transformed 3730: x=320.00, y=240.00, width=640.00, height=640.00 [ ] D/NCNN_DETECTOR( 9180): Skipping invalid detection 3730: x=320.00, y=240.00, w=640.00, h=640.00 [ ] D/NCNN_DETECTOR( 9180): Prediction 3731: x_center=640.00, y_center=640.00, width=640.00, height=640.00 [ ] D/NCNN_DETECTOR( 9180): Transformed 3731: x=320.00, y=240.00, width=640.00, height=640.00 [ ] D/NCNN_DETECTOR( 9180): Skipping invalid detection 3731: x=320.00, y=240.00, w=640.00, h=640.00 [ ] D/NCNN_DETECTOR( 9180): Prediction 3732: x_center=640.00, y_center=640.00, width=640.00, height=640.00 [ ] D/NCNN_DETECTOR( 9180): Transformed 3732: x=320.00, y=240.00, width=640.00, height=640.00 [ ] D/NCNN_DETECTOR( 9180): Skipping invalid detection 3732: x=320.00, y=240.00, w=640.00, h=640.00 [ ] D/NCNN_DETECTOR( 9180): Detections after NMS: 0 [ ] I/flutter ( 9180): Detection result: none [ ] I/flutter ( 9180): STATUS: No objects detected [ ] E/libEGL ( 9180): called unimplemented OpenGL ES API
 Glenn JocherUltralytics(editado)
@gpsamt looking at your logs, the issue appears to be with output format parsing. YOLO11 NCNN outputs have no separate objectness score, and the class scores are already sigmoid-activated, so don't apply sigmoid again. Try parsing each prediction like this:
// Box is x_center, y_center, width, height (no sigmoid needed)
float x_center = pred[0];
float y_center = pred[1];
float width = pred[2];
float height = pred[3];
// pred[4 .. 4+nc) are the per-class scores; take the max class as the confidence

// Convert from center format to corner format
float x = (x_center - width / 2 - dx) / scale;
float y = (y_center - height / 2 - dy) / scale;
Also verify your model's actual output format by checking if coordinates are normalized (0-1) or absolute (0-640). The repeated 640.00 values suggest coordinate parsing issues. For official Android deployment examples, refer to the NCNN Android documentation.
aram199922
Hey everyone, I have trained yolo11n.pt pretrained model on my custom dataset. Run the detection on a video and got quite good results. Now trying to export ncnn with the given guide, files are being generated correctly, however the detection on the same video seems corrupted. I am trying to detect potholes on road, however ncnn model predict 300 potholes on each frame. Any suggestion?
One more note is that I have trained my model with 736p, 640p modes are converting fine. But does this mean I can't conver higher resolution trained model to ncnn?
- Glenn JocherUltralytics
@aram199922 The issue with your NCNN model detecting 300 potholes likely relates to confidence thresholds. When exporting to NCNN, default thresholds may not transfer properly. Try explicitly setting a higher confidence threshold during inference:
# Load the NCNN model
ncnn_model = YOLO("your_model_ncnn_model")

# Run inference with higher confidence threshold
results = ncnn_model("video.mp4", conf=0.5)  # Adjust this value as needed
Regarding your 736p model - yes, you can export higher resolution models to NCNN by specifying the custom size during export:
model = YOLO("your_trained_model.pt")
model.export(format="ncnn", imgsz=736)  # Use your training resolution
This ensures the exported model maintains the same input dimensions you used during training. Let me know if this helps resolve the issue!
Hello. Does anyone have any example of implementing the converted ncnn model in android?
PabloBR99
Do this work with YOLOv12?
- Glenn JocherUltralytics(editado)
@PabloBR99 YOLO12 isn't recommended for NCNN export due to training instability and performance limitations. For NCNN deployments, we strongly recommend using YOLO26 (or YOLO11), which offer optimized performance and stability across all platforms. You can find the NCNN export guide in our documentation.
I am exporting a YOLOv11s model to ncnn. My model has 4 classes, however, when I perform the export, it appears that it is identifying 3 classes: PyTorch: starting from '/content/drive/MyDrive/IAGeneration/yolo11/runs/detect/train3/weights/best.pt' with input shape (1, 3, 640, 640) BCHW and output shape(s) (1, 8, 8400) (18.3 MB). In Android Studio, this message appears:
2025-03-04 17:08:58.490 3853-3853 NcnnDetector com.example.agroinsect D Starting detection 2025-03-04 17:08:58.502 3853-3853 NcnnDetector com.example.test D Param file size: 22768 bytes 2025-03-04 17:08:58.504 3853-3853 NcnnDetector com.example.test D Load param result: 0 2025-03-04 17:08:58.504 3853-3853 NcnnDetector com.example.test D Bin file size: 10633344 bytes 2025-03-04 17:08:58.596 3853-3853 NcnnDetector com.example.test D Load model result: 10633344 2025-03-04 17:08:58.597 3853-3853 NcnnDetector com.example.test D Failed to load model file
[ +82 ms] D/CompatChangeReporter( 3853): Compat change id reported: 312399441; UID 10209; state: ENABLED [ +11 ms] D/nativeloader( 3853): Load /data/app/~~yVwXpMN1F9boaEz-oh0Bpw==/com.example.test-J2_0Fz9v3HSf0USV8uxz6Q==/lib/x86_64/libncnn_detector.so using ns clns-7 from class loader (caller=/data/app/~~yVwXpMN1F9boaEz-oh0Bpw==/com.example.test-J2_0Fz9v3HSf0USV8uxz6Q==/base.apk!classes4.dex): ok [ ] D/NcnnDetector( 3853): Library ncnn_detector loaded successfully [ ] D/NcnnDetector( 3853): Starting detection [ +10 ms] D/NcnnDetector( 3853): Param file size: 22768 bytes [ +2 ms] D/NcnnDetector( 3853): Load param result: 0 [ ] D/NcnnDetector( 3853): Bin file size: 10633344 bytes [ +97 ms] D/NcnnDetector( 3853): Load model result: 10633344 [ +1 ms] D/NcnnDetector( 3853): Failed to load model file [ ] I/flutter ( 3853): Native detect result: null [ ] I/flutter ( 3853): Detections received: [] [ ] I/flutter ( 3853): No detections found.
I have repeated the process several times, but I have not been able to resolve it. I found this answer: 'The current problem (Load model result: 37825744) suggests difficulties in exporting or compatibility.'"
- Glenn JocherUltralytics
@gpsamt thank you for reporting this issue. Let's address both aspects systematically:
-
Class Count Mismatch:
The output shape (1,8,8400) suggests your model is correctly configured for 4 classes (4 classes + 4 box coordinates = 8). This indicates the export itself is successful. The Android implementation might need adjustment to handle the 4-class output format. -
Model Loading Failure:
The "Failed to load model file" error typically indicates either:
- Missing/corrupted
.paramor.binfiles in deployment - Architecture mismatch between PyTorch and NCNN versions
- Incorrect Android NCNN implementation
We recommend:
- Verify successful local inference with your NCNN model using
yolo predict model='yolo11n_ncnn_model'before Android deployment - Ensure you're using the latest NCNN Android library from Tencent's NCNN GitHub repo
- Double-check that all NCNN model files are properly bundled in your Android assets
For specific Android implementation guidance, please consult NCNN's official Android deployment documentation.
-
I made several attempts and ended up not proceeding, however I really wanted to test my trained model running on android with ncnn. I made an export on windows of a yolo11 model trained in colab. To test the converted model yolo --> ncnn I did a test with an image with two objects. C:\Users\guips\Downloads>yolo predict model=C:\Users\guips\Downloads\best_ncnn_model source="C:\Users\guips\Downloads\brasil\test129.jpg" save_txt=true WARNING ⚠️ Unable to automatically guess model task, assuming 'task=detect'. Explicitly define task for your model, i.e. 'task=detect', 'segment', 'classify','pose' or 'obb'. Ultralytics 8.3.105 🚀 Python-3.11.9 torch-2.6.0+cpu CPU (12th Gen Intel Core(TM) i7-12700KF) Loading C:\Users\guips\Downloads\best_ncnn_model for NCNN inference...
image 1/1 C:\Users\guips\Downloads\brasil\test129.jpg: 640x640 2 Car, 103.0ms Speed: 20.4ms preprocess, 103.0ms inference, 24.2ms postprocess per image at shape (1, 3, 640, 640) Results saved to runs\detect\predict6 1 label saved to runs\detect\predict6\labels 💡 Learn more at https://docs.ultralytics.com/modes/predict
When I try to run the same image in the android application with flutter I can't. In TFLITE the output was (1,8,8400) Now it seems to be outputting (1,9,8400). I'm not able to work with the output data. I/flutter (14031): Labels loaded: 4E/libEGL (14031): called unimplemented OpenGL ES API I/flutter (14031): Storage permission denied D/InsetsController(14031): hide(ime(), fromIme=false) I/ImeTracker(14031): com.example.ncnnmy_ok:e29c5e1e: onCancelled at PHASE_CLIENT_ALREADY_HIDDEN E/libEGL (14031): called unimplemented OpenGL ES API D/InsetsController(14031): hide(ime(), fromIme=false) I/ImeTracker(14031): com.example.ncnnmy_ok:6f2d251e: onCancelled at PHASE_CLIENT_ALREADY_HIDDEN E/libEGL (14031): called unimplemented OpenGL ES API D/CompatChangeReporter(14031): Compat change id reported: 312399441; UID 10223; state: ENABLED I/flutter (14031): Image dimensions: 680.0x453.0 I/flutter (14031): Running inference on /data/user/0/com.example.ncnnmy_ok/cache/a6b569b8-5ff1-4466-ad32-49121fb24aa4/38.jpg D/MainActivity(14031): Received method call: detect I/NCNN (14031): Detecting on image: /data/user/0/com.example.ncnnmy_ok/cache/a6b569b8-5ff1-4466-ad32-49121fb24aa4/38.jpg I/NCNN (14031): Original image size: 680x453 I/NCNN (14031): Output dimensions: w=8400, h=9, c=1 I/NCNN (14031): Output saved to /data/user/0/com.example.ncnnmy_ok/cache/a6b569b8-5ff1-4466-ad32-49121fb24aa4/38.jpg_ncnn_output.txt W/NCNN (14031): Output has 4424 channels, expected 8. Using first 8 channels W/NCNN (14031): Invalid box at idx=9: w=0.000000, h=0.000000 W/NCNN (14031): Invalid box at idx=15: w=-0.010868, h=-0.063400 W/NCNN (14031): Invalid box at idx=16: w=-0.630245, h=-0.447460 W/NCNN (14031): Invalid box at idx=17: w=-0.685141, h=-0.837424 . . . W/NCNN (14031): Invalid box at idx=347: w=-0.077838, h=0.846499 F/libc (14031): Fatal signal 11 (SIGSEGV), code 2 (SEGV_ACCERR), fault addr 0x71c0c2499110 in tid 14031 (ample.ncnnmy_ok), pid 14031 (ample.ncnnmy_ok)
Build fingerprint: 'google/sdk_gphone64_x86_64/emu64xa:16/BP22.250221.010/13193326:user/release-keys' Revision: '0' ABI: 'x86_64' Timestamp: 2025-04-15 01:29:54.291432600+0000 Process uptime: 156s Cmdline: com.example.ncnnmy_ok pid: 14031, tid: 14031, name: ample.ncnnmy_ok >>> com.example.ncnnmy_ok <<< uid: 10223 signal 11 (SIGSEGV), code 2 (SEGV_ACCERR), fault addr 0x000071c0c2499110 rax 000071c0c2499100 rbx 000071c247d33be0 rcx 0000000000000004 rdx 0000000000000008 r8 00007ffc6ffc4080 r9 00007ffc6ffc40a0 r10 0000000000e8cada r11 0000000000000213 r12 00007ffc6ff903b0 r13 000071c247d33c88 r14 00007ffc6ff90718 r15 000071c247d33be0 rdi 00007ffc6ff8f840 rsi 0000000000000167 rbp 00007ffc6ff8f970 rsp 00007ffc6ff8f8b0 rip 000071c053d969ea 90 total frames backtrace: #00 pc 00000000000109ea /data/app/~~ygC8oOQ2RMgj_IeB2wDRKw==/com.example.ncnnmy_ok-1Q_3JHdbdZSe1RwVvc5qjQ==/lib/x86_64/libnative-lib.so (BuildId: 63a90d5f64ab095e3ac958c5db79324dfa15e937) #01 pc 000000000000fd3a /data/app/~~ygC8oOQ2RMgj_IeB2wDRKw==/com.example.ncnnmy_ok-1Q_3JHdbdZSe1RwVvc5qjQ==/lib/x86_64/libnative-lib.so (BuildId: 63a90d5f64ab095e3ac958c5db79324dfa15e937) #02 pc 000000000000e8aa /data/app/~~ygC8oOQ2RMgj_IeB2wDRKw==/com.example.ncnnmy_ok-1Q_3JHdbdZSe1RwVvc5qjQ==/lib/x86_64/libnative-lib.so (Java_com_example_ncnnmy_1ok_MainActivity_detect+2634) (BuildId: 63a90d5f64ab095e3ac958c5db79324dfa15e937) #03 pc 000000000022c80b /apex/com.android.art/lib64/libart.so (art_quick_generic_jni_trampoline+219) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #04 pc 0000000000211dd4 /apex/com.android.art/lib64/libart.so (art_quick_invoke_stub+756) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #05 pc 0000000000461715 /apex/com.android.art/lib64/libart.so (art::ArtMethod::Invoke(art::Thread*, unsigned int*, unsigned int, art::JValue*, char const*)+181) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #06 pc 00000000005f74b2 /apex/com.android.art/lib64/libart.so (bool art::interpreter::DoCall(art::ArtMethod*, art::Thread*, art::ShadowFrame&, art::Instruction const*, unsigned short, bool, art::JValue*)+2402) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #07 pc 0000000000233611 /apex/com.android.art/lib64/libart.so (void art::interpreter::ExecuteSwitchImplCpp(art::interpreter::SwitchImplContext*)+10625) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #08 pc 000000000022eb25 /apex/com.android.art/lib64/libart.so (ExecuteSwitchImplAsm+5) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #09 pc 00000000000006a4 anonymous:71c395b1d000 (com.example.ncnnmy_ok.MainActivity.configureFlutterEngine$lambda$0+0) #10 pc 00000000005ef3f2 /apex/com.android.art/lib64/libart.so (art::interpreter::Execute(art::Thread*, art::CodeItemDataAccessor const&, art::ShadowFrame&, art::JValue, bool, bool) (.__uniq.112435418011751916792819755956732575238)+466) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #11 pc 00000000005f6706 /apex/com.android.art/lib64/libart.so (art::interpreter::ArtInterpreterToInterpreterBridge(art::Thread*, art::CodeItemDataAccessor const&, art::ShadowFrame*, art::JValue*)+102) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #12 pc 00000000005f7498 /apex/com.android.art/lib64/libart.so (bool art::interpreter::DoCall(art::ArtMethod*, art::Thread*, art::ShadowFrame&, art::Instruction const*, unsigned short, bool, art::JValue*)+2376) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #13 pc 0000000000234b05 /apex/com.android.art/lib64/libart.so (void art::interpreter::ExecuteSwitchImplCpp(art::interpreter::SwitchImplContext*)+15989) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #14 pc 000000000022eb25 /apex/com.android.art/lib64/libart.so (ExecuteSwitchImplAsm+5) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #15 pc 0000000000000604 anonymous:71c395b1d000 (com.example.ncnnmy_ok.MainActivity.$r8$lambda$8rE-0sywqH2S4u1lhbBM5kfBEYE+0) #16 pc 00000000005ef3f2 /apex/com.android.art/lib64/libart.so (art::interpreter::Execute(art::Thread*, art::CodeItemDataAccessor const&, art::ShadowFrame&, art::JValue, bool, bool) (.__uniq.112435418011751916792819755956732575238)+466) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #17 pc 00000000005f6706 /apex/com.android.art/lib64/libart.so (art::interpreter::ArtInterpreterToInterpreterBridge(art::Thread*, art::CodeItemDataAccessor const&, art::ShadowFrame*, art::JValue*)+102) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #18 pc 00000000005f7498 /apex/com.android.art/lib64/libart.so (bool art::interpreter::DoCall(art::ArtMethod*, art::Thread*, art::ShadowFrame&, art::Instruction const*, unsigned short, bool, art::JValue*)+2376) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #19 pc 0000000000234b05 /apex/com.android.art/lib64/libart.so (void art::interpreter::ExecuteSwitchImplCpp(art::interpreter::SwitchImplContext*)+15989) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #20 pc 000000000022eb25 /apex/com.android.art/lib64/libart.so (ExecuteSwitchImplAsm+5) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #21 pc 00000000000005b8 anonymous:71c395b1d000 (com.example.ncnnmy_ok.MainActivity$$ExternalSyntheticLambda0.onMethodCall+0) #22 pc 00000000005ef3f2 /apex/com.android.art/lib64/libart.so (art::interpreter::Execute(art::Thread*, art::CodeItemDataAccessor const&, art::ShadowFrame&, art::JValue, bool, bool) (.__uniq.112435418011751916792819755956732575238)+466) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #23 pc 00000000005f6706 /apex/com.android.art/lib64/libart.so (art::interpreter::ArtInterpreterToInterpreterBridge(art::Thread*, art::CodeItemDataAccessor const&, art::ShadowFrame*, art::JValue*)+102) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #24 pc 00000000005f7498 /apex/com.android.art/lib64/libart.so (bool art::interpreter::DoCall(art::ArtMethod*, art::Thread*, art::ShadowFrame&, art::Instruction const*, unsigned short, bool, art::JValue*)+2376) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #25 pc 00000000002346e5 /apex/com.android.art/lib64/libart.so (void art::interpreter::ExecuteSwitchImplCpp(art::interpreter::SwitchImplContext*)+14933) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #26 pc 000000000022eb25 /apex/com.android.art/lib64/libart.so (ExecuteSwitchImplAsm+5) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #27 pc 00000000001bfabc anonymous:71c054260000 (io.flutter.plugin.common.MethodChannel$IncomingMethodCallHandler.onMessage+0) #28 pc 00000000005ef3f2 /apex/com.android.art/lib64/libart.so (art::interpreter::Execute(art::Thread*, art::CodeItemDataAccessor const&, art::ShadowFrame&, art::JValue, bool, bool) (.__uniq.112435418011751916792819755956732575238)+466) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #29 pc 00000000005f6706 /apex/com.android.art/lib64/libart.so (art::interpreter::ArtInterpreterToInterpreterBridge(art::Thread*, art::CodeItemDataAccessor const&, art::ShadowFrame*, art::JValue*)+102) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #30 pc 00000000005f7498 /apex/com.android.art/lib64/libart.so (bool art::interpreter::DoCall(art::ArtMethod*, art::Thread*, art::ShadowFrame&, art::Instruction const*, unsigned short, bool, art::JValue*)+2376) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #31 pc 00000000002346e5 /apex/com.android.art/lib64/libart.so (void art::interpreter::ExecuteSwitchImplCpp(art::interpreter::SwitchImplContext*)+14933) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #32 pc 000000000022eb25 /apex/com.android.art/lib64/libart.so (ExecuteSwitchImplAsm+5) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #33 pc 00000000001b1954 anonymous:71c054260000 (io.flutter.embedding.engine.dart.DartMessenger.invokeHandler+0) #34 pc 00000000005ef3f2 /apex/com.android.art/lib64/libart.so (art::interpreter::Execute(art::Thread*, art::CodeItemDataAccessor const&, art::ShadowFrame&, art::JValue, bool, bool) (.__uniq.112435418011751916792819755956732575238)+466) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #35 pc 00000000005f6706 /apex/com.android.art/lib64/libart.so (art::interpreter::ArtInterpreterToInterpreterBridge(art::Thread*, art::CodeItemDataAccessor const&, art::ShadowFrame*, art::JValue*)+102) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #36 pc 00000000005f7498 /apex/com.android.art/lib64/libart.so (bool art::interpreter::DoCall(art::ArtMethod*, art::Thread*, art::ShadowFrame&, art::Instruction const*, unsigned short, bool, art::JValue*)+2376) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #37 pc 0000000000233611 /apex/com.android.art/lib64/libart.so (void art::interpreter::ExecuteSwitchImplCpp(art::interpreter::SwitchImplContext*)+10625) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #38 pc 000000000022eb25 /apex/com.android.art/lib64/libart.so (ExecuteSwitchImplAsm+5) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #39 pc 00000000001b19d8 anonymous:71c054260000 (io.flutter.embedding.engine.dart.DartMessenger.lambda$dispatchMessageToQueue$0$io-flutter-embedding-engine-dart-DartMessenger+0) #40 pc 00000000005ef3f2 /apex/com.android.art/lib64/libart.so (art::interpreter::Execute(art::Thread*, art::CodeItemDataAccessor const&, art::ShadowFrame&, art::JValue, bool, bool) (.__uniq.112435418011751916792819755956732575238)+466) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #41 pc 00000000005f6706 /apex/com.android.art/lib64/libart.so (art::interpreter::ArtInterpreterToInterpreterBridge(art::Thread*, art::CodeItemDataAccessor const&, art::ShadowFrame*, art::JValue*)+102) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #42 pc 00000000005f827f /apex/com.android.art/lib64/libart.so (bool art::interpreter::DoCall(art::ArtMethod*, art::Thread*, art::ShadowFrame&, art::Instruction const*, unsigned short, bool, art::JValue*)+2319) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #43 pc 000000000023482d /apex/com.android.art/lib64/libart.so (void art::interpreter::ExecuteSwitchImplCpp(art::interpreter::SwitchImplContext*)+15261) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #44 pc 000000000022eb25 /apex/com.android.art/lib64/libart.so (ExecuteSwitchImplAsm+5) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #45 pc 00000000001b1168 anonymous:71c054260000 (io.flutter.embedding.engine.dart.DartMessenger$$ExternalSyntheticLambda0.run+0) #46 pc 00000000005ef3f2 /apex/com.android.art/lib64/libart.so (art::interpreter::Execute(art::Thread*, art::CodeItemDataAccessor const&, art::ShadowFrame&, art::JValue, bool, bool) (.__uniq.112435418011751916792819755956732575238)+466) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #47 pc 00000000009978fb /apex/com.android.art/lib64/libart.so (artQuickToInterpreterBridge+907) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #48 pc 000000000022c99c /apex/com.android.art/lib64/libart.so (art_quick_to_interpreter_bridge+140) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #49 pc 0000000000160efc [anon_shmem:dalvik-jit-code-cache] (offset 0x2000000) (android.os.Handler.handleCallback+156) #50 pc 00000000000718af [anon_shmem:dalvik-jit-code-cache] (offset 0x2000000) (android.os.Handler.dispatchMessage+159) #51 pc 000000000006e9a4 [anon_shmem:dalvik-jit-code-cache] (offset 0x2000000) (android.os.Looper.loopOnce+1348) #52 pc 0000000000212136 /apex/com.android.art/lib64/libart.so (art_quick_invoke_static_stub+806) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #53 pc 000000000046175c /apex/com.android.art/lib64/libart.so (art::ArtMethod::Invoke(art::Thread*, unsigned int*, unsigned int, art::JValue*, char const*)+252) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #54 pc 00000000005f74b2 /apex/com.android.art/lib64/libart.so (bool art::interpreter::DoCall(art::ArtMethod*, art::Thread*, art::ShadowFrame&, art::Instruction const*, unsigned short, bool, art::JValue*)+2402) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #55 pc 0000000000234b05 /apex/com.android.art/lib64/libart.so (void art::interpreter::ExecuteSwitchImplCpp(art::interpreter::SwitchImplContext*)+15989) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #56 pc 000000000022eb25 /apex/com.android.art/lib64/libart.so (ExecuteSwitchImplAsm+5) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #57 pc 000000000027c140 /system/framework/framework.jar (offset 0x1274000) (android.os.Looper.loop+0) #58 pc 00000000005ef3f2 /apex/com.android.art/lib64/libart.so (art::interpreter::Execute(art::Thread*, art::CodeItemDataAccessor const&, art::ShadowFrame&, art::JValue, bool, bool) (.__uniq.112435418011751916792819755956732575238)+466) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #59 pc 00000000005f6706 /apex/com.android.art/lib64/libart.so (art::interpreter::ArtInterpreterToInterpreterBridge(art::Thread*, art::CodeItemDataAccessor const&, art::ShadowFrame*, art::JValue*)+102) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #60 pc 00000000005f7498 /apex/com.android.art/lib64/libart.so (bool art::interpreter::DoCall(art::ArtMethod*, art::Thread*, art::ShadowFrame&, art::Instruction const*, unsigned short, bool, art::JValue*)+2376) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #61 pc 0000000000234b05 /apex/com.android.art/lib64/libart.so (void art::interpreter::ExecuteSwitchImplCpp(art::interpreter::SwitchImplContext*)+15989) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #62 pc 000000000022eb25 /apex/com.android.art/lib64/libart.so (ExecuteSwitchImplAsm+5) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #63 pc 00000000001f1254 /system/framework/framework.jar (offset 0x7000) (android.app.ActivityThread.main+0) #64 pc 00000000005ef3f2 /apex/com.android.art/lib64/libart.so (art::interpreter::Execute(art::Thread*, art::CodeItemDataAccessor const&, art::ShadowFrame&, art::JValue, bool, bool) (.__uniq.112435418011751916792819755956732575238)+466) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #65 pc 00000000009978fb /apex/com.android.art/lib64/libart.so (artQuickToInterpreterBridge+907) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #66 pc 000000000022c99c /apex/com.android.art/lib64/libart.so (art_quick_to_interpreter_bridge+140) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #67 pc 0000000000212136 /apex/com.android.art/lib64/libart.so (art_quick_invoke_static_stub+806) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #68 pc 000000000046175c /apex/com.android.art/lib64/libart.so (art::ArtMethod::Invoke(art::Thread*, unsigned int*, unsigned int, art::JValue*, char const*)+252) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #69 pc 000000000088b130 /apex/com.android.art/lib64/libart.so (_jobject* art::InvokeMethod<(art::PointerSize)8>(art::ScopedObjectAccessAlreadyRunnable const&, _jobject*, _jobject*, _jobject*, unsigned long)+2240) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #70 pc 00000000007e0f1a /apex/com.android.art/lib64/libart.so (art::Method_invoke(_JNIEnv*, _jobject*, _jobject*, _jobjectArray*) (.__uniq.165753521025965369065708152063621506277)+42) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #71 pc 000000000022c80b /apex/com.android.art/lib64/libart.so (art_quick_generic_jni_trampoline+219) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #72 pc 0000000000211dd4 /apex/com.android.art/lib64/libart.so (art_quick_invoke_stub+756) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #73 pc 0000000000461715 /apex/com.android.art/lib64/libart.so (art::ArtMethod::Invoke(art::Thread*, unsigned int*, unsigned int, art::JValue*, char const*)+181) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #74 pc 00000000005f74b2 /apex/com.android.art/lib64/libart.so (bool art::interpreter::DoCall(art::ArtMethod*, art::Thread*, art::ShadowFrame&, art::Instruction const*, unsigned short, bool, art::JValue*)+2402) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #75 pc 0000000000233611 /apex/com.android.art/lib64/libart.so (void art::interpreter::ExecuteSwitchImplCpp(art::interpreter::SwitchImplContext*)+10625) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #76 pc 000000000022eb25 /apex/com.android.art/lib64/libart.so (ExecuteSwitchImplAsm+5) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #77 pc 000000000027f6ec /system/framework/framework.jar (offset 0x2430000) (com.android.internal.os.RuntimeInit$MethodAndArgsCaller.run+0) #78 pc 00000000005ef3f2 /apex/com.android.art/lib64/libart.so (art::interpreter::Execute(art::Thread*, art::CodeItemDataAccessor const&, art::ShadowFrame&, art::JValue, bool, bool) (.__uniq.112435418011751916792819755956732575238)+466) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #79 pc 00000000009978fb /apex/com.android.art/lib64/libart.so (artQuickToInterpreterBridge+907) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #80 pc 000000000022c99c /apex/com.android.art/lib64/libart.so (art_quick_to_interpreter_bridge+140) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #81 pc 00000000007fc865 /system/framework/x86_64/boot-framework.oat (com.android.internal.os.ZygoteInit.main+2693) (BuildId: 5539d75c58ae9a874c8bdd56a20d5ad37b7a2757) #82 pc 0000000000212136 /apex/com.android.art/lib64/libart.so (art_quick_invoke_static_stub+806) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #83 pc 000000000046175c /apex/com.android.art/lib64/libart.so (art::ArtMethod::Invoke(art::Thread*, unsigned int*, unsigned int, art::JValue*, char const*)+252) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #84 pc 000000000088bc46 /apex/com.android.art/lib64/libart.so (art::JValue art::InvokeWithVarArgs<_jmethodID*>(art::ScopedObjectAccessAlreadyRunnable const&, _jobject*, _jmethodID*, __va_list_tag*)+518) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #85 pc 000000000072f31a /apex/com.android.art/lib64/libart.so (art::JNI::CallStaticVoidMethodV(_JNIEnv*, _jclass*, _jmethodID*, __va_list_tag*)+602) (BuildId: 53a0485d03b4e7011d7d555e293a17af) #86 pc 00000000000eefae /system/lib64/libandroid_runtime.so (_JNIEnv::CallStaticVoidMethod(_jclass*, _jmethodID*, ...)+126) (BuildId: 0e1c658a58fcbbaafa02d3d78a368ee8) #87 pc 000000000011b496 /system/lib64/libandroid_runtime.so (android::AndroidRuntime::start(char const*, android::Vectorandroid::String8 const&, bool)+966) (BuildId: 0e1c658a58fcbbaafa02d3d78a368ee8) #88 pc 0000000000004708 /system/bin/app_process64 (main+1640) (BuildId: e2134dffba60b5f40425e9c838419a02) #89 pc 0000000000054ea5 /apex/com.android.runtime/lib64/bionic/libc.so (__libc_init+117) (BuildId: 2fa253bed5a3b3aee8fce00edb55a139) Lost connection to device.
These are the first layers of the .param file and the last ones.
7767517 275 327 Input in0 0 1 in0 Convolution conv_0 1 1 in0 1 0=32 1=3 11=3 12=1 13=2 14=1 2=1 3=2 4=1 5=1 6=864 Swish silu_84 1 1 1 2 Convolution conv_1 1 1 2 3 0=64 1=3 11=3 12=1 13=2 14=1 2=1 3=2 4=1 5=1 6=18432 Swish silu_85 1 1 3 4 Convolution conv_2 1 1 4 5 0=64 1=1 11=1 12=1 13=1 14=0 2=1 3=1 4=0 5=1 6=4096
Last layer
Split splitncnn_27 1 2 313 314 315 BinaryOp add_16 2 1 310 312 316 0=0 Split splitncnn_28 1 2 316 317 318 BinaryOp add_17 2 1 314 317 319 0=0 BinaryOp div_18 1 1 319 320 0=3 1=1 2=2.000000e+00 BinaryOp sub_19 2 1 318 315 321 0=1 Concat cat_21 2 1 320 321 322 0=0 Reshape reshape_167 1 1 252 323 0=8400 1=1 BinaryOp mul_20 2 1 322 323 324 0=2 Sigmoid sigmoid_163 1 1 303 325 Concat cat_22 2 1 324 325 out0 0=0
I thank you in advance for your attention and help.
UltralyticsAssistantUltralytics
👋 Hello, thank you for your interest in Ultralytics 🚀! It's exciting to see discussions around optimizing YOLO models for mobile and embedded devices. The link you shared regarding NCNN integration is a great starting point for exploring this topic: https://docs.ultralytics.com/zh/integrations/ncnn/.
If you're encountering issues or have specific queries regarding the NCNN export or deployment, here are a few recommendations:
-
If this is a 🐛 Bug Report, please provide a minimum reproducible example so our team can better understand and debug any potential issues.
-
If this is an ❓ integration or optimization question, please provide as much context as possible, such as your model configuration, device specifications, and any logs or error messages.
For further learning and exploration, you may also find these resources helpful:
- Integration Examples: Comprehensive guides for integrating YOLO with various platforms and tools.
- NCNN Documentation: Specific details about NCNN and its benefits for resource-constrained environments.
Upgrade
Ensure you're using the latest Ultralytics package and dependencies by upgrading your environment with the following command:
pip install -U ultralyticsEnvironments
To experiment with YOLO in diverse, GPU-enabled environments, check out the following setups:
- Notebooks with free GPU:


- Cloud services like Google Cloud and AWS.
- Docker Image for efficient deployment and reproducibility
.
Status

This badge indicates the status of Ultralytics CI tests, which ensure the reliability of YOLO models across various environments. A green badge means all tests are successful ✅.
Lastly, this is an automated response to guide you as quickly as possible, but rest assured that an Ultralytics engineer will follow up soon to assist you further. Feel free to share additional information or questions in the meantime 😊.
 haitao5676
I have created a single target tracking model for deployment on Android devices. How can I export the ncnn file for deployment using my own model?
- haitao5676
I have resolved the issue of using the model trained by ncnn in Python and am now preparing to deploy Java references for Android. Excuse me!
- Glenn JocherUltralytics
@xiao5676wen thank you for your update. To deploy your YOLO11 NCNN model on Android, you'll need to build NCNN for Android using Tencent NCNN's build guide and integrate the exported model using the NCNN Android SDK. For detailed integration steps, refer to the official NCNN documentation for Android. Let me know if you encounter issues!
-
- haitao5676
How can I export ncnn using the PT file I trained myself?
- Glenn JocherUltralytics
@xiao5676wen to export your trained YOLO11
.ptmodel to NCNN format, load your model using theYOLOclass in Python and then call theexportmethod withformat="ncnn". Example:from ultralytics import YOLO model = YOLO("path_to_your_trained_model.pt") model.export(format="ncnn") # Creates the NCNN modelFor additional details, refer to the NCNN export documentation.
trungnb34
Hi everyone NCNN can be inferred from the int8 model I have a question. when converting Yolo model to int8 . Can ultralytics support it and Does the accuracy decrease much? Thanks
- Glenn JocherUltralytics(editado)
@trungnb34 Ultralytics can export YOLO models to NCNN in FP16 with
quantize=16, but INT8 quantization is not currently supported for NCNN exports (quantize=8is rejected for this format). For details, refer to the Export to NCNN guide. robert-hardman
Hello ultralytics==8.3.53 Like it doesn't support int8 yet
File "C:\Users***\AppData\Local\Programs\Python\Python312\Lib\site-packages\ultralytics\engine\exporter.py", line 253, in call validate_args(fmt, self.args, fmts_dict["Arguments"][flags.index(True) + 1]) File "C:\Users***AppData\Local\Programs\Python\Python312\Lib\site-packages\ultralytics\engine\exporter.py", line 144, in validate_args assert arg in valid_args, f"ERROR \u274c\ufe0f argument '{arg}' is not supported for format='{format}'" ^^^^^^^^^^^^^^^^^ AssertionError: ERROR \u274c\ufe0f argument 'int8' is not supported for format='ncnn'
- Glenn JocherUltralytics
@robert-hardman thank you for raising this issue. Currently, INT8 quantization is not supported for NCNN exports in Ultralytics. For updates on supported features, keep an eye on our Export documentation. Let us know if you have further questions!
1
amrboef66
Hellooo, im trying to run interference on a raspberry Pi 5, now indeed NCNN has the fastest time, but i need it to be even quicker, so i tried reducing the image format from 640 to 480, since my model does not require such a large image size, but when i do that it misidentifies and puts bounding boxes everywhere on screen. How do i reduce image size while still allowing the model to run accurately?
Also, do you have any thoughts on how i can make it quicker, perhaps a different method? I am already using Nano model and int8 quantisation.
Thank you so much!
- Glenn JocherUltralytics
@amrboef66 to improve accuracy with a smaller image size, consider fine-tuning your model on images of the desired size. Additionally, you might explore using a more efficient model architecture or further optimizing your inference pipeline.
abdullah000123
Can we directly export model in ncnn while training or we only can convert model which i obtained after training ie converting from pt to ncnn if we can convert directly while training whats is benefit in case of accuracy and also give me code if we can export directly while training model
 Paula DerrengerUltralytics
@abdullah000123 you can only export a YOLOv8 model to NCNN format after training is complete. Direct export during training is not supported. Exporting post-training ensures that the model is fully trained and optimized before conversion, which does not impact accuracy. For exporting, you can use the following command after training:
from ultralytics import YOLO
model = YOLO("yolov8n.pt")
model.export(format="ncnn")
For more details, please refer to the NCNN export guide.
woerstcase
Hey there!
I tried and on my Mac M2 Mac the inference time got from around 60ms to 30ms. And in a custom Model even faster.
But now i have the "problem" that the BBoxes are very flickering. Is there a good technique to make the bbox drawing even more smooth. I tried some approaches like drawing over 5 Frames for e.g. But if i have same classes on the image the bbox starts wandering trough the image.
best regards
- Glenn JocherUltralytics
Hey there! 👋
Great to hear about the speed improvements on your Mac M2! For smoothing out the flickering BBoxes, one approach is to apply a moving average or some form of temporal smoothing to the bounding box coordinates across frames. This helps in making the position more stable. A simple example could be:
# Assuming bbox is a list of bounding box coordinates for the current frame # prev_bboxes is a list of previous bounding boxes (could store N previous states) smoothed_bbox = current_bbox * alpha + prev_bbox * (1 - alpha)alphais a weighting factor that determines the balance between the current and previous frame's information (e.g.,alpha=0.6). This approach assumesprev_bboxis the bounding box coordinate from the previous frame. Adjustalphabased on your preference for smoothness vs. responsiveness.If you're handling multiple objects of the same class, consider incorporating an object tracker that assigns unique IDs to each object. This way, you can apply the smoothing individually to each tracked object, preventing the "wandering" effect across objects of the same class.
Hope this helps! Let us know if you have any more questions. 😊
Best regards
1 Worked for me! With my custom Model the inference time is around 15ms!
This is my smoothing function:
#Smoothing function def smooth_bbox(current_bbox, prev_bbox): if prev_bbox is None: return current_bbox smoothed_bbox = [(c * alpha + p * (1 - alpha)) for c, p in zip(current_bbox, prev_bbox)] return smoothed_bbox
....#later in the code i use it like this
    for box, confidence, cls in zip(boxes, confidences, classes):
        x1, y1, x2, y2 = map(int, box[:4])  # Extract bounding box coordinates
        class_name = names[int(cls)]

        # Generate a unique key for each bbox assuming no tracking ID available
        bbox_key = f"{x1}_{y1}_{x2}_{y2}"

        # Apply smoothing
        current_bbox = [x1, y1, x2, y2]
        if bbox_key in prev_bboxes:
            smoothed_coords = smooth_bbox(current_bbox, prev_bboxes[bbox_key])
        else:
            smoothed_coords = current_bbox

        # Update prev_bboxes
        prev_bboxes[bbox_key] = smoothed_coords

        # Calculate the center of the smoothed bbox
        center_x = int((smoothed_coords[0] + smoothed_coords[2]) / 2)
        center_y = int((smoothed_coords[1] + smoothed_coords[3]) / 2)
best regards
- Glenn JocherUltralytics
Hey there!
Great to see your impressive inference times, and thanks for sharing your smoothing function! 🚀 It looks like a solid approach. To address the flickering and "wandering" of bounding boxes for objects of the same class, you might consider integrating an object tracking algorithm like SORT or DeepSORT that assigns unique IDs to each object. This way, you can ensure that the smoothing you apply is object-specific.
Here's a small tweak to include object tracking by simply creating a unique key based on the object's class and center coordinates, assuming you'd implement tracking to assign IDs:
# Assuming bbox_key generation after object tracking assigns a unique track_id
bbox_key = f"{class_name}_{track_id}"

# Use this key for previous bbox retrieval and smoothing application
This tweak can help keep the smoothing consistent across consecutive frames for the same object, reducing "wandering."
Hope this helps make your bboxes smooth as silk! Let me know if you have other questions or if there's more we can help with.
Happy coding! 😊
Best regards