COCO-Pose Dataset#
The COCO-Pose dataset adapts COCO (Common Objects in Context) for pose estimation: 58,945 images from COCO Keypoints 2017, annotated with 156,165 people using a 17-keypoint schema. It is the standard set for training and benchmarking keypoint models such as Ultralytics YOLO26, and the 8-image COCO8-Pose subset mirrors its format for quick sanity checks.
COCO-Pose Pretrained Models#
| Model | size (pixels) | mAPpose50-95 (e2e) | mAPpose50 (e2e) | Speed CPU ONNX (ms) | Speed T4 TensorRT10 (ms) | params (M) | FLOPs (B) |
|---|---|---|---|---|---|---|---|
| YOLO26n-pose | 640 | 57.2 | 83.3 | 40.3 ± 0.5 | 1.8 ± 0.0 | 2.9 | 7.6 |
| YOLO26s-pose | 640 | 63.0 | 86.6 | 85.3 ± 0.9 | 2.7 ± 0.0 | 10.4 | 24.1 |
| YOLO26m-pose | 640 | 68.8 | 89.6 | 218.0 ± 1.5 | 5.0 ± 0.1 | 21.5 | 73.3 |
| YOLO26l-pose | 640 | 70.4 | 90.5 | 275.4 ± 2.4 | 6.5 ± 0.1 | 25.9 | 91.7 |
| YOLO26x-pose | 640 | 71.6 | 91.6 | 565.4 ± 3.0 | 12.2 ± 0.2 | 57.6 | 202.3 |
Key Features#
- COCO-Pose builds upon the COCO Keypoints 2017 challenge, which labels 1,710,498 individual keypoints across 156,165 annotated people.
- Each person annotation uses 17 keypoint types — nose, eyes, ears, shoulders, elbows, wrists, hips, knees, and ankles — stored as
(x, y, visibility)triplets. - Like COCO, it provides standardized evaluation metrics, including Object Keypoint Similarity (OKS) for pose estimation tasks, making it suitable for comparing model performance.
- Download size: ~20.2 GB on first use (
train2017.zip+val2017.zip+ labels). The 7 GBtest2017.zipis not fetched automatically, since those images have withheld ground truth and are only needed for a test-dev2017 submission.
Dataset Structure#
For training and validation, COCO-Pose includes only COCO 2017 images with keypoint-annotated people, so its labeled splits are smaller than full COCO's. Its YAML defines three subsets:
- Train2017: This subset contains 56,599 images from the COCO dataset, annotated for training pose estimation models.
- Val2017: This subset has 2,346 images used for validation purposes during model training.
- Test-dev2017: A 20,288-image subset of the full 40,670-image test2017 set with withheld ground truth. The dataset YAML links this split to the COCO test-dev keypoints evaluation server.
Training at this scale is where Ultralytics Platform helps most — it manages the compute so you can launch and monitor runs without provisioning your own GPUs.
Applications#
The COCO-Pose dataset is specifically used for training and evaluating deep learning models on keypoint detection and pose estimation. The dataset's large number of annotated images and standardized evaluation metrics make it an essential resource for computer vision researchers and practitioners working on human pose.
Dataset YAML#
A YAML file is used to define the dataset configuration. It contains information about the dataset's paths, classes, and other relevant information. In the case of the COCO-Pose dataset, the coco-pose.yaml file is maintained at https://github.com/ultralytics/ultralytics/blob/main/ultralytics/cfg/datasets/coco-pose.yaml.
# Ultralytics 🚀 AGPL-3.0 License - https://ultralytics.com/license

# COCO 2017 Keypoints dataset https://cocodataset.org by Microsoft
# Documentation: https://docs.ultralytics.com/datasets/pose/coco
# Example usage: yolo train data=coco-pose.yaml
# parent
# ├── ultralytics
# └── datasets
#     └── coco-pose ← downloads here (20.2 GB)

# Train/val/test sets as 1) dir: path/to/imgs, 2) file: path/to/imgs.txt, or 3) list: [path/to/imgs1, path/to/imgs2, ..]
path: coco-pose # dataset root dir
train: train2017.txt # train images (relative to 'path') 56599 images
val: val2017.txt # val images (relative to 'path') 2346 images
test: test-dev2017.txt # 20288 of 40670 images, submit to https://codalab.lisn.upsaclay.fr/competitions/7403

# Keypoints
kpt_shape: [17, 3] # number of keypoints, number of dims (2 for x,y or 3 for x,y,visible)
flip_idx: [0, 2, 1, 4, 3, 6, 5, 8, 7, 10, 9, 12, 11, 14, 13, 16, 15]

# Classes
names:
  0: person

# Keypoint names per class
kpt_names:
  0:
    - nose
    - left_eye
    - right_eye
    - left_ear
    - right_ear
    - left_shoulder
    - right_shoulder
    - left_elbow
    - right_elbow
    - left_wrist
    - right_wrist
    - left_hip
    - right_hip
    - left_knee
    - right_knee
    - left_ankle
    - right_ankle

# Download script/URL (optional)
download: |
  from pathlib import Path

  from ultralytics.utils import ASSETS_URL
  from ultralytics.utils.downloads import download

  # Download labels
  dir = Path(yaml["path"])  # dataset root dir

  urls = [f"{ASSETS_URL}/coco2017labels-pose.zip"]
  download(urls, dir=dir.parent)

  # Download data (test2017.zip excluded: ground truth is withheld, only used for the CodaLab test-dev split)
  urls = [
      "http://images.cocodataset.org/zips/train2017.zip",  # 19G, 118k images
      "http://images.cocodataset.org/zips/val2017.zip",  # 1G, 5k images
  ]
download(urls, dir=dir / "images", threads=3)Usage#
To train a YOLO26n-pose model on the COCO-Pose dataset for 100 epochs with an image size of 640, you can use the following code snippets.
from ultralytics import YOLO

# Load a model
model = YOLO("yolo26n-pose.pt")  # load a pretrained model (recommended for training)

# Train the model
results = model.train(data="coco-pose.yaml", epochs=100, imgsz=640)
Sample Images and Annotations#
The COCO-Pose dataset contains a diverse set of images with human figures annotated with keypoints. Here are some examples of images from the dataset, along with their corresponding annotations:
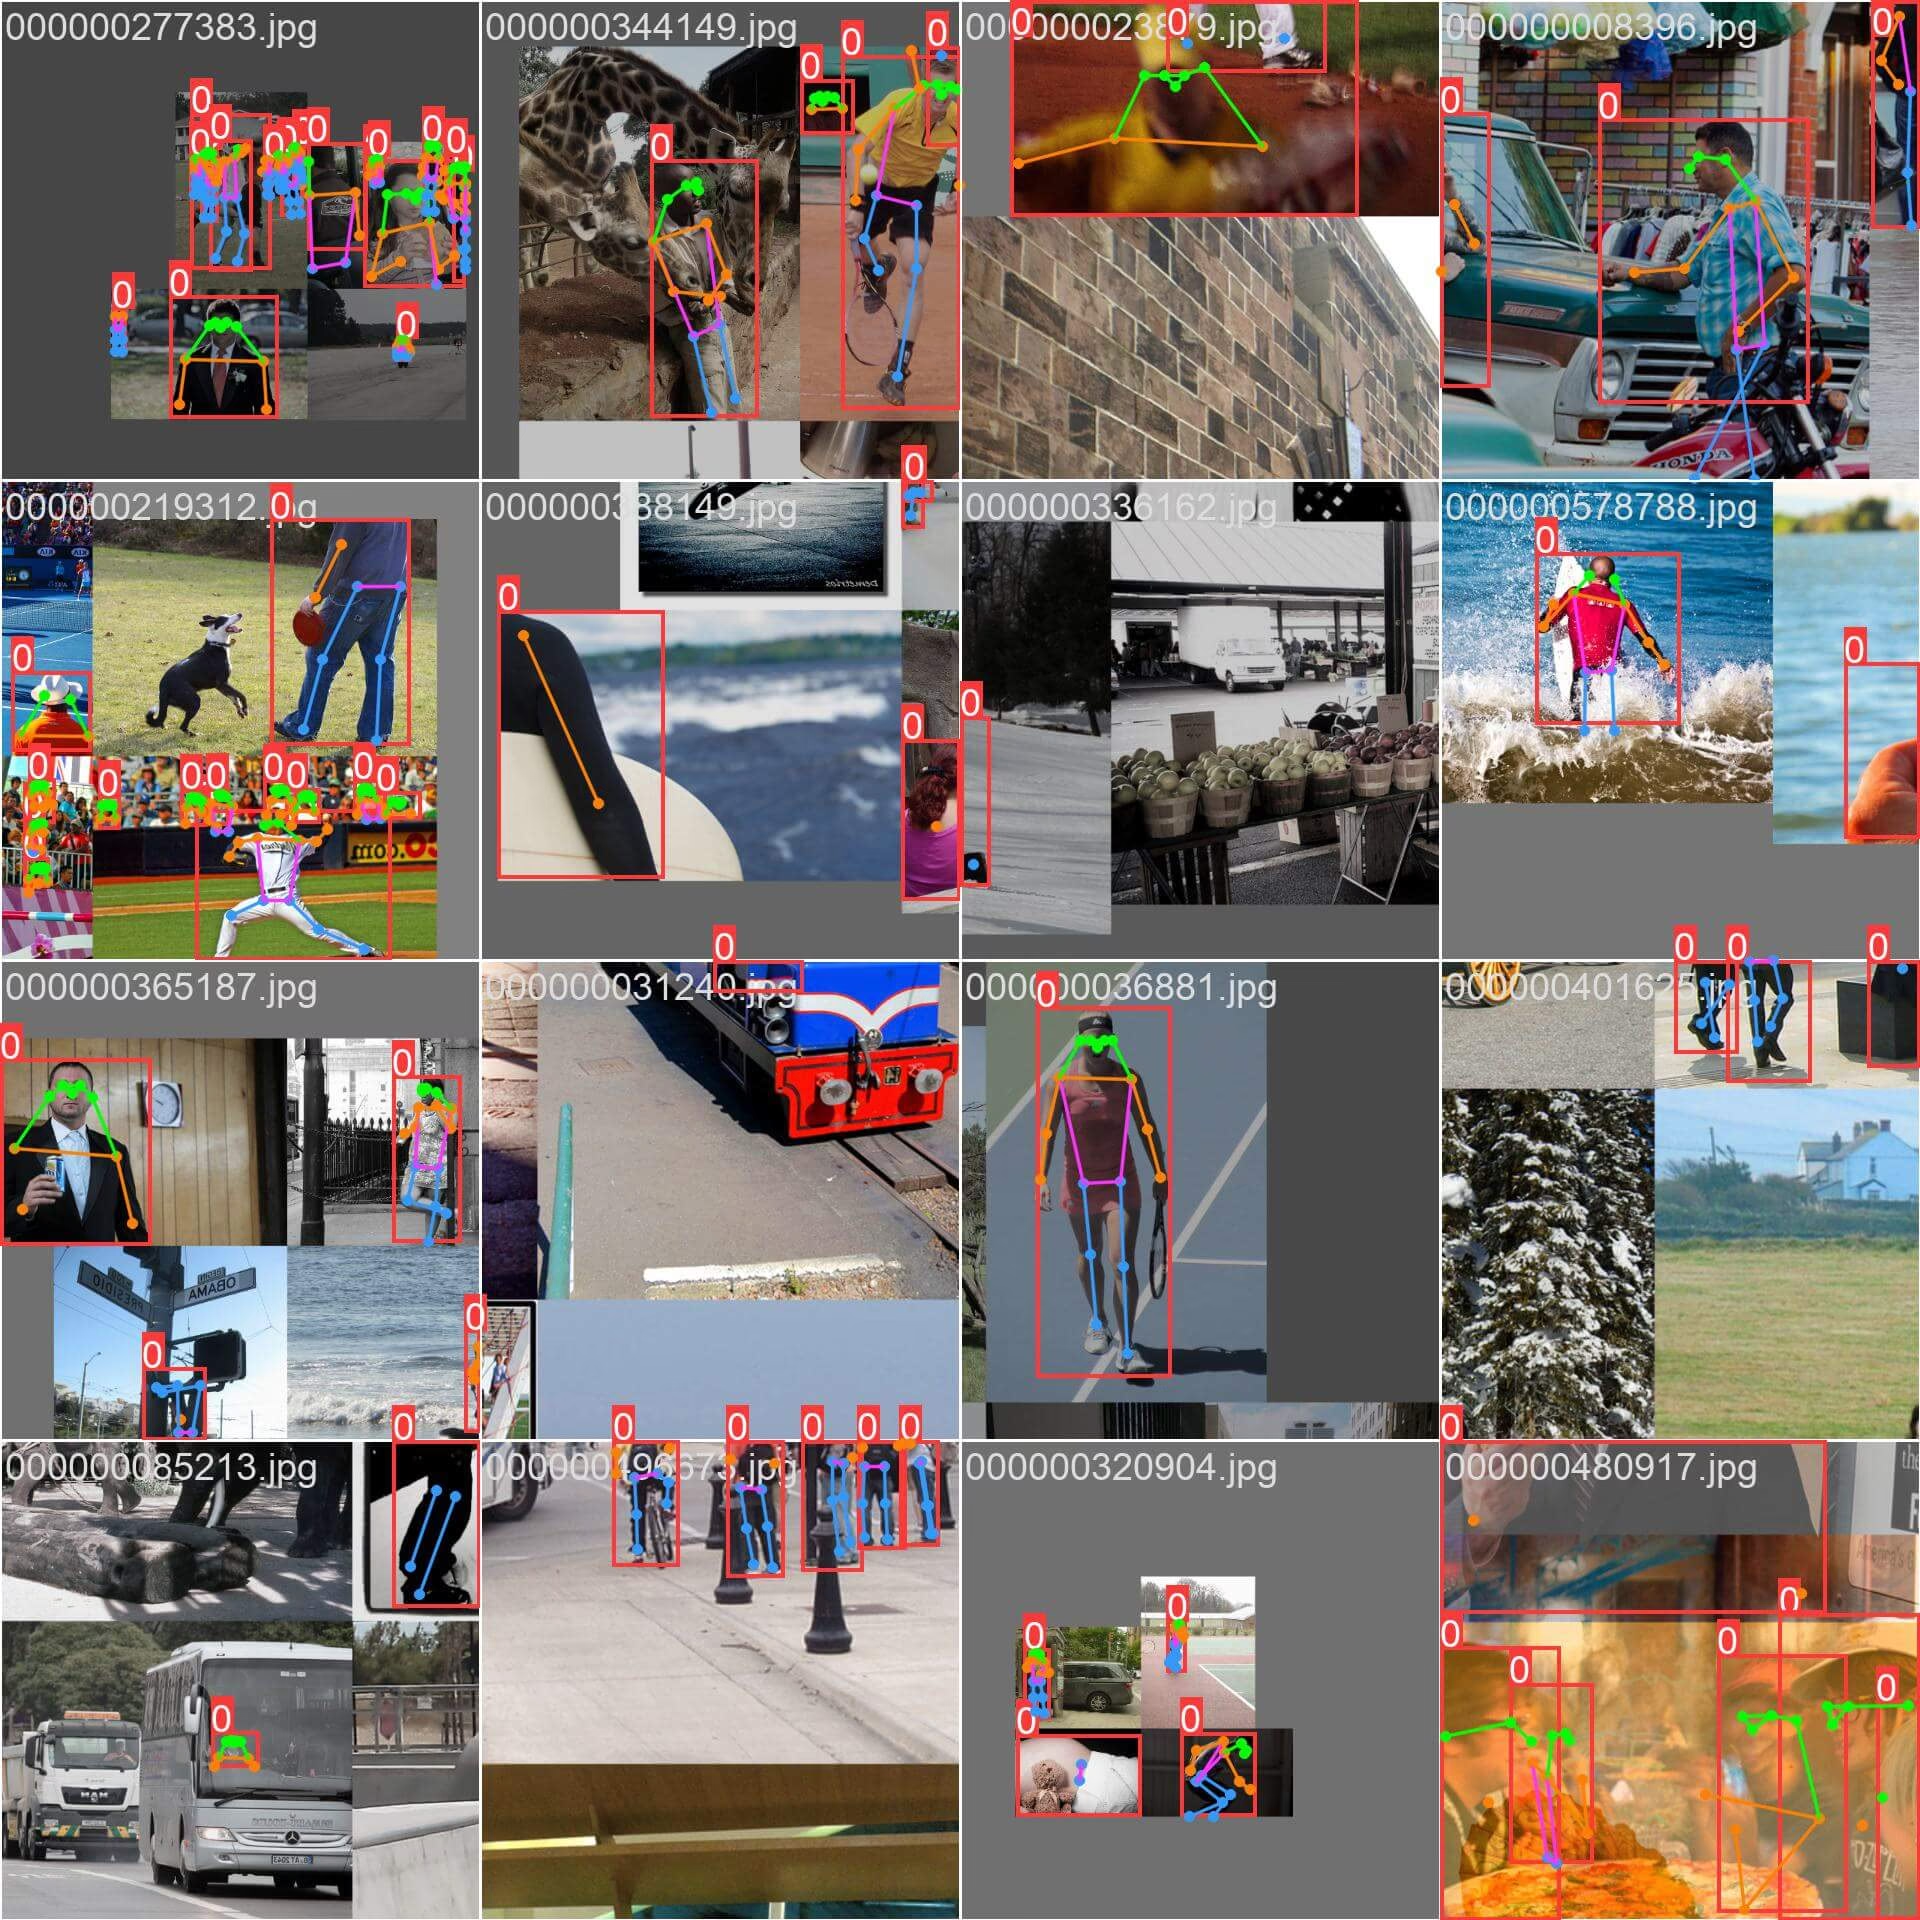
- Mosaiced Image: This image demonstrates a training batch composed of mosaiced dataset images. Mosaicing is a technique used during training that combines multiple images into a single image to increase the variety of objects and scenes within each training batch. This helps improve the model's ability to generalize to different object sizes, aspect ratios, and contexts.
The example showcases the variety and complexity of the images in the COCO-Pose dataset and the benefits of using mosaicing during the training process.
Citations and Acknowledgments#
If you use the COCO-Pose dataset in your research or development work, please cite the following paper:
@misc{lin2015microsoft,
      title={Microsoft COCO: Common Objects in Context},
      author={Tsung-Yi Lin and Michael Maire and Serge Belongie and Lubomir Bourdev and Ross Girshick and James Hays and Pietro Perona and Deva Ramanan and C. Lawrence Zitnick and Piotr Dollár},
      year={2015},
      eprint={1405.0312},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}
We would like to acknowledge the COCO Consortium for creating and maintaining this valuable resource for the computer vision community. For more information about the COCO-Pose dataset and its creators, visit the COCO dataset website.
FAQ#
COCO-Pose supplies the COCO Keypoints 2017 images and annotations converted to YOLO keypoint format, using a 17-keypoint schema across 58,945 images. Point any Ultralytics YOLO pose model at it with
data=coco-pose.yaml, and the Training page documents every argument you can tune from there.Load
yolo26n-pose.ptand callmodel.train(data="coco-pose.yaml", epochs=100, imgsz=640)— see the Train Example above for the full Python and CLI snippets, and the training page for a comprehensive list of arguments.The COCO-Pose dataset provides several standardized evaluation metrics for pose estimation tasks, similar to the original COCO dataset. Key metrics include the Object Keypoint Similarity (OKS), which evaluates the accuracy of predicted keypoints against ground truth annotations. These metrics allow for thorough performance comparisons between different models. For instance, the COCO-Pose pretrained models such as YOLO26n-pose, YOLO26s-pose, and others have specific performance metrics listed in the documentation, like mAPpose50-95 and mAPpose50.
COCO-Pose ships two labeled splits: 56,599 train2017 images and 2,346 val2017 images. A third split, test-dev2017 (20,288 of the full 40,670 test2017 images), keeps its ground truth private; the dataset YAML links it to the COCO test-dev keypoints evaluation server. See the Dataset Structure section, or the
coco-pose.yamlfile on GitHub for the exact split paths.COCO-Pose uses 17 human keypoint types and inherits COCO's standardized metrics, including Object Keypoint Similarity (OKS), for comparing models. That combination suits human pose applications such as sports analytics, healthcare, and human-computer interaction. Pretrained YOLO26-pose weights are listed under COCO-Pose Pretrained Models.
For more on keypoint models, see the Pose Estimation task docs.
Comments51
Ask a question, share your results, or help someone else.
xcf1
Hello, I used the trained model to infer the test-dev dataset of coco2017, and converted the inference results into the json format required by coco official. My json file format is like [{"image_id": 16, "category_id": 1, "keypoints": [310, 382, 0, 377, 404, 0, 438, 412, 0, 444, 0, 0, 148, 452, 0, 445, 0, 0, 19, 499, 0, 476, 424, 0, 455, 503, 0, 474, 373, 0, 393, 391, 0, 473, 354, 0, 420, 495, 0, 479, 463, 0, 478, 365, 0, 479, 471, 0, 477, 317, 0], "score": 0.962377}, {"image_id": 16, "category_id": 1, "keypoints": [21, 341, 0, 267, 0, 0, 23, 0, 0, 22, 0, 0, 7, 0, 0, 78, 0, 0, 13, 0, 0, 167, 0, 0, 53, 0, 0, 237, 0, 0, 53, 0, 0, 212, 0, 0, 75, 14, 0, 323, 7, 0, 240, 9, 0, 292, 0, 0, 223, 0, 0], "score": 0.233321}, {"image_id": 57, "category_id": 1, "keypoints": [443, 223, 0, 556, 263, 0, 629, 268, 0, 618, 259, 0, 592, 280, 0, 568, 256, 0, 405, 290, 0, 638, 256, 0, 635, 306, 0, 632, 284, 0, 612, 326, 0, 624, 325, 0, 597, 288, 0, 639, 265, 0, 638, 308, 0, 638, 281, 0, 638, 300, 0], "score": 0.988164},...........], but after uploading to the official website, I still got an error: AssertionError: Results do not correspond to current coco set. Could you please tell me the reason? Can you provide an accurate json file format, or give me a code that converts the predicted results into the correct json file? Thank you very much.
 Glenn JocherUltralytics(edited)
@xcf1 thank you for your question. The AssertionError typically occurs when your results file doesn't match COCO's expected format for keypoints. For COCO test-dev2017 submissions, please ensure your JSON follows the exact format shown in the COCO keypoints evaluation format. The keypoints array should contain 17 keypoints in (x,y,visibility) format where visibility=2 for visible points.
Here's a minimal validation script to generate correct JSON:
from ultralytics import YOLO

model = YOLO('yolo26n-pose.pt')
model.val(data='coco-pose.yaml', split='test-dev', save_json=True)
This will automatically generate a properly formatted
predictions.jsonin your runs/val directory. For further assistance, please review the COCO evaluation guidelines.Thank you very much for your reply. I have obtained the results.json file, but when I upload its compressed package to the COCO official website, the webpage displays a file loading failure. What could be the reason for this? My compressed file size is 238MB, while the COCO official website specifies a size of about 200MB. Also, the img_id in this JSON file is arranged in descending order. Is there a requirement for the order of IDs? I have also noticed an issue: for the image with img_id 16, the corresponding generated txt file contains many lines of data, even though there are only two people in the image, suggesting a mismatch in data. Other images seem to be normal.
this is isuue_img
- Glenn JocherUltralytics(edited)
Thank you for the follow-up. The file size discrepancy and ID ordering issues typically occur when not using the official test-dev2017 split. For COCO evaluation server submissions, please ensure you're validating with
split='test-dev'in your validation command to generate results that strictly correspond to the 20,288 test images. The JSON should auto-generate with correct IDs and sizing when using:model.val(data='coco-pose.yaml', split='test-dev', save_json=True)Validation already uses a low confidence threshold by default (
conf=0.001), so you normally don't need to setconf. If issues persist, please verify your dataset YAML points to test-dev2017.txt as shown in the COCO-Pose dataset configuration. Hello, thank you for your reply. I have increased the conf value to reduce the detection size, and now it can be uploaded to the COCO official website for testing. However, I still get the error “AssertionError: Results do not correspond to current coco set.” The content of the JSON file generated by the code you provided is as shown in the image below. What could be the reason for this? I have been struggling with this issue for a long time, and it still persists.
- Glenn JocherUltralytics(edited)
The "AssertionError" typically indicates mismatched image IDs between your results and COCO's test-dev2017 set. Please ensure you're validating with the exact command:
model.val(data='coco-pose.yaml', split='test-dev', save_json=True)
This guarantees proper ID alignment. For direct verification, compare your JSON's image IDs with those in the test-dev2017.txt from our dataset YAML. Hello, I have already ensured that my results correspond to the images in the COCO2017 test-dev dataset. When I submitted a small subset of my model's inference results in JSON format to the COCO official service platform, it worked and I received evaluation results. However, after adding more images' JSON results, the platform threw an error: "AssertionError: Results do not correspond to current COCO set". I have confirmed that the additional images, such as the one with ID 426923, are indeed in the COCO2017 test-dev dataset. Could you please tell me why this is happening? Thank you very much. hank you very much.
- Glenn JocherUltralytics(edited)
The AssertionError typically occurs when your JSON contains image IDs not present in the official COCO test-dev2017 split (20,288 images). Please verify that all image IDs in your results match those in the test-dev2017.txt list from our dataset YAML. For validation, try loading your JSON with the COCO API's
loadRes()function to detect mismatches. thank you very much,the isuue is solved
- Glenn JocherUltralytics
Great to hear your issue is resolved! For future users encountering similar COCO evaluation challenges, ensure your dataset YAML points to the correct test split and use the official
model.val()method to generate results. Let us know if any other questions arise.
I used my pre-trained model to infer the test-dev2017 dataset and uploaded the inference results to the COCO official website for evaluation, but I encountered an error stating “Results do not correspond to current coco set.” However, my JSON file format complies with the requirements of the COCO official website. Can you help me solve this issue?
- Glenn JocherUltralytics
@xcf1 ensure your results JSON file uses image IDs from the COCO test-dev2017 set (20,288 images) and follows the exact keypoints format required. The error often occurs when using validation set IDs or incorrect keypoint ordering. Double-check against the COCO Keypoints Evaluation page submission requirements.
LeBron-Jian(edited)
hello, I noticed that to train the pose model using the coco dataset, I can use the following code snippet:
# Load a model
model = YOLO("yolov8n-pose.pt")  # load a pretrained model (recommended for training)

# Train the model
results = model.train(data="coco-pose.yaml", epochs=100, imgsz=640, device=[0,1])
But I tested the effect of the given pre-trained model(yolov8n-pose.pt), and the results are as follows:
Then the effect of the pre-trained model has reached the given indicators. So what is the point of using the pre-trained model for training directly, and can it still improve the accuracy?
therefore, if i want to reproduce the effect of yolo-pose on the coco dataset, how should I do it?
- Glenn JocherUltralytics
@LeBron-Jian using a pretrained model like YOLOv8n-pose provides a strong starting point, allowing you to fine-tune on your specific data to potentially improve accuracy. To reproduce the effects on the COCO dataset, ensure you're using the correct dataset configuration and training parameters as outlined in the
coco-pose.yaml. For more details, refer to the COCO-Pose documentation. @glenn-jocher hi, thanks for your reply. I went through the documentation https://docs.ultralytics.com/datasets/pose/coco/,。 I used the original configuration file and did not use the pre-trained model. Can this reproduce the effect of yolo-pose on the coco dataset? the code is as follows:
# build a new model from YAML model = YOLO("cfg/models/v8/yolov8-pose.yaml") # Train the model model.train(data='cfg/datasets/coco-pose.yaml', batch=16, workers=8, device=[0, 1])- Glenn JocherUltralytics
To reproduce the YOLO-Pose results on the COCO dataset, ensure you're using the correct
coco-pose.yamlconfiguration and consider starting with a pretrained model for better initial performance. Fine-tuning on your specific data can help improve accuracy. To reproduce the YOLO-Pose results on the COCO dataset, ensure you're using the correct
coco-pose.yamlconfiguration and consider starting with a pretrained model for better initial performance. Fine-tuning on your specific data can help improve accuracy.hi, I trained the pose model on my own small dataset based on the pre-trained model. my training set is about 200 pictures and the validation set is 40 pictures. the scene is a very simple scene with no occlusion and pure background. I found that the mAP50~95 of both bbox and keypoint are very high, but the keypoints of the actual test pictures are not so accurate. why is this?
the only thing i can think of is the setting of sigmas used in the calculation of metrics. the sigmas i gave is the default
torch.ones(nkpt)/nkptin the code- Glenn JocherUltralytics
High mAP but inaccurate keypoints can result from overfitting, especially with a small dataset. Consider increasing your dataset size or using data augmentation to improve generalization. Adjusting sigma values might help, but focus on data diversity first.
Hello, according to your suggestion, I diversified my own small hand dataset. Then I trained it based on the pre-trained model. I found a strange phenomenon, it is not that the larger the model, the better the effect. (Based on the experience of object detection, the X model is always better than the L model, M model, and S model), but the mAP of the bbox here is relatively stable. As for the mAP of Pose, the mAP of the X model reached 0.888, but the L model only had 0.664, the M model had 0.748, the S model had 0.928, and the nano model had an accuracy of 0.914. This conclusion was obtained when I controlled the training set and the validation set, and epochs=100. This makes me a little confused, why is it? Does it mean that the fine-tuning of the pre-trained model for a small dataset is not that the larger the model, the better the effect?
Is it because the larger the model, the harder it is to converge? Do I need more epochs?
- Glenn JocherUltralytics
@LeBron-Jian model size doesn't always correlate with better performance, especially on small datasets. Smaller models might generalize better due to fewer parameters. Consider experimenting with different architectures and hyperparameters to find the best fit for your specific dataset.
xhf3571
Issue: Error While Running Inference on COCO Test Set
Hello,
I saw your response and code regarding the COCO test set, and I tried running the following code:
from ultralytics import YOLO
import json

# Load the model
model = YOLO("/my/path/best.pt")

# Run inference on the test set
results = model.val(data="coco-pose.yaml", split="test")

# Convert results to COCO format
coco_results = []
for result in results:
    for box in result.boxes:
        coco_results.append({
            "image_id": result.image_id,
            "category_id": box.cls,
            "bbox": box.xywh.tolist(),
            "score": box.conf,
            "keypoints": box.keypoints.tolist()
        })

# Save results to JSON file
with open("coco_results.json", "w") as f:
    json.dump(coco_results, f)
However, I encountered the following error:
  raise FileNotFoundError(f"{self.prefix}Error loading data from {img_path}\n{HELP_URL}") from e
FileNotFoundError: val: Error loading data from /mnt/workspace/ultralytics-8.1.45/ultralytics/cfg/datasets/test-dev2017.txt
See https://docs.ultralytics.com/datasets/detect for dataset formatting guidance.
Could you please tell me the correct steps to resolve this issue? Additionally, what should the output file format be after running the code? What contents should it include? Lastly, should this generated file be submitted to this URL? https://codalab.lisn.upsaclay.fr/competitions/7403#participate-submit_results
Thank you!
- Glenn JocherUltralytics(edited)
@xhf3571 hello,
It looks like the error is due to a missing or incorrect path to the
test-dev2017.txtfile. Ensure that your dataset directory structure matches the paths specified in yourcoco-pose.yamlfile. Verify that thetest-dev2017.txtfile exists in the correct location.Regarding the output file format, your JSON should include the image ID, category ID, bounding box coordinates, confidence score, and keypoints. This format is suitable for submission to the COCO evaluation server, as specified in the competition guidelines.
For more details on dataset formatting, you can refer to the Ultralytics documentation.
Best of luck!
以下是英文简洁版的提问: I adjusted and ran the code, but it still reports an error saying no labels found. I think it is normal for the test set to have no labels. The error is as follows:
WARNING ⚠️ No labels found in /mnt/workspace/ultralytics-8.1.45/ultralytics/assets/test2017.cache, training may not work correctly. See https://docs.ultralytics.com/datasets/detect for dataset formatting guidance.
                 Class     Images  Instances      Box(P          R      mAP50  mAP50-95)     Pose(P          R      mAP50  mAP50-95): 100%|██████████| 1268/1268 [00:57<00:00, 21.92it/s]
                   all      20288          0          0          0          0          0          0          0          0          0
WARNING ⚠️ no labels found in pose set, can not compute metrics without labels
Speed: 0.1ms preprocess, 1.3ms inference, 0.0ms loss, 0.6ms postprocess per image
Results saved to runs/pose/val6
Traceback (most recent call last):
  File "/mnt/workspace/ultralytics-8.1.45/ultralytics/coco-test.py", line 12, in <module>
    for result in results:
TypeError: 'PoseMetrics' object is not iterable
Thank you!
Hi there, I've looked through other responses and tried the following command:
```bash
(yolov8Pose) root@dsw-405310-8475c8cfcb-zbvfs:/mnt/workspace/ultralytics-8.1.45/ultralytics# python detect --source /mnt/workspace/ultralytics-8.1.45/ultralytics/assets/test2017 --weights /mnt/workspace/ultralytics-8.1.45/ultralytics/runs/train/C2F_CCA/weights/best.pt --save-json
However, I encountered an error:
python: can't open file '/mnt/workspace/ultralytics-8.1.45/ultralytics/detect': [Errno 2] No such file or directoryCould you please advise which directory I should be running this command from?
Additionally, I tried running the following command:
python predict model=/mnt/workspace/ultralytics-8.1.45/ultralytics/runs/train/C2F_CCA/weights/best.pt data=coco-pose.yaml split=testBut I received the same type of error:
python: can't open file '/mnt/workspace/ultralytics-8.1.45/ultralytics/predict': [Errno 2] No such file or directoryCould you help clarify where these scripts are located or if there is a step I might be missing?
Thanks for your help!
If the operation is successful, should a JSON file be generated? I noticed that the final submission to the website https://competitions.codalab.org/competitions/12061#participate is a ZIP file. Could you please let me know what else should be included in this ZIP file?
- Glenn JocherUltralytics
@xhf3571 yes, a JSON file should be generated if the operation is successful. For the final submission to the competition, you need to include this JSON file in a ZIP archive. The ZIP file should contain the JSON results formatted according to the competition guidelines. Make sure to follow the specific instructions provided on the competition's submission page to ensure your results are correctly evaluated.
I've posted my specific issue on the GitHub project, and the issue link is: https://github.com/ultralytics/ultralytics/issues/14510. I really need your help as I've been stuck for 3 days now. Thank you so much!
- Glenn JocherUltralytics(edited)
@xhf3571 thank you for sharing the issue link. Please ensure you are using the latest version of the Ultralytics package, as updates often resolve such issues. The error indicates that no labels were found, which is expected for the test set. The
PoseMetricsobject is not iterable becausemodel.val()returns a metrics object, not a list of results.To generate the COCO-format JSON for the test set, set
save_json=True:from ultralytics import YOLO # Load the model model = YOLO("/my/path/best.pt") # Validate on the test split and save COCO-format predictions metrics = model.val(data="coco-pose.yaml", split="test", save_json=True)Ensure the paths in your
coco-pose.yamlare correct and point to the appropriate test set files. Apredictions.jsonfile is written to the validation run directory (for exampleruns/pose/val); zip it and submit it as required by the competition guidelines. If the issue persists, please update the GitHub issue with any new error messages or behavior observed. Thank you for your response. I have now switched to the latest version of YOLOv8, version 8.2.59, and am running the following code:
```python
from ultralytics import YOLO
import json

# Load the model
model = YOLO("/root/lanyun-tmp/ultralytics-8.2.59/ultralytics/runs/train/C2F_CCA/weights/best.pt")

# Run inference on the test set
results = model.predict(source="/root/lanyun-tmp/ultralytics-8.1.45/ultralytics/assets/test2017")

# Convert results to COCO format
coco_results = []
for result in results:
    for box in result.boxes:
        coco_results.append({
            "image_id": result.image_id,
            "category_id": box.cls,
            "bbox": box.xywh.tolist(),
            "score": box.conf,
            "keypoints": box.keypoints.tolist()
        })

# Save results to JSON file
with open("coco_results.json", "w") as f:
    json.dump(coco_results, f)
I encountered the following error:
image 40665/40670 /root/lanyun-tmp/ultralytics-8.1.45/ultralytics/assets/test2017/000000581864.jpg: 480x640 2 persons, 16.0ms
image 40666/40670 /root/lanyun-tmp/ultralytics-8.1.45/ultralytics/assets/test2017/000000581872.jpg: 480x640 (no detections), 15.5ms
image 40667/40670 /root/lanyun-tmp/ultralytics-8.1.45/ultralytics/assets/test2017/000000581897.jpg: 448x640 (no detections), 15.8ms
image 40668/40670 /root/lanyun-tmp/ultralytics-8.1.45/ultralytics/assets/test2017/000000581908.jpg: 640x640 (no detections), 18.1ms
image 40669/40670 Traceback (most recent call last):
  File "/root/autodl-tmp/ultralytics-8.2.59/ultralytics/coco-test.py", line 17, in <module>
    "image_id": result.image_id,
  File "/root/autodl-tmp/ultralytics-8.2.59/ultralytics/utils/__init__.py", line 160, in __getattr__
    raise AttributeError(f"'{name}' object has no attribute '{attr}'. See valid attributes below.\n{self.__doc__}")
AttributeError: 'Results' object has no attribute 'image_id'. See valid attributes below.
ValueError: not enough values to unpack (expected 4, got 1)
I am using the new version of YOLOv8, and it seems to predict correctly, but I am still unable to generate the JSON file for evaluation on the COCO test set. Could you please provide me with the correct and complete code to generate this? I have been working on this for four days now.
Thank you and look forward to your reply
- Glenn JocherUltralytics(edited)
@xhf3571 thank you for updating to the latest version. The error you're encountering indicates that the
Resultsobject does not have animage_idattribute, andresult.boxesdoes not hold keypoints (they are inresult.keypoints). Rather than assembling the COCO JSON by hand, let validation write it for you:from ultralytics import YOLO # Load the model model = YOLO("path/to/best.pt") # Validate on the test split and save COCO-format predictions metrics = model.val(data="coco-pose.yaml", split="test", save_json=True)This writes
predictions.json(image IDs, category IDs, boxes, scores and keypoints) to the validation run directory, for exampleruns/pose/val. Once you have the JSON file, you can zip it and submit it to the competition as specified. If you encounter further issues, please update the GitHub issue with the new error details. Thank you for your response. I've run into an issue when executing the new code:
```python
from ultralytics import YOLO
import json
import os

# Load the model
model = YOLO("/root/lanyun-tmp/ultralytics-8.2.59/ultralytics/runs/train/C2F_CCA/weights/best.pt")

# Run inference on the test set
results = model.predict(source="/root/lanyun-tmp/ultralytics-8.1.45/ultralytics/assets/test0003")

# Convert results to COCO format
coco_results = []
for result in results:
    image_id = int(os.path.basename(result.path).split('.')[0])
    for box in result.boxes:
        coco_results.append({
            "image_id": image_id,
            "category_id": box.cls,
            "bbox": box.xywh.tolist(),
            "score": box.conf,
            "keypoints": box.keypoints.tolist()
        })

# Save results to JSON file
with open("coco_results.json", "w") as f:
    json.dump(coco_results, f)
The error I'm encountering is:
Traceback (most recent call last):
  File "coco-test.py", line 21, in <module>
    "keypoints": box.keypoints.tolist()
  File "/root/lanyun-tmp/ultralytics-8.2.59/ultralytics/utils/__init__.py", line 162, in __getattr__
    raise AttributeError(f"'{name}' object has no attribute '{attr}'. See valid attributes below.\n{self.__doc__}")
AttributeError: 'Boxes' object has no attribute 'keypoints'. See valid attributes below.
Thank you and look forward to your reply
- Glenn JocherUltralytics(edited)
@xhf3571 it looks like the
Boxesobject does not have akeypointsattribute. This is likely because the model you are using is not a pose estimation model or the predictions do not include keypoints. Ensure you are using a pose-specific model likeyolo26n-pose.pt. If the problem persists, please verify that your model and dataset are correctly configured for pose estimation. If you need further assistance, please update the issue with any new details. Thank you for your reply. I used the official
yolov8n-pose.ptbut still encountered the same error. I referred to the issue link and raised a question in my own issue link. I am very confused about which method to use to correctly generate the JSON evaluation file. This seems like a small task, but I have been struggling with it for 5 days. Please help me, I would be extremely grateful.Thank you very much, and I look forward to your response.
- Glenn JocherUltralytics
Thank you for your patience. Since you're using the official
yolov8n-pose.ptmodel and still encountering issues, please ensure you have the latest version of the Ultralytics package. The error suggests that theBoxesobject does not containkeypoints. Verify that your model is correctly configured for pose estimation and that your dataset paths are accurate. If the problem persists, please update your GitHub issue with any new details or errors. This will help us provide more targeted assistance.
Hi,
I've noticed some inconsistencies in the reported numbers of images in the COCO-Pose dataset across different sources. For instance, some papers mention that the train2017 set includes 57K images, whereas the val2017 and test-dev2017 sets consist of 5K and 20K images respectively. However, the dataset I downloaded has over 64,000 images in the training set and only about 2,600 images in the validation set.
Could you please clarify the official numbers of images used in the COCO-Pose dataset? Knowing the exact figures would be very helpful for my research.
Thank you for your assistance.
Best regards,
I recently redownloaded the COCO-pose using the coco-pose.yaml configuration. I noticed that in the coco-pose/labels/val2017 directory, there are only 2346 .txt files, whereas the coco-pose/images/val2017 directory contains 5000 images. Is this discrepancy expected?
Additionally, I observed that coco-pose/labels/train2017 contains 56599 .txt files, but I encountered a failure while downloading the train2017 images. I plan to manually download these images and match them with the 56599 .txt files. Would this approach be appropriate?
Thank you for your assistance.
- Glenn JocherUltralytics
@xhf3571 hi there,
Thank you for your detailed observation and for bringing this to our attention.
The discrepancy you're noticing between the number of images and labels in the COCO-Pose dataset is indeed expected. The COCO dataset, including its pose estimation subset, often has more images than annotations because not all images contain the objects or keypoints of interest.
Val2017 Set
- Images: 5000
- Annotations: 2346
Train2017 Set
- Images: 118,287 (as per the full COCO dataset)
- Annotations: 56,599
For the val2017 set, the 5000 images include those without keypoint annotations, which explains why there are fewer
.txtfiles. Similarly, for the train2017 set, the number of images and annotations can differ due to the same reason.Downloading and Matching Images
Your approach to manually download the images and match them with the 56,599
.txtfiles is appropriate. Ensure that the images are correctly placed in the directory structure as specified in thecoco-pose.yamlfile.path: ../datasets/coco-pose train: train2017.txt val: val2017.txt test: test-dev2017.txtAdditional Resources
For more detailed information and to ensure you're using the latest dataset configuration, please refer to the COCO-Pose Dataset Documentation.
If you encounter any further issues or have additional questions, please provide a minimum reproducible example of your setup and code. This will help us assist you more effectively. You can find guidelines for creating a reproducible example here.
Thank you for your understanding and cooperation. Happy training! 🚀
aridas96
I used Roboflow for annotation and downloaded the dataset in YOLOv8 TXT format.
code snippet which i used for Training and Testing,
For Training
from ultralytics import YOLO
model = YOLO("yolov8n-pose.yaml") # build a new model from YAML model = YOLO("yolov8n-pose.pt") # load a pretrained model (recommended for training) model = YOLO("yolov8n-pose.yaml").load("yolov8n-pose.pt") # build from YAML and transfer weights
results = model.train(data="data.yaml", epochs=100, imgsz=640)
#For Testing model = YOLO("best.pt") results = model("path to my image.jpg") for result in results: result.show(kpt_line=True) # Ensure kpt_line is set to True to show connections
When I try to test my image I am getting the key points at the exact position as I annotated but the key point connections(lines) are missing. I have also attached the data.yaml file which I used for training.
On Sun, Jun 23, 2024 at 10:37 PM Paula Derrenger @.***> wrote:
@aridas96 https://github.com/aridas96 hello,
Thank you for reaching out and for your detailed description of the issue you're encountering. It sounds like you've successfully trained your YOLOv8n-pose model, but you're not seeing the keypoint connections in your predictions.
To help you better, could you please confirm the following:
Reproducible Code Example: Ensure that you provide a minimum reproducible code example. This helps us replicate the issue on our end and investigate a solution. You can refer to our guide on creating a minimum reproducible example here https://docs.ultralytics.com/help/minimum_reproducible_example. 2.
Package Versions: Verify that you are using the latest versions of torch and ultralytics. If not, please upgrade your packages and try again:
pip install --upgrade torch ultralytics
Regarding the keypoint connections, you can visualize them by ensuring that the show method is correctly configured to display the connections. Here's a quick example of how you can do this:
from ultralytics import YOLO
Load the trained modelmodel = YOLO("path/to/your/trained/model.pt")
Run inference on an imageresults = model("path/to/your/image.jpg")
Visualize the results with keypoint connectionsfor result in results:
result.show(kpt_line=True) # Ensure kpt_line is set to True to show connectionsIf you still face issues, please provide the specific code snippet you used for testing and any relevant details about your environment. This will help us diagnose the problem more effectively.
For more detailed information on pose estimation datasets and configurations, you can visit our Pose Estimation Datasets https://docs.ultralytics.com/datasets/pose/ documentation.
Looking forward to your response!
— Reply to this email directly, view it on GitHub https://github.com/orgs/ultralytics/discussions/13816#discussioncomment-9852983, or unsubscribe https://github.com/notifications/unsubscribe-auth/A7NLL37OY4HURNR4RI5N7H3ZI36FDAVCNFSM6AAAAABJS7OUKCVHI2DSMVQWIX3LMV43SRDJONRXK43TNFXW4Q3PNVWWK3TUHM4TQNJSHE4DG . You are receiving this because you were mentioned.Message ID: @.*** com>
- Glenn JocherUltralytics
Hi @aridas96,
Thank you for providing detailed information about your issue. It sounds like you've successfully trained your YOLOv8n-pose model, but you're encountering a problem with visualizing keypoint connections during inference.
To assist you better, could you please confirm the following:
-
Reproducible Code Example: Ensure that you provide a minimum reproducible code example. This helps us replicate the issue on our end and investigate a solution. You can refer to our guide on creating a minimum reproducible example here.
-
Package Versions: Verify that you are using the latest versions of
torchandultralytics. If not, please upgrade your packages and try again:pip install --upgrade torch ultralytics
Regarding the keypoint connections, it seems like you are already using the
kpt_line=Trueparameter, which is correct. Here’s a quick example to ensure everything is set up properly:from ultralytics import YOLO # Load the trained model model = YOLO("best.pt") # Run inference on an image results = model("path/to/your/image.jpg") # Visualize the results with keypoint connections for result in results: result.show(kpt_line=True) # Ensure kpt_line is set to True to show connectionsIf you still face issues, please provide the specific code snippet you used for testing and any relevant details about your environment. This will help us diagnose the problem more effectively.
For more detailed information on pose estimation datasets and configurations, you can visit our Pose Estimation Datasets documentation.
Looking forward to your response!
-
I have trained the yolov8n-pose.yaml model on the yolov8 dataset which I exported directly from roboflow, after training I tested it with images and videos I can't find the key point connections lines only key points are visible
 Paula DerrengerUltralytics
@aridas96 hello,
Thank you for reaching out and for your detailed description of the issue you're encountering. It sounds like you've successfully trained your YOLOv8n-pose model, but you're not seeing the keypoint connections in your predictions.
To help you better, could you please confirm the following:
-
Reproducible Code Example: Ensure that you provide a minimum reproducible code example. This helps us replicate the issue on our end and investigate a solution. You can refer to our guide on creating a minimum reproducible example here.
-
Package Versions: Verify that you are using the latest versions of
torchandultralytics. If not, please upgrade your packages and try again:pip install --upgrade torch ultralytics
Regarding the keypoint connections, you can visualize them by ensuring that the
showmethod is correctly configured to display the connections. Here's a quick example of how you can do this:from ultralytics import YOLO # Load the trained model model = YOLO("path/to/your/trained/model.pt") # Run inference on an image results = model("path/to/your/image.jpg") # Visualize the results with keypoint connections for result in results: result.show(kpt_line=True) # Ensure kpt_line is set to True to show connectionsIf you still face issues, please provide the specific code snippet you used for testing and any relevant details about your environment. This will help us diagnose the problem more effectively.
For more detailed information on pose estimation datasets and configurations, you can visit our Pose Estimation Datasets documentation.
Looking forward to your response!
-
perry-smartsizer
Is there any documentation around on using a YOLO Pose model when there are multiple classes, each with a separate set of keypoints? For example, how would this YAML look if we wanted to have both a "person" and a "tiger" class. Thanks!
- Paula DerrengerUltralytics(edited)
@perry-smartsizer hi there!
Thank you for your question. Ultralytics YOLO pose does not support a different set of keypoints per class. A dataset has a single
kpt_shapeand a singleflip_idxthat apply to all classes, so a YAML with per-classkpt_shapewill not work.You have two options:
- Train separate models (one dataset YAML per keypoint layout), for example one for
person(17 keypoints) and one fortiger(12 keypoints). - Use one dataset with the maximum number of keypoints and pad unused keypoints with
0 0 0(x, y, visibility), where visibility 0 marks them as missing.
Example YAML for the second option (person with 17 keypoints, tiger padded to 17):
path: ../datasets/multi-class-pose
train: images/train
val: images/val

kpt_shape: [17, 3] # number of keypoints, number of dims (2 for x,y or 3 for x,y,visible)
flip_idx: [0, 2, 1, 4, 3, 6, 5, 8, 7, 10, 9, 12, 11, 14, 13, 16, 15] # must match your own keypoint ordering

names:
  0: person
  1: tiger
Every label row then has the form
<class-index> <x> <y> <width> <height> <px1> <py1> <p1-visibility> ... <px17> <py17> <p17-visibility>.To train your model:
from ultralytics import YOLO

# Load a model
model = YOLO("yolo26n-pose.pt")  # load a pretrained model

# Train the model
results = model.train(data="multi-class-pose.yaml", epochs=100, imgsz=640)
Or via CLI:
yolo pose train data=multi-class-pose.yaml model=yolo26n-pose.pt epochs=100 imgsz=640For more detailed information on dataset preparation and configuration, please refer to our Pose Estimation Datasets Documentation.
I hope this helps! If you have any further questions, feel free to ask. 😊
- Train separate models (one dataset YAML per keypoint layout), for example one for
WangDayeYa
Hi, is the coco dataset that you train keypoint detection with directly from the coco website, or is there another dataset, is it necessary to have people present on the training images when performing keypoint detection, could you please help me with this question. Or does the coco dataset need to be filtered when performing keypoint detection in order to filter out images with people present? Hope to get your help on this.
- Paula DerrengerUltralytics(edited)
Hello!
Yes, the COCO-Pose dataset used for keypoint detection with YOLOv8 is based directly on the COCO dataset available from the COCO website. Specifically, it leverages the COCO Keypoints 2017 images and labels to train models for pose estimation tasks.
For keypoint detection, it's indeed necessary for the images to have people present because the dataset supports 17 human keypoints to facilitate detailed pose estimation. There's no need to filter out images without people for this task, as the COCO-Pose dataset is already curated to include images annotated with keypoints relevant to pose estimation.
The Coco-Pose dataset does include images with people and has annotations for human keypoints. So, you don't need to filter out images without people. This dataset is specifically structured to aid in pose estimation tasks and includes a variety of images that are annotated for this purpose. Here’s a quick peek into how you can train a pose model with our dataset:
from ultralytics import YOLO

# Load a pretrained pose estimation model
model = YOLO("yolo26n-pose.pt")

# Train the model on the COCO-Pose dataset
results = model.train(data="coco-pose.yaml", epochs=100, imgsz=640)
This command will use images that already have people in them and are labeled for pose estimation. If you need further details or assistance, feel free to ask. Happy modeling! 😊
Hello, could you please provide the download link of the coco-pose dataset, so that I can start to perform a replay of the key point detection? How did you come up with those evaluation indicators? What are the specific data set requirements and parameter configurations?
- Paula DerrengerUltralytics(edited)
@WangDayeYa hey there! 🌟
For the COCO-Pose dataset, the labels are downloaded from Ultralytics and the images from the official COCO Dataset website.
data=coco-pose.yamldoes this automatically on first use, or you can run the same download yourself:from pathlib import Path from ultralytics.utils import ASSETS_URL from ultralytics.utils.downloads import download # Dataset root directory dir = Path("../datasets/coco-pose") # Labels download([f"{ASSETS_URL}/coco2017labels-pose.zip"], dir=dir.parent) # Images urls = [ "http://images.cocodataset.org/zips/train2017.zip", # 118k training images "http://images.cocodataset.org/zips/val2017.zip", # 5k validation images ] download(urls, dir=dir / "images", threads=3)The evaluation indicators, such as Object Keypoint Similarity (OKS), are standardized metrics provided by COCO to facilitate performance comparison across different models on pose estimation tasks.
For training on the COCO-Pose dataset, your dataset YAML file (
coco-pose.yaml) is crucial. Here's how you'd train a YOLO26n-pose model for 100 epochs with images sized at 640:yolo pose train data=coco-pose.yaml model=yolo26n-pose.pt epochs=100 imgsz=640This setup assumes
coco-pose.yamlis properly pointing to your COCO-Pose dataset's directory and the dataset files.Hope this gets you started on the right foot with keypoint detection! If you've got more questions, feel free to reach out. Happy detecting! 😊
Okay, According to your description, are you guys using the corresponding labeling information of train2017 and val2017 in the labels of coco2017labels-pose.zip in yolov5 to filter all the coco dataset images in order to get the coco-pose dataset for training.In other words, are you training and validating the dataset images corresponding to the labels file of coco2017labels-pose.zip in yolov5? may I ask how many rounds of training on the coco-pose dataset did you get your data results inside the document?Thank you.
- Paula DerrengerUltralytics(edited)
@WangDayeYa hey there! 👋
Yes, you're correct! We use the labeling information from
train2017andval2017found in thecoco2017labels-pose.zipfor filtering the COCO dataset images to obtain the COCO-Pose dataset. This enables our models, such as YOLO26n-pose, to be trained and validated specifically for pose estimation tasks using these annotated images.Regarding the number of training epochs, the performance results documented are typically achieved after comprehensive training, often spanning hundreds of epochs to maximize accuracy and model effervescence. The specific number of epochs may vary depending on the model and training configurations.
For example, to train a pose estimation model like YOLO26n-pose, you might use:
yolo pose train data=coco-pose.yaml model=yolo26n-pose.pt epochs=100 imgsz=640This command initiates training with the COCO-Pose dataset, targeting 100 epochs.
Each model listed in the docs is trained to ensure optimal performance, with detailed evaluations conducted to generate the documentation results. For up-to-date performance metrics, it's a good idea to refer to our official documentation and experiment logs. 😊
Thanks for your question, and best of luck with your pose estimation projects!