YOLO26 모델을 TFLite Edge TPU 형식으로 내보내기
모바일 또는 임베디드 시스템처럼 연산 능력이 제한된 기기에 컴퓨터 비전 모델을 배포하는 일은 까다로울 수 있습니다. 더 빠른 성능에 최적화된 모델 형식을 사용하면 이 과정을 간소화할 수 있습니다. TensorFlow Lite Edge TPU 또는 TFLite Edge TPU 모델 형식은 신경망에 빠른 성능을 제공하면서 전력 소비를 최소화하도록 설계되었습니다.
TFLite Edge TPU 형식으로 내보내면 Ultralytics YOLO26 모델을 고속 저전력 추론에 맞게 최적화할 수 있습니다. 이 가이드에서는 모델을 TFLite Edge TPU 형식으로 변환하는 방법을 살펴보고, 다양한 모바일 및 임베디드 기기에서 모델이 원활하게 작동하도록 지원합니다.
TFLite Edge TPU로 내보내야 하는 이유는 무엇인가요?#
모델을 TensorFlow Edge TPU로 내보내면 머신러닝 작업을 빠르고 효율적으로 수행할 수 있습니다. 이 기술은 전력, 컴퓨팅 리소스, 연결성이 제한된 애플리케이션에 적합합니다. Edge TPU는 Google의 텐서 처리 장치(TPU) 하드웨어 가속기를 엣지 환경에 맞게 구현한 버전입니다. 엣지 기기에서 TensorFlow Lite 모델의 실행 속도를 높입니다. 아래 이미지는 관련 프로세스의 예시를 보여줍니다.
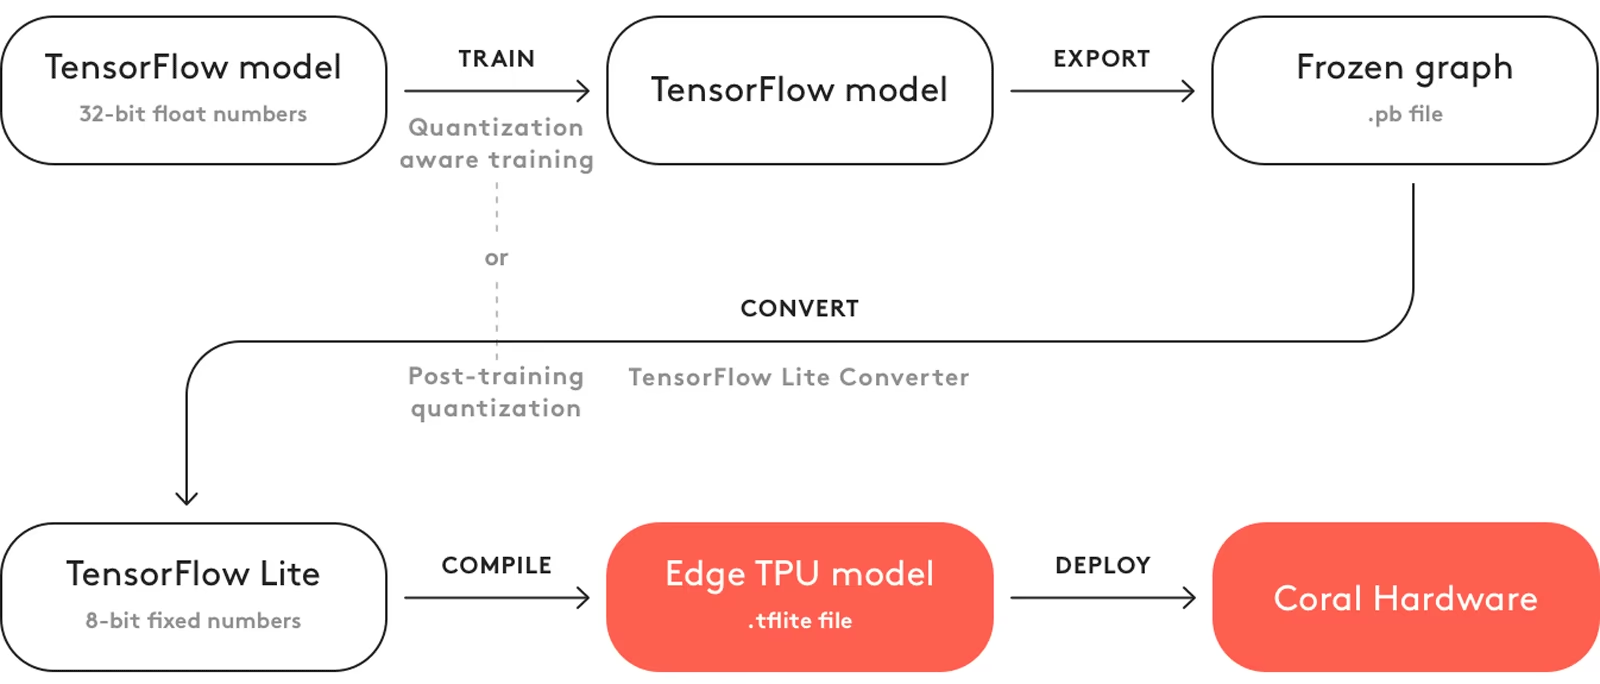
Edge TPU는 양자화된 모델과 함께 작동합니다. 양자화는 정확도를 크게 떨어뜨리지 않으면서 모델을 더 작고 빠르게 만듭니다. 리소스가 제한된 엣지 컴퓨팅에 적합하며, 지연 시간을 줄이고 데이터를 로컬에서 빠르게 처리해 클라우드에 의존하지 않고 애플리케이션이 신속하게 응답하도록 합니다. 로컬 처리는 사용자 데이터를 원격 서버로 전송하지 않으므로 데이터의 개인정보와 보안도 유지합니다.
TFLite Edge TPU의 주요 기능#
TFLite Edge TPU가 개발자에게 매력적인 모델 형식인 이유를 보여주는 주요 기능은 다음과 같습니다.
-
엣지 기기 성능 최적화: TFLite Edge TPU는 양자화, 모델 최적화, 하드웨어 가속, 컴파일러 최적화를 통해 신경망 추론 속도를 높입니다. 미니멀한 아키텍처 덕분에 크기가 작고 비용 효율적입니다.
-
높은 연산 처리량: TFLite Edge TPU는 전용 하드웨어 가속과 효율적인 런타임 실행을 결합하여 높은 연산 처리량을 달성합니다. 엣지 디바이스에서 엄격한 성능 요구 사항을 충족해야 하는 머신러닝 모델을 배포하는 데 적합합니다.
-
효율적인 행렬 연산: TensorFlow Edge TPU는 신경망 연산에 중요한 행렬 연산에 최적화되어 있습니다. 이러한 효율성은 머신러닝 모델, 특히 복잡한 행렬 곱셈과 변환을 많이 수행해야 하는 모델에서 핵심적인 역할을 합니다.
TFLite Edge TPU 배포 옵션#
YOLO26 모델을 TFLite Edge TPU 형식으로 내보내기 전에, 이러한 모델이 일반적으로 어디에 사용되는지 알아두면 도움이 됩니다.
TFLite Edge TPU는 머신러닝 모델에 다음과 같은 다양한 배포 옵션을 제공합니다.
-
온디바이스 배포: TensorFlow Edge TPU 모델은 모바일 및 임베디드 디바이스에 직접 배포할 수 있습니다. 온디바이스 배포를 사용하면 모델을 애플리케이션 번들에 포함하거나 필요할 때 다운로드하여 하드웨어에서 직접 실행할 수 있으므로 클라우드 연결이 필요하지 않습니다.
-
하이브리드 배포: 하이브리드 방식은 온디바이스 배포와 클라우드 배포를 결합하여 머신러닝 모델을 배포하는 다용도 확장형 솔루션을 제공합니다. 빠른 응답을 위한 온디바이스 처리와 복잡한 연산을 위한 클라우드 컴퓨팅이 장점입니다.
지원 작업#
Edge TPU 내보내기는 Ultralytics의 7개 작업 중 6개를 지원합니다. 의미론적 분할은 해당 헤드를 제공하는 유일한 제품군인 YOLO26에서만 사용할 수 있습니다. INT8 모델이 Edge TPU 컴파일러에서 파싱할 수 없는 EXP v2 연산자를 출력하므로 깊이 추정은 지원되지 않습니다.
Edge TPU 컴파일러는 지원하는 연산을 가속기에 매핑하고 나머지는 CPU에서 실행하므로, 작업을 지원한다고 해서 모든 연산이 TPU에서 실행되는 것은 아닙니다.
YOLO26 모델을 TFLite Edge TPU로 내보내기#
YOLO26 모델을 TensorFlow Edge TPU로 변환하면 모델 호환성과 배포 유연성을 높일 수 있습니다.
설치#
필수 패키지를 설치하려면 다음을 실행하세요:
# Install the required package for YOLO26
pip install ultralytics
설치 절차에 대한 자세한 지침과 모범 사례는 Ultralytics 설치 가이드를 참조하세요. YOLO26에 필요한 패키지를 설치하는 중 문제가 발생하면 해결 방법과 팁을 확인할 수 있는 일반적인 문제 가이드를 참조하세요.
사용법#
모든 Ultralytics YOLO26 모델은 별도의 설정 없이 내보내기를 지원하도록 설계되어 있어 원하는 배포 워크플로에 쉽게 통합할 수 있습니다. 애플리케이션에 가장 적합한 설정을 선택하려면 지원되는 내보내기 형식 및 구성 옵션 전체 목록을 확인하세요.
TFLite Edge TPU 형식은 내보내기, 예측, 검증 모드를 지원합니다. 추론과 검증은 Coral Edge TPU 하드웨어에서 실행됩니다. 모델을 내보낸 다음 내보낸 모델을 로드하여 추론을 실행하거나 정확도를 검증하세요.
from ultralytics import YOLO

# YOLO26 모델 로드
model = YOLO("yolo26n.pt")

# 모델을 TFLite Edge TPU 형식으로 내보냅니다
model.export(format="edgetpu") # 'yolo26n_saved_model/yolo26n_full_integer_quant_edgetpu.tflite'를 생성합니다from ultralytics import YOLO
# 내보낸 TFLite Edge TPU 모델을 로드합니다
model = YOLO("yolo26n_saved_model/yolo26n_full_integer_quant_edgetpu.tflite")
# 추론 실행
results = model("https://ultralytics.com/images/bus.jpg")from ultralytics import YOLO
# 내보낸 TFLite Edge TPU 모델을 로드합니다
model = YOLO("yolo26n_saved_model/yolo26n_full_integer_quant_edgetpu.tflite")
# COCO8 데이터셋에서 정확도 검증
metrics = model.val(data="coco8.yaml")내보내기 인수#
| 인수 | 유형 | 기본값 | 설명 |
|---|---|---|---|
format | str | 'edgetpu' | 내보낸 모델의 대상 형식으로, 다양한 배포 환경과의 호환성을 정의합니다. |
imgsz | int 또는 tuple | 640 | 모델 입력에 사용할 이미지 크기입니다. 정사각형 이미지에는 정수를 사용하고, 특정 크기에는 튜플 (height, width)을 사용할 수 있습니다. |
quantize | int 또는 str | 8/auto | 양자화 정밀도입니다. Edge TPU에는 8 (INT8)이 필요하며 자동으로 활성화됩니다. 이를 통해 모델을 압축하고 정확도 손실을 최소화하면서 엣지 기기에서 추론 속도를 높입니다. 더 이상 사용되지 않는 half/int8 플래그를 대체합니다. |
opset | int | None | 중간 ONNX 그래프의 ONNX opset 버전을 지정합니다. 설정하지 않으면 opset 18을 사용하며(PyTorch < 2.4에서는 더 낮은 버전), 설치된 onnx 버전으로 제한됩니다. |
data | str | None | 양자화에 필수적인 데이터셋 YAML 경로입니다. 분류 작업의 경우 데이터셋 디렉터리 또는 기본 제공 데이터셋 이름을 사용합니다. quantize=8이 지정되지 않으면 Ultralytics가 모델 작업에 맞는 기본 보정 데이터셋을 선택합니다. |
fraction | float, int 또는 list | 1.0 | 비율, 이미지 수 또는 [train, val, test] 비율/개수로 지정하는 보정 하위 집합입니다. 항목이 두 개인 목록에서는 test이 전체로 설정되고, 0는 건너뜁니다. |
device | str | None | 내보내기에 사용할 디바이스를 지정합니다. CPU(device=cpu). |
Edge TPU로 내보낼 때는 x86 Linux 머신을 사용하세요.
내보내기 프로세스에 관한 자세한 내용은 내보내기에 관한 Ultralytics 문서 페이지를 참조하세요.
내보낸 YOLO26 TFLite Edge TPU 모델 배포#
Ultralytics YOLO26 모델을 TFLite Edge TPU 형식으로 성공적으로 내보낸 후에는 모델을 배포할 수 있습니다. 앞서 사용 예제 코드에 설명된 것처럼, TFLite Edge TPU 모델을 실행할 때 가장 먼저 권장하는 방법은 YOLO("model_edgetpu.tflite") 메서드를 사용하는 것입니다.
TFLite Edge TPU 모델 배포에 대한 자세한 지침은 다음 리소스를 참고하세요.
-
Raspberry Pi에서 Ultralytics YOLO26으로 Coral Edge TPU 사용하기: Coral Edge TPU를 Raspberry Pi와 통합하여 머신러닝 기능을 향상하는 방법을 알아보세요.
-
Edge TPU 컴파일러: Edge TPU 컴파일러가 TensorFlow Lite 모델을 가속기에 매핑하는 방법과 지원하는 연산을 알아보세요.
-
Python으로 Edge TPU에서 추론 실행하기: 설정 및 사용 지침을 포함하여 Edge TPU 애플리케이션에 TensorFlow Lite Python API를 사용하는 방법을 살펴보세요.
요약#
이 가이드에서는 Ultralytics YOLO26 모델을 TFLite Edge TPU 형식으로 내보내는 방법을 알아보았습니다. 위 단계를 따르면 엣지 기기에서 컴퓨터 비전 애플리케이션을 더 빠르고 적은 전력으로 실행할 수 있습니다.
사용에 대한 자세한 내용은 Coral Edge TPU 공식 웹사이트를 방문하세요.
자주 묻는 질문#
YOLO26 모델을 TFLite Edge TPU 형식으로 내보내려면 다음 단계를 따르세요.
사용법from ultralytics import YOLO # YOLO26 모델 로드 model = YOLO("yolo26n.pt") # 모델을 TFLite Edge TPU 형식으로 내보냅니다 model.export(format="edgetpu") # 'yolo26n_saved_model/yolo26n_full_integer_quant_edgetpu.tflite'를 생성합니다 # 내보낸 TFLite Edge TPU 모델을 로드합니다 edgetpu_model = YOLO("yolo26n_saved_model/yolo26n_full_integer_quant_edgetpu.tflite") # 추론 실행 results = edgetpu_model("https://ultralytics.com/images/bus.jpg")다른 형식으로 모델을 내보내는 자세한 방법은 내보내기 가이드를 참고하세요.
YOLO26 모델을 TFLite Edge TPU로 내보내면 다양한 이점을 얻을 수 있습니다.
- 최적화된 성능: 전력 소비를 최소화하면서 신경망을 고속으로 실행할 수 있습니다.
- 지연 시간 감소: 클라우드에 의존하지 않고 데이터를 로컬에서 빠르게 처리할 수 있습니다.
- 개인정보 보호 강화: 로컬 처리를 통해 사용자 데이터를 비공개로 안전하게 유지합니다.
따라서 전력과 컴퓨팅 리소스가 제한된 기기를 사용하는 엣지 컴퓨팅 애플리케이션에 적합합니다.
예. TensorFlow Lite Edge TPU 모델은 모바일 및 임베디드 디바이스에 직접 배포할 수 있습니다. 이 배포 방식에서는 모델이 하드웨어에서 직접 실행되므로 추론 속도가 더 빠르고 효율적입니다. 통합 예제는 Raspberry Pi에 Coral Edge TPU를 배포하는 가이드를 참고하세요.
TFLite Edge TPU 모델의 일반적인 사용 사례는 다음과 같습니다.
- 스마트 카메라: 실시간 이미지 및 동영상 분석을 향상합니다.
- IoT 디바이스: 스마트 홈 및 산업 자동화를 구현합니다.
- 헬스케어: 의료 영상 처리 및 진단을 가속화합니다.
- 소매: 재고 관리와 고객 행동 분석을 개선합니다.
이러한 애플리케이션은 TFLite Edge TPU 모델의 높은 성능과 낮은 전력 소비의 이점을 활용합니다. 사용 시나리오를 자세히 알아보세요.
TFLite Edge TPU 모델을 내보내거나 배포하는 중에 문제가 발생하면 문제 해결 방법을 확인할 수 있는 일반적인 문제 가이드를 참고하세요. 이 가이드에서는 원활한 작동을 위해 일반적인 문제와 해결책을 다룹니다. 추가 지원이 필요하면 도움말 센터를 방문하세요.


댓글30
질문을 하거나 결과를 공유하거나 다른 사람을 도와주세요.
faizaanscnz
I am running a float32 TFLite model on Pixel 8a using the GPU. How can I run an Edge TPU model on the hardware to get faster FPS? I’m currently getting 8 FPS, but I need 20+. (Kivy app)
walissong
I would like to know if this tutorial works with yolov8n. I've been trying for many days and I'm not able to convert it to edgetpu.tflite.
dbro
Hello. This seems to be broken for yolo11, although it works for yolov8. After running these two commands in Google colab, the output file is less than 1kb and it generates an error.
! pip install ultralytics ! yolo mode=export model=yolo11n.pt format=edgetpu imgsz=320
The final step to run the EdgeTPU compiler seems to be where the problem is:
... TensorFlow SavedModel: export success ✅ 112.9s, saved as 'yolo11n_saved_model' (33.8 MB)
Edge TPU: starting export with Edge TPU compiler 16.0.384591198... Edge TPU: running 'edgetpu_compiler --out_dir "yolo11n_saved_model" --show_operations --search_delegate --delegate_search_step 30 --timeout_sec 180 "yolo11n_saved_model/yolo11n_full_integer_quant.tflite"' Edge TPU Compiler version 16.0.384591198 Searching for valid delegate with step 30 Try to compile segment with 677 ops ERROR: Didn't find op for builtin opcode 'CONV_2D' version '6'. An older version of this builtin might be supported. Are you using an old TFLite binary with a newer model?
ERROR: Registration failed.
Invalid model: yolo11n_saved_model/yolo11n_full_integer_quant.tflite Model could not be parsed Edge TPU: export success ✅ 0.0s, saved as 'yolo11n_saved_model/yolo11n_full_integer_quant_edgetpu.tflite' (0.0 MB) ...
tomcomtang
I am still studying edge computing(https://edgeone.ai/learning/edge-computing), while you have already delved into a deeper level.
 Glenn JocherUltralytics
@tomcomtang yes, TFLite Edge TPU is designed for optimized performance in edge computing, offering high-speed neural networking with minimal power, reduced latency, and enhanced privacy. For details see the TFLite Edge TPU docs: https://docs.ultralytics.com/integrations/edge-tpu/
manu13008
Hi, Once I exported my best.pt model into edgetpu tflite, I tried to run an inference on an image as the code above but I got the following error :
OSError: libedgetpu.so.1: cannot open shared object file: No such file or directory
Do you have any insights of how resolving this ?
Thanks :)
- Glenn JocherUltralytics
@manu13008 it seems like the error is due to the missing Edge TPU runtime library. Please ensure you have installed the Edge TPU runtime on your device. You can find installation instructions in the Edge TPU documentation. If you need further assistance, feel free to check the resources there.
Abdullah-Ory
Hi friends, i am using google colap to compile yolo11n.pt into edgetpu format, since i have orange pi 5 pro which is arm, so when i am trying to do it in my laptop i got this Ultralytics 8.3.9 🚀 Python-3.10.12 torch-2.4.1+cu121 CPU (Intel Xeon 2.20GHz) YOLO11n summary (fused): 238 layers, 2,616,248 parameters, 0 gradients, 6.5 GFLOPs
PyTorch: starting from '/content/yolo11n.pt' with input shape (1, 3, 640, 640) BCHW and output shape(s) (1, 84, 8400) (5.4 MB)
TensorFlow SavedModel: starting export with tensorflow 2.17.0...
ONNX: starting export with onnx 1.17.0 opset 19... ONNX: slimming with onnxslim 0.1.34... ONNX: export success ✅ 3.0s, saved as '/content/yolo11n.onnx' (10.3 MB) TensorFlow SavedModel: starting TFLite export with onnx2tf 1.22.3...
Automatic generation of each OP name started ======================================== Automatic generation of each OP name complete!
Model loaded ========================================================================
Model conversion started ============================================================ saved_model output started ========================================================== saved_model output complete! Float32 tflite output complete! Float16 tflite output complete! Dynamic Range Quantization tflite output complete! Input signature information for quantization signature_name: serving_default input_name.0: images shape: (1, 640, 640, 3) dtype: <dtype: 'float32'> INT8 Quantization tflite output complete! Full INT8 Quantization tflite output complete! Traceback (most recent call last): File "/usr/local/lib/python3.10/dist-packages/onnx2tf/onnx2tf.py", line 1566, in convert tflite_model = converter.convert() File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/lite.py", line 1231, in wrapper return self._convert_and_export_metrics(convert_func, *args, **kwargs) File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/lite.py", line 1183, in _convert_and_export_metrics result = convert_func(self, *args, **kwargs) File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/lite.py", line 1562, in convert return self._convert_from_saved_model(graph_def) File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/lite.py", line 1424, in _convert_from_saved_model return self._optimize_tflite_model( File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/convert_phase.py", line 215, in wrapper raise error from None # Re-throws the exception. File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/convert_phase.py", line 205, in wrapper return func(*args, **kwargs) File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/lite.py", line 1127, in _optimize_tflite_model model = self._quantize( File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/lite.py", line 767, in _quantize return calibrate_quantize.calibrate_and_quantize( File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/convert_phase.py", line 215, in wrapper raise error from None # Re-throws the exception. File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/convert_phase.py", line 205, in wrapper return func(*args, **kwargs) File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/optimize/calibrator.py", line 194, in calibrate_and_quantize return self._calibrator.QuantizeModel( RuntimeError: Quantized dimension for tensor property and quantization parameters do not match. Got 3 and 0 respectively.
WARNING: INT8 Quantization with int16 activations tflite output failed. Traceback (most recent call last): File "/usr/local/lib/python3.10/dist-packages/onnx2tf/onnx2tf.py", line 1597, in convert tflite_model = converter.convert() File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/lite.py", line 1231, in wrapper return self._convert_and_export_metrics(convert_func, *args, **kwargs) File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/lite.py", line 1183, in _convert_and_export_metrics result = convert_func(self, *args, **kwargs) File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/lite.py", line 1562, in convert return self._convert_from_saved_model(graph_def) File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/lite.py", line 1424, in _convert_from_saved_model return self._optimize_tflite_model( File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/convert_phase.py", line 215, in wrapper raise error from None # Re-throws the exception. File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/convert_phase.py", line 205, in wrapper return func(*args, **kwargs) File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/lite.py", line 1127, in _optimize_tflite_model model = self._quantize( File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/lite.py", line 767, in _quantize return calibrate_quantize.calibrate_and_quantize( File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/convert_phase.py", line 215, in wrapper raise error from None # Re-throws the exception. File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/convert_phase.py", line 205, in wrapper return func(*args, **kwargs) File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/optimize/calibrator.py", line 194, in calibrate_and_quantize return self._calibrator.QuantizeModel( RuntimeError: Quantized dimension for tensor property and quantization parameters do not match. Got 3 and 0 respectively.
WARNING: Full INT8 Quantization with int16 activations tflite output failed. TensorFlow SavedModel: export success ✅ 248.1s, saved as '/content/yolo11n_saved_model' (36.1 MB) Edge TPU: WARNING ⚠️ Edge TPU known bug https://github.com/ultralytics/ultralytics/issues/1185
Edge TPU: starting export with Edge TPU compiler 16.0.384591198... Edge TPU: running 'edgetpu_compiler -s -d -k 10 --out_dir "/content/yolo11n_saved_model" "/content/yolo11n_saved_model/yolo11n_full_integer_quant.tflite"' Edge TPU: export success ✅ 3.9s, saved as '/content/yolo11n_saved_model/yolo11n_full_integer_quant_edgetpu.tflite' (3.5 MB)
Export complete (252.6s) Results saved to /content Predict: yolo predict task=detect model=/content/yolo11n_saved_model/yolo11n_full_integer_quant_edgetpu.tflite imgsz=640 int8 Validate: yolo val task=detect model=/content/yolo11n_saved_model/yolo11n_full_integer_quant_edgetpu.tflite imgsz=640 data=/usr/src/ultralytics/ultralytics/cfg/datasets/coco.yaml int8 Visualize: https://netron.app /content/yolo11n_saved_model/yolo11n_full_integer_quant_edgetpu.tflite
- Glenn JocherUltralytics
@Abdullah-Ory it seems you're encountering an issue with INT8 quantization during the TFLite Edge TPU export. Please ensure your model is compatible with Edge TPU requirements, and consider checking the Ultralytics documentation for detailed guidance on exporting models to TFLite Edge TPU format. If the issue persists, reviewing the quantization parameters might help.
MECHAAMER
Hi,
I trained a YOLOv8l model with VisDrone dataset, and attempted to convert the best weights.pt to Edge TPU TFlite format using:
model = YOLO("best.pt") model.export(format="edgetpu")
my board is Coral dev board.
The conversion completed successfully, but the results indicate that 164 of operations will run on the CPU instead of the Edge TPU. only 223 operation will run using Edge TPU This CPU usage will likely cause performance delays.
I'm wondering if there are any strategies or techniques to improve Edge TPU utilization and minimize CPU usage during inference for this model. Any suggestions or insights would be greatly appreciated.
Thanks,
- Glenn JocherUltralytics
@MECHAAMER to improve Edge TPU utilization, ensure your model is fully quantized and compatible with Edge TPU operations. Consider simplifying the model architecture or using supported operations. For detailed guidance, please refer to the Ultralytics Edge TPU documentation.
Hi, thank you for your support, I follow the attached link, and apply it using: model.export(format="edgetpu") , and I get this output:
Number of operations that will run on Edge TPU: 133 Number of operations that will run on CPU: 364
more details in the attached photo.
I think with this big percent of ops that runs on the CPU, the model will be very slow and I will suffer from large latency.
Do you have any suggestions?
- Glenn JocherUltralytics
To improve Edge TPU utilization, ensure your model is fully quantized and uses supported operations. Simplifying the model architecture might help. For more details, please refer to the Ultralytics Edge TPU documentation.
Hi there,
I'm following the Ultralytics Edge TPU documentation to train a YOLO model for object detection. However, I'm encountering suboptimal results.
I suspect that the issue might lie in the model's compatibility with the TPU. It's possible that certain operations within the model are not optimized for the TPU, leading to delays.
To address this, I'm considering using a YOLO model that is specifically designed to run efficiently on the Edge TPU. Do you have any recommendations for such models?
- Glenn JocherUltralytics
For optimal Edge TPU performance, consider using a smaller YOLO model like YOLOv8n, which is more compatible with Edge TPU operations. Simplifying the model architecture can also help.
I'm encountering a "Segmentation fault" error while trying to run a segmented YOLOv5s model on my Coral Dev Board with an external Coral ML Accelerator (USB). I followed the recommended steps to export, compile, and segment the model using edgetpu_compiler.
I follow these steps:
I trained Yolov5su model, then I exported the model as tflite - 8int by using:
model.export()

then I use the edgetpu_compiler to compile the tflite model and segmented it into 2 models:
edgetpu_compiler model.tflite --num_segments=2

then I get 12 files, 8 models and 4 logs, the models are:
1- best_float32_segment_0_of_2.tflite
2- best_float32_segment_1_of_2.tflite
3- best_float32_segment_0_of_2_edgetpu.tflite
4- best_float32_segment_1_of_2_edgetpu.tflite
5- best_full_integer_quant_segment_0_of_2.tflite
6- best_full_integer_quant_segment_1_of_2.tflite
7- best_full_integer_quant_segment_0_of_2_edgetpu.tflite
8- best_full_integer_quant_segment_1_of_2_edgetpu.tflite
I transfer the "best_full_integer_quant_segment_0_of_2_edgetpu.tflite" and "best_full_integer_quant_segment_1_of_2_edgetpu.tflite" to the coral board and I tried to run the models to detect object in a video, the code:
import argparse
import re
import threading
import time

import numpy as np
import cv2

from pycoral.adapters import classify
from pycoral.adapters import common
import pycoral.pipeline.pipelined_model_runner as pipeline
from pycoral.utils.dataset import read_label_file
from pycoral.utils.edgetpu import list_edge_tpus
from pycoral.utils.edgetpu import make_interpreter


def _get_devices(num_devices):
  edge_tpus = list_edge_tpus()

  if len(edge_tpus) < num_devices:
    raise RuntimeError(
        'Not enough Edge TPUs detected, expected %d, detected %d.' %
        (num_devices, len(edge_tpus)))

  num_pci_devices = sum(1 for device in edge_tpus if device['type'] == 'pci')

  return ['pci:%d' % i for i in range(min(num_devices, num_pci_devices))] + [
      'usb:%d' % i for i in range(max(0, num_devices - num_pci_devices))
  ]


def _make_runner(model_paths, devices):
  """Constructs PipelinedModelRunner given model paths and devices."""
  print('Using devices: ', devices)
  print('Using models: ', model_paths)

  print("  hey runner   1")
  if len(model_paths) != len(devices):
    raise ValueError('# of devices and #of model_paths should match')

  print("  hey runner   2", model_paths[0], devices[1])

  interpreters = []
  interpreter = make_interpreter(model_paths[0], devices[0])
  print("  hey runner   3")
  interpreter.allocate_tensors()
  print("  hey runner   4")
  interpreters.append(interpreter)
  print("  hey runner   5", model_paths[1], devices[0])

  interpreter2 = make_interpreter(model_paths[1], devices[1])
  print("  hey runner   6")
  interpreter.allocate_tensors()
  interpreter2.allocate_tensors()
  print("  hey runner   7")
  interpreters.append(interpreter2)
  print("  hey runner   8")

  return pipeline.PipelinedModelRunner(interpreters)


def main():
  parser = argparse.ArgumentParser(
      formatter_class=argparse.ArgumentDefaultsHelpFormatter)
  parser.add_argument(
      '-m',
      '--models',
      required=True,
      help=('File path template of .tflite model segments, e.g.,'
            'inception_v3_299_quant_segment_%d_of_2_edgetpu.tflite'))
  parser.add_argument(
      '-i', '--input', required=True, help='Image to be classified.')
  parser.add_argument('-l', '--labels', help='File path of labels file.')
  parser.add_argument(
      '-k',
      '--top_k',
      type=int,
      default=1,
      help='Max number of classification results')
  parser.add_argument(
      '-t',
      '--threshold',
      type=float,
      default=0.0,
      help='Classification score threshold')
  parser.add_argument(
      '-c',
      '--count',
      type=int,
      default=1,
      help='Number of times to run inference')
  args = parser.parse_args()
  labels = {0:"pedestrian", 1:"people", 2:"bicycle", 3:"car", 4:"van", 5:"truck", 6:"tricycle", 7:"awning-tricycle", 8:"bus", 9:"motor"}
  print("hey lets begin   1")
  result = re.search(r'^.*_segment_%d_of_(?P<num_segments>[0-9]+)_.*.tflite',
                     args.models)
  print("hey lets begin   2")

  if not result:
    print("hey lets begin    3")

    raise ValueError(
        '--models should follow *_segment%d_of_[num_segments]_*.tflite pattern')
  print("hey lets begin    4")

  num_segments = int(result.group('num_segments'))
  model_paths = [args.models % i for i in range(num_segments)]
  print("hey lets begin    5")

  devices = _get_devices(num_segments)

  print("hey lets begin    6")

  runner = _make_runner(model_paths, devices)

  print("hey lets begin      7")


  # Get the input name and size
  size = common.input_size(runner.interpreters()[0])

  print("hey lets begin     8")

  name = common.input_details(runner.interpreters()[0], 'name')

  print("hey lets begin    9")

  cap = cv2.VideoCapture(args.input)

  print("hey lets begin    10")

  if not cap.isOpened():
      print("Error opening video capture device")
      return

  print("hey lets begin    11")

  while True:
      ret, frame = cap.read()
      if not ret:
          break

      # Preprocess the frame
      height, width, _ = frame.shape
      new_height = int(640 * height / width)
      image = cv2.resize(frame, (640, new_height))

      # Run inference
      runner.push({name: image})

      output_details = runner.interpreters()[-1].get_output_details()[0]
      scale, zero_point = output_details['quantization']

      result = runner.pop()

      if result:
          # Process the results
          values, = result.values()
          scores = scale * (values[0].astype(np.int64) - zero_point)
          classes, scores = classify.get_classes_from_scores(result[0], args.top_k, args.threshold)

          for klass in classes:
              print('%s: %.5f' % (labels.get(klass.id, klass.id), klass.score))

          print('-------RESULTS--------')
      else:
          print("No results")

if __name__ == '__main__':
  main()
then I try execute the python file:python3 test2tpu.py -m best_full_integer_quant_segment_%d_of_2_edgetpu.tflite -i "/coral/720p/Busy Road.mp4"
the output that I get:
hey lets begin 1 hey lets begin 2 hey lets begin 4 hey lets begin 5 hey lets begin 6 Using devices: ['pci:0', 'usb:0'] Using models: ['best_full_integer_quant_segment_0_of_2_edgetpu.tflite', 'best_full_integer_quant_segment_1_of_2_edgetpu.tflite'] hey runner 1 hey runner 2 best_full_integer_quant_segment_0_of_2_edgetpu.tflite usb:0 hey runner 3 hey runner 4 hey runner 5 best_full_integer_quant_segment_1_of_2_edgetpu.tflite pci:0 Segmentation fault
Note: pycoral version: 2.0.0
- Glenn JocherUltralytics
It seems like the segmentation fault might be due to compatibility issues with the model operations on the Edge TPU. Consider simplifying the model architecture or ensuring all operations are supported by the Edge TPU. You can also check the Common Issues guide for additional troubleshooting tips.
Can you help me to know more about: simplifying the model architecture or ensuring all operations are supported by the Edge TPU.
I don't have access now to the records because I am outside office, as I remember In yolov5su, there are more than 200 process depends in TPU and only 25 process use CPU, Also the model working well on 1 TPU (with no segmentation).
- Glenn JocherUltralytics
@MECHAAMER to improve Edge TPU compatibility, consider using a smaller model like YOLOv8n, which is more likely to use supported operations, or simplify the architecture by reducing layers and operations that are not TPU-optimized.
Taufiq-Ahmed
Hi, I have train my custom dataset for detect fire and smoke with yolov8 nano. it's best model size is around 6MB and after exporting it using "yolo export model=yolov8n.pt format=edgetpu". it's size reduced to 3MB. But have to integrate this model in XIAO RP2040 MCU. So I need more light weight model for my edge device. In this case what I should? Please give me a solution.
- Glenn JocherUltralytics
@Taufiq-Ahmed hi! It's great to hear that you've successfully trained your custom dataset with YOLOv8 nano. For further reducing the model size for your XIAO RP2040 MCU, you might want to explore additional quantization techniques. The TFLite Edge TPU format already applies full integer quantization, but you can experiment with pruning or other model compression techniques to further reduce the size. If you haven't already, ensure you're using the latest version of the Ultralytics package for the best optimization features. For more detailed guidance, you can check out our Edge TPU integration guide. Good luck with your deployment!
samphonic
So I have a tflite model and object detection is working, but I can't seem to figure out how to tell if (and how effectively) the model is actually using the Edge TPU hardware. Is there some way to confirm that the hardware is actually being used? Can I manually enable/disable it to compare inference time?
- Glenn JocherUltralytics
@Sammy1Am to confirm if your model is utilizing the Edge TPU hardware, you can check the inference time and compare it with and without the Edge TPU. Typically, when the Edge TPU is in use, you should see a significant reduction in inference time. You can manually enable or disable the Edge TPU by using the
edgetpuinterpreter for the Edge TPU and the standard TFLite interpreter otherwise. For more details on setting this up, you might find the Edge TPU documentation helpful. If you need further assistance, feel free to explore our Ultralytics documentation.
FearL0rd
How do I use YOLO with a Dual TPU card?
I have APEX_0 and APEX_1 devices.
Streamline segmentation during export https://coral.ai/docs/edgetpu/pipeline/
- Glenn JocherUltralytics
@FearL0rd thank you for your suggestion! Streamlining segmentation during export is indeed a valuable enhancement. For detailed guidance on exporting YOLOv8 models to TFLite Edge TPU format, you can refer to our documentation. This will help you optimize your models for high-speed, low-power inferencing on devices with limited computational power.
For more information on using YOLO with a Dual TPU card, you can leverage the APEX_0 and APEX_1 devices to distribute the workload effectively. This setup can significantly boost performance and efficiency in your machine learning tasks.
Feel free to explore the provided resources and let us know if you have any further questions! 🚀
@glenn-jocher where is the doc talking about segmentation using APEX_0 and APEX_1
- Glenn JocherUltralytics
Hi @FearL0rd,
For documentation on segmentation using APEX_0 and APEX_1, you can refer to the guide on exporting YOLOv8 models to TFLite Edge TPU format. This guide covers optimizing your models for high-speed, low-power inferencing on devices like the Coral Edge TPU.
To utilize both APEX_0 and APEX_1 devices, you can distribute the workload effectively across the dual TPU setup, enhancing performance and efficiency. For more detailed instructions, please visit the relevant sections in our documentation.
Feel free to reach out if you have any more questions! 😊