SAM 2: Segment Anything Model 2

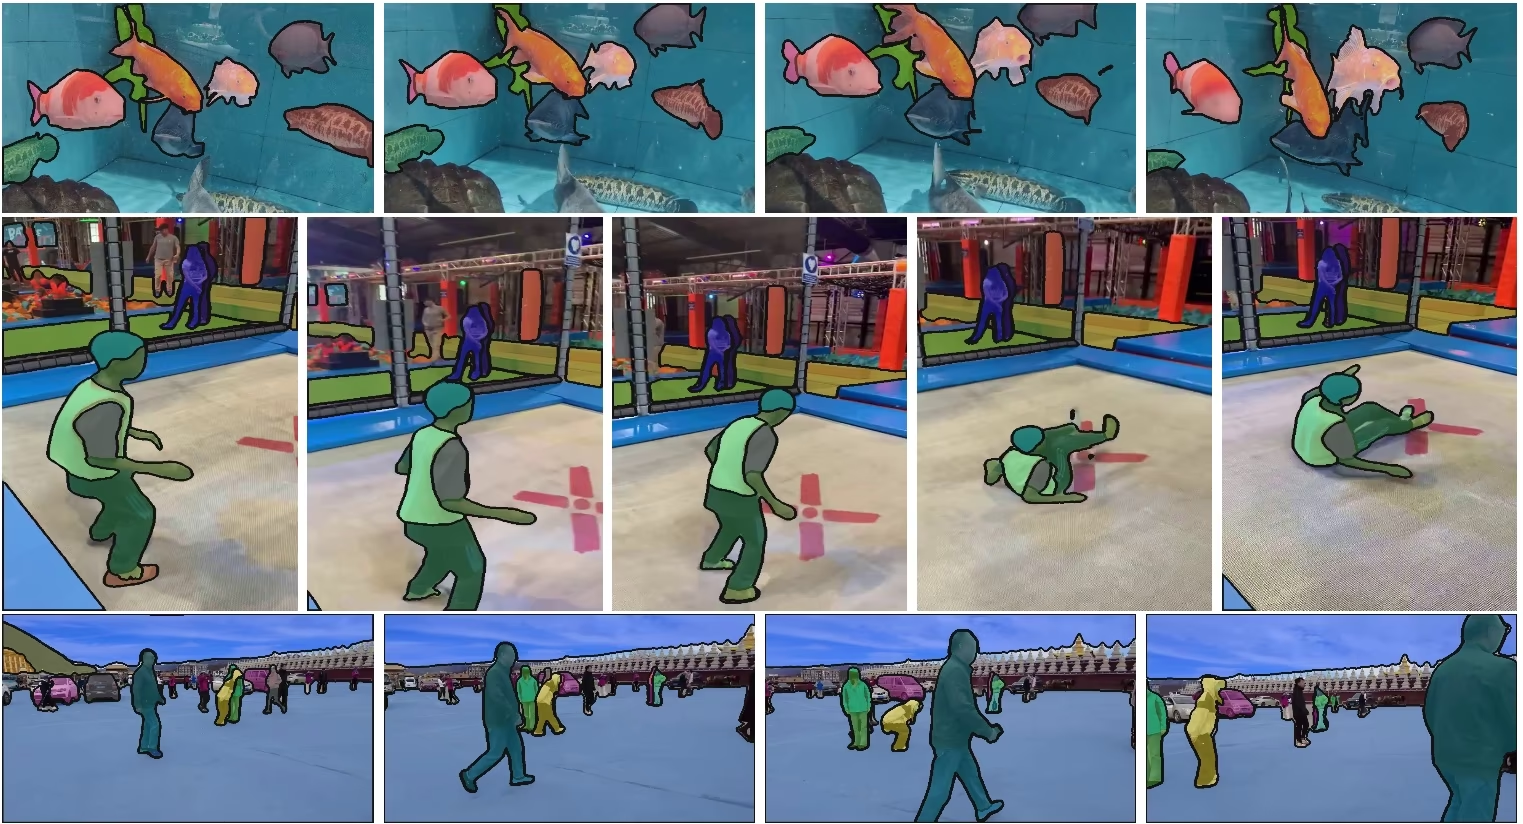
SAM 2, the successor to Meta's Segment Anything Model (SAM), is a unified model for promptable object segmentation in both images and videos. Its single promptable architecture supports real-time processing and zero-shot generalization.
SAM 2.1 models power the smart annotation feature on Ultralytics Platform, enabling click-based segmentation for fast dataset labeling. See the annotation guide for details.
Key Features#
Watch: How to Run Inference with Meta's SAM2 using Ultralytics | Step-by-Step Guide
Unified Model Architecture#
SAM 2 combines the capabilities of image and video segmentation in a single model. This unification simplifies deployment and allows for consistent performance across different media types. It uses a flexible prompt-based interface, enabling users to specify objects of interest through various prompt types, such as points, bounding boxes, or masks.
Real-Time Performance#
The model achieves real-time inference speeds, processing approximately 44 frames per second. This makes SAM 2 suitable for applications requiring immediate feedback, such as video editing and augmented reality.
Zero-Shot Generalization#
SAM 2 can segment objects it has never encountered before, demonstrating strong zero-shot generalization. This is particularly useful in diverse or evolving visual domains where pre-defined categories may not cover all possible objects.
Interactive Refinement#
Users can iteratively refine the segmentation results by providing additional prompts, allowing for precise control over the output. This interactivity is essential for refining results in applications like video annotation or medical imaging.
Advanced Handling of Visual Challenges#
SAM 2 includes mechanisms to manage common video segmentation challenges, such as object occlusion and reappearance. It uses a memory mechanism to keep track of objects across frames, ensuring continuity even when objects are temporarily obscured or exit and re-enter the scene.
For a deeper understanding of SAM 2's architecture and capabilities, explore the SAM 2 research paper.
Performance and Technical Details#
According to Meta, SAM 2 outperforms previous models on several metrics:
| Metric | SAM 2 | Previous SOTA |
|---|---|---|
| Interactive Video Segmentation | Best | - |
| Human Interactions Required | 3x fewer | Baseline |
| Image Segmentation Accuracy | Improved | SAM |
| Inference Speed | 6x faster | SAM |
Model Architecture#
Core Components#
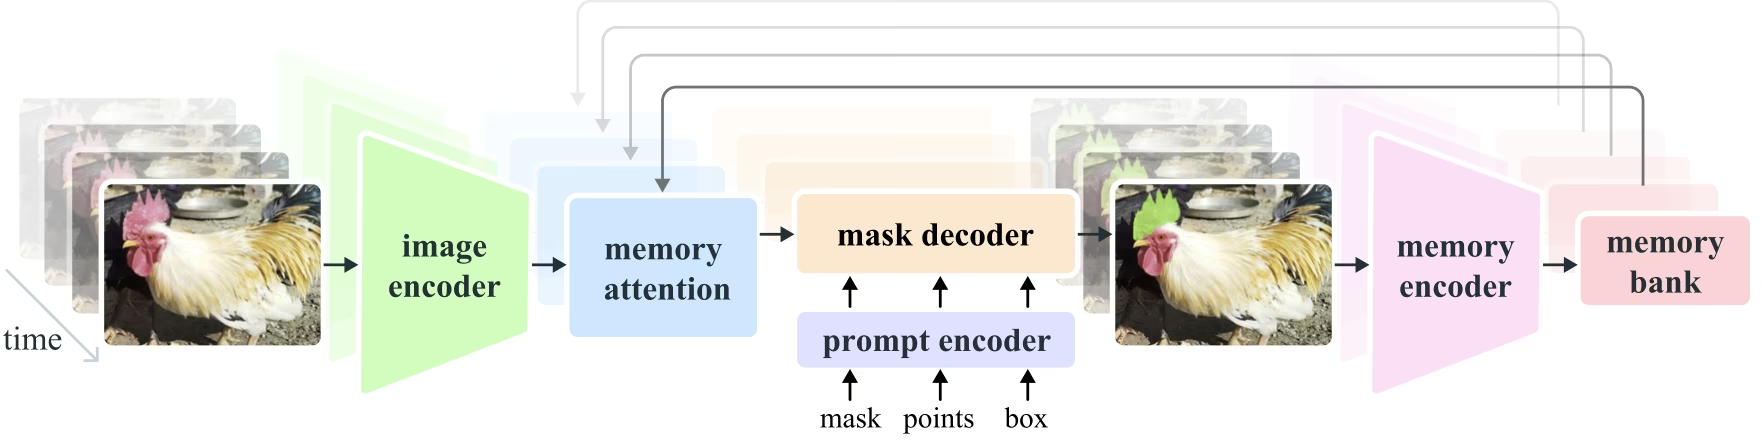
- Image and Video Encoder: Utilizes a transformer-based architecture to extract high-level features from both images and video frames. This component is responsible for understanding the visual content at each timestep.
- Prompt Encoder: Processes user-provided prompts (points, boxes, masks) to guide the segmentation task. This allows SAM 2 to adapt to user input and target specific objects within a scene.
- Memory Mechanism: Includes a memory encoder, memory bank, and memory attention module. These components collectively store and utilize information from past frames, enabling the model to maintain consistent object tracking over time.
- Mask Decoder: Generates the final segmentation masks based on the encoded image features and prompts. In video, it also uses memory context to ensure accurate tracking across frames.
Memory Mechanism and Occlusion Handling#
The memory mechanism allows SAM 2 to handle temporal dependencies and occlusions in video data. As objects move and interact, SAM 2 records their features in a memory bank. When an object becomes occluded, the model can rely on this memory to predict its position and appearance when it reappears. The occlusion head specifically handles scenarios where objects are not visible, predicting the likelihood of an object being occluded.
Multi-Mask Ambiguity Resolution#
In situations with ambiguity (e.g., overlapping objects), SAM 2 can generate multiple mask predictions. This helps represent complex scenes where a single mask might not capture the intended object.
SA-V Dataset#
The SA-V dataset, developed for SAM 2's training, is one of the largest and most diverse video segmentation datasets available. It includes:
- 51,000+ Videos: Captured across 47 countries, providing a wide range of real-world scenarios.
- 600,000+ Mask Annotations: Detailed spatio-temporal mask annotations, referred to as "masklets," covering whole objects and parts.
- Dataset Scale: It features 4.5 times more videos and 53 times more annotations than the previous largest video segmentation datasets.
Benchmarks#
Video Object Segmentation#
SAM 2 reports the following results on major video segmentation benchmarks:
| Dataset | J&F | J | F |
|---|---|---|---|
| DAVIS 2017 | 82.5 | 79.8 | 85.2 |
| YouTube-VOS | 81.2 | 78.9 | 83.5 |
Interactive Segmentation#
On interactive segmentation tasks, SAM 2 achieves the following results:
| Dataset | NoC@90 | AUC |
|---|---|---|
| DAVIS Interactive | 1.54 | 0.872 |
Installation#
SAM 2 is included in the ultralytics package. Install it with the following command; SAM 2 weights download automatically on first use.
pip install ultralyticsHow to Use SAM 2: Versatility in Image and Video Segmentation#
The following table details the available SAM 2 models, their pretrained weights, supported tasks, and compatibility with different operating modes like Training, Validation, Inference, and Export.
| Model Type | Pretrained Weights | Tasks Supported | Training | Validation | Inference | Export |
|---|---|---|---|---|---|---|
| SAM 2 tiny | sam2_t.pt | Instance Segmentation | ❌ | ❌ | ✅ | ❌ |
| SAM 2 small | sam2_s.pt | Instance Segmentation | ❌ | ❌ | ✅ | ❌ |
| SAM 2 base | sam2_b.pt | Instance Segmentation | ❌ | ❌ | ✅ | ❌ |
| SAM 2 large | sam2_l.pt | Instance Segmentation | ❌ | ❌ | ✅ | ❌ |
| SAM 2.1 tiny | sam2.1_t.pt | Instance Segmentation | ❌ | ❌ | ✅ | ❌ |
| SAM 2.1 small | sam2.1_s.pt | Instance Segmentation | ❌ | ❌ | ✅ | ❌ |
| SAM 2.1 base | sam2.1_b.pt | Instance Segmentation | ❌ | ❌ | ✅ | ❌ |
| SAM 2.1 large | sam2.1_l.pt | Instance Segmentation | ❌ | ❌ | ✅ | ❌ |
SAM 2 Prediction Examples#
SAM 2 can be used across a broad range of tasks, including real-time video editing, medical imaging, and autonomous systems. Its ability to segment both static and dynamic visual data makes it a versatile tool for researchers and developers.
Segment with Prompts#
Use prompts to segment specific objects in images or videos.
from ultralytics import SAM

# Load a model
model = SAM("sam2.1_b.pt")

# Display model information (optional)
model.info()

# Run inference with bboxes prompt
results = model("path/to/image.jpg", bboxes=[100, 100, 200, 200])

# Run inference with single point
results = model(points=[900, 370], labels=[1])

# Run inference with multiple points
results = model(points=[[400, 370], [900, 370]], labels=[1, 1])

# Run inference with multiple points prompt per object
results = model(points=[[[400, 370], [900, 370]]], labels=[[1, 1]])

# Run inference with negative points prompt
results = model(points=[[[400, 370], [900, 370]]], labels=[[1, 0]])
Segment Everything#
Segment the entire image or video content without specific prompts.
from ultralytics import SAM

# Load a model
model = SAM("sam2.1_b.pt")

# Display model information (optional)
model.info()

# Run inference
model("path/to/video.mp4")- This example demonstrates how SAM 2 can be used to segment the entire content of an image or video if no prompts (bboxes/points/masks) are provided.
Segment Video and Track objects#
Segment the entire video content with specific prompts and track objects.
from ultralytics.models.sam import SAM2VideoPredictor

# Create SAM2VideoPredictor
overrides = {"conf": 0.25, "task": "segment", "mode": "predict", "imgsz": 1024, "model": "sam2_b.pt"}
predictor = SAM2VideoPredictor(overrides=overrides)

# Run inference with single point
results = predictor(source="test.mp4", points=[920, 470], labels=[1])

# Run inference with multiple points
results = predictor(source="test.mp4", points=[[920, 470], [909, 138]], labels=[1, 1])

# Run inference with multiple points prompt per object
results = predictor(source="test.mp4", points=[[[920, 470], [909, 138]]], labels=[[1, 1]])

# Run inference with negative points prompt
results = predictor(source="test.mp4", points=[[[920, 470], [909, 138]]], labels=[[1, 0]])
Dynamic Interactive Segment and Track#
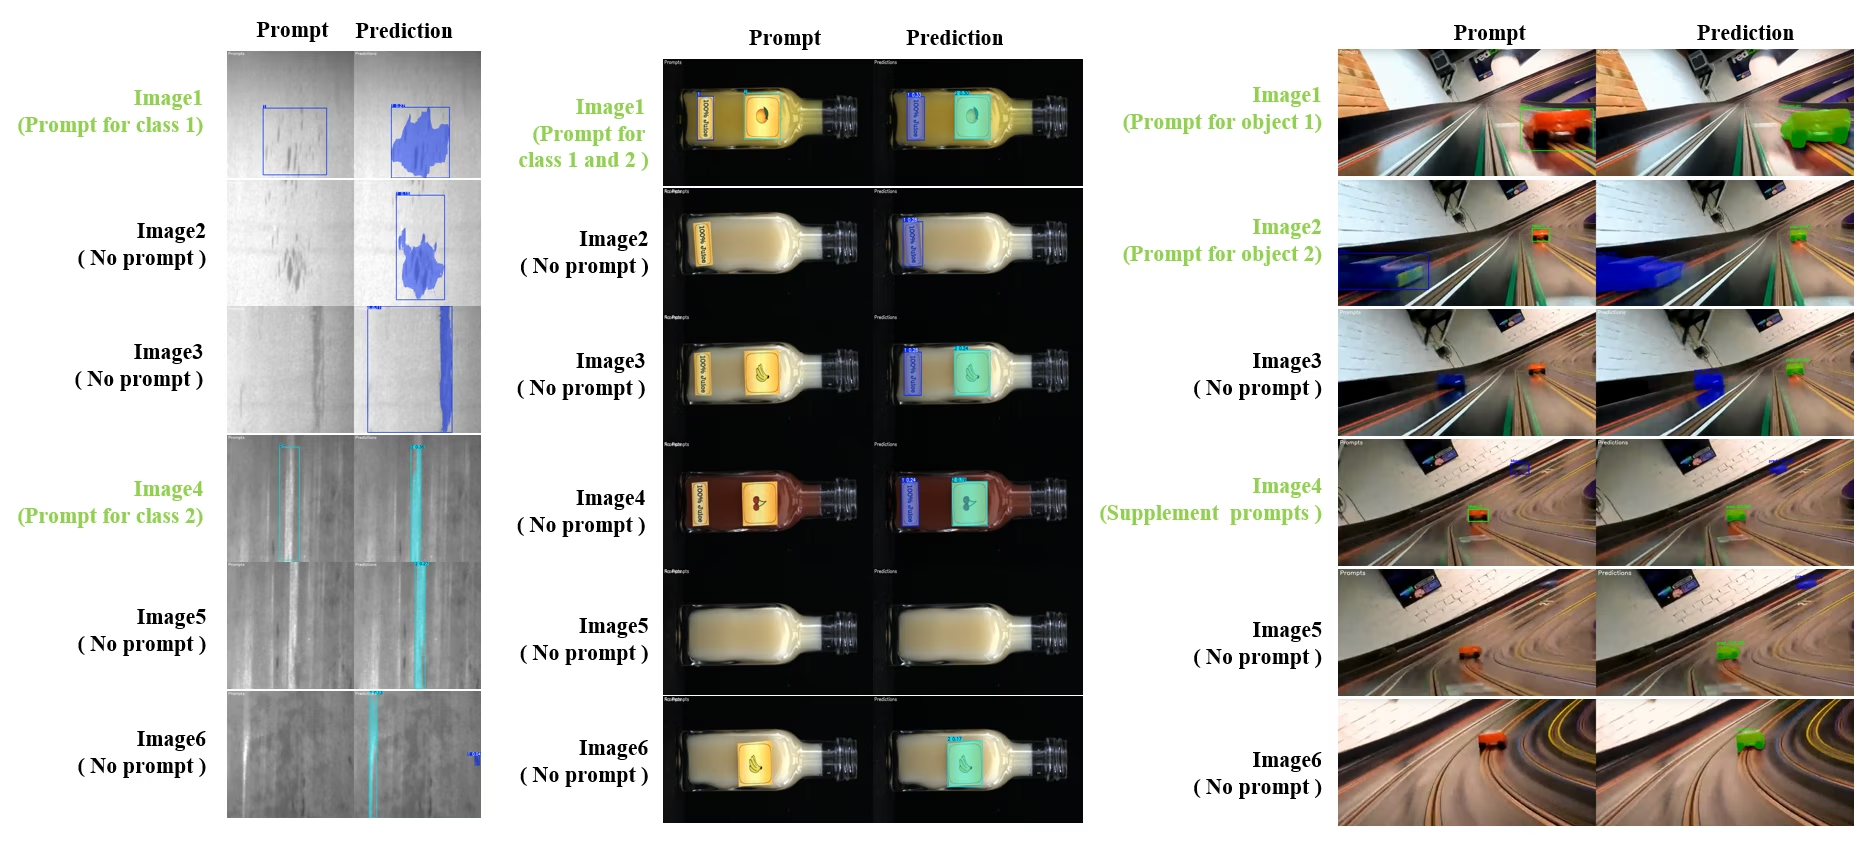
SAM2DynamicInteractivePredictor is a training-free extension of SAM 2 that enables dynamic interaction with multiple frames and continual learning capabilities. This predictor supports real-time prompt updates and memory management for improved tracking performance across a sequence of images. Compared to the original SAM 2, SAM2DynamicInteractivePredictor rebuilds the inference flow to make the best use of pretrained SAM 2 models without requiring additional training.
Key Features#
It offers three enhancements:
- Dynamic Interactive: Add prompts for new, untracked instances in later frames at any time during video processing
- Continual Learning: Add new prompts for existing instances to improve the model performance over time
- Independent Multi-Image Support: Process multiple independent images (not necessarily from a video sequence) with memory sharing and cross-image object tracking
Core Capabilities#
- Prompt Flexibility: Accepts bounding boxes, points, and masks as prompts
- Memory Bank Management: Maintains a dynamic memory bank to store object states across frames
- Multi-Object Tracking: Supports tracking multiple objects simultaneously with individual object IDs
- Real-Time Updates: Allows adding new prompts during inference without reprocessing previous frames
- Independent Image Processing: Process standalone images with shared memory context for cross-image object consistency
from ultralytics.models.sam import SAM2DynamicInteractivePredictor

# Create SAM2DynamicInteractivePredictor
overrides = {"conf": 0.01, "task": "segment", "mode": "predict", "imgsz": 1024, "model": "sam2_t.pt", "save": False}
predictor = SAM2DynamicInteractivePredictor(overrides=overrides, max_obj_num=10)

# Define a category by box prompt
predictor(source="image1.jpg", bboxes=[[100, 100, 200, 200]], obj_ids=[0], update_memory=True)

# Detect this particular object in a new image
results = predictor(source="image2.jpg")

# Add new category with a new object ID
results = predictor(
    source="image4.jpg",
    bboxes=[[300, 300, 400, 400]],  # New object
    obj_ids=[1],  # New object ID
    update_memory=True,  # Add to memory
)
# Perform inference
results = predictor(source="image5.jpg")

# Add refinement prompts to the same category to boost performance
# This helps when object appearance changes significantly
results = predictor(
    source="image6.jpg",
    points=[[150, 150]],  # Refinement point
    labels=[1],  # Positive point
    obj_ids=[1],  # Same object ID
    update_memory=True,  # Update memory with new information
)
# Perform inference on new image
results = predictor(source="image7.jpg")The SAM2DynamicInteractivePredictor is designed to work with SAM 2 models, and supports adding and refining categories with all the box, point, and mask prompts that SAM 2 supports natively. It is particularly useful for scenarios where objects appear or change over time, such as in video annotation or interactive editing tasks.
Arguments#
| Name | Default Value | Data Type | Description |
|---|---|---|---|
max_obj_num | 3 | int | The preset maximum number of categories |
update_memory | False | bool | Whether to update memory with new prompts |
obj_ids | None | List[int] | List of object IDs corresponding to prompts |
Use Cases#
SAM2DynamicInteractivePredictor is ideal for:
- Video annotation workflows where new objects appear during the sequence
- Interactive video editing requiring real-time object addition and refinement
- Surveillance applications with dynamic object tracking needs
- Medical imaging for tracking anatomical structures across time series
- Autonomous systems requiring adaptive object detection and tracking
- Multi-image datasets for consistent object segmentation across independent images
- Image collection analysis where objects need to be tracked across different scenes
- Cross-domain segmentation leveraging memory from diverse image contexts
- Semi-automatic annotation for efficient dataset creation with minimal manual intervention
SAM Comparison vs YOLO#
Here we compare Meta's SAM 2 models, including the smallest SAM2-t variant, with Ultralytics segmentation models, including YOLO26:
| Model | Size (MB) | Parameters (M) | Speed (CPU) (ms/im) |
|---|---|---|---|
| Meta SAM-b | 375 | 93.7 | 41703 |
| Meta SAM2-b | 162 | 80.8 | 28867 |
| Meta SAM2-t | 78.1 | 38.9 | 23430 |
| MobileSAM | 40.7 | 10.1 | 23802 |
| FastSAM-s with YOLOv8 backbone | 23.9 | 11.8 | 58.0 |
| Ultralytics YOLOv8n-seg | 7.1 (11.0x smaller) | 3.4 (11.4x less) | 24.8 (945x faster) |
| Ultralytics YOLO11n-seg | 6.2 (12.6x smaller) | 2.9 (13.4x less) | 24.3 (964x faster) |
| Ultralytics YOLO26n-seg | 6.7 (11.7x smaller) | 2.7 (14.4x less) | 25.2 (930x faster) |
This comparison demonstrates the substantial differences in model sizes and speeds between SAM variants and YOLO segmentation models. While SAM provides unique automatic segmentation capabilities, YOLO models, particularly YOLOv8n-seg, YOLO11n-seg and YOLO26n-seg, are significantly smaller, faster, and more computationally efficient.
SAM speeds measured with PyTorch, YOLO speeds measured with ONNX Runtime. Tests run on a 2025 Apple M4 Air with 16GB of RAM using torch==2.10.0, ultralytics==8.4.31, and onnxruntime==1.24.4. To reproduce this test:
from ultralytics import ASSETS, SAM, YOLO, FastSAM

# Profile SAM2-t, SAM2-b, SAM-b, MobileSAM
for file in ["sam_b.pt", "sam2_b.pt", "sam2_t.pt", "mobile_sam.pt"]:
    model = SAM(file)
    model.info()
    model(ASSETS)

# Profile FastSAM-s
model = FastSAM("FastSAM-s.pt")
model.info()
model(ASSETS)

# Profile YOLO models (ONNX)
for file_name in ["yolov8n-seg.pt", "yolo11n-seg.pt", "yolo26n-seg.pt"]:
    model = YOLO(file_name)
    model.info()
    onnx_path = model.export(format="onnx", dynamic=True, nms=False)  # YOLO26 NMS-free head; no-op for YOLOv8/YOLO11
    model = YOLO(onnx_path)
    model(ASSETS)
Auto-Annotation: Efficient Dataset Creation#
Auto-annotation pairs SAM 2 with a pretrained detection model to generate segmentation datasets quickly, without extensive manual labeling. Ultralytics Platform also offers browser-based auto-annotation with hosted vision models; compare their detection accuracy, cost and speed on the VLM leaderboard.
How to Auto-Annotate with SAM 2#
Watch: Auto Annotation with Meta's Segment Anything 2 Model using Ultralytics | Data Labeling
To auto-annotate your dataset with a YOLO26x detector and SAM 2, follow this example:
from ultralytics.data.annotator import auto_annotate

auto_annotate(data="path/to/images", det_model="yolo26x.pt", sam_model="sam2_b.pt")| Argument | Type | Default | Description |
|---|---|---|---|
data | str | required | Path to directory containing target images for annotation or segmentation. |
det_model | str | 'yolo26x.pt' | YOLO detection model path for initial object detection. |
sam_model | str | 'sam_b.pt' | SAM model path for segmentation (supports SAM, SAM 2, MobileSAM, and SAM 3 weights). |
device | str | '' | Computation device (e.g., 'cuda:0', 'cpu', or '' for automatic device detection). |
conf | float | 0.25 | YOLO detection confidence threshold for filtering weak detections. |
iou | float | 0.5 | IoU threshold for Non-Maximum Suppression to filter overlapping boxes. |
imgsz | int | 640 | Input size for resizing images (rounded up to a multiple of 32 if needed). |
max_det | int | 300 | Maximum number of detections per image for memory efficiency. |
classes | list[int] | None | List of class indices to detect (e.g., [0, 1] for person & bicycle). |
output_dir | str | None | Save directory for annotations (default: <data>_auto_annotate_labels sibling). |
This function turns a folder of unlabeled images into a segmentation dataset with minimal manual effort.
Limitations#
Despite its strengths, SAM 2 has certain limitations:
- Tracking Stability: SAM 2 may lose track of objects during extended sequences or significant viewpoint changes.
- Object Confusion: The model can sometimes confuse similar-looking objects, particularly in crowded scenes.
- Efficiency with Multiple Objects: Segmentation efficiency decreases when processing multiple objects simultaneously due to the lack of inter-object communication.
- Detail Accuracy: May miss fine details, especially with fast-moving objects. Additional prompts can partially address this issue, but temporal smoothness is not guaranteed.
Citations and Acknowledgments#
If you use SAM 2 in your research or development work, please cite it using the following reference:
@article{ravi2024sam2,
  title={SAM 2: Segment Anything in Images and Videos},
  author={Ravi, Nikhila and Gabeur, Valentin and Hu, Yuan-Ting and Hu, Ronghang and Ryali, Chaitanya and Ma, Tengyu and Khedr, Haitham and R{\"a}dle, Roman and Rolland, Chloe and Gustafson, Laura and Mintun, Eric and Pan, Junting and Alwala, Kalyan Vasudev and Carion, Nicolas and Wu, Chao-Yuan and Girshick, Ross and Doll{\'a}r, Piotr and Feichtenhofer, Christoph},
  journal={arXiv preprint},
  year={2024}
}
We thank Meta AI for releasing this model and dataset to the AI community.
FAQ#
SAM 2, the successor to Meta's Segment Anything Model (SAM), is a unified, promptable model for object segmentation in both images and videos. SAM 2 offers several improvements over the original SAM, including:
- Unified Model Architecture: Combines image and video segmentation capabilities in a single model.
- Real-Time Performance: Processes approximately 44 frames per second, making it suitable for applications requiring immediate feedback.
- Zero-Shot Generalization: Segments objects it has never encountered before, useful in diverse visual domains.
- Interactive Refinement: Allows users to iteratively refine segmentation results by providing additional prompts.
- Advanced Handling of Visual Challenges: Manages common video segmentation challenges like object occlusion and reappearance.
For more details on SAM 2's architecture and capabilities, explore the SAM 2 research paper.
SAM 2 supports real-time video segmentation through its promptable interface and fast inference. Here's a basic example:
Segment with PromptsUse prompts to segment specific objects in images or videos.
from ultralytics import SAM

# Load a model
model = SAM("sam2_b.pt")

# Display model information (optional)
model.info()

# Segment with bounding box prompt
results = model("path/to/image.jpg", bboxes=[100, 100, 200, 200])

# Segment with point prompt
results = model("path/to/image.jpg", points=[150, 150], labels=[1])
For more comprehensive usage, refer to the How to Use SAM 2 section.
SAM 2 is trained on the SA-V dataset, one of the largest and most diverse video segmentation datasets available. The SA-V dataset includes:
- 51,000+ Videos: Captured across 47 countries, providing a wide range of real-world scenarios.
- 600,000+ Mask Annotations: Detailed spatio-temporal mask annotations, referred to as "masklets," covering whole objects and parts.
- Dataset Scale: Features 4.5 times more videos and 53 times more annotations than previous largest datasets, offering unprecedented diversity and complexity.
This dataset allows SAM 2 to achieve strong results on major video segmentation benchmarks and enhances its zero-shot generalization capabilities.
SAM 2 includes a memory mechanism to manage temporal dependencies and occlusions in video data. The memory mechanism consists of:
- Memory Encoder and Memory Bank: Stores features from past frames.
- Memory Attention Module: Utilizes stored information to maintain consistent object tracking over time.
- Occlusion Head: Specifically handles scenarios where objects are not visible, predicting the likelihood of an object being occluded.
This mechanism ensures continuity even when objects are temporarily obscured or exit and re-enter the scene. For more details, refer to the Memory Mechanism and Occlusion Handling section.
SAM 2 models, such as Meta's SAM2-t and SAM2-b, offer powerful zero-shot segmentation capabilities but are significantly larger and slower compared to YOLO models. For instance, YOLO26n-seg is approximately 24 times smaller and over 1145 times faster than SAM2-b on CPU. While SAM 2 excels in versatile, prompt-based, and zero-shot segmentation scenarios, YOLO26 is optimized for speed, efficiency, and real-time applications with NMS-free end-to-end inference, making it better suited for deployment in resource-constrained environments.


Comments150
Ask a question, share your results, or help someone else.
 Glenn JocherUltralytics
Hey everyone! We wanted to give you a quick update: our team is currently busy integrating SAM 2 (Segment Anything Model 2) into the Ultralytics package. This new model is super exciting, with features like real-time performance and the ability to segment objects it’s never seen before.
We're really pumped about what SAM2 can do, but it's still in the works. Thanks for your patience as we get everything set up! We'll keep you posted as we make progress. Stay tuned!
10- Glenn JocherUltralytics
Update: SAM 2 is now fully integrated! Update your package to
ultralytics>=8.2.70withpip install -U ultralyticsand then for example:from ultralytics import ASSETS, SAM # Load a model model = SAM("sam2_s.pt") # Segment with point prompt results = model(ASSETS / "bus.jpg", points=[150, 150], labels=[1], device="cpu")1
avasanjesh
Hello,
Can i use sam2.1 for real time segmentation? i want to specify the object on the first frame of live video webcam then sam2.1 shows the segmentation and continue to track and show the result of segmentation of that object. Is it possible to do this?
1thedatamask
Breaking News: 🚨 SAM 1.0 outperforms SAM 2.0 on low-contrast images like CT Scan and MRI images! Check out this insightful video from Data Mask YouTube channel where they dive deep into the architecture, demos, and limitations of both Meta's segmentation models. Discover when to use SAM 1.0 for superior results on challenging images.
Use case with ultralytics
https://www.youtube.com/watch?v=vMI-TnyNLYU
Please do like and subscribe for exciting video like above .
#SAM #SAM2.0 #MetaAI #ImageSegmentation #AI #MachineLearning #DeepLearning #DataMask #BreakingNews
1- Glenn JocherUltralytics
@thedatamask thank you for sharing the video. For insights on SAM 2's capabilities and its comparison with other models, you can explore our documentation. If you have specific questions about using SAM 2 with Ultralytics, feel free to ask!
ram-from-tvl
Hi Team,
the below is the code I have been using to annotate some items in a folder of several images. I am planning to segment everything first and then try to cherry pick the ones that are to be annotated for a downstream segmentation task. Could you please tailor the code for the same. I am not getting any help from the docs regarding the same. i have tried auto annotate but its not working for my use case. So please help me in this approach
` from ultralytics import SAM
Load a model
model = SAM("sam2.1_b.pt")
Display model information (optional)
model.info()
Run inference
model("/kaggle/working/10_random_frames") `
Thankyou
Regards Ram
 Onuralp SezerUltralytics
Hi Team,
the below is the code I have been using to annotate some items in a folder of several images. I am planning to segment everything first and then try to cherry pick the ones that are to be annotated for a downstream segmentation task. Could you please tailor the code for the same. I am not getting any help from the docs regarding the same. i have tried auto annotate but its not working for my use case. So please help me in this approach
` from ultralytics import SAM
Load a model
model = SAM("sam2.1_b.pt")
Display model information (optional)
model.info()
Run inference
model("/kaggle/working/10_random_frames") `
Thankyou
Regards Ram
You may want check out here https://docs.ultralytics.com/reference/data/annotator/#ultralytics.data.annotator.auto_annotate
zhaowangalready
Hello, dear doctor, I encountered some problems in the automatic annotation segmentation. I used the successfully annotated data for verification and found that the data of each species has a serial number border. How can I remove the serial number border? I hope to hear from you.
- Glenn JocherUltralytics
auto_annotate()生成的是标准 YOLO-seg 标签:每一行开头的“数字”是类别class_id(必需字段,不能删),如果你看到的是验证/预测保存出来的图片上带编号的边框/轮廓,那只是可视化绘图,不会写进数据本身;你可以按 SAM 2 文档 继续用同一套数据训练/验证,同时关掉这些 plot:yolo val model=yolo26n-seg.pt data=path/to/data.yaml plots=False yolo predict model=sam2.1_b.pt source=path/to/images show_labels=False show_boxes=False方便的话把“带序号边框”的截图 + 对应的一行标签
.txt内容贴在这个 discussion 里,我帮你确认你看到的到底是class_id还是绘图叠加效果。
cyberpunk-edgerunner
I have to question related to SAM2 :
- How to use text-prompt for segmentation using SAM ?
- Along with the bounding box coordinates, is there a way to tell SAM what not to segment ?
I have two questions regarding segmentation with SAM2 and YOLOv11:
1. Visualization and Editing with SAM2 I've used the
auto_annotatefeature and I'm wondering:- How can I visualize the segmentations produced by the SAM2 model?
- Is there a way to manually inspect or edit these segmentations?
I'm aiming to verify the outputs before proceeding further.
2. Saving and Cropping Segmentations I'm using the following code to detect and segment images with YOLOv11 and SAM2:
from ultralytics import YOLO
from ultralytics import SAM

model = YOLO(r"runs\detect\train2\weights\best.pt")
sam_model = SAM("sam2_b.pt")

results = model("more_test_images", save=True)

for result in results:
    class_ids = result.boxes.cls.int().tolist()

    if len(class_ids):
        boxes = result.boxes.xyxy
        sam_results = sam_model(result.orig_img, bboxes=boxes, verbose=False, save=True)
The detection results from YOLOv11 are saved correctly, but only one segmented result is saved by SAM2.
Questions:
- How can I ensure all SAM2 segmentations are saved for each image?
- How can I crop and save only the segmented parts (i.e., masked regions) from each image? I need these as separate images, containing only the segmented pixels.
Any help or pointers would be greatly appreciated!
fangyuZ1025
Hello, dear doctor, I encountered some problems in the automatic annotation segmentation. The automatic annotation automatically marked various marks on my output, but in fact, this is not the correct mark of my picture, and even some pictures cannot recognise the objects in it. How can I make it change the label uniform? For example, all of them are labelled as "fruit", "vehicle" and so on? I hope to get your reply.
from ultralytics.data.annotator import auto_annotate
auto_annotate(data=r"D:\graduation.thesis\mydata\mt_label\images", det_model="yolov8n.pt", sam_model="sam2_b.pt")
image 19/461 D:\graduation.thesis\mydata\mt_label\images\IMG_20241003_112848.jpg: 640x640 (no detections), 33.4ms image 20/461 D:\graduation.thesis\mydata\mt_label\images\IMG_20241003_112858.jpg: 640x640 1 orange, 31.9ms image 21/461 D:\graduation.thesis\mydata\mt_label\images\IMG_20241003_112907.jpg: 640x640 1 apple, 35.3ms image 22/461 D:\graduation.thesis\mydata\mt_label\images\IMG_20241003_112916.jpg: 640x640 (no detections), 34.0ms image 23/461 D:\graduation.thesis\mydata\mt_label\images\IMG_20241003_112938.jpg: 640x640 (no detections), 35.3ms image 24/461 D:\graduation.thesis\mydata\mt_label\images\IMG_20241003_112947.jpg: 640x640 1 donut, 32.1ms image 25/461 D:\graduation.thesis\mydata\mt_label\images\IMG_20241003_113004.jpg: 640x640 (no detections), 28.6ms image 26/461 D:\graduation.thesis\mydata\mt_label\images\IMG_20241003_113014.jpg: 640x640 1 donut, 33.9ms image 27/461 D:\graduation.thesis\mydata\mt_label\images\IMG_20241003_113028.jpg: 640x640 1 apple, 1 donut, 35.8ms
- Glenn JocherUltralytics(edited)
@fangyuZ1025 to improve label consistency in auto-annotation, you'll need to train a custom detection model with your specific classes ("fruit", "vehicle") first. The auto_annotate function relies on your detection model's class definitions - it doesn't rename labels but uses whatever classes your det_model was trained on. For immediate improvement, try a newer detection model such as YOLO26 (for example
det_model="yolo26n.pt"), which is more accurate than YOLOv8.
Fatima-khanjar
Hello, I am using SAM2 with my fine-tuned YOLOv11 on my custom dataset to perform auto-annotation for an object detection task. However, the annotations in the .txt file are not in the YOLO format (class_label x_center y_center width height).
Could you clarify the format of the labels generated when using both SAM2 and YOLOv11 for auto-annotation?
- Glenn JocherUltralytics
@Fatima-khanjar the auto-annotation function generates segmentation masks in YOLO segmentation format (polygon points normalized 0-1), not bounding boxes. For object detection tasks, you'll need to convert these masks to bounding boxes using
masks.xyfrom Results objects. We recommend reviewing the Auto-Annotation with SAM2 documentation for implementation details and conversion examples.1
danieltudosiu(edited)
How does one use SAM2 with a numpy input? I saw how to do it with SAM but SAM2 does not have a preprocess method like SAM.
- Glenn JocherUltralytics(edited)
@danieltudosiu you can pass numpy arrays directly as the source to
SAM. Here's a minimal example:import numpy as np from ultralytics import SAM model = SAM("sam2.1_b.pt") img = np.random.randint(0, 255, (640, 640, 3), dtype=np.uint8) # Your numpy array results = model(img, points=[100, 100], labels=[1])For more details, see the SAM 2 documentation.
But what about the Image one? Or just use the Video one for Images as well?
- Glenn JocherUltralytics(edited)
You can pass numpy arrays or file paths directly to
SAM("sam2.1_b.pt"), for examplemodel(img_array, points=[100, 100], labels=[1]).SAM2VideoPredictoris only needed for video. For image-specific examples, see the SAM 2 documentation.