Ultralytics YOLO 超参数调优指南
Ultralytics YOLO 的超参数调优是一种自动化的迭代搜索,用于优化学习率、损失权重和增强强度等设置,从而最大化机器学习模型在准确率、精确率和召回率等指标上的表现。Ultralytics YOLO 不会手动逐一测试这些值,而是使用遗传算法探索超参数空间,在多次短时训练中不断变异并评估候选配置。
观看: 如何调整超参数以提升模型性能 🚀
什么是超参数?#
超参数是算法的高级结构设置。它们在训练阶段开始前设定,并在训练过程中保持不变。以下是 Ultralytics YOLO 中一些常见的调优超参数:
- 学习率
lr0:决定每次迭代中向损失函数最小值移动时的步长。 - 批量大小
batch:一次前向传播中同时处理的图像数量。 - 轮数
epochs:一个轮次是对所有训练样本进行一次完整的前向传播和反向传播。 - 架构细节:例如通道数、层数、激活函数类型等。这些内容位于模型 YAML 配置中,而不是训练参数中。
这四项中,只有学习率位于默认搜索空间内:batch、epochs 和架构保持不变。调优器还会改变调度策略、损失增益,以及下方列出的增强方法。
遗传演化与变异#
Ultralytics YOLO 使用遗传算法(属于一类进化算法)来优化超参数。遗传算法的灵感来自自然选择和遗传机制。
- 选择:每次迭代都会从适应度最高的最多九个配置中按适应度加权选取一个。结果达到 30 个后,所有结果中适应度最高的 20%(最多 30 个)也会用于估算参数协方差;随着精英样本证据不断积累,其影响也会增大。
- 变异:每次迭代使用按搜索范围归一化的高斯步长,对大约一半的参数进行变异。协方差启用后,置信度加权的部分变异(最多 40%)会采用相关步长,并通过反射将这些步长限制在边界内,不会累积被截断的值。若多次试验持续没有改进,步长会在 25 次试验内线性缩小,最多缩小 20%;找到新的最佳结果时,步长会重置。第 1 次迭代没有父代,使用默认训练超参数作为基线。
准备超参数调优#
开始调优前,请务必:
- 确定指标:内置调优器(
use_ray=False)会根据任务的fitness得分为试验排序,而use_ray=True使用任务指标。确定要检查哪些次要指标,例如 AP50 或 F1 分数。 - 设定调优预算:明确你愿意分配多少计算资源。超参数调优可能需要大量计算。
调优循环的工作方式#
每次迭代中,内置调优器都会重复执行以下循环:
- 初始化超参数 — 从合理的基线开始,可以使用 Ultralytics YOLO 设置的默认超参数,也可以采用基于领域知识或先前实验确定的值。
- 变异超参数 —
Tuner类会自动通过其_mutate方法,根据现有超参数生成一组新的超参数。 - 训练模型 — 使用变异后的超参数进行训练,然后用你选择的指标评估训练性能。
- 评估模型 — 评估流程会生成本次迭代的适应度分数,并将其与之前迭代的分数进行比较,以判断当前超参数是否有所改进。
- 记录结果 — 记录性能指标和对应的超参数,以供日后参考。Ultralytics YOLO 会自动以 NDJSON 格式保存这些结果。
- 重复 — 持续执行,直到达到设定的迭代次数;每次迭代都会基于之前运行积累的经验继续进行。内置调优器会运行所有
iterations;Ray Tune 会在每个拟合轮次后报告指标,使 ASHA 能在宽限期后停止表现不佳的试验。
迭代次数与种群规模#
使用内置调优器(use_ray=False)时,iterations 控制顺序执行的试验总数,默认值为 300。每次试验都会使用一种超参数配置训练一个模型。例如,iterations=40 与 epochs=50 会安排 40 次相互独立的 50 轮训练,而不是用 40 个不同候选项组成的种群执行一次 50 轮训练。
内置遗传算法没有明确的种群规模参数。存在先前试验结果后,它会从适应度最高的最多九个配置中进行选择,并在每次迭代中变异一个候选配置。
如需并行试验或更高级的搜索策略,请将 use_ray=True 设置为使用 Ray Tune。Ray Tune 使用相同的默认试验次数 300,并接收 iterations 作为 num_samples。详情请参阅 Ray Tune 集成指南。
默认搜索空间#
下表列出了 YOLO26 超参数调优的默认搜索空间参数。每个参数都有由元组 (min, max) 定义的特定取值范围。
| 参数 | 类型 | 取值范围 | 说明 |
|---|---|---|---|
lr0 | float | (1e-5, 1e-2) | 训练开始时的初始学习率。较低的值能让训练更稳定,但收敛速度较慢 |
lrf | float | (0.01, 1.0) | 最终学习率相对于 lr0 的比例因子。控制训练过程中学习率的下降幅度 |
momentum | float | (0.7, 0.98) | SGD 动量因子。较高的值有助于保持梯度方向一致,并可能加快收敛 |
weight_decay | float | (0.0, 0.001) | 用于防止过拟合的 L2 正则化因子。较大的值会施加更强的正则化 |
warmup_epochs | float | (0.0, 5.0) | 线性学习率预热的轮数。有助于防止训练早期不稳定 |
warmup_momentum | float | (0.0, 0.95) | 预热阶段的初始动量。该值会逐渐增加到最终动量值 |
box | float | (1.0, 20.0) | 总损失函数中的边界框损失权重。用于平衡边界框回归与分类 |
cls | float | (0.1, 4.0) | 总损失函数中的分类损失权重。较高的值会更加重视正确的类别预测 |
cls_pw | float | (0.0, 1.0) | 用于处理类别不平衡的类别加权指数。较高的值会增加稀有类别的权重 |
dfl | float | (0.4, 12.0) | 边界框距离回归项的权重。无 DFL 的 YOLO26 会将此增益应用于归一化边界框距离上的 L1 损失;较高的值会更加重视精确定位 |
hsv_h | float | (0.0, 0.1) | HSV 色彩空间中的随机色调增强范围。有助于模型适应不同的颜色变化 |
hsv_s | float | (0.0, 0.9) | HSV 空间中的随机饱和度增强范围。用于模拟不同的光照条件 |
hsv_v | float | (0.0, 0.9) | 随机明度(亮度)增强范围。有助于模型适应不同的曝光水平 |
degrees | float | (0.0, 45.0) | 最大旋转增强角度(度)。有助于模型不受物体方向影响 |
translate | float | (0.0, 0.9) | 最大平移增强量,占图像尺寸的比例。提高模型对物体位置变化的鲁棒性 |
scale | float | (0.0, 0.95) | 随机缩放增强范围。有助于模型检测不同尺寸的物体 |
shear | float | (0.0, 10.0) | 最大剪切增强角度(度)。为训练图像添加类似透视的畸变 |
perspective | float | (0.0, 0.001) | 随机透视增强范围。用于模拟不同的观察角度 |
flipud | float | (0.0, 1.0) | 训练期间垂直翻转图像的概率。适用于俯视或航拍图像 |
fliplr | float | (0.0, 1.0) | 水平翻转图像的概率。有助于模型不受物体方向影响 |
bgr | float | (0.0, 1.0) | 使用 BGR 增强(交换颜色通道)的概率。有助于模型适应颜色变化 |
mosaic | float | (0.0, 1.0) | 使用马赛克增强(组合 4 张图像)的概率。对小物体检测尤其有用 |
mixup | float | (0.0, 1.0) | 使用 MixUp 增强(混合两张图像)的概率。有助于提高模型鲁棒性 |
cutmix | float | (0.0, 1.0) | 使用 CutMix 增强的概率。该增强会组合图像区域,同时保留局部特征 |
copy_paste | float | (0.0, 1.0) | 在 flip 模式下,表示符合条件的物体中被复制的比例;在 mixup 模式下,还表示应用该增强的概率 |
close_mosaic | int | (0.0, 10.0) | 在最后 N 个轮次中禁用马赛克增强,以便在训练结束前稳定训练。该值以浮点数进行变异,然后四舍五入为整数轮次 |
自定义搜索空间示例#
下面的示例定义了搜索空间,并调用 model.tune() 运行 Tuner 类,使用 AdamW 优化器在 COCO8 上对 YOLO26n 进行 30 个 epoch 的调优。为加快调优速度,会跳过绘图、检查点保存以及最后一个 epoch 以外的验证。
此示例仅用于演示。通过短时或小规模调优运行得出的超参数,在真实训练中很少能达到最优。实际应用中,调优应在与完整训练相近的设置下进行,包括相似的数据集、轮数和增强方式,以确保结果可靠且可迁移。快速调优可能会使参数偏向更快收敛或短期验证指标提升,而这些效果未必能泛化。
from ultralytics import YOLO

# 初始化 YOLO 模型
model = YOLO("yolo26n.pt")

# 定义搜索空间
search_space = {
    "lr0": (1e-5, 1e-2),
    "degrees": (0.0, 45.0),
}

# 在 COCO8 上调优 30 轮的超参数
model.tune(
    data="coco8.yaml",
    epochs=30,
    iterations=300,
    optimizer="AdamW",
    space=search_space,
    plots=False,
    save=False,
    val=False,
)恢复中断的超参数调优会话#
传入 resume=True 即可恢复中断的超参数调优会话。你也可以选择传入在 runs/{task} 下使用的目录 name 来恢复会话。如果不指定 name,则会恢复名为 tune 的目录;这是默认名称,而不一定是最近运行的会话,因此,对于使用自定义名称启动的运行,请传入 name。你还需要提供之前使用的所有训练参数,包括 data、epochs、iterations 和 space。
from ultralytics import YOLO

# 定义 YOLO 模型
model = YOLO("yolo26n.pt")

# 定义搜索空间
search_space = {
    "lr0": (1e-5, 1e-2),
    "degrees": (0.0, 45.0),
}

# 恢复之前的运行
results = model.tune(data="coco8.yaml", epochs=50, iterations=300, space=search_space, resume=True)

# 使用名称 'tune_exp' 恢复调优运行
results = model.tune(data="coco8.yaml", epochs=50, iterations=300, space=search_space, name="tune_exp", resume=True)结果#
成功完成超参数调优后,你会获得若干封装调优结果的文件和目录。以下是各项内容的说明:
文件结构#
以下是结果目录结构示例。multitrain/ 和 multitrain-2/ 等搜索目录存放各次独立的调优迭代,也就是每个数据集使用一组超参数训练一个模型,并存放在以数据集命名的子目录中。为节省存储空间,调优器会删除非当前最佳迭代对应的各数据集运行目录。tune/ 目录包含所有单个模型训练的调优结果:
runs/
└── detect/
    ├── multitrain/
    │   └── coco8/
    ├── multitrain-2/
    ├── ...
    └── tune/
        ├── best_hyperparameters.yaml
        ├── tune_fitness.png
        ├── tune_results.ndjson
        ├── tune_scatter_plots.png
        └── weights/
            ├── last.pt
└── best.pt文件说明#
best_hyperparameters.yaml#
此 YAML 文件包含调优过程中找到的性能最佳超参数。你可以使用此文件,在后续训练中以这些经过优化的设置进行初始化。
-
格式:YAML
-
用途:超参数结果
-
示例:
# 558/900 iterations complete ✅ (45536.81s)
# Results saved to /usr/src/ultralytics/runs/detect/tune
# Best fitness=0.64297 observed at iteration 498
# Best fitness metrics are {'metrics/precision(B)': 0.87247, 'metrics/recall(B)': 0.71387, 'metrics/mAP50(B)': 0.79106, 'metrics/mAP50-95(B)': 0.62651, 'val/box_loss': 2.79884, 'val/cls_loss': 2.72386, 'val/l1_loss': 0.68503, 'fitness': 0.64297}
# Best fitness model is /usr/src/ultralytics/runs/detect/tune/weights
# Best fitness hyperparameters are printed below.

lr0: 0.00269
lrf: 0.00288
momentum: 0.73375
weight_decay: 0.00015
warmup_epochs: 1.22935
warmup_momentum: 0.1525
box: 18.27875
cls: 1.32899
dfl: 0.56016
hsv_h: 0.01148
hsv_s: 0.53554
hsv_v: 0.13636
degrees: 0.0
translate: 0.12431
scale: 0.07643
shear: 0.0
perspective: 0.0
flipud: 0.0
fliplr: 0.08631
mosaic: 0.42551
mixup: 0.0
copy_paste: 0.0
tune_fitness.png#
此图展示了适应度随迭代次数的变化情况,可帮助你直观了解遗传算法随时间的表现。
- 格式:PNG
- 用途:性能可视化
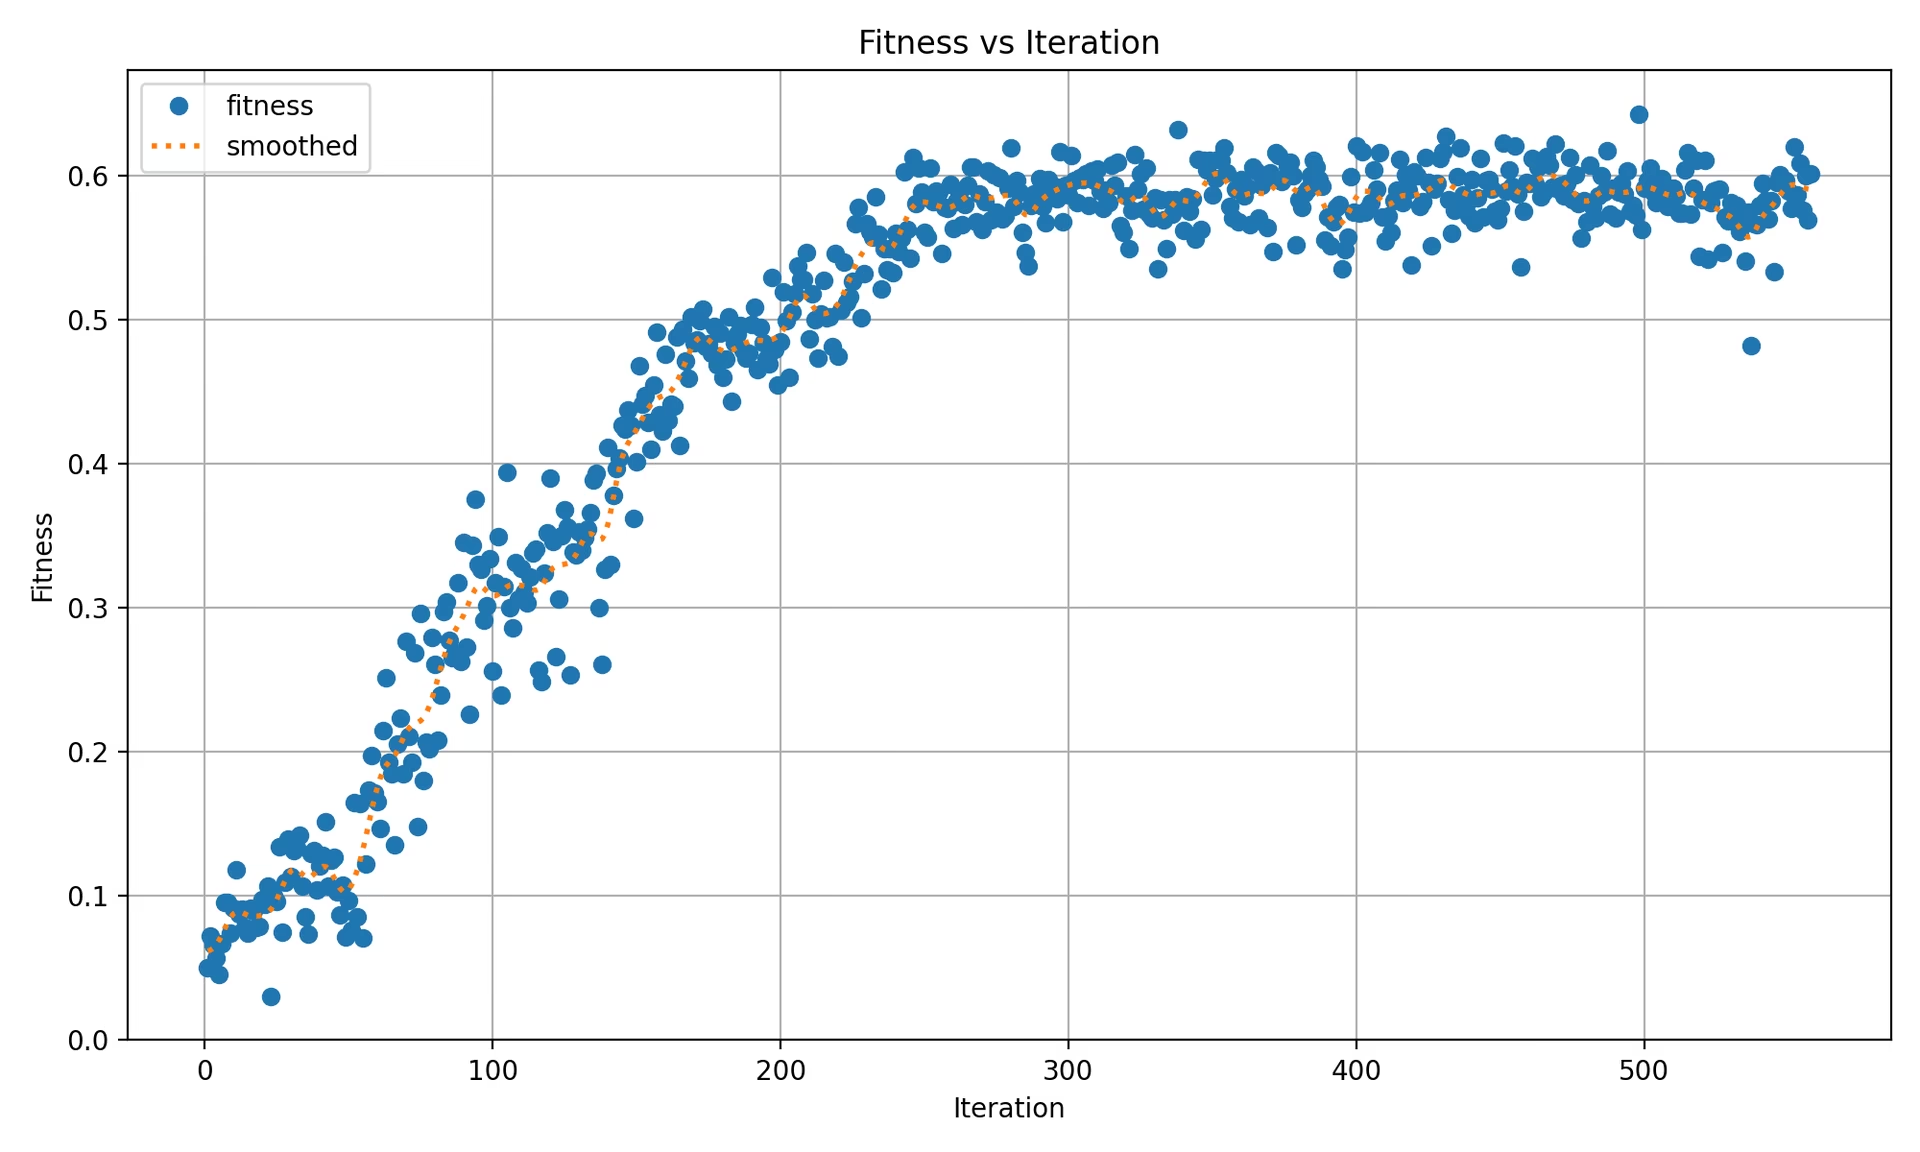
图中包含:
- 每个数据集的每次迭代各有一个标记,因此,单数据集运行中每次迭代显示一个点,多数据集运行中每个数据集的每次迭代均显示一个点。
- 一条点状的“平滑均值”曲线,通过对每次迭代的顶层适应度值进行高斯平滑(
sigma=3)计算得出。
tune_results.ndjson#
此 NDJSON 文件包含每次调优迭代的详细结果。每行都是一个 JSON 对象,包含汇总适应度、调优后的超参数和各数据集的指标。单数据集和多数据集调优使用相同的文件格式。
- 格式:NDJSON
- 用途:跟踪每次迭代的结果。
- 示例:
下面给出了经过美化排版的示例,便于阅读;在实际的 .ndjson 文件中,每个对象都存储在单独一行中。
{
    "iteration": 1,
    "fitness": 0.48628,
    "hyperparameters": {
        "lr0": 0.01,
        "lrf": 0.01,
        "momentum": 0.937,
        "weight_decay": 0.0005
    },
    "datasets": {
        "coco8": {
            "metrics/precision(B)": 0.65666,
            "metrics/recall(B)": 0.85,
            "metrics/mAP50(B)": 0.85086,
            "metrics/mAP50-95(B)": 0.64104,
            "val/box_loss": 1.57958,
            "val/cls_loss": 1.04986,
            "val/l1_loss": 1.32641,
            "fitness": 0.64104
        },
        "coco8-grayscale": {
            "metrics/precision(B)": 0.6582,
            "metrics/recall(B)": 0.51667,
            "metrics/mAP50(B)": 0.59106,
            "metrics/mAP50-95(B)": 0.33152,
            "val/box_loss": 1.95424,
            "val/cls_loss": 1.64059,
            "val/l1_loss": 1.70226,
            "fitness": 0.33152
        }
    },
    "save_dirs": {
        "coco8": "runs/detect/multitrain/coco8",
        "coco8-grayscale": "runs/detect/multitrain/coco8-grayscale"
    }
}
顶层的 fitness 是各数据集 fitness 值的算术平均值。对于单数据集调优,datasets 字典只有一个条目,其 fitness 等于顶层的 fitness。每完成一次迭代,就会记录一个 JSON 对象。实际的 save_dirs 路径都是绝对路径;上方为便于阅读进行了缩写。
tune_scatter_plots.png#
此文件包含根据 tune_results.ndjson 生成的散点图,可帮助你直观了解不同超参数与性能指标之间的关系。变异会使用每个超参数配置的范围,因此其值可以从 degrees 和 shear 等默认值为零的参数开始演化。
- 格式:PNG
- 用途:探索性数据分析
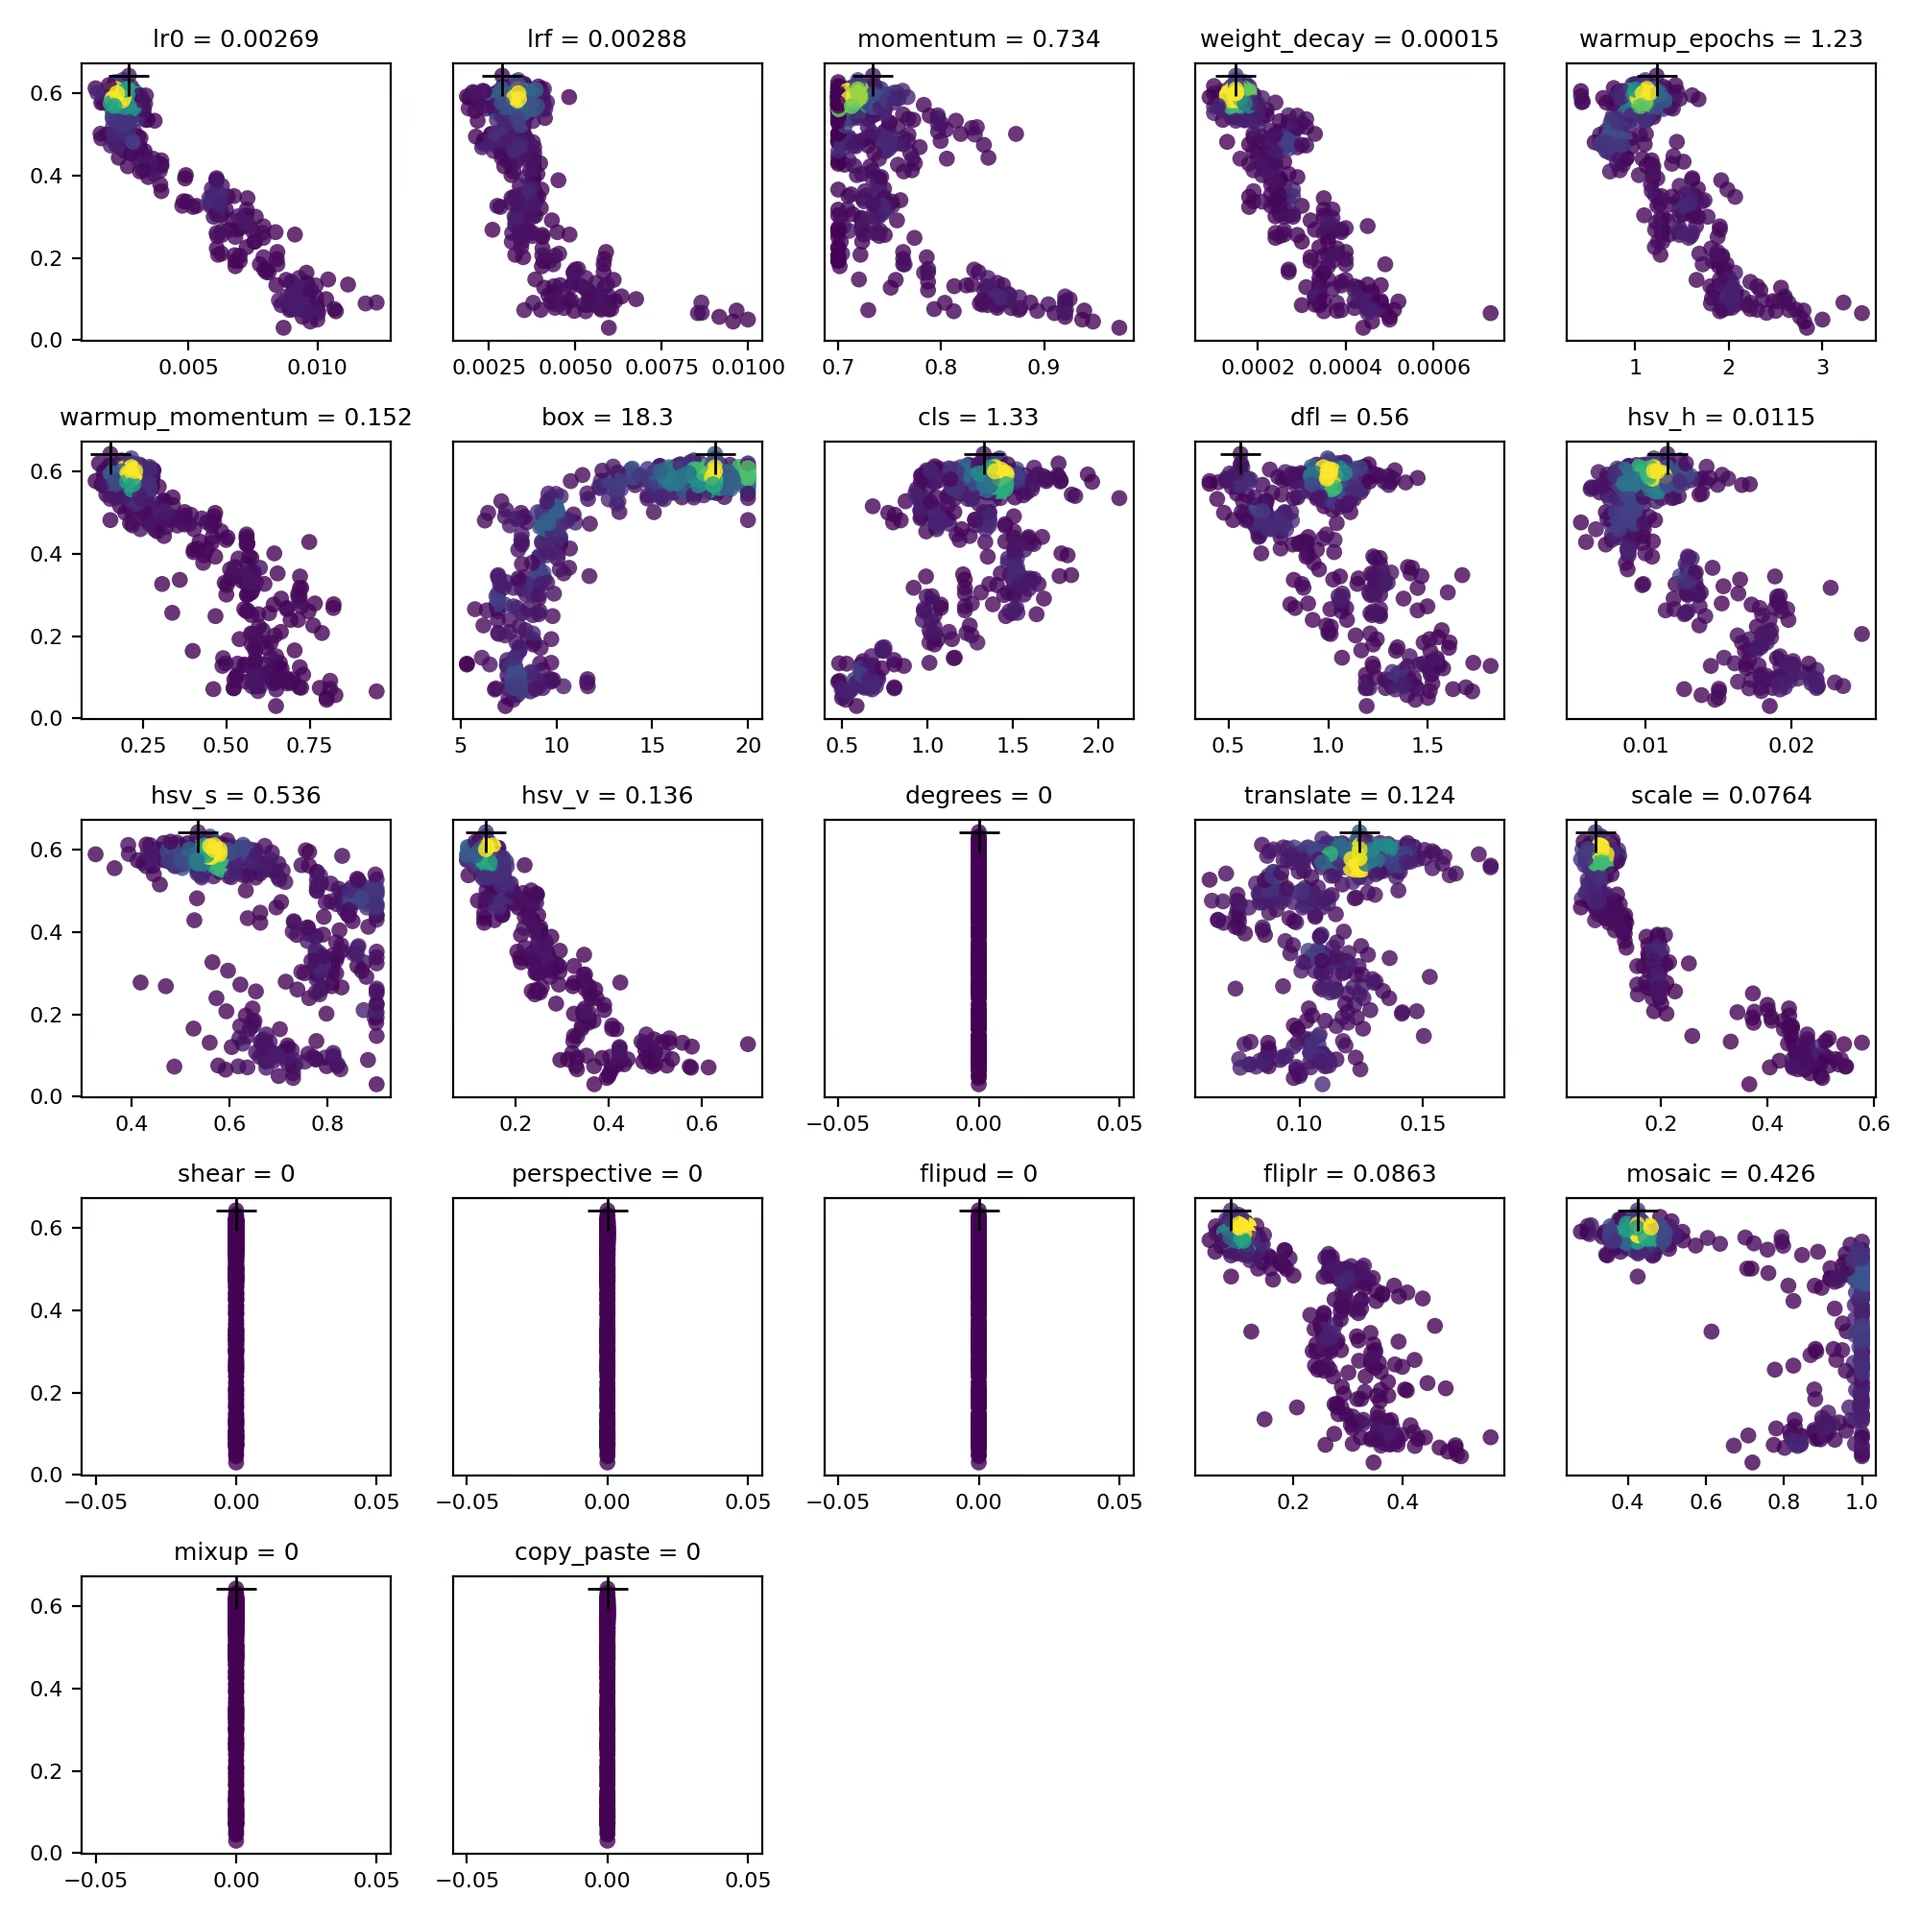
weights/#
此目录包含来自调优运行中适应度最佳迭代的已保存 PyTorch 模型。两个文件都来自同一次迭代:
last.pt:该轮训练最后一个 epoch 的权重。best.pt:该轮训练中适应度最佳的 epoch 所对应的权重。
利用这些结果,你可以为后续模型训练和分析做出更明智的决策。
结论#
Ultralytics YOLO 的超参数调优既易于启动,底层机制也很强大:它在遗传算法中使用基于适应度的加权选择和按范围归一化的变异。按照本指南概述的循环操作,你可以系统地调优模型以获得更好的性能,然后复用生成的 best_hyperparameters.yaml 来初始化后续训练。要在并行试验中扩展调优并使用更高级的搜索算法,请继续阅读 Ray Tune 集成指南;或者通过 云端训练,在 Ultralytics Platform 上运行托管任务,并配置超参数、实时跟踪指标。
对于没有任何参数可以设置的选项,例如逐层学习率或自定义适应度指标,请改为对训练器进行子类化。如需深入了解,请查看 Tuner 类的源代码。如果你有问题或功能需求,请在 GitHub 或 Discord 上联系我们。
常见问题#
使用
lr0参数设置初始值——常见取值范围是0.001到0.01——然后让调优过程从该值开始变异,以找到最优值。你可以使用model.tune()方法自动执行此操作。例如:示例from ultralytics import YOLO # 初始化 YOLO 模型 model = YOLO("yolo26n.pt") # 在 COCO8 上调优 30 轮的超参数 model.tune(data="coco8.yaml", epochs=30, iterations=300, optimizer="AdamW", plots=False, save=False, val=False)如需了解更多详情,请查看 Ultralytics YOLO 配置页面。
遗传算法为 Ultralytics YOLO26 提供了一种稳健的方式,无需手动反复试错即可探索超参数空间。主要优点包括:
- 高效搜索:基于适应度的加权选择会保留表现良好的配置,而按范围归一化的变异则会探索新的候选配置。
- 避免局部最优:随机变异有助于搜索跳出局部最优,而纯贪心搜索可能会困在其中。
- 性能指标:这些指标会根据特定任务的适应度分数进行调整(目标检测使用 mAP50-95)。
如需了解遗传算法如何优化超参数,请查看超参数演化指南。
使用 Ultralytics YOLO 进行超参数调优所需的时间,很大程度上取决于多个因素,例如数据集大小、模型架构的复杂度、迭代次数以及可用的计算资源。例如,在 COCO8 这类数据集上对 YOLO26n 调优 30 个 epoch,可能需要数小时到数天,具体取决于硬件。
要有效管理调优时间,请预先设定明确的调优预算,相关内容请参阅超参数调优准备工作。这有助于平衡资源分配与优化目标。


评论152
提出问题、分享结果,或帮助其他人。
GengBin414(已编辑)
I tuned my defect detection dataset ,which are composed of 8000+ images, this is my tune code: model.tune( data="../data/data20260420_line_scan_merged_6ch.yaml", epochs=300, iterations=300, #space=search_space, #optimizer="AdamW", optimizer="MuSGD", lr0=0.01, momentum=0.9, shear=1, degrees=1, perspective=0.0001, mixup=0.1, cutmix=0.1, batch=20 )
I got the best mAP 0.586 at iteration 5 after tuned 30+ iterations, then I retrain the dataset with the following code: model.train( data="../data/data20260420_line_scan_merged_6ch.yaml", epochs=300, batch=20, imgsz=640, device=0, workers=16, optimizer="MuSGD", lr0=0.00721, lrf=0.01267, momentum=0.81816, weight_decay=0.00077, warmup_epochs=3.31429, warmup_momentum=0.95, box=7.11682, cls=0.48318, dfl=0.9397, hsv_h=0.00364, hsv_s=0.9, hsv_v=0.29751, degrees=0.99922, translate=0.07662, scale=0.51303, shear=0.76723, perspective=0.0, flipud=0.00019, fliplr=0.57639, bgr=0.00634, mosaic=0.62424, mixup=0.11307, cutmix=0.13007, copy_paste=0.00583, close_mosaic=10 #cfg="best_hyperparameters_map0.586.yaml" )
I copied the hyperparameters from best_hyperparameters_map0.586.yaml, but I got the best mAP 0.568, what cause the discrepancy?Can sb help me out? Thanks.
 Glenn JocherUltralytics
A small gap like
0.586 -> 0.568is usually expected becausetune()saves the best single stochastic run, while your latertrain()is a fresh run with different randomness and augmentation order; please first validate the tuning checkpointruns/detect/tune/weights/best.pt, then retrain with the exact same args plusseed=0anddeterministic=True, and make sure you are comparing the same metric (fitness/mAP50-95) described in the Hyperparameter Tuning guide. If the gap still looks too large, please share the text output from validating that checkpoint and the matching row fromtune_results.ndjsonhere in Discussions so the team can compare them directly.Thank you for your timely reply, I validated the tuning checkpoint, here is the text output from validating that checkpoint: (yolo26) ps@ps:~/Desktop/GB/ultralytics$ python val.py Ultralytics 8.4.26 🚀 Python-3.11.15 torch-2.5.1 CUDA:0 (NVIDIA GeForce RTX 4090 D, 24208MiB) YOLO26x summary (fused): 190 layers, 55,645,380 parameters, 0 gradients, 193.9 GFLOPs val: Fast image access ✅ (ping: 0.0±0.0 ms, read: 10744.4±1424.6 MB/s, size: 734.1 KB) val: Scanning /home/ps/Desktop/GB/ultralytics/datasets/Merged_6Chanel_20260420/imagesH/val.cache... 786 images, 47 backgrounds, 0 corrupt: 100% ━━━━━━━━━━━━ 786/786 412.1Mit/s 0.0s Class Images Instances Box(P R mAP50 mAP50-95): 100% ━━━━━━━━━━━━ 50/50 6.9it/s 7.2s all 786 1363 0.843 0.69 0.765 0.585 black 45 47 0.914 0.677 0.828 0.648 crack 120 145 0.681 0.517 0.55 0.334 edge 184 195 0.916 0.899 0.94 0.833 line 116 147 0.809 0.646 0.736 0.544 pit 73 89 0.775 0.543 0.642 0.447 raw 279 318 0.861 0.745 0.81 0.644 white 95 106 0.9 0.623 0.712 0.46 yellow 299 316 0.884 0.873 0.9 0.773 Speed: 0.9ms preprocess, 7.3ms inference, 0.0ms loss, 0.0ms postprocess per image Results saved to /home/ps/Desktop/GB/ultralytics/runs/detect/val81
I checked my retrain args, it show that seed=0 and deterministic=True already set: python train.py New https://pypi.org/project/ultralytics/8.4.53 available 😃 Update with 'pip install -U ultralytics' Ultralytics 8.4.26 🚀 Python-3.11.15 torch-2.5.1 CUDA:0 (NVIDIA GeForce RTX 4090 D, 24208MiB) engine/trainer: agnostic_nms=False, amp=True, angle=1.0, augment=False, auto_augment=randaugment, batch=20, bgr=0.00634, box=7.11682, cache=False, cfg=None, classes=None, close_mosaic=10, cls=0.48318, compile=False, conf=None, copy_paste=0.00583, copy_paste_mode=flip, cos_lr=False, cutmix=0.13007, data=../data/data20260420_line_scan_merged_6ch.yaml, degrees=0.99922, deterministic=True, device=0, dfl=0.9397, dnn=False, dropout=0.0, dynamic=False, embed=None, end2end=None, epochs=500, erasing=0.4, exist_ok=False, fliplr=0.57639, flipud=0.00019, format=torchscript, fraction=1.0, freeze=None, half=False, hsv_h=0.00364, hsv_s=0.9, hsv_v=0.29751, imgsz=640, int8=False, iou=0.7, keras=False, kobj=1.0, line_width=None, lr0=0.00721, lrf=0.01267, mask_ratio=4, max_det=300, mixup=0.11307, mode=train, model=yolo26x.pt, momentum=0.81816, mosaic=0.62424, multi_scale=0.0, name=train137, nbs=64, nms=False, opset=None, optimize=False, optimizer=MuSGD, overlap_mask=True, patience=100, perspective=0.0, plots=True, pose=12.0, pretrained=True, profile=False, project=None, rect=False, resume=False, retina_masks=False, rle=1.0, save=True, save_conf=False, save_crop=False, save_dir=/home/ps/Desktop/GB/ultralytics/runs/detect/train137, save_frames=False, save_json=False, save_period=-1, save_txt=False, scale=0.51303, seed=0, shear=0.76723, show=False, show_boxes=True, show_conf=True, show_labels=True, simplify=True, single_cls=False, source=None, split=val, stream_buffer=False, task=detect, time=None, tracker=botsort.yaml, translate=0.07662, val=True, verbose=True, vid_stride=1, visualize=False, warmup_bias_lr=0.1, warmup_epochs=3.31429, warmup_momentum=0.95, weight_decay=0.00077, workers=16, workspace=None
And here is the train output: Epoch GPU_mem box_loss cls_loss dfl_loss Instances Size 260/300 20.8G 0.4503 0.4947 0.004246 50 640: 100% ━━━━━━━━━━━━ 354/354 2.7it/s 2:10 Class Images Instances Box(P R mAP50 mAP50-95): 100% ━━━━━━━━━━━━ 20/20 4.5it/s 4.4s all 786 1363 0.841 0.682 0.751 0.564 EarlyStopping: Training stopped early as no improvement observed in last 100 epochs. Best results observed at epoch 160, best model saved as best.pt. To update EarlyStopping(patience=100) pass a new patience value, i.e.
patience=300or usepatience=0to disable EarlyStopping.260 epochs completed in 9.792 hours. Optimizer stripped from /home/ps/Desktop/GB/ultralytics/runs/detect/train138/weights/last.pt, 118.4MB Optimizer stripped from /home/ps/Desktop/GB/ultralytics/runs/detect/train138/weights/best.pt, 118.4MB
Validating /home/ps/Desktop/GB/ultralytics/runs/detect/train138/weights/best.pt... Ultralytics 8.4.26 🚀 Python-3.11.15 torch-2.5.1 CUDA:0 (NVIDIA GeForce RTX 4090 D, 24208MiB) YOLO26x summary (fused): 190 layers, 55,645,380 parameters, 0 gradients, 193.9 GFLOPs Class Images Instances Box(P R mAP50 mAP50-95): 100% ━━━━━━━━━━━━ 20/20 4.9it/s 4.1s all 786 1363 0.826 0.685 0.758 0.568 black 45 47 0.882 0.634 0.773 0.579 crack 120 145 0.675 0.559 0.577 0.314 edge 184 195 0.925 0.885 0.949 0.824 line 116 147 0.785 0.667 0.714 0.52 pit 73 89 0.84 0.528 0.662 0.447 raw 279 318 0.812 0.72 0.804 0.638 white 95 106 0.802 0.611 0.674 0.434 yellow 299 316 0.888 0.877 0.911 0.787 Speed: 0.1ms preprocess, 4.4ms inference, 0.0ms loss, 0.0ms postprocess per image Results saved to /home/ps/Desktop/GB/ultralytics/runs/detect/train138
And I don't know where to find tune_results.ndjson mentioned in your reply. I guess you mean the matching row from tune_results.csv then here is: fitness lr0 lrf momentum weight_decay warmup_epochs warmup_momentum box cls dfl hsv_h hsv_s hsv_v degrees translate scale shear perspective flipud fliplr bgr mosaic mixup cutmix copy_paste close_mosaic 0.58582 0.00721 0.01267 0.81816 0.00077 3.31429 0.95 7.11682 0.48318 0.9397 0.00364 0.9 0.29751 0.99922 0.07662 0.51303 0.76723 0 0.00019 0.57639 0.00634 0.62424 0.11307 0.13007 0.00583 10
- Glenn JocherUltralytics
The main issue I see is that your retrain is not matching the tuned trial: the runtime log shows
epochs=500rather than300, so the schedule driven bylr0andlrfis different and that alone can explain0.585 -> 0.568; the current Hyperparameter Tuning guide writestune_results.ndjsonunderruns/detect/tune/, but in your older8.4.26install the equivalent may betune_results.csv, so please rerun with the exact runtime args from the best trial, especiallyepochs=300and the samepatience, and if it still printsepochs=500then another override is being applied. Sorry, after hyperparameter tuning, I retrained first with epochs=500, observed mAP=0.57, then I changed epochs=300, observed mAP=0.568. In the previous reply, I mistakenly copied the retrain args from the epochs=500 run. But the train output is correctly copied from the epochs=300 run, you can tell this out from the EarlyStopping output: Epoch GPU_mem box_loss cls_loss dfl_loss Instances Size 260/300 20.8G 0.4503 0.4947 0.004246 50 640: 100% ━━━━━━━━━━━━ 354/354 2.7it/s 2:10 Class Images Instances Box(P R mAP50 mAP50-95): 100% ━━━━━━━━━━━━ 20/20 4.5it/s 4.4s all 786 1363 0.841 0.682 0.751 0.564 EarlyStopping: Training stopped early as no improvement observed in last 100 epochs. Best results observed at epoch 160, best model saved as best.pt. To update EarlyStopping(patience=100) pass a new patience value, i.e. patience=300 or use patience=0 to disable EarlyStopping.
And the retrain args of the epochs=300 run, it shows that seed=0 and deterministic=True already set: python train.py New https://pypi.org/project/ultralytics/8.4.53 available 😃 Update with 'pip install -U ultralytics' Ultralytics 8.4.26 🚀 Python-3.11.15 torch-2.5.1 CUDA:0 (NVIDIA GeForce RTX 4090 D, 24208MiB) engine/trainer: agnostic_nms=False, amp=True, angle=1.0, augment=False, auto_augment=randaugment, batch=20, bgr=0.00634, box=7.11682, cache=False, cfg=None, classes=None, close_mosaic=10, cls=0.48318, compile=False, conf=None, copy_paste=0.00583, copy_paste_mode=flip, cos_lr=False, cutmix=0.13007, data=../data/data20260420_line_scan_merged_6ch.yaml, degrees=0.99922, deterministic=True, device=0, dfl=0.9397, dnn=False, dropout=0.0, dynamic=False, embed=None, end2end=None, epochs=300, erasing=0.4, exist_ok=False, fliplr=0.57639, flipud=0.00019, format=torchscript, fraction=1.0, freeze=None, half=False, hsv_h=0.00364, hsv_s=0.9, hsv_v=0.29751, imgsz=640, int8=False, iou=0.7, keras=False, kobj=1.0, line_width=None, lr0=0.00721, lrf=0.01267, mask_ratio=4, max_det=300, mixup=0.11307, mode=train, model=yolo26x.pt, momentum=0.81816, mosaic=0.62424, multi_scale=0.0, name=train138, nbs=64, nms=False, opset=None, optimize=False, optimizer=MuSGD, overlap_mask=True, patience=100, perspective=0.0, plots=True, pose=12.0, pretrained=True, profile=False, project=None, rect=False, resume=False, retina_masks=False, rle=1.0, save=True, save_conf=False, save_crop=False, save_dir=/home/ps/Desktop/GB/ultralytics/runs/detect/train138, save_frames=False, save_json=False, save_period=-1, save_txt=False, scale=0.51303, seed=0, shear=0.76723, show=False, show_boxes=True, show_conf=True, show_labels=True, simplify=True, single_cls=False, source=None, split=val, stream_buffer=False, task=detect, time=None, tracker=botsort.yaml, translate=0.07662, val=True, verbose=True, vid_stride=1, visualize=False, warmup_bias_lr=0.1, warmup_epochs=3.31429, warmup_momentum=0.95, weight_decay=0.00077, workers=16, workspace=None
 Murat Raimbekov
quick check on what is likely going on, framed generally: tune saves the best of N stochastic trials, and a single retrain is one new stochastic draw with the same hyperparameters. bit-exact reproduction between the two is not guaranteed even with
seed=0, deterministic=True. ourinit_seeds(deterministic=True)setstorch.use_deterministic_algorithms(True, warn_only=True)inultralytics/utils/torch_utils.py, matching the pytorch reproducibility notes - cuda ops without a deterministic alternative still run non-deterministically with just a warning. over many epochs on a real dataset that variance can compound.a few practical takeaways before assuming the gap is a tuning bug:
- your trial weights at
runs/detect/tune/weights/best.ptalready validate to 0.585, so the trial result is real and reusable - if you need exactly that performance for deployment, use that checkpoint directly. - the recommended way to reuse tuned hyperparameters in a fresh train run is
cfg="runs/detect/tune/best_hyperparameters.yaml"(the commented-out line in your script). that file contains the exact values the trial used and matches the workflow described in the hyperparameter tuning guide. - to bound run-to-run variance, retrain a few times with
seed=0,seed=1,seed=2and compare the mean against the tune's reported best, not a single retrain.
unrelated, you are on ultralytics 8.4.26 and the current release is 8.4.53; for new tuning runs it is worth updating.
- your trial weights at
 User
Hi, I have a question about Hyperparameter Tuning. What value of
epochsanditerationsshould I pass to model.tune(). Default value of epochs is 100, and iterations is 10. Are the default values OK, or should I change them ? My dataset is about 10,000 images.- Glenn JocherUltralytics
For a 10k-image dataset, the defaults are fine for a quick sanity check, but for useful tuning you should set
epochsclose to your real training length becauseepochsis per trial, whileiterationsis how many different trials are tested; a practical starting point isepochs=50to100withiterations=30to100depending on your compute budget, then retrain once with the best settings frombest_hyperparameters.yamlas shown in the Hyperparameter Tuning guide.1 - User
Thank you very much ! I will try to search the best hyperparameters !
- Glenn JocherUltralytics
You're welcome — sounds good; if anything looks off during tuning, please share your
model.tune()call plus the resultingbest_hyperparameters.yamlortune_results.ndjsonhere, and we can help compare it against the expected outputs in the Hyperparameter Tuning guide.
harunemrekiran61
You’ve shown the box range as 0.02 to 0.2, but the default value appears to be 7.5. Is there a mistake here? Could you please check?
- Glenn JocherUltralytics
Good catch —
boxis a loss gain (default7.5during training), so the0.02–0.2range shown in the docs table is outdated/incorrect; the current built-in tuner boundsboxto1.0–20.0(see the Tuner class reference), and you can always override it viaspace={...}as shown in the Hyperparameter Tuning guide.
Larry-zhai
How can I directly apply the optimized best_hyperparameters.yaml to my training? In fact, when I use code similar to the following: from ultralytics import YOLO model = YOLO("yolov8n.pt") model.train(data="data.yaml", hyp="hyp.yaml") an error occurs: SyntaxError: 'hyp' is not a valid YOLO argument.
 J.Q. Pan
Hi I have used the above code to apply the tuning but neither the diagram nor the models will be saved. I only get a single tune folder with all tuning details. I may ask if someone else has also the same problem.
BrianNieuwenhuis
When running the code below the model.tune() call does not recognize my model specification. Could someone explain to me what I am doing wrong. I am using model.overrides so that I can also tune the shear and perspective parameters that are otherwise initialized at 0.
from ultralytics import YOLO import wandb from ultralytics import settings settings.update({"wandb": True})
import argparse
def main(): # parse command-line args if needed parser = argparse.ArgumentParser() parser.add_argument("--gpus", type=int, default=1) parser.add_argument("--workers", type=int, default=4) args = parser.parse_args()
# Define a YOLO model
model = YOLO("yolo11x.pt")

# Dynamically assign GPUs based on --gpus argument
device = list(range(args.gpus))  # e.g., [0, 1, 2, 3] if args.gpus = 4

# Define search space
search_space = {
    "lr0": (1e-5, 1e-1),
    "lrf": (0.01, 1.0),
    "momentum": (0.6, 0.98),
    "weight_decay": (0.0, 0.001),
    "warmup_epochs": (0, 5),
    "warmup_momentum": (0.0,0.95),
    "box": (0.02, 0.2),
    "cls": (0.2, 4.0),
    "hsv_h": (0.0, 0.1),
    "hsv_s": (0.0, 0.9),
    "hsv_v": (0.0, 0.9),
    "translate":(0.0, 0.9),
    "scale": (0.0, 0.9),
    "shear": (0.0, 10.0),
    "perspective": (0.0, 0.001),
    "mosaic": (0.0,1.0),
    "mixup": (0.0, 1.0),
    "copy_paste": (0.0, 1.0)
}

# Manually initialize certain hperparameters that would not be tuned otherwise
model.overrides = {
    'shear': 1,
    'perspective': 0.001,
    'mixup': 0.01,
    'copy_paste' : 0.01,

}

# tune the model
results = model.tune(project='./tune/crop1344',name="tune_default_batch16_v100", use_ray = False,
    data="data.yaml",
    #hyp="custom_hyp.yaml", # this does not seem to work work for tune scripts!!
    batch = 16,
    imgsz = 1344,
    device = device,
    workers = args.workers,

    degrees = 180, #these parameters are fixed in the model tune
    flipud = 0.5,
    fliplr = 0.5,
    bgr = 0,
    auto_augment = None,
    #erasing = 0,

    epochs = 100,
    iterations=10,
    space=search_space,
    optimizer="AdamW",
    resume=False,  #start over or resume previous checkpoint
    plots=False,  # don't make plots etc to save time until last timepoint
    save=False,
    val=False,
    verbose=False)
if name == "main": main()
yyagmurkyaa
Hello again, I have trained new models using the parameters you provided and by organizing my datasets. However, a common issue across all of them is that the models mistakenly classify objects like myself or nearby computer screens as the traffic sign "turn right ahead" (which is one of the labeled classes in my dataset). I have checked my dataset and confirmed that there are no such unrelated objects in the background.
Additionally, the models sometimes confuse left and right directional signs.
Why might these errors be occurring, and how can I fix them? Thank you in advance for your help.
- Glenn JocherUltralytics(已编辑)
@Fatima-khanjar to balance precision and recall in your over-predicting model, try these adjustments:
- Increase confidence threshold during inference (not training) to filter out low-confidence predictions
- Adjust IoU threshold in NMS to reduce duplicate detections
- Increase classification loss weight with
cls=1.0or higher to improve class discrimination - Check annotation quality in your dataset, especially for small or ambiguous objects
- Add hard negative examples to your dataset - images with objects similar to your classes but not actually part of them
These changes should help improve precision without significantly sacrificing your excellent recall. For implementation details, see our NMS documentation for confidence thresholding examples.
@yyagmurkyaa for your traffic sign confusion issues:
-
For the model detecting unrelated objects as "turn right ahead" signs:
- Add "hard negative" examples to your training set (images with computers, people, but no traffic signs)
- Increase
cls=1.0or higher to improve classification accuracy - Check if the "turn right ahead" sign has visual similarities to these false positives
-
For left/right confusion:
- Create specific augmentations for directional signs without flipping (as you noted)
- Ensure balanced examples of both directional types
- Consider using a slightly larger model like YOLO26m for better feature discrimination
These targeted adjustments should help address the specific confusion patterns you're seeing.
Fatima-khanjar
Hello again!!
First of all, thank you so much for your help @glenn-jocher __ you've truly helped me a lot, and I really appreciate it!
I have a question regarding fine-tuning a pre-trained YOLO model (e.g., trained on the COCO dataset) for my custom use case. My dataset includes a combination of both new classes (not present in COCO) and some of the existing COCO classes , but with different layouts or contexts.
What I’d like to do is the following:
Add my new classes starting from index 80, while still leveraging the pre-trained weights for the existing COCO classes.
Ideally, I want to preserve the learned knowledge for the COCO classes (especially the ones shared with my dataset), and only train the model further on the new classes.
Is it possible to:
Fine-tune the model in such a way that it uses the pre-trained weights for the common classes, and only learns new classes from scratch starting from a different index?
Retain and benefit from the original COCO knowledge while introducing and training on new class definitions?
Also, I’ve noticed that when I fine-tune a pre-trained model and define my own data.yaml file — completely different from coco.yaml — I redefine the class names and indexes based on my custom dataset, completely removing the COCO classes not present in my data. In this case, what really happens during fine-tuning or transfer learning under the hood? Is the model discarding unused class weights? Are shared class weights still used effectively?
I'd greatly appreciate any clarification or guidance on how to approach this setup properly.
Best regards,
- Glenn JocherUltralytics
@Fatima-khanjar great question about fine-tuning with mixed COCO and custom classes!
Yes, you can leverage pre-trained COCO weights while adding new classes. Here's how:
-
When fine-tuning a YOLO model, the model's detection head is automatically resized to accommodate your new class count. The weights for existing classes are preserved where possible.
-
For classes that overlap with COCO, the model will leverage transfer learning from those pre-trained weights, while new classes will be initialized with random weights.
-
You don't need to explicitly start from index 80 - just define your classes in your data.yaml file, and the model will handle the mapping automatically.
-
During fine-tuning, the model doesn't discard unused class weights but rather reshapes the classification head to match your class count. Weights for classes that exist in both datasets are transferred and further optimized for your specific data.
For best results with mixed classes, I recommend using a smaller learning rate initially (e.g.,
lr0=0.001) to preserve the knowledge in the pre-trained weights while allowing the model to adapt to your new classes. -
Hello! @glenn-jocher thank you so much for your explanation!
I have a follow-up question regarding class index matching. Let's say the person class in the COCO dataset is indexed as 0, but in my data.yaml file, I assign person to index 5. In this case, the model will not treat the person at index 5 as the same class as COCO’s index 0, correct?
So, to benefit from the pretrained weights of shared classes, do the class indices in my custom dataset need to match the COCO indices exactly?
Best regards,
- Glenn JocherUltralytics(已编辑)
@Fatima-khanjar you're asking a crucial question about class mapping during transfer learning!
You no longer need to keep COCO's class indices. With
cls_remap=True(the default), training copies the pretrained classification-head rows by class name, so a class such aspersonkeeps its pretrained weights at whatever index it has in your dataset, while new classes such astraffic_signstart from fresh weights. Training printsRemapped N/M cls head rows from pretrained weights by class namewhen rows are copied, andcls_remap=Falsedisables it. For example, thisdata.yamlworks:names: 0: person 1: car 2: traffic_signJust make sure the shared classes use the same names as in COCO. See the Fine-Tuning Guide for details.
@glenn-jocher Hello again!!!
Thank you so much for your clarification! I have a quick follow-up question.
Let’s say the COCO dataset defines the following class indices in its YAML file: 0: person, 2: car, 3: cat.
In my own dataset, I share only the person and car classes with COCO — I don’t want to include cat. If I define my shared classes using the same indices as COCO (i.e., 0: person, 2: car), but then replace the COCO class cat at index 3 with a new class (e.g., 3: animal), will I still benefit from the pretrained weights for the shared classes (person and car)?
Or will assigning a new class at an index previously used by COCO (like 3) cause any issues?
best regards,
- Glenn JocherUltralytics(已编辑)
@Fatima-khanjar great question about reusing COCO indices for new classes!
With
cls_remap=True(the default), pretrained classification-head rows are matched by class name, not by index. Shared classes such aspersonandcarkeep their pretrained weights wherever they sit in your dataset. A new class like "animal" at index 3 does not inherit the pretrained "cat" row, because the names do not match, so it starts from fresh weights. Reusing a COCO index therefore neither helps nor hurts the shared classes.If a new class is close to a pretrained one, give it that class's name so its row is copied. Using a lower learning rate initially (e.g.,
lr0=0.001) also helps preserve the pretrained features while the model adapts to your new classes.1
Thank you for your feedback. I trained my dataset using YOLOv11s. Although I didn’t experience severe overfitting with the current parameters, I couldn’t achieve optimal performance either. Some traffic signs were misclassified or not detected at all.
While searching for the best hyperparameters, I realized that I hadn't applied data augmentation—except for the flip parameter. I have an example parameter file, and I plan to include all relevant augmentation options except for flipping.
I would really appreciate your help in finding the most suitable parameters for my dataset, as I’m planning to participate in a competition soon. I need to enhance my model by adjusting the parameters properly to achieve the best possible performance.
Thank you in advance for your support.
On Sun, Apr 20, 2025 at 1:51 PM phatima khanjar @.***> wrote:
Hello,
I hope this message finds you well.
image.png (view on web) https://github.com/user-attachments/assets/be6db84b-fe0d-4356-ba77-9b4426c253ee
I fine-tuned YOLOv11s on my custom dataset, which is relatively small (1,156 images split into 75% training, 15% validation, and 10% test). The dataset consists of 41 classes, with each class containing between 200 and 300 images. I experimented with three different sets of hyperparameters: the default values, those optimized using Ray Tune, and others obtained through a Genetic Algorithm. In all cases, I observed oscillations in the validation dfl and box losses, which may indicate signs of overfitting. I would appreciate any suggestions or insights on how to address this issue, particularly given the small size of the dataset, and how to improve model generalization.
best regards,
— Reply to this email directly, view it on GitHub https://github.com/orgs/ultralytics/discussions/9536#discussioncomment-12889695, or unsubscribe https://github.com/notifications/unsubscribe-auth/BPQ7ZLAQ2G7ZL434FN3WFYD22N345AVCNFSM6AAAAABFVXPSL2VHI2DSMVQWIX3LMV43URDJONRXK43TNFXW4Q3PNVWWK3TUHMYTEOBYHE3DSNI . You are receiving this because you were mentioned.Message ID: @.*** com>
- Glenn JocherUltralytics(已编辑)
@yyagmurkyaa for traffic sign detection and classification with YOLO26s, I recommend focusing on these specific augmentation and training parameters:
from ultralytics import YOLO

model = YOLO("yolo26s.pt")
model.train(
    data="your_traffic_signs.yaml",
    epochs=100,
    patience=25,
    batch=16,
    imgsz=640,  # Consider 800+ for small traffic signs
    hsv_h=0.015,  # Color augmentation helps with varying lighting conditions
    hsv_s=0.7,
    hsv_v=0.4,
    scale=0.5,  # Scale augmentation critical for varying distances
    translate=0.1,  # Helps with signs at different positions
    mosaic=1.0,  # Excellent for object detection tasks
    mixup=0.1,  # Light mixup can help with generalization
    perspective=0.0005,  # Slight perspective change for different viewing angles
    weight_decay=0.0005,  # Regularization to reduce overfitting
    optimizer="AdamW",
    lr0=0.001,
    lrf=0.01,
    cos_lr=True  # Cosine learning rate scheduler
)
For traffic sign detection specifically:
- Increase image size to better detect small signs
- Focus on color-preserving augmentations as colors are critical for traffic signs
- Use perspective transformations to simulate different viewing angles
- Enable strong scale/translate augmentations to handle varying distances
Consider running
model.tune()with these parameters as starting points to find the optimal configuration for your competition. You might also need to address class imbalance if some signs appear less frequently in your dataset. You're very welcome! I wasn't expecting such a quick response either. I'm excited to hear that you'll be training with these parameters and look forward to seeing the results as soon as possible. Thank you again for your support!
- Glenn JocherUltralytics(已编辑)
@Fatima-khanjar for a small dataset (1,156 images) with 41 classes, oscillations in validation losses often indicate overfitting. Here are specific recommendations to improve generalization:
-
Strengthen regularization:
- Increase
weight_decayto 0.001-0.003 - Add dropout with
dropout=0.1to reduce co-adaptation
- Increase
-
Enhance data augmentation:
- Maximize augmentations:
mosaic=1.0,mixup=0.2,copy_paste=0.1 - Use strong geometric transforms:
translate=0.2,scale=0.5
- Maximize augmentations:
-
Training modifications:
- Reduce model complexity by using YOLO26n instead of YOLO26s
- Implement gradual unfreezing (
freezelayers at first) - Enable
cos_lr=Truefor smoother learning rate decay
-
Consider transfer learning modifications:
- Start with a model pre-trained on a domain similar to yours
- Use fewer epochs with higher
patiencefor early stopping
With 41 classes and limited samples per class, these techniques should help stabilize training and improve generalization. You might also benefit from training ensembles of multiple models if computational resources allow. For more details, refer to our Model Training Tips.
-
Hello,
Thank you for your advice! Your instructions have improved my model’s performance compared to before. I have now achieved the following metrics:
Mean Precision: 0.794 Mean Recall: 0.99 Mean F1 Score: 0.881 mAP@0.5: 0.938 mAP@0.5-0.95: 0.827
After analyzing these results, it seems that the model is over-predicting. Do you have any suggestions on how I can better balance precision and recall?
best regards,
Hello,
I hope this message finds you well.
I fine-tuned YOLOv11s on my custom dataset, which is relatively small (1,156 images split into 75% training, 15% validation, and 10% test). The dataset consists of 41 classes, with each class containing between 200 and 300 images. I experimented with three different sets of hyperparameters: the default values, those optimized using Ray Tune, and others obtained through a Genetic Algorithm. In all cases, I observed oscillations in the validation dfl and box losses, which may indicate signs of overfitting. I would appreciate any suggestions or insights on how to address this issue, particularly given the small size of the dataset, and how to improve model generalization.
best regards,
Hello, I am training a model using YOLOv11, and the dataset consists of traffic signs. There are 22 classes, and each class has 400 labeled images. I’m not sure what parameters I should use for training. What parameters should I set to prevent overfitting, and what are the correct values? Could you help me with this?
- Glenn JocherUltralytics(已编辑)
@yyagmurkyaa your dataset of 22 classes with 400 images per class should provide a good foundation for traffic sign detection. To prevent overfitting with YOLO26, I'd recommend:
- Start with hyperparameter tuning using the
model.tune()method to find optimal values:
from ultralytics import YOLO model = YOLO("yolo26n.pt") # Start with a smaller model for faster tuning model.tune( data="your_traffic_signs.yaml", epochs=30, iterations=100, weight_decay=0.0005, # Try higher values like 0.001-0.005 to increase regularization patience=15, # Early stopping val=True )-
Key hyperparameters to prevent overfitting:
- Increase
weight_decay(0.001-0.005) - Enable strong data augmentation (
hsv_h,hsv_s,translate,scale,fliplr,mosaic) - Use early stopping with reasonable
patience - Consider reducing model capacity (use n or s model variants)
- Increase
-
Monitor validation metrics to detect overfitting (when training accuracy continues improving but validation metrics plateau or decline)
The automated tuning process should help identify the optimal parameter values for your specific dataset. For more details, check out our Hyperparameter Tuning Guide.
- Start with hyperparameter tuning using the
Thank you for your feedback. I trained my dataset using YOLOv11s. Although I didn’t experience severe overfitting with the current parameters, I couldn’t achieve optimal performance either. Some traffic signs were misclassified or not detected at all.
While searching for the best hyperparameters, I realized that I hadn't applied data augmentation—except for the flip parameter. I have an example parameter file, and I plan to include all relevant augmentation options except for flipping.
I would really appreciate your help in finding the most suitable parameters for my dataset, as I’m planning to participate in a competition soon. I need to enhance my model by adjusting the parameters properly to achieve the best possible performance.
Thank you in advance for your support.