YOLO12: اكتشاف الكائنات المرتكز على آلية الانتباه
نظرة عامة#
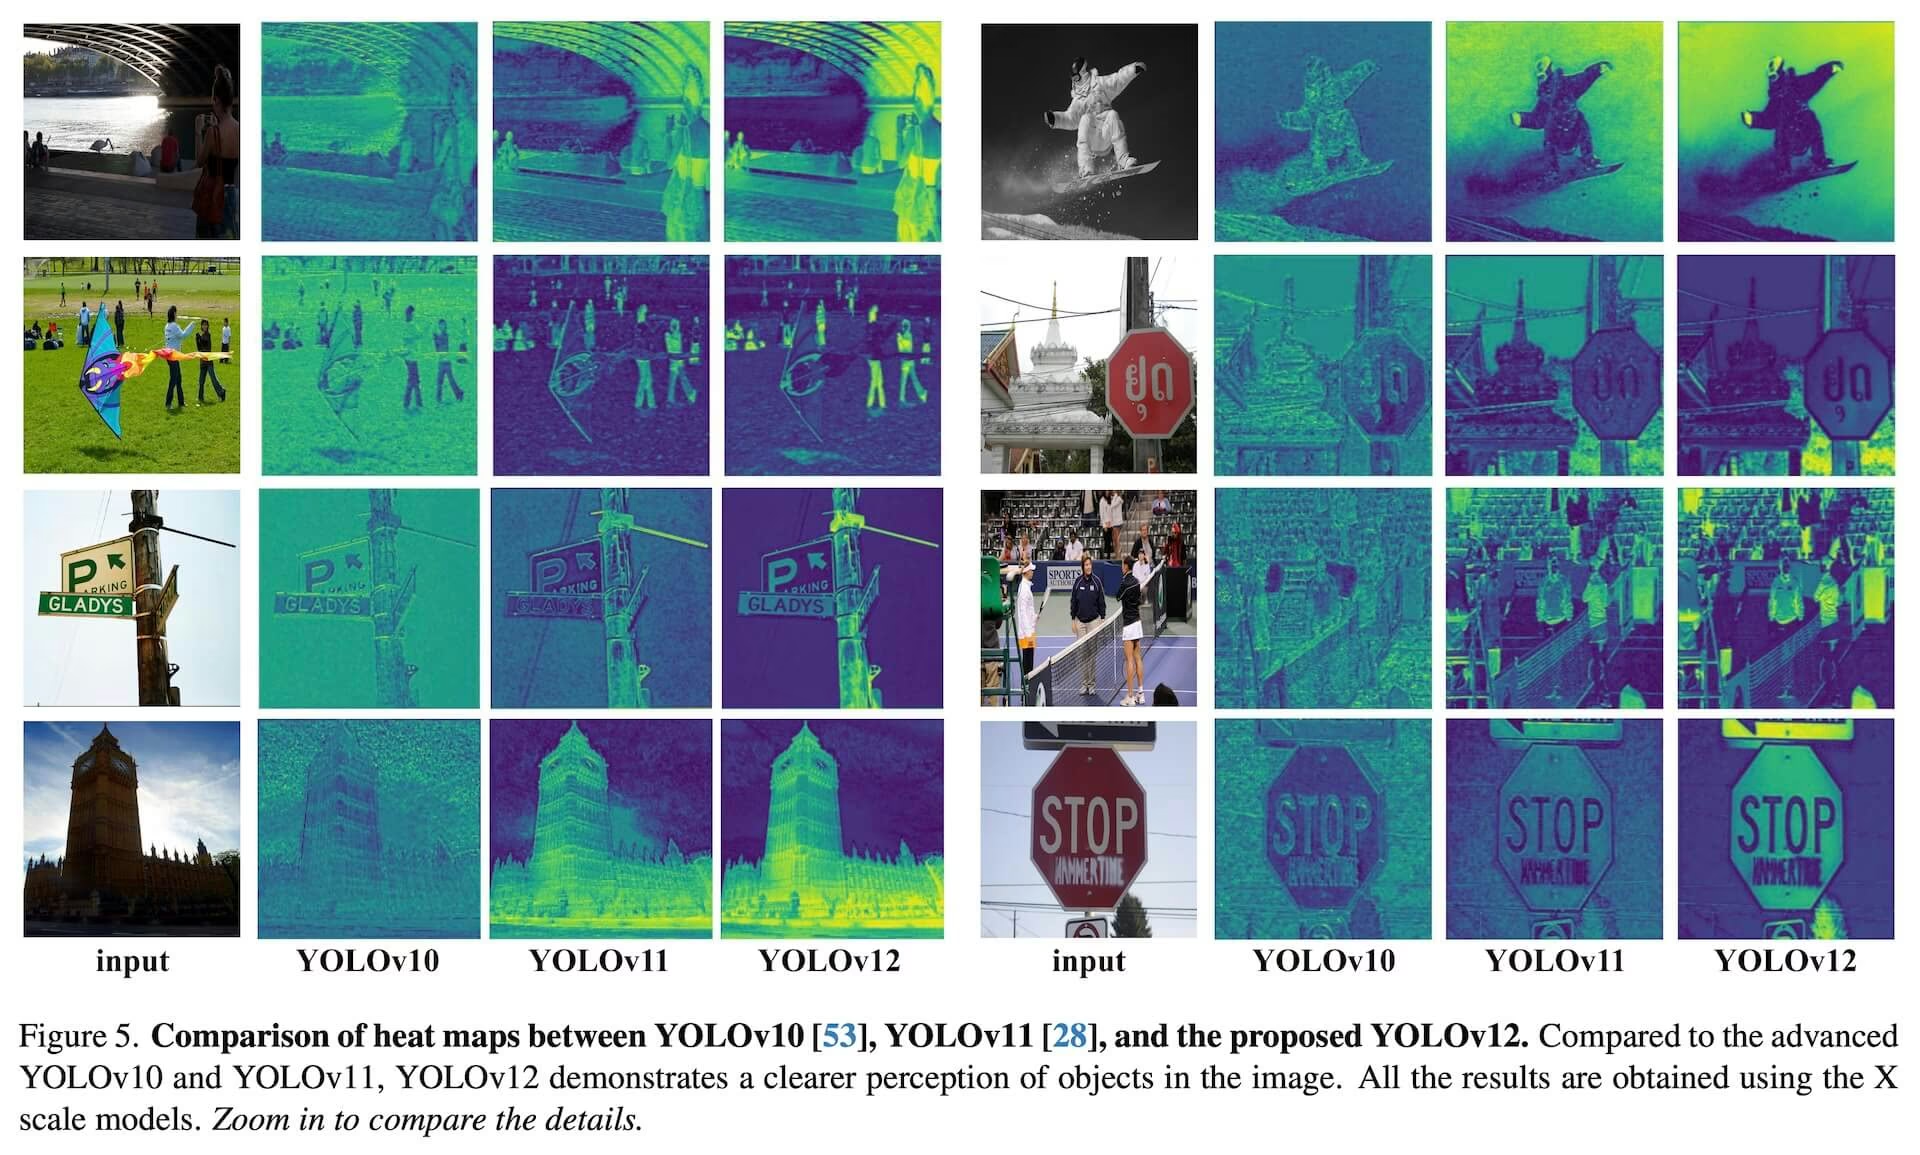
يقدم YOLO12، الذي أُصدر في أوائل عام 2025، بنية تتمحور حول الانتباه، وتختلف عن الأساليب التقليدية القائمة على الشبكات العصبية الالتفافية المستخدمة في نماذج YOLO السابقة، مع الحفاظ على سرعة الاستدلال الآني الضرورية لكثير من التطبيقات. ويحقق دقة عالية في اكتشاف الكائنات من خلال تغييرات في آليات الانتباه وبنية الشبكة ككل. وعلى الرغم من هذه المزايا، يظل YOLO12 إصدارًا تقوده مساهمات المجتمع وقد يُظهر عدم استقرار أثناء التدريب واستهلاكًا مرتفعًا للذاكرة ومعدل معالجة أبطأ على CPU بسبب كتل الانتباه الثقيلة فيه؛ لذا توصي Ultralytics باستخدام YOLO11 أو YOLO26 لمعظم أحمال العمل الإنتاجية.
يُصان YOLO12 أساسًا لأغراض القياس المعياري والبحث. إذا كنت بحاجة إلى تدريب مستقر واستخدام متوقع للذاكرة واستدلال محسّن على CPU، فاختر YOLO11 أو YOLO26 للنشر.
شاهد: كيفية استخدام YOLO12 لاكتشاف الكائنات باستخدام حزمة Ultralytics | هل YOLO12 سريع أم بطيء؟
الميزات الرئيسية#
- آلية الانتباه المناطقي: نهج جديد في الانتباه الذاتي يعالج الحقول الاستقبالية الكبيرة بكفاءة. ويقسّم خرائط السمات إلى مناطق متساوية الحجم عددها l (العدد الافتراضي 4)، أفقيًا أو عموديًا، متجنبًا العمليات المعقدة ومحافظًا على مجال استقبالي فعال واسع. ويقلل ذلك كثيرًا الكلفة الحسابية مقارنةً بالانتباه الذاتي القياسي.
- شبكات تجميع الطبقات الفعّالة ذات الوصلات المتبقية (R-ELAN): وحدة محسّنة لتجميع السمات تستند إلى ELAN، ومصممة لمعالجة تحديات التحسين، ولا سيما في النماذج الأكبر حجماً والمرتكزة على الانتباه. تقدّم R-ELAN ما يلي:
- وصلات متبقية على مستوى الكتل مع التحجيم (على غرار تحجيم الطبقات).
- أسلوباً معاد تصميمه لتجميع السمات ينشئ بنية شبيهة بعنق الزجاجة.
- بنية معمارية محسّنة للانتباه: يبسّط YOLO12 آلية الانتباه القياسية لتحسين الكفاءة والتوافق مع إطار عمل YOLO. ويشمل ذلك:
- استخدام FlashAttention لتقليل عبء الوصول إلى الذاكرة.
- إزالة الترميز الموضعي لإنشاء نموذج أبسط وأسرع.
- تعديل نسبة MLP (من القيمة المعتادة 4 إلى 1.2 أو 2) لتحقيق توازن أفضل في العمليات الحسابية بين طبقات الانتباه والتغذية الأمامية.
- تقليل عمق الكتل المتراصة لتحسين التحسين.
- استخدام عمليات الالتفاف (حيثما كان ذلك مناسبًا) لكفاءتها الحسابية.
- إضافة التفاف قابل للفصل بحجم 7x7 (يُسمى «مدرِك الموضع») إلى آلية الانتباه لترميز المعلومات الموضعية ضمنياً.
- دعم شامل للمهام: يدعم YOLO12 مجموعة من مهام الرؤية الحاسوبية الأساسية: اكتشاف الكائنات، وتقسيم الكائنات إلى مثيلات، وتصنيف الصور، وتقدير الوضعية، واكتشاف الكائنات الموجّهة (OBB).
- كفاءة محسّنة: يحقق دقة أعلى باستخدام عدد أقل من المعلمات مقارنة بالعديد من النماذج السابقة، ما يدل على تحسن التوازن بين السرعة والدقة.
- نشر مرن: صُمم للنشر على منصات متنوعة، من الأجهزة الطرفية إلى البنية التحتية السحابية.
المهام والأوضاع المدعومة#
يدعم YOLO12 مجموعة متنوعة من مهام الرؤية الحاسوبية. يوضح الجدول أدناه المهام المدعومة وأوضاع التشغيل (التدريب والتحقق والاستدلال والتصدير) المتاحة لكل منها:
لم تُنشر على ultralytics/assets سوى أوزان الاكتشاف (yolo12n.pt وyolo12s.pt وyolo12m.pt وyolo12l.pt وyolo12x.pt). أما بُنى التقسيم والتصنيف والوضعية وOBB فمحددة في ultralytics/cfg/models/12/، لذا تدعم هذه المتغيرات التدريب من الصفر باستخدام إعدادات .yaml، لكن لا تتوفر حالياً لها ملفات .pt مدرّبة مسبقاً. وبالنسبة إلى نقاط التحقق المدرّبة مسبقاً للتقسيم أو الوضعية أو التصنيف أو OBB، توصي Ultralytics باستخدام YOLO11 أو YOLO26.
| نوع النموذج | المهمة | الأوزان المدرّبة مسبقاً | التدريب | التحقق | الاستدلال | التصدير |
|---|---|---|---|---|---|---|
| YOLO12 | الكشف | ✅ | ✅ | ✅ | ✅ | ✅ |
| YOLO12-seg | التقسيم | ❌ | ✅ | ✅ | ✅ | ✅ |
| YOLO12-cls | التصنيف | ❌ | ✅ | ✅ | ✅ | ✅ |
| YOLO12-pose | الوضعية | ❌ | ✅ | ✅ | ✅ | ✅ |
| YOLO12-obb | OBB | ❌ | ✅ | ✅ | ✅ | ✅ |
تدعم جميع بُنى YOLO12 كل الأنماط عند توفر نقطة تحقق مدرّبة. ويشير عمود Pretrained Weights فقط إلى ما إذا كانت Ultralytics تنشر نموذجاً رسمياً مدرّباً مسبقاً .pt على ultralytics/assets: وبالنسبة إلى التقسيم والوضعية والتصنيف وOBB، يجب تدريب نقطة التحقق الخاصة بك باستخدام .yaml المقابل قبل تشغيل الاستدلال أو التحقق أو التصدير.
مقاييس الأداء#
يحسّن YOLO12 الدقة عبر جميع أحجام النماذج، مع بعض التنازلات في السرعة مقارنةً بنماذج YOLO السابقة الأسرع. فيما يلي النتائج الكمية لمهمة اكتشاف الكائنات على مجموعة بيانات التحقق من COCO:
أداء الاكتشاف (COCO val2017)#
| النموذج | الحجم (بكسل) | mAPval50-95 | السرعة CPU ONNX (مللي ثانية) | السرعة T4 TensorRT (مللي ثانية) | المعاملات (M) | FLOPs (B) | المقارنة (mAP/السرعة) |
|---|---|---|---|---|---|---|---|
| YOLO12n | 640 | 40.6 | - | 1.64 | 2.6 | 7.5 | +2.1%/-9% (مقارنةً بـ YOLOv10n) |
| YOLO12s | 640 | 48.0 | - | 2.61 | 9.3 | 23.3 | +0.1%/+42% (مقارنةً بـ RT-DETRv2) |
| YOLO12m | 640 | 52.5 | - | 4.86 | 20.2 | 70.7 | +1.0%/-3% (مقارنةً بـ YOLO11m) |
| YOLO12l | 640 | 53.7 | - | 6.77 | 26.4 | 95.4 | +0.4%/-8% (مقارنةً بـ YOLO11l) |
| YOLO12x | 640 | 55.2 | - | 11.79 | 59.1 | 208.9 | +0.6%/-4% (مقارنةً بـ YOLO11x) |
- تم قياس سرعة الاستدلال على وحدة GPU من طراز NVIDIA T4 بدقة FP16 باستخدام TensorRT.
- توضح المقارنات التحسن النسبي في mAP والنسبة المئوية للتغير في السرعة (تشير القيمة الموجبة إلى سرعة أعلى، والسالبة إلى سرعة أقل). وأُجريت المقارنات بالاستناد إلى النتائج المنشورة لـ YOLOv10 وYOLO11 وRT-DETR متى توفرت.
أمثلة الاستخدام#
يقدم هذا القسم أمثلة على التدريب والاستدلال باستخدام YOLO12.
تركز الأمثلة أدناه على نماذج YOLO12 للاكتشاف (لاكتشاف الكائنات). للاطلاع على وثائق المهام الأخرى المدعومة (التقسيم والتصنيف وتقدير الوضعية واكتشاف الكائنات الموجّهة)، راجع وثائق كل مهمة على حدة: التقسيم، والتصنيف، والوضعية، وOBB.
يمكن تمرير النماذج المدرّبة مسبقاً *.pt (باستخدام PyTorch) وملفات الإعداد *.yaml إلى الفئة YOLO() لإنشاء مثيل نموذج في Python:
from ultralytics import YOLO
# تحميل نموذج YOLO12n مدرّب مسبقاً على COCO
model = YOLO("yolo12n.pt")
# تدريب النموذج على مجموعة بيانات المثال COCO8 لمدة 100 حقبة
results = model.train(data="coco8.yaml", epochs=100, imgsz=640)
# تشغيل الاستدلال باستخدام نموذج YOLO12n على الصورة 'bus.jpg'
results = model("path/to/bus.jpg")أبرز التحسينات#
-
تحسين استخراج السمات:
- الانتباه المناطقي: يعالج الحقول الاستقبالية الكبيرة بكفاءة، مما يقلل الكلفة الحسابية.
- توازن محسّن: تحسين التوازن بين العمليات الحسابية للانتباه والشبكة ذات التغذية الأمامية.
- R-ELAN: يعزز تجميع السمات باستخدام بنية R-ELAN.
-
ابتكارات التحسين:
- الوصلات المتبقية: يضيف وصلات متبقية مع التحجيم لتحقيق استقرار التدريب، ولا سيما في النماذج الأكبر.
- تكامل محسّن للسمات: يطبّق أسلوباً محسّناً لتكامل السمات ضمن R-ELAN.
- FlashAttention: يدمج FlashAttention لتقليل العبء الناتج عن الوصول إلى الذاكرة.
-
كفاءة البنية المعمارية:
- تقليل المعلمات: يحقق عدداً أقل من المعلمات مع الحفاظ على الدقة أو تحسينها مقارنة بالعديد من النماذج السابقة.
- تبسيط الانتباه: يستخدم تطبيقاً مبسطاً للانتباه، ويتجنب الترميز الموضعي.
- نسب MLP محسّنة: يضبط نسب MLP لتوزيع الموارد الحسابية بفعالية أكبر.
المتطلبات#
لا يتطلب تطبيق Ultralytics YOLO12، افتراضياً، استخدام FlashAttention. ومع ذلك، يمكن تجميع FlashAttention واستخدامه اختيارياً مع YOLO12. ويتطلب تجميع FlashAttention توفر إحدى وحدات GPU التالية من NVIDIA:
- وحدات GPU من Turing (مثل T4 وسلسلة Quadro RTX)
- وحدات GPU من Ampere (مثل سلسلة RTX30 وA30/40/100)
- وحدات GPU من Ada Lovelace (مثل سلسلة RTX40)
- وحدات معالجة الرسومات من Hopper (مثل H100/H200)
الاستشهادات والشكر والتقدير#
إذا استخدمت YOLO12 في أبحاثك، يُرجى الاستشهاد بالعمل الأصلي لجامعة University at Buffalo وجامعة الأكاديمية الصينية للعلوم:
@inproceedings{tian2025yolov12,
  title={YOLOv12: Attention-Centric Real-Time Object Detectors},
  author={Tian, Yunjie and Ye, Qixiang and Doermann, David},
  booktitle={Advances in Neural Information Processing Systems},
  volume={38},
  pages={78433--78457},
  year={2025},
  url={https://proceedings.neurips.cc/paper_files/paper/2025/file/7103444259031cc58051f8c9a4868533-Paper-Conference.pdf}
}

@software{yolo12,
  author = {Tian, Yunjie and Ye, Qixiang and Doermann, David},
  title = {YOLO12: Attention-Centric Real-Time Object Detectors},
  year = {2025},
  url = {https://github.com/sunsmarterjie/yolov12},
  license = {AGPL-3.0}
}
نُشرت ورقة YOLO12 في وقائع NeurIPS 2025، مع نسخة أولية على arXiv.
الأسئلة الشائعة#
يضم YOLO12 عدة ابتكارات أساسية لتحقيق التوازن بين السرعة والدقة. تعالج آلية الانتباه المناطقي الحقول الاستقبالية الكبيرة بكفاءة، مما يقلل الكلفة الحسابية مقارنةً بالانتباه الذاتي القياسي. وتحسّن شبكات تجميع الطبقات الفعالة المتبقية (R-ELAN) تجميع السمات، وتعالج تحديات التحسين في النماذج الأكبر التي تتمحور حول الانتباه. كما تعزز بنية الانتباه المحسّنة الكفاءة، بما في ذلك استخدام FlashAttention وإزالة الترميز الموضعي. وتتيح هذه الميزات لـ YOLO12 تحقيق دقة عالية مع الحفاظ على سرعة الاستدلال الآني التي تحتاج إليها تطبيقات كثيرة.
يدعم YOLO12 نطاقًا واسعًا من مهام الرؤية الحاسوبية الأساسية: اكتشاف الكائنات، وتقسيم الكائنات الفردية، وتصنيف الصور، وتقدير الوضعية، واكتشاف الكائنات الموجّهة (OBB). وهذا يجعل YOLO12 مناسبًا لـمجالات متنوعة، من الروبوتات والقيادة الذاتية إلى التصوير الطبي والفحص الصناعي. تجدر الإشارة إلى أن أوزان
.ptالمدرّبة مسبقًا منشورة حاليًا لمهمة الاكتشاف فقط؛ أما بنيات التقسيم وتقدير الوضعية والتصنيف وOBB فتُتاح في صورة ملفات إعداد.yamlللتدريب من البداية.يحسّن YOLO12 الدقة في جميع أحجام النماذج مقارنةً بنماذج YOLO السابقة مثل YOLOv10 وYOLO11، مع بعض التنازلات في السرعة مقارنةً بأسرع النماذج السابقة. فعلى سبيل المثال، يحقق YOLO12n تحسنًا قدره +2.1% في mAP مقارنةً بـ YOLOv10n، وتحسنًا قدره +1.2% مقارنةً بـ YOLO11n على مجموعة بيانات COCO val2017. وبالمقارنة مع نماذج مثل RT-DETR، يحقق YOLO12s تحسنًا قدره +1.5% في mAP وزيادة في السرعة قدرها +42%. وتبرز هذه المقاييس التوازن القوي الذي يحققه YOLO12 بين الدقة والكفاءة.
لا يتطلب تنفيذ Ultralytics لـYOLO12 استخدام FlashAttention افتراضيًا. ومع ذلك، يمكن تجميع FlashAttention اختياريًا واستخدامه مع YOLO12 لتقليل عبء الوصول إلى الذاكرة. ولتجميع FlashAttention، يلزم استخدام إحدى وحدات GPU من NVIDIA التالية: وحدات GPU من Turing (مثل T4 وسلسلة Quadro RTX)، أو Ampere (مثل سلسلة RTX30 وA30/40/100)، أو Ada Lovelace (مثل سلسلة RTX40)، أو Hopper (مثل H100/H200). ويتيح ذلك للمستخدمين الاستفادة من FlashAttention عندما تدعم أجهزتهم ذلك.
تقدم هذه الصفحة أمثلة استخدام أساسية للتدريب والاستدلال. يستخدم YOLO12 واجهات الأوضاع Train وVal وPredict وExport نفسها، وواجهات المهام Segment وClassify وPose وOBB نفسها، التي تستخدمها نماذج Ultralytics الأخرى.


التعليقات69
اطرح سؤالًا، وشارك نتائجك، أو ساعد شخصًا آخر.
Zixuan-He
I try use the YOLO12-seg, but with update to lastest version (> pip install -U ultralytics) it is still showing (No such file or directory: 'YOLO12n-seg.pt) with code (yolo segment train data=data.yaml model=YOLO12n-seg.pt epochs=200 batch=16 imgsz=640 patience=25 ). theYOLO12n.pt for obj is good. Is the code changed or need other input?
1 Glenn JocherUltralytics
@Zixuan-He Answer:
The YOLO12-seg model requires using its specific configuration file. Trymodel=yolo12-seg.yamlinstead of the.ptfile to initialize training. The segmentation weights are not yet released as pretrained.ptfiles, but you can train from scratch using the YAML configuration. For details, see the YOLO12-seg documentation.2LucasGenoud
Hello, thank you for your answer ! Do you have any date estimation of when the pretrained segmentation models for YOLO12 will be available ? Thanks
- Glenn JocherUltralytics
We don't have an official release date for YOLO12-seg pretrained weights yet, but you can train segmentation models from scratch using the YOLO12-seg.yaml configuration. For updates, please monitor the YOLO12 documentation.
Thank you for your response. Great work :)
- Glenn JocherUltralytics
Thank you for your kind words! We don't have a specific release date for YOLO12-seg pretrained weights yet, but you can monitor the YOLO12 documentation for updates. The team typically announces new model releases there first. For now, training from scratch using the YOLO12-seg.yaml configuration remains the recommended approach.
dolokbutarbutar24
Here are some sample images for the healthy class. I also attached some "results" images, hopefully can give more information so you guys can help me with the project.
Pada Sen, 30 Mar 2026 pukul 15.58 Glenn Jocher @.***> menulis:
Thanks for dropping this question here so the Ultralytics team can see it; for leaf-disease datasets, mAP50-95 usually improves more from cleaner labels, balanced class counts, harder negative samples, and reviewing per-class PR/confusion outputs than from pushing loss weights alone, so I’d next tune weight_decay, momentum, warmup_epochs, lrf, translate, shear, perspective, fliplr, and close_mosaic using the hyperparameter tuning guide https://docs.ultralytics.com/guides/hyperparameter-tuning/ and performance metrics guide https://docs.ultralytics.com/guides/yolo-performance-metrics/. If you can share a few sample images, labels, and training curves here, we can suggest a tighter search space, and it’s also worth benchmarking the same split with YOLO26 https://docs.ultralytics.com/models/yolo26/ since YOLO12 is mainly maintained as a community research model.
— Reply to this email directly, view it on GitHub https://github.com/orgs/ultralytics/discussions/19360?email_source=notifications&email_token=A23CVICPPIXOD6F3LMBB52T4TIZKDA5CNFSNUABIM5UWIORPF5TWS5BNNB2WEL2ENFZWG5LTONUW63SDN5WW2ZLOOQXTCNRTG44DGNRZUZZGKYLTN5XKOY3PNVWWK3TUUVSXMZLOOSWGM33PORSXEX3DNRUWG2Y#discussioncomment-16378369, or unsubscribe https://github.com/notifications/unsubscribe-auth/A23CVIG2PM2BD5335IFZQXT4TIZKDAVCNFSM6AAAAABXS26SR6VHI2DSMVQWIX3LMV43URDJONRXK43TNFXW4Q3PNVWWK3TUHMYTMMZXHAZTMOI . You are receiving this because you commented.Message ID: @.*** com>
- Glenn JocherUltralytics
Thanks, that helps; from those samples I’d next verify that the
healthylabels are fully consistent and that the class counts are not skewed, then please attach a few matching image/label.txtpairs plusresults.csvandconfusion_matrix_normalized.pngso we can check whether this is a data issue rather than a YOLO12 training issue, and if you recently fixed labels please delete anylabels/*.cachefiles before retraining.
I am currently working on a project to detect cassava leaf diseases using YOLOv12. The focus of this research is to perform hyperparameter tuning and also determine the most suitable augmentation configuration to improve model performance. So far, the trained model is still hovering around the 0.5 range for the mAP@50-95 evaluation metric. Here are the hyperparameters I have used for tuning so far: epochs=100, patience=20, imgsz=1024, batch=8, optimizer='auto', lr0=0.00511, box=6.32971, cls=2.87957, dfl=2.12658, mosaic=0.25, scale=0.15, mixup=0.0, copy_paste=0.0, degrees=10.0, hsv_h=0.015, hsv_s=0.7, hsv_v=0.4.
What other strategies can I do to improve my model's performance, especially on the mAP@50-95 evaluation metric? Do you have any suggestions for other hyperparameters that need to be added to this project for tuning? I'm sure your experience and skills can answer that and help me hahaha.
- Glenn JocherUltralytics
Thanks for dropping this question here so the Ultralytics team can see it; for leaf-disease datasets, mAP50-95 usually improves more from cleaner labels, balanced class counts, harder negative samples, and reviewing per-class PR/confusion outputs than from pushing loss weights alone, so I’d next tune
weight_decay,momentum,warmup_epochs,lrf,translate,shear,perspective,fliplr, andclose_mosaicusing the hyperparameter tuning guide and performance metrics guide. If you can share a few sample images, labels, and training curves here, we can suggest a tighter search space, and it’s also worth benchmarking the same split with YOLO26 since YOLO12 is mainly maintained as a community research model.
 Clousy
在5090 32G上使用yolo12l训练模型的时候,数据量大概7万左右,batch_size=24 内存占用在24G左右,为啥速度只有2-3it/s 是哪里设置有问题?下面是训练参数: rain_args = dict( data="data.yaml", epochs=500, imgsz=640, batch=24, device=device, workers=16,
cache=False, amp=True, # --- 减少 CPU 负担 --- mosaic=0.0, # 暂时关掉 Mosaic 看看速度是否飙升 mixup=0.0, # 同上 )- Glenn JocherUltralytics
yolo12l本身是重注意力结构,吞吐会比同尺度的 CNN 系列低不少,所以你看到的2–3 it/s在batch=24下未必异常(折算大约是48–72 img/s);如果你目标是更高训练/CPU 端速度,建议直接换到更稳更快的 Ultralytics YOLO26(YOLO12 更偏研究/基准用途,见 YOLO12 文档)。想确认是不是环境/数据读取瓶颈的话,请把yolo checks输出和完整文本训练日志(含第一轮的进度条行、CUDA:/显卡名、DataLoader相关信息)贴在这里;另外你现在cache=False可能会被磁盘 IO 卡住、workers=16在部分系统上也会造成额外调度开销,建议先用下面这组参数做一次对照测试(同一数据/同一imgsz),看it/s是否明显变化:yolo checks yolo train model=yolo12l.pt data=data.yaml epochs=2 imgsz=640 batch=24 device=0 workers=8 cache=True mosaic=0.0 mixup=0.0
is there any video (tutorial) about how to classify plant disease? i'm confused about how to do it because i need guidance to do classify task
- Glenn JocherUltralytics(تم التعديل)
Yes—plant disease is just a standard image classification workflow; please follow the Ultralytics YOLO classification guide (and drop any follow-up questions here in this discussion so the Ultralytics team can see them), then try:
from ultralytics import YOLO

# ImageNet-pretrained classifier backbone (recommended starting point)
model = YOLO("yolo26n-cls.pt")

# Your dataset folder should contain train/ and val/ with one subfolder per class
model.train(data="path/to/plant_disease_dataset", epochs=50, imgsz=224)
If you share your dataset folder layout (just the directory tree) and what’s confusing you, I can point you to the exact next step.
asad121101
Hello , this new yolo12 is using what architecture in neck ? pan or fpn ? or some thing else ?
Sourabh0052
while working on classification model using YOLO12-cls and i do not make any .yaml file, just simply provide the data source path then will it work same or not
radadiavasu
I faced a problem that recently I put my model on training with yolo12x but at 98/100 epoch it stopped due to units are over on colab pro but when I start again and expect to start from 98 but it start from 1/100 instead of 98 even in results.csv I couldn't get anything. Why this problem occurs?
deldanr
When resuming a training session started with Yolov12, after the AMP check, the training session downloads a Yolov11 model to continue, which I assume is an error.
Attached is part of the log: YOLOv12l summary: 488 layers, 26,389,875 parameters, 26,389,859 gradients, 89.4 GFLOPs
Transferred 1245/1245 items from pretrained weights Freezing layer 'model.21.dfl.conv.weight' AMP: Running Automatic Mixed Precision (AMP) checks... Downloading https://github.com/ultralytics/assets/releases/download/v8.3.0/yolo11n.pt to 'yolo11n.pt'... <-- Here's the error
pvurda
Has anyone found a low-cost, low-latency way to generate a short semantic scene caption (e.g., “two people loading a van”) on top of YOLO12 detections in real time?