Uso de YOLO26 con SAHI para la inferencia por fragmentos
Esta guía de integración de SAHI ha quedado obsoleta en favor del argumento tile de Ultralytics para el entrenamiento, la validación y la predicción. Consulta Teselado de alta resolución.

Esta guía explica cómo usar YOLO26 con SAHI (inferencia hiperrápida asistida por recortes). Abarca qué es SAHI, por qué la inferencia por recortes ayuda a detectar objetos pequeños en imágenes grandes y de alta resolución, y cómo ejecutarla con YOLO26 para mejorar los resultados de detección de objetos.
Introducción a SAHI#
SAHI (inferencia hiperrápida asistida por recortes) es una biblioteca diseñada para mejorar la detección de objetos en imágenes de gran tamaño y alta resolución. Divide las imágenes en recortes manejables, detecta objetos en cada recorte y, después, vuelve a unir los resultados. SAHI es compatible con diversos modelos de detección de objetos, incluida la serie YOLO.
Ver: Cómo usar SAHI con Ultralytics YOLO26 para detectar objetos pequeños | Inferencia con mosaicos asistida por recortes 🚀
Características principales de SAHI#
- Integración sencilla: SAHI funciona con los modelos Ultralytics YOLO mediante
AutoDetectionModel, así que puedes empezar a recortar y detectar con muy pocos cambios en el código. - Eficiencia de recursos: Al dividir las imágenes grandes en partes más pequeñas, SAHI mantiene bajo el uso de memoria y permite realizar detecciones de alta calidad en hardware con recursos limitados.
- Alta precisión: SAHI combina las detecciones superpuestas de recortes adyacentes al unirlos, mediante técnicas de posprocesamiento como la supresión no máxima o la fusión no máxima.
¿Qué es la inferencia por fragmentos?#
La inferencia por recortes consiste en subdividir una imagen grande o de alta resolución en segmentos más pequeños (recortes), detectar objetos en esos segmentos y, después, asignar las detecciones a las ubicaciones correspondientes en la imagen original. Esta técnica resulta útil cuando los recursos computacionales son limitados, cuando se trabaja con imágenes de resolución extremadamente alta que podrían causar problemas de memoria o cuando los objetos son demasiado pequeños para detectarlos tras reducir la imagen completa al tamaño de entrada del modelo.
Ventajas de la inferencia por fragmentos#
-
Menor consumo de memoria: Cada recorte es pequeño, por lo que el uso máximo de memoria se mantiene bajo incluso con imágenes muy grandes y el funcionamiento es más fluido en hardware de gama baja.
-
Mejor detección de objetos pequeños: Cada recorte se procesa con la resolución de entrada del modelo, por lo que los objetos pequeños ocupan más píxeles y son más fáciles de detectar, siempre que los recortes sean lo bastante grandes para contener los objetos de interés.
-
Mayor escalabilidad: Esta técnica facilita el escalado de la detección de objetos a imágenes de distintos tamaños y resoluciones, por lo que resulta adecuada para una amplia variedad de aplicaciones, desde las imágenes por satélite hasta el diagnóstico médico.
| Ultralytics YOLO26 sin SAHI | Ultralytics YOLO26 con SAHI |
|---|---|
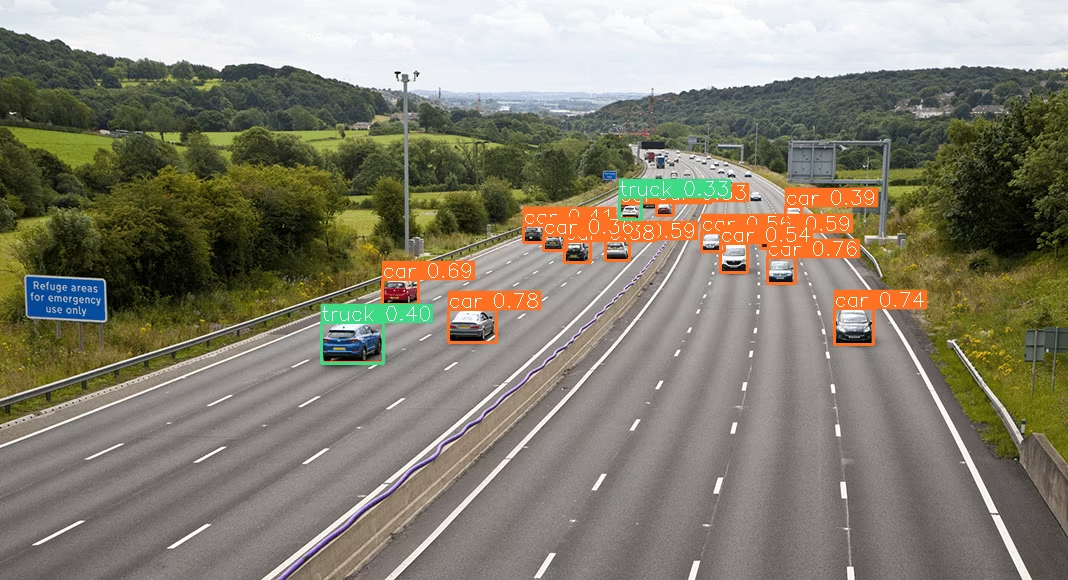 | 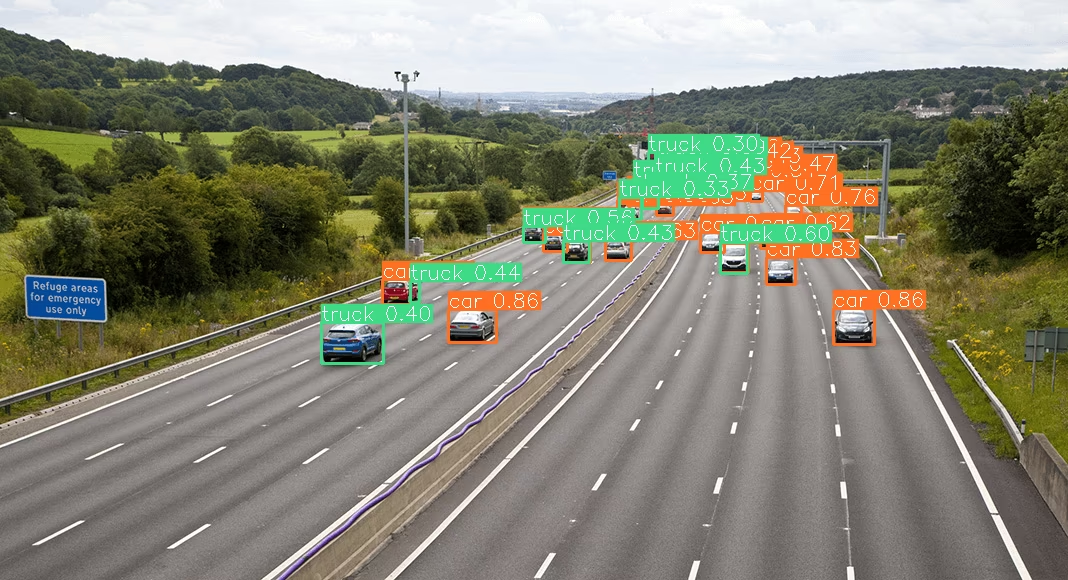 |
Instalación y preparación#
Instalación#
Para empezar, instala las últimas versiones de SAHI y Ultralytics:
pip install -U ultralytics sahiImportar módulos y descargar recursos#
A continuación, se explica cómo descargar algunas imágenes de prueba:
from sahi.utils.file import download_from_url

# Descargar imágenes de prueba
download_from_url(
    "https://raw.githubusercontent.com/obss/sahi/main/demo/demo_data/small-vehicles1.jpeg",
    "demo_data/small-vehicles1.jpeg",
)
download_from_url(
    "https://raw.githubusercontent.com/obss/sahi/main/demo/demo_data/terrain2.png",
    "demo_data/terrain2.png",
)
Inferencia estándar con YOLO26#
Instanciar el modelo#
Puedes instanciar un modelo YOLO26 para la detección de objetos de esta forma:
from sahi import AutoDetectionModel

detection_model = AutoDetectionModel.from_pretrained(
    model_type="ultralytics",
    model_path="yolo26n.pt",
    confidence_threshold=0.3,
    device="cpu",  # o 'cuda:0'
)
Realizar una predicción estándar#
Realiza una inferencia estándar utilizando la ruta de una imagen.
from sahi.predict import get_prediction

result = get_prediction("demo_data/small-vehicles1.jpeg", detection_model)

result.export_visuals(export_dir="demo_data/", hide_conf=True)
Visualizar los resultados#
Exporta y visualiza los cuadros delimitadores y las máscaras predichos:
from PIL import Image

# Abrir la imagen predicha
processed_image = Image.open("demo_data/prediction_visual.png")

# Mostrar la imagen predicha
processed_image.show()
Inferencia por fragmentos con YOLO26#
Realiza una inferencia por fragmentos especificando sus dimensiones y las proporciones de solapamiento:
from PIL import Image
from sahi.predict import get_sliced_prediction

result = get_sliced_prediction(
    "demo_data/small-vehicles1.jpeg",
    detection_model,
    slice_height=256,
    slice_width=256,
    overlap_height_ratio=0.2,
    overlap_width_ratio=0.2,
)

# Exportar resultados
result.export_visuals(export_dir="demo_data/", hide_conf=True)

# Abrir la imagen predicha
processed_image = Image.open("demo_data/prediction_visual.png")

# Mostrar la imagen predicha
processed_image.show()
Gestionar los resultados de las predicciones#
SAHI proporciona un objeto PredictionResult que se puede convertir a varios formatos de anotación:
# Acceder a la lista de predicciones de objetos
object_prediction_list = result.object_prediction_list

# Convertir a los formatos de anotación COCO y de predicción COCO
result.to_coco_annotations()[:3]
result.to_coco_predictions(image_id=1)[:3]Predicción por lotes#
Para realizar predicciones por lotes en un directorio de imágenes:
from sahi.predict import predict

predict(
    model_type="ultralytics",
    model_path="yolo26n.pt",
    model_device="cpu",  # o 'cuda:0'
    model_confidence_threshold=0.4,
    source="path/to/dir",
    slice_height=256,
    slice_width=256,
    overlap_height_ratio=0.2,
    overlap_width_ratio=0.2,
)
Ya puedes utilizar YOLO26 con SAHI tanto para la inferencia estándar como para la inferencia por fragmentos.
Citas y agradecimientos#
Si utilizas SAHI en tus trabajos de investigación o desarrollo, cita el artículo original de SAHI y reconoce la contribución de sus autores:
@article{akyon2022sahi,
  title={Slicing Aided Hyper Inference and Fine-tuning for Small Object Detection},
  author={Akyon, Fatih Cagatay and Altinuc, Sinan Onur and Temizel, Alptekin},
  journal={2022 IEEE International Conference on Image Processing (ICIP)},
  doi={10.1109/ICIP46576.2022.9897990},
  pages={966-970},
  year={2022}
}
Agradecemos al grupo de investigación SAHI la creación y el mantenimiento de este recurso para la comunidad de visión artificial.
Preguntas frecuentes#
La integración de Ultralytics YOLO26 con SAHI (inferencia hiperrápida asistida por recortes) para la inferencia por recortes mejora la detección de objetos en imágenes de alta resolución al dividirlas en recortes manejables. Este método ayuda a detectar objetos pequeños y mantiene el uso de memoria bajo control. Para empezar, tienes que instalar las bibliotecas ultralytics y sahi:
pip install -U ultralytics sahiA continuación, descarga las imágenes de prueba:
from sahi.utils.file import download_from_url # Descargar imágenes de prueba download_from_url( "https://raw.githubusercontent.com/obss/sahi/main/demo/demo_data/small-vehicles1.jpeg", "demo_data/small-vehicles1.jpeg", ) download_from_url( "https://raw.githubusercontent.com/obss/sahi/main/demo/demo_data/terrain2.png", "demo_data/terrain2.png", )Utilizar SAHI con Ultralytics YOLO26 para detectar objetos en imágenes grandes ofrece varias ventajas:
- Menor consumo de memoria: Los recortes más pequeños consumen menos memoria, lo que permite realizar detecciones de alta calidad en hardware con recursos limitados.
- Mejor detección de objetos pequeños: Los recortes mantienen los objetos pequeños grandes en relación con la entrada del modelo, y SAHI combina los cuadros superpuestos de los recortes adyacentes.
- Mayor escalabilidad: Al escalar las tareas de detección de objetos a imágenes de distintos tamaños y resoluciones, SAHI resulta adecuado para varias aplicaciones, como el análisis de imágenes por satélite y el diagnóstico médico.
Obtén más información sobre las ventajas de la inferencia por fragmentos en nuestra documentación.
Sí, puedes visualizar los resultados de las predicciones al utilizar YOLO26 con SAHI. A continuación, se explica cómo exportar y visualizar los resultados:
from PIL import Image

result.export_visuals(export_dir="demo_data/", hide_conf=True)

processed_image = Image.open("demo_data/prediction_visual.png")

processed_image.show()
Este comando guardará las predicciones visualizadas en el directorio especificado. Después podrás cargar la imagen para verla en tu cuaderno o aplicación. Para obtener una guía detallada, consulta la sección Inferencia estándar.
SAHI (inferencia hiper asistida por segmentación) ofrece varias funciones que complementan Ultralytics YOLO26 para la detección de objetos:
- Integración sencilla: SAHI funciona con modelos YOLO con cambios mínimos en el código.
- Eficiencia de recursos: Divide las imágenes grandes en recortes más pequeños, lo que mantiene bajo el uso de memoria.
- Alta precisión: Al combinar los cuadros de detección superpuestos durante el proceso de unión, SAHI evita las detecciones duplicadas en los límites entre recortes.
Para profundizar, lee sobre las características principales de SAHI.
Para gestionar proyectos de inferencia a gran escala con YOLO26 y SAHI, sigue estas prácticas recomendadas:
- Instala las bibliotecas necesarias: asegúrate de tener las versiones más recientes de ultralytics y sahi.
- Configura la inferencia por recortes: determina las dimensiones óptimas de los recortes y los índices de solapamiento para tu proyecto concreto.
- Ejecuta predicciones por lotes: Usa la función
predictde SAHI para ejecutar predicciones por lotes en un directorio de imágenes.
Ejemplo de predicción por lotes:
from sahi.predict import predict

predict(
    model_type="ultralytics",
    model_path="path/to/yolo26n.pt",
    model_device="cpu",  # o 'cuda:0'
    model_confidence_threshold=0.4,
    source="path/to/dir",
    slice_height=256,
    slice_width=256,
    overlap_height_ratio=0.2,
    overlap_width_ratio=0.2,
)
Para consultar los pasos detallados, visita nuestra sección sobre predicción por lotes.


Comentarios215
Haz una pregunta, comparte tus resultados o ayuda a otra persona.
ZSBSB
Your work is perfect, I have one question, does the current point SAHI library support yolov11's rotating frame target detection?
1 Fatih AkyonUltralytics
Yes it supports 👌🏻
illink7
Hi folks. I still work with SAHI and YOLOv8-seg When I tried to do segmentation with small aerial image without SAHI it works well and segment my objects (forest and buildings) But when I try to do this with SAHI it doesn't provide results with mask. I've installed all nececcary libraries, and they have the same environment but still no results Could you check my code and maybe you find the best solution?
from sahi.predict import get_sliced_prediction from sahi import AutoDetectionModel from PIL import Image import os from ultralytics import YOLO import torch import numpy as np from PIL import Image
Set the path to the image
IMAGE_PATH = r"PATH"
Setting the path to the model
MODEL_PATH = r"PATH"
Upload an image
image = Image.open(IMAGE_PATH)
Initialize the model
detection_model = AutoDetectionModel.from_pretrained( model_type='yolov8', model_path=MODEL_PATH, confidence_threshold=0.25, device="cpu" # if torch.cuda.is_available() else "cpu" )
Performing predictions with cutting the image into 512x512 parts
result = get_sliced_prediction( image, detection_model, slice_height=512, slice_width=512, overlap_height_ratio=0.2, overlap_width_ratio=0.2 )
Saving the results
output_dir = 'output_vs' os.makedirs(output_dir, exist_ok=True) result.export_visuals(export_dir=output_dir, file_name='segmented_image.png')
Initialize the dictionary for merged masks by class
combined_masks_by_class = {}
Export masks and combine them by class
for prediction in result.object_prediction_list: mask = prediction.mask
category_name = prediction.category.name
if mask is not None: mask_array = mask.bool_mask # Scale the mask to the size of the original image mask_image = Image.fromarray((mask_array.astype(np.uint8) * 255)) mask_resized = mask_image.resize((image.width, image.height), resample=Image.NEAREST) mask_resized_np = np.array(mask_resized)# Add a mask to the appropriate class in the dictionary if category_name not in combined_masks_by_class: combined_masks_by_class[category_name] = np.zeros((image.height, image.width), dtype=np.uint8) combined_masks_by_class[category_name] = np.maximum(combined_masks_by_class[category_name], mask_resized_np)Store merged masks by class
for category_name, combined_mask in combined_masks_by_class.items(): combined_mask_image = Image.fromarray(combined_mask) combined_mask_image.save(os.path.join(output_dir, f'combined_mask_{category_name}.png'))
print(f"Results saved in {output_dir}")
After that code I receive aerial image with boxes and label but without masks ( How I can export masks divided by classes which exist in my model?
1 Paula DerrengerUltralytics(editado)
@illink7 hi there!
Thank you for sharing your detailed code and describing the issue you're encountering with SAHI and YOLOv8-seg. Let's work through this together to find a solution.
Firstly, could you please confirm that you are using the latest versions of both
torchandultralytics? You can upgrade them using the following commands:pip install --upgrade torch ultralyticsNext, let's ensure that the issue isn't related to the specific environment or versions. If you haven't already, please try running your code in a fresh environment with the latest versions of all necessary libraries.
Regarding your code, it looks well-structured, but there are a few areas we can check and potentially improve:
- Model Initialization: Ensure that the model path and image path are correctly set.
- Prediction Results: Verify that the
result.object_prediction_listcontains the expected mask data.
Here's a slightly modified version of your code with additional checks and comments:
from sahi.predict import get_sliced_prediction
from sahi import AutoDetectionModel
from PIL import Image
import os
from ultralytics import YOLO
import torch
import numpy as np

# Set the path to the image and model
IMAGE_PATH = r"PATH_TO_IMAGE"
MODEL_PATH = r"PATH_TO_MODEL"

# Upload an image
image = Image.open(IMAGE_PATH)

# Initialize the model
detection_model = AutoDetectionModel.from_pretrained(
    model_type='ultralytics',
    model_path=MODEL_PATH,
    confidence_threshold=0.25,
    device="cuda" if torch.cuda.is_available() else "cpu"
)

# Performing predictions with slicing the image into 512x512 parts
result = get_sliced_prediction(
    image,
    detection_model,
    slice_height=512,
    slice_width=512,
    overlap_height_ratio=0.2,
    overlap_width_ratio=0.2
)

# Check if masks are present in the predictions
if not result.object_prediction_list:
    print("No predictions found. Please check your model and input image.")
else:
    print(f"Found {len(result.object_prediction_list)} predictions.")

# Saving the results
output_dir = 'output_vs'
os.makedirs(output_dir, exist_ok=True)
result.export_visuals(export_dir=output_dir, file_name='segmented_image.png')

# Initialize the dictionary for merged masks by class
combined_masks_by_class = {}

# Export masks and combine them by class
for prediction in result.object_prediction_list:
    mask = prediction.mask
    category_name = prediction.category.name
    if mask is not None:
        mask_array = mask.bool_mask
        # Scale the mask to the size of the original image
        mask_image = Image.fromarray((mask_array.astype(np.uint8) * 255))
        mask_resized = mask_image.resize((image.width, image.height), resample=Image.NEAREST)
        mask_resized_np = np.array(mask_resized)

        # Add a mask to the appropriate class in the dictionary
        if category_name not in combined_masks_by_class:
            combined_masks_by_class[category_name] = np.zeros((image.height, image.width), dtype=np.uint8)
        combined_masks_by_class[category_name] = np.maximum(combined_masks_by_class[category_name], mask_resized_np)

# Store merged masks by class
for category_name, combined_mask in combined_masks_by_class.items():
    combined_mask_image = Image.fromarray(combined_mask)
    combined_mask_image.save(os.path.join(output_dir, f'combined_mask_{category_name}.png'))

print(f"Results saved in {output_dir}")
Please ensure that the paths to your image and model are correct. Additionally, the
result.object_prediction_listshould contain the mask data if the model is correctly configured and the image contains detectable objects.If the issue persists, could you provide more details or a minimum reproducible example? This will help us better understand the problem and provide a more accurate solution. You can refer to our guide on creating a minimum reproducible example here: Minimum Reproducible Example.
Looking forward to your response! 😊
- Paula DerrengerUltralytics(editado)
@illink7 hi there! Thanks for reaching out and providing a detailed description of your issue along with the code snippet. Let's work through this together to get your segmentation results with SAHI and YOLOv8-seg.
Firstly, let's ensure a few things:
-
Reproducible Example: Your code looks comprehensive, but to help us reproduce the issue accurately, could you please confirm that you are using the latest versions of
torch,ultralytics, andsahi? You can update them using:pip install -U torch ultralytics sahi -
Model and Environment: Verify that your model path and image path are correctly set and accessible. Also, ensure that your environment is correctly set up to use the necessary libraries.
-
Code Review: Your code for performing sliced inference and exporting masks looks good. However, let's make sure that the masks are being correctly processed and saved. Here’s a slightly modified version of your code to ensure that the masks are correctly handled:
from sahi.predict import get_sliced_prediction from sahi import AutoDetectionModel from PIL import Image import os import numpy as np # Set the path to the image and model IMAGE_PATH = r"PATH_TO_IMAGE" MODEL_PATH = r"PATH_TO_MODEL" # Upload an image image = Image.open(IMAGE_PATH) # Initialize the model detection_model = AutoDetectionModel.from_pretrained( model_type='ultralytics', model_path=MODEL_PATH, confidence_threshold=0.25, device="cpu" # or 'cuda:0' ) # Performing predictions with slicing the image into 512x512 parts result = get_sliced_prediction( image, detection_model, slice_height=512, slice_width=512, overlap_height_ratio=0.2, overlap_width_ratio=0.2 ) # Saving the results output_dir = 'output_vs' os.makedirs(output_dir, exist_ok=True) result.export_visuals(export_dir=output_dir, file_name='segmented_image.png') # Initialize the dictionary for merged masks by class combined_masks_by_class = {} # Export masks and combine them by class for prediction in result.object_prediction_list: mask = prediction.mask category_name = prediction.category.name if mask is not None: mask_array = mask.bool_mask # Scale the mask to the size of the original image mask_image = Image.fromarray((mask_array.astype(np.uint8) * 255)) mask_resized = mask_image.resize((image.width, image.height), resample=Image.NEAREST) mask_resized_np = np.array(mask_resized) # Add a mask to the appropriate class in the dictionary if category_name not in combined_masks_by_class: combined_masks_by_class[category_name] = np.zeros((image.height, image.width), dtype=np.uint8) combined_masks_by_class[category_name] = np.maximum(combined_masks_by_class[category_name], mask_resized_np) # Store merged masks by class for category_name, combined_mask in combined_masks_by_class.items(): combined_mask_image = Image.fromarray(combined_mask) combined_mask_image.save(os.path.join(output_dir, f'combined_mask_{category_name}.png')) print(f"Results saved in {output_dir}") -
Debugging: If the issue persists, please check the following:
- Ensure that the
maskattribute inprediction.maskis notNone. - Verify that the
mask.bool_maskis correctly processed and resized.
- Ensure that the
If you continue to face issues, please provide any error messages or additional details that could help us diagnose the problem further.
For more detailed guidance, you can refer to our SAHI Tiled Inference Guide.
Let us know how it goes! 😊
-
Hi, I did this but there is no result so yeah result exist but there is only image with bboxes and labels but without masks( Could you help me with peace of code or some recommendations how I can do this in another way?
- Paula DerrengerUltralytics(editado)
Hi there! 😊
Thank you for providing the details. It sounds like you're encountering an issue where the masks are not being generated during sliced inference with SAHI and YOLOv8-seg. Let's troubleshoot this together.
First, please ensure that you are using the latest versions of
torch,ultralytics, andsahi. You can update them using:pip install -U torch ultralytics sahiNext, let's verify that your code is correctly set up to handle masks. Here’s a refined version of your code with additional checks to ensure that masks are processed correctly:
from sahi.predict import get_sliced_prediction
from sahi import AutoDetectionModel
from PIL import Image
import os
import numpy as np
import torch

# Set the path to the image and model
IMAGE_PATH = r"PATH_TO_IMAGE"
MODEL_PATH = r"PATH_TO_MODEL"

# Upload an image
image = Image.open(IMAGE_PATH)

# Initialize the model
detection_model = AutoDetectionModel.from_pretrained(
    model_type='ultralytics',
    model_path=MODEL_PATH,
    confidence_threshold=0.25,
    device="cuda" if torch.cuda.is_available() else "cpu"
)

# Performing predictions with slicing the image into 512x512 parts
result = get_sliced_prediction(
    image,
    detection_model,
    slice_height=512,
    slice_width=512,
    overlap_height_ratio=0.2,
    overlap_width_ratio=0.2
)

# Check if masks are present in the predictions
if not result.object_prediction_list:
    print("No predictions found. Please check your model and input image.")
else:
    print(f"Found {len(result.object_prediction_list)} predictions.")

# Saving the results
output_dir = 'output_vs'
os.makedirs(output_dir, exist_ok=True)
result.export_visuals(export_dir=output_dir, file_name='segmented_image.png')

# Initialize the dictionary for merged masks by class
combined_masks_by_class = {}

# Export masks and combine them by class
for prediction in result.object_prediction_list:
    mask = prediction.mask
    category_name = prediction.category.name
    if mask is not None:
        mask_array = mask.bool_mask
        # Scale the mask to the size of the original image
        mask_image = Image.fromarray((mask_array.astype(np.uint8) * 255))
        mask_resized = mask_image.resize((image.width, image.height), resample=Image.NEAREST)
        mask_resized_np = np.array(mask_resized)

        # Add a mask to the appropriate class in the dictionary
        if category_name not in combined_masks_by_class:
            combined_masks_by_class[category_name] = np.zeros((image.height, image.width), dtype=np.uint8)
        combined_masks_by_class[category_name] = np.maximum(combined_masks_by_class[category_name], mask_resized_np)

# Store merged masks by class
for category_name, combined_mask in combined_masks_by_class.items():
    combined_mask_image = Image.fromarray(combined_mask)
    combined_mask_image.save(os.path.join(output_dir, f'combined_mask_{category_name}.png'))

print(f"Results saved in {output_dir}")
Key Points to Check:
- Model Path and Image Path: Ensure that the paths to your model and image are correct.
- Prediction Results: Verify that
result.object_prediction_listcontains predictions with masks. - Mask Processing: Ensure that the mask processing logic correctly handles and resizes the masks.
If the issue persists, please provide a minimum reproducible example as outlined in our Minimum Reproducible Example Guide. This will help us investigate the issue more effectively.
Feel free to reach out if you have any further questions or need additional assistance. We're here to help! 🚀
from sahi.predict import get_sliced_prediction
from sahi import AutoDetectionModel
from PIL import Image
import os
import numpy as np

# Встановлюємо шлях до зображення
IMAGE_PATH = r"D:\Illia\YOLO_test\weights_v2_multiModel\img4test\img_139_shift.png"

# Встановлюємо шлях до моделі
MODEL_PATH = r"D:\Illia\YOLO_test\weights_v2_multiModel\best.pt"

# Upload an image
image = Image.open(IMAGE_PATH)

# Initialize the model
detection_model = AutoDetectionModel.from_pretrained(
    model_type='yolov8',
    model_path=MODEL_PATH,
    confidence_threshold=0.25,
    device="cuda" # if torch.cuda.is_available() else "cpu"
)

# Performing predictions with slicing the image into 512x512 parts
result = get_sliced_prediction(
    image,
    detection_model,
    slice_height=512,
    slice_width=512,
    overlap_height_ratio=0.2,
    overlap_width_ratio=0.2
)

# Check if masks are present in the predictions
if not result.object_prediction_list:
    print("No predictions found. Please check your model and input image.")
else:
    print(f"Found {len(result.object_prediction_list)} predictions.")

# Saving the results
output_dir = 'output_vs2'
os.makedirs(output_dir, exist_ok=True)
result.export_visuals(export_dir=output_dir, file_name='segmented_image.png')

# Initialize the dictionary for merged masks by class
combined_masks_by_class = {}

# Export masks and combine them by class
for prediction in result.object_prediction_list:
    mask = prediction.mask
    category_name = prediction.category.name
    if mask is not None:
        mask_array = mask.bool_mask
        # Scale the mask to the size of the original image
        mask_image = Image.fromarray((mask_array.astype(np.uint8) * 255))
        mask_resized = mask_image.resize((image.width, image.height), resample=Image.NEAREST)
        mask_resized_np = np.array(mask_resized)

        # Add a mask to the appropriate class in the dictionary
        if category_name not in combined_masks_by_class:
            combined_masks_by_class[category_name] = np.zeros((image.height, image.width), dtype=np.uint8)
        combined_masks_by_class[category_name] = np.maximum(combined_masks_by_class[category_name], mask_resized_np)

# Store merged masks by class
for category_name, combined_mask in combined_masks_by_class.items():
    combined_mask_image = Image.fromarray(combined_mask)
    combined_mask_image.save(os.path.join(output_dir, f'combined_mask_{category_name}.png'))

print(f"Results saved in {output_dir}")
Result: Performing prediction on 60 slices. Found 33 predictions. Results saved in output_vs2 But still just image without masks, only bboxes and labels I double-checked model and images but still noresult Maybe that is a bug
- Paula DerrengerUltralytics(editado)
Hi @illink7,
Thank you for sharing your detailed code and the issue you're encountering. Let's work through this together to resolve the problem with the masks not appearing in your results.
Steps to Troubleshoot and Resolve
-
Verify Library Versions: Ensure you are using the latest versions of
torch,ultralytics, andsahi. You can update them using:pip install -U torch ultralytics sahi -
Check Model and Image Paths: Ensure that the paths to your model and image are correct and accessible.
-
Debugging the Mask Generation:
- Ensure that the
maskattribute inprediction.maskis notNone. - Verify that the
mask.bool_maskis correctly processed and resized.
- Ensure that the
Here’s a slightly modified version of your code with additional checks:
from sahi.predict import get_sliced_prediction
from sahi import AutoDetectionModel
from PIL import Image
import os
import numpy as np
import torch

# Set the path to the image and model
IMAGE_PATH = r"D:\Illia\YOLO_test\weights_v2_multiModel\img4test\img_139_shift.png"
MODEL_PATH = r"D:\Illia\YOLO_test\weights_v2_multiModel\best.pt"

# Upload an image
image = Image.open(IMAGE_PATH)

# Initialize the model
detection_model = AutoDetectionModel.from_pretrained(
    model_type='ultralytics',
    model_path=MODEL_PATH,
    confidence_threshold=0.25,
    device="cuda" if torch.cuda.is_available() else "cpu"
)

# Performing predictions with slicing the image into 512x512 parts
result = get_sliced_prediction(
    image,
    detection_model,
    slice_height=512,
    slice_width=512,
    overlap_height_ratio=0.2,
    overlap_width_ratio=0.2
)

# Check if masks are present in the predictions
if not result.object_prediction_list:
    print("No predictions found. Please check your model and input image.")
else:
    print(f"Found {len(result.object_prediction_list)} predictions.")

# Saving the results
output_dir = 'output_vs2'
os.makedirs(output_dir, exist_ok=True)
result.export_visuals(export_dir=output_dir, file_name='segmented_image.png')

# Initialize the dictionary for merged masks by class
combined_masks_by_class = {}

# Export masks and combine them by class
for prediction in result.object_prediction_list:
    mask = prediction.mask
    category_name = prediction.category.name
    if mask is not None:
        mask_array = mask.bool_mask
        # Scale the mask to the size of the original image
        mask_image = Image.fromarray((mask_array.astype(np.uint8) * 255))
        mask_resized = mask_image.resize((image.width, image.height), resample=Image.NEAREST)
        mask_resized_np = np.array(mask_resized)

        # Add a mask to the appropriate class in the dictionary
        if category_name not in combined_masks_by_class:
            combined_masks_by_class[category_name] = np.zeros((image.height, image.width), dtype=np.uint8)
        combined_masks_by_class[category_name] = np.maximum(combined_masks_by_class[category_name], mask_resized_np)

# Store merged masks by class
for category_name, combined_mask in combined_masks_by_class.items():
    combined_mask_image = Image.fromarray(combined_mask)
    combined_mask_image.save(os.path.join(output_dir, f'combined_mask_{category_name}.png'))

print(f"Results saved in {output_dir}")
Additional Recommendations:
- Check the Model Output: Ensure that your model is indeed capable of generating masks. You can test this by running standard inference without slicing to verify mask generation.
- Review SAHI Documentation: For more detailed guidance, refer to the SAHI Tiled Inference Guide.
If the issue persists, please provide a minimum reproducible example as outlined in our Minimum Reproducible Example Guide. This will help us investigate the issue more effectively.
Feel free to reach out if you have any further questions or need additional assistance. We're here to help! 😊
-
Hi. I checked all above mentioned Here is MRE Bug description: I wrote a code which can export the detected mask of the objects and divide them into existing classes. However, something unexpectable happened and I still don't have a desirable result. Segmentation masks disappeared:))). The most strange thing when I run this code on my laptop - it works correctly, but when I shared this code to my friend or even tried to run on my PC - it didn't export masks I cloned the environments and in both situations environment was Python 3.12 here is the link on image - https://www.princeton.edu/sites/default/files/styles/1x_full_2x_half_crop/public/images/2022/02/KOA_Nassau_2697x1517.jpg?itok=Bg2K7j7J Code
from sahi.predict import get_sliced_prediction
from sahi import AutoDetectionModel
from PIL import Image
import os
import numpy as np
import torch
import torchvision
# Set the path to the image and model
IMAGE_PATH = r"D:\Illia\dog.jpg"
MODEL_PATH = "yolov8n-seg.pt"

# Upload an image
image = Image.open(IMAGE_PATH)

# Initialize the model
detection_model = AutoDetectionModel.from_pretrained(
    model_type='yolov8',
    model_path=MODEL_PATH,
    confidence_threshold=0.25,
    device="cuda" if torch.cuda.is_available() else "cpu"
)

# Performing predictions with slicing the image into 512x512 parts
result = get_sliced_prediction(
    image,
    detection_model,
    slice_height=1024,
    slice_width=1024,
    overlap_height_ratio=0.2,
    overlap_width_ratio=0.2
)

# Check if masks are present in the predictions
if not result.object_prediction_list:
    print("No predictions found. Please check your model and input image.")
else:
    print(f"Found {len(result.object_prediction_list)} predictions.")

# Saving the results
output_dir = 'output_vs2'
os.makedirs(output_dir, exist_ok=True)
result.export_visuals(export_dir=output_dir, file_name='segmented_image.png')

# Initialize the dictionary for merged masks by class
combined_masks_by_class = {}

# Export masks and combine them by class
for prediction in result.object_prediction_list:
    mask = prediction.mask
    category_name = prediction.category.name
    if mask is not None:
        mask_array = mask.bool_mask
        # Scale the mask to the size of the original image
        mask_image = Image.fromarray((mask_array.astype(np.uint8) * 255))
        mask_resized = mask_image.resize((image.width, image.height), resample=Image.NEAREST)
        mask_resized_np = np.array(mask_resized)

        # Add a mask to the appropriate class in the dictionary
        if category_name not in combined_masks_by_class:
            combined_masks_by_class[category_name] = np.zeros((image.height, image.width), dtype=np.uint8)
        combined_masks_by_class[category_name] = np.maximum(combined_masks_by_class[category_name], mask_resized_np)

# Store merged masks by class
for category_name, combined_mask in combined_masks_by_class.items():
    combined_mask_image = Image.fromarray(combined_mask)
    combined_mask_image.save(os.path.join(output_dir, f'combined_mask_{category_name}.png'))

print(f"Results saved in {output_dir}")
I wish we can solve this together
- Paula DerrengerUltralytics(editado)
Hi @illink7,
Thank you for providing a detailed description and the minimum reproducible example (MRE). Let's work together to resolve the issue with the segmentation masks not appearing in your results.
Steps to Troubleshoot and Resolve
-
Verify Library Versions: Ensure you are using the latest versions of
torch,ultralytics, andsahi. You can update them using:pip install -U torch ultralytics sahi -
Environment Consistency: Since the code works on your laptop but not on other machines, ensure that all environments are consistent. Verify that the same versions of Python and all dependencies are installed.
-
Debugging the Mask Generation:
- Ensure that the
maskattribute inprediction.maskis notNone. - Verify that the
mask.bool_maskis correctly processed and resized.
- Ensure that the
Here’s a slightly modified version of your code with additional checks:
from sahi.predict import get_sliced_prediction
from sahi import AutoDetectionModel
from PIL import Image
import os
import numpy as np
import torch

# Set the path to the image and model
IMAGE_PATH = r"D:\Illia\YOLO_test\weights_v2_multiModel\img4test\img_139_shift.png"
MODEL_PATH = r"D:\Illia\YOLO_test\weights_v2_multiModel\best.pt"

# Upload an image
image = Image.open(IMAGE_PATH)

# Initialize the model
detection_model = AutoDetectionModel.from_pretrained(
    model_type='ultralytics',
    model_path=MODEL_PATH,
    confidence_threshold=0.25,
    device="cuda" if torch.cuda.is_available() else "cpu"
)

# Performing predictions with slicing the image into 512x512 parts
result = get_sliced_prediction(
    image,
    detection_model,
    slice_height=512,
    slice_width=512,
    overlap_height_ratio=0.2,
    overlap_width_ratio=0.2
)

# Check if masks are present in the predictions
if not result.object_prediction_list:
    print("No predictions found. Please check your model and input image.")
else:
    print(f"Found {len(result.object_prediction_list)} predictions.")

# Saving the results
output_dir = 'output_vs2'
os.makedirs(output_dir, exist_ok=True)
result.export_visuals(export_dir=output_dir, file_name='segmented_image.png')

# Initialize the dictionary for merged masks by class
combined_masks_by_class = {}

# Export masks and combine them by class
for prediction in result.object_prediction_list:
    mask = prediction.mask
    category_name = prediction.category.name
    if mask is not None:
        mask_array = mask.bool_mask
        # Scale the mask to the size of the original image
        mask_image = Image.fromarray((mask_array.astype(np.uint8) * 255))
        mask_resized = mask_image.resize((image.width, image.height), resample=Image.NEAREST)
        mask_resized_np = np.array(mask_resized)

        # Add a mask to the appropriate class in the dictionary
        if category_name not in combined_masks_by_class:
            combined_masks_by_class[category_name] = np.zeros((image.height, image.width), dtype=np.uint8)
        combined_masks_by_class[category_name] = np.maximum(combined_masks_by_class[category_name], mask_resized_np)

# Store merged masks by class
for category_name, combined_mask in combined_masks_by_class.items():
    combined_mask_image = Image.fromarray(combined_mask)
    combined_mask_image.save(os.path.join(output_dir, f'combined_mask_{category_name}.png'))

print(f"Results saved in {output_dir}")
Additional Recommendations:
- Check the Model Output: Ensure that your model is indeed capable of generating masks. You can test this by running standard inference without slicing to verify mask generation.
- Review SAHI Documentation: For more detailed guidance, refer to the SAHI Tiled Inference Guide.
If the issue persists, please provide any error messages or additional details that could help us diagnose the problem further.
Feel free to reach out if you have any further questions or need additional assistance. We're here to help! 😊
-
Thank you for help, but again there is no masks Could you provide me maybe another solution And try as I mentioned above with open model and image IMAGE_PATH = r"D:\Illia\dog.jpg" here is the link on image - https://www.princeton.edu/sites/default/files/styles/1x_full_2x_half_crop/public/images/2022/02/KOA_Nassau_2697x1517.jpg?itok=Bg2K7j7J MODEL_PATH = "yolov8n-seg.pt"
- Paula DerrengerUltralytics(editado)
Hi @illink7,
Thank you for your patience and for providing the detailed information. Let's work through this together to resolve the issue with the segmentation masks not appearing in your results.
Steps to Troubleshoot and Resolve
-
Verify Library Versions: Ensure you are using the latest versions of
torch,ultralytics, andsahi. You can update them using:pip install -U torch ultralytics sahi -
Environment Consistency: Since the code works on your laptop but not on other machines, ensure that all environments are consistent. Verify that the same versions of Python and all dependencies are installed.
-
Debugging the Mask Generation:
- Ensure that the
maskattribute inprediction.maskis notNone. - Verify that the
mask.bool_maskis correctly processed and resized.
- Ensure that the
Here’s a slightly modified version of your code with additional checks:
from sahi.predict import get_sliced_prediction
from sahi import AutoDetectionModel
from PIL import Image
import os
import numpy as np
import torch

# Set the path to the image and model
IMAGE_PATH = r"D:\Illia\dog.jpg"
MODEL_PATH = "yolov8n-seg.pt"

# Upload an image
image = Image.open(IMAGE_PATH)

# Initialize the model
detection_model = AutoDetectionModel.from_pretrained(
    model_type='ultralytics',
    model_path=MODEL_PATH,
    confidence_threshold=0.25,
    device="cuda" if torch.cuda.is_available() else "cpu"
)

# Performing predictions with slicing the image into 1024x1024 parts
result = get_sliced_prediction(
    image,
    detection_model,
    slice_height=1024,
    slice_width=1024,
    overlap_height_ratio=0.2,
    overlap_width_ratio=0.2
)

# Check if masks are present in the predictions
if not result.object_prediction_list:
    print("No predictions found. Please check your model and input image.")
else:
    print(f"Found {len(result.object_prediction_list)} predictions.")

# Saving the results
output_dir = 'output_vs2'
os.makedirs(output_dir, exist_ok=True)
result.export_visuals(export_dir=output_dir, file_name='segmented_image.png')

# Initialize the dictionary for merged masks by class
combined_masks_by_class = {}

# Export masks and combine them by class
for prediction in result.object_prediction_list:
    mask = prediction.mask
    category_name = prediction.category.name
    if mask is not None:
        mask_array = mask.bool_mask
        # Scale the mask to the size of the original image
        mask_image = Image.fromarray((mask_array.astype(np.uint8) * 255))
        mask_resized = mask_image.resize((image.width, image.height), resample=Image.NEAREST)
        mask_resized_np = np.array(mask_resized)

        # Add a mask to the appropriate class in the dictionary
        if category_name not in combined_masks_by_class:
            combined_masks_by_class[category_name] = np.zeros((image.height, image.width), dtype=np.uint8)
        combined_masks_by_class[category_name] = np.maximum(combined_masks_by_class[category_name], mask_resized_np)

# Store merged masks by class
for category_name, combined_mask in combined_masks_by_class.items():
    combined_mask_image = Image.fromarray(combined_mask)
    combined_mask_image.save(os.path.join(output_dir, f'combined_mask_{category_name}.png'))

print(f"Results saved in {output_dir}")
Additional Recommendations:
- Check the Model Output: Ensure that your model is indeed capable of generating masks. You can test this by running standard inference without slicing to verify mask generation.
- Review SAHI Documentation: For more detailed guidance, refer to the SAHI Tiled Inference Guide.
If the issue persists, please provide any error messages or additional details that could help us diagnose the problem further.
Feel free to reach out if you have any further questions or need additional assistance. We're here to help! 😊
-
pinnintipraneethkumar
Hi, @illink7 can you please check the sahi version, i have the same problem i fixed this by updating the sahi library.
Rohan-Python
@pinnintipraneethkumar Do you know how to disable bounding boxes on segmented images?
mxxxbbbb
When I use Sahi, the inference speed is normal in a single main thread, but when I load Sahi into one of multiple threads, it causes the inference speed to be much slower. What is the reason for this
1 Glenn JocherUltralytics
Hello! It sounds like you're experiencing a slowdown when running SAHI in a multi-threaded environment. This can often happen due to the increased overhead of managing multiple threads, especially if the threads are competing for limited computational resources like CPU or GPU.
Here are a couple of suggestions to potentially improve the performance:
-
Ensure Adequate Resources: Make sure that your system has enough resources (CPU/GPU) to handle multiple threads efficiently. If each thread is performing intensive computations, you might need more powerful hardware or fewer concurrent threads.
-
Optimize Thread Management: Try to manage the number of threads based on the workload and the hardware capabilities. Sometimes, reducing the number of threads can actually improve overall performance.
-
Profile Your Application: Use profiling tools to understand where the bottlenecks are. This can provide insights into whether the issue is due to thread management, I/O operations, or something else.
If you continue to experience issues, consider providing more details about your setup, such as the hardware specifications and the specific code implementation, so we can help you better. 🚀
-
I have loaded many deep learning models in one thread across multiple threads, among which sahi is one. When testing with a single main thread, the speed is not a problem, but with multiple threads, the speed is very slow
def pre_sahi(self,img_all):
    resize_img = self.resize_long_image(img_all,640)
    t1 = time.time()
    slice_image_result = slice_image(
        image=resize_img,
        slice_height=640,
        slice_width=640,
        overlap_height_ratio=0.2,
        overlap_width_ratio=0.2,
        auto_slice_resolution=True,
    )

    result = get_sliced_prediction(
        resize_img,
        slice_image_result,
        self.model_sahi,
    )
    box = []
    t2 = time.time()
    print("time:",t2-t1)
This is my call to this class's function in a certain thread, and the model is actually loaded by the constructor
- Glenn JocherUltralytics
Hello! It sounds like you're encountering a common issue when using multiple threads for inference, especially when each thread is loading a deep learning model like SAHI. This slowdown can occur due to several reasons:
-
Resource Contention: Each thread may be competing for limited computational resources (CPU/GPU). This is particularly significant if each model in the threads is substantial in size and computational demand.
-
Global Interpreter Lock (GIL) in Python: If you're using Python, the GIL can become a bottleneck in multi-threaded applications, as it allows only one thread to execute Python bytecode at a time. This can severely limit performance when using CPU-bound tasks.
-
I/O Bottlenecks: If your application involves reading from or writing to disk, such as loading models or accessing data, I/O operations can become a bottleneck when scaled across multiple threads.
To mitigate these issues, consider the following:
- Use multiprocessing instead of multithreading: This can help bypass the GIL and better utilize multiple cores.
- Optimize resource allocation: Ensure that each thread or process has enough resources to perform its tasks efficiently.
- Load models once: If possible, load your models once and share them across threads, rather than loading them separately in each thread.
For more detailed guidance, you might find our documentation on using YOLOv8 with SAHI helpful: Using YOLOv8 with SAHI for Sliced Inference. This guide provides insights into efficiently managing resources and optimizing inference tasks.
-
How I can combine SAHI with segmentation model for aerial images, could you provide me some details please
1- Paula DerrengerUltralytics(editado)
Certainly! To use SAHI with a segmentation model for aerial images, you can follow these steps to integrate and run sliced inference, which is particularly useful for large images, like those taken from aerial perspectives.
-
Install SAHI and Ultralytics:
pip install -U ultralytics sahi -
Import Necessary Modules:
from sahi.predict import get_sliced_prediction from sahi import AutoDetectionModel -
Download and Set Up Your Model: Assuming you have a trained segmentation model, ensure it's compatible with SAHI. You can convert YOLO models to work with SAHI quite easily.
-
Perform Sliced Inference: Here’s how to perform sliced inference on an aerial image:
# Assuming 'model_path' is the path to your trained model detection_model = AutoDetectionModel.from_pretrained( model_type='ultralytics', model_path=model_path, confidence_threshold=0.3, device="cpu", ) # Perform sliced prediction result = get_sliced_prediction( image="path/to/aerial_image.jpg", detection_model=detection_model, slice_height=256, slice_width=256, overlap_height_ratio=0.2, overlap_width_ratio=0.2 ) -
Visualize Results: You can visualize or further process the detection results as needed.
This approach helps handle large aerial images by dividing them into smaller, manageable slices, running the segmentation, and then combining the results. Let me know if you need more details on any specific part! 🚀
-
I did it, but unfortunately I receive the same result, detection instead segmentation
- Paula DerrengerUltralytics(editado)
Hello! SAHI supports sliced inference for segmentation too, as long as you load a segmentation model and use a recent
sahiversion. If you're not getting masks, check that:- Correct Model: The model loaded is a segmentation model (for example
yolo26n-seg.ptor your own trained-segweights), not a detection model. - Model Type: You load it with
AutoDetectionModel.from_pretrained(model_type="ultralytics", ...). - Versions: Both packages are current (
pip install -U ultralytics sahi). Masks are then available asprediction.maskon each item inresult.object_prediction_list.
If you need more specific guidance or a code example, let me know, and I'd be happy to help further! Cheers! 🚀
- Correct Model: The model loaded is a segmentation model (for example
Okay, I'll provide my code and maybe we solve this together
from sahi import AutoDetectionModel
detection_model = AutoDetectionModel.from_pretrained( model_type='yolov8', model_path=r"D:\best.pt", confidence_threshold=0.7, device="cuda:0", # or 'cuda:0' )
result = get_sliced_prediction( r"D:\img_0_shift.png", detection_model, slice_height=600, slice_width=600, overlap_height_ratio=0.2, overlap_width_ratio=0.2 )
result.export_visuals(export_dir="demo_data/") Image("demo_data/prediction_visual.png")
My best.pt is definitely segmentation model, but instead of doing this it does detection
- Paula DerrengerUltralytics(editado)
Hello! It seems like there's an issue with the setup where you're expecting segmentation results but getting detection results instead. Here's a couple of things you could check:
-
Model Type: Ensure that the model loaded is specifically trained for segmentation tasks. Even though the file might be named aptly, it's crucial to confirm its internals are meant for segmentation.
-
Model Loading: Use
AutoDetectionModel.from_pretrained(model_type="ultralytics", model_path=...), which also loads Ultralytics segmentation models, and make suresahiandultralyticsare up to date. -
Output Handling: Segmentation masks are returned on each prediction as
prediction.mask(for exampleprediction.mask.bool_mask) inresult.object_prediction_list, so check that your code reads them from there.
If none of these checks resolve the issue, consider sharing more details about the model and its training specifics. This will help narrow down the issue! 😊 Keep me posted on your progress!
-
Hi, I've tried a lot to find a solution on the internet, but I haven't found any results. What can you recommend or suggest to me?
recall - my purpose is segment objects from aerial images with my custom model
Yeah, I did it. Here is my code
import os from sahi import AutoDetectionModel from sahi.predict import get_sliced_prediction from PIL import Image
import torchIMAGE_PATH = r"C:\Users\ILLINK\Desktop\img4test\img_10_shift.png"
MODEL_PATH = r"C:\Users\ILLINK\Desktop\img4test\best.pt"
image = Image.open(IMAGE_PATH)
detection_model = AutoDetectionModel.from_pretrained( model_type='yolov8', model_path=MODEL_PATH, confidence_threshold=0.25, device="cuda" if torch.cuda.is_available() else "cpu" )
result = get_sliced_prediction( image, detection_model, slice_height=512, slice_width=512, overlap_height_ratio=0.2, overlap_width_ratio=0.2 )
output_dir = 'output' os.makedirs(output_dir, exist_ok=True) result.export_visuals(export_dir=output_dir, file_name='segmented_image.png')
print(f"Результати збережено в {output_dir}")
How I can get rid of bboxes and labels, just pure result, please help me?
- Paula DerrengerUltralytics(editado)
Hello! SAHI exposes the masks on each prediction rather than on the result, so you can skip
export_visualsand save only the masks without boxes or labels. Each item inresult.object_prediction_listhas amaskattribute (prediction.mask.bool_mask) when you use a segmentation model:import os import numpy as np from PIL import Image # 'result' is the PredictionResult from get_sliced_prediction() and 'image' is the PIL image you passed in combined_mask = np.zeros((image.height, image.width), dtype=np.uint8) for prediction in result.object_prediction_list: if prediction.mask is not None: combined_mask = np.maximum(combined_mask, prediction.mask.bool_mask.astype(np.uint8) * 255) Image.fromarray(combined_mask).save(os.path.join(output_dir, "segmentation_mask.png"))This requires a segmentation model loaded with
model_type="ultralytics"and a recentsahiversion. 👍Feel free to reach out if you need further clarification or assistance!
I combined your and my code there
import os from sahi import AutoDetectionModel from sahi.predict import get_sliced_prediction from PIL import Image import numpy as np import torch
IMAGE_PATH = r"C:\Users\ILLINK\Desktop\img4test\img_10_shift.png" MODEL_PATH = r"C:\Users\ILLINK\Desktop\img4test\best.pt"
Load the image
image = Image.open(IMAGE_PATH)
Load the detection model
detection_model = AutoDetectionModel.from_pretrained( model_type='yolov8', model_path=MODEL_PATH, confidence_threshold=0.25, device="cuda" if torch.cuda.is_available() else "cpu" )
Get sliced prediction
result = get_sliced_prediction( image, detection_model, slice_height=512, slice_width=512, overlap_height_ratio=0.2, overlap_width_ratio=0.2 )
Define output directory and create it if it doesn't exist
output_dir = 'output' os.makedirs(output_dir, exist_ok=True)
Simplified approach to handle masks and save them as an image
if hasattr(result, 'masks'): masks = result.masks # Your masks would come from your model's output combined_mask = np.max(masks, axis=0) # Combine masks assuming each is a separate channel
# Convert to a uint8 grayscale image mask_image = Image.fromarray((combined_mask * 255).astype(np.uint8)) mask_image.save(os.path.join(output_dir, 'segmentation_mask.png')) print(f"Результати збережено в {output_dir}")else: print("No masks found in the result. Ensure the model outputs segmentation masks.")
And there is result - No masks found in the result. Ensure the model outputs segmentation masks. Help me solve problem please
- Paula DerrengerUltralytics(editado)
Hello! The error message "No masks found in the result. Ensure the model outputs segmentation masks" means the predictions have no
mask. SAHI does return masks for Ultralytics segmentation models, so check the following:- Model: Confirm
best.ptis a segmentation model (it should load astask=segment), and that you load it withAutoDetectionModel.from_pretrained(model_type="ultralytics", model_path="best.pt", ...). - Versions: Update both packages with
pip install -U ultralytics sahi. Oldersahireleases don't return masks. - Verify: Run the plain Ultralytics model on one image (
YOLO("best.pt")("image.jpg")[0].masks) and then checkprediction.maskon the items ofresult.object_prediction_list.
If you need further assistance, feel free to reach out! Happy coding! 😊
1 - Model: Confirm
But here is AttributeError: 'dict' object has no attribute 'eval'. What you can recommend me please?
- Paula DerrengerUltralytics
Hey there! It looks like you're trying to call
.eval()on a dictionary object, which isn't possible since.eval()is a method typically used on PyTorch models to set them to evaluation mode. If you're trying to set your model to evaluation mode, make sure you're applying.eval()to your model instance, not a dictionary.Here's a quick example to ensure you're using it correctly:
import torch # Assuming 'model' is your loaded model instance model = torch.load('path_to_your_model.pt') model.eval() # Set the model to evaluation modeMake sure that
modelis indeed a PyTorch model object. If you're loading the model and it's returning a dictionary (perhaps with model state and other metadata), you'll need to properly extract the model from that dictionary. Typically, this looks something like:model = torch.load('path_to_your_model.pt') actual_model = model['model'] # Adjust the key according to how your model is saved actual_model.eval()Hope this helps! Let me know if there's anything else you need! 😊
thank you for your reply but unfortunately I didn't get the result I wanted or I don't understand your idea. initially I wanted to use the YOLOv8-seg model to segment aerial images. it worked for me, but along with the result there were labels and bounding boxes that hindered me. maybe there is a way to export the segmented image (data) separately or any other ideas? I am very grateful for your attention and tips, thank you so much
- Paula DerrengerUltralytics(editado)
Hello! Thank you for your feedback and for sharing your experience with the YOLOv8-seg model. It sounds like you're looking to extract just the segmentation masks without the bounding boxes and labels. With SAHI, every item in
result.object_prediction_listcarries its mask, so you can save only the mask data:import os import numpy as np from PIL import Image # 'result' is the PredictionResult from get_sliced_prediction() and 'image' is the PIL image you passed in combined_mask = np.zeros((image.height, image.width), dtype=np.uint8) for prediction in result.object_prediction_list: if prediction.mask is not None: combined_mask = np.maximum(combined_mask, prediction.mask.bool_mask.astype(np.uint8) * 255) Image.fromarray(combined_mask).save(os.path.join(output_dir, "segmentation_mask.png"))This works with segmentation models loaded via
AutoDetectionModel.from_pretrained(model_type="ultralytics", ...). If you need more specific guidance, please let me know more about your model and setup! 😊 Thank you so much
- Paula DerrengerUltralytics(editado)
Hello! Thanks for reaching out. 🌟
If you're looking to use YOLOv8-seg for segmentation and want to export the segmented images without bounding boxes and labels, you can read the masks from the SAHI result:
import os

import numpy as np
from PIL import Image

# 'result' is the PredictionResult from get_sliced_prediction() and 'image' is the PIL image you passed in
combined_mask = np.zeros((image.height, image.width), dtype=np.uint8)
for prediction in result.object_prediction_list:
    if prediction.mask is not None:
        combined_mask = np.maximum(combined_mask, prediction.mask.bool_mask.astype(np.uint8) * 255)

Image.fromarray(combined_mask).save(os.path.join(output_dir, "segmentation_mask.png"))
This saves the segmentation masks directly, bypassing any bounding boxes or labels. Hope this helps! Let me know if there's anything else you need. 😊
傅民 王
Thanks for your sharing, I would like to know that if the performance will be a side-effect. Do you have any report to compare the performance with and without SAHI? Thanks!
- Paula DerrengerUltralytics
Yes—SAHI generally trades inference speed for better small-object detection because it runs detection on multiple slices and merges the results. The original SAHI paper, Tables 1–2, compares full-image and sliced inference, reporting gains of up to 6.8 AP points for the evaluated detectors—not YOLO26—and discusses the additional computational cost. (arxiv.org) This guide does not provide a numerical YOLO26 speed comparison. For your application, compare mAP and end-to-end latency on the same images and hardware, including slicing and merging time.
Mz-Han
Hello. When using YOLO26 for instance segmentation, I encountered an issue of insufficient CUDA memory and plan to solve it through slice inference. The current environment is torch==1.13.1+cu116, torchvision==0.14.1+cu116, torchaudio==0.13.1, while installing the latest version of Sahi requires PyTorch 2.4+ as a prerequisite. Is there a version of Sahi that can be installed without upgrading PyTorch? It would be greatly appreciated if you could provide an example of inference visualization. I have installed sahi==0.11.15, but this version cannot output masks
- Glenn JocherUltralytics
@Mz-Han
sahi==0.11.15is too old for Ultralytics segmentation mask support, so gettingmask=Nonethere is expected; mask output was added in newer SAHI releases (see the SAHI maintainer note in obss/sahi discussion #1000) and the current SAHI PyPI page shows the latest version stream. If you’re pinned totorch==1.13.1, you can install/upgrade SAHI without forcing a PyTorch upgrade by avoiding dependency resolution, but to actually run YOLO26-seg + sliced masks you’ll likely need a newer PyTorch/Ultralytics stack—please paste!yolo checks(orultralytics.utils.checks.collect_system_info()) and your full install command here so we can confirm what’s constraining your environment; also restart your notebook kernel after any upgrades. For visualization (without SAHI), this works for YOLO26 segmentation:from ultralytics import YOLO model = YOLO("yolo26n-seg.pt") results = model.predict(source="path/to/image.jpg", imgsz=640, conf=0.25, device=0) results[0].plot(pil=True).save("pred.png")If you do proceed with SAHI, the parameter/visual export pattern is the same as in the SAHI sliced inference guide, but you’ll need a newer SAHI version than
0.11.15to get masks. Hello, thank you for your reply. I have upgraded PyTorch. How can I display only the mask? My image resolution is 3807*3000, with over a thousand small targets. How can I improve the running speed
- Glenn JocherUltralytics
@Mz-Han To visualize/save only the mask, render the pixel-space polygons from
results[0].masks.xy(see theMasksoutputs in Predict mode docs) into a blank image, e.g.:from ultralytics import YOLO import cv2 import numpy as np model = YOLO("yolo26n-seg.pt") img_path = "path/to/image.jpg" img = cv2.imread(img_path) h, w = img.shape[:2] r = model.predict(source=img_path, device=0, imgsz=1280, conf=0.25)[0] mask_img = np.zeros((h, w), dtype=np.uint8) if r.masks is not None: for seg in r.masks.xy: # list of Nx2 polygons in pixel coords cv2.fillPoly(mask_img, [seg.astype(np.int32)], 255) cv2.imwrite("mask.png", mask_img)For speed on 3807×3000 with 1000+ small objects, sliced inference runtime is dominated by slice count, so increase
slice_height/slice_widthand reduce overlap until you stop missing small targets (and if you’re on NVIDIA, exporting to TensorRT can help; if you share!yolo checksplus your current slice settings we can suggest concrete values based on your GPU/CPU).
YWJ-sudo
你好,请问预测时出现预测的锚框的长或宽为0的无效锚框,那么其是否会自动过滤这些无效锚框
- Glenn JocherUltralytics
@YWJ-sudo 一般情况下 Ultralytics 的后处理不会返回宽或高为 0 的检测框;若在 SAHI 切片拼接或导出为 COCO 后仍出现,可在评估前用 SAHI 的
remove_invalid_coco_results进行清理,示例:from sahi.utils.coco import remove_invalid_coco_results from sahi.utils.file import save_json coco_results = remove_invalid_coco_results("coco_results.json") # 过滤无效/越界框 save_json(coco_results, "coco_results_fixed.json")函数示例见SAHI COCO utilities 文档。
Hello author, I am encountering an issue when using SAHI for sliced prediction. When I change the model_path in detection_model to the path of my locally trained weight file (best.pt), it produces an error. However, if I rename best.pt to yolov8n.pt, it can run successfully.What's going on here? How should I quickly use my own weight file?
ERROR:TypeError: ('model_path is not a valid Ultralytics model path: ', SSLError(MaxRetryError('HTTPSConnectionPool(host='api.github.com', port=443): Max retries exceeded with url: /repos/ultralytics/assets/releases/tags/v8.3.0 (Caused by SSLError("Can't connect to HTTPS URL because the SSL module is not available."))')))
Sorry, it's been resolved now. There were just some minor errors.
1- Fatih AkyonUltralytics
@YWJ-sudo I'm glad to hear it's resolved. Feel free to tag me if you have any more SAHI related issues (SAHI author and core maintainer here) 👍🏻
1 How to obtain the COCO format annotation file after batch patch prediction?
如果我有一张16001600的图片,在预处理阶段我先将其切割成4个切片,即每个切片尺寸为400400,并以此训练模型,而当预测时,我在原图上进行预测,且使用sahi切片推理并将切片高宽设置为400,这会不会得到更好的效果
- Fatih AkyonUltralytics
@YWJ-sudo when you provide
coco_dataset_jsonto sahi predict cli or function, it saves results in coco prediction format: cli usage | functional usageOr you can convert each ObjectPrediction object to COCO prediction format by using
object_prediction.to_coco_prediction(image_id=...): https://github.com/obss/sahi/blob/e7109ee3a117d421f64ed383ad4a073b8ff7b000/sahi/prediction.py#L122 - Fatih AkyonUltralytics
@YWJ-sudo based on your second question. If you are cropping images to 400x400, then resize to 640 on training (ultralytics does this by default), then you should use 400 as slice height and width in
sahi, and that's all (sahi ultralytics integration resizes crops to 640 before inference by default).Optionally (I don't suggest this unless you know what you are doing), if you want
sahito crop images to 400, then perform inference without resizing the crops, then you should set image_size in UltralyticsDetectionModel/AutoDetectionModel class as 400.
MasIgor
Hello! Could you please elaborate on how the training would work? Lets say i have 100 images with 24 mpx. what would the steps be? would I label the 24 mpx images and use sahi for training? if yes, how? or would i have to extract 640x640 images on my own from the 24mpx images and do the training as usual? any help is greatly appreciated.
thanks
Tony2408
Hi. I've applied sahi and yolov11 to infer the bbox of small instance. What confuses me is that multiple local regions of some large targets are individually detected as bounding boxes. I would like to ask: Can this situation only be mitigated by adjusting the slice size and confidence threshold? Are there parameters similar to global NMS that can be adjusted?
- Fatih AkyonUltralytics
Hey, SAHI author here 👋🏻
@Tony2408, it means your slices are smaller than your objects. You can slightly increase the slice height and width or you apply Non-Maximum-Merging to combine these predictions that belong to same object.
1 Great work! Thank you for your reply. Increasing the height and width of the slices for the same image has significantly improved the results. However, I'm wondering if this means that when my task requires identifying multi-scale targets in an image, it's difficult for Sahi's inference method to cover all scales?
- Glenn JocherUltralytics
@Tony2408 You've identified an important challenge with tiled inference approaches. When dealing with multi-scale targets, there's indeed a trade-off: larger slices work better for big objects but might be less efficient for small ones, while smaller slices excel at detecting tiny objects but fragment larger ones.
Some approaches to handle multi-scale targets with SAHI:
- Use multiple inference passes with different slice configurations and merge results
- Adjust overlap ratios (higher overlap can help with object fragmentation)
- Customize the Non-Maximum-Merging parameters to better combine fragmented detections
The SAHI library continues to evolve with improvements to handle these scenarios. For particularly challenging multi-scale detection tasks, you might also consider combining SAHI with model ensembling techniques for more robust results.