YOLO12:アテンション中心の物体検出
概要#
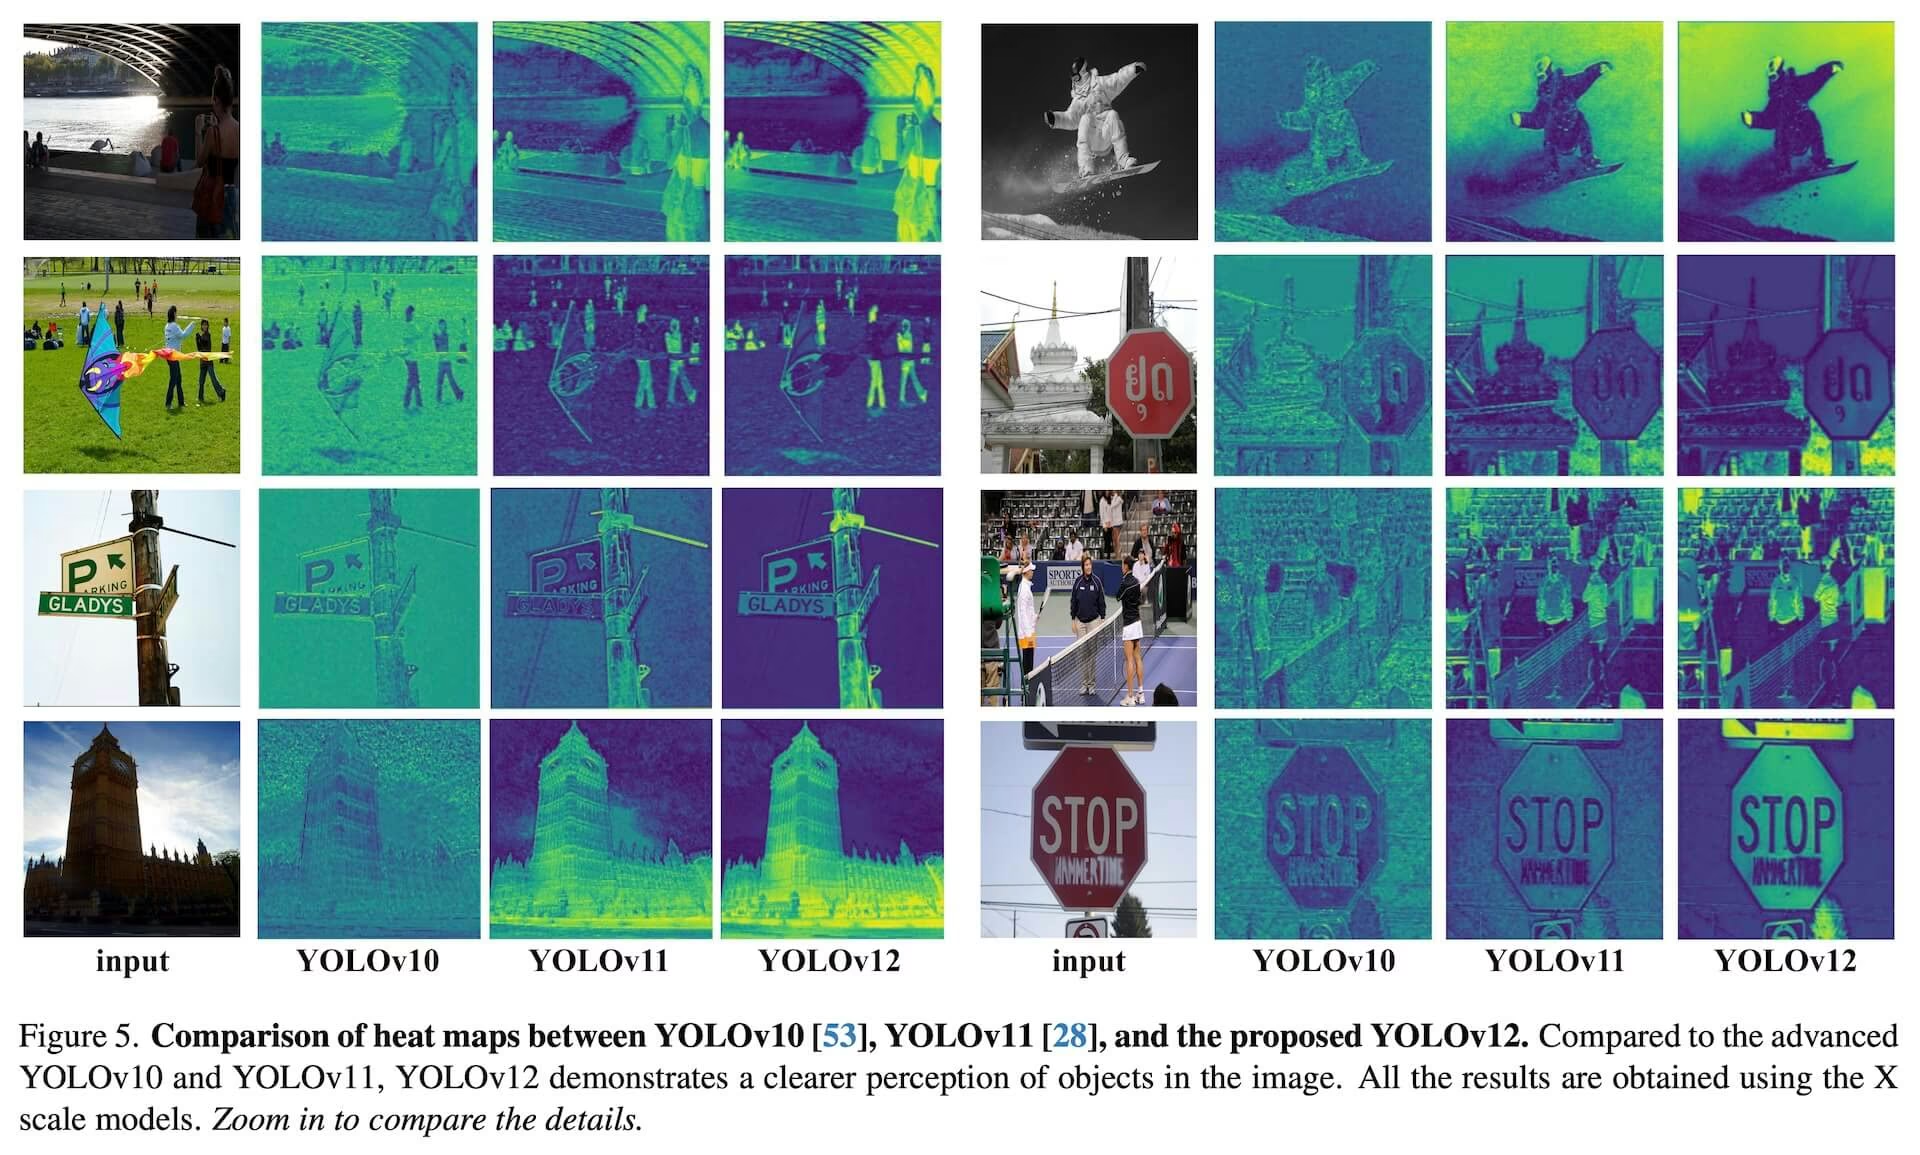
2025年初頭にリリースされたYOLO12は、従来のYOLOモデルで使用されていたCNNベースのアプローチとは異なる、Attention中心のアーキテクチャを導入し、多くのアプリケーションに不可欠なリアルタイム推論速度を維持しています。Attentionメカニズムとネットワーク全体のアーキテクチャを変更することで、高い物体検出精度を実現しています。こうした利点がある一方、YOLO12はコミュニティ主導のリリースであり、Attentionブロックの負荷が大きいため、トレーニングが不安定になったり、メモリ消費量が増加したり、CPUのスループットが低下したりする可能性があります。そのためUltralyticsでは、ほとんどの本番ワークロードにYOLO11またはYOLO26を推奨しています。
YOLO12は主にベンチマークと研究向けにメンテナンスされています。安定したトレーニング、予測可能なメモリ使用量、最適化されたCPU推論が必要な場合は、デプロイにYOLO11またはYOLO26を選択してください。
視聴する: Ultralytics PackageでYOLO12を使って物体検出を行う方法 | YOLO12は高速か低速か?
主な機能#
- Area Attention Mechanism: 大きな受容野を効率的に処理する、新しい自己Attentionの手法です。特徴マップを水平方向または垂直方向に l 個の同じサイズの領域(デフォルトは4)に分割し、複雑な演算を避けながら、大きな有効受容野を維持します。標準的な自己Attentionと比べ、計算コストを大幅に削減します。
- 残差効率的レイヤー集約ネットワーク(R-ELAN):ELANをベースに、特に大規模なアテンション中心モデルの最適化課題に対処するために設計された、改良型の特徴集約モジュールです。R-ELANでは、次の要素を導入しています。
- スケーリングを伴うブロックレベルの残差接続(レイヤースケーリングに類似)。
- ボトルネックに似た構造を作る、再設計された特徴集約手法。
- 最適化されたアテンションアーキテクチャ:YOLO12は、YOLOフレームワークとの効率性と互換性を高めるため、標準的なアテンション機構を効率化しています。具体的には、次の要素が含まれます。
- FlashAttentionを使用して、メモリアクセスのオーバーヘッドを最小限に抑えます。
- モデルをよりシンプルかつ高速にするため、位置エンコーディングを削除します。
- アテンション層とフィードフォワード層の計算バランスをより適切に調整するため、MLP比率を一般的な4から1.2または2に変更します。
- 最適化を改善するため、積み重ねるブロックの深さを減らします。
- 計算効率が高い場合は、畳み込み演算を使用します。
- 位置情報を暗黙的にエンコードするため、「位置パーセプター」と呼ばれる7x7の分離可能な畳み込みをアテンション機構に追加します。
- 包括的なタスクサポート:YOLO12は、物体検出、インスタンスセグメンテーション、画像分類、姿勢推定、方向付き物体検出(OBB)など、さまざまなコンピュータービジョンの主要タスクをサポートしています。
- 効率性の向上:多くの従来モデルと比較して、パラメーター数を抑えながら高い精度を実現し、速度と精度のバランスを改善しています。
- 柔軟なデプロイ:エッジデバイスからクラウドインフラストラクチャまで、さまざまなプラットフォームへのデプロイを想定して設計されています。
サポート対象のタスクとモード#
YOLO12は、さまざまなコンピュータービジョンタスクに対応しています。以下の表は、各タスクのサポート状況と利用可能な操作モード(トレーニング、検証、推論、エクスポート)を示しています。
検出用の重み(yolo12n.pt、yolo12s.pt、yolo12m.pt、yolo12l.pt、yolo12x.pt)のみがultralytics/assetsで公開されています。セグメンテーション、分類、姿勢推定、OBBのアーキテクチャはultralytics/cfg/models/12/で定義されているため、これらのバリエーションは.yaml設定からスクラッチでトレーニングできますが、現在、これらに対応する事前学習済みの.ptファイルはありません。セグメンテーション、姿勢推定、分類、OBBの事前学習済みチェックポイントには、UltralyticsはYOLO11またはYOLO26を推奨しています。
| モデルタイプ | タスク | 事前学習済み重み | トレーニング | 検証 | 推論 | エクスポート |
|---|---|---|---|---|---|---|
| YOLO12 | 物体検出 | ✅ | ✅ | ✅ | ✅ | ✅ |
| YOLO12-seg | セグメンテーション | ❌ | ✅ | ✅ | ✅ | ✅ |
| YOLO12-cls | 分類 | ❌ | ✅ | ✅ | ✅ | ✅ |
| YOLO12-pose | 姿勢推定 | ❌ | ✅ | ✅ | ✅ | ✅ |
| YOLO12-obb | OBB | ❌ | ✅ | ✅ | ✅ | ✅ |
学習済みチェックポイントがあれば、すべてのYOLO12アーキテクチャですべてのモードをサポートします。Pretrained Weights列が示すのは、Ultralyticsが公式の事前学習済み.ptをultralytics/assetsで公開しているかどうかのみです。セグメンテーション、姿勢推定、分類、OBBでは、推論、検証、エクスポートを実行する前に、対応する.yamlから独自のチェックポイントをトレーニングする必要があります。
性能指標#
YOLO12は、すべてのモデルスケールで精度を向上させていますが、従来のYOLOモデルの中で 最速 のものと比べると、速度面でトレードオフがあります。以下に、COCO検証データセットにおける物体検出の定量的な結果を示します。
検出性能(COCO val2017)#
| モデル | サイズ (ピクセル) | mAPval50-95 | 速度 CPU ONNX (ms) | 速度 T4 TensorRT (ms) | パラメーター (M) | FLOPs (B) | 比較 (mAP/速度) |
|---|---|---|---|---|---|---|---|
| YOLO12n | 640 | 40.6 | - | 1.64 | 2.6 | 7.5 | +2.1%/-9%(YOLOv10n比) |
| YOLO12s | 640 | 48.0 | - | 2.61 | 9.3 | 23.3 | +0.1%/+42%(RT-DETRv2比) |
| YOLO12m | 640 | 52.5 | - | 4.86 | 20.2 | 70.7 | +1.0%/-3%(YOLO11m比) |
| YOLO12l | 640 | 53.7 | - | 6.77 | 26.4 | 95.4 | +0.4%/-8%(YOLO11l比) |
| YOLO12x | 640 | 55.2 | - | 11.79 | 59.1 | 208.9 | +0.6%/-4%(YOLO11x比) |
- 推論速度は、TensorRTのFP16精度を使用し、NVIDIA T4 GPUで測定しました。
- 比較結果は、mAPの相対的な改善と速度の変化率を示します(正の値は高速化、負の値は低速化を示します)。比較対象には、公開結果がある場合、YOLOv10、YOLO11、RT-DETRを使用しています。
使用例#
このセクションでは、YOLO12のトレーニングと推論の例を紹介します。
以下の例では、YOLO12の検出モデル(物体検出向け)を取り上げます。その他のサポート対象タスク(セグメンテーション、分類、姿勢推定、方向付き物体検出)については、各タスク専用のドキュメントであるセグメンテーション、分類、姿勢推定、OBBをご覧ください。
事前学習済みの*.ptモデル(PyTorchを使用)と設定用の*.yamlファイルをYOLO()クラスに渡すと、Pythonでモデルインスタンスを作成できます。
from ultralytics import YOLO

# COCOで事前学習済みのYOLO12nモデルを読み込みます
model = YOLO("yolo12n.pt")

# COCO8サンプルデータセットでモデルを100エポック学習する
results = model.train(data="coco8.yaml", epochs=100, imgsz=640)

# 'bus.jpg'画像に対してYOLO12nモデルで推論を実行します
results = model("path/to/bus.jpg")主な改善点#
-
特徴抽出の強化:
- Area Attention: 大きな受容野を効率的に処理し、計算コストを削減します。
- バランスの最適化:アテンションとフィードフォワードネットワークの計算バランスを改善します。
- R-ELAN:R-ELANアーキテクチャを使用して特徴集約を強化します。
-
最適化に関する新機能:
- 残差接続:スケーリングを伴う残差接続を導入し、特に大規模モデルでの学習を安定させます。
- 特徴統合の改善:R-ELAN内で特徴を統合する手法を改良しています。
- FlashAttention:FlashAttentionを導入して、メモリアクセスのオーバーヘッドを削減します。
-
アーキテクチャの効率化:
- パラメーター数の削減:多くの従来モデルと比較して、精度を維持または向上させながらパラメーター数を減らしています。
- アテンションの効率化:位置エンコーディングを使用せず、簡素化されたアテンション実装を採用しています。
- MLP比率の最適化:計算リソースをより効果的に割り当てるため、MLP比率を調整しています。
要件#
UltralyticsのYOLO12実装では、デフォルトでFlashAttentionは必要ありません。ただし、FlashAttentionを任意でコンパイルし、YOLO12で使用できます。FlashAttentionをコンパイルするには、次のいずれかのNVIDIA GPUが必要です。
- Turing GPU(例:T4、Quadro RTXシリーズ)
- Ampere GPU(例:RTX30シリーズ、A30/40/100)
- Ada Lovelace GPU(例:RTX40シリーズ)
- Hopper GPU(例:H100/H200)
引用と謝辞#
研究でYOLO12を使用する場合は、バッファロー大学および中国科学院大学による原著論文を引用してください。
@inproceedings{tian2025yolov12,
  title={YOLOv12: Attention-Centric Real-Time Object Detectors},
  author={Tian, Yunjie and Ye, Qixiang and Doermann, David},
  booktitle={Advances in Neural Information Processing Systems},
  volume={38},
  pages={78433--78457},
  year={2025},
  url={https://proceedings.neurips.cc/paper_files/paper/2025/file/7103444259031cc58051f8c9a4868533-Paper-Conference.pdf}
}

@software{yolo12,
  author = {Tian, Yunjie and Ye, Qixiang and Doermann, David},
  title = {YOLO12: Attention-Centric Real-Time Object Detectors},
  year = {2025},
  url = {https://github.com/sunsmarterjie/yolov12},
  license = {AGPL-3.0}
}YOLO12の論文はNeurIPS 2025の論文集で公開され、arXivでプレプリントも公開されています。
よくある質問#
YOLO12には、速度と精度のバランスを取るための重要な革新がいくつか取り入れられています。Area Attentionメカニズムは大きな受容野を効率的に処理し、標準的な自己Attentionに比べて計算コストを削減します。Residual Efficient Layer Aggregation Networks(R-ELAN)は特徴集約を改善し、Attention中心の大規模モデルにおける最適化の課題に対処します。FlashAttentionの使用や位置エンコーディングの削除を含む最適化されたAttentionアーキテクチャにより、効率がさらに高まります。これらの機能により、YOLO12は多くのアプリケーションに必要なリアルタイム推論速度を維持しながら、高い精度を実現します。
YOLO12は、主要なコンピュータービジョンタスクを幅広くサポートしています。物体検出、インスタンスセグメンテーション、画像分類、姿勢推定、方向付き物体検出(OBB)に対応しています。このため、YOLO12はロボティクスや自動運転から医用画像、産業検査に至るまで、幅広い分野で活用できます。なお、事前学習済みの
.pt重みは現在、検出用のみ公開されています。セグメンテーション、姿勢推定、分類、OBBのアーキテクチャは、スクラッチからトレーニングするための.yaml設定として提供されています。デフォルトでは、UltralyticsのYOLO12実装にFlashAttentionは必要ありません。ただし、メモリアクセスのオーバーヘッドを最小限に抑えるため、FlashAttentionを任意でコンパイルし、YOLO12で使用できます。FlashAttentionのコンパイルには、次のいずれかのNVIDIA GPUが必要です。Turing GPU(例: T4、Quadro RTXシリーズ)、Ampere GPU(例: RTX30シリーズ、A30/40/100)、Ada Lovelace GPU(例: RTX40シリーズ)、またはHopper GPU(例: H100/H200)。これにより、対応ハードウェアを使用する場合にFlashAttentionの利点を活用できます。


コメント69
質問したり、結果を共有したり、ほかの人をサポートしたりできます。
Zixuan-He
I try use the YOLO12-seg, but with update to lastest version (> pip install -U ultralytics) it is still showing (No such file or directory: 'YOLO12n-seg.pt) with code (yolo segment train data=data.yaml model=YOLO12n-seg.pt epochs=200 batch=16 imgsz=640 patience=25 ). theYOLO12n.pt for obj is good. Is the code changed or need other input?
1 Glenn JocherUltralytics
@Zixuan-He Answer:
The YOLO12-seg model requires using its specific configuration file. Trymodel=yolo12-seg.yamlinstead of the.ptfile to initialize training. The segmentation weights are not yet released as pretrained.ptfiles, but you can train from scratch using the YAML configuration. For details, see the YOLO12-seg documentation.2LucasGenoud
Hello, thank you for your answer ! Do you have any date estimation of when the pretrained segmentation models for YOLO12 will be available ? Thanks
- Glenn JocherUltralytics
We don't have an official release date for YOLO12-seg pretrained weights yet, but you can train segmentation models from scratch using the YOLO12-seg.yaml configuration. For updates, please monitor the YOLO12 documentation.
Thank you for your response. Great work :)
- Glenn JocherUltralytics
Thank you for your kind words! We don't have a specific release date for YOLO12-seg pretrained weights yet, but you can monitor the YOLO12 documentation for updates. The team typically announces new model releases there first. For now, training from scratch using the YOLO12-seg.yaml configuration remains the recommended approach.
dolokbutarbutar24
Here are some sample images for the healthy class. I also attached some "results" images, hopefully can give more information so you guys can help me with the project.
Pada Sen, 30 Mar 2026 pukul 15.58 Glenn Jocher @.***> menulis:
Thanks for dropping this question here so the Ultralytics team can see it; for leaf-disease datasets, mAP50-95 usually improves more from cleaner labels, balanced class counts, harder negative samples, and reviewing per-class PR/confusion outputs than from pushing loss weights alone, so I’d next tune weight_decay, momentum, warmup_epochs, lrf, translate, shear, perspective, fliplr, and close_mosaic using the hyperparameter tuning guide https://docs.ultralytics.com/guides/hyperparameter-tuning/ and performance metrics guide https://docs.ultralytics.com/guides/yolo-performance-metrics/. If you can share a few sample images, labels, and training curves here, we can suggest a tighter search space, and it’s also worth benchmarking the same split with YOLO26 https://docs.ultralytics.com/models/yolo26/ since YOLO12 is mainly maintained as a community research model.
— Reply to this email directly, view it on GitHub https://github.com/orgs/ultralytics/discussions/19360?email_source=notifications&email_token=A23CVICPPIXOD6F3LMBB52T4TIZKDA5CNFSNUABIM5UWIORPF5TWS5BNNB2WEL2ENFZWG5LTONUW63SDN5WW2ZLOOQXTCNRTG44DGNRZUZZGKYLTN5XKOY3PNVWWK3TUUVSXMZLOOSWGM33PORSXEX3DNRUWG2Y#discussioncomment-16378369, or unsubscribe https://github.com/notifications/unsubscribe-auth/A23CVIG2PM2BD5335IFZQXT4TIZKDAVCNFSM6AAAAABXS26SR6VHI2DSMVQWIX3LMV43URDJONRXK43TNFXW4Q3PNVWWK3TUHMYTMMZXHAZTMOI . You are receiving this because you commented.Message ID: @.*** com>
- Glenn JocherUltralytics
Thanks, that helps; from those samples I’d next verify that the
healthylabels are fully consistent and that the class counts are not skewed, then please attach a few matching image/label.txtpairs plusresults.csvandconfusion_matrix_normalized.pngso we can check whether this is a data issue rather than a YOLO12 training issue, and if you recently fixed labels please delete anylabels/*.cachefiles before retraining.
I am currently working on a project to detect cassava leaf diseases using YOLOv12. The focus of this research is to perform hyperparameter tuning and also determine the most suitable augmentation configuration to improve model performance. So far, the trained model is still hovering around the 0.5 range for the mAP@50-95 evaluation metric. Here are the hyperparameters I have used for tuning so far: epochs=100, patience=20, imgsz=1024, batch=8, optimizer='auto', lr0=0.00511, box=6.32971, cls=2.87957, dfl=2.12658, mosaic=0.25, scale=0.15, mixup=0.0, copy_paste=0.0, degrees=10.0, hsv_h=0.015, hsv_s=0.7, hsv_v=0.4.
What other strategies can I do to improve my model's performance, especially on the mAP@50-95 evaluation metric? Do you have any suggestions for other hyperparameters that need to be added to this project for tuning? I'm sure your experience and skills can answer that and help me hahaha.
- Glenn JocherUltralytics
Thanks for dropping this question here so the Ultralytics team can see it; for leaf-disease datasets, mAP50-95 usually improves more from cleaner labels, balanced class counts, harder negative samples, and reviewing per-class PR/confusion outputs than from pushing loss weights alone, so I’d next tune
weight_decay,momentum,warmup_epochs,lrf,translate,shear,perspective,fliplr, andclose_mosaicusing the hyperparameter tuning guide and performance metrics guide. If you can share a few sample images, labels, and training curves here, we can suggest a tighter search space, and it’s also worth benchmarking the same split with YOLO26 since YOLO12 is mainly maintained as a community research model.
 Clousy
在5090 32G上使用yolo12l训练模型的时候,数据量大概7万左右,batch_size=24 内存占用在24G左右,为啥速度只有2-3it/s 是哪里设置有问题?下面是训练参数: rain_args = dict( data="data.yaml", epochs=500, imgsz=640, batch=24, device=device, workers=16,
cache=False, amp=True, # --- 减少 CPU 负担 --- mosaic=0.0, # 暂时关掉 Mosaic 看看速度是否飙升 mixup=0.0, # 同上 )- Glenn JocherUltralytics
yolo12l本身是重注意力结构,吞吐会比同尺度的 CNN 系列低不少,所以你看到的2–3 it/s在batch=24下未必异常(折算大约是48–72 img/s);如果你目标是更高训练/CPU 端速度,建议直接换到更稳更快的 Ultralytics YOLO26(YOLO12 更偏研究/基准用途,见 YOLO12 文档)。想确认是不是环境/数据读取瓶颈的话,请把yolo checks输出和完整文本训练日志(含第一轮的进度条行、CUDA:/显卡名、DataLoader相关信息)贴在这里;另外你现在cache=False可能会被磁盘 IO 卡住、workers=16在部分系统上也会造成额外调度开销,建议先用下面这组参数做一次对照测试(同一数据/同一imgsz),看it/s是否明显变化:yolo checks yolo train model=yolo12l.pt data=data.yaml epochs=2 imgsz=640 batch=24 device=0 workers=8 cache=True mosaic=0.0 mixup=0.0
is there any video (tutorial) about how to classify plant disease? i'm confused about how to do it because i need guidance to do classify task
- Glenn JocherUltralytics(編集済み)
Yes—plant disease is just a standard image classification workflow; please follow the Ultralytics YOLO classification guide (and drop any follow-up questions here in this discussion so the Ultralytics team can see them), then try:
from ultralytics import YOLO

# ImageNet-pretrained classifier backbone (recommended starting point)
model = YOLO("yolo26n-cls.pt")

# Your dataset folder should contain train/ and val/ with one subfolder per class
model.train(data="path/to/plant_disease_dataset", epochs=50, imgsz=224)
If you share your dataset folder layout (just the directory tree) and what’s confusing you, I can point you to the exact next step.
asad121101
Hello , this new yolo12 is using what architecture in neck ? pan or fpn ? or some thing else ?
Sourabh0052
while working on classification model using YOLO12-cls and i do not make any .yaml file, just simply provide the data source path then will it work same or not
radadiavasu
I faced a problem that recently I put my model on training with yolo12x but at 98/100 epoch it stopped due to units are over on colab pro but when I start again and expect to start from 98 but it start from 1/100 instead of 98 even in results.csv I couldn't get anything. Why this problem occurs?
deldanr
When resuming a training session started with Yolov12, after the AMP check, the training session downloads a Yolov11 model to continue, which I assume is an error.
Attached is part of the log: YOLOv12l summary: 488 layers, 26,389,875 parameters, 26,389,859 gradients, 89.4 GFLOPs
Transferred 1245/1245 items from pretrained weights Freezing layer 'model.21.dfl.conv.weight' AMP: Running Automatic Mixed Precision (AMP) checks... Downloading https://github.com/ultralytics/assets/releases/download/v8.3.0/yolo11n.pt to 'yolo11n.pt'... <-- Here's the error
pvurda
Has anyone found a low-cost, low-latency way to generate a short semantic scene caption (e.g., “two people loading a van”) on top of YOLO12 detections in real time?