YOLOv9: 物体検出技術の飛躍的な進歩
YOLOv9は、Programmable Gradient Information(PGI)とGeneralized Efficient Layer Aggregation Network(GELAN)を導入し、リアルタイム物体検出を進化させました。リリース時点で、MS COCOデータセットにおいて従来のリアルタイム検出器より効率と精度を向上させました。YOLOv9プロジェクトは独立したオープンソースチームが開発し、UltralyticsのYOLOv5コードベースを基盤としています。
視聴: Ultralytics を使ったカスタムデータによる YOLOv9 のトレーニング | 工業製品パッケージデータセット
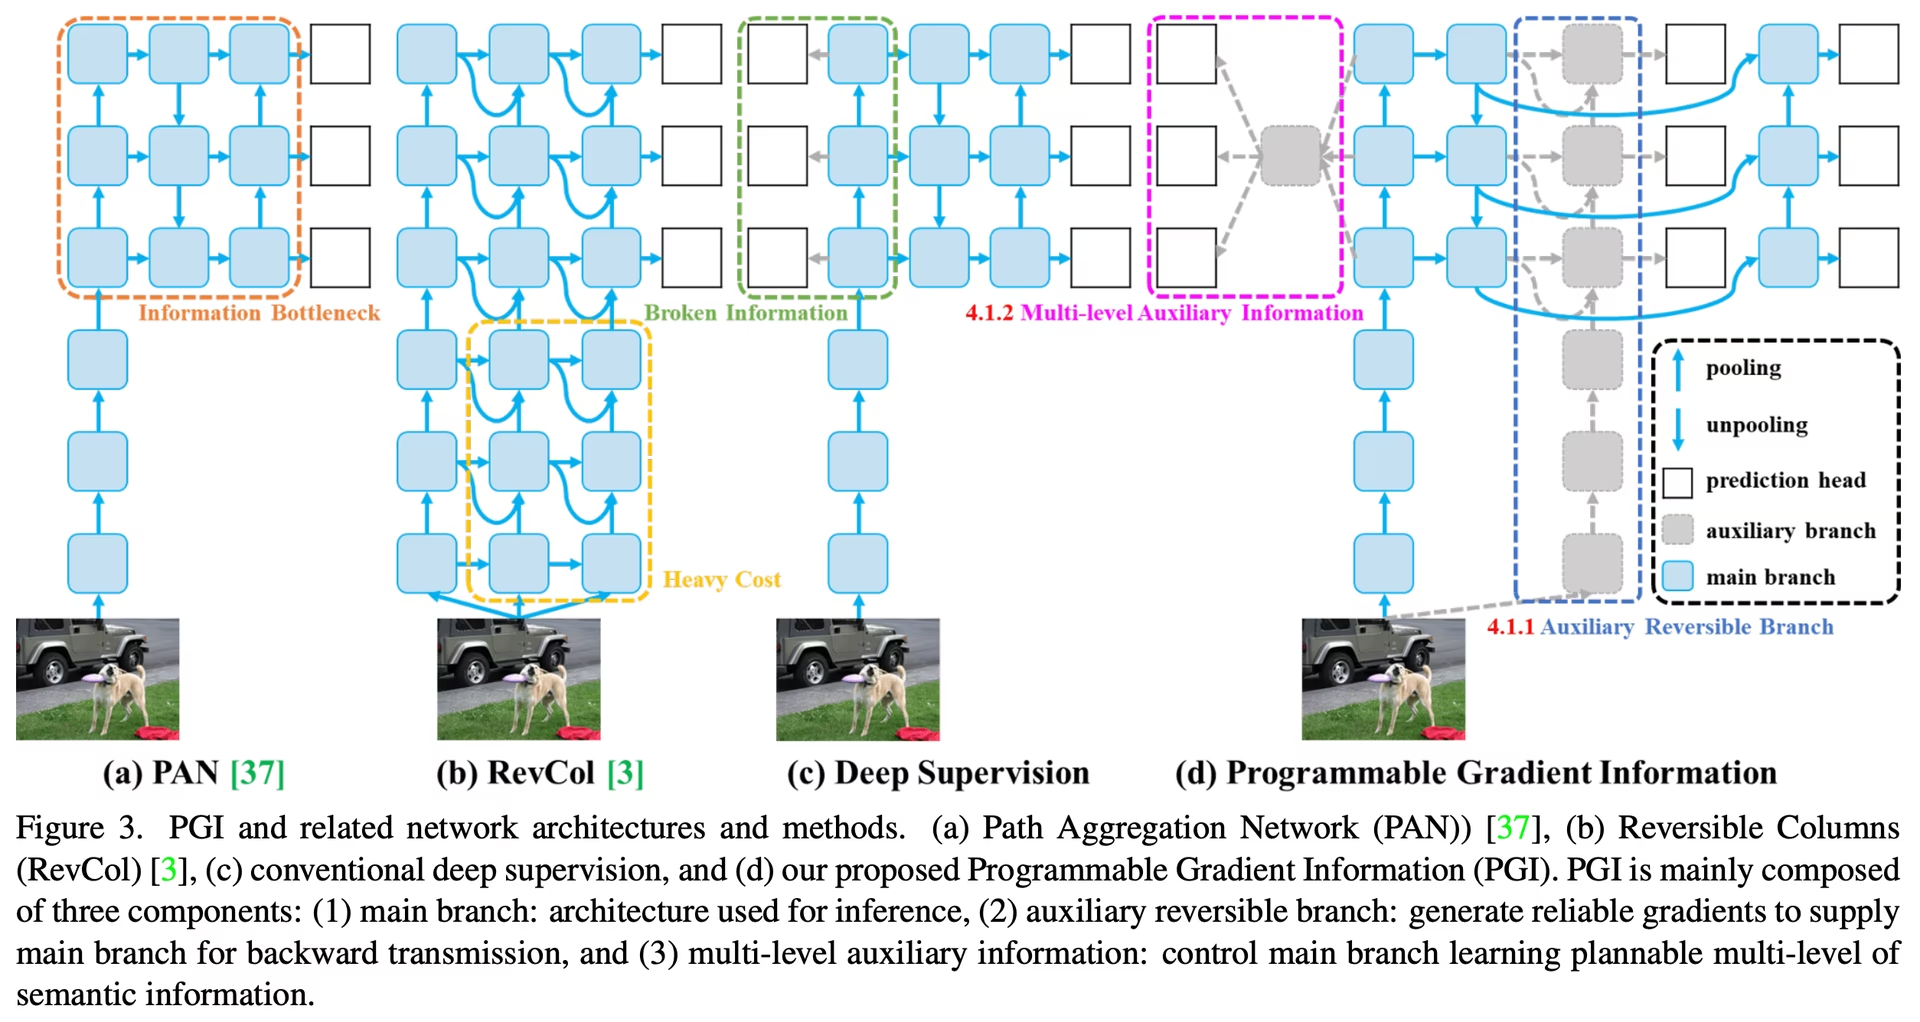
YOLOv9の概要#
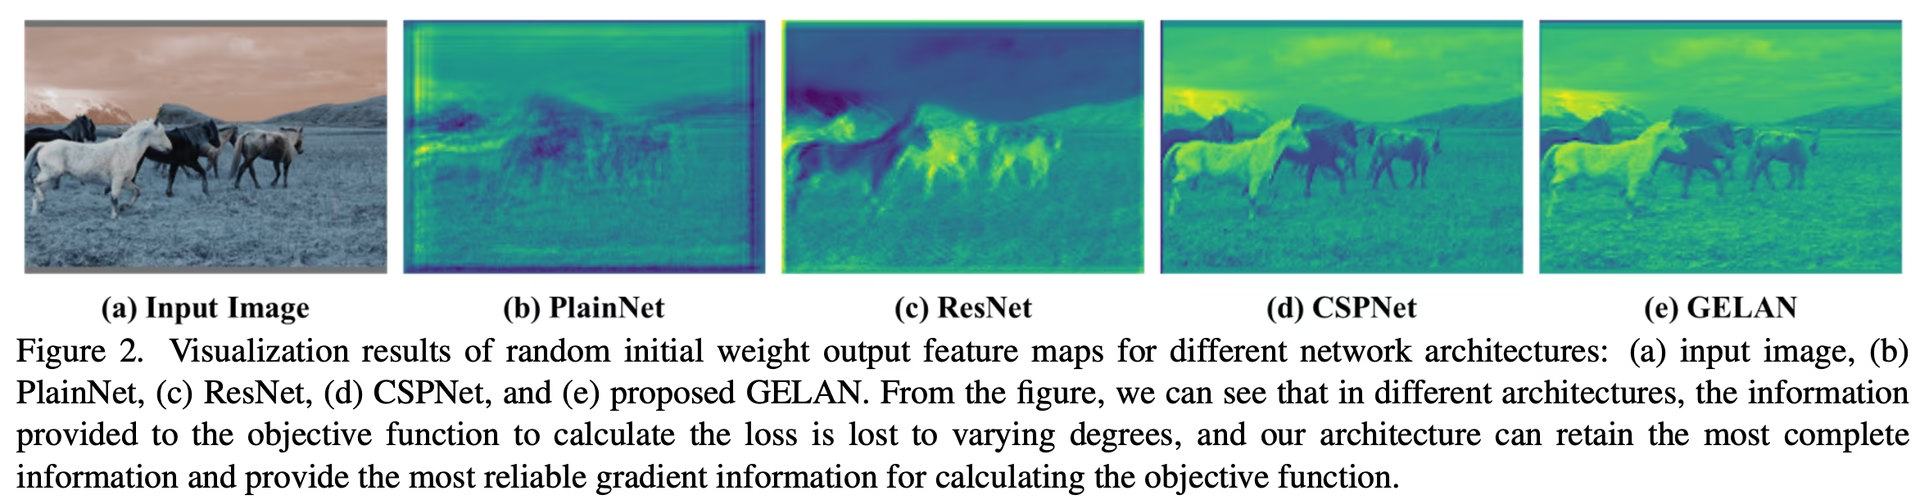
YOLOv9は、深層ニューラルネットワークに固有の情報損失に対処します。PGIとGELANアーキテクチャを組み合わせることで、モデルの学習能力を高め、検出プロセス全体で重要な情報を保持し、精度と効率の両方を向上させます。
YOLOv9の主要なイノベーション#
YOLOv9の設計は、深層ニューラルネットワークにおける情報損失への対処を目的としています。情報ボトルネック原理と可逆関数の使用が設計の中核を成し、YOLOv9が高い効率と精度を維持できるようにします。
情報ボトルネック原理#
情報ボトルネック原理は、ディープラーニングにおける根本的な課題を明らかにします。データがネットワークの層を順次通過するにつれて、情報損失の可能性が高まります。この現象は、次のように数式で表されます。
I(X, X) >= I(X, f_theta(X)) >= I(X, g_phi(f_theta(X)))ここで、Iは相互情報量を表し、fとgは、それぞれパラメーターthetaとphiを持つ変換関数を表します。YOLOv9はプログラマブル勾配情報(PGI)を実装することでこの課題に対処します。PGIはネットワークの深さ全体にわたり重要なデータを保持し、より信頼性の高い勾配生成を実現するため、モデルの収束と性能が向上します。
可逆関数#
可逆関数もYOLOv9の設計の要です。情報を一切失わずに逆関数を求められる関数は可逆であるとされ、次のように表されます。
X = v_zeta(r_psi(X))可逆関数のパラメーターとして、それぞれ psi と zeta を使用します。この特性はディープラーニングアーキテクチャに不可欠です。ネットワーク内の情報の流れを完全に保持できるため、モデルのパラメーターをより正確に更新できます。YOLOv9は、特に深い層での情報劣化のリスクを軽減するために、アーキテクチャ内に可逆関数を組み込んでいます。これにより、物体検出タスクに必要な重要なデータを確実に保持します。
軽量モデルへの影響#
情報損失への対処は、パラメーター数が不足しがちで、順伝播処理中に多くの情報を失いやすい軽量モデルにとって特に重要です。YOLOv9はPGIと可逆関数を活用したアーキテクチャにより、モデルを簡素化しても、正確な物体検出に必要な情報を保持し、効果的に活用できるようにします。
プログラマブル勾配情報(PGI)#
PGIは、情報ボトルネック問題に対処し、ディープネットワークの各層で重要なデータを保持するためにYOLOv9で導入された新しい概念です。これにより信頼性の高い勾配を生成でき、モデルを正確に更新し、検出性能全体を向上させます。
一般化効率的レイヤー集約ネットワーク(GELAN)#
GELANは、YOLOv9のパラメーター利用効率と計算効率を向上させるアーキテクチャです。さまざまな計算ブロックを柔軟に統合できる設計により、速度や精度を損なわず、幅広いアプリケーションにYOLOv9を適応させられます。
YOLOv9のベンチマーク#
UltralyticsのBenchmarkモードを使ったYOLOv9のベンチマークでは、トレーニングと検証を行ったモデルの性能を実環境のシナリオで評価します。このプロセスには次の内容が含まれます。
- 性能評価:モデルの速度と精度を評価します。
- エクスポート形式:さまざまなエクスポート形式でモデルをテストし、必要な基準を満たし、多様な環境で良好に動作することを確認します。
- フレームワークのサポート: Ultralyticsパッケージ内でこれらの評価を実行し、一貫性と信頼性の高い結果を得られます。
ベンチマークを実施することで、管理されたテスト環境だけでなく、実際の用途でもモデルが高い性能を維持できることを確認できます。
視聴: Ultralytics Python パッケージを使って YOLOv9 モデルをベンチマークする方法
MS COCOデータセットでの性能#
リリース時点で、YOLOv9はさまざまなモデルサイズにおいてCOCOデータセットの新たなベンチマークを確立しました。以下の表は、Ultralyticsで利用可能な各YOLOv9モデルの精度、パラメーター数、FLOPsを示しています。
小型の t モデルから大型の e モデルまで、YOLOv9の各バリエーションは、従来バージョンや競合モデルと比べて、パラメーター数と計算量(FLOPs)を維持または削減しながら、精度(mAP)を向上させています。
他のリアルタイム検出器と比べたYOLOv9の主な改善点は次のとおりです。
- 軽量モデル:YOLOv9sは、パラメーター効率と計算負荷の面でYOLO MS-Sを上回り、APを0.4~0.6%向上させています。
- 中型から大型のモデル: YOLOv9mとYOLOv9eは、モデルの複雑さと検出性能のトレードオフを改善し、パラメーター数と計算量を削減しながら精度を高めます。
YOLOv9cはYOLOv7 AFと比べてパラメーター数が42%、計算量が21%少なく、同程度の精度を実現します。YOLOv9eはYOLOv8xと比べてパラメーター数が15%、計算量が25%少なく、APが1.7%向上しています。
これらの結果は、YOLOv9がリアルタイム物体検出やその他のコンピュータービジョンタスクに必要な精度を損なわず、計算効率を向上させたことを示しています。
結論#
2024年2月にリリースされたYOLOv9は、リアルタイム物体検出の効率と精度を向上させました。PGIとGELANによって情報損失に対処し、リリース時点で新たなベンチマークを確立しました。その後、YOLO26やYOLO11などの新しいモデルがさらなる改善を実現していますが、YOLOv9のアーキテクチャ上の革新は今もこの分野に影響を与えています。
使用例#
この例では、YOLOv9の簡単なトレーニングと推論の方法を紹介します。
PyTorchの事前学習済み*.ptモデルと構成*.yamlファイルをYOLO()クラスに渡すことで、Pythonでモデルインスタンスを作成できます。
from ultralytics import YOLO

# YOLOv9cモデルをスクラッチから構築する
model = YOLO("yolov9c.yaml")

# 事前学習済みの重みからYOLOv9cモデルを構築する
model = YOLO("yolov9c.pt")

# モデル情報を表示(任意)
model.info()

# COCO8サンプルデータセットでモデルを100エポック学習する
results = model.train(data="coco8.yaml", epochs=100, imgsz=640)

# 「bus.jpg」画像でYOLOv9cモデルの推論を実行する
results = model("path/to/bus.jpg")サポート対象のタスクとモード#
YOLOv9シリーズには、物体検出とインスタンスセグメンテーションに対応するさまざまなモデルがあり、異なる計算予算と精度要件をカバーしています。
| モデル | ファイル名 | タスク | トレーニング | 検証 | 推論 | エクスポート |
|---|---|---|---|---|---|---|
| YOLOv9 | yolov9t.pt yolov9s.pt yolov9m.pt yolov9c.pt yolov9e.pt | 物体検出 | ✅ | ✅ | ✅ | ✅ |
| YOLOv9-seg | yolov9c-seg.pt yolov9e-seg.pt | インスタンスセグメンテーション | ✅ | ✅ | ✅ | ✅ |
この表は、YOLOv9のモデルバリエーションと、トレーニング、検証、推論、エクスポートの各モードへの対応状況をまとめたものです。
YOLOv9モデルの学習には、同程度のサイズのYOLOv8モデルより多くのリソースが必要で、時間も長くかかります。
引用と謝辞#
リアルタイム物体検出分野への多大な貢献に対し、YOLOv9の著者の皆様に謝意を表します。
@inproceedings{wang2024yolov9,
  title={YOLOv9: Learning What You Want to Learn Using Programmable Gradient Information},
  author={Wang, Chien-Yao and Yeh, I-Hau and Liao, Hong-Yuan Mark},
  booktitle={Computer Vision -- ECCV 2024},
  pages={1--21},
  year={2024},
  organization={Springer Nature Switzerland}
}YOLOv9の公式論文はSpringer ECCV 2024論文集で発表され、arXivにプレプリントが公開されています。著者は研究成果を一般公開しており、コードベースはGitHubからアクセスできます。この分野の発展に貢献し、研究成果を幅広いコミュニティに公開してくださったことに感謝します。
よくある質問#
YOLOv9では、2つの主要な手法として、プログラム可能な勾配情報(PGI)と一般化効率的レイヤー集約ネットワーク(GELAN)が導入されています。これらのイノベーションは、ディープニューラルネットワークにおける情報損失の課題に対処し、高い効率、精度、適応性を実現します。PGIはネットワーク層全体で重要なデータを保持し、GELANはパラメーターの利用効率と計算効率を最適化します。
リリース時点で、YOLOv9は精度と効率の両面で、他の最先端リアルタイム物体検出モデルを上回っていました。COCOデータセットでは、YOLOv9モデルはさまざまなサイズでより高いmAPスコアを達成しながら、計算オーバーヘッドを維持または削減します。たとえば、YOLOv9cはYOLOv7 AFと同程度の精度を、パラメーター数を42%、計算負荷を21%削減して実現します。
PythonとCLIコマンドの両方でYOLOv9モデルを学習できます。Pythonでは、
YOLOクラスを使用してモデルをインスタンス化し、trainメソッドを呼び出します。from ultralytics import YOLO # 事前学習済みの重みからYOLOv9cモデルを構築して学習する model = YOLO("yolov9c.pt") results = model.train(data="coco8.yaml", epochs=100, imgsz=640)CLIで学習する場合は、次を実行します。
yolo train model=yolov9c.yaml data=coco8.yaml epochs=100 imgsz=640学習と推論の使用例について、詳しくご覧ください。
YOLOv9は情報損失を軽減するように設計されており、重要な情報を失いやすい軽量モデルにとって特に有効です。プログラマブル勾配情報(PGI)と可逆関数を統合することで、YOLOv9は重要なデータを確実に保持し、モデルの精度と効率を高めます。そのため、高性能なコンパクトモデルが求められる用途に非常に適しています。詳細については、YOLOv9が軽量モデルに与える影響のセクションをご覧ください。
YOLOv9は、トレーニング、検証、推論、エクスポートのモードで、物体検出とインスタンスセグメンテーションに対応しています。


コメント482
質問したり、結果を共有したり、ほかの人をサポートしたりできます。
vuvanhieu
to load a YOLOv5 model def load_yolov5_model(yolo_model_path): device = torch.device('cuda' if torch.cuda.is_available() else 'cpu') model = torch.hub.load('ultralytics/yolov5', 'custom', path=yolo_model_path, force_reload=True).to(device) return model
How in yolov8, yolov9?
1 Paula DerrengerUltralytics
To load a YOLOv8 or YOLOv9 model, you can use the
YOLOclass from the Ultralytics package. Here's a concise way to do it:from ultralytics import YOLO # Load a YOLOv8 model model_v8 = YOLO("yolov8n.pt") # Load a YOLOv9 model model_v9 = YOLO("yolov9c.pt")For more details, you can refer to the YOLOv9 documentation: https://docs.ultralytics.com/models/yolov9/.
MoAbbasid
@glenn-jocher @pderrenger any idea of when the lightweight models can be used in ultralytics?
1 Glenn JocherUltralytics(編集済み)
Hi there! 😊
Lightweight models are available in Ultralytics. YOLOv9 ships
yolov9t.pt,yolov9s.ptandyolov9m.ptalongsideyolov9c.ptandyolov9e.pt. For new projects we recommend YOLO26, whose smallest modelyolo26n.ptis built for efficiency.To try a lightweight model:
yolo train model=yolo26n.pt data=coco128.yaml epochs=100If you're tinkering with custom lightweight designs, copy an existing model YAML from the Ultralytics repo and adjust its layers or scales. Contributions or insights are welcome.
Happy detecting!
deepanalyticszlc
Very exciting! Is there a schedule for release of lightweight models?
1- Paula DerrengerUltralytics(編集済み)
@deepanalyticszlc hey there! 😊
Lightweight YOLOv9 models are now available:
yolov9t.pt,yolov9s.ptandyolov9m.pt, alongsideyolov9c.ptandyolov9e.pt. For the latest releases, see the Ultralytics GitHub releases.Here's a little snippet on how to load and use YOLOv9 for predictions:
from ultralytics import YOLO

# Load YOLOv9 model
model = YOLO('yolov9t.pt')  # Replace 'yolov9t.pt' with your model file

# Run inference on an image
results = model('path/to/your/image.jpg')

# Display results
results[0].show()
For new projects, we recommend YOLO26, which also comes in small sizes like
yolo26n.pt. ⏰
DolapoSalim(編集済み)
@glenn-jocher Kindly assist with this TypeError: TypeError: ERROR C:\path_to_custom_model/yolov9c.pt appears to be an Ultralytics YOLOv5 model originally trained with https://github.com/ultralytics/yolov5. This model is NOT forwards compatible with YOLOv8 at https://github.com/ultralytics/ultralytics. Recommend fixes are to train a new model using the latest 'ultralytics' package or to run a command with an official Ultralytics model, i.e. 'yolo predict model=yolo11n.pt'
Here is my code:
from ultralytics import YOLO

model = YOLO(path_to_YOLOV9.pt )

results = model.predict(source="IMAGE_SOURCE", show=True, conf=0.10)
Note, I am actually working with a custom trained YOLOV9
- Glenn JocherUltralytics
@DolapoSalim to resolve the YOLOv5/YOLOv9 compatibility error when using custom-trained models, please ensure you're using the latest
ultralytics>=8.2.0package and retrain your YOLOv9 model using the official YOLOv9 configuration files from our documentation. For custom training guidance, see the YOLOv9 Training section in our docs.This error typically occurs when using older model formats - newer versions maintain full backward compatibility when models are trained with current Ultralytics implementations.
1
gusreic
This article claims that Yolov9 is based on Yolov5. The Yolov9 paper claims that v9 is based on Yolov7 which is also not based on 5. Is there any other way that would explain this claim? Otherwise maybe adjust the article.
- Glenn JocherUltralytics
@gusreic yes that's correct. YOLOv9 repo is a fork of my YOLOv5 repo. I know this because I wrote nearly all the files in the YOLOv9 repo myself. Unfortunately the author has failed to make this clear, though he did include a (hidden) acknowledgement at the bottom of the README.
1 Oh, that is really unfortunate, thank you for clearing it up since it is not directly apparent. Do you think that YOLOv9 is based on YOLOv5 only with respect to the structure of the repository or would you say that the architecture of the model itself is also based on the architecture of YOLOv5?
- Glenn JocherUltralytics
@gusreic thank you for your question! YOLOv9's repository structure is indeed based on Ultralytics YOLOv5, while its architecture introduces novel components like Programmable Gradient Information (PGI) and GELAN as described in the YOLOv9 documentation. The model itself represents an independent advancement building on broader YOLO research. We'll clarify this distinction in our article! 😊
ghost
Hello,
Thanks for the great documentation!
Quick question: Is the code licensed under AGPLv3 (Ultralytics) or GPLv3 (Wang, Chien-Yao and Liao, Hong-Yuan Mark Github)?
Thanks!
- Glenn JocherUltralytics
@ProfessorHT the YOLOv9 project codebase, developed by Wang, Chien-Yao and Liao, Hong-Yuan Mark, is available on GitHub and licensed under GPLv3, while Ultralytics models and software use the AGPL-3.0 license.
Thank you for your quick response. So to be sure if I use Yolov9 from this documentation with the ultralytics library i will be under the AGPLv3 license and i should buy a license?
- Glenn JocherUltralytics
Yes, if you use YOLOv9 models from the Ultralytics library, you are under the AGPL-3.0 license and would need an Enterprise License for commercial use, unless you open-source your entire project under AGPL-3.0.
 liuweiqing
Does it support automatic downloading of pretrained weights?
- Glenn JocherUltralytics
@14790897 yes, YOLOv9 supports automatic downloading of pretrained weights when using the
YOLO()class in Python or CLI commands, as long as the specified weights file (e.g.,yolov9c.pt) is available in the Ultralytics repository. You can find more details in the YOLOv9 documentation.
jane7166
Hello. I have retrained the YOLOv9 model, and I would like to deploy it as an API. How should I proceed?
- Glenn JocherUltralytics
@jane7166 to deploy your retrained YOLOv9 model as an API, you can use frameworks like FastAPI or Flask to build an endpoint and load your model using the Ultralytics Python package. Refer to the YOLOv9 documentation for guidance on inference, which can be integrated into your API logic. Let us know if you have further questions!
Gnoot01
I'm getting the following errors despite latest torch and ultralytics installs. Kindly assist
File "C:\Users\.venv\lib\site-packages\ultralytics\engine\model.py", line 547, in predict self.predictor.setup_model(model=self.model, verbose=is_cli) File "C:\Users\.venv\lib\site-packages\ultralytics\engine\predictor.py", line 303, in setup_model self.model = AutoBackend( File "C:\Users\.venv\lib\site-packages\torch\utils\_contextlib.py", line 116, in decorate_context return func(*args, **kwargs) File "C:\Users\.venv\lib\site-packages\ultralytics\nn\autobackend.py", line 145, in __init__ model = model.fuse(verbose=verbose) TypeError: BaseModel.fuse() got an unexpected keyword argument 'verbose'- Glenn JocherUltralytics
@Gnoot01 it seems like there's a compatibility issue with the
fusemethod. Please ensure you're using the latest version of the Ultralytics package. If the issue persists, consider checking for any updates or changes in the repository that might address this. For further assistance, you can explore the YOLOv9 documentation. @glenn-jocher Hi, I'm using the latest ultralytics 8.3.24 and latest torch. However, still facing this issue. Any suggestions?
- Glenn JocherUltralytics
@Gnoot01 i'm sorry you're experiencing this issue. Please ensure your Ultralytics package is up-to-date. If the problem persists, try reinstalling the package or checking for any recent updates in the repository. For more details, you can refer to the YOLOv9 documentation.
foskyblue
I'm having issues with my Yolov9 model exported to tflite. Model was successfully exported to tflite but I cannot get the right bounding boxes. I'm following the steps listed here: https://stackoverflow.com/questions/76381317/yolov8-tflite-python-predictions-and-interpreting-output (for folov8) to make inference for my yolov9 tflite model.
1Step 1: Resizing and Padding (Letterboxing) Step 2: Non-Maximum Suppression (NMS) Step 3: Rescaling Bounding Boxes
However, when I draw the outputed bounding boxes on my image the boxes don't fit the objects in the image correctly.
The code I'm using can be seen below:
from tflite_runtime.interpreter import Interpreter from PIL import Image import numpy as np from glob import glob from typing import Tuple, List interpreter = None input_shape = (320, 576) # Input tensor dimensions (width, height) in pixels input_index = 0 # Input tensor index (from input details in model signature) output_index = 409 model_path = 'model/saved_model.tflite' def load_model(): interpreter = None interpreter = Interpreter(model_path=model_path, num_threads=2) interpreter.allocate_tensors() input_details = interpreter.get_input_details() global input_shape input_shape = tuple(input_details[0]['shape'][1:3]) global input_index input_index = input_details[0]['index'] output_details = interpreter.get_output_details() global output_index output_index = output_details[0]['index'] return interpreter def letter_box(img: np.ndarray, new_shape: Tuple[int, int]) -> np.ndarray: """ Resizes an image to fit within a new shape while maintaining the aspect ratio, and pads the remaining space with a constant value. Args: img (np.ndarray): The input image as a NumPy array. new_shape (Tuple[int, int]): The desired output shape (height, width). Returns: np.ndarray: The resized and padded image. """ shape = img.shape[:2] # Calculate the scaling ratio to fit the image within the new shape r = min(new_shape[0] / shape[0], new_shape[1] / shape[1]) # Calculate the new unpadded dimensions new_unpad = int(round(shape[1] * r)), int(round(shape[0] * r)) # Calculate the padding required on each side dw, dh = new_shape[1] - new_unpad[0], new_shape[0] - new_unpad[1] dw, dh = dw / 2, dh / 2 # Resize the image if necessary if shape[::-1] != new_unpad: img = Image.fromarray(img).resize(new_unpad, Image.Resampling.BILINEAR) img = np.array(img) # Calculate the top, bottom, left, and right padding values top, bottom = int(round(dh - 0.1)), int(round(dh + 0.1)) left, right = int(round(dw - 0.1)), int(round(dw + 0.1)) # Add padding to the image img = np.pad(img, ((top, bottom), (left, right), (0, 0)), mode='constant', constant_values=114) return img def non_max_suppression( prediction: np.ndarray, conf_thres: float = 0.25, iou_thres: float = 0.45, max_det: int = 300, max_wh: int = 7680, ): """ Perform non-maximum suppression (NMS) on a single image prediction. Args: prediction (np.ndarray): A numpy array of shape (1, num_boxes, num_classes + 4 + num_masks) containing the predicted boxes, classes, and masks. conf_thres (float): Confidence threshold for filtering boxes (0.0 to 1.0). iou_thres (float): IoU threshold for NMS (0.0 to 1.0). max_det (int): Maximum number of boxes to keep after NMS. max_wh (int): Maximum box width and height in pixels. Returns: np.ndarray: Array containing kept boxes with format (x1, y1, x2, y2, confidence, class, mask1, mask2, ...). """ # Input validation (can be removed if you're sure of your input) if 0 > conf_thres > 1: raise ValueError(f"Invalid Confidence threshold {conf_thres}, valid values are between 0.0 and 1.0") if 0 > iou_thres > 1: raise ValueError(f"Invalid IoU {iou_thres}, valid values are between 0.0 and 1.0") # Extract dimensions and metadata directly _, _, dims = prediction.shape nc = dims - 4 - prediction.shape[1] # number of classes nm = dims - nc - 4 # number of masks mi = 4 + nc # mask start index # Process the single image in the batch x = prediction[0] # Extract the single image data # Move class scores to last axis and threshold x = np.transpose(x, (1, 0)) xc = x[..., 4:mi].max(axis=-1) > conf_thres x = x[xc] if not x.shape[0]: # No boxes left after confidence thresholding return np.zeros((0, 6 + nm)) # Convert xywh to xyxy directly on the filtered boxes x[..., :4] = xywh2xyxy(x[..., :4]) # Split and process boxes, classes, and masks # pylint: disable=unbalanced-tuple-unpacking box, cls, mask = np.split(x, (4, mi), 1) conf = cls.max(1) j = cls.argmax(1) x = np.concatenate((box, conf[:, None], j[:, None].astype(float), mask), 1) x = x[conf > conf_thres] n = x.shape[0] if not n: # No boxes left after additional confidence thresholding return np.zeros((0, 6 + nm)) # NMS (simplified since we're dealing with a single image) c = x[:, 5:6] * max_wh boxes, scores = x[:, :4] + c, x[:, 4] i = numpy_nms(boxes, scores, iou_thres) i = i[:max_det] return x[i] def numpy_nms(boxes: np.ndarray, scores: np.ndarray, iou_threshold: float = 0.5) -> np.ndarray: """ Perform Non-Maximum Suppression (NMS) on a set of bounding boxes. Args: boxes (np.ndarray): Array of shape (N, 4) representing N bounding boxes. Each box is [x1, y1, x2, y2]. scores (np.ndarray): Array of shape (N,) representing the confidence scores for each box. iou_threshold (float): IoU threshold for suppressing overlapping boxes. Defaults to 0.5. Returns: np.ndarray: Boolean array of shape (N,) indicating which boxes to keep. """ # Sort boxes by score in descending order order = scores.argsort()[::-1] keep = np.ones(len(boxes), dtype=bool) # Calculate IoU matrix ious = box_iou_batch(boxes, boxes) np.fill_diagonal(ious, 0) # Set self-IoU to 0 for i, idx in enumerate(order): if not keep[idx]: continue # Suppress boxes with IoU > threshold overlap = ious[idx] > iou_threshold keep[order[i + 1:]] &= ~overlap[order[i + 1:]] return keep def box_iou_batch(boxes_a: np.ndarray, boxes_b: np.ndarray) -> np.ndarray: """ Calculate the Intersection over Union (IoU) between two sets of bounding boxes. Args: boxes_a (np.ndarray): Array of shape (N, 4) representing N bounding boxes. boxes_b (np.ndarray): Array of shape (M, 4) representing M bounding boxes. Returns: np.ndarray: Array of shape (N, M) containing IoU values for each pair of boxes. Note: Each bounding box is represented as [x1, y1, x2, y2], where (x1, y1) is the top-left corner and (x2, y2) is the bottom-right corner. """ # Calculate areas of boxes_a area_a = (boxes_a[:, 2] - boxes_a[:, 0]) * (boxes_a[:, 3] - boxes_a[:, 1]) # Calculate areas of boxes_b area_b = (boxes_b[:, 2] - boxes_b[:, 0]) * (boxes_b[:, 3] - boxes_b[:, 1]) # Calculate intersection coordinates top_left = np.maximum(boxes_a[:, None, :2], boxes_b[:, :2]) bottom_right = np.minimum(boxes_a[:, None, 2:], boxes_b[:, 2:]) # Calculate intersection area area_inter = np.prod(np.clip(bottom_right - top_left, a_min=0, a_max=None), 2) # Calculate IoU return area_inter / (area_a[:, None] + area_b - area_inter) def xywh2xyxy(box: np.ndarray) -> np.ndarray: """ Convert bounding box coordinates from (x, y, width, height) format to (x1, y1, x2, y2) format where (x1, y1) is the top-left corner and (x2, y2) is the bottom-right corner. Args: x (np.ndarray): The input bounding box coordinates in (x, y, width, height) format. Returns: np.ndarray: The bounding box coordinates in (x1, y1, x2, y2) format. """ if box.shape[-1] != 4: raise ValueError(f"input shape last dimension expected 4 but input shape is {box.shape}") # pylint: disable=unbalanced-tuple-unpacking xy, wh = np.split(box, [2], axis=-1) wh_half = wh / 2 return np.concatenate([xy - wh_half, xy + wh_half], axis=-1) def preprocess_image(pil_image: Image.Image, input_size: Tuple[int, int]) -> np.ndarray: """ Preprocesses an image for inference with a TFLite model. Args: image_path (str): Path to the image file. input_size (Tuple[int, int]): Desired input size (height, width) for the model. Returns: np.ndarray: Preprocessed image as a NumPy array, ready for inference. """ if pil_image.mode != "RGB": pil_image = pil_image.convert("RGB") im = np.asarray(pil_image) im = letter_box(im, new_shape=input_size) im = np.expand_dims(im, axis=0) # goal is to have the format (number of images, size of image, number of channnels) im = im.astype(np.float32) / 255.0 # Normalize to 0.0 - 1.0 return im def postprocess_results(output: np.ndarray, model_input_size: Tuple[int, int], image_original_size: Tuple[int, int]) -> np.ndarray: """ Postprocesses the raw outputs from a TFLite model, including scaling bounding boxes back to the original image size. Args: output (np.ndarray): List of output tensors from the TFLite model. model_input_size (Tuple[int, int]): Desired input size (height, width) for the model. image_original_size (Tuple[int, int]): Original size (height, width) of the input image. Returns: np.ndarray: Postprocessed results with bounding boxes adjusted to original image size. """ predictions = non_max_suppression(output, conf_thres=0.25, iou_thres=0.45, max_det=300, max_wh=1) return scale_boxes(image_original_size, predictions, model_input_size) def scale_boxes(image_original_size: Tuple[int, int], boxes: np.ndarray, model_input_size: Tuple[int, int]): """ Rescales bounding boxes (in the format of xyxy by default) from the shape of the image they were originally specified in (img1_shape) to the shape of a different image (img0_shape). Args: image_original_size (Tuple[int, int]): The shape of the image that the bounding boxes are for, in the format of (height, width). boxes (np.ndarray): the bounding boxes of the objects in the image, in the format of (x1, y1, x2, y2) model_input_size (Tuple[int, int]): the shape of the target image, in the format of (height, width). Returns: np.ndarray: The scaled bounding boxes, in the format of (x1, y1, x2, y2) """ # calculate from img0_shape gain = min(model_input_size[0] / image_original_size[0], model_input_size[1] / image_original_size[1]) # gain = old / new pad = ( round((model_input_size[1] - image_original_size[1] * gain) / 2 - 0.1) / model_input_size[1], round((model_input_size[0] - image_original_size[0] * gain) / 2 - 0.1) / model_input_size[0], ) # wh padding inner_image_scale = ( (1 - pad[0] * 2), (1 - pad[1] * 2), ) # wh scale boxes[..., 0] = (boxes[..., 0] - pad[0]) / inner_image_scale[0] # x padding boxes[..., 1] = (boxes[..., 1] - pad[1]) / inner_image_scale[1] # y padding boxes[..., 2] = (boxes[..., 2] - pad[0]) / inner_image_scale[0] # x padding boxes[..., 3] = (boxes[..., 3] - pad[1]) / inner_image_scale[1] # y padding boxes[..., [0, 2]] = boxes[..., [0, 2]].clip(0, 1) # x1, x2 boxes[..., [1, 3]] = boxes[..., [1, 3]].clip(0, 1) # y1, y2 return boxes def prepare_input(image_pil): # Input image must match input shape (ex: 640x640 pixels) [note: only use BILINEAR here] resized = image_pil.copy().resize(input_shape, resample=Image.Resampling.BILINEAR) # SSD Mobilenet V2 FPNLite take as input pixels between [-1.0, 1.0] expanded = np.expand_dims(np.asarray(resized, dtype=np.float32) * 2. / 255. - 1., axis=0) del resized # Enforce garbage collection sooner than later return expanded def predict(tmp_images_dir): interpreter = load_model() model_predictions = [] for img_path in tmp_images_dir: pil_image = Image.open(img_path) input_data = preprocess_image(pil_image, input_shape) interpreter.set_tensor(input_index, input_data) interpreter.invoke() output_data = interpreter.get_tensor(output_index) preds = postprocess_results(output_data, input_shape, (pil_image.size[1], pil_image.size[0])) model_predictions.append({ 'detection_classes': (preds[:, 5] + 1).tolist(), # Class values are offset by +1.0 'detection_boxes': preds[:, 0:4].tolist(), 'detection_scores': preds[:, 4].tolist(), }) print(model_predictions) images_path = glob('utilities/images/*.JPG') predict(images_path)- Glenn JocherUltralytics
@foskyblue it seems like the issue might be related to the scaling and padding logic when converting bounding boxes. Ensure that the
scale_boxesfunction correctly rescales the boxes to the original image size. For more detailed guidance, please refer to the YOLOv9 documentation: https://docs.ultralytics.com/models/yolov9/. Hi Glen thanks for your response. Unfortunately I find it difficult to correctly scale the bounding boxes from the example script I mentioned above: https://stackoverflow.com/questions/76381317/yolov8-tflite-python-predictions-and-interpreting-output.
How can I implement the YOLOv9 TFLite model with an input ape of [1, 320, 576, 3] and output shape of [1, 19, 3780] in Python?
- Glenn JocherUltralytics
To correctly scale bounding boxes for your YOLOv9 TFLite model, ensure your
scale_boxesfunction accurately adjusts the coordinates based on the original image size and model input size. Verify that padding and scaling calculations align with your preprocessing steps. For further details, please refer to the YOLOv9 documentation.