Ultralytics YOLOによる複数オブジェクト追跡
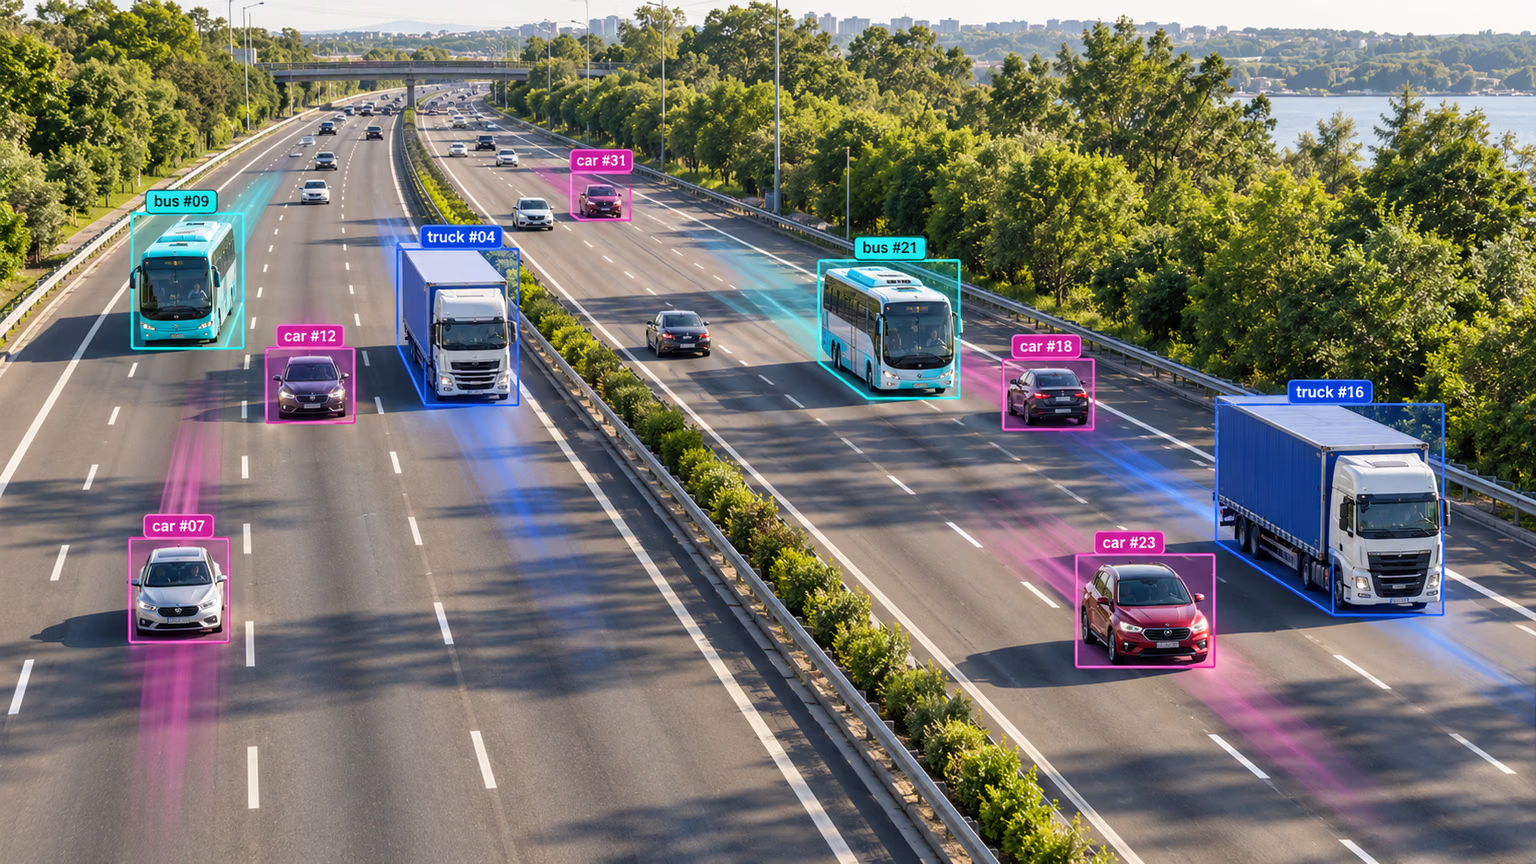
動画分析におけるマルチオブジェクトトラッキングでは、各フレーム内のオブジェクトの位置とクラスを特定し、動画の進行に合わせて検出された各オブジェクトに固有のIDを維持します。監視やセキュリティからリアルタイムのスポーツ分析まで、幅広い用途に活用できます。
追跡機能の今後の対応予定については、未リリースのYOLO27プレビューをご覧ください。
ultralytics 8.4.63以降では、OC-SORT、Deep OC-SORT、FastTracker、TrackTrackをBoT-SORTおよびByteTrackと併せて使用できます。
オブジェクト追跡にUltralytics YOLOを選ぶ理由#
Ultralyticsのトラッカーの出力は標準的な物体検出と一貫性があり、オブジェクトIDが追加されます。これにより、動画ストリーム内のオブジェクトを追跡し、その後の分析を簡単に行えます。物体追跡にUltralytics YOLOを使用する主な理由:
- 効率性:精度を損なわず、動画ストリームをリアルタイムで処理できます。
- 柔軟性: 複数のトラッキングアルゴリズムと構成に対応しています。
- 使いやすさ:シンプルなPython APIとCLIオプションにより、すばやく統合してデプロイできます。
- カスタマイズ性:カスタム学習済みYOLOモデルを簡単に使用でき、特定の分野向けアプリケーションに統合できます。
視聴: Ultralytics YOLO26 でマルチオブジェクトトラッキングを実行する方法 | BoT-SORT と ByteTrack | VisionAI 🚀
実世界での活用例#
| 交通 | 小売 | 養殖 |
|---|---|---|
| 車両追跡 | 人物追跡 | 魚の追跡 |
クイックスタート#
デフォルトのTrackTrackトラッカーを使用して動画の追跡を実行します。tracker引数を変更すると、別のトラッカーに切り替えられます。
from ultralytics import YOLO

model = YOLO("yolo26n.pt")

# デフォルトのトラッカー(TrackTrack)
results = model.track(source="https://youtu.be/LNwODJXcvt4", show=True)

# ByteTrackに切り替え
results = model.track(source="https://youtu.be/LNwODJXcvt4", show=True, tracker="bytetrack.yaml")
動画ストリームでトラッカーを実行するには、YOLO26n、YOLO26n-seg、YOLO26n-pose、YOLO26n-obbなど、トレーニング済みのDetect、Segment、Pose、OBBモデルを使用します。これらのモデルは、Ultralytics PlatformのYOLO26コレクションで利用できます。カスタムモデルは、ローカル環境またはUltralytics Platformのクラウドトレーニングでトレーニングできます。
from ultralytics import YOLO

# 公式モデルまたはカスタムモデルを読み込む
model = YOLO("yolo26n.pt")  # 公式Detectモデルを読み込む
model = YOLO("yolo26n-seg.pt")  # 公式Segmentモデルを読み込む
model = YOLO("yolo26n-pose.pt")  # 公式Poseモデルを読み込む
model = YOLO("path/to/best.pt")  # カスタム学習済みモデルを読み込む

# モデルで追跡を実行する
results = model.track("https://youtu.be/LNwODJXcvt4", show=True)  # デフォルトのトラッカーで追跡
results = model.track("https://youtu.be/LNwODJXcvt4", show=True, tracker="bytetrack.yaml") # ByteTrackを使用対応トラッカー#
Ultralytics YOLOには、6種類のトラッカーが組み込まれています。tracker引数にYAML設定ファイルを渡すと有効になります。
| トラッカー | 設定ファイル | モーションモデル | 外観 / ReID | カメラモーション補正 | オクルージョンへの対応 |
|---|---|---|---|---|---|
| BoT-SORT | botsort.yaml | 線形カルマン | 任意(with_reid) | 設定可能(gmc_method) | トラックバッファ + ReID再割り当て |
| ByteTrack | bytetrack.yaml | 線形カルマン | なし | いいえ | 低信頼度検出を2段階で救済 |
| OC-SORT | ocsort.yaml | 観測中心型カルマン | なし | いいえ | ORU、OCM、OCRによる最終観測からの再更新 |
| Deep OC-SORT | deepocsort.yaml | 観測中心型カルマン | 任意(with_reid) | 設定可能(gmc_method) | OC-SORT + 任意の適応型外観EMA |
| FastTracker | fasttrack.yaml | 線形カルマン + ロールバック | なし | いいえ | カルマンロールバック + オクルージョン時のbbox拡大 |
| TrackTrack | tracktrack.yaml | 線形カルマン(NSA) | 任意(with_reid) | 設定可能(gmc_method) | 複数の手掛かりによる反復的な対応付け + TAI |
どのトラッカーを使えばよいですか?#
次の手順を参考に、最初に使うトラッカーを選んでください。trackerを渡さない場合は、tracktrack.yamlが使用されます。
- 最速でシンプルなベースラインが必要ですか? → ByteTrack(ReIDなし、カメラモーション補正なし、オーバーヘッド最小)。
- 手持ち、ドローン、または移動カメラで撮影した映像ですか? → BoT-SORT(カメラモーション補正と任意のReIDを追加)。
- 非線形な動き(スポーツ、ダンス、急な方向転換)があり、ReIDは不要ですか? → OC-SORT(外観特徴の計算コストなしで、観測中心の補正を実行)。
- 移動カメラによる混雑したシーンで、IDの入れ替わりが主な問題ですか? → Deep OC-SORTまたはTrackTrack(どちらも任意の外観照合に対応し、TrackTrackは複数の手掛かりによる対応付けと重複IDの抑制も追加)。
- リアルタイム処理で部分的な重なりが頻繁に発生し、ReIDに割ける計算予算がありませんか? → FastTracker(カルマンロールバックを備えた、オクルージョンに対応するByteTrackの派生版)。
トラッカーの切り替え#
tracker=にトラッカー設定ファイル名を渡します。それ以外のコードは変更不要です。
from ultralytics import YOLO

model = YOLO("yolo26n.pt")

results = model.track(source="path/to/video.mp4", tracker="bytetrack.yaml")
results = model.track(source="path/to/video.mp4", tracker="ocsort.yaml")
results = model.track(source="path/to/video.mp4", tracker="tracktrack.yaml")設定#
追跡の引数#
トラッキングの設定では、Predictモードと推論引数を共有します。たとえば、conf、iou、showを使用できます。
from ultralytics import YOLO

# 追跡パラメーターを設定してトラッカーを実行する
model = YOLO("yolo26n.pt")
results = model.track(source="https://youtu.be/LNwODJXcvt4", conf=0.1, iou=0.5, show=True)カスタムトラッカー設定#
トラッカーの設定を変更するには、ultralytics/cfg/trackersからトラッカー設定ファイル(例:custom_tracker.yaml)をコピーし、tracker_type以外の設定を変更します。
from ultralytics import YOLO

# モデルを読み込み、カスタム設定ファイルでトラッカーを実行する
model = YOLO("yolo26n.pt")
results = model.track(source="https://youtu.be/LNwODJXcvt4", tracker="custom_tracker.yaml")共通のトラッカー引数#
次のパラメーターは、ほとんどのトラッカーYAMLファイルで共通です。すべての設定ファイルに含まれるわけではありません。
track_high_thresh以上の検出結果は、最初の対応付け段階に進みます。track_low_thresh以上track_high_thresh未満の検出結果は、選択したトラッカーが低信頼度の対応付けに対応している場合、既存のトラックの復旧に利用できますが、新しいトラックの開始には使用されません。track_low_thresh以下の検出結果は無視されます。
| パラメーター | 有効な値または範囲 | 説明 |
|---|---|---|
tracker_type | botsort, bytetrack, ocsort, deepocsort, fasttrack, tracktrack | トラッカーの種類を指定します。 |
track_high_thresh | 0.0-1.0 | 最初の関連付けのしきい値です。検出結果を既存のトラックにどの程度確実に対応付けるかに影響します。 |
track_low_thresh | 0.0-1.0 | 低信頼度の復帰検出に対する下限値です。OC-SORTとDeep OC-SORTでは、use_byte: Trueの場合にのみ低信頼度の復帰検出を使用します。TrackTrackでは、低信頼度の復帰検出をペナルティ付きの関連付け候補プールに含めます。 |
new_track_thresh | 0.0-1.0 | 検出結果が既存のどのトラックにも一致しない場合に、新しいトラックを初期化するためのしきい値です。 |
track_buffer | >=0 | 消失したトラックを削除せずに維持するフレーム数です。値が大きいほど、オクルージョンに対する許容度が高くなります。 |
match_thresh | 0.0-1.0 | トラック照合のしきい値です。値が大きいほど、照合が緩やかになります。 |
fuse_score | True, False | 照合の前に、信頼度スコアとIoU距離を融合するかどうかを指定します。 |
gmc_method | sparseOptFlow, orb, sift, ecc, none | グローバルモーション補償の方式です。カメラの動きを考慮するのに役立ちます。 |
proximity_thresh | 0.0-1.0 | 有効なReID照合に必要な最小IoUです。外観情報を使用する前に、位置が十分近いことを確認します。 |
appearance_thresh | 0.0-1.0 | ReIDに必要な最小正規化外観類似度です。 |
with_reid | True, False | オクルージョンをまたいだ追跡の精度を高めるため、外観ベースの照合を有効にします。BoT-SORT、Deep OC-SORT、TrackTrackでサポートされています。 |
model | autoまたは互換性のあるReIDモデルのパス | ReIDモデルです。autoでは、利用可能な場合はネイティブYOLOバックボーンの特徴を使用し、それ以外の場合はyolo26n-cls.ptにフォールバックします。カスタムエンコーダーには、.ptチェックポイント、または.torchscript、.onnx、.engineなどのエクスポート済みモデルや、OpenVINOモデルディレクトリを指定できます。 |
トラッカー固有の引数#
各アルゴリズムには、共通パラメーターに加えて追加の設定項目があります。説明や調整のヒントについては、以下の各トラッカーのセクションを参照するか、設定ファイルを直接確認してください。
再識別(ReID)の有効化#
オーバーヘッドを最小限に抑えるため、ReIDはデフォルトで無効になっています。トラッカー設定ファイルでwith_reid: Trueを設定すると有効になります。
ReIDモデルのオプション:
model: auto— ネイティブYOLO検出器の特徴を使用するため、オーバーヘッドは最小限です。パフォーマンスへの影響を抑えながらReIDを利用したい場合に適しています。検出器が互換性のある特徴を公開していない場合は、yolo26n-cls.ptにフォールバックします。- カスタムReIDモデル —
model:に、.ptチェックポイント、または.torchscript、.onnx、.engineなどの互換性のあるエクスポート済み埋め込みモデルや、OpenVINOモデルディレクトリを指定します。エクスポート済みモデルはAutoBackend経由で読み込まれ、埋め込みテンソルを直接出力する必要があります。
すべてのモデルサイズ向けに、すぐに使えるONNXエンコーダーが公開されています。model:に以下のいずれかの名前を設定すると、トラッカーの初回実行時にファイルが自動的にダウンロードされます(YOLOの重みを取得する場合と同様です)。手動でエクスポートやダウンロードを行う必要はありません。
# In your tracker config (e.g. tracktrack.yaml)
with_reid: True
model: yolo26n-reid.onnx # downloaded on first use; swap n→s/m/l/x for a larger encoder| モデル | サイズ (ピクセル) | パラメーター (M) | FLOPs (B) |
|---|---|---|---|
| YOLO26n-reid.onnx | 448 | 2.8 | 2.0 |
| YOLO26s-reid.onnx | 448 | 7.5 | 6.6 |
| YOLO26m-reid.onnx | 448 | 12.4 | 20.1 |
| YOLO26l-reid.onnx | 448 | 15.3 | 25.2 |
| YOLO26x-reid.onnx | 448 | 32.7 | 55.9 |
現在利用できるのは、トラッカーの外観ブランチ向けONNX ReIDエンコーダーのみです。ReIDのtrain、val、predictモードと、専用のReIDエクスポート手順は、現在開発中です。
別の分類モデルを使ってパフォーマンスを高めるには、TensorRTなどの高速なバックエンド向けにエクスポートしてください。
from torch import nn

from ultralytics import YOLO

# 分類モデルを読み込みます
model = YOLO("yolo26n-cls.pt")

# 平均プーリング層を追加します
head = model.model.model[-1]
pool = nn.Sequential(nn.AdaptiveAvgPool2d((1, 1)), nn.Flatten(start_dim=1))
pool.f, pool.i = head.f, head.i
model.model.model[-1] = pool

# TensorRTにエクスポートします
model.export(format="engine", quantize=16, dynamic=True, batch=32)
エクスポート後、トラッカー設定でTensorRTモデルのパスを指定します。
トラッカーの詳細#
以下の各セクションでは、トラッカーごとの設計、固有のパラメーター、調整のヒントについて説明します。
視聴: どのオブジェクトトラッカーが優れているか? | 速度、FPS、ID 安定性 | Ultralytics YOLO26 📊
BoT-SORT#
BoT-SORT(Aharon et al., 2022)は、ByteTrackを拡張し、カメラモーション補償とオプションのReIDを追加しています。
- カメラモーション補償(CMC): 各フレームで推定したアフィン変換(デフォルトではスパースオプティカルフロー。ORB / ECCも利用可能)を、IoU照合の前にカルマン状態へ適用します。
- オプションのReID: 外観埋め込みをコスト行列に融合できます。デフォルトでは無効です。有効にするには
with_reid: Trueを設定します。
適した用途: 汎用的な追跡、特にカメラが動く場合に適しています。外見の似た物体が多く、IDの入れ替わりが発生する場合にのみReIDを追加してください。
BoT-SORT固有の引数:
| パラメーター | 有効な値または範囲 | 説明 |
|---|---|---|
gmc_method | sparseOptFlow, orb, sift, ecc, none | カメラモーション補償のバックエンドです。sparseOptFlowがデフォルトです。noneではCMCが無効になります。 |
with_reid | True, False | 外観ベースの照合を有効にします。デフォルトでは無効です。 |
model | autoまたは互換性のあるReIDモデルのパス | autoでは、利用可能な場合はネイティブYOLOの特徴を使用します。カスタムモデルには.ptチェックポイントや互換性のあるエクスポート済みモデルを指定できます。 |
proximity_thresh | 0.0-1.0 | 外観特徴を考慮する前に必要な最小IoUです。 |
appearance_thresh | 0.0-1.0 | ReIDの照合に必要な最小正規化外観類似度です。値を大きくすると、照合が厳格になります。 |
調整のヒント:
- 固定カメラ:
gmc_method: noneを設定すると、1フレームあたり数ミリ秒を節約できます。 - カメラの動きが大きい場合:
sparseOptFlowを維持してください。eccの方が精度は高くなりますが、処理は遅くなります。 - 外見の似た物体が多い場合:
with_reid: Trueを有効にし、appearance_threshを大きくします(例:0.85+)。
ByteTrack#
ByteTrack(Zhang et al., ECCV 2022)は、軽量なベースラインです。線形カルマンフィルターとIoUを用いた2段階の関連付けを行います。
- ステージ1: 高スコアの検出結果をアクティブなトラックに照合します。
- ステージ2: 短時間の部分的なオクルージョンを経たトラックを再取得するため、未照合のトラックを低スコアの検出結果と再度照合します。
外観モデルもカメラモーション補償もありません。
適した用途: 検出器のコストが処理全体の大半を占める固定またはほぼ固定のカメラで、トラッカーのオーバーヘッドを最小限に抑えたい場合に適しています。
ByteTrack固有の引数: 共通のトラッカー引数以外にはありません。
調整のヒント:
- ノイズの多い検出器:
track_low_threshを下げると、第2段階で候補が増えます。 - 再現率の高い検出器:
track_high_threshを上げると、IDの断片化を抑えられます。 - IDが頻繁にちらつく場合:
track_bufferを上げると、一時的に検出されなかったトラックが維持されます。
OC-SORT#
OC-SORT(Cao et al., CVPR 2023)は、SORTを観測中心の方式に拡張したものです。SORTの軽量な設計(外観特徴なし)を維持しながら、3つの補正を追加しています。
- 観測中心の再更新(ORU): 最後の観測から現在の検出結果までの仮想軌跡を再生し、カルマン更新を再実行して、ずれた速度を補正します。
- 観測中心のモメンタム(OCM): 速度の一貫性を考慮した項を用いて、進行方向が誤っている検出結果にペナルティを与えます。
- 観測中心の再取得(OCR): 最後の観測を使い、予測状態ではなく最近消失したトラックと未照合の検出結果を再確認します。
適した用途: ReIDモデルのコストをかけずに、非線形の動きを追跡する場合に適しています。
OC-SORT固有の引数:
| パラメーター | 有効な値または範囲 | 説明 |
|---|---|---|
delta_t | >=1 | OCMで速度方向を計算する際の時間窓(フレーム数)です。値が大きいほど平滑化が強くなります。 |
inertia | 0.0-1.0 | 速度一貫性コストの重みです。値が大きいほど、急な方向転換へのペナルティが強くなります。 |
use_byte | True, False | 低信頼度の検出結果を対象に、ByteTrack方式の第2段階の関連付けを有効にします。 |
調整のヒント:
- 非線形の動き:
inertiaを上げます(例:0.3-0.4)。 - 検出がまばらな場合:
use_byte: Trueを有効にします。 - 長時間のオクルージョン:
track_bufferを上げると、OCRが再関連付けできる消失トラックが増えます。
OBBモデルでは、方向付きボックスの最後の観測履歴が保持されないため、OCRはカルマンフィルターが予測した方向付きボックスを使用します。
Deep OC-SORT#
Deep OC-SORTは、OC-SORTに外観情報とカメラモーション補償を追加したものです。
- 外観照合: コサイン埋め込み距離を重なり具合で制限し、動きのコストと融合します。
- 動的な外観EMA: トラックの埋め込みをEMAで更新します。平滑化係数は検出信頼度に応じて変化します。
- カメラモーション補償: スパースオプティカルフロー、ORB、またはECCを用いて、フレーム間でカルマン状態を変換します。
適した用途: 視覚的には異なるものの位置が近い物体間でIDの入れ替わりが頻発する、混雑したシーンやカメラが動くシーンに適しています。
Deep OC-SORT固有の引数:
| パラメーター | 有効な値または範囲 | 説明 |
|---|---|---|
with_reid | True, False | 外観ベースの照合を有効にします。デフォルトでは無効です。 |
model | autoまたは互換性のあるReIDモデルのパス | autoでは、利用可能な場合はネイティブYOLOの特徴を使用します。カスタムモデルには.ptチェックポイントや互換性のあるエクスポート済みモデルを指定できます。 |
proximity_thresh | 0.0-1.0 | 外観特徴を考慮する前に必要な最小IoUです。 |
appearance_thresh | 0.0-1.0 | ReIDの照合に必要な最小正規化外観類似度です。 |
alpha_fixed_emb | 0.0-1.0 | トラック埋め込みの更新に使う基本EMA係数です。値が大きいほど、古い埋め込みが長く維持されます。 |
gmc_method | sparseOptFlow, orb, sift, ecc, none | グローバルモーション補償の方式です。 |
delta_t | >=1 | OCMで速度方向を計算する際の時間窓(フレーム数)です(OC-SORTから継承)。 |
inertia | 0.0-1.0 | 速度一貫性コストの重みです(OC-SORTから継承)。 |
use_byte | True, False | 低信頼度の検出結果を対象に、ByteTrack方式の第2段階の関連付けを有効にします(OC-SORTから継承)。 |
調整のヒント:
- 混雑時のID入れ替わり:
appearance_threshを上げ(例:0.92-0.95)、alpha_fixed_embも上げると、埋め込みの適応が遅くなります。 - カメラが動く場合:
gmc_method: sparseOptFlowを設定します(Deep OC-SORTではデフォルトでnoneが設定されています)。 - レイテンシを抑える場合: 動きとCMCのみを使うデフォルトの
with_reid: Falseを維持し、IDの入れ替わりが主なエラー要因の場合にのみReIDを有効にします。
FastTracker#
FastTrackerは、外観モデルを使わない、オクルージョン対応のByteTrack派生手法です。
- オクルージョン検出: 他のアクティブなトラックによる被覆率が
occ_cover_threshを超えた場合、そのトラックをオクルージョン状態として判定します。 - オクルージョン時のカルマン状態のロールバック: リングバッファに保存した履歴を使って、カルマン状態をオクルージョン前のフレームに戻します。
- 動きの減衰と探索範囲の拡大: オクルージョン中は速度を減衰させ、予測したbboxを拡大します。
- 初期化時のIoUによる抑制: アクティブなトラックに重なる位置から新しいトラックが生成されるのを防ぎます。
適した用途: 対象同士の重なりが頻繁に発生する(混雑、行列、スポーツなど)、リアルタイムの検出専用パイプラインに適しています。
FastTracker固有の引数:
| パラメーター | 有効な値または範囲 | 説明 |
|---|---|---|
reset_velocity_offset_occ | >=0 | オクルージョン開始時にカルマン速度を復元するための、遡る履歴フレーム数です。 |
reset_pos_offset_occ | >=0 | オクルージョン開始時にカルマン位置を復元するための、遡る履歴フレーム数です。 |
enlarge_bbox_occ | >=1.0 | オクルージョン中に予測bboxへ適用される高さのスケーリングです(幅はXYAHのアスペクト比に応じてスケーリングされます)。 |
dampen_motion_occ | 0.0-1.0 | オクルージョン中の速度乗数です。値を小さくすると、トラックはオクルージョン中に「減速」します。 |
active_occ_to_lost_thresh | >=1 | アクティブなトラックがlostに移行するまでの、連続してオクルージョン状態となる最大フレーム数です。 |
occ_cover_thresh | 0.0-1.0 | オクルージョンを宣言するための、別のアクティブなトラックに覆われたトラック面積の割合です。 |
occ_reappear_window | >=0 | 最近オクルージョン状態になったlostトラックを、優先的に再検出できる状態に保つフレーム数です。 |
init_iou_suppress | 0.0-1.0 | 新しいトラックの初期化を、そのIoUがいずれかのアクティブなトラックとの間でこの値を超える場合に抑制します。無効にするには1.0を設定します。 |
調整のヒント:
- 部分的なオクルージョンが頻繁に発生する場合:
occ_cover_threshを小さくします(例:0.5-0.6)。 - 重なり付近でIDが重複する場合:
init_iou_suppressを小さくします(例:0.5)。 - 長時間のオクルージョン:
occ_reappear_windowとtrack_bufferを同時に大きくします。 - 高速で移動する対象:
dampen_motion_occを大きくします(1.0に近づけます)。探索範囲を広げることで再検出が改善する場合に限り、enlarge_bbox_occを大きくします。
TrackTrack#
TrackTrack(Shim et al., CVPR 2025)はデフォルトのトラッカーです。各トラックの視点から判断し、複数の手掛かりを用いて反復的に関連付けを行います。
- トラック視点ベースの関連付け(TPA): HMIoU、任意のコサインReID距離、信頼度投影距離、コーナー角度距離を組み合わせます。割り当ては、しきい値を緩和しながら反復的に解決されます。
- トラック対応初期化(TAI): 新しいIDが作成される前に、重複するトラックの生成を抑制します。
最適な用途: オクルージョンが頻繁に発生し、IDの重複が問題となる混雑したシーンです。
TrackTrack固有の引数:
| パラメーター | 有効な値または範囲 | 説明 |
|---|---|---|
iou_weight | 0.0-1.0 | ReIDが有効な場合のHMIoU距離の重みです。それ以外の場合はHMIoUがそのまま使用されます。 |
reid_weight | 0.0-1.0 | ReIDが有効な場合のコサインReID距離の重みです。それ以外の場合は無視されます。 |
conf_weight | 0.0-1.0 | 信頼度投影距離の重みです。 |
angle_weight | 0.0-1.0 | コーナー角度距離の重みです。 |
penalty_p | 0.0-1.0 | 信頼度の低い検出に対するコストペナルティです。 |
penalty_q | 0.0-1.0 | セカンダリNMSによって再検出された対象に対するコストペナルティです。 |
reduce_step | 0.0-1.0 | 反復ごとのマッチしきい値の緩和量です。 |
tai_thr | 0.0-1.0 | トラック対応初期化NMSのIoUしきい値です。 |
min_track_len | >=0 | 新しいトラックを確定するまでに必要な最小履歴長です。 |
lost_match_thr | 0.0-1.0 | 緩和されたlost再関連付けパスに適用する、より緩いコストゲートです。無効にするには0を設定します。 |
with_reid | True, False | コサインReIDによる外観マッチングを有効にします(ネイティブのYOLO特徴を使用)。デフォルトでは無効です。 |
model | autoまたは互換性のあるReIDモデルのパス | autoでは、利用可能な場合はネイティブYOLOの特徴を使用します。カスタムモデルには.ptチェックポイントや互換性のあるエクスポート済みモデルを指定できます。 |
gmc_method | sparseOptFlow, orb, sift, ecc, none | グローバルモーション補償の方式です。 |
調整のヒント:
- 混雑した場所の歩行者:
tai_thrを小さくして(例:0.45)、重複するトラックの生成をさらに抑制します。長時間のオクルージョンではtrack_bufferを大きくします。 - カメラが高速に動く場合:
gmc_method: sparseOptFlowを有効にしたままにします。 - 小型または高速の物体:
angle_weightを少し大きくし、min_track_lenを小さくします。 - 必要な場合にのみReIDを有効にします: 推論コストが増加するため、短時間のオクルージョンには、通常、デフォルトの複数手掛かりコストで十分です。
SegmentモデルとPoseモデルでは、TrackTrackは緩いNMSによる検出の再取得をスキップするため、マスクとキーポイントが対応する検出とずれません。
Pythonの例#
視聴: Ultralytics YOLO26でインタラクティブな物体追跡を構築する方法:数分で構築 | Python!
トラックを維持するループ#
以下は、OpenCV(cv2)とYOLO26を使用して、ビデオフレーム上で物体追跡を実行するPythonスクリプトです。このスクリプトでは、必要なパッケージ(opencv-pythonとultralytics)がすでにインストールされていることを前提としています。persist=True引数は、現在の画像またはフレームがシーケンス内の次のフレームであり、現在の画像内で前の画像からのトラックを予測するようトラッカーに指示します。
同じビデオストリームからの連続したフレームをmodel.track()に渡す場合に限り、persist=Trueを使用してください。これにより、トラッカーは以前のフレームの状態を再利用し、時間の経過に伴って一貫したトラックIDを維持できます。以前のトラック状態が引き継がれる可能性があるため、関連のない画像や別のストリームに対してpersist=Trueを使用しないでください。
tracker="botsort.yaml"、tracker="bytetrack.yaml"、tracker="tracktrack.yaml"などのトラッカー設定ファイルを渡して、トラッカーのバックエンドを選択することもできます。
import cv2

from ultralytics import YOLO

# YOLO26モデルを読み込む
model = YOLO("yolo26n.pt")

# ビデオファイルを開く
video_path = "path/to/video.mp4"
cap = cv2.VideoCapture(video_path)

# ビデオフレームをループ処理する
while cap.isOpened():
    # ビデオからフレームを読み込む
    success, frame = cap.read()

    if success:
        # フレーム間でトラックを維持しながら、フレーム上でYOLO26のトラッキングを実行する
        # BoT-SORTトラッカーのバックエンドを使用する
        results = model.track(frame, persist=True, tracker="botsort.yaml")

        # フレーム上に結果を可視化する
        annotated_frame = results[0].plot()

        # 注釈付きフレームを表示する
        cv2.imshow("YOLO26 Tracking", annotated_frame)

        # 'q'が押された場合にループを終了する
        if cv2.waitKey(1) & 0xFF == ord("q"):
            break
    else:
        # ビデオの最後に到達した場合にループを終了する
        break

# ビデオキャプチャオブジェクトを解放し、表示ウィンドウを閉じる
cap.release()
cv2.destroyAllWindows()model(frame)からmodel.track(frame)への変更により、単純な検出ではなくオブジェクトのトラッキングが有効になります。この変更後のスクリプトは、動画の各フレームでトラッカーを実行し、結果を可視化してウィンドウに表示します。「q」キーを押すとループを終了できます。
時間経過に伴うトラックのプロット#
連続するフレーム上でオブジェクトの軌跡を可視化すると、動画内で検出されたオブジェクトの移動パターンや挙動を把握するうえで役立ちます。Ultralytics YOLO26では、これらの軌跡を簡単にプロットできます。
次の例では、YOLO26のトラッキングを使用して、複数の動画フレームにわたる検出オブジェクトの動きをプロットします。スクリプトは動画ファイルを開いてフレームごとに読み込み、YOLOモデルでオブジェクトを識別して追跡します。検出されたバウンディングボックスの中心点を保持して線でつなぐことで、追跡対象の移動経路を描画します。
from collections import defaultdict

import cv2
import numpy as np

from ultralytics import YOLO

# YOLO26モデルを読み込む
model = YOLO("yolo26n.pt")

# ビデオファイルを開く
video_path = "path/to/video.mp4"
cap = cv2.VideoCapture(video_path)

# トラック履歴を保存する
track_history = defaultdict(list)

# ビデオフレームをループ処理する
while cap.isOpened():
    # ビデオからフレームを読み込む
    success, frame = cap.read()

    if success:
        # フレーム間でトラックを維持しながら、フレーム上でYOLO26のトラッキングを実行する
        result = model.track(frame, persist=True)[0]

        # ボックスとトラックIDを取得する
        if result.boxes and result.boxes.is_track:
            boxes = result.boxes.xywh.cpu()
            track_ids = result.boxes.id.int().cpu().tolist()

            # フレーム上に結果を可視化する
            frame = result.plot()

            # トラックをプロットする
            for box, track_id in zip(boxes, track_ids):
                x, y, w, h = box
                track = track_history[track_id]
                track.append((float(x), float(y)))  # 中心点のx座標、y座標
                if len(track) > 30:  # 30フレームにわたって30個のトラックを保持する
                    track.pop(0)

                # トラッキングラインを描画する
                points = np.hstack(track).astype(np.int32).reshape((-1, 1, 2))
                cv2.polylines(frame, [points], isClosed=False, color=(230, 230, 230), thickness=10)

        # 注釈付きフレームを表示する
        cv2.imshow("YOLO26 Tracking", frame)

        # 'q'が押された場合にループを終了する
        if cv2.waitKey(1) & 0xFF == ord("q"):
            break
    else:
        # ビデオの最後に到達した場合にループを終了する
        break

# ビデオキャプチャオブジェクトを解放し、表示ウィンドウを閉じる
cap.release()
cv2.destroyAllWindows()マルチスレッドトラッキング#
マルチスレッドトラッキングでは、複数の動画ストリームでオブジェクト追跡を同時に実行できます。複数の監視カメラからの入力など、複数の動画入力を扱う場合に特に有用で、並行処理によってスループットが向上します。
以下のPythonスクリプトでは、Pythonのthreadingモジュールを使用して、複数のトラッカーインスタンスを並行して実行します。各スレッドが1つの動画ソースでトラッカーを実行し、すべてのスレッドがバックグラウンドで同時に動作します。
各スレッドが正しいパラメーター(使用するモデルと動画ソース)を受け取れるように、スクリプトではこれらのパラメーターを受け取り、追跡のメインループを含む関数 run_tracker_in_thread を定義します。この関数は動画をフレームごとに読み込み、トラッカーを実行して、注釈付きの結果を保存します。
この例では、yolo26n.pt と yolo26n-seg.pt の2つの異なるモデルを使用し、それぞれローカルの動画ファイルとWebカメラという異なるソースでオブジェクトを追跡します。ソースは SOURCES で指定します。
threading.Thread内のdaemon=Trueパラメーターは、メインプログラムが終了するとすぐにこれらのスレッドが閉じられることを意味します。次に、start()でスレッドを開始し、join()を使って、両方のトラッカースレッドが終了するまでメインスレッドを待機させます。
最後に、すべてのスレッドのタスクが完了した後、結果を表示するウィンドウをcv2.destroyAllWindows()で閉じます。
import threading

import cv2

from ultralytics import YOLO

# モデル名とビデオソースを定義する
MODEL_NAMES = ["yolo26n.pt", "yolo26n-seg.pt"]
SOURCES = ["path/to/video.mp4", "0"]  # ローカルビデオ。ウェブカメラの場合は0

def run_tracker_in_thread(model_name, filename):
    """Run YOLO tracker in its own thread for concurrent processing.

    Args:
        model_name (str): Model checkpoint name or path loaded inside the thread.
        filename (str): The path to the video file or the identifier for the webcam/external camera source.
    """
    model = YOLO(model_name)
    results = model.track(filename, save=True, stream=True)
    for r in results:
        pass

# forループを使ってトラッカースレッドを作成し、開始する
tracker_threads = []
for video_file, model_name in zip(SOURCES, MODEL_NAMES):
    thread = threading.Thread(target=run_tracker_in_thread, args=(model_name, video_file), daemon=True)
    tracker_threads.append(thread)
    thread.start()

# すべてのトラッカースレッドが終了するまで待機する
for thread in tracker_threads:
    thread.join()

# 後処理を行い、ウィンドウを閉じる
cv2.destroyAllWindows()
スレッドを追加して同じ方法を適用すれば、この例を簡単に拡張し、より多くのビデオファイルやモデルを扱えます。
新しいトラッカーのコントリビューション#
Ultralytics YOLO向けのマルチオブジェクト追跡アルゴリズムを実装または改変した場合は、対応する設定ファイルとともに貢献して、ultralytics/trackersのultralytics/cfg/trackersに追加することをご検討ください。貢献により、コミュニティ全体で利用できる追跡オプションが増えます。
よくある質問#
いいえ。標準のUltralytics
.ptファイルにはYOLOモデルの重みが保存され、トラッカーは推論時にmodel.track()によって作成されます。トラックIDは連続するフレーム間のトラッカー状態に依存するため、単独の画像からはボックス、クラス、信頼度などの検出結果を取得できますが、それだけでは意味のある永続的なトラッキングIDを生成できません。デプロイ時には、検出器とトラッカーをアプリケーションにまとめ、同じビデオストリームからのフレームに対して
persist=Trueとともにmodel.track()をフレームごとに呼び出してください。ビデオ間で状態が引き継がれないよう、関連のないストリームには個別のモデルインスタンスまたはトラッカーインスタンスを使用してください。Ultralyticsトラッカー設定ディレクトリから既存のトラッカー設定ファイル(例:
custom_tracker.yaml)をコピーし、tracker_typeを除く必要なパラメーターを変更することで、カスタムトラッカーを設定できます。トラッキングモデルで次のようにこのファイルを使用します。例from ultralytics import YOLO model = YOLO("yolo26n.pt") results = model.track(source="https://youtu.be/LNwODJXcvt4", tracker="custom_tracker.yaml")複数のビデオストリーム上で物体追跡を同時に実行するには、Pythonの
threadingモジュールを使用できます。各スレッドが個別のビデオストリームを処理します。設定例を以下に示します。マルチスレッドトラッキングimport threading import cv2 from ultralytics import YOLO # モデル名とビデオソースを定義する MODEL_NAMES = ["yolo26n.pt", "yolo26n-seg.pt"] SOURCES = ["path/to/video.mp4", "0"] # ローカルビデオ。ウェブカメラの場合は0 def run_tracker_in_thread(model_name, filename): """Run YOLO tracker in its own thread for concurrent processing. Args: model_name (str): Model checkpoint name or path loaded inside the thread. filename (str): The path to the video file or the identifier for the webcam/external camera source. """ model = YOLO(model_name) results = model.track(filename, save=True, stream=True) for r in results: pass # forループを使ってトラッカースレッドを作成し、開始する tracker_threads = [] for video_file, model_name in zip(SOURCES, MODEL_NAMES): thread = threading.Thread(target=run_tracker_in_thread, args=(model_name, video_file), daemon=True) tracker_threads.append(thread) thread.start() # すべてのトラッカースレッドが終了するまで待機する for thread in tracker_threads: thread.join() # 後処理を行い、ウィンドウを閉じる cv2.destroyAllWindows()Ultralytics YOLOによるマルチオブジェクトトラッキングには、次のような多くの用途があります。
- 交通: 交通管理や自動運転のための車両追跡。
- 小売: 店舗内分析やセキュリティのための人物追跡。
- 水産養殖: 水生環境のモニタリングを目的とした魚の追跡。
- スポーツ解析: パフォーマンス分析のための選手や用具の追跡。
- セキュリティシステム: 不審な行動の監視とセキュリティアラームの作成。
これらのアプリケーションでは、高い精度で高フレームレートの動画をリアルタイムに処理できるUltralytics YOLOの能力が役立ちます。
複数のビデオフレームにわたる物体トラックを可視化するには、YOLOモデルのトラッキング機能とOpenCVを使って、検出された物体の経路を描画できます。方法を示すスクリプトの例を以下に示します。
複数のビデオフレームにわたるトラックのプロットfrom collections import defaultdict import cv2 import numpy as np from ultralytics import YOLO model = YOLO("yolo26n.pt") video_path = "path/to/video.mp4" cap = cv2.VideoCapture(video_path) track_history = defaultdict(list) while cap.isOpened(): success, frame = cap.read() if success: result = model.track(frame, persist=True)[0] annotated_frame = result.plot() if result.boxes and result.boxes.is_track: boxes = result.boxes.xywh.cpu() track_ids = result.boxes.id.int().cpu().tolist() for box, track_id in zip(boxes, track_ids): x, y, w, h = box track = track_history[track_id] track.append((float(x), float(y))) if len(track) > 30: track.pop(0) points = np.hstack(track).astype(np.int32).reshape((-1, 1, 2)) cv2.polylines(annotated_frame, [points], isClosed=False, color=(230, 230, 230), thickness=10) cv2.imshow("YOLO26 Tracking", annotated_frame) if cv2.waitKey(1) & 0xFF == ord("q"): break else: break cap.release() cv2.destroyAllWindows()このスクリプトは、時間経過に伴う追跡対象の移動経路を示すトラッキングラインをプロットし、物体の挙動やパターンを把握するうえで役立つ情報を提供します。


コメント679
質問したり、結果を共有したり、ほかの人をサポートしたりできます。
bhaskar2443053
I’m using YOLO-Pose to detect and track people throughout ~1-hour videos and need each person to keep the same ID. I already have high-quality ground-truth tracks from a SAM-based tracker.
Do you have a script that can fine-tune YOLO-Pose (and its tracker/Re-ID parameters) against this ground truth to squeeze out the best IDF1 or HOTA scores ?
1maxexplorer
Hi!
Thank you for your great work on YOLO and tracking integration. We are using YOLO with ByteTrack/BoT-SORT for object counting and tracking and want to improve ID stability.
-
We notice that sometimes, even when the object visually looks the same and the scene and motion are stable, the track_id changes. What parameters or reasons should we check to understand why the ID changes unexpectedly?
-
Is the match_thresh parameter based on IoU, and is it possible to print or visualize the IoU used during matching for debugging?
-
Is there a way to output Kalman-predicted boxes of lost tracks so we can analyze them?
-
Could increasing the video FPS improve tracking and IoU consistency, or is this mainly related to detection stability and parameter tuning?
-
Does ByteTrack or BoT-SORT use a min_hits parameter before confirming tracks, or are tracks confirmed immediately after creation?
-
If a track is lost, can a new ID only be assigned on the second frame after reappearance if conf > new_track_thresh and then conf > track_high_thresh, or can it happen immediately on the first detection?
-
Is the track_buffer parameter the number of frames a track is kept using Kalman prediction after it is lost before being deleted?
-
Do you have any tips to improve tracking stability and avoid unnecessary ID switches?
Thank you for your support!
-
 Glenn JocherUltralytics
@bhaskar2443053 currently there isn't a built-in script for fine-tuning YOLO-Pose tracking parameters against ground truth. You would need to implement custom evaluation using libraries like TrackEval or MOTChallenge to compute IDF1/HOTA scores and optimize tracker parameters iteratively.
@maxexplorer great questions about tracking stability! Here are the key points:
-
ID changes typically occur due to low IoU between predicted and detected boxes, occlusions, or threshold mismatches. Check
track_high_threshandmatch_threshin your tracker config. -
match_threshis indeed IoU-based. For debugging, you can add logging to the tracker code, but there's no built-in visualization. -
Kalman predictions aren't directly exposed, but you can access them by modifying the tracker implementation.
-
Higher FPS generally improves tracking by reducing inter-frame motion, making associations more reliable.
-
Both trackers use confirmation logic - tracks need to meet certain criteria before being confirmed as valid tracks.
-
New tracks can be assigned immediately if detection confidence exceeds
new_track_thresh. -
Correct -
track_buffermaintains lost tracks for that many frames using prediction. -
For stability: increase
track_buffer, adjustmatch_threshbased on your scenario, and ensure consistent detection quality with appropriateconfthresholds.
For detailed parameter tuning, refer to the tracker configuration files and our tracking documentation.
-
rohith-aiunika(編集済み)
Hi YOLO Team, I've been using the following Python script to track objects with my YOLOv8 model: from ultralytics import YOLO
model = YOLO(r"/home/best_pt_files/v1.0.2.pt") results = model.track(r"/home/video.MP4", save=False, stream=False)
However, I noticed that my GPU memory usage gradually increases, leading to an "out of memory" error before the video finishes processing. Interestingly, when I use the following command from the terminal, the entire video tracks successfully without excessive GPU memory consumption: yolo track model=/home/best_pt_files/1.0.2.pt source=/home/video.MP4
Previously, the Python script worked without any issues. The memory issue has only recently started occurring. Could you please help me understand the possible reasons for this memory increase and how to address it?
i have experimented with persist= True and False,stream = true and false, show = true and false also but the issue is still there
1- Glenn JocherUltralytics
@rohith-aiunika thanks for reporting this. The memory buildup in Python scripts (but not CLI) typically occurs when not using streaming mode. To match the CLI's memory behavior, modify your Python script to process frames iteratively using
stream=True:from ultralytics import YOLO model = YOLO("/home/best_pt_files/v1.0.2.pt") for result in model.track("/home/video.MP4", stream=True): # Process frames iteratively pass # Add your frame processing logic hereThis streams frames sequentially like the CLI, preventing memory accumulation. For more details, see the streaming implementation in our Tracking documentation. Let us know if this resolves the issue!
i have used stream = True, then the code is just executing without showing error and without tracking also
- Glenn JocherUltralytics
@rohith-aiunika thanks for the update. Let's ensure you're properly iterating through streaming results. Try adding a processing loop like this:
for result in model.track(source=video_path, stream=True):
    annotated_frame = result[0].plot()
    cv2.imshow('Tracking', annotated_frame)
    if cv2.waitKey(1) == ord('q'):
        break
This actively processes each frame and displays tracking annotations. If issues persist, you might need to verify your video source format using our supported inference sources documentation.
mwasela
Hello, Made a custom model that i can successfully run and with a well tweaked confidence filter, am getting good results.
Now Ive wrapped the classification and tracking functionality into a flask app, that returns the count ID's when accessed by a REST call like get, meaning it can be accessed by a separate app for processing and stuff. I want to be able to reset the counting through some other request. My camera feed is always live, i need a way to reset the track id's to zero when neccessary, they just keep counting until i exit the program.
1- Glenn JocherUltralytics
@mwasela hello,
It's great to hear that your custom model is performing well. To reset the tracking IDs in your Flask app, you can implement a mechanism to reinitialize the tracker state upon receiving a specific request. This can be done by resetting the tracker object or reloading the model within your tracking function.
For more detailed guidance on configuring and using trackers, please refer to our documentation: Multi-Object Tracking with Ultralytics YOLO.
Orziqulov-Javohir
I really need help to do this programm: I wanna select region via mouse "dangerous zone" Track detected person, If person enters this zone crop and save person's photo Can you show me pls how to do it for 10 cameras, my gpu is RTX 3080TI
1It is kind a security program detecting who entered zone
1import cv2 from ultralytics import YOLO import time
Load the YOLOv8 model
model = YOLO("yolov8n.pt") # pretrained YOLOv8n model
Initialize video capture for multiple cameras
camera_ids = [
'rtsp://admin:admin12345@172.17.67.20:554',
'rtsp://admin:admin12345@172.17.67.16:554', 'rtsp://admin:admin12345@172.17.67.18:554', 'rtsp://admin:admin12345@172.17.67.19:554', 'rtsp://admin:admin12345@172.17.67.17:554', 'rtsp://admin:admin12345@172.17.67.21:554', 'rtsp://admin:admin12345@172.17.67.17:554', 'rtsp://admin:admin12345@172.17.67.21:554', 'rtsp://admin:admin12345@172.17.67.17:554',
]caps = [cv2.VideoCapture(camera_id) for camera_id in camera_ids]
Open the video file
roi_start = [(0, 0)] * len(caps) roi_end = [(0, 0)] * len(caps) drawing = [False] * len(caps)
tracked_persons = [[] for _ in range(len(caps))] # List to track persons in dangerous zones
def draw_rectangle(event, x, y, flags, param): global roi_start, roi_end, drawing idx = param # Use param to identify the camera index if event == cv2.EVENT_LBUTTONDOWN: drawing[idx] = True roi_start[idx] = (x, y) roi_end[idx] = (x, y) print(f"Camera {idx}: Started drawing rectangle at: {roi_start[idx]}") elif event == cv2.EVENT_MOUSEMOVE: if drawing[idx]: roi_end[idx] = (x, y) print(f"Camera {idx}: Updated rectangle end to: {roi_end[idx]}") elif event == cv2.EVENT_LBUTTONUP: drawing[idx] = False roi_end[idx] = (x, y) print(f"Camera {idx}: Finished drawing rectangle at: {roi_end[idx]}")
Create a window and set mouse callback for each camera
for idx in range(len(caps)): window_name = f'Video {idx}' cv2.namedWindow(window_name) cv2.setMouseCallback(window_name, draw_rectangle, idx)
def is_inside_roi(x, y, roi_start, roi_end): x1, y1 = roi_start x2, y2 = roi_end return min(x1, x2) <= x <= max(x1, x2) and min(y1, y2) <= y <= max(y1, y2)
while True: frames = [] for cap in caps: ret, frame = cap.read() if not ret: continue # frame = cv2.resize(frame, (640, 480)) frames.append(frame)
for idx, frame in enumerate(frames):
    window_name = f'Video {idx}'

    # Draw the ROI rectangle on the frame
    if drawing[idx] or roi_start[idx] != roi_end[idx]:
        cv2.rectangle(frame, roi_start[idx], roi_end[idx], (0, 255, 0), 2)
        cv2.putText(frame, "Dangerous Zone", (roi_start[idx][0], roi_start[idx][1] - 10), cv2.FONT_HERSHEY_SIMPLEX, 0.9, (0, 255, 0), 2)

    # Run YOLOv8 tracking on the frame, persisting tracks between frames
    results = model.track(frame, tracker="bytetrack.yaml", persist=True)

    for result in results:
        boxes = result.boxes

        for box in boxes:
            x1, y1, x2, y2 = box.xyxy.tolist()[0][:4]
            cls = box.cls.tolist()[0]
            if cls == 0:  # Person class in COCO dataset
                # Check if the center of the person is inside the ROI
                cx, cy = int((x1 + x2) / 2), int((y1 + y2) / 2)
                if is_inside_roi(cx, cy, roi_start[idx], roi_end[idx]):
                    # Check if this person is already tracked
                    person_id = box.id.tolist()[0] if box.id is not None else None

                    if person_id not in tracked_persons[idx]:
                        tracked_persons[idx].append(person_id)
                        # Crop and save the frame
                        crop = frame[int(y1):int(y2), int(x1):int(x2)]
                        cv2.imwrite(f"cropped_camera{idx}_person{person_id}_{int(time.time())}.jpg", crop)
                        # Draw a label on the person
                        cv2.putText(frame, "Person in Dangerous Zone", (int(x1), int(y1) - 10), cv2.FONT_HERSHEY_SIMPLEX, 0.9, (0, 0, 255), 2)
                        cv2.rectangle(frame, (int(x1), int(y1)), (int(x2), int(y2)), (0, 0, 255), 2)

    cv2.imshow(window_name, frame)

if cv2.waitKey(1) & 0xFF == ord('q'):
    break
Release all video captures
for cap in caps: cap.release() cv2.destroyAllWindows()
- Glenn JocherUltralytics
Your approach looks solid for setting up a security program to track and save images of individuals entering a designated "dangerous zone" across multiple cameras. To enhance your implementation, ensure you're using the latest versions of the Ultralytics package for optimal performance and bug fixes. For more detailed guidance on tracking configurations and additional features, you can refer to the Ultralytics tracking documentation. If you encounter any specific issues or need further assistance, feel free to ask!
mariem158
File "", line 91 results = model.track(frame, persist=True, tracker="botsort.yaml") ^ IndentationError: unexpected indent COMMENT CORRIGER CETTE ERREUR
- Glenn JocherUltralytics
The error you're encountering is due to an unexpected indent in your code. Ensure that the indentation is consistent throughout your script. If the issue persists, please verify it with the latest version of the Ultralytics package. For more details on tracking configurations, you can refer to the Ultralytics tracking documentation.
GKYoffice
How can I get the tracking metrics of a tracker such as MOTA, IDF1, etc.
1Can I set the parameter ''save_txt'' to True in the track function, and then write code to evaluate the tracking data?
 Paula DerrengerUltralytics
Currently, the Ultralytics YOLO framework doesn't provide built-in functionality for computing tracking metrics like MOTA or IDF1 directly through the API or command line. However, you can utilize external libraries such as MOTChallenge eval for calculating these metrics.
After running your tracking with YOLOv8, you'd typically export your tracking results in a format compatible with these libraries (usually a
.txtformat with frame ID, object ID, bounding boxes, etc.). Then, use the external library to compute the desired metrics by providing it with both the ground truth and your results file.Here's a generic example on how you might save tracking results (modify based on your actual use case):
from ultralytics import YOLO

# Initialize and load your model
model = YOLO("path/to/your/model.pt")

# Tracking
results = model.track(source='path/to/video.mp4', save_txt=True, project='runs/track', name='exp')

# results are saved in 'runs/track/exp' in a format that can be used with MOTChallenge eval tools
Afterwards, follow the documentation of the MOTChallenge eval toolkit to compute the metrics using the outputs stored in
'runs/track/exp'.If you encounter any specific issues while implementing this, feel free to ask!🛠️
AdadAlShabab
Can I run two models simultaneously in one video? Ex: model = YOLO('E:/Ultralytics/best.pt') model = YOLO('yolov8m-pose.pt') results = model.track(source="file.mp4", show=True, conf=0.3, save=False) results = model.track(source="file.mp4", show=True, conf=0.3, save=False)
I want that two models will works simultaneously with cumulative results? Is it possible? Please let me know. Thanks in advance!!
1- Paula DerrengerUltralytics
@AdadAlShabab yes, you can run two models simultaneously on one video, but you'll need to manage the inference in a way that allows both models to process the video frames concurrently. Here's a simplified example using threading to achieve this:
import threading
from ultralytics import YOLO

# Load the models
model1 = YOLO('E:/Ultralytics/best.pt')
model2 = YOLO('yolov8m-pose.pt')

# Function to run tracking
def track_video(model, source, conf, show, save):
    results = model.track(source=source, show=show, conf=conf, save=save)
    # Process results here or return them

# Create threads for each model
thread1 = threading.Thread(target=track_video, args=(model1, "file.mp4", 0.3, True, False))
thread2 = threading.Thread(target=track_video, args=(model2, "file.mp4", 0.3, True, False))

# Start the threads
thread1.start()
thread2.start()

# Wait for both threads to finish
thread1.join()
thread2.join()
This script will run both models in separate threads. If you want to combine the results from both models, you'll need to implement a mechanism to synchronize and merge the results from both threads. Keep in mind that displaying the results (
show=True) from two threads might not work as expected, and you might need to handle the visualization separately.Remember to handle the GPU memory usage carefully, as running two models simultaneously will require more memory. If you encounter any issues, consider running the models sequentially or on separate GPUs if available.
4
Journey2-20
Hello I'm newer to Opencv and I'm trying to run a tracking camera for airsoft. How would i select specific bounding boxes?
- Paula DerrengerUltralytics
Use
model.track(frame, persist=True)and inspectresults[0].boxes.xyxywithresults[0].boxes.id; select the box containing your OpenCV mouse-click coordinates, store its track ID, then process or draw only boxes whoseboxes.idmatches that ID. Feel free to continue posting questions here so the Ultralytics team can help.
yashpatel2010
In my jetson orin nano super developer kit with jetpack6.1 and deepstream7.1 i want to do cross camera person tracking. Is there any default way in deepstream configs to do it? Or any other lightweight thing that can be easily doable in jetson orin nano 8 gb super dev kit.
- Glenn JocherUltralytics
Ultralytics
trackis single-camera MOT, so cross-camera person IDs are not built in; on DeepStream 7.1 the practical Orin Nano path isNvDeepSORT/ReID per stream plus downstream association from the exported embeddings described in the DeepStreamgst-nvtrackerdocs, or NVIDIA’s separate Multi-Camera Tracking workflow for full MTMC. Please keep the details here in Discussions and share your current tracker config if you want a minimal setup suggestion. (docs.nvidia.com)
anvi97(編集済み)
Hi @glenn-jocher,
I am building a road surface detection system using YOLO segmentation.
My pipeline:
Apply bird eye view using cv2.getPerspectiveTransform()
Mask only road area
Detect potholes, zebra crossings, and speed bumps
I am facing the following issues:
1️⃣ Overlapping Potholes Not Merging Properly
I want overlapping potholes to merge into one bounding box.
In many cases it works, but sometimes:
Two boxes are still shown for the same pothole
Even when they overlap visually
I am using YOLO with:
results = model(frame, conf=0.45, iou=0.4)
Is YOLO’s internal NMS preventing full merging? Should I apply custom merging after inference? Is segmentation-based merging better than bounding box merging for potholes?
2️⃣ Object Size Changing After Bird Eye View
I calculate pothole size using:
pixels_per_foot = 220
But I selected this value randomly (no real-world measurement).
Because of this:
Object size changes depending on frame position
Same pothole appears different size
Is it correct that without real-world calibration, size cannot be accurate? What is the correct method to calculate real-world size in a monocular dashcam setup?
3️⃣ Zebra Crossing vs Black–White Speed Bump Confusion
Black–white speed bumps are getting confused with zebra crossings because both have parallel white-black stripes.
Currently I am detecting only yellow speed bumps to avoid confusion.
What is the better approach to separate them?
Use segmentation instead of boxes?
Add geometry-based filtering?
Train with more hard-negative examples?
this is my code ..... from ultralytics import YOLO import cv2 import numpy as np
model = YOLO("runs/segment/pothole_seg_model3/weights/best.pt") pixels_per_foot = 220
video_path = "sample_video.mp4" cap = cv2.VideoCapture(video_path)
if not cap.isOpened(): print(" Cannot open video") exit()
width = int(cap.get(cv2.CAP_PROP_FRAME_WIDTH)) height = int(cap.get(cv2.CAP_PROP_FRAME_HEIGHT)) fps = cap.get(cv2.CAP_PROP_FPS) or 25.0
fourcc = cv2.VideoWriter_fourcc(*'avc1') out = cv2.VideoWriter("pothole5.mp4", fourcc, fps, (width, height))
STRETCH_AMOUNT = 50
src = np.float32([ [0, height],
[width, height],
[922, 183],
[265, 183]
])dst = np.float32([ [0, height], [width, height], [width + STRETCH_AMOUNT, 0], [0 - STRETCH_AMOUNT, 0] ])
matrix = cv2.getPerspectiveTransform(src, dst) def compute_iou(box1, box2): x1 = max(box1[0], box2[0]) y1 = max(box1[1], box2[1]) x2 = min(box1[2], box2[2]) y2 = min(box1[3], box2[3])
inter_area = max(0, x2 - x1) * max(0, y2 - y1)

box1_area = (box1[2] - box1[0]) * (box1[3] - box1[1])
box2_area = (box2[2] - box2[0]) * (box2[3] - box2[1])

union = box1_area + box2_area - inter_area

if union == 0:
    return 0

return inter_area / union
def should_merge(box1, box2, iou_thresh=0.1, dist_thresh=150): # Containment check - if one box is inside the other if (box1[0] >= box2[0] and box1[1] >= box2[1] and box1[2] <= box2[2] and box1[3] <= box2[3]): return True if (box2[0] >= box1[0] and box2[1] >= box1[1] and box2[2] <= box1[2] and box2[3] <= box1[3]): return True
iou = compute_iou(box1, box2)
if iou > iou_thresh:
    return True

cx1, cy1 = (box1[0]+box1[2])/2, (box1[1]+box1[3])/2
cx2, cy2 = (box2[0]+box2[2])/2, (box2[1]+box2[3])/2

if np.sqrt((cx1-cx2)**2 + (cy1-cy2)**2) < dist_thresh:
    return True

return False
while True: ret, frame = cap.read() if not ret: break
bird_eye = cv2.warpPerspective(frame, matrix, (width, height))

results = model(bird_eye, conf=0.45, iou=0.4)[0]
annotated = results.plot()

if results.boxes is not None:
    for box in results.boxes:
        cls_id = int(box.cls.item())

        if cls_id == 0:  # pothole only
            x1, y1, x2, y2 = map(int, box.xyxy.cpu().numpy()[0])

            w_px = x2 - x1
            h_px = y2 - y1

            w_ft = w_px / pixels_per_foot
            h_ft = h_px / pixels_per_foot

            label = f"{w_ft:.2f}ft x {h_ft:.2f}ft"

            cv2.putText(
                annotated,
                label,
                (x1, y1 - 15),
                cv2.FONT_HERSHEY_SIMPLEX,
                0.6,
                (0, 255, 255),
                2
            )

cv2.imshow("Bird Eye + Pothole Detection", annotated)
out.write(annotated)

if cv2.waitKey(1) & 0xFF == 27:
    break
cap.release() out.release() cv2.destroyAllWindows()
- Glenn JocherUltralytics
For (1), YOLO’s NMS will only suppress duplicate detections based on
iou=...—it won’t “merge” two overlapping detections into a larger union box, and in your snippetcompute_iou()/should_merge()aren’t actually applied toresults.boxes, so you’re still visualizing the raw post-NMS output; since you’re using a Segment model, the most robust way to merge “split” potholes is to union the pothole masks and re-extract connected components (then box/measure those) rather than trying to union boxes.import cv2 import numpy as np r = model(bird_eye, conf=0.45, iou=0.4)[0] if r.masks is not None and r.boxes is not None: cls = r.boxes.cls.int().cpu().numpy() pothole_idx = np.where(cls == 0)[0] if pothole_idx.size: m = r.masks.data[pothole_idx].cpu().numpy() # (N,H,W), 0/1 union = (m.sum(0) > 0).astype(np.uint8) * 255 n, labels = cv2.connectedComponents(union) for k in range(1, n): ys, xs = np.where(labels == k) x1, y1, x2, y2 = xs.min(), ys.min(), xs.max(), ys.max() cv2.rectangle(bird_eye, (x1, y1), (x2, y2), (0, 255, 255), 2)For (2), yes—without real-world calibration (and a valid “road plane” assumption),
pixels_per_foot=220can’t be physically meaningful, and even with a BEV warp you only get consistent scale if your homography is tied to metric coordinates; the usual monocular approach is: calibrate camera intrinsics, estimate the road plane, build a homography to a top-down plane in real units (or derive scale from at least one known road-plane measurement like lane width/stripe spacing), then measure in the BEV plane.For (3), the best fix is usually data: train both classes explicitly with lots of “hard negatives” (zebra crossings that look like bumps and vice versa) and keep labels consistent; segmentation often helps because you can then add simple shape/location constraints on the mask (zebra = large repeated pattern region, bump = single narrow band across lane) and optionally smooth decisions over time (if you’re doing video, using
model.track(..., persist=True)from the Track mode docs can help stabilize per-frame flicker, even though it won’t merge instances within a frame).If you can paste
!yolo checksoutput and one representative frame (plus what you consider the “correct” merged result), I can suggest concrete thresholds/post-processing for your exact outputs. In the attached frame:
The large water-filled pothole on the left should be treated as a single instance.
The small region in the top-left corner (currently detected as separate) should be merged with the large region.
Essentially, all visually continuous damaged area should result in one bounding box / one connected component.
Currently:
Mask union + connected components splits them due to small segmentation gaps
Goal:
Treat visually continuous pothole surface as one instance for measurement stability.
- Glenn JocherUltralytics
That split is expected because
connectedComponents()treats any 1–2 px “mask hole” as a hard break, so add a small gap-closing step on the union mask (morphological close / dilate→erode) before components, with the kernel sized to the largest gap you still consider “visually continuous” (see Ultralytics YOLO segmentation docs for more mask/seg usage details):# union: uint8 {0,255} union = (m.sum(0) > 0).astype(np.uint8) * 255 # bridge small gaps (tune kernel size to your expected mask discontinuities) k_close = cv2.getStructuringElement(cv2.MORPH_ELLIPSE, (25, 25)) union_closed = cv2.morphologyEx(union, cv2.MORPH_CLOSE, k_close, iterations=1) # optional: remove tiny speckles after closing k_open = cv2.getStructuringElement(cv2.MORPH_ELLIPSE, (7, 7)) union_closed = cv2.morphologyEx(union_closed, cv2.MORPH_OPEN, k_open, iterations=1) n, labels = cv2.connectedComponents(union_closed)
mslabdelhak29
Reid doesn't work how can i fix it i tried to change it True in botsort.yaml but it doesn't work
@glenn_jocher
- Glenn JocherUltralytics(編集済み)
@mslabdelhak29 ReID is only supported by some trackers (for example BoT-SORT), not ByteTrack, and it’s enabled via the tracker YAML you pass at runtime. Copy the default config, enable ReID explicitly, and point
track()to your copy:# custom_botsort.yaml tracker_type: botsort with_reid: True model: yolo26n-cls.pt # or another YOLO classification weight you have locallyfrom ultralytics import YOLO model = YOLO("yolo26n.pt") # any YOLO detector results = model.track(source="path/to/video.mp4", tracker="custom_botsort.yaml", persist=True, show=False)If it still doesn’t work, you’re likely editing a different YAML than the one being loaded; always pass the path as above. Also share the output of
yolo checksand the exactcustom_botsort.yamlyou used so we can verify your environment and keys. See the ReID section in the tracking guide and the BoT-SORT config for details: Multi‑Object Tracking docs and botsort.yaml config.