使用 Ultralytics 进行 K 折交叉验证
简介#
本指南介绍如何在 Ultralytics 生态系统中为目标检测数据集实现 K 折交叉验证。本指南使用 YOLO 检测格式和 scikit-learn、pandas、PyYAML 等 Python 库,逐步讲解配置、生成特征向量以及执行 K 折数据集划分。
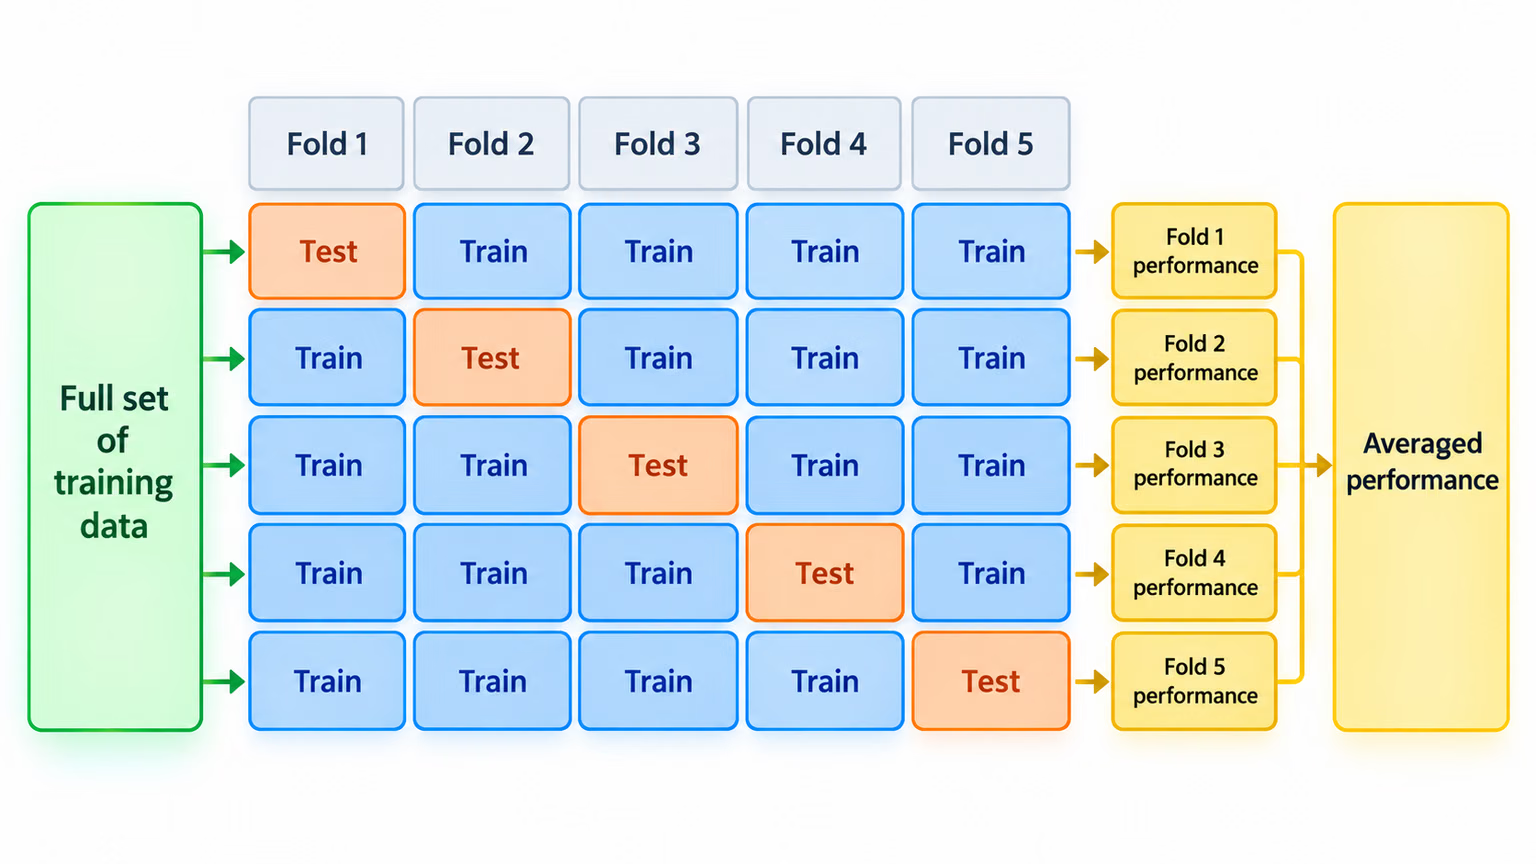
无论你的项目使用的是 Fruit Detection 数据集还是自定义数据源,本教程都能帮助你理解并应用 K 折交叉验证,提升机器学习模型的可靠性和鲁棒性。本教程使用 k=5 折,但请注意,最佳折数会因数据集和项目具体情况而异。对于规模较小、噪声较多或变化很大的数据集,K 折交叉验证最有价值;对于规模较大且多样化的数据集,设计良好的训练集/验证集/测试集划分通常就足够了。
设置#
-
你的标注应采用 YOLO detection format。
-
本指南假设标注文件已保存在本地。
-
在本示例中,我们使用 Fruit Detection 数据集。
- 该数据集共包含 8479 张图像。
- 数据集包含 6 个类别标签,每个类别的实例总数如下所示。
| 类别标签 | 实例数量 |
|---|---|
| 苹果 | 7049 |
| 葡萄 | 7202 |
| 菠萝 | 1613 |
| 橙子 | 15549 |
| 香蕉 | 3536 |
| 西瓜 | 1976 |
-
所需的 Python 软件包包括:
ultralyticssklearnpandaspyyaml
-
本教程使用
k=5折。不过,你应根据自己的数据集确定最佳折数。
-
为你的项目创建并激活新的 Python 虚拟环境(
venv)。使用pip(或你偏好的包管理器)安装:- Ultralytics 库:
pip install -U ultralytics。或者,你也可以克隆官方 repo。 - Scikit-learn、pandas 和 PyYAML:
pip install -U scikit-learn pandas pyyaml。
- Ultralytics 库:
-
确认你的标注采用 YOLO detection format。
- 本教程中的所有标注文件都位于
Fruit-Detection/labels目录中。
- 本教程中的所有标注文件都位于
为目标检测数据集生成特征向量#
-
首先,新建一个
example.pyPython 文件,用于执行以下步骤。 -
使用 Ultralytics 的
YOLODataset类加载数据集 YAML 中列出的训练图像和验证图像,不要改动测试集划分。from pathlib import Path from ultralytics.data.dataset import YOLODataset from ultralytics.data.utils import check_det_dataset yaml_file = "path/to/data.yaml" data = check_det_dataset(yaml_file) dataset_path = Path(data["path"]) sources = [] for split in ("train", "val"): source = data.get(split) if source: sources.extend(source if isinstance(source, list) else [source]) dataset = YOLODataset(sources, data=data, augment=False) images = [Path(p) for p in dataset.im_files] -
现在,读取数据集 YAML 文件的内容,并提取类别标签的索引。
classes = data["names"] cls_idx = sorted(classes.keys()) -
初始化一个空的
pandasDataFrame。import pandas as pd labels_df = pd.DataFrame(0.0, columns=cls_idx, index=images) -
统计标注文件中每个类别标签的实例数量。
from collections import Counter for image, label in zip(images, dataset.labels): lbl_counter = Counter(label["cls"].flatten().astype(int)) labels_df.loc[image, list(lbl_counter)] = list(lbl_counter.values()) -
以下是填充数据后的 DataFrame 示例:
                                                       0    1    2    3    4    5
'0000a16e4b057580_jpg.rf.00ab48988370f64f5ca8ea4...'  0.0  0.0  0.0  0.0  0.0  7.0
'0000a16e4b057580_jpg.rf.7e6dce029fb67f01eb19aa7...'  0.0  0.0  0.0  0.0  0.0  7.0
'0000a16e4b057580_jpg.rf.bc4d31cdcbe229dd022957a...'  0.0  0.0  0.0  0.0  0.0  7.0
'00020ebf74c4881c_jpg.rf.508192a0a97aa6c4a3b6882...'  0.0  0.0  0.0  1.0  0.0  0.0
'00020ebf74c4881c_jpg.rf.5af192a2254c8ecc4188a25...'  0.0  0.0  0.0  1.0  0.0  0.0
 ...                                                  ...  ...  ...  ...  ...  ...
'ff4cd45896de38be_jpg.rf.c4b5e967ca10c7ced3b9e97...'  0.0  0.0  0.0  0.0  0.0  2.0
'ff4cd45896de38be_jpg.rf.ea4c1d37d2884b3e3cbce08...'  0.0  0.0  0.0  0.0  0.0  2.0
'ff5fd9c3c624b7dc_jpg.rf.bb519feaa36fc4bf630a033...'  1.0  0.0  0.0  0.0  0.0  0.0
'ff5fd9c3c624b7dc_jpg.rf.f0751c9c3aa4519ea3c9d6a...'  1.0  0.0  0.0  0.0  0.0  0.0
'fffe28b31f2a70d4_jpg.rf.7ea16bd637ba0711c53b540...'  0.0  6.0  0.0  0.0  0.0  0.0
行使用图像的绝对路径,列对应类别标签索引。缺少标签的行会保留全零背景值。这种数据结构支持对目标检测数据集应用 K 折交叉验证。
K 折数据集划分#
-
现在,我们将使用
sklearn.model_selection中的KFold类,将数据集划分为k份。- 重要提示:
- 设置
shuffle=True可确保各划分中的类别分布随机化。 - 将
random_state=M设置为所选整数M,即可获得可重复的结果。
- 设置
from sklearn.model_selection import KFold ksplit = 5 kf = KFold(n_splits=ksplit, shuffle=True, random_state=20) # 设置 random_state 以获得可重复的结果 kfolds = list(kf.split(labels_df)) - 重要提示:
-
现在,数据集已划分为
k折,每折包含train和val索引列表。我们将构建一个 DataFrame,以便更清晰地展示这些结果。folds = [f"split_{n}" for n in range(1, ksplit + 1)] folds_df = pd.DataFrame(index=labels_df.index, columns=folds) for i, (train, val) in enumerate(kfolds, start=1): folds_df.loc[labels_df.index[train], f"split_{i}"] = "train" folds_df.loc[labels_df.index[val], f"split_{i}"] = "val" -
现在,我们将计算每折的类别标签分布,即
val中各类别的数量与train中各类别的数量之比。fold_lbl_distrb = pd.DataFrame(index=folds, columns=cls_idx) for n, (train_indices, val_indices) in enumerate(kfolds, start=1): train_totals = labels_df.iloc[train_indices].sum() val_totals = labels_df.iloc[val_indices].sum() # To avoid division by zero, we add a small value (1E-7) to the denominator ratio = val_totals / (train_totals + 1e-7) fold_lbl_distrb.loc[f"split_{n}"] = ratio理想情况下,各划分中不同类别的比例应大致相近。不过,具体情况取决于你的数据集。
-
为每个划分写入图像列表和数据集 YAML 文件。使用文本列表可以避免复制数据集
k次。import yaml save_path = dataset_path.parent / f"{ksplit}-Fold_Cross-val" save_path.mkdir(parents=True, exist_ok=True) ds_yamls = [] for split in folds_df.columns: for partition in ("train", "val"): split_images = folds_df.index[folds_df[split] == partition] paths = "\n".join(map(str, split_images)) (save_path / f"{split}_{partition}.txt").write_text(f"{paths}\n") dataset_yaml = save_path / f"{split}.yaml" ds_yamls.append(dataset_yaml) with open(dataset_yaml, "w") as ds_y: yaml.safe_dump( { "path": save_path.as_posix(), "train": f"{split}_train.txt", "val": f"{split}_val.txt", "names": classes, }, ds_y, )
保存记录(可选)#
你也可以将 K 折划分记录和标签分布 DataFrame 保存为 CSV 文件,以供日后参考。
folds_df.to_csv(save_path / "kfold_datasplit.csv")
fold_lbl_distrb.to_csv(save_path / "kfold_label_distribution.csv")
使用 K 折数据划分训练 YOLO#
-
首先,加载 YOLO 模型。
from ultralytics import YOLO weights_path = "path/to/weights.pt" # 小型模型请使用 yolo26n.pt model = YOLO(weights_path, task="detect") -
接下来,遍历数据集 YAML 文件来运行训练。结果会保存到由
project和name参数指定的目录中。默认目录为runs/detect/train#,其中#是整数索引。results = {} # Define your additional arguments here batch = 16 project = "kfold_demo" epochs = 100 for k, dataset_yaml in enumerate(ds_yamls): model = YOLO(weights_path, task="detect") results[k] = model.train( data=dataset_yaml, epochs=epochs, batch=batch, project=project, name=f"fold_{k + 1}" ) # include any additional train arguments -
你也可以使用 Ultralytics 的自动划分函数自动划分数据集:
from ultralytics.data.split import autosplit

# 自动将数据集划分为 train/val/test
autosplit(path="path/to/images", weights=(0.8, 0.2, 0.0), annotated_only=True)
结论#
本指南介绍了如何使用 K 折交叉验证训练 YOLO 目标检测模型。我们了解了如何将训练集和验证集划分为 K 个分区,以及如何使用生成的比例表检查随机划分后的类别平衡情况。
我们还介绍了如何创建报告 DataFrame,以可视化各数据集划分及其标签分布,清晰呈现训练集和验证集的结构。
我们还可以选择保存记录以供日后参考,这在大型项目或排查模型性能问题时尤其有用。
最后,我们通过循环使用每个划分来训练模型,并保存训练结果,以便进一步分析和比较。
K 折交叉验证是一种充分利用现有数据的稳健方法,有助于确保模型在不同数据子集上的性能可靠且一致。这样可以得到泛化能力更强、可靠性更高的模型,降低模型对特定数据模式过拟合的可能性。
请记住,虽然本指南使用的是 YOLO,但这些步骤大多也适用于其他机器学习模型。了解这些步骤后,你就能在自己的机器学习项目中有效地应用交叉验证。
常见问题#
K 折交叉验证是一种将数据集划分为 'k' 个子集(折)来更可靠地评估模型性能的方法。每一折都会用作训练数据和验证数据。在目标检测中,使用 K 折交叉验证有助于确保 Ultralytics YOLO 模型在不同数据划分上的性能稳健且具有良好的泛化能力,从而提高模型的可靠性。有关使用 Ultralytics YOLO 设置 K 折交叉验证的详细说明,请参阅使用 Ultralytics 进行 K 折交叉验证。
使用 Ultralytics YOLO 实现 K 折交叉验证,请按以下步骤操作:
- 确认标注采用 YOLO detection format。
- 使用
sklearn、pandas和pyyaml等 Python 库。 - 根据数据集创建特征向量。
- 使用来自
sklearn.model_selection的KFold划分数据集。 - 在每个划分上训练 YOLO 模型。
如需完整指南,请参阅文档中的 K 折数据集划分部分。
本指南介绍的工作流程针对 YOLO 检测格式,但同样的方法也适用于所有 YOLO 任务——任务会影响折的组成方式,而不会改变交叉验证是否有帮助:
任务 折的设计 detect按图像划分,并平衡各折中的目标和类别分布。将相关图像(来自同一患者、视频序列、摄像头或地点的图像)放在同一折中。 segment采用与检测任务相同的图像级策略,同时确保每折都涵盖相应的掩码和类别。 classify优先使用分层划分,使训练集和验证集中的类别频率保持平衡。 pose按个体或序列划分,确保同一个人或动物不会同时出现在某一折的两侧。 obb按图像划分,并将来自同一场景的切片或裁剪图像放在一起——这对于航空影像尤其重要。 无论任务是什么,都要避免将近似重复样本和相关样本放入相互对立的折中:这种数据泄漏会大幅抬高验证指标,使其远超模型在生产环境中实际能达到的水平。
Ultralytics YOLO提供先进的实时目标检测能力,兼具高准确率和高效率。它用途广泛,支持多种计算机视觉任务,例如检测、实例分割、语义分割和分类。此外,它还能与 Ultralytics Platform 等工具集成,实现无代码模型训练和部署。
你的标注应遵循 YOLO 检测格式。每个标注文件都必须列出目标类别及其在图像中的边界框坐标。YOLO 格式能为目标检测模型训练提供高效、标准化的数据处理流程。有关正确标注格式的更多信息,请参阅 YOLO 检测格式指南。
可以,只要标注采用 YOLO 检测格式,你就能对任何自定义数据集使用 K 折交叉验证。将数据集路径和类别标签替换为适用于自定义数据集的内容即可。这种灵活性让任何目标检测项目都能通过 K 折交叉验证获得稳健的模型评估结果。如需查看实际示例,请参阅生成特征向量部分。


评论23
提出问题、分享结果,或帮助其他人。
 chenxin liao
我有一个理论性的问题想咨询,文章最后谈到 “这样可以得到泛化能力更强、可靠性更高的模型,降低模型对特定数据模式过拟合的可能性。” ,那么K折交叉验证到底是验证并展示模型的稳健性,还是用于增强模型的泛化能力(扩充训练集)?依据我的理解更偏向于前者,谢谢!
 Paula DerrengerUltralytics
你的理解是对的:K 折交叉验证主要用于估计训练方案在未见数据上的表现,并观察结果对数据划分有多敏感。它轮换使用同一批样本,不会扩充训练集,也不会直接提升模型的泛化能力。文章结尾更准确的说法是:交叉验证可以帮助选出在不同划分下表现更稳定的模型配置或超参数;最终模型是否真的泛化得更好,仍需用未参与训练和调参的独立测试集来评估。
jingieboy
does this work with yolov8-cls? if so how would the folder structure look like? how are the data splits
 Glenn JocherUltralytics(已编辑)
Yes—K‑Fold works the same for classification; use the standard ImageNet-style layout per fold, and train each fold separately (YOLO infers classes from folder names). For YOLO26 (recommended) you can do:
dataset/
  split_1/
    train/
      class_a/ ...
      class_b/ ...
    val/
      class_a/ ...
      class_b/ ...
  split_2/
    train/...
    val/...
  ...
from ultralytics import YOLO weights = "yolo26n-cls.pt" # swap to 'yolov8n-cls.pt' if you prefer YOLOv8 splits = ["dataset/split_1", "dataset/split_2", "dataset/split_3"] for d in splits: model = YOLO(weights) model.train(data=d, epochs=20, batch=16) # d must contain 'train/' and 'val/' subfoldersFor building folds, use
StratifiedKFoldon image-level labels derived from parent folder names to keep class balance, or use the random splitter shown in the autosplit reference if stratification isn’t required. Classification usage details are in the classification task docs.thank you for this! I have also notice that everytime I run model.val(), the accuracies and confusion matrix values are slightly different this time. Is this normal or during evaluation, there is a small randomness when calling the function.
- Glenn JocherUltralytics
@jingieboy minor variations can occur from non-deterministic CUDA ops or multi-threading; validation itself doesn’t add randomness by default—set seeds and force deterministic ops to lock results:
import random, numpy as np, torch

seed = 0
random.seed(seed); np.random.seed(seed); torch.manual_seed(seed)
torch.backends.cudnn.deterministic = True
torch.backends.cudnn.benchmark = False

model.val()  # run evaluation
If differences are still large, double-check your eval args in the validation mode docs.
Nehasq
Hi, I am applying K-fold validation using the leave-one-out technique. My dataset consists of a single class and includes 21 images in total. For each split, I use 20 images for training and 1 image for testing. I am implementing the leave-one-out technique with the code above, setting ksplit=21.
I am not using a separate validation dataset, only training and testing data. Here is the code I am using:
results = {}
Define additional arguments here
batch = 16 project = "kfold_demo" epochs = 100
for k in range(ksplit): dataset_yaml = ds_yamls[k] model = YOLO(weights_path, task="detect") model.train(data=dataset_yaml, epochs=epochs, batch=batch, project=project) # Include any train arguments results[k] = model.metrics # Save output metrics for further analysis
In my data.yaml file, I have provided the validation path as the test set. When it trains and validates on the "1 test data," does this mean the model is being tested on data it has never seen during training? This is my first point of confusion.
my data.yaml file for each split looks like this: names:
- pothole path: ../ 2024-12-10_21-Fold_Cross-val/split_1 train: train val: test
My second question is about calculating the final performance. When I ran the above code, it calculated scores for each individual split. Do I need to calculate the final performance metrics manually, or is there any functionality in YOLOv8 to compute the aggregated performance automatically?
- Glenn JocherUltralytics
@Nehasq to address your first question, yes, the model is being tested on unseen data during each split, as the test set (1 image) is excluded from training and only used for validation. Regarding your second question, YOLO does not automatically aggregate metrics across splits. You need to compute the final performance metrics manually by averaging the results from all splits. For reference, you can review the K-Fold Cross Validation guide.
Thanks for your reply. I understand your point. So, are you saying that, for example, in my case, where I have 21 scores (precision, recall, etc.), I should simply add all the precision values together and divide the sum by 21 to get the final precision of the model? Is that correct?
Also, in y case of 20 images( training) and 1 images for test, what batch size would you suggest?
- Glenn JocherUltralytics
Yes, to calculate the final precision (or any metric), you average the values across all splits, i.e., sum all precision scores and divide by the number of splits (21 in your case). As for the batch size, given your small dataset, you could keep it low (e.g., 1 or 2) to ensure efficient utilization of the data while avoiding overfitting.
Thanks, that really helps! With a batch size of 1, I am keeping the epochs at 10. Should it be fewer? Also, to check for overfitting, I need to review the result graphs for each split. However, I can't definitively determine if it is overfitting since each split is separate, right?
- Glenn JocherUltralytics
Keeping epochs at 10 with a batch size of 1 is reasonable given your small dataset size. To check for overfitting, reviewing result graphs from each split can help, but overfitting may be harder to detect since each split involves different training and test data. Consider comparing trends across splits for consistent insights. For further details, you can reference the K-Fold Cross Validation guide.
semyon-v-dot
After the loop:
for ext in supported_extensions:
    images.extend(sorted((dataset_path / "images").rglob(f"*{ext}")))
Should be this line of code:
images = sorted(images)For
imagesmatching withlabelslist:labels = sorted(dataset_path.rglob("*labels/*.txt"))Otherwise the script creates background images because some images missing their labels.
- Glenn JocherUltralytics
@semyon-v-dot thank you for your suggestion. Sorting the
imageslist after extending it with supported extensions is a good practice to ensure alignment with thelabelslist. This helps prevent issues with missing labels.1
 sangeun jo
K-폴드 데이터 세트 분할 4번에서
images.extend(sorted((dataset_path / "images").rglob(f"*{ext}")))이 코드를images.extend(sorted(dataset_path.rglob(f"*images/*{ext}")))로 변환해야 작동했습니다.- Glenn JocherUltralytics
@sangeun-jo thank you for pointing that out. Your modification to
images.extend(sorted(dataset_path.rglob(f"*images/*{ext}")))is indeed correct and ensures the code works as intended. If you have any further questions or need additional assistance, feel free to ask!
kh-diab
is it usefult to use this k fold approach when I just have one class only but my issue is the class is detected as background or vice versa as per the attached Confusion matrix
- Glenn JocherUltralytics
@kh-diab using K-Fold Cross Validation can still be beneficial even with a single class. It helps ensure that your model's performance is robust and not overly dependent on a particular subset of the data. This can be particularly useful if you're experiencing issues with class detection accuracy, as it allows you to validate the model's performance across multiple splits and identify any inconsistencies. If your class is being detected as background or vice versa, K-Fold Cross Validation can help diagnose whether this issue is consistent across different data splits or specific to certain subsets. For more details, you can refer to our guide on K-Fold Cross Validation: https://docs.ultralytics.com/guides/kfold-cross-validation/.
alexander-sony
Good guide, consider adding it in a colab notebook.
In section "Train YOLO using K-Fold Data Splits", model should be re-initialized foe every k, i.e. it should be inside the for-loop: for k in range(ksplit).
- Glenn JocherUltralytics
@alexander-sony thank you for your feedback and suggestion! 😊
You're absolutely right about re-initializing the model within the loop for each fold to ensure a fresh start for every training iteration. This can help avoid any potential carryover effects from previous folds. Here's the corrected code snippet for the training section:
from ultralytics import YOLO

weights_path = "path/to/weights.pt"
results = {}

# Define your additional arguments here
batch = 16
project = "kfold_demo"
epochs = 100

for k in range(ksplit):
    model = YOLO(weights_path, task="detect")  # Re-initialize the model inside the loop
    dataset_yaml = ds_yamls[k]
    model.train(data=dataset_yaml, epochs=epochs, batch=batch, project=project)  # include any train arguments
    results[k] = model.metrics  # save output metrics for further analysis
Regarding your suggestion to add this guide to a Colab notebook, that's a fantastic idea! It would make the process more interactive and accessible for users. We'll consider creating a Colab version of this guide in the future.
For more details on K-Fold Cross Validation, you can refer to our comprehensive guide.
Thanks again for your valuable input! If you have any more suggestions or questions, feel free to share. Happy coding! 🚀
Likhith-Sugganahalli
@alexander-sony
woudnt that be a new model trained on each split, giving us n different models trained on 1/nth of the dataset?
 Fazri Gading
Is there any way to implement Stratified K-Fold Cross Validation with YOLOv8?
- Paula DerrengerUltralytics
Yes, you can implement Stratified K-Fold Cross Validation with YOLOv8! Stratified K-Fold ensures that each fold has a similar distribution of class labels, which can be particularly useful for imbalanced datasets.
To achieve this, you can use
StratifiedKFoldfromsklearn.model_selectioninstead ofKFold. Here's a brief example of how to modify the K-Fold implementation:from sklearn.model_selection import StratifiedKFold # Assuming labels_df is your DataFrame with class counts ksplit = 5 skf = StratifiedKFold(n_splits=ksplit, shuffle=True, random_state=20) # Generate stratified splits kfolds = list(skf.split(labels_df, labels_df.idxmax(axis=1))) # The rest of the process remains the sameFor a detailed guide on K-Fold Cross Validation, please refer to the Ultralytics documentation. If you have any more questions, feel free to ask! 😊
1