Optimizing YOLO26 Inferences with Neural Magic's DeepSparse Engine#
When deploying object detection models like Ultralytics YOLO26 on various hardware, optimizing inference speed can be a challenge. Neural Magic's DeepSparse Engine addresses this on CPUs, using sparsity and quantization to approach GPU-class inference speeds without a GPU.
This guide shows you how to deploy YOLO26 using Neural Magic's DeepSparse, how to run inferences, and also how to benchmark performance to ensure it is optimized.
Neural Magic was acquired by Red Hat in January 2025, and is deprecating the community versions of their deepsparse, sparseml, sparsezoo, and sparsify libraries. For additional information, see the notice posted in the Readme on the sparsify GitHub repository.
Neural Magic's DeepSparse#
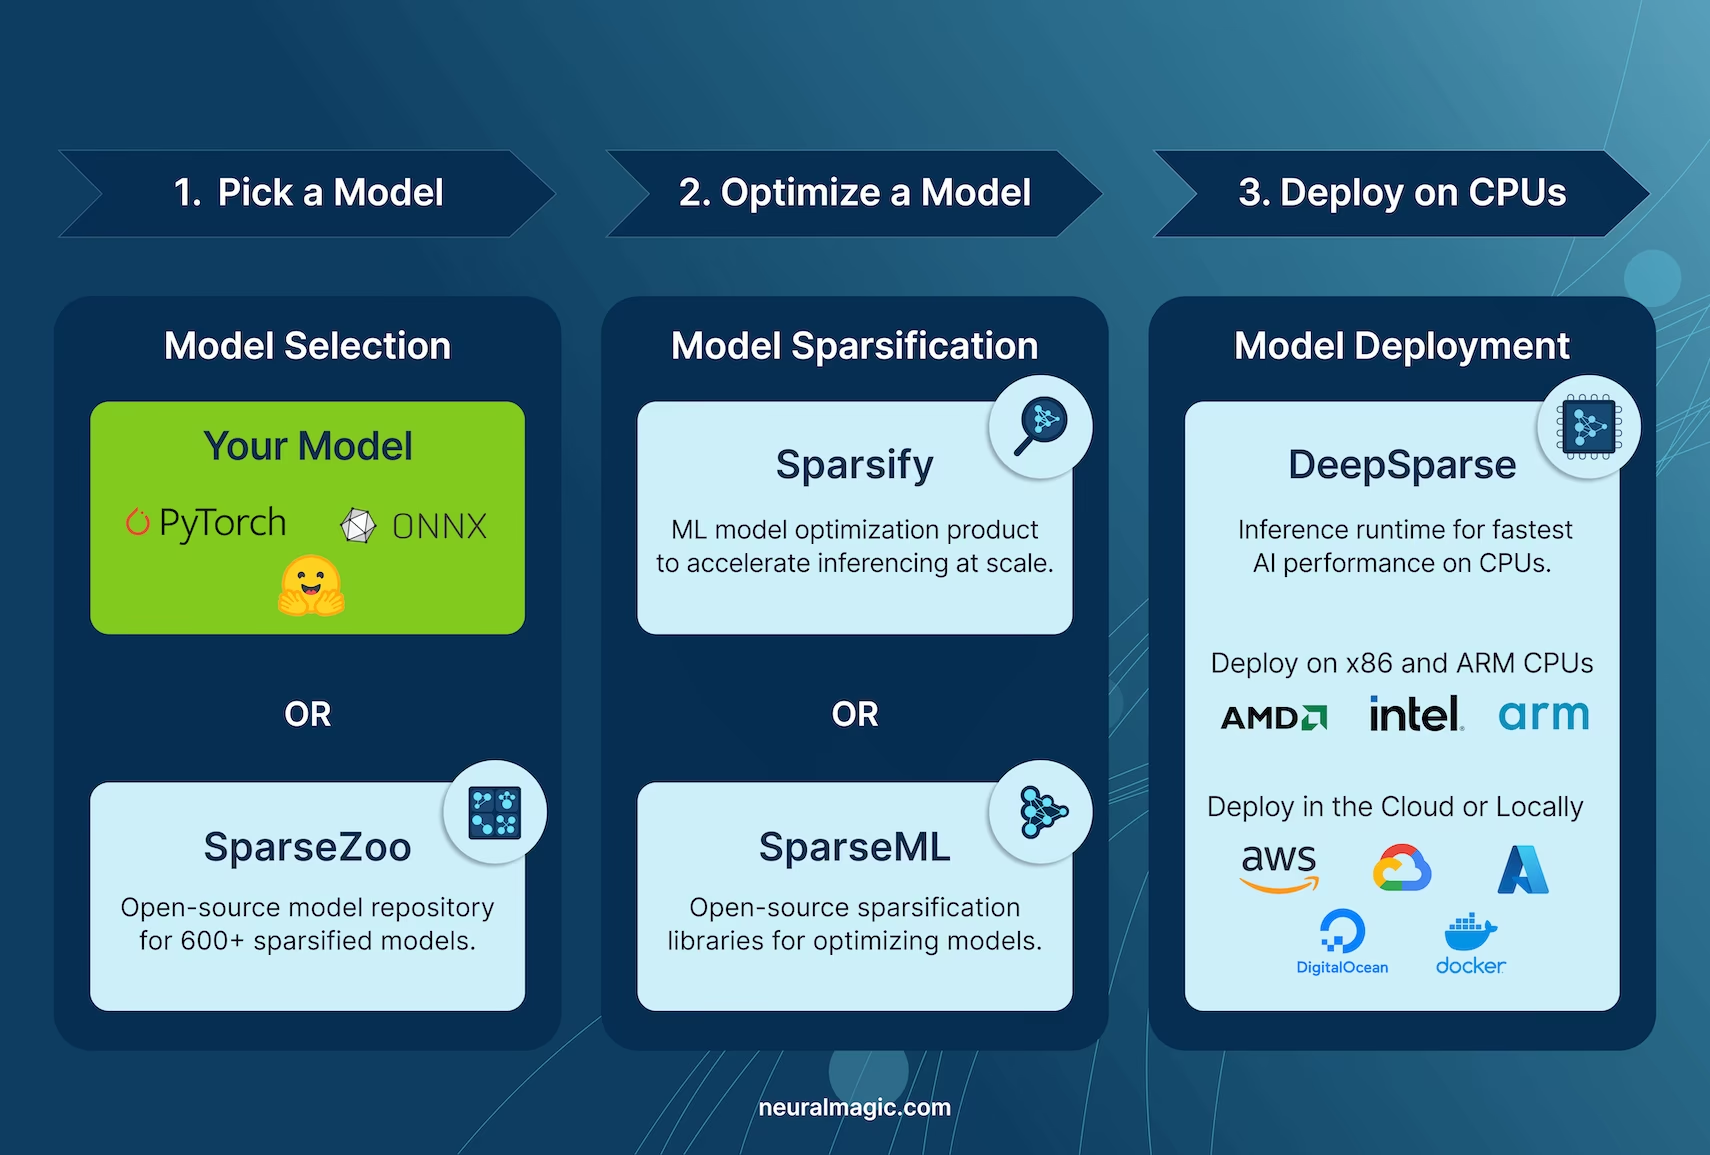
Neural Magic's DeepSparse is an inference runtime designed to optimize the execution of neural networks on CPUs. It applies techniques like sparsity, pruning, and quantization to reduce computational demands while maintaining accuracy, for efficient and scalable neural network execution across various devices.
Benefits of Integrating Neural Magic's DeepSparse with YOLO26#
Key advantages of DeepSparse include:
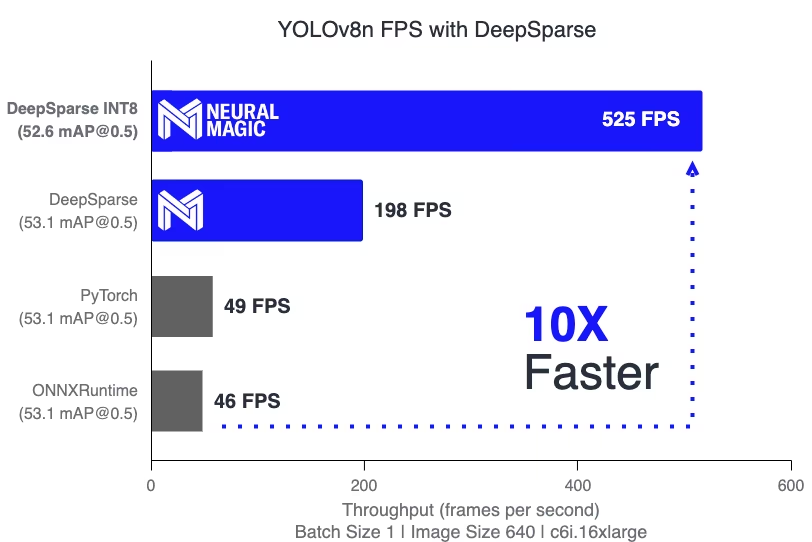
- Enhanced Inference Speed: Neural Magic reports up to 525 FPS on YOLOv8n, significantly faster than standard CPU inference.
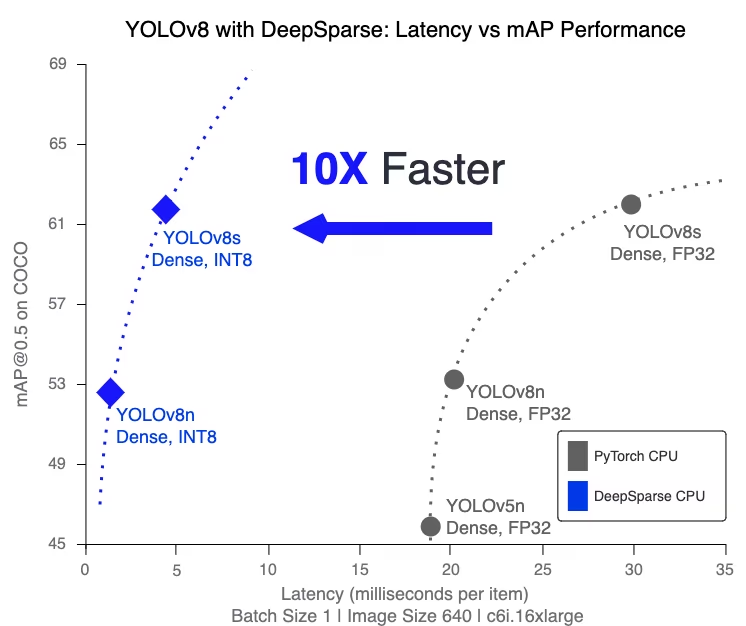
- Optimized Model Efficiency: Uses pruning and quantization to enhance YOLO26's efficiency, reducing model size and computational requirements while maintaining accuracy.
-
High Performance on Standard CPUs: Delivers GPU-like performance on CPUs, a more accessible and cost-effective option for many applications.
-
Streamlined Integration and Deployment: Provides tools for integrating YOLO models into applications, including image and video annotation features.
-
Support for Various Model Types: Compatible with both standard and sparsity-optimized YOLO models, adding deployment flexibility.
-
Cost-Effective and Scalable Solution: Reduces operational expenses and offers scalable deployment of advanced object detection models.
How Does Neural Magic's DeepSparse Technology Work?#
Neural Magic's DeepSparse technology is inspired by the human brain's efficiency in neural network computation. It adopts two key principles from the brain as follows:
-
Sparsity: The process of sparsification involves pruning redundant information from deep learning networks, leading to smaller and faster models with minimal accuracy loss. This technique reduces the network's size and computational needs significantly.
-
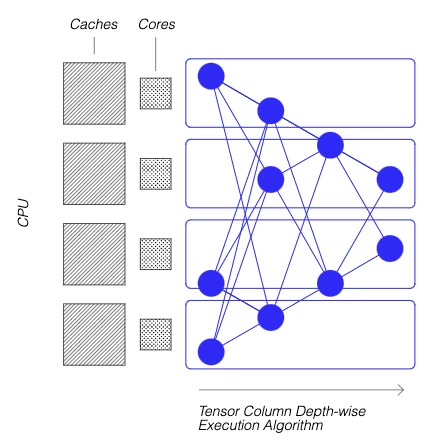
Locality of Reference: DeepSparse uses a unique execution method, breaking the network into Tensor Columns. These columns are executed depth-wise, fitting entirely within the CPU's cache. This approach mimics the brain's efficiency, minimizing data movement and maximizing the CPU's cache use.
Creating A Sparse Version of YOLOv8 Trained on a Custom Dataset#
SparseZoo, an open-source model repository by Neural Magic, offers a collection of pre-sparsified YOLOv8 model checkpoints. With SparseML, which integrates with Ultralytics, users can fine-tune these sparse checkpoints on their own datasets from the command line.
Check out Neural Magic's SparseML YOLOv8 documentation for more details.
Usage: Deploying YOLO26 using DeepSparse#
Deploying YOLO26 with Neural Magic's DeepSparse involves a few steps.
Step 1: Installation#
To install the required packages, run:
# Install the required packages
pip install deepsparse[yolov8]
Step 2: Exporting YOLO26 to ONNX Format#
DeepSparse Engine requires YOLO26 models in ONNX format. Use the following command to export YOLO26 models:
# Export YOLO26 model to ONNX format
yolo detect export model=yolo26n.pt format=onnx opset=13
This command will save the yolo26n.onnx model to your disk.
Step 3: Deploying and Running Inferences#
With your YOLO26 model in ONNX format, you can deploy and run inferences with the DeepSparse Python API:
from deepsparse import Pipeline

# Specify the path to your YOLO26 ONNX model
model_path = "path/to/yolo26n.onnx"

# Set up the DeepSparse Pipeline
yolo_pipeline = Pipeline.create(task="yolov8", model_path=model_path)

# Run the model on your images
images = ["path/to/image.jpg"]
pipeline_outputs = yolo_pipeline(images=images)
Step 4: Benchmarking Performance#
It's important to check that your YOLO26 model is performing optimally on DeepSparse. You can benchmark your model's performance to analyze throughput and latency:
# Benchmark performance
deepsparse.benchmark model_path="path/to/yolo26n.onnx" --scenario=sync --input_shapes="[1,3,640,640]"
Step 5: Additional Features#
DeepSparse provides additional features for practical integration of YOLO26 in applications, such as image annotation and dataset evaluation.
# For image annotation
deepsparse.yolov8.annotate --source "path/to/image.jpg" --model_filepath "path/to/yolo26n.onnx"

# For evaluating model performance on a dataset
deepsparse.yolov8.eval --model_path "path/to/yolo26n.onnx"
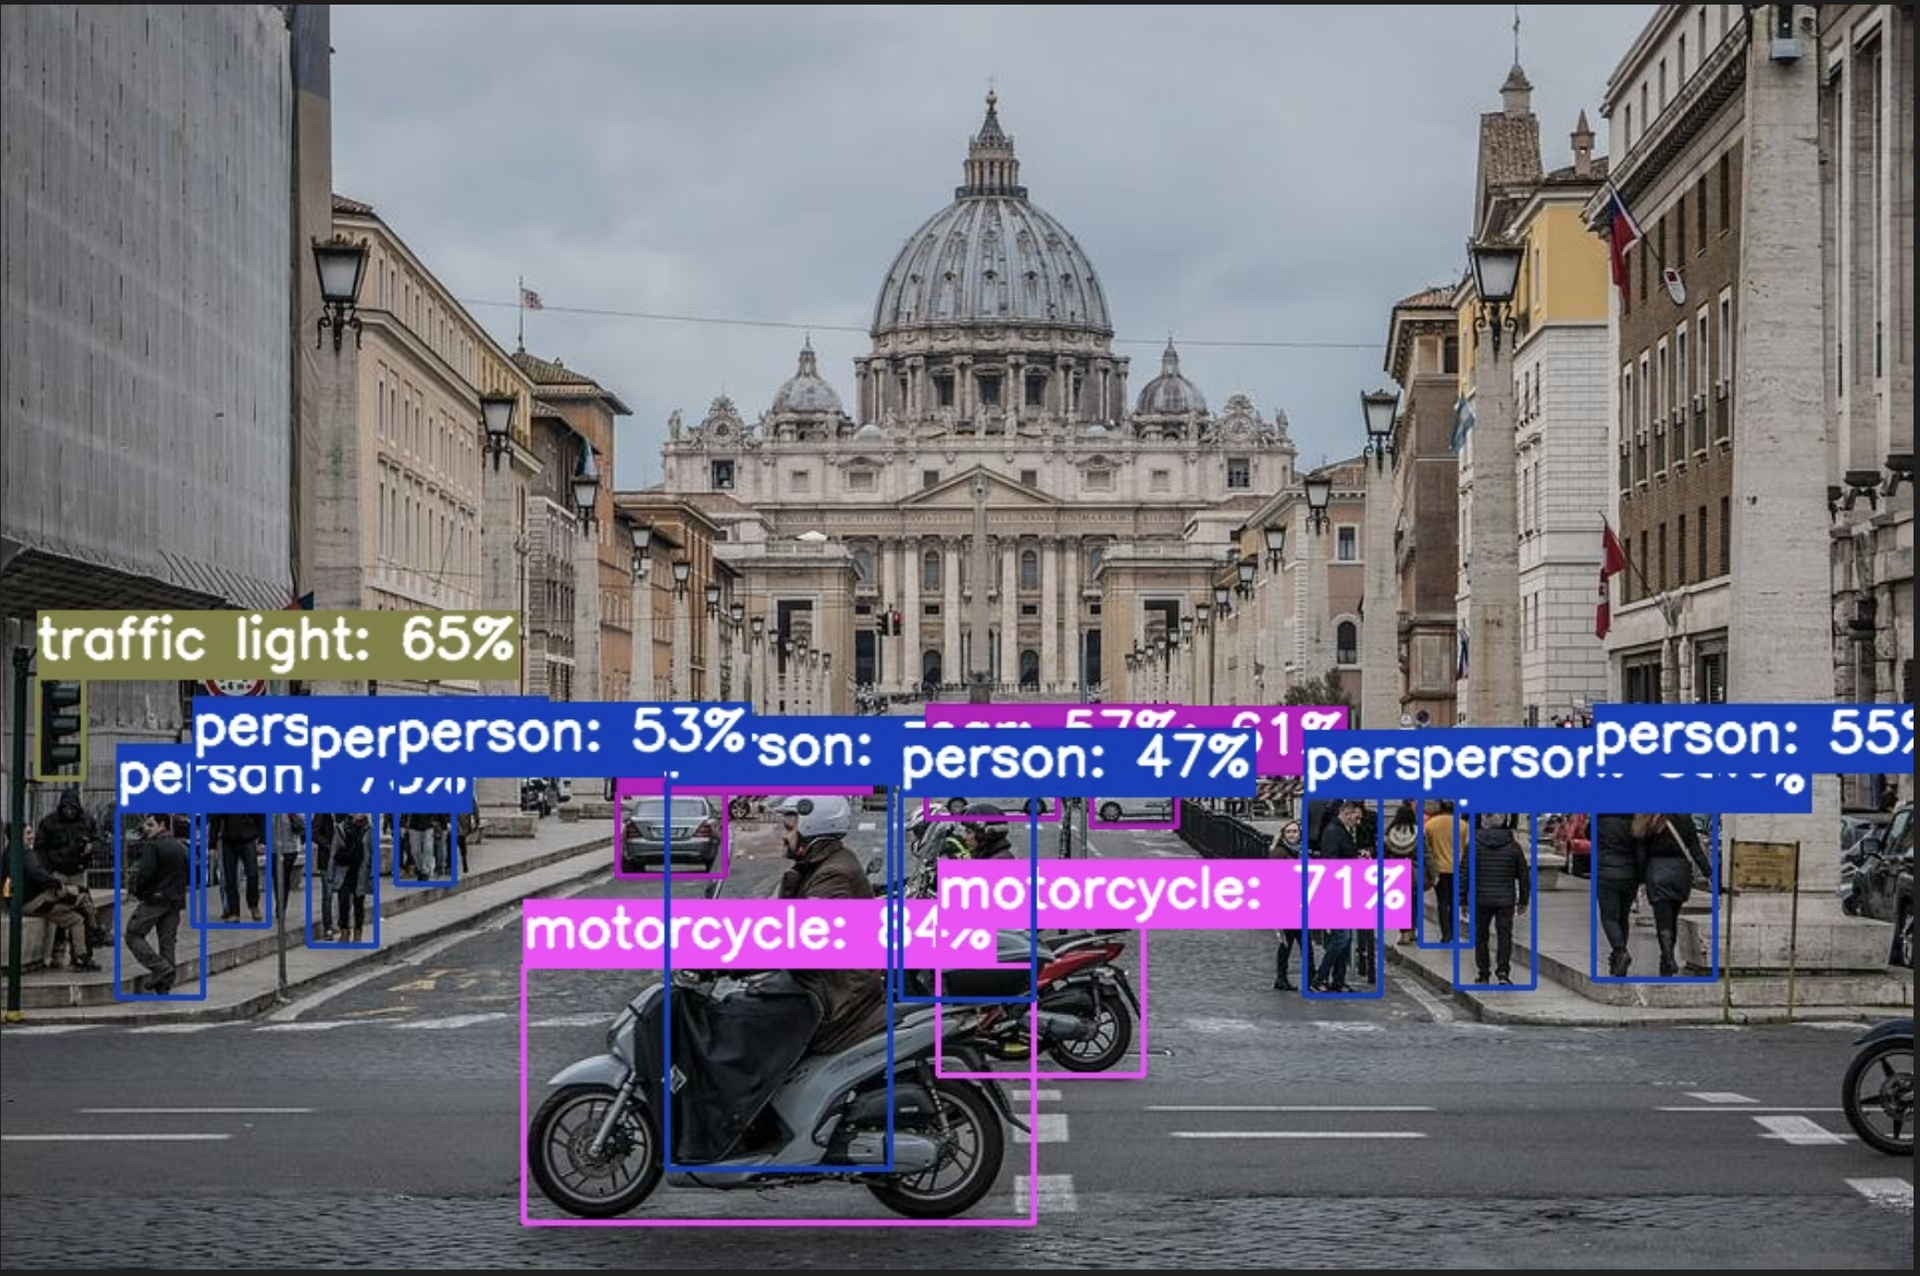
Running the annotate command processes your specified image, detecting objects, and saving the annotated image with bounding boxes and class labels. The annotated image will be stored in an annotation-results folder. This helps provide a visual representation of the model's detection capabilities.
After running the eval command, you will receive detailed output metrics such as precision, recall, and mAP (mean Average Precision). These metrics show how your model performs on the dataset and help guide fine-tuning and optimization for specific use cases.
Summary#
This guide explored integrating Ultralytics YOLO26 with Neural Magic's DeepSparse Engine and how its sparsity techniques speed up inference on CPU platforms.
For more detailed information and advanced usage, visit the DeepSparse repository by Neural Magic. You can also explore the YOLOv8 integration guide and watch a walkthrough session on YouTube.
FAQ#
Neural Magic's DeepSparse Engine is an inference runtime designed to optimize the execution of neural networks on CPUs through advanced techniques such as sparsity, pruning, and quantization. By integrating DeepSparse with YOLO26, you can achieve GPU-like performance on standard CPUs, significantly enhancing inference speed, model efficiency, and overall performance while maintaining accuracy. For more details, check out the Neural Magic's DeepSparse section.
Install the required packages with pip:
pip install deepsparse[yolov8]Once installed, follow the steps provided in the Installation section to set up your environment and start using DeepSparse with YOLO26.
To convert YOLO26 models to the ONNX format, which is required for compatibility with DeepSparse, you can use the following CLI command:
yolo detect export model=yolo26n.pt format=onnx opset=13This command will export your YOLO26 model (
yolo26n.pt) to a format (yolo26n.onnx) that can be used by the DeepSparse Engine.Benchmarking YOLO26 performance on DeepSparse helps you analyze throughput and latency to ensure your model is optimized. You can use the following CLI command to run a benchmark:
deepsparse.benchmark model_path="path/to/yolo26n.onnx" --scenario=sync --input_shapes="[1,3,640,640]"This command reports throughput and latency metrics.
Integrating Neural Magic's DeepSparse with YOLO26 offers several benefits:
- Enhanced Inference Speed: Achieves up to 525 FPS (on YOLOv8n), demonstrating DeepSparse's optimization capabilities.
- Optimized Model Efficiency: Uses sparsity, pruning, and quantization techniques to reduce model size and computational needs while maintaining accuracy.
- High Performance on Standard CPUs: Offers GPU-like performance on cost-effective CPU hardware.
- Streamlined Integration: Tools for deployment and integration.
- Flexibility: Supports both standard and sparsity-optimized YOLO models.
- Cost-Effective: Reduces operational expenses through efficient resource utilization.
For a deeper dive into these advantages, visit the Benefits of Integrating Neural Magic's DeepSparse with YOLO26 section.
Comments12
Ask a question, share your results, or help someone else.
Nithinpbabu
Can I use DeepSparse on Raspberry pi 5? (To process in CPU)
 Glenn JocherUltralytics(edited)
@Nithinpbabu Yes, DeepSparse can work on Raspberry Pi 5 since it's specifically designed for CPU optimization. However, performance will depend on your model size and the Pi's ARM architecture. DeepSparse is particularly effective on x86 CPUs with AVX-512 instructions, so while it will run on the Pi 5, you might not see the same dramatic speedups as on Intel/AMD systems. For the best Pi 5 performance, I'd recommend using a smaller YOLO11 model like YOLO11n exported to ONNX format.
Framecyber
I'm curious that can I use sparseML with the open ai clip model? is there a code or support for this?
- Glenn JocherUltralytics
@Framecyber SparseML primarily focuses on computer vision models including YOLO and ResNet, and I haven't seen specific examples for CLIP models in their documentation. While theoretically possible since SparseML works with PyTorch models, you'd likely need to create custom pruning recipes. I recommend checking Neural Magic's GitHub or reaching out to their team directly for the most current information on CLIP support.
wisrovi
Install the required packages
pip install deepsparse[yolov8]
error: no matches found: deepsparse[yolov8]
contexto
tengo un modelo que he exportado a onnx segun la guia: https://docs.ultralytics.com/es/integrations/onnx/#installation
luego, como la instalacion me fallo segun el error anterior, intente: pip install deepsparse, pero claramente estuvo mal, porque cuando intento importar el modelo:
from deepsparse import Pipeline yolo_pipeline = Pipeline.create( task="yolov8", model_path="mymodel.onnx" )
me da error : 2024-07-23 21:53:45 deepsparse.pipeline WARNING Could not create v2 'yolov8' pipeline, trying legacy File "/home/myuser/anaconda3/lib/python3.11/site-packages/deepsparse/tasks.py", line 129, in check_register_task raise ValueError( ValueError: Unknown Pipeline task yolov8. Currently supported tasks are ['codegen', 'mpt', 'code_gen', 'text_generation', 'code_generation', 'opt', 'image_classification', 'llama'] File "/home/myuser/anaconda3/lib/python3.11/site-packages/deepsparse/yolov8/pipelines.py", line 26, in from ultralytics.yolo.utils.ops import non_max_suppression as non_max_supression_torch ModuleNotFoundError: No module named 'ultralytics.yolo'
donde se evidencia que no instale la version correcta de deepsparse, pero no puedo instalar la versi{on recomendada, no la encuentra
estoy en ubuntu22.04 con intelI5 y una NVIDIA GeForce GTX 1650 Ti,
solicitud
me podrian ayudar, para solucionar el error y poder usar mi modelo onnx con Neural Magic
gracias
 Paula DerrengerUltralytics
@wisrovi gracias por tu mensaje. Parece que el problema radica en la instalación de la versión correcta de DeepSparse. Primero, asegúrate de que estás utilizando la última versión de los paquetes. Puedes intentar instalar DeepSparse con el siguiente comando:
pip install 'deepsparse[yolov8]'Si el problema persiste, verifica que tu entorno de Python esté configurado correctamente y que no haya conflictos con otras dependencias. Además, asegúrate de que tu modelo YOLOv8 esté exportado correctamente a ONNX utilizando el comando:
yolo task=detect mode=export model=yolov8n.pt format=onnx opset=13Para más detalles, puedes consultar la documentación de Neural Magic en este enlace. Si necesitas más ayuda, no dudes en preguntar.
gracias, con eso lo pude instalar, ahora me estoy peleando con la conversion a ONNX porque el archivo se convierte pero no me da rsultados de inferencia cercanos a los resultados antes de la conversion, pero postee este problema en https://docs.ultralytics.com/es/integrations/onnx/#how-can-i-troubleshoot-issues-when-exporting-yolov8-models-to-onnx
- Paula DerrengerUltralytics
@wisrovi gracias por tu comentario. Me alegra saber que la instalación fue exitosa. En cuanto a la conversión a ONNX, es crucial asegurarse de que todos los parámetros y configuraciones sean correctos para mantener la precisión del modelo. Te recomiendo revisar la documentación específica sobre la exportación a ONNX y los posibles problemas que pueden surgir: https://docs.ultralytics.com/es/integrations/onnx/#how-can-i-troubleshoot-issues-when-exporting-yolov8-models-to-onnx. Si el problema persiste, asegúrate de estar utilizando las versiones más recientes de los paquetes. ¡Buena suerte!
Hemilibeatriz
Which version of YOLO was DeepSparse tested on? In version 8.2.2, I'm unable to get it to work
- Glenn JocherUltralytics
Hi there! It seems you're having trouble with DeepSparse on YOLOv8 version 8.2.2. The integration and testing with Neural Magic’s DeepSparse were primarily conducted on earlier versions of YOLOv8. It's possible that there have been changes in version 8.2.2 that affect compatibility.
I recommend checking the version compatibility in the Neural Magic documentation or trying to export and run your model with an earlier version of YOLOv8. If the issue persists, it might be helpful to reach out to Neural Magic's support or check their community forums for more specific guidance.
Here’s a quick example of how you might export your model to ONNX, which is required for DeepSparse:
yolo task=detect mode=export model=yolov8n.pt format=onnx opset=13And then deploy it using DeepSparse:
from deepsparse import Pipeline

# Specify the path to your YOLOv8 ONNX model
model_path = "path/to/yolov8n.onnx"

# Set up the DeepSparse Pipeline
yolo_pipeline = Pipeline.create(task="yolov8", model_path=model_path)

# Run the model on your images
images = ["path/to/image.jpg"]
pipeline_outputs = yolo_pipeline(images=images)
Hope this helps! Let me know if there's anything else you need. 😊
sanvir19
"Can I use DeepSparse on my Jetson Nano Dev Kit? Do I need to convert my YOLO model to TensorRT for that? The blog mentions converting it to ONNX format. Will using DeepSparse make my model run faster on my Jetson?"
- Glenn JocherUltralytics
@sanvir19 hey there! 😊
DeepSparse is designed to optimize neural network execution on CPUs, leveraging techniques like sparsity to enhance performance. While it's great for CPU environments, the Jetson Nano Dev Kit primarily benefits from GPU acceleration.
For your Jetson Nano, converting your YOLO model to TensorRT is indeed the recommended path. TensorRT is specifically designed to optimize deep learning inference on NVIDIA GPUs, including those on Jetson devices. Exporting your model to ONNX is a step in the right direction, as ONNX models can be further converted to TensorRT for deployment on Jetson.
Using DeepSparse could potentially make your model run faster on CPU-based systems, but for Jetson Nano, focusing on TensorRT will leverage the GPU for optimal performance. Here's a quick guide to convert your model to TensorRT:
-
Export your YOLO model to ONNX format:
yolo export model=yolov8n.pt format=onnx -
Use the
onnx2trttool to convert the ONNX model to TensorRT:onnx2trt yolov8n.onnx -o yolov8n.trt
This approach should give you the best inference speed on your Jetson Nano. If you have any more questions or need further assistance, feel free to ask!
-