ONNX Export for YOLO26 Models#
~43% faster CPU ONNX inference: YOLO26n vs YOLO11n
- YOLO26n runs up to 43% faster than YOLO11n on CPU ONNX inference (Intel Xeon CPU @ 2.00 GHz). See the YOLO26 model page for the full comparison.
Often, when deploying computer vision models, you'll need a model format that's both flexible and compatible with multiple platforms.
Exporting Ultralytics YOLO26 models to ONNX format simplifies deployment across many runtimes and hardware platforms. This guide shows how to convert your YOLO26 models to ONNX and run them in real-world applications.
Watch: Ultralytics YOLO26 vs Ultralytics YOLO11 ONNX Inference Test | ~43% Faster Inference with YOLO26 🚀
ONNX and ONNX Runtime#
ONNX, which stands for Open Neural Network Exchange, is a community project that Facebook and Microsoft initially developed. The ongoing development of ONNX is a collaborative effort supported by various organizations like IBM, Amazon (through AWS), and Google. The project aims to create an open file format designed to represent machine learning models in a way that allows them to be used across different AI frameworks and hardware.
ONNX models can be used to move between different frameworks. For instance, a deep learning model trained in PyTorch can be exported to ONNX format and then imported into TensorFlow.
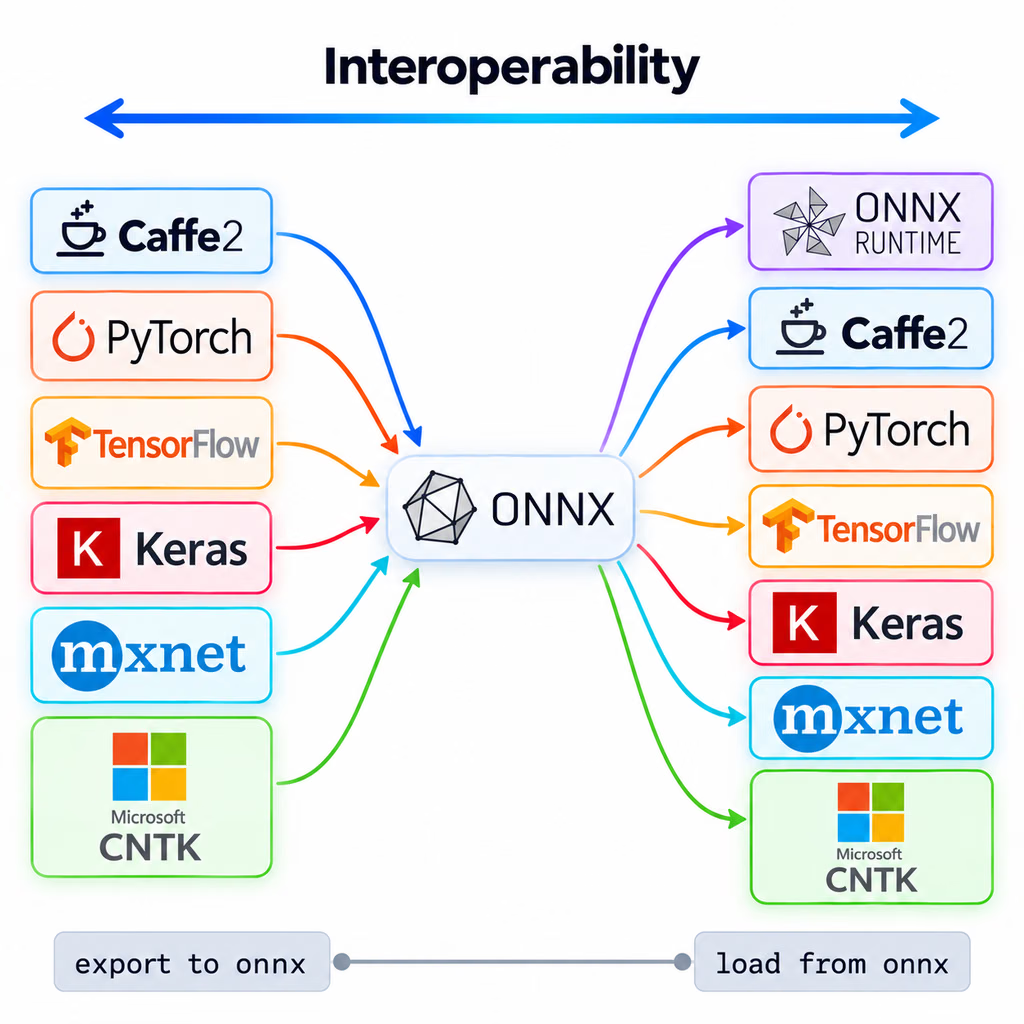
Alternatively, ONNX models can be used with ONNX Runtime. ONNX Runtime is a versatile cross-platform accelerator for machine learning models that is compatible with frameworks like PyTorch, TensorFlow, scikit-learn, etc.
ONNX Runtime optimizes the execution of ONNX models by using hardware-specific capabilities. This optimization allows the models to run efficiently and with high performance on various hardware platforms, including CPUs, GPUs, and specialized accelerators.
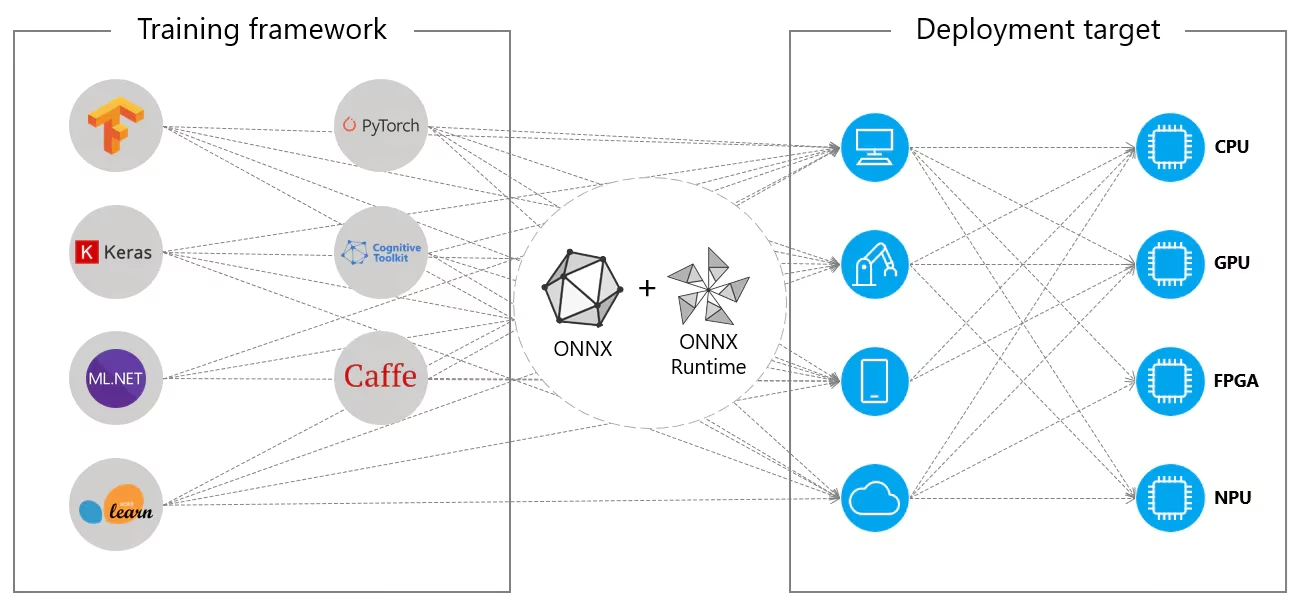
Whether used independently or in tandem with ONNX Runtime, ONNX provides a flexible solution for machine learning model deployment and compatibility.
Key Features of ONNX Models#
The ability of ONNX to handle various formats can be attributed to the following key features:
-
Common Model Representation: ONNX defines a common set of operators (like convolutions, layers, etc.) and a standard data format. When a model is converted to ONNX format, its architecture and weights are translated into this common representation. This uniformity ensures that the model can be understood by any framework that supports ONNX.
-
Versioning and Backward Compatibility: ONNX maintains a versioning system for its operators. This ensures that even as the standard evolves, models created in older versions remain usable. Backward compatibility is a crucial feature that prevents models from becoming obsolete quickly.
-
Graph-based Model Representation: ONNX represents models as computational graphs. This graph-based structure is a universal way of representing machine learning models, where nodes represent operations or computations, and edges represent the tensors flowing between them. This format is easily adaptable to various frameworks which also represent models as graphs.
-
Tools and Ecosystem: There is a rich ecosystem of tools around ONNX that assist in model conversion, visualization, and optimization. These tools make it easier for developers to work with ONNX models and to convert models between different frameworks.
Common Usage of ONNX#
ONNX models are commonly used in the following scenarios.
CPU Deployment#
ONNX models are often deployed on CPUs due to their compatibility with ONNX Runtime. This runtime is optimized for CPU execution. It significantly improves inference speed and makes real-time CPU deployments feasible.
Supported Deployment Options#
While ONNX models are commonly used on CPUs, they can also be deployed on the following platforms:
-
GPU Acceleration: ONNX fully supports GPU acceleration on NVIDIA GPUs through CUDA and on AMD GPUs through ROCm and MIGraphX.
-
Edge and Mobile Devices: ONNX extends to edge and mobile devices, suited to on-device and real-time inference scenarios. It's lightweight and compatible with edge hardware, and serves as the basis for vendor NPU formats such as Huawei Ascend, Qualcomm QNN for Snapdragon devices, and RKNN for Rockchip NPUs.
-
Web Browsers: ONNX can run directly in web browsers, powering interactive and dynamic web-based AI applications.
Supported Tasks#
ONNX export supports all seven Ultralytics tasks. Semantic segmentation and depth estimation are available only with YOLO26, the only family that ships those heads.
Exporting YOLO26 Models to ONNX#
You can expand model compatibility and deployment flexibility by converting YOLO26 models to ONNX format. Ultralytics YOLO26 provides a straightforward export process for running your model across different platforms.
Installation#
To install the required package, run:
# Install the required package for YOLO26
pip install ultralytics
For detailed instructions and best practices related to the installation process, check our YOLO26 Installation guide. While installing the required packages for YOLO26, if you encounter any difficulties, consult our Common Issues guide for solutions and tips.
Usage#
The ONNX format supports the Export, Predict, and Validate modes. Export your model, then load the exported model to run inference or validate its accuracy.
from ultralytics import YOLO

# Load a YOLO26 model
model = YOLO("yolo26n.pt")

# Export the model to ONNX format
model.export(format="onnx")  # creates 'yolo26n.onnx'

# Export an INT8-quantized ONNX model with calibration data
model.export(format="onnx", quantize=8, data="coco8.yaml") # creates 'yolo26n_int8.onnx'from ultralytics import YOLO
# Load the exported ONNX model
model = YOLO("yolo26n.onnx")
# Run inference
results = model("https://ultralytics.com/images/bus.jpg")from ultralytics import YOLO
# Load the exported ONNX model
model = YOLO("yolo26n.onnx")
# Validate accuracy on the COCO8 dataset
metrics = model.val(data="coco8.yaml")Export Arguments#
When exporting your YOLO26 model to ONNX format, you can customize the process using various arguments to optimize for your specific deployment needs:
| Argument | Type | Default | Description |
|---|---|---|---|
format | str | 'onnx' | Target format for the exported model, defining compatibility with various deployment environments. |
imgsz | int or tuple | 640 | Desired image size for the model input. Can be an integer for square images or a tuple (height, width) for specific dimensions. |
quantize | int or str | None | Quantization precision: 16 (FP16) or 8 (INT8 static quantization with ONNX Runtime using calibration images from data, producing an _int8.onnx model); 32/unset is FP32. A checkpoint trained with quantize=8 always exports INT8 as Q/DQ nodes from the ranges it carries, without calibration and under the plain .onnx name. Replaces the deprecated half/int8 flags. |
data | str | None | Dataset YAML used for INT8 calibration; classification instead takes a dataset directory or a built-in dataset name. If omitted with quantize=8, Ultralytics selects the default calibration dataset for the model task; a checkpoint trained with quantize=8 needs none. |
fraction | float, int, or list | 1.0 | Calibration subset as a ratio, image count, or [train, val, test] ratios/counts. Two-item lists leave test full, while 0 skips it. |
dynamic | bool | False | Allows dynamic input sizes, enhancing flexibility in handling varying image dimensions. |
simplify | bool | True | Simplifies the model graph with onnxslim, potentially improving performance and compatibility. |
opset | int | None | Specifies the ONNX opset version for compatibility with different ONNX parsers and runtimes. If not set, uses opset 18 (lower on PyTorch < 2.4), capped at the installed onnx version. |
nms | bool, optional | None | Select raw output (None, default), embedded NMS (True), or the NMS-free head (False). |
batch | int | 1 | Specifies export model batch inference size or the max number of images the exported model will process concurrently in predict mode. |
device | str | None | Specifies the device for exporting: GPU (device=0), CPU (device=cpu), MPS for Apple silicon (device=mps). |
For more details about the export process, visit the Ultralytics documentation page on exporting.
INT8 Quantization#
For checkpoints not trained with quantization-aware training, quantize=8 applies ONNX Runtime static quantization to Conv, Gemm, and MatMul nodes only. All other nodes stay in float, including the ops that assemble output0: box coordinates (pixels) and class scores (0 to 1) share that tensor, so a single INT8 scale for it would round every class score to zero. Exclude the same nodes if you run quantize_static on an exported FP32 model yourself:
import onnx
from onnxruntime.quantization import quantize_static

model = "yolo26n.onnx"
exclude = [n.name for n in onnx.load(model).graph.node if n.op_type not in {"Conv", "Gemm", "MatMul"}]
quantize_static(model, "yolo26n_int8.onnx", calibration_reader, nodes_to_exclude=exclude)
Here calibration_reader is an onnxruntime.quantization.CalibrationDataReader that yields {"images": array} for each calibration image, preprocessed as for inference: letterboxed to the export size, RGB, NCHW, float32 in 0-1.
Deploying Exported YOLO26 ONNX Models#
Once you've successfully exported your Ultralytics YOLO26 models to ONNX format, the next step is deploying these models in various environments. For detailed instructions on deploying your ONNX models, take a look at the following resources:
-
ONNX Runtime Python API Documentation: This guide provides essential information for loading and running ONNX models using ONNX Runtime.
-
Deploying on Edge Devices: Examples of deploying ONNX models on edge devices.
-
ONNX Tutorials on GitHub: A collection of tutorials that cover various aspects of using and implementing ONNX models in different scenarios.
-
Triton Inference Server: Learn how to deploy your ONNX models with NVIDIA's Triton Inference Server for high-performance, scalable deployments.
Windows ML Inference#
On Windows 11 24H2 (build 26100) or newer with Python 3.10+, you can install onnxruntime-windowsml in a separate environment to let Windows ML select execution providers for your hardware. Install it instead of other ONNX Runtime builds, then use the same exported .onnx model with YOLO("model.onnx"). The backend preserves the PyTorch thread count and supplied session options, including an explicit provider policy. Without a supplied policy, Windows ML selects hardware for maximum performance, even when the PyTorch device is cpu. Measure prediction latency on your device before choosing this runtime; it is optional and is not installed by default.
On integrated GPUs that share power with the CPU, idle PyTorch threads in preprocessing and postprocessing can slow Windows ML inference. Call torch.set_num_threads(1) before predicting to reduce this. It applies to the whole process, so other PyTorch models in that process also run on one thread.
import torch

from ultralytics import YOLO

torch.set_num_threads(1)  # optional, measure on your device
results = YOLO("yolo26n.onnx")("https://ultralytics.com/images/bus.jpg")
AMD GPU Inference with MIGraphX#
Ultralytics runs exported ONNX models on AMD GPUs through the ONNX Runtime MIGraphX execution provider. On a ROCm (HIP) system, the ONNX backend installs the onnxruntime-ep-migraphx plugin on first use and selects MIGraphXExecutionProvider automatically with no code changes, and all YOLO26 tasks are supported. See the AMD GPU inference guide for prerequisites, installation, usage, benchmarks, and the compiled-program cache.
Summary#
In this guide, you've learned how to export Ultralytics YOLO26 models to ONNX format to increase their interoperability and performance across various platforms. You were also introduced to the ONNX Runtime and ONNX deployment options.
ONNX export is just one of many export formats supported by Ultralytics YOLO26, allowing you to deploy your models in virtually any environment. Depending on your specific needs, you might also want to explore other export options like TensorRT for maximum GPU performance or CoreML for Apple devices.
For further details on usage, visit the ONNX official documentation.
FAQ#
To export your YOLO26 models to ONNX format using Ultralytics, follow these steps:
Usagefrom ultralytics import YOLO # Load a YOLO26 model model = YOLO("yolo26n.pt") # Export the model to ONNX format model.export(format="onnx") # creates 'yolo26n.onnx' # Load the exported ONNX model onnx_model = YOLO("yolo26n.onnx") # Run inference results = onnx_model("https://ultralytics.com/images/bus.jpg")For more details, visit the export documentation.
Using ONNX Runtime for deploying YOLO26 models offers several advantages:
- Cross-platform compatibility: ONNX Runtime supports various platforms, such as Windows, macOS, and Linux, ensuring your models run smoothly across different environments.
- Hardware acceleration: ONNX Runtime can use hardware-specific optimizations for CPUs, GPUs, and dedicated accelerators, providing high-performance inference.
- Framework interoperability: Models trained in popular frameworks like PyTorch or TensorFlow can be converted to ONNX format and run using ONNX Runtime.
- Performance optimization: ONNX Runtime is often faster than native PyTorch inference on CPU, which helps in deployment scenarios where GPU resources are limited.
Learn more by checking the ONNX Runtime documentation.
YOLO26 models exported to ONNX can be deployed on various platforms including:
- CPUs: Using ONNX Runtime for optimized CPU inference.
- NVIDIA GPUs: Using NVIDIA CUDA for high-performance GPU acceleration.
- AMD GPUs: Using AMD ROCm and the MIGraphX execution provider for high-performance GPU acceleration on Linux.
- Edge devices: Running lightweight models on edge and mobile devices for real-time, on-device inference.
- Web browsers: Executing models directly within web browsers for interactive web-based applications.
- Cloud services: Deploying on cloud platforms that support ONNX format for scalable inference.
For more information, explore our guide on model deployment options.
Using ONNX format for Ultralytics YOLO26 models provides several benefits:
- Interoperability: ONNX allows models to be transferred between different machine learning frameworks.
- Performance Optimization: ONNX Runtime can enhance model performance by utilizing hardware-specific optimizations.
- Flexibility: ONNX supports various deployment environments, enabling you to use the same model on different platforms without modification.
- Standardization: ONNX provides a standardized format that is widely supported across the industry, ensuring long-term compatibility.
When exporting YOLO26 models to ONNX, you might encounter common issues such as mismatched dependencies or unsupported operations. To troubleshoot these problems:
- Verify that you have the correct version of required dependencies installed.
- Check the official ONNX documentation for supported operators and features.
- Review the error messages for clues and consult the Ultralytics Common Issues guide.
- Try using different export arguments like
simplify=Trueor adjusting theopsetversion. - For dynamic input size issues, set
dynamic=Trueduring export.
If issues persist, contact Ultralytics support for further assistance.
Comments77
Ask a question, share your results, or help someone else.
dopeggguy
The parameter "half" bost apperence in train and export, what’s difference. when we using this parameter what should we need attention.
 Glenn JocherUltralytics(edited)
@dopeggguy Good question—summary: training uses mixed precision via
amp=True(weights stay FP32; compute is FP16 where safe), while export usesquantize=16(the formerhalf=True, now deprecated) to write an FP16 model for runtimes that support FP16. During training preferamp; use FP16 only at export/inference, and don't combine it with INT8 (quantize=8). See the train overview and AMP notes in the Train mode docs and thequantizeoption details in Model Export – Arguments and Configuration – Export Settings.from ultralytics import YOLO # Mixed-precision training (recommended) YOLO("yolo26n.yaml").train(data="data.yaml", amp=True) # FP16 export for FP16-capable runtimes (e.g., CUDA/TensorRT/OpenVINO FP16) YOLO("best.pt").export(format="onnx", quantize=16)yoloModel = YOLO(path_dir) yoloModel.export(format='onnx', dynamic=False, half=True, imgsz=(640, 640))
I'm not sure why. I enabled half=True, but the actual size of the exported model doesn't seem to change at all.
- Glenn JocherUltralytics(edited)
@dopeggguy
half=Trueis deprecated in favor ofquantize=16. On older releases a CPU-only ONNX export ignored the flag and stayed FP32, so the file size was almost identical. Current releases convert CPU ONNX exports to FP16 too (keeping float32 inputs/outputs), and GPU exports are FP16 natively. If you have a GPU, you can force export on it and re-check:from ultralytics import YOLO YOLO(path_dir).export(format="onnx", imgsz=(640, 640), dynamic=False, quantize=16, device=0)You can then open the ONNX in Netron or inspect it with the
onnxPython API to confirm the weights arefloat16; for pure CPU deployments it is often better to keep ONNX as FP32 or use a CPU‑oriented backend (e.g. OpenVINO) for FP16/INT8 optimization instead, with some general ONNX background outlined in the ONNX: Open Neural Network Exchange overview.
bastinj98
Hi, I trained d a YOLOV8-segn model to detect and segment a single class (nc=1) and then exported in to onnx (simplify, nms, half are all False) with opset = 17. The output shape is 1x37x8400.
I am building a C++ pipeline to use this model to run inference. How can I process this output to get the final segmentation mask ?
NgZiming
I exported a yolo 11 segment model to onnx format, and used onnx-runtime to infer. It responded two ndarrays of shapes (1, 37, 21504) and (1, 32, 256, 256). (imgsz=1024) So, how can i extract masks from these two arrays?
- Glenn JocherUltralytics
@NgZiming 这两个输出正是分割模型的“检测头 + 原型掩码”:
(1, 37, 21504)=4(xywh) + nc + 32(mask系数),(1, 32, 256, 256)为32个原型;掩码可由原型与对应检测的32维系数线性组合并裁剪到框内,最小示例(Python/NumPy)如下:import numpy as np import cv2 def sigmoid(x): return 1 / (1 + np.exp(-x)) def mask_from_outputs(det, proto, img_h, img_w, det_idx): # det: (1, C, N) -> (C, N), proto: (1, 32, 256, 256) -> (32, 256, 256) det = det[0]; proto = proto[0] nm, ph, pw = proto.shape # 32, 256, 256 nc = det.shape[0] - 4 - nm # 1) 取该检测的框、类别分数与32维掩码系数 cx, cy, w, h = det[0, det_idx], det[1, det_idx], det[2, det_idx], det[3, det_idx] coeff = det[4+nc:4+nc+nm, det_idx] # (32,) # 2) 原型 × 系数 -> 原始掩码 (ph, pw) m = sigmoid((proto.reshape(nm, -1).T @ coeff).reshape(ph, pw)) # 3) 可选:按框在原型分辨率下裁剪(坐标为[0,1]比例) x0 = int(max(0, (cx - w/2) * pw)); x1 = int(min(pw, (cx + w/2) * pw)) y0 = int(max(0, (cy - h/2) * ph)); y1 = int(min(ph, (cy + h/2) * ph)) crop = np.zeros_like(m); crop[y0:y1, x0:x1] = m[y0:y1, x0:x1] # 4) 上采样到原图尺寸并二值化 mask = cv2.resize(crop, (img_w, img_h), interpolation=cv2.INTER_LINEAR) return (mask > 0.5).astype(np.uint8)要点:确保与推理时的预处理一致(letterbox 缩放与填充、RGB/归一化等),否则框与掩码会错位。关于分割导出产生两个输出(
output0检测+系数,output1原型)的由来,可见导出实现参考的export_onnx说明:export_onnx 函数参考.1 thanks
- Glenn JocherUltralytics
Glad it helped—if you later need a C++ reference for segmentation mask decoding and preprocessing alignment, the step-by-step overview is in the Segmentation task docs.
 User
I have a question. If it's convenient, please answer it. Thank you! I'm working with cell images, and the image size is 3072*2048. I trained with imagesize=3072, but if I use imagesize=640, I can't detect objects. I can predict with a 3072 imagesize using a pt file, but now I'm trying to switch to C++ and call onnx, and the 3072 inference is very slow. Is this normal?
denni281
You should keep the same preprocess way between python-inference and cpp-inference.
- Glenn JocherUltralytics
@giter915 Yes—running 3072×2048 through ONNX/C++ will be much slower; inference time grows quickly with input area. Two practical options: use a faster backend or reduce effective input while keeping accuracy. For GPU, prefer TensorRT; for CPU, OpenVINO FP16/INT8 gives the largest gains. Examples:
from ultralytics import YOLO

# GPU-optimized
YOLO("best.pt").export(format="engine", imgsz=1536, half=True, dynamic=True)

# CPU-optimized
YOLO("best.pt").export(format="openvino", imgsz=1536, half=True)  # add int8=True with calibration if desired
If you must keep 3072, tile the image (e.g., 1024×1024 patches), run ONNX per tile, then merge detections with NMS in C++; this is a common approach for microscopy. Also ensure preprocessing in C++ exactly matches Python (letterbox padding, RGB order, 1/255 scaling)—agree with @DennisJcy here. For backend choices and supported export targets, see the export formats table in Object Detection – Ultralytics YOLO Docs, and for high‑throughput GPU serving consider Triton Inference Server with YOLO11.
- User
Thank you very much!
- Glenn JocherUltralytics
Glad it helped—one extra tip for ONNX Runtime C++: enable full graph optimizations and tune threads to squeeze more speed from large inputs like 3072×2048.
#include <onnxruntime_cxx_api.h>
#include <thread>

Ort::Env env(ORT_LOGGING_LEVEL_WARNING, "yolo");
Ort::SessionOptions so;
so.SetGraphOptimizationLevel(GraphOptimizationLevel::ORT_ENABLE_ALL);
so.SetIntraOpNumThreads(std::thread::hardware_concurrency());
so.SetInterOpNumThreads(1);  // often fine to leave at 1

Ort::Session session(env, "best.onnx", so);
Hello, I use ultratics to export YOLO11 half-Precision onnx model, but when I load the .onnx model to eval by onnxruntime, exception shows :Unexpected input data type. Actual: (tensor(float16)) , expected: (tensor(float)). And I compare the Float32 and Float16(half) .onnx model,These two files are exactly the same in size and input type.So the "half" keyword doesn't take effect when exporting ONNX, right? I remember Ultralytics didn't have this issue last year.
Here is my python script to export half-precision onnx model:
def main(opt): model = YOLO(opt.model) model.export( format="onnx", # opset=12, simplify=True, dynamic=False, imgsz=opt.imgsz, half=opt.half, batch=opt.batch, ) if __name__ == "__main__": multiprocessing.freeze_support() parser = argparse.ArgumentParser() parser.add_argument( "--model", type=str, default="/home/ultralytics/runs/detect/SHFY/weights/best.pt", ) parser.add_argument("--imgsz", type=int, default=640) parser.add_argument("--half", type=bool, default=True) parser.add_argument("--batch", type=int, default=1) opt, unparsed = parser.parse_known_args() print(opt) main(opt)Fine... It's my fault. My docker environment is Python-3.11.9 torch-2.4.1+cu118 CPU (unknown). The error is made by my cpu environment
- Glenn JocherUltralytics(edited)
@DennisJcy thanks for the update. On older releases
half=Truehad no effect on CPU ONNX exports, so the file stayed FP32. Current Ultralytics usesquantize=16(replacing the deprecatedhalf) and also converts CPU ONNX exports to FP16 while keeping float32 inputs/outputs, whereas GPU exports (device=0) are FP16 natively and need an FP16-capable ONNX Runtime provider. For CPU-optimized FP16 you can also export OpenVINO. For example:from ultralytics import YOLO # FP16 ONNX YOLO("best.pt").export(format="onnx", quantize=16) # CPU-optimized FP16 (OpenVINO) YOLO("best.pt").export(format="openvino", quantize=16)Details on OpenVINO export are in the export_openvino reference.
ShuaibZyx
def yolo_to_onnx(model_path, input_shape=(600, 600)): # Load the YOLOv8 model model = YOLO(model_path)
# Export the model to ONNX format
model.export(format='onnx',
             imgsz=input_shape,
             dynamic=True,
             batch=1,
             device="0")
Ultralytics YOLOv8.0.220 🚀 Python-3.9.18 torch-2.1.1+cu121 CUDA:0 (Tesla T4, 14931MiB) Model summary (fused): 268 layers, 43610463 parameters, 0 gradients, 164.8 GFLOPs
PyTorch: starting from 'best.pt' with input shape (1, 3, 640, 640) BCHW and output shape(s) (1, 9, 8400) (83.6 MB)
ONNX: starting export with onnx 1.18.0 opset 17... ONNX: export success ✅ 3.3s, saved as 'best.onnx' (166.5 MB) 我的模型在训练时是5个类别的目标检测,导出的模型的输出格式是(1, 9, 8400)。 我想请问您其中9具体代表的是什么呢? 如果是为了预测5个类别(1, 9, 8400)的输出格式是正确的嘛? 期待您的帮助!感谢!
xiaoqiang-l
9指的是:[x,y,w,h,class1_scores,class2_scores,class3_scores,class4_scores,class5_scores],即四个坐标及N个类别分数。 8400指的是:640下采样8倍、16倍、32倍特征图的anchor总数,(640/8)(640/8)+(640/16)(640/16)+(640/32)(640/32)=8080+4040+2020=8400
感谢您的指导!
- Glenn JocherUltralytics
@ShuaibZyx you're welcome! @xiaoqiang-l provided an excellent explanation. Just to confirm, the output shape (1, 9, 8400) is indeed correct for your 5-class detection model - the 9 channels represent the 4 bounding box coordinates (x, y, w, h) plus 5 class confidence scores. The 8400 represents all detection anchors across the three feature map scales (80×80 + 40×40 + 20×20 = 8400 total anchors).
UltralyticsAssistantUltralytics
👋 Hello, thank you for your interest in Ultralytics 🚀! We recommend a visit to the Docs for new users where you can find many Python and CLI usage examples, as well as detailed guides about exporting YOLO models to ONNX and other formats.
If this is a 🐛 Bug Report, please provide a minimum reproducible example to help us debug it.
If you have a custom training ❓ Question or require help with ONNX export, please include as much detail as possible—such as your command, model version, logs, and environment details. Also, check out our Tips for Best Training Results for optimal performance.
Join the Ultralytics community where it suits you best! For real-time chat, head to Discord 🎧. For in-depth discussions, try Discourse, or join the conversation on our Subreddit.
Upgrade
Upgrade to the latest
ultralyticspackage including all requirements in a Python>=3.8 environment with PyTorch>=1.8 to ensure you’re using the most up-to-date features and bug fixes:pip install -U ultralyticsEnvironments
YOLO can be run in these up-to-date verified environments, with all dependencies including CUDA/CUDNN, Python, and PyTorch preinstalled:
- Notebooks with free GPU:


- Google Cloud Deep Learning VM. See GCP Quickstart Guide
- Amazon Deep Learning AMI. See AWS Quickstart Guide
- Docker Image. See Docker Quickstart Guide
Status

If this badge is green, all Ultralytics CI tests are currently passing. CI tests verify correct operation of all YOLO Modes and Tasks on macOS, Windows, and Ubuntu every 24 hours and on every commit.
This is an automated response 🤖. An Ultralytics engineer will review your discussion and assist you soon!
- Glenn JocherUltralytics
Hello! Thanks for your interest in exporting YOLO11 models to ONNX format. This is a great option for deployment across different platforms with performance benefits.
Exporting to ONNX is straightforward with Ultralytics:
from ultralytics import YOLO

# Load model
model = YOLO("yolo11n.pt")  # or your custom trained model

# Export to ONNX with optional parameters
model.export(format="onnx", dynamic=True, simplify=True)  # creates 'yolo11n.onnx'

# Use the exported model
onnx_model = YOLO("yolo11n.onnx")
results = onnx_model("https://ultralytics.com/images/bus.jpg")
ONNX export can provide up to 3x CPU speedup compared to PyTorch models. You can customize the export with several parameters like
half=Truefor FP16 precision,dynamic=Truefor variable input sizes, oropsetto specify the ONNX version.For deployment, you can use ONNX Runtime or integrate with platforms like NVIDIA Triton Inference Server for production-scale serving.
If you have specific questions about exporting your models or encounter any issues during the process, please let us know!
- Notebooks with free GPU:
👋 Hello, thank you for your interest in Ultralytics 🚀! For users exploring ONNX integration and YOLO11, we recommend checking out the Docs where you’ll find dedicated Python and CLI tutorials, as well as specific ONNX integration guidance.
If this is a 🐛 Bug Report, please provide a minimum reproducible example to help us investigate further.
For custom deployment or export ❓ questions, please include as many details as possible, such as your export commands, model versions, and error logs. Make sure you review our Tips for Best Training Results for optimal performance.
Join the Ultralytics community where it suits you best: jump into real-time conversations on Discord 🎧, post or search on Discourse, or connect on our Subreddit.
Upgrade
Upgrade to the latest
ultralyticspackage, including all requirements, in a Python>=3.8 environment with PyTorch>=1.8 to ensure you have the latest features and fixes:pip install -U ultralyticsEnvironments
YOLO can be run in any of the following up-to-date verified environments (with all dependencies including CUDA/CUDNN, Python and PyTorch preinstalled):
- Notebooks with free GPU:
- Google Cloud Deep Learning VM. See GCP Quickstart Guide
- Amazon Deep Learning AMI. See AWS Quickstart Guide
- Docker Image. See Docker Quickstart Guide
Status
If this badge is green, all Ultralytics CI tests are currently passing. CI tests verify correct operation of all YOLO Modes and Tasks on macOS, Windows, and Ubuntu every 24 hours and on every commit.
This is an automated response. An Ultralytics engineer will assist you here soon!
- Glenn JocherUltralytics
Yes, you can adjust the batch size dynamically when exporting to ONNX format by using the
dynamic=Trueparameter in your export call. When this is enabled, the batch dimension becomes dynamic, allowing you to use various batch sizes during inference without reexporting the model.Here's a simple example:
from ultralytics import YOLO

# Load your model
model = YOLO("yolo11n.pt")

# Export with dynamic input size
model.export(format="onnx", dynamic=True)
This creates dynamic dimensions in the exported ONNX model, where the batch dimension (as well as height and width) can vary during inference. The resulting model will be more flexible for production deployments where batch size requirements might change.
- Notebooks with free GPU:
skyceeee
First of all, thank you for everything. Can we adjust the batch size dynamically when exporting the model as onnx?
When I export the YOLOV11 onnx model, I use: model.export(format='onnx', imgsz=640, device='cpu'). Then I use onnxruntime (1.14.0) to deploy it on the C++ side, but an error is reported during runtime: onnxruntime::Model::Model Unsupported model IR version: 9, max supported IR version: 8. Is there any parameter or method to set the exported model to support IR version: 8? Because I cannot upgrade onnxruntime to other higher versions locally, I look forward to your help
- Glenn JocherUltralytics
@xiaoqiang-l to resolve the ONNX IR version compatibility issue, you can specify an older
opsetversion during export. Try addingopset=13to your export command:model.export(format='onnx', imgsz=640, device='cpu', opset=13)This will generate an ONNX model compatible with IR version 8. For detailed version mapping, see the ONNX operator version matrix in the ONNX documentation.
