YOLO12: 어텐션 중심 객체 탐지
개요#
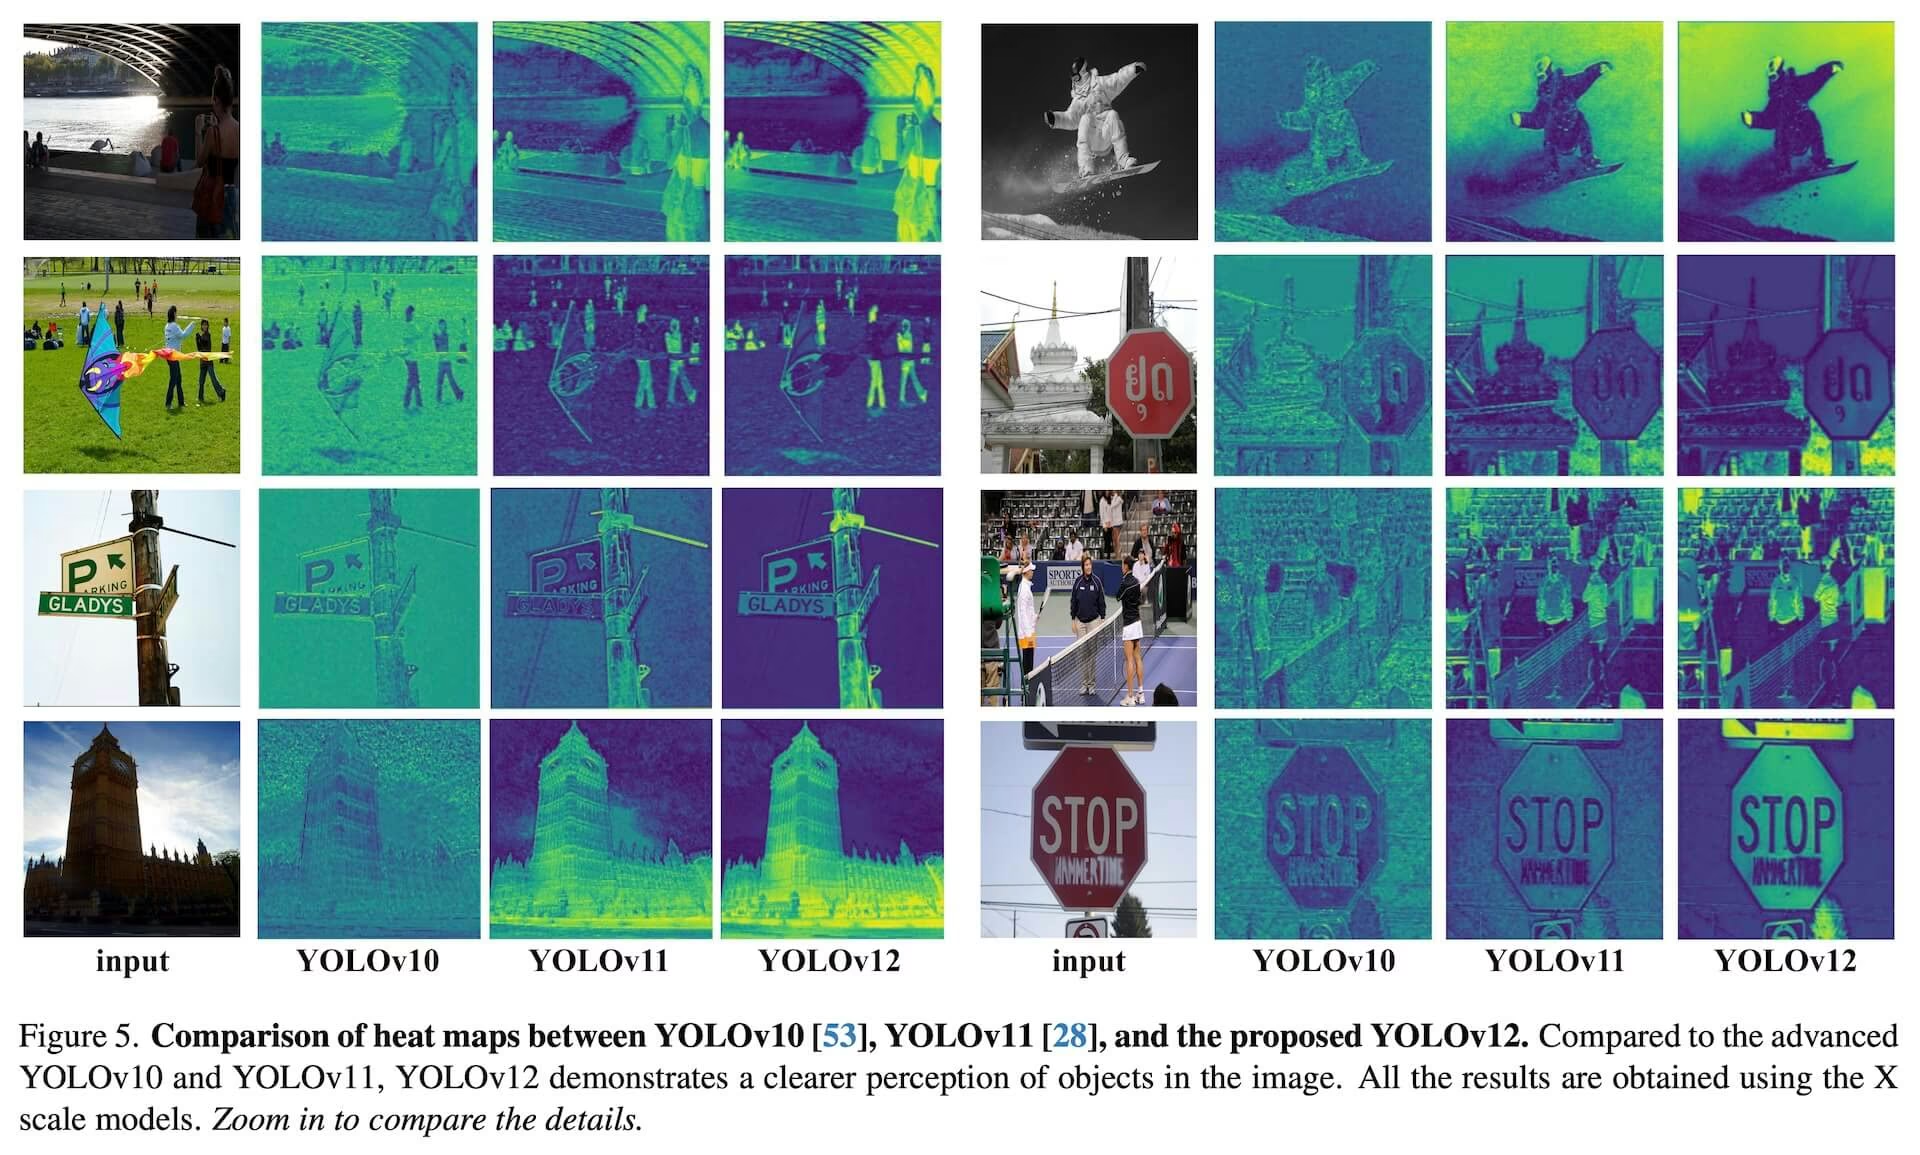
2025년 초에 출시된 YOLO12는 기존 YOLO 모델에서 사용하던 전통적인 CNN 기반 접근 방식에서 벗어나 어텐션 중심 아키텍처를 도입하면서도 여러 애플리케이션에 필수적인 실시간 추론 속도를 유지합니다. 어텐션 메커니즘과 전체 네트워크 아키텍처를 변경해 높은 객체 탐지 정확도를 달성합니다. 이러한 장점에도 불구하고 YOLO12는 커뮤니티 주도로 출시된 모델로, 과도한 어텐션 블록으로 인해 학습이 불안정하고 메모리 사용량이 증가하며 CPU 처리량이 저하될 수 있습니다. 따라서 Ultralytics는 대부분의 프로덕션 워크로드에 YOLO11 또는 YOLO26을 권장합니다.
YOLO12는 주로 벤치마킹과 연구 목적으로 유지 관리됩니다. 안정적인 학습, 예측 가능한 메모리 사용량, 최적화된 CPU 추론이 필요하다면 배포에 YOLO11 또는 YOLO26을 선택하세요.
시청: Ultralytics 패키지로 객체 탐지에 YOLO12를 사용하는 방법 | YOLO12는 빠를까요, 느릴까요?
주요 기능#
- 영역 어텐션 메커니즘: 넓은 수용 영역을 효율적으로 처리하는 새로운 셀프 어텐션 접근 방식입니다. 특징 맵을 가로 또는 세로 방향으로 동일한 크기의 l개 영역(기본값은 4개)으로 나누어 복잡한 연산을 피하면서 넓은 유효 수용 영역을 유지합니다. 이를 통해 표준 셀프 어텐션보다 계산 비용을 크게 줄입니다.
- 잔차 효율적 계층 집계 네트워크(R-ELAN): ELAN을 기반으로 개선한 특징 집계 모듈로, 특히 대규모 어텐션 중심 모델의 최적화 문제를 해결하도록 설계되었습니다. R-ELAN은 다음을 도입합니다.
- 스케일링을 적용한 블록 수준 잔차 연결(레이어 스케일링과 유사).
- 병목 구조를 형성하는 새롭게 설계된 특징 집계 방식.
- 최적화된 어텐션 아키텍처: YOLO12는 표준 어텐션 메커니즘을 간소화하여 효율성과 YOLO 프레임워크와의 호환성을 높입니다. 여기에는 다음이 포함됩니다.
- 메모리 액세스 오버헤드를 최소화하기 위해 FlashAttention을 사용합니다.
- 모델을 더 간결하고 빠르게 만들기 위해 위치 인코딩 제거.
- 어텐션 계층과 피드포워드 계층 간 연산 균형을 더 효과적으로 맞추기 위해 MLP 비율을 일반적인 4에서 1.2 또는 2로 조정.
- 최적화를 개선하기 위해 스택 블록의 깊이를 줄임.
- 계산 효율이 높은 경우 컨볼루션 연산을 사용합니다.
- 위치 정보를 암묵적으로 인코딩하기 위해 어텐션 메커니즘에 7x7 분리형 컨볼루션("position perceiver") 추가.
- 폭넓은 작업 지원: YOLO12는 객체 탐지, 인스턴스 분할, 이미지 분류, 포즈 추정, 방향성 객체 탐지(OBB) 등 다양한 핵심 컴퓨터 비전 작업을 지원합니다.
- 향상된 효율성: 이전의 여러 모델보다 적은 파라미터로 더 높은 정확도를 달성하여 속도와 정확도 간 균형이 개선되었습니다.
- 유연한 배포: 엣지 디바이스부터 클라우드 인프라까지 다양한 플랫폼에 배포할 수 있도록 설계되었습니다.
지원 작업 및 모드#
YOLO12는 다양한 컴퓨터 비전 작업을 지원합니다. 아래 표는 각 작업의 지원 여부와 사용 가능한 운영 모드(학습, 검증, 추론, 내보내기)를 보여줍니다:
탐지 가중치(yolo12n.pt, yolo12s.pt, yolo12m.pt, yolo12l.pt, yolo12x.pt)만 ultralytics/assets에서 공개합니다. 분할, 분류, 포즈, OBB 아키텍처는 ultralytics/cfg/models/12/에 정의되어 있으므로, 해당 변형 모델은 .yaml 설정으로 처음부터 학습할 수 있지만 현재 사전 학습된 .pt 파일은 제공되지 않습니다. 사전 학습된 분할, 포즈, 분류 또는 OBB 체크포인트가 필요하다면 YOLO11 또는 YOLO26을 권장합니다.
| 모델 유형 | 작업 | 사전 학습 가중치 | 학습 | 검증 | 추론 | 내보내기 |
|---|---|---|---|---|---|---|
| YOLO12 | 감지 | ✅ | ✅ | ✅ | ✅ | ✅ |
| YOLO12-seg | 분할 | ❌ | ✅ | ✅ | ✅ | ✅ |
| YOLO12-cls | 분류 | ❌ | ✅ | ✅ | ✅ | ✅ |
| YOLO12-pose | 포즈 | ❌ | ✅ | ✅ | ✅ | ✅ |
| YOLO12-obb | OBB | ❌ | ✅ | ✅ | ✅ | ✅ |
학습된 체크포인트가 있으면 모든 YOLO12 아키텍처에서 모든 모드를 사용할 수 있습니다. Pretrained Weights 열은 Ultralytics가 ultralytics/assets에 공식 사전 학습 .pt을 공개하는지 여부만 나타냅니다. 분할, 포즈, 분류, OBB의 경우 추론, 검증 또는 내보내기를 실행하기 전에 해당 .yaml에서 자체 체크포인트를 학습해야 합니다.
성능 지표#
YOLO12는 모든 모델 크기에서 정확도를 향상했으며, 이전 YOLO 모델 중 가장 빠른 모델과 비교하면 속도에서 일부 절충이 있습니다. 아래는 COCO 검증 데이터셋에서 객체 탐지를 수행한 정량적 결과입니다:
탐지 성능(COCO val2017)#
| 모델 | 크기 (픽셀) | mAPval50-95 | 속도 CPU ONNX (ms) | 속도 T4 TensorRT (ms) | 파라미터 (M) | FLOPs (B) | 비교 (mAP/속도) |
|---|---|---|---|---|---|---|---|
| YOLO12n | 640 | 40.6 | - | 1.64 | 2.6 | 7.5 | +2.1%/-9% (YOLOv10n 대비) |
| YOLO12s | 640 | 48.0 | - | 2.61 | 9.3 | 23.3 | +0.1%/+42% (RT-DETRv2 대비) |
| YOLO12m | 640 | 52.5 | - | 4.86 | 20.2 | 70.7 | +1.0%/-3% (YOLO11m 대비) |
| YOLO12l | 640 | 53.7 | - | 6.77 | 26.4 | 95.4 | +0.4%/-8% (YOLO11l 대비) |
| YOLO12x | 640 | 55.2 | - | 11.79 | 59.1 | 208.9 | +0.6%/-4% (YOLO11x 대비) |
- NVIDIA T4 GPU에서 TensorRT FP16 정밀도로 측정한 추론 속도입니다.
- 비교 결과는 mAP의 상대적 개선율과 속도의 변화율을 나타냅니다(양수는 더 빠름, 음수는 더 느림). 비교 대상은 공개된 결과가 있는 경우 YOLOv10, YOLO11, RT-DETR입니다.
사용 예시#
이 섹션에서는 YOLO12의 학습 및 추론 예제를 제공합니다.
아래 예제는 YOLO12 탐지 모델(객체 탐지용)에 중점을 둡니다. 분할, 분류, 포즈 추정, 방향성 객체 탐지 등 다른 지원 작업은 각 작업의 문서인 분할, 분류, 포즈, OBB를 참조하세요.
사전 학습된 *.pt 모델(PyTorch 사용)과 설정 *.yaml 파일을 YOLO() 클래스에 전달하면 Python에서 모델 인스턴스를 생성할 수 있습니다.
from ultralytics import YOLO

# COCO 사전 학습 YOLO12n 모델 로드
model = YOLO("yolo12n.pt")

# COCO8 예제 데이터셋으로 100 에포크 동안 모델 학습
results = model.train(data="coco8.yaml", epochs=100, imgsz=640)

# 'bus.jpg' 이미지로 YOLO12n 모델 추론 실행
results = model("path/to/bus.jpg")
주요 개선 사항#
-
향상된 특징 추출:
- 영역 어텐션: 넓은 수용 영역을 효율적으로 처리해 계산 비용을 줄입니다.
- 균형 최적화: 어텐션 연산과 피드포워드 네트워크 연산 간 균형을 개선했습니다.
- R-ELAN: R-ELAN 아키텍처를 사용해 특징 집계를 개선합니다.
-
최적화 혁신:
- 잔차 연결: 특히 대규모 모델에서 학습을 안정화하기 위해 스케일링을 적용한 잔차 연결을 도입합니다.
- 개선된 특징 통합: R-ELAN 내부의 특징 통합 방식을 개선했습니다.
- FlashAttention: 메모리 액세스 오버헤드를 줄이기 위해 FlashAttention을 적용합니다.
-
아키텍처 효율성:
- 파라미터 감소: 이전의 여러 모델보다 파라미터 수를 줄이면서 정확도를 유지하거나 개선합니다.
- 간소화된 어텐션: 위치 인코딩을 사용하지 않는 간소화된 어텐션 구현을 사용합니다.
- 최적화된 MLP 비율: 연산 리소스를 더 효과적으로 배분하도록 MLP 비율을 조정합니다.
요구 사항#
Ultralytics YOLO12 구현은 기본적으로 FlashAttention을 필요로 하지 않습니다. 하지만 FlashAttention을 선택적으로 컴파일하여 YOLO12와 함께 사용할 수 있습니다. FlashAttention을 컴파일하려면 다음 NVIDIA GPU 중 하나가 필요합니다.
- Turing GPU(예: T4, Quadro RTX 시리즈)
- Ampere GPU(예: RTX30 시리즈, A30/40/100)
- Ada Lovelace GPU(예: RTX40 시리즈)
- Hopper GPU (예: H100/H200)
인용 및 감사의 글#
연구에서 YOLO12를 사용하신다면 University at Buffalo와 University of Chinese Academy of Sciences의 원저를 인용해 주세요:
@inproceedings{tian2025yolov12,
  title={YOLOv12: Attention-Centric Real-Time Object Detectors},
  author={Tian, Yunjie and Ye, Qixiang and Doermann, David},
  booktitle={Advances in Neural Information Processing Systems},
  volume={38},
  pages={78433--78457},
  year={2025},
  url={https://proceedings.neurips.cc/paper_files/paper/2025/file/7103444259031cc58051f8c9a4868533-Paper-Conference.pdf}
}

@software{yolo12,
  author = {Tian, Yunjie and Ye, Qixiang and Doermann, David},
  title = {YOLO12: Attention-Centric Real-Time Object Detectors},
  year = {2025},
  url = {https://github.com/sunsmarterjie/yolov12},
  license = {AGPL-3.0}
}
YOLO12 논문은 NeurIPS 2025 proceedings에 게재되었으며, arXiv에 프리프린트가 게시되어 있습니다.
자주 묻는 질문#
YOLO12는 속도와 정확도의 균형을 맞추기 위해 몇 가지 핵심 혁신을 적용합니다. 영역 어텐션 메커니즘은 넓은 수용 영역을 효율적으로 처리해 표준 셀프 어텐션보다 계산 비용을 줄입니다. 잔차 효율적 계층 집계 네트워크(Residual Efficient Layer Aggregation Networks, R-ELAN)는 특징 집계를 개선하여 대규모 어텐션 중심 모델의 최적화 문제를 해결합니다. FlashAttention 사용과 위치 인코딩 제거를 포함한 최적화된 어텐션 아키텍처는 효율성을 한층 높입니다. 이러한 기능을 통해 YOLO12는 여러 애플리케이션에 필요한 실시간 추론 속도를 유지하면서 높은 정확도를 달성합니다.
기본적으로 Ultralytics YOLO12 구현에는 FlashAttention이 필요하지 않습니다. 그러나 메모리 액세스 오버헤드를 최소화하기 위해 FlashAttention을 선택적으로 컴파일해 YOLO12에서 사용할 수 있습니다. FlashAttention을 컴파일하려면 다음 NVIDIA GPU 중 하나가 필요합니다. Turing GPU(예: T4, Quadro RTX 시리즈), Ampere GPU(예: RTX30 시리즈, A30/40/100), Ada Lovelace GPU(예: RTX40 시리즈) 또는 Hopper GPU(예: H100/H200)입니다. 이를 통해 하드웨어가 지원하는 경우 FlashAttention의 이점을 활용할 수 있습니다.


댓글69
질문을 하거나 결과를 공유하거나 다른 사람을 도와주세요.
Zixuan-He
I try use the YOLO12-seg, but with update to lastest version (> pip install -U ultralytics) it is still showing (No such file or directory: 'YOLO12n-seg.pt) with code (yolo segment train data=data.yaml model=YOLO12n-seg.pt epochs=200 batch=16 imgsz=640 patience=25 ). theYOLO12n.pt for obj is good. Is the code changed or need other input?
1 Glenn JocherUltralytics
@Zixuan-He Answer:
The YOLO12-seg model requires using its specific configuration file. Trymodel=yolo12-seg.yamlinstead of the.ptfile to initialize training. The segmentation weights are not yet released as pretrained.ptfiles, but you can train from scratch using the YAML configuration. For details, see the YOLO12-seg documentation.2LucasGenoud
Hello, thank you for your answer ! Do you have any date estimation of when the pretrained segmentation models for YOLO12 will be available ? Thanks
- Glenn JocherUltralytics
We don't have an official release date for YOLO12-seg pretrained weights yet, but you can train segmentation models from scratch using the YOLO12-seg.yaml configuration. For updates, please monitor the YOLO12 documentation.
Thank you for your response. Great work :)
- Glenn JocherUltralytics
Thank you for your kind words! We don't have a specific release date for YOLO12-seg pretrained weights yet, but you can monitor the YOLO12 documentation for updates. The team typically announces new model releases there first. For now, training from scratch using the YOLO12-seg.yaml configuration remains the recommended approach.
dolokbutarbutar24
Here are some sample images for the healthy class. I also attached some "results" images, hopefully can give more information so you guys can help me with the project.
Pada Sen, 30 Mar 2026 pukul 15.58 Glenn Jocher @.***> menulis:
Thanks for dropping this question here so the Ultralytics team can see it; for leaf-disease datasets, mAP50-95 usually improves more from cleaner labels, balanced class counts, harder negative samples, and reviewing per-class PR/confusion outputs than from pushing loss weights alone, so I’d next tune weight_decay, momentum, warmup_epochs, lrf, translate, shear, perspective, fliplr, and close_mosaic using the hyperparameter tuning guide https://docs.ultralytics.com/guides/hyperparameter-tuning/ and performance metrics guide https://docs.ultralytics.com/guides/yolo-performance-metrics/. If you can share a few sample images, labels, and training curves here, we can suggest a tighter search space, and it’s also worth benchmarking the same split with YOLO26 https://docs.ultralytics.com/models/yolo26/ since YOLO12 is mainly maintained as a community research model.
— Reply to this email directly, view it on GitHub https://github.com/orgs/ultralytics/discussions/19360?email_source=notifications&email_token=A23CVICPPIXOD6F3LMBB52T4TIZKDA5CNFSNUABIM5UWIORPF5TWS5BNNB2WEL2ENFZWG5LTONUW63SDN5WW2ZLOOQXTCNRTG44DGNRZUZZGKYLTN5XKOY3PNVWWK3TUUVSXMZLOOSWGM33PORSXEX3DNRUWG2Y#discussioncomment-16378369, or unsubscribe https://github.com/notifications/unsubscribe-auth/A23CVIG2PM2BD5335IFZQXT4TIZKDAVCNFSM6AAAAABXS26SR6VHI2DSMVQWIX3LMV43URDJONRXK43TNFXW4Q3PNVWWK3TUHMYTMMZXHAZTMOI . You are receiving this because you commented.Message ID: @.*** com>
- Glenn JocherUltralytics
Thanks, that helps; from those samples I’d next verify that the
healthylabels are fully consistent and that the class counts are not skewed, then please attach a few matching image/label.txtpairs plusresults.csvandconfusion_matrix_normalized.pngso we can check whether this is a data issue rather than a YOLO12 training issue, and if you recently fixed labels please delete anylabels/*.cachefiles before retraining.
I am currently working on a project to detect cassava leaf diseases using YOLOv12. The focus of this research is to perform hyperparameter tuning and also determine the most suitable augmentation configuration to improve model performance. So far, the trained model is still hovering around the 0.5 range for the mAP@50-95 evaluation metric. Here are the hyperparameters I have used for tuning so far: epochs=100, patience=20, imgsz=1024, batch=8, optimizer='auto', lr0=0.00511, box=6.32971, cls=2.87957, dfl=2.12658, mosaic=0.25, scale=0.15, mixup=0.0, copy_paste=0.0, degrees=10.0, hsv_h=0.015, hsv_s=0.7, hsv_v=0.4.
What other strategies can I do to improve my model's performance, especially on the mAP@50-95 evaluation metric? Do you have any suggestions for other hyperparameters that need to be added to this project for tuning? I'm sure your experience and skills can answer that and help me hahaha.
- Glenn JocherUltralytics
Thanks for dropping this question here so the Ultralytics team can see it; for leaf-disease datasets, mAP50-95 usually improves more from cleaner labels, balanced class counts, harder negative samples, and reviewing per-class PR/confusion outputs than from pushing loss weights alone, so I’d next tune
weight_decay,momentum,warmup_epochs,lrf,translate,shear,perspective,fliplr, andclose_mosaicusing the hyperparameter tuning guide and performance metrics guide. If you can share a few sample images, labels, and training curves here, we can suggest a tighter search space, and it’s also worth benchmarking the same split with YOLO26 since YOLO12 is mainly maintained as a community research model.
 Clousy
在5090 32G上使用yolo12l训练模型的时候,数据量大概7万左右,batch_size=24 内存占用在24G左右,为啥速度只有2-3it/s 是哪里设置有问题?下面是训练参数: rain_args = dict( data="data.yaml", epochs=500, imgsz=640, batch=24, device=device, workers=16,
cache=False, amp=True, # --- 减少 CPU 负担 --- mosaic=0.0, # 暂时关掉 Mosaic 看看速度是否飙升 mixup=0.0, # 同上 )- Glenn JocherUltralytics
yolo12l本身是重注意力结构,吞吐会比同尺度的 CNN 系列低不少,所以你看到的2–3 it/s在batch=24下未必异常(折算大约是48–72 img/s);如果你目标是更高训练/CPU 端速度,建议直接换到更稳更快的 Ultralytics YOLO26(YOLO12 更偏研究/基准用途,见 YOLO12 文档)。想确认是不是环境/数据读取瓶颈的话,请把yolo checks输出和完整文本训练日志(含第一轮的进度条行、CUDA:/显卡名、DataLoader相关信息)贴在这里;另外你现在cache=False可能会被磁盘 IO 卡住、workers=16在部分系统上也会造成额外调度开销,建议先用下面这组参数做一次对照测试(同一数据/同一imgsz),看it/s是否明显变化:yolo checks yolo train model=yolo12l.pt data=data.yaml epochs=2 imgsz=640 batch=24 device=0 workers=8 cache=True mosaic=0.0 mixup=0.0
is there any video (tutorial) about how to classify plant disease? i'm confused about how to do it because i need guidance to do classify task
- Glenn JocherUltralytics(수정됨)
Yes—plant disease is just a standard image classification workflow; please follow the Ultralytics YOLO classification guide (and drop any follow-up questions here in this discussion so the Ultralytics team can see them), then try:
from ultralytics import YOLO

# ImageNet-pretrained classifier backbone (recommended starting point)
model = YOLO("yolo26n-cls.pt")

# Your dataset folder should contain train/ and val/ with one subfolder per class
model.train(data="path/to/plant_disease_dataset", epochs=50, imgsz=224)
If you share your dataset folder layout (just the directory tree) and what’s confusing you, I can point you to the exact next step.
asad121101
Hello , this new yolo12 is using what architecture in neck ? pan or fpn ? or some thing else ?
Sourabh0052
while working on classification model using YOLO12-cls and i do not make any .yaml file, just simply provide the data source path then will it work same or not
radadiavasu
I faced a problem that recently I put my model on training with yolo12x but at 98/100 epoch it stopped due to units are over on colab pro but when I start again and expect to start from 98 but it start from 1/100 instead of 98 even in results.csv I couldn't get anything. Why this problem occurs?
deldanr
When resuming a training session started with Yolov12, after the AMP check, the training session downloads a Yolov11 model to continue, which I assume is an error.
Attached is part of the log: YOLOv12l summary: 488 layers, 26,389,875 parameters, 26,389,859 gradients, 89.4 GFLOPs
Transferred 1245/1245 items from pretrained weights Freezing layer 'model.21.dfl.conv.weight' AMP: Running Automatic Mixed Precision (AMP) checks... Downloading https://github.com/ultralytics/assets/releases/download/v8.3.0/yolo11n.pt to 'yolo11n.pt'... <-- Here's the error
pvurda
Has anyone found a low-cost, low-latency way to generate a short semantic scene caption (e.g., “two people loading a van”) on top of YOLO12 detections in real time?