Multi-Object Tracking with Ultralytics YOLO
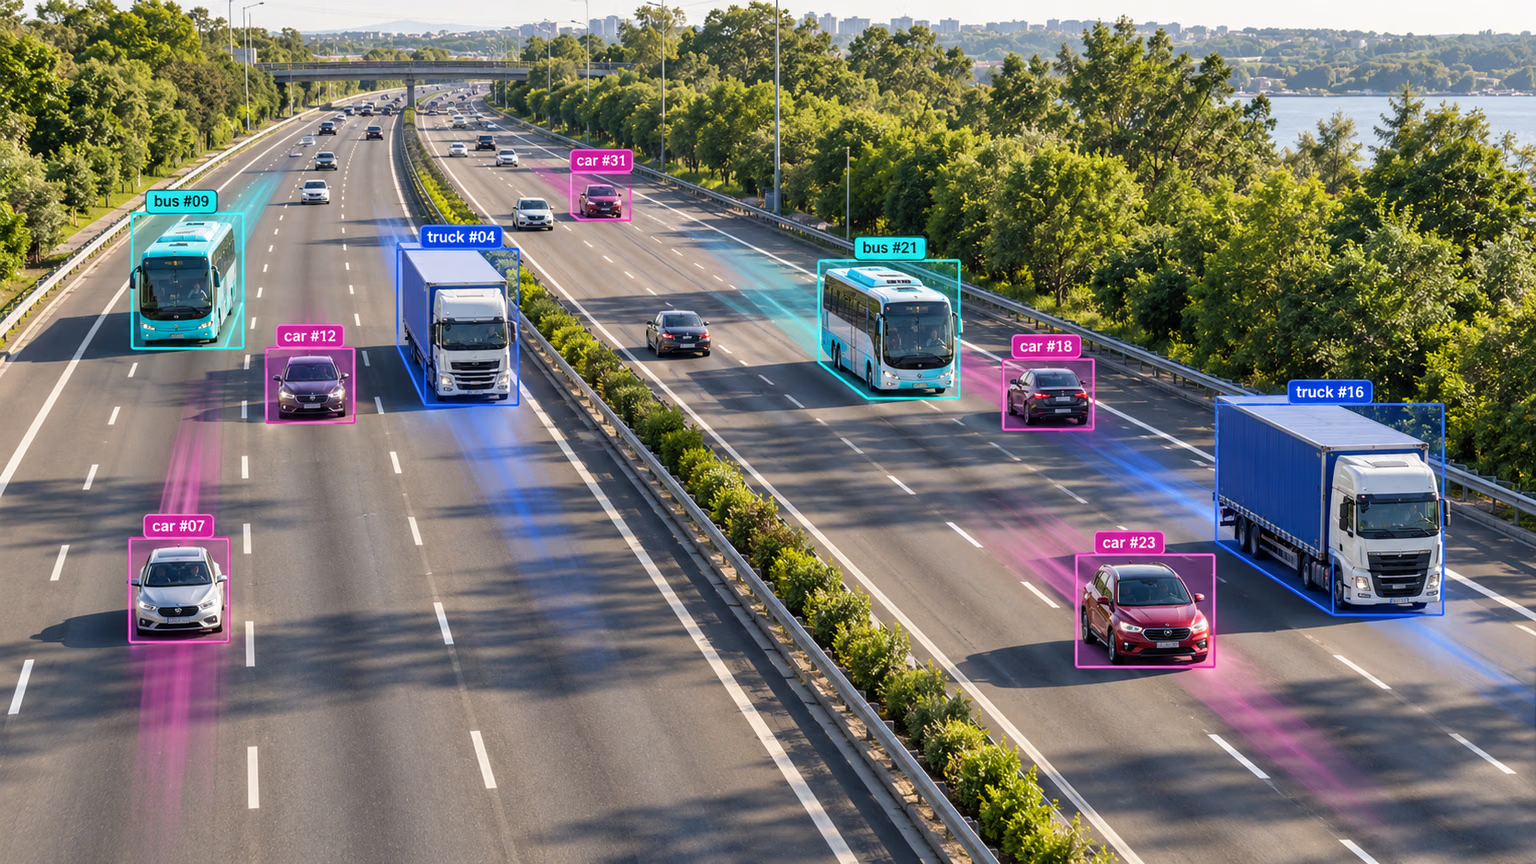
Multi-object tracking in video analytics identifies the location and class of objects within each frame and also maintains a unique ID for each detected object as the video progresses. Applications range from surveillance and security to real-time sports analytics.
See the unreleased YOLO27 preview for planned tracking support.
Starting with ultralytics 8.4.63, OC-SORT, Deep OC-SORT, FastTracker, and TrackTrack are available alongside BoT-SORT and ByteTrack.
Why Choose Ultralytics YOLO for Object Tracking?#
The output from Ultralytics trackers is consistent with standard object detection but has the added value of object IDs. This makes it easy to track objects in video streams and perform subsequent analytics. Key reasons to use Ultralytics YOLO for object tracking:
- Efficiency: Process video streams in real-time without compromising accuracy.
- Flexibility: Supports multiple tracking algorithms and configurations.
- Ease of Use: Simple Python API and CLI options for quick integration and deployment.
- Customizability: Easy to use with custom-trained YOLO models, allowing integration into domain-specific applications.
Watch: How to Run Multi-Object Tracking with Ultralytics YOLO26 | BoT-SORT & ByteTrack | VisionAI 🚀
Real-world Applications#
| Transportation | Retail | Aquaculture |
|---|---|---|
| Vehicle Tracking | People Tracking | Fish Tracking |
Quick Start#
Run tracking on a video with the default TrackTrack tracker. Swap to another tracker by changing the tracker argument.
from ultralytics import YOLO

model = YOLO("yolo26n.pt")

# Default tracker (TrackTrack)
results = model.track(source="https://youtu.be/LNwODJXcvt4", show=True)

# Switch to ByteTrack
results = model.track(source="https://youtu.be/LNwODJXcvt4", show=True, tracker="bytetrack.yaml")
To run the tracker on video streams, use a trained Detect, Segment, Pose, or OBB model such as YOLO26n, YOLO26n-seg, YOLO26n-pose, or YOLO26n-obb, all available in the YOLO26 collection on Ultralytics Platform. You can train custom models locally or with Ultralytics Platform cloud training.
from ultralytics import YOLO

# Load an official or custom model
model = YOLO("yolo26n.pt")  # Load an official Detect model
model = YOLO("yolo26n-seg.pt")  # Load an official Segment model
model = YOLO("yolo26n-pose.pt")  # Load an official Pose model
model = YOLO("path/to/best.pt")  # Load a custom-trained model

# Perform tracking with the model
results = model.track("https://youtu.be/LNwODJXcvt4", show=True)  # Tracking with default tracker
results = model.track("https://youtu.be/LNwODJXcvt4", show=True, tracker="bytetrack.yaml")  # with ByteTrack
Supported Trackers#
Ultralytics YOLO ships with six built-in trackers. Enable one by passing its YAML config file to the tracker argument.
| Tracker | Config file | Motion model | Appearance / ReID | Camera motion compensation | Occlusion handling |
|---|---|---|---|---|---|
| BoT-SORT | botsort.yaml | Linear Kalman | Optional (with_reid) | Configurable (gmc_method) | Track buffer + ReID rebinding |
| ByteTrack | bytetrack.yaml | Linear Kalman | None | No | Two-stage low-conf rescue |
| OC-SORT | ocsort.yaml | Observation-centric Kalman | None | No | ORU, OCM, OCR re-update from last observation |
| Deep OC-SORT | deepocsort.yaml | Observation-centric Kalman | Optional (with_reid) | Configurable (gmc_method) | OC-SORT + optional adaptive appearance EMA |
| FastTracker | fasttrack.yaml | Linear Kalman + rollback | None | No | Kalman rollback + bbox enlargement on occlusion |
| TrackTrack | tracktrack.yaml | Linear Kalman (NSA) | Optional (with_reid) | Configurable (gmc_method) | Iterative multi-cue association + TAI |
Which Tracker Should I Use?#
Use this flow to pick a starting point; tracktrack.yaml is used when you pass no tracker:
- Need the fastest, simplest baseline? → ByteTrack (no ReID, no camera-motion compensation, minimum overhead).
- Handheld, drone, or moving-camera footage? → BoT-SORT (adds camera-motion compensation and optional ReID).
- Non-linear motion (sports, dancing, abrupt turns) and no ReID? → OC-SORT (observation-centric corrections without appearance cost).
- Crowded moving-camera scenes where ID swaps are the main problem? → Deep OC-SORT or TrackTrack (both support optional appearance matching; TrackTrack also adds multi-cue association and duplicate-ID suppression).
- Frequent partial overlap in real-time, no ReID budget? → FastTracker (occlusion-aware ByteTrack variant with Kalman rollback).
Switching Trackers#
Pass the tracker config filename to tracker=. All other code stays the same.
from ultralytics import YOLO

model = YOLO("yolo26n.pt")

results = model.track(source="path/to/video.mp4", tracker="bytetrack.yaml")
results = model.track(source="path/to/video.mp4", tracker="ocsort.yaml")
results = model.track(source="path/to/video.mp4", tracker="tracktrack.yaml")Configuration#
Tracking Arguments#
Tracking configuration shares inference arguments with Predict mode, such as conf, iou, and show.
from ultralytics import YOLO

# Configure the tracking parameters and run the tracker
model = YOLO("yolo26n.pt")
results = model.track(source="https://youtu.be/LNwODJXcvt4", conf=0.1, iou=0.5, show=True)
Custom Tracker Configuration#
To use a modified tracker configuration, copy a tracker config file (for example, as custom_tracker.yaml) from ultralytics/cfg/trackers and modify any settings except tracker_type.
from ultralytics import YOLO

# Load the model and run the tracker with a custom configuration file
model = YOLO("yolo26n.pt")
results = model.track(source="https://youtu.be/LNwODJXcvt4", tracker="custom_tracker.yaml")
Shared Tracker Arguments#
The following parameters are common to most tracker YAML files; not every parameter appears in every config:
Detections at or above track_high_thresh enter the first association stage. Detections between track_low_thresh and track_high_thresh can recover existing tracks when the selected tracker enables low-confidence association, but they do not start new tracks. Detections at or below track_low_thresh are ignored.
| Parameter | Valid Values or Ranges | Description |
|---|---|---|
tracker_type | botsort, bytetrack, ocsort, deepocsort, fasttrack, tracktrack | Specifies the tracker type. |
track_high_thresh | 0.0-1.0 | Threshold for the first association. Affects how confidently a detection is matched to an existing track. |
track_low_thresh | 0.0-1.0 | Lower bound for low-confidence recovery detections. OC-SORT and Deep OC-SORT use these only when use_byte: True; TrackTrack includes them in its penalized association pool. |
new_track_thresh | 0.0-1.0 | Threshold to initialize a new track if the detection does not match any existing tracks. |
track_buffer | >=0 | Frames lost tracks are kept alive before removal. Higher value means more tolerance for occlusion. |
match_thresh | 0.0-1.0 | Threshold for matching tracks. Higher values make matching more lenient. |
fuse_score | True, False | Whether to fuse confidence scores with IoU distances before matching. |
gmc_method | sparseOptFlow, orb, sift, ecc, none | Global motion compensation method. Helps account for camera movement. |
proximity_thresh | 0.0-1.0 | Minimum IoU required for a valid ReID match. Ensures spatial closeness before using appearance cues. |
appearance_thresh | 0.0-1.0 | Minimum normalized appearance similarity required for ReID. |
with_reid | True, False | Enable appearance-based matching for better tracking across occlusions. Supported by BoT-SORT, Deep OC-SORT, and TrackTrack. |
model | auto or compatible ReID model path | ReID model. auto uses native YOLO backbone features when available; otherwise falls back to yolo26n-cls.pt. A custom encoder can be a .pt checkpoint or an exported model such as .torchscript, .onnx, .engine, or an OpenVINO model directory. |
Tracker-specific Arguments#
Each algorithm exposes additional knobs on top of the shared parameters. See the per-tracker sections below for descriptions and tuning advice, or refer directly to the config files:
Enabling Re-Identification (ReID)#
ReID is disabled by default to minimize overhead. Enable it by setting with_reid: True in a tracker config file.
ReID model options:
model: auto— Uses native YOLO detector features, adding minimal overhead. Ideal when you need some ReID without a large performance hit. Falls back toyolo26n-cls.ptif the detector does not expose compatible features.- Custom ReID model — Point
model:at a.ptcheckpoint or a compatible exported embedding model, such as.torchscript,.onnx,.engine, or an OpenVINO model directory. Exported models are loaded throughAutoBackendand must output an embedding tensor directly.
Ready-to-use ONNX encoders are published for every model size. Set model: to one of these names and the file is downloaded automatically the first time the tracker runs (the same way YOLO weights are fetched) — no manual export or download step required:
# In your tracker config (e.g. tracktrack.yaml)
with_reid: True
model: yolo26n-reid.onnx # downloaded on first use; swap n→s/m/l/x for a larger encoder| Model | size (pixels) | params (M) | FLOPs (B) |
|---|---|---|---|
| YOLO26n-reid.onnx | 448 | 2.8 | 2.0 |
| YOLO26s-reid.onnx | 448 | 7.5 | 6.6 |
| YOLO26m-reid.onnx | 448 | 12.4 | 20.1 |
| YOLO26l-reid.onnx | 448 | 15.3 | 25.2 |
| YOLO26x-reid.onnx | 448 | 32.7 | 55.9 |
Only ONNX ReID encoders for the tracker appearance branch are currently available. ReID train, val, and predict modes, as well as dedicated ReID export recipes, are still under development.
For better performance with a separate classification model, export it to a faster backend like TensorRT:
from torch import nn

from ultralytics import YOLO

# Load the classification model
model = YOLO("yolo26n-cls.pt")

# Add average pooling layer
head = model.model.model[-1]
pool = nn.Sequential(nn.AdaptiveAvgPool2d((1, 1)), nn.Flatten(start_dim=1))
pool.f, pool.i = head.f, head.i
model.model.model[-1] = pool

# Export to TensorRT
model.export(format="engine", quantize=16, dynamic=True, batch=32)
Once exported, point to the TensorRT model path in your tracker config.
Tracker Details#
The sections below describe each tracker's design, specific parameters, and tuning tips.
Watch: Which Object Tracker Performs Better? | Speed, FPS & ID Stability | Ultralytics YOLO26 📊
BoT-SORT#
BoT-SORT (Aharon et al., 2022) extends ByteTrack with camera-motion compensation and optional ReID:
- Camera Motion Compensation (CMC): an affine warp estimated each frame (sparse optical flow by default; ORB / ECC also available) is applied to Kalman states before IoU matching.
- Optional ReID: appearance embeddings can be fused into the cost matrix. Disabled by default; enable with
with_reid: True.
Best for: general-purpose tracking, especially moving cameras. Add ReID only when look-alike crowds cause ID swaps.
BoT-SORT-specific arguments:
| Parameter | Valid Values or Ranges | Description |
|---|---|---|
gmc_method | sparseOptFlow, orb, sift, ecc, none | Camera-motion-compensation backend. sparseOptFlow is the default. none disables CMC. |
with_reid | True, False | Enable appearance-based matching. Off by default. |
model | auto or compatible ReID model path | auto uses native YOLO features when available; custom models can be .pt checkpoints or compatible exports. |
proximity_thresh | 0.0-1.0 | Minimum IoU before appearance features are considered. |
appearance_thresh | 0.0-1.0 | Minimum normalized appearance similarity required for a ReID match. Raise to make matching stricter. |
Tuning tips:
- Static camera: set
gmc_method: noneto save a few ms/frame. - Heavy camera motion: keep
sparseOptFlow;eccis more accurate but slower. - Look-alike crowds: turn on
with_reid: Trueand raiseappearance_thresh(e.g.0.85+).
ByteTrack#
ByteTrack (Zhang et al., ECCV 2022) is the lightweight baseline. It uses linear Kalman + IoU with a two-stage association:
- Stage 1: match high-score detections against active tracks.
- Stage 2: retry unmatched tracks against low-score detections to recover through brief partial occlusion.
There is no appearance model and no camera-motion compensation.
Best for: static or near-static cameras where detector cost dominates and you want minimum tracker overhead.
ByteTrack-specific arguments: None beyond the shared tracker arguments.
Tuning tips:
- Noisy detector: lower
track_low_threshso the second stage has more candidates. - High-recall detector: raise
track_high_threshto reduce fragmented IDs. - Frequent ID flicker: raise
track_bufferso briefly-missed tracks survive.
OC-SORT#
OC-SORT (Cao et al., CVPR 2023) is an observation-centric extension of SORT. It keeps SORT's lightweight design (no appearance features) and adds three corrections:
- Observation-Centric Re-update (ORU): replays a virtual trajectory between the last observation and the current detection, re-running the Kalman update to repair drifted velocity.
- Observation-Centric Momentum (OCM): penalizes detections moving in the wrong direction via a velocity-consistency term.
- Observation-Centric Recovery (OCR): re-checks unmatched detections against recently lost tracks using their last observation rather than the predicted state.
Best for: non-linear motion without the cost of a ReID model.
OC-SORT-specific arguments:
| Parameter | Valid Values or Ranges | Description |
|---|---|---|
delta_t | >=1 | Temporal window (frames) for velocity-direction computation in OCM. Larger values smooth more. |
inertia | 0.0-1.0 | Weight of the velocity-consistency cost. Higher values penalize sudden direction changes. |
use_byte | True, False | Enable a ByteTrack-style second association pass over low-confidence detections. |
Tuning tips:
- Non-linear motion: raise
inertia(e.g.0.3-0.4). - Sparse detections: enable
use_byte: True. - Long occlusions: raise
track_bufferso OCR has more lost tracks to rebind.
With OBB models, OCR uses the Kalman-predicted oriented box because an oriented last-observation history is not retained.
Deep OC-SORT#
Deep OC-SORT augments OC-SORT with appearance information and camera-motion compensation:
- Appearance matching: cosine embedding distance is gated by overlap and fused with motion cost.
- Dynamic appearance EMA: track embeddings update with an EMA whose smoothing factor adapts to detection confidence.
- Camera Motion Compensation: Kalman states are warped frame-to-frame via sparse optical flow, ORB, or ECC.
Best for: crowded or moving-camera scenes where ID swaps between visually different but spatially close objects are common.
Deep OC-SORT-specific arguments:
| Parameter | Valid Values or Ranges | Description |
|---|---|---|
with_reid | True, False | Enable appearance-based matching. Off by default. |
model | auto or compatible ReID model path | auto uses native YOLO features when available; custom models can be .pt checkpoints or compatible exports. |
proximity_thresh | 0.0-1.0 | Minimum IoU before appearance features are considered. |
appearance_thresh | 0.0-1.0 | Minimum normalized appearance similarity required for a ReID match. |
alpha_fixed_emb | 0.0-1.0 | Base EMA factor for track-embedding updates. Higher values preserve the older embedding longer. |
gmc_method | sparseOptFlow, orb, sift, ecc, none | Global motion compensation method. |
delta_t | >=1 | Temporal window (frames) for velocity-direction computation in OCM (inherited from OC-SORT). |
inertia | 0.0-1.0 | Weight of the velocity-consistency cost (inherited from OC-SORT). |
use_byte | True, False | Enable a ByteTrack-style second association over low-confidence detections (inherited from OC-SORT). |
Tuning tips:
- Identity swaps in crowds: raise
appearance_thresh(e.g.0.92-0.95) and raisealpha_fixed_embso embeddings adapt more slowly. - Moving camera: set
gmc_method: sparseOptFlow(Deep OC-SORT defaults tonone). - Lower latency: keep
with_reid: False(default) for motion + CMC only; enable ReID only when ID swaps dominate errors.
FastTracker#
FastTracker is an occlusion-aware ByteTrack variant with no appearance model:
- Occlusion detection: flags tracks occluded when coverage by other active tracks exceeds
occ_cover_thresh. - Kalman rollback on occlusion: rolls the Kalman state back to a pre-occlusion frame using ring-buffered history.
- Motion dampening and search expansion: velocity is dampened and the predicted bbox is enlarged while occluded.
- Init-IoU suppression: prevents new tracks from spawning on top of active tracks.
Best for: real-time detection-only pipelines with frequent target-on-target overlap (crowds, queues, sports).
FastTracker-specific arguments:
| Parameter | Valid Values or Ranges | Description |
|---|---|---|
reset_velocity_offset_occ | >=0 | History frames back to restore Kalman velocity on occlusion onset. |
reset_pos_offset_occ | >=0 | History frames back to restore Kalman position on occlusion onset. |
enlarge_bbox_occ | >=1.0 | Height scaling applied to the predicted bbox while occluded (width scales via XYAH aspect ratio). |
dampen_motion_occ | 0.0-1.0 | Velocity multiplier while occluded. Lower values make the track "slow down" through occlusion. |
active_occ_to_lost_thresh | >=1 | Max consecutive occluded frames before an active track is moved to lost. |
occ_cover_thresh | 0.0-1.0 | Fraction of a track's area covered by another active track to declare occlusion. |
occ_reappear_window | >=0 | Frames a recently-occluded lost track stays preferentially re-findable. |
init_iou_suppress | 0.0-1.0 | Suppress new-track initialization if its IoU with any active track exceeds this. Set to 1.0 to disable. |
Tuning tips:
- Frequent partial occlusions: lower
occ_cover_thresh(e.g.0.5-0.6). - Duplicate IDs around overlap: lower
init_iou_suppress(e.g.0.5). - Long occlusions: raise
occ_reappear_windowandtrack_buffertogether. - Fast-moving targets: raise
dampen_motion_occ(closer to1.0); raiseenlarge_bbox_occonly when a wider search region improves recovery.
TrackTrack#
TrackTrack (Shim et al., CVPR 2025) is the default tracker. It reasons from each track's perspective with multi-cue iterative association:
- Track-Perspective-Based Association (TPA): combines HMIoU, optional cosine ReID distance, confidence-projection distance, and corner-angle distance. Assignment is solved iteratively with a relaxing threshold.
- Track-Aware Initialization (TAI): suppresses duplicate spawns before a new ID is created.
Best for: crowded scenes with frequent occlusion where duplicate IDs are a problem.
TrackTrack-specific arguments:
| Parameter | Valid Values or Ranges | Description |
|---|---|---|
iou_weight | 0.0-1.0 | Weight of HMIoU distance when ReID is enabled; otherwise HMIoU is used directly. |
reid_weight | 0.0-1.0 | Weight of cosine ReID distance when ReID is enabled; otherwise it is ignored. |
conf_weight | 0.0-1.0 | Weight of confidence-projection distance. |
angle_weight | 0.0-1.0 | Weight of corner-angle distance. |
penalty_p | 0.0-1.0 | Cost penalty for low-confidence detections. |
penalty_q | 0.0-1.0 | Cost penalty for detections recovered by secondary NMS. |
reduce_step | 0.0-1.0 | Match-threshold relaxation per iteration. |
tai_thr | 0.0-1.0 | IoU threshold for Track-Aware Initialization NMS. |
min_track_len | >=0 | Minimum history length before a new track is confirmed. |
lost_match_thr | 0.0-1.0 | Looser cost gate for relaxed lost-rebind pass; 0 disables it. |
with_reid | True, False | Enable cosine-ReID appearance matching (uses native YOLO features). Off by default. |
model | auto or compatible ReID model path | auto uses native YOLO features when available; custom models can be .pt checkpoints or compatible exports. |
gmc_method | sparseOptFlow, orb, sift, ecc, none | Global motion compensation method. |
Tuning tips:
- Crowded pedestrians: lower
tai_thr(e.g.0.45) to suppress more duplicate spawns; raisetrack_bufferfor longer occlusions. - Fast camera motion: keep
gmc_method: sparseOptFlowenabled. - Small/fast objects: raise
angle_weightslightly and lowermin_track_len. - Enable ReID only when needed: it adds inference cost; for short occlusions, the default multi-cue cost is usually sufficient.
With Segment and Pose models, TrackTrack skips loose-NMS detection recovery so masks and keypoints remain aligned with their detections.
Python Examples#
Watch: How to Build Interactive Object Tracking with Ultralytics YOLO26: Build it in Minutes | Python!
Persisting Tracks Loop#
Here is a Python script using OpenCV (cv2) and YOLO26 to run object tracking on video frames. This script assumes the necessary packages (opencv-python and ultralytics) are already installed. The persist=True argument tells the tracker that the current image or frame is the next in a sequence and to expect tracks from the previous image in the current image.
Use persist=True only when passing consecutive frames from the same video stream to model.track(). This lets the tracker reuse state from earlier frames and maintain consistent track IDs over time. Do not use persist=True across unrelated images or a different stream, since previous track state can carry over.
You can also choose a tracker backend by passing a tracker configuration file, such as tracker="botsort.yaml", tracker="bytetrack.yaml", or tracker="tracktrack.yaml".
import cv2

from ultralytics import YOLO

# Load the YOLO26 model
model = YOLO("yolo26n.pt")

# Open the video file
video_path = "path/to/video.mp4"
cap = cv2.VideoCapture(video_path)

# Loop through the video frames
while cap.isOpened():
    # Read a frame from the video
    success, frame = cap.read()

    if success:
        # Run YOLO26 tracking on the frame, persisting tracks between frames
        # and using the BoT-SORT tracker backend
        results = model.track(frame, persist=True, tracker="botsort.yaml")

        # Visualize the results on the frame
        annotated_frame = results[0].plot()

        # Display the annotated frame
        cv2.imshow("YOLO26 Tracking", annotated_frame)

        # Break the loop if 'q' is pressed
        if cv2.waitKey(1) & 0xFF == ord("q"):
            break
    else:
        # Break the loop if the end of the video is reached
        break

# Release the video capture object and close the display window
cap.release()
cv2.destroyAllWindows()
Note the change from model(frame) to model.track(frame), which enables object tracking instead of simple detection. This modified script will run the tracker on each frame of the video, visualize the results, and display them in a window. The loop can be exited by pressing 'q'.
Plotting Tracks Over Time#
Visualizing object tracks over consecutive frames can provide valuable insights into the movement patterns and behavior of detected objects within a video. Ultralytics YOLO26 makes plotting these tracks straightforward.
The following example uses YOLO26 tracking to plot the movement of detected objects across multiple video frames. The script opens a video file, reads it frame by frame, and uses the YOLO model to identify and track objects. By retaining the center points of the detected bounding boxes and connecting them, it draws lines that represent the paths followed by the tracked objects.
from collections import defaultdict

import cv2
import numpy as np

from ultralytics import YOLO

# Load the YOLO26 model
model = YOLO("yolo26n.pt")

# Open the video file
video_path = "path/to/video.mp4"
cap = cv2.VideoCapture(video_path)

# Store the track history
track_history = defaultdict(list)

# Loop through the video frames
while cap.isOpened():
    # Read a frame from the video
    success, frame = cap.read()

    if success:
        # Run YOLO26 tracking on the frame, persisting tracks between frames
        result = model.track(frame, persist=True)[0]

        # Get the boxes and track IDs
        if result.boxes and result.boxes.is_track:
            boxes = result.boxes.xywh.cpu()
            track_ids = result.boxes.id.int().cpu().tolist()

            # Visualize the result on the frame
            frame = result.plot()

            # Plot the tracks
            for box, track_id in zip(boxes, track_ids):
                x, y, w, h = box
                track = track_history[track_id]
                track.append((float(x), float(y)))  # x, y center point
                if len(track) > 30:  # retain 30 tracks for 30 frames
                    track.pop(0)

                # Draw the tracking lines
                points = np.hstack(track).astype(np.int32).reshape((-1, 1, 2))
                cv2.polylines(frame, [points], isClosed=False, color=(230, 230, 230), thickness=10)

        # Display the annotated frame
        cv2.imshow("YOLO26 Tracking", frame)

        # Break the loop if 'q' is pressed
        if cv2.waitKey(1) & 0xFF == ord("q"):
            break
    else:
        # Break the loop if the end of the video is reached
        break

# Release the video capture object and close the display window
cap.release()
cv2.destroyAllWindows()
Multithreaded Tracking#
Multithreaded tracking provides the capability to run object tracking on multiple video streams simultaneously. This is particularly useful when handling multiple video inputs, such as from multiple surveillance cameras, where concurrent processing improves throughput.
The Python script below uses Python's threading module to run multiple instances of the tracker concurrently. Each thread runs the tracker on one video source, and all the threads run simultaneously in the background.
To ensure that each thread receives the correct parameters (the model to use and the video source), the script defines a function run_tracker_in_thread that accepts these parameters and contains the main tracking loop. This function reads the video frame by frame, runs the tracker, and saves the annotated results.
Two different models are used in this example, yolo26n.pt and yolo26n-seg.pt, each tracking objects in a different source: a local video file and a webcam. The sources are specified in SOURCES.
The daemon=True parameter in threading.Thread means that these threads will be closed as soon as the main program finishes. We then start the threads with start() and use join() to make the main thread wait until both tracker threads have finished.
Finally, after all threads have completed their task, the windows displaying the results are closed using cv2.destroyAllWindows().
import threading

import cv2

from ultralytics import YOLO

# Define model names and video sources
MODEL_NAMES = ["yolo26n.pt", "yolo26n-seg.pt"]
SOURCES = ["path/to/video.mp4", "0"]  # local video, 0 for webcam

def run_tracker_in_thread(model_name, filename):
    """Run YOLO tracker in its own thread for concurrent processing.

    Args:
        model_name (str): Model checkpoint name or path loaded inside the thread.
        filename (str): The path to the video file or the identifier for the webcam/external camera source.
    """
    model = YOLO(model_name)
    results = model.track(filename, save=True, stream=True)
    for r in results:
        pass

# Create and start tracker threads using a for loop
tracker_threads = []
for video_file, model_name in zip(SOURCES, MODEL_NAMES):
    thread = threading.Thread(target=run_tracker_in_thread, args=(model_name, video_file), daemon=True)
    tracker_threads.append(thread)
    thread.start()

# Wait for all tracker threads to finish
for thread in tracker_threads:
    thread.join()

# Clean up and close windows
cv2.destroyAllWindows()
This example can easily be extended to handle more video files and models by creating more threads and applying the same methodology.
Contribute New Trackers#
If you have implemented or adapted a multi-object tracking algorithm for Ultralytics YOLO, consider contributing it to ultralytics/trackers with a matching config in ultralytics/cfg/trackers. Contributions expand the tracking options available to the whole community.
FAQ#
Multi-object tracking in video analytics involves both identifying objects and maintaining a unique ID for each detected object across video frames. Ultralytics YOLO supports this by providing real-time tracking along with object IDs, facilitating tasks such as security surveillance and sports analytics. The system uses trackers such as BoT-SORT, ByteTrack, OC-SORT, Deep OC-SORT, FastTracker, and TrackTrack, which can be configured via YAML files.
No. Standard Ultralytics
.ptfiles store the YOLO model weights, while the tracker is created at inference time bymodel.track(). Track IDs depend on tracker state across consecutive frames, so a single standalone image can return detections such as boxes, classes, and confidences, but it cannot produce meaningful persistent tracking IDs by itself.For deployment, package the detector and tracker together in your application and call
model.track()frame by frame withpersist=Truewhen frames come from the same video stream. Use separate model or tracker instances for unrelated streams so state does not carry over between videos.You can configure a custom tracker by copying an existing tracker configuration file (e.g.,
custom_tracker.yaml) from the Ultralytics tracker configuration directory and modifying parameters as needed, except for thetracker_type. Use this file in your tracking model like so:Examplefrom ultralytics import YOLO model = YOLO("yolo26n.pt") results = model.track(source="https://youtu.be/LNwODJXcvt4", tracker="custom_tracker.yaml")To run object tracking on multiple video streams simultaneously, you can use Python's
threadingmodule. Each thread will handle a separate video stream. Here's an example of how you can set this up:Multithreaded Trackingimport threading import cv2 from ultralytics import YOLO # Define model names and video sources MODEL_NAMES = ["yolo26n.pt", "yolo26n-seg.pt"] SOURCES = ["path/to/video.mp4", "0"] # local video, 0 for webcam def run_tracker_in_thread(model_name, filename): """Run YOLO tracker in its own thread for concurrent processing. Args: model_name (str): Model checkpoint name or path loaded inside the thread. filename (str): The path to the video file or the identifier for the webcam/external camera source. """ model = YOLO(model_name) results = model.track(filename, save=True, stream=True) for r in results: pass # Create and start tracker threads using a for loop tracker_threads = [] for video_file, model_name in zip(SOURCES, MODEL_NAMES): thread = threading.Thread(target=run_tracker_in_thread, args=(model_name, video_file), daemon=True) tracker_threads.append(thread) thread.start() # Wait for all tracker threads to finish for thread in tracker_threads: thread.join() # Clean up and close windows cv2.destroyAllWindows()Multi-object tracking with Ultralytics YOLO has numerous applications, including:
- Transportation: Vehicle tracking for traffic management and autonomous driving.
- Retail: People tracking for in-store analytics and security.
- Aquaculture: Fish tracking for monitoring aquatic environments.
- Sports Analytics: Tracking players and equipment for performance analysis.
- Security Systems: Monitoring suspicious activities and creating security alarms.
These applications benefit from Ultralytics YOLO's ability to process high-frame-rate videos in real time with high accuracy.
To visualize object tracks over multiple video frames, you can use the YOLO model's tracking features along with OpenCV to draw the paths of detected objects. Here's an example script that demonstrates this:
Plotting tracks over multiple video framesfrom collections import defaultdict import cv2 import numpy as np from ultralytics import YOLO model = YOLO("yolo26n.pt") video_path = "path/to/video.mp4" cap = cv2.VideoCapture(video_path) track_history = defaultdict(list) while cap.isOpened(): success, frame = cap.read() if success: result = model.track(frame, persist=True)[0] annotated_frame = result.plot() if result.boxes and result.boxes.is_track: boxes = result.boxes.xywh.cpu() track_ids = result.boxes.id.int().cpu().tolist() for box, track_id in zip(boxes, track_ids): x, y, w, h = box track = track_history[track_id] track.append((float(x), float(y))) if len(track) > 30: track.pop(0) points = np.hstack(track).astype(np.int32).reshape((-1, 1, 2)) cv2.polylines(annotated_frame, [points], isClosed=False, color=(230, 230, 230), thickness=10) cv2.imshow("YOLO26 Tracking", annotated_frame) if cv2.waitKey(1) & 0xFF == ord("q"): break else: break cap.release() cv2.destroyAllWindows()This script will plot the tracking lines showing the movement paths of the tracked objects over time, providing valuable insights into object behavior and patterns.


Comments679
Ask a question, share your results, or help someone else.
bhaskar2443053
I’m using YOLO-Pose to detect and track people throughout ~1-hour videos and need each person to keep the same ID. I already have high-quality ground-truth tracks from a SAM-based tracker.
Do you have a script that can fine-tune YOLO-Pose (and its tracker/Re-ID parameters) against this ground truth to squeeze out the best IDF1 or HOTA scores ?
1maxexplorer
Hi!
Thank you for your great work on YOLO and tracking integration. We are using YOLO with ByteTrack/BoT-SORT for object counting and tracking and want to improve ID stability.
-
We notice that sometimes, even when the object visually looks the same and the scene and motion are stable, the track_id changes. What parameters or reasons should we check to understand why the ID changes unexpectedly?
-
Is the match_thresh parameter based on IoU, and is it possible to print or visualize the IoU used during matching for debugging?
-
Is there a way to output Kalman-predicted boxes of lost tracks so we can analyze them?
-
Could increasing the video FPS improve tracking and IoU consistency, or is this mainly related to detection stability and parameter tuning?
-
Does ByteTrack or BoT-SORT use a min_hits parameter before confirming tracks, or are tracks confirmed immediately after creation?
-
If a track is lost, can a new ID only be assigned on the second frame after reappearance if conf > new_track_thresh and then conf > track_high_thresh, or can it happen immediately on the first detection?
-
Is the track_buffer parameter the number of frames a track is kept using Kalman prediction after it is lost before being deleted?
-
Do you have any tips to improve tracking stability and avoid unnecessary ID switches?
Thank you for your support!
-
 Glenn JocherUltralytics
@bhaskar2443053 currently there isn't a built-in script for fine-tuning YOLO-Pose tracking parameters against ground truth. You would need to implement custom evaluation using libraries like TrackEval or MOTChallenge to compute IDF1/HOTA scores and optimize tracker parameters iteratively.
@maxexplorer great questions about tracking stability! Here are the key points:
-
ID changes typically occur due to low IoU between predicted and detected boxes, occlusions, or threshold mismatches. Check
track_high_threshandmatch_threshin your tracker config. -
match_threshis indeed IoU-based. For debugging, you can add logging to the tracker code, but there's no built-in visualization. -
Kalman predictions aren't directly exposed, but you can access them by modifying the tracker implementation.
-
Higher FPS generally improves tracking by reducing inter-frame motion, making associations more reliable.
-
Both trackers use confirmation logic - tracks need to meet certain criteria before being confirmed as valid tracks.
-
New tracks can be assigned immediately if detection confidence exceeds
new_track_thresh. -
Correct -
track_buffermaintains lost tracks for that many frames using prediction. -
For stability: increase
track_buffer, adjustmatch_threshbased on your scenario, and ensure consistent detection quality with appropriateconfthresholds.
For detailed parameter tuning, refer to the tracker configuration files and our tracking documentation.
-
rohith-aiunika(edited)
Hi YOLO Team, I've been using the following Python script to track objects with my YOLOv8 model: from ultralytics import YOLO
model = YOLO(r"/home/best_pt_files/v1.0.2.pt") results = model.track(r"/home/video.MP4", save=False, stream=False)
However, I noticed that my GPU memory usage gradually increases, leading to an "out of memory" error before the video finishes processing. Interestingly, when I use the following command from the terminal, the entire video tracks successfully without excessive GPU memory consumption: yolo track model=/home/best_pt_files/1.0.2.pt source=/home/video.MP4
Previously, the Python script worked without any issues. The memory issue has only recently started occurring. Could you please help me understand the possible reasons for this memory increase and how to address it?
i have experimented with persist= True and False,stream = true and false, show = true and false also but the issue is still there
1- Glenn JocherUltralytics
@rohith-aiunika thanks for reporting this. The memory buildup in Python scripts (but not CLI) typically occurs when not using streaming mode. To match the CLI's memory behavior, modify your Python script to process frames iteratively using
stream=True:from ultralytics import YOLO model = YOLO("/home/best_pt_files/v1.0.2.pt") for result in model.track("/home/video.MP4", stream=True): # Process frames iteratively pass # Add your frame processing logic hereThis streams frames sequentially like the CLI, preventing memory accumulation. For more details, see the streaming implementation in our Tracking documentation. Let us know if this resolves the issue!
i have used stream = True, then the code is just executing without showing error and without tracking also
- Glenn JocherUltralytics
@rohith-aiunika thanks for the update. Let's ensure you're properly iterating through streaming results. Try adding a processing loop like this:
for result in model.track(source=video_path, stream=True):
    annotated_frame = result[0].plot()
    cv2.imshow('Tracking', annotated_frame)
    if cv2.waitKey(1) == ord('q'):
        break
This actively processes each frame and displays tracking annotations. If issues persist, you might need to verify your video source format using our supported inference sources documentation.
mwasela
Hello, Made a custom model that i can successfully run and with a well tweaked confidence filter, am getting good results.
Now Ive wrapped the classification and tracking functionality into a flask app, that returns the count ID's when accessed by a REST call like get, meaning it can be accessed by a separate app for processing and stuff. I want to be able to reset the counting through some other request. My camera feed is always live, i need a way to reset the track id's to zero when neccessary, they just keep counting until i exit the program.
1- Glenn JocherUltralytics
@mwasela hello,
It's great to hear that your custom model is performing well. To reset the tracking IDs in your Flask app, you can implement a mechanism to reinitialize the tracker state upon receiving a specific request. This can be done by resetting the tracker object or reloading the model within your tracking function.
For more detailed guidance on configuring and using trackers, please refer to our documentation: Multi-Object Tracking with Ultralytics YOLO.
Orziqulov-Javohir
I really need help to do this programm: I wanna select region via mouse "dangerous zone" Track detected person, If person enters this zone crop and save person's photo Can you show me pls how to do it for 10 cameras, my gpu is RTX 3080TI
1It is kind a security program detecting who entered zone
1import cv2 from ultralytics import YOLO import time
Load the YOLOv8 model
model = YOLO("yolov8n.pt") # pretrained YOLOv8n model
Initialize video capture for multiple cameras
camera_ids = [
'rtsp://admin:admin12345@172.17.67.20:554',
'rtsp://admin:admin12345@172.17.67.16:554', 'rtsp://admin:admin12345@172.17.67.18:554', 'rtsp://admin:admin12345@172.17.67.19:554', 'rtsp://admin:admin12345@172.17.67.17:554', 'rtsp://admin:admin12345@172.17.67.21:554', 'rtsp://admin:admin12345@172.17.67.17:554', 'rtsp://admin:admin12345@172.17.67.21:554', 'rtsp://admin:admin12345@172.17.67.17:554',
]caps = [cv2.VideoCapture(camera_id) for camera_id in camera_ids]
Open the video file
roi_start = [(0, 0)] * len(caps) roi_end = [(0, 0)] * len(caps) drawing = [False] * len(caps)
tracked_persons = [[] for _ in range(len(caps))] # List to track persons in dangerous zones
def draw_rectangle(event, x, y, flags, param): global roi_start, roi_end, drawing idx = param # Use param to identify the camera index if event == cv2.EVENT_LBUTTONDOWN: drawing[idx] = True roi_start[idx] = (x, y) roi_end[idx] = (x, y) print(f"Camera {idx}: Started drawing rectangle at: {roi_start[idx]}") elif event == cv2.EVENT_MOUSEMOVE: if drawing[idx]: roi_end[idx] = (x, y) print(f"Camera {idx}: Updated rectangle end to: {roi_end[idx]}") elif event == cv2.EVENT_LBUTTONUP: drawing[idx] = False roi_end[idx] = (x, y) print(f"Camera {idx}: Finished drawing rectangle at: {roi_end[idx]}")
Create a window and set mouse callback for each camera
for idx in range(len(caps)): window_name = f'Video {idx}' cv2.namedWindow(window_name) cv2.setMouseCallback(window_name, draw_rectangle, idx)
def is_inside_roi(x, y, roi_start, roi_end): x1, y1 = roi_start x2, y2 = roi_end return min(x1, x2) <= x <= max(x1, x2) and min(y1, y2) <= y <= max(y1, y2)
while True: frames = [] for cap in caps: ret, frame = cap.read() if not ret: continue # frame = cv2.resize(frame, (640, 480)) frames.append(frame)
for idx, frame in enumerate(frames):
    window_name = f'Video {idx}'

    # Draw the ROI rectangle on the frame
    if drawing[idx] or roi_start[idx] != roi_end[idx]:
        cv2.rectangle(frame, roi_start[idx], roi_end[idx], (0, 255, 0), 2)
        cv2.putText(frame, "Dangerous Zone", (roi_start[idx][0], roi_start[idx][1] - 10), cv2.FONT_HERSHEY_SIMPLEX, 0.9, (0, 255, 0), 2)

    # Run YOLOv8 tracking on the frame, persisting tracks between frames
    results = model.track(frame, tracker="bytetrack.yaml", persist=True)

    for result in results:
        boxes = result.boxes

        for box in boxes:
            x1, y1, x2, y2 = box.xyxy.tolist()[0][:4]
            cls = box.cls.tolist()[0]
            if cls == 0:  # Person class in COCO dataset
                # Check if the center of the person is inside the ROI
                cx, cy = int((x1 + x2) / 2), int((y1 + y2) / 2)
                if is_inside_roi(cx, cy, roi_start[idx], roi_end[idx]):
                    # Check if this person is already tracked
                    person_id = box.id.tolist()[0] if box.id is not None else None

                    if person_id not in tracked_persons[idx]:
                        tracked_persons[idx].append(person_id)
                        # Crop and save the frame
                        crop = frame[int(y1):int(y2), int(x1):int(x2)]
                        cv2.imwrite(f"cropped_camera{idx}_person{person_id}_{int(time.time())}.jpg", crop)
                        # Draw a label on the person
                        cv2.putText(frame, "Person in Dangerous Zone", (int(x1), int(y1) - 10), cv2.FONT_HERSHEY_SIMPLEX, 0.9, (0, 0, 255), 2)
                        cv2.rectangle(frame, (int(x1), int(y1)), (int(x2), int(y2)), (0, 0, 255), 2)

    cv2.imshow(window_name, frame)

if cv2.waitKey(1) & 0xFF == ord('q'):
    break
Release all video captures
for cap in caps: cap.release() cv2.destroyAllWindows()
- Glenn JocherUltralytics
Your approach looks solid for setting up a security program to track and save images of individuals entering a designated "dangerous zone" across multiple cameras. To enhance your implementation, ensure you're using the latest versions of the Ultralytics package for optimal performance and bug fixes. For more detailed guidance on tracking configurations and additional features, you can refer to the Ultralytics tracking documentation. If you encounter any specific issues or need further assistance, feel free to ask!
mariem158
File "", line 91 results = model.track(frame, persist=True, tracker="botsort.yaml") ^ IndentationError: unexpected indent COMMENT CORRIGER CETTE ERREUR
- Glenn JocherUltralytics
The error you're encountering is due to an unexpected indent in your code. Ensure that the indentation is consistent throughout your script. If the issue persists, please verify it with the latest version of the Ultralytics package. For more details on tracking configurations, you can refer to the Ultralytics tracking documentation.
GKYoffice
How can I get the tracking metrics of a tracker such as MOTA, IDF1, etc.
1Can I set the parameter ''save_txt'' to True in the track function, and then write code to evaluate the tracking data?
 Paula DerrengerUltralytics
Currently, the Ultralytics YOLO framework doesn't provide built-in functionality for computing tracking metrics like MOTA or IDF1 directly through the API or command line. However, you can utilize external libraries such as MOTChallenge eval for calculating these metrics.
After running your tracking with YOLOv8, you'd typically export your tracking results in a format compatible with these libraries (usually a
.txtformat with frame ID, object ID, bounding boxes, etc.). Then, use the external library to compute the desired metrics by providing it with both the ground truth and your results file.Here's a generic example on how you might save tracking results (modify based on your actual use case):
from ultralytics import YOLO

# Initialize and load your model
model = YOLO("path/to/your/model.pt")

# Tracking
results = model.track(source='path/to/video.mp4', save_txt=True, project='runs/track', name='exp')

# results are saved in 'runs/track/exp' in a format that can be used with MOTChallenge eval tools
Afterwards, follow the documentation of the MOTChallenge eval toolkit to compute the metrics using the outputs stored in
'runs/track/exp'.If you encounter any specific issues while implementing this, feel free to ask!🛠️
AdadAlShabab
Can I run two models simultaneously in one video? Ex: model = YOLO('E:/Ultralytics/best.pt') model = YOLO('yolov8m-pose.pt') results = model.track(source="file.mp4", show=True, conf=0.3, save=False) results = model.track(source="file.mp4", show=True, conf=0.3, save=False)
I want that two models will works simultaneously with cumulative results? Is it possible? Please let me know. Thanks in advance!!
1- Paula DerrengerUltralytics
@AdadAlShabab yes, you can run two models simultaneously on one video, but you'll need to manage the inference in a way that allows both models to process the video frames concurrently. Here's a simplified example using threading to achieve this:
import threading
from ultralytics import YOLO

# Load the models
model1 = YOLO('E:/Ultralytics/best.pt')
model2 = YOLO('yolov8m-pose.pt')

# Function to run tracking
def track_video(model, source, conf, show, save):
    results = model.track(source=source, show=show, conf=conf, save=save)
    # Process results here or return them

# Create threads for each model
thread1 = threading.Thread(target=track_video, args=(model1, "file.mp4", 0.3, True, False))
thread2 = threading.Thread(target=track_video, args=(model2, "file.mp4", 0.3, True, False))

# Start the threads
thread1.start()
thread2.start()

# Wait for both threads to finish
thread1.join()
thread2.join()
This script will run both models in separate threads. If you want to combine the results from both models, you'll need to implement a mechanism to synchronize and merge the results from both threads. Keep in mind that displaying the results (
show=True) from two threads might not work as expected, and you might need to handle the visualization separately.Remember to handle the GPU memory usage carefully, as running two models simultaneously will require more memory. If you encounter any issues, consider running the models sequentially or on separate GPUs if available.
4
Journey2-20
Hello I'm newer to Opencv and I'm trying to run a tracking camera for airsoft. How would i select specific bounding boxes?
- Paula DerrengerUltralytics
Use
model.track(frame, persist=True)and inspectresults[0].boxes.xyxywithresults[0].boxes.id; select the box containing your OpenCV mouse-click coordinates, store its track ID, then process or draw only boxes whoseboxes.idmatches that ID. Feel free to continue posting questions here so the Ultralytics team can help.
yashpatel2010
In my jetson orin nano super developer kit with jetpack6.1 and deepstream7.1 i want to do cross camera person tracking. Is there any default way in deepstream configs to do it? Or any other lightweight thing that can be easily doable in jetson orin nano 8 gb super dev kit.
- Glenn JocherUltralytics
Ultralytics
trackis single-camera MOT, so cross-camera person IDs are not built in; on DeepStream 7.1 the practical Orin Nano path isNvDeepSORT/ReID per stream plus downstream association from the exported embeddings described in the DeepStreamgst-nvtrackerdocs, or NVIDIA’s separate Multi-Camera Tracking workflow for full MTMC. Please keep the details here in Discussions and share your current tracker config if you want a minimal setup suggestion. (docs.nvidia.com)
anvi97(edited)
Hi @glenn-jocher,
I am building a road surface detection system using YOLO segmentation.
My pipeline:
Apply bird eye view using cv2.getPerspectiveTransform()
Mask only road area
Detect potholes, zebra crossings, and speed bumps
I am facing the following issues:
1️⃣ Overlapping Potholes Not Merging Properly
I want overlapping potholes to merge into one bounding box.
In many cases it works, but sometimes:
Two boxes are still shown for the same pothole
Even when they overlap visually
I am using YOLO with:
results = model(frame, conf=0.45, iou=0.4)
Is YOLO’s internal NMS preventing full merging? Should I apply custom merging after inference? Is segmentation-based merging better than bounding box merging for potholes?
2️⃣ Object Size Changing After Bird Eye View
I calculate pothole size using:
pixels_per_foot = 220
But I selected this value randomly (no real-world measurement).
Because of this:
Object size changes depending on frame position
Same pothole appears different size
Is it correct that without real-world calibration, size cannot be accurate? What is the correct method to calculate real-world size in a monocular dashcam setup?
3️⃣ Zebra Crossing vs Black–White Speed Bump Confusion
Black–white speed bumps are getting confused with zebra crossings because both have parallel white-black stripes.
Currently I am detecting only yellow speed bumps to avoid confusion.
What is the better approach to separate them?
Use segmentation instead of boxes?
Add geometry-based filtering?
Train with more hard-negative examples?
this is my code ..... from ultralytics import YOLO import cv2 import numpy as np
model = YOLO("runs/segment/pothole_seg_model3/weights/best.pt") pixels_per_foot = 220
video_path = "sample_video.mp4" cap = cv2.VideoCapture(video_path)
if not cap.isOpened(): print(" Cannot open video") exit()
width = int(cap.get(cv2.CAP_PROP_FRAME_WIDTH)) height = int(cap.get(cv2.CAP_PROP_FRAME_HEIGHT)) fps = cap.get(cv2.CAP_PROP_FPS) or 25.0
fourcc = cv2.VideoWriter_fourcc(*'avc1') out = cv2.VideoWriter("pothole5.mp4", fourcc, fps, (width, height))
STRETCH_AMOUNT = 50
src = np.float32([ [0, height],
[width, height],
[922, 183],
[265, 183]
])dst = np.float32([ [0, height], [width, height], [width + STRETCH_AMOUNT, 0], [0 - STRETCH_AMOUNT, 0] ])
matrix = cv2.getPerspectiveTransform(src, dst) def compute_iou(box1, box2): x1 = max(box1[0], box2[0]) y1 = max(box1[1], box2[1]) x2 = min(box1[2], box2[2]) y2 = min(box1[3], box2[3])
inter_area = max(0, x2 - x1) * max(0, y2 - y1)

box1_area = (box1[2] - box1[0]) * (box1[3] - box1[1])
box2_area = (box2[2] - box2[0]) * (box2[3] - box2[1])

union = box1_area + box2_area - inter_area

if union == 0:
    return 0

return inter_area / union
def should_merge(box1, box2, iou_thresh=0.1, dist_thresh=150): # Containment check - if one box is inside the other if (box1[0] >= box2[0] and box1[1] >= box2[1] and box1[2] <= box2[2] and box1[3] <= box2[3]): return True if (box2[0] >= box1[0] and box2[1] >= box1[1] and box2[2] <= box1[2] and box2[3] <= box1[3]): return True
iou = compute_iou(box1, box2)
if iou > iou_thresh:
    return True

cx1, cy1 = (box1[0]+box1[2])/2, (box1[1]+box1[3])/2
cx2, cy2 = (box2[0]+box2[2])/2, (box2[1]+box2[3])/2

if np.sqrt((cx1-cx2)**2 + (cy1-cy2)**2) < dist_thresh:
    return True

return False
while True: ret, frame = cap.read() if not ret: break
bird_eye = cv2.warpPerspective(frame, matrix, (width, height))

results = model(bird_eye, conf=0.45, iou=0.4)[0]
annotated = results.plot()

if results.boxes is not None:
    for box in results.boxes:
        cls_id = int(box.cls.item())

        if cls_id == 0:  # pothole only
            x1, y1, x2, y2 = map(int, box.xyxy.cpu().numpy()[0])

            w_px = x2 - x1
            h_px = y2 - y1

            w_ft = w_px / pixels_per_foot
            h_ft = h_px / pixels_per_foot

            label = f"{w_ft:.2f}ft x {h_ft:.2f}ft"

            cv2.putText(
                annotated,
                label,
                (x1, y1 - 15),
                cv2.FONT_HERSHEY_SIMPLEX,
                0.6,
                (0, 255, 255),
                2
            )

cv2.imshow("Bird Eye + Pothole Detection", annotated)
out.write(annotated)

if cv2.waitKey(1) & 0xFF == 27:
    break
cap.release() out.release() cv2.destroyAllWindows()
- Glenn JocherUltralytics
For (1), YOLO’s NMS will only suppress duplicate detections based on
iou=...—it won’t “merge” two overlapping detections into a larger union box, and in your snippetcompute_iou()/should_merge()aren’t actually applied toresults.boxes, so you’re still visualizing the raw post-NMS output; since you’re using a Segment model, the most robust way to merge “split” potholes is to union the pothole masks and re-extract connected components (then box/measure those) rather than trying to union boxes.import cv2 import numpy as np r = model(bird_eye, conf=0.45, iou=0.4)[0] if r.masks is not None and r.boxes is not None: cls = r.boxes.cls.int().cpu().numpy() pothole_idx = np.where(cls == 0)[0] if pothole_idx.size: m = r.masks.data[pothole_idx].cpu().numpy() # (N,H,W), 0/1 union = (m.sum(0) > 0).astype(np.uint8) * 255 n, labels = cv2.connectedComponents(union) for k in range(1, n): ys, xs = np.where(labels == k) x1, y1, x2, y2 = xs.min(), ys.min(), xs.max(), ys.max() cv2.rectangle(bird_eye, (x1, y1), (x2, y2), (0, 255, 255), 2)For (2), yes—without real-world calibration (and a valid “road plane” assumption),
pixels_per_foot=220can’t be physically meaningful, and even with a BEV warp you only get consistent scale if your homography is tied to metric coordinates; the usual monocular approach is: calibrate camera intrinsics, estimate the road plane, build a homography to a top-down plane in real units (or derive scale from at least one known road-plane measurement like lane width/stripe spacing), then measure in the BEV plane.For (3), the best fix is usually data: train both classes explicitly with lots of “hard negatives” (zebra crossings that look like bumps and vice versa) and keep labels consistent; segmentation often helps because you can then add simple shape/location constraints on the mask (zebra = large repeated pattern region, bump = single narrow band across lane) and optionally smooth decisions over time (if you’re doing video, using
model.track(..., persist=True)from the Track mode docs can help stabilize per-frame flicker, even though it won’t merge instances within a frame).If you can paste
!yolo checksoutput and one representative frame (plus what you consider the “correct” merged result), I can suggest concrete thresholds/post-processing for your exact outputs. In the attached frame:
The large water-filled pothole on the left should be treated as a single instance.
The small region in the top-left corner (currently detected as separate) should be merged with the large region.
Essentially, all visually continuous damaged area should result in one bounding box / one connected component.
Currently:
Mask union + connected components splits them due to small segmentation gaps
Goal:
Treat visually continuous pothole surface as one instance for measurement stability.
- Glenn JocherUltralytics
That split is expected because
connectedComponents()treats any 1–2 px “mask hole” as a hard break, so add a small gap-closing step on the union mask (morphological close / dilate→erode) before components, with the kernel sized to the largest gap you still consider “visually continuous” (see Ultralytics YOLO segmentation docs for more mask/seg usage details):# union: uint8 {0,255} union = (m.sum(0) > 0).astype(np.uint8) * 255 # bridge small gaps (tune kernel size to your expected mask discontinuities) k_close = cv2.getStructuringElement(cv2.MORPH_ELLIPSE, (25, 25)) union_closed = cv2.morphologyEx(union, cv2.MORPH_CLOSE, k_close, iterations=1) # optional: remove tiny speckles after closing k_open = cv2.getStructuringElement(cv2.MORPH_ELLIPSE, (7, 7)) union_closed = cv2.morphologyEx(union_closed, cv2.MORPH_OPEN, k_open, iterations=1) n, labels = cv2.connectedComponents(union_closed)
mslabdelhak29
Reid doesn't work how can i fix it i tried to change it True in botsort.yaml but it doesn't work
@glenn_jocher
- Glenn JocherUltralytics(edited)
@mslabdelhak29 ReID is only supported by some trackers (for example BoT-SORT), not ByteTrack, and it’s enabled via the tracker YAML you pass at runtime. Copy the default config, enable ReID explicitly, and point
track()to your copy:# custom_botsort.yaml tracker_type: botsort with_reid: True model: yolo26n-cls.pt # or another YOLO classification weight you have locallyfrom ultralytics import YOLO model = YOLO("yolo26n.pt") # any YOLO detector results = model.track(source="path/to/video.mp4", tracker="custom_botsort.yaml", persist=True, show=False)If it still doesn’t work, you’re likely editing a different YAML than the one being loaded; always pass the path as above. Also share the output of
yolo checksand the exactcustom_botsort.yamlyou used so we can verify your environment and keys. See the ReID section in the tracking guide and the BoT-SORT config for details: Multi‑Object Tracking docs and botsort.yaml config.