Ultralytics YOLO26 ile Örnek Segmentasyonu ve İzleme
Örnek Segmentasyonu Nedir?#
Örnek segmentasyonu, görüntüdeki tek tek nesneleri piksel düzeyinde tanımlamayı ve ana hatlarını belirlemeyi içeren bir bilgisayarlı görü görevidir. Pikselleri yalnızca kategorilere göre sınıflandıran anlamsal segmentasyondan farklı olarak örnek segmentasyonu, her nesne örneğini benzersiz biçimde etiketler ve sınırlarını kesin olarak belirler. Bu özellik, tıbbi görüntüleme, otonom sürüş ve endüstriyel otomasyon gibi ayrıntılı mekânsal anlayış gerektiren uygulamalar için kritik önem taşır.
Ultralytics YOLO26, YOLO modellerinin bilinen hızını ve verimliliğini korurken nesne sınırlarını hassas biçimde belirler.
Ultralytics paketinde iki tür örnek segmentasyonu izleme yöntemi kullanılabilir:
-
Sınıf Nesneleriyle Örnek Segmentasyonu: Görsel ayrımı belirginleştirmek için her sınıf nesnesine benzersiz bir renk atanır.
-
Nesne İzleriyle Örnek Segmentasyonu: Her iz farklı bir renkle gösterilir; böylece nesneleri video kareleri boyunca kolayca tanımlayıp izleyebilirsin.
İzle: Ultralytics YOLO26 ile Nesne Takibi Kullanarak Örnek Segmentasyonu
Örnekler#
| Örnek Segmentasyonu | Örnek Segmentasyonu + Nesne İzleme |
|---|---|
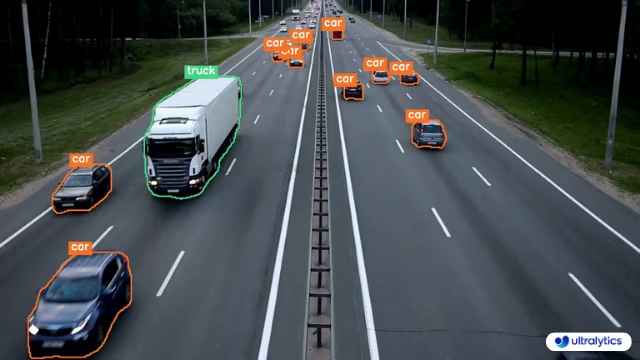 | 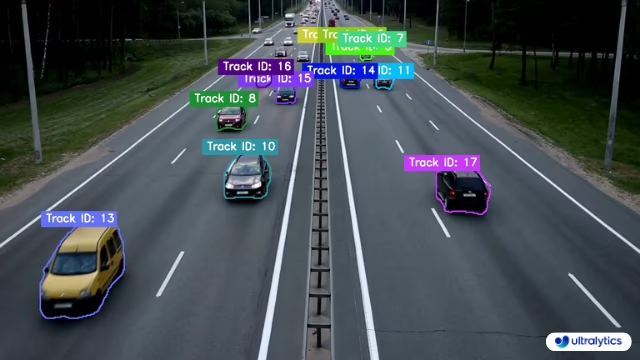 |
| Ultralytics Örnek Segmentasyonu | Nesne İzlemeli Ultralytics Örnek Segmentasyonu |
YOLO26 ile Segmentasyon ve İzleme#
InstanceSegmentation çözümü, her karede bir YOLO26 segmentasyon modeli çalıştırır, nesne başına maskeler çizer ve her örneği ayrı renklendirerek video boyunca tek tek nesneleri izlemeni sağlar. YOLO26n-seg gibi bir -seg modeli yükle, ardından Python API'si veya CLI ile kaynağın üzerinde çalıştır.
# Instance segmentation using Ultralytics YOLO26
yolo solutions isegment show=True

# Pass a source video
yolo solutions isegment source="path/to/video.mp4"

# Monitor the specific classes
yolo solutions isegment classes="[0, 5]"
InstanceSegmentation Bağımsız Değişkenleri#
Aşağıda InstanceSegmentation bağımsız değişkenlerini içeren bir tablo bulabilirsin:
| Bağımsız değişken | Tür | Varsayılan | Açıklama |
|---|---|---|---|
model | str | None | Ultralytics YOLO model dosyasının yolu. |
line_width | int | 2 | Çözümün çizdiği kutular, anahtar noktalar ve sayılar için çizgi kalınlığı. |
verbose | bool | True | Çözümün her kare için girdi şekli, sınıf sayıları ve işleme hızına ilişkin günlüğünü etkinleştirir. İzleme çağrısının kendisi her zaman sessizdir. |
InstanceSegmentation çözümünde track bağımsız değişkenlerini de kullanabilirsin:
| Bağımsız değişken | Tür | Varsayılan | Açıklama |
|---|---|---|---|
tracker | str | 'tracktrack.yaml' | Kullanılacak izleme algoritmasını belirtir. Yerleşik seçenekler: botsort.yaml, bytetrack.yaml, ocsort.yaml, deepocsort.yaml, fasttrack.yaml, tracktrack.yaml. |
conf | float | 0.25 | Algılamalar için güven eşiğini belirler; düşük değerler daha fazla nesnenin izlenmesine olanak tanır ancak yanlış pozitifleri de içerebilir. |
iou | float | 0.5 | Çakışan algılamaları filtrelemek için Kesişim-Birleşim Oranı (IoU) eşiğini belirler. |
classes | list | None | Sonuçları sınıf dizinine göre filtreler. Örneğin, classes=[0, 2, 3] yalnızca belirtilen sınıfları izler. |
device | str | None | Çıkarım için kullanılacak cihazı belirtir (ör. cpu, cuda:0 veya 0). Kullanıcıların model yürütme için CPU, belirli bir GPU veya başka hesaplama cihazları arasında seçim yapmasına olanak tanır. |
imgsz | int or tuple | 640 | Hedef çıkarım görüntü boyutu: kare görüntüler için bir tam sayı veya bir (height, width) çifti. Boyutlar model adım değerine göre ayarlanır. |
max_det | int | 300 | Yoğun sahnelerde bir çözümün işleyeceği nesne sayısını sınırlamak için izleme öncesinde kare başına tutulan en yüksek algılama sayısı. |
quantize | int or str | None | Çıkarım hassasiyeti: CPU dışında PyTorch ve TorchScript modelleri için 16 (FP16) veya 32/unset (FP32); diğer biçimler, model yapıtının ve çalışma zamanının seçtiği hassasiyeti kullanır. Kullanımdan kaldırılan half argümanının yerini alır. |
Ayrıca aşağıdaki görselleştirme bağımsız değişkenleri kullanılabilir:
| Bağımsız değişken | Tür | Varsayılan | Açıklama |
|---|---|---|---|
show | bool | False | True ise açıklama eklenmiş görüntüleri veya videoları bir pencerede gösterir. Geliştirme veya test sırasında anında görsel geri bildirim almak için kullanışlıdır. |
show_conf | bool | True | Her algılamanın güven puanını etiketinin yanında gösterir. Modelin her algılamaya ne kadar güvendiğini görmeni sağlar. |
show_labels | bool | True | Görsel çıktıda her algılama için etiketleri gösterir. Algılanan nesnelerin hemen anlaşılmasını sağlar. |
show_boxes | bool | True | Algılanan nesnelerin çevresine sınırlayıcı kutular çizer. Görüntülerde veya video karelerinde nesneleri görsel olarak tanımlamak ve konumlarını belirlemek için gereklidir. |
Örnek Segmentasyonu Uygulamaları#
YOLO26 ile örnek segmentasyonu, çeşitli sektörlerde çok sayıda gerçek dünya uygulamasına sahiptir:
Atık Yönetimi ve Geri Dönüşüm#
YOLO26, farklı malzeme türlerini tanımlamak ve ayırmak için atık yönetim tesislerinde kullanılabilir. Model; plastik atıkları, kartonu, metali ve geri dönüştürülebilir diğer malzemeleri yüksek hassasiyetle segmente ederek otomatik ayrıştırma sistemlerinin atıkları daha verimli işlemesini sağlar. Dünya genelinde üretilen 7 milyar ton plastik atığın yalnızca yaklaşık %10'unun geri dönüştürüldüğü düşünüldüğünde bu özellikle değerlidir.
Otonom Araçlar#
Otonom araçlarda örnek segmentasyonu; yayaları, araçları, trafik işaretlerini ve yoldaki diğer unsurları piksel düzeyinde belirlemeye ve izlemeye yardımcı olur. Çevrenin bu hassas biçimde anlaşılması, seyrüsefer ve güvenlik kararları açısından kritik önem taşır. YOLO26'nın gerçek zamanlı performansı, onu zamana duyarlı bu uygulamalar için son derece uygun kılar.
Tıbbi Görüntüleme#
Örnek segmentasyonu, tıbbi taramalardaki tümörleri, organları veya hücresel yapıları tanımlayıp sınırlarını belirleyebilir. YOLO26'nın nesne sınırlarını hassas biçimde belirleme yeteneği, onu tıbbi tanılama ve tedavi planlaması için değerli kılar.
Şantiye İzleme#
İnşaat sahalarında örnek segmentasyonu ağır makineleri, çalışanları ve malzemeleri izleyebilir. Bu, ekipman konumlarını takip ederek ve çalışanların tehlikeli alanlara girdiğini algılayarak güvenliği sağlamaya yardımcı olur; aynı zamanda iş akışını ve kaynak dağılımını optimize eder.
Sık Sorulan Sorular#
Ultralytics YOLO26 ile örnek segmentasyonu yapmak için
InstanceSegmentationçözümünü bir YOLO26 segmentasyon modeli ile başlat ve video karelerini bu çözümden geçir. Basitleştirilmiş bir kod örneği:import cv2 from ultralytics import solutions cap = cv2.VideoCapture("path/to/video.mp4") assert cap.isOpened(), "Error reading video file" # Video yazıcısı w, h, fps = (int(cap.get(x)) for x in (cv2.CAP_PROP_FRAME_WIDTH, cv2.CAP_PROP_FRAME_HEIGHT, cv2.CAP_PROP_FPS)) video_writer = cv2.VideoWriter("instance-segmentation.avi", cv2.VideoWriter_fourcc(*"mp4v"), fps, (w, h)) # ÖrnekSegmentasyonuBaşlat isegment = solutions.InstanceSegmentation( show=True, # çıktıyı görüntüle model="yolo26n-seg.pt", # YOLO26 ile nesne segmentasyonu için model="yolo26n-seg.pt". ) # Videoyu işle while cap.isOpened(): success, im0 = cap.read() if not success: print("Video frame is empty or processing is complete.") break results = isegment(im0) video_writer.write(results.plot_im) cap.release() video_writer.release() cv2.destroyAllWindows()Örnek segmentasyonu, bir görüntüdeki nesneleri tek tek belirler ve ana hatlarını çıkarır; her nesneye benzersiz bir etiket ve maske verir. Nesne izleme, video kareleri boyunca nesnelere tutarlı kimlikler atayarak bunu genişletir ve aynı nesnelerin zaman içindeki kesintisiz takibini sağlar. YOLO26'nın uygulamasında olduğu gibi bu iki yöntem bir araya geldiğinde, hassas sınır bilgilerini korurken videolardaki nesne hareketlerini ve davranışlarını inceleyebilirsin.
Ultralytics YOLO26, Mask R-CNN veya Faster R-CNN gibi iki aşamalı modellere kıyasla gerçek zamanlı performans, rekabetçi doğruluk ve kullanım kolaylığı sunar. YOLO26, görüntüleri tek geçişte (tek aşamalı algılama) işler; böylece yüksek hassasiyeti korurken çok daha hızlı çalışır. Ayrıca modelleri, veri kümelerini ve eğitim işlem hatlarını yönetmek için Ultralytics Platform ile entegre olur. Hem hız hem doğruluk gerektiren uygulamalarda YOLO26 güçlü bir denge sunar.
Evet, Ultralytics örnek segmentasyonu için YOLO26 modellerini eğitmeye uygun çeşitli veri kümeleri sunar. Bunlar arasında COCO-Seg, COCO8-Seg (hızlı test için daha küçük bir alt küme), Package-Seg ve Crack-Seg bulunur. Bu veri kümeleri, örnek segmentasyonu görevleri için gereken piksel düzeyinde açıklamalarla birlikte gelir. Daha özel uygulamalar için Ultralytics biçimini izleyerek özel veri kümeleri de oluşturabilirsin. Veri kümeleriyle ilgili tüm bilgilere ve kullanım talimatlarına Ultralytics Veri Kümeleri belgelerinden ulaşabilirsin.


Yorumlar99
Bir soru sor, sonuçlarını paylaş veya başka birine yardım et.
CatFatOw
Hello, I am trying to analyze a video and see if features grow/shrink over time. I am currently trying to use instance segmentation with object tracking; however, specifying
save_txt=Trueparameter inmodel.tracksaves every single prediction into a single huge txt file. Trying to count the frames by going through this large txt apparently doesn't work as the class ID are not in order and sorting it would lose all information.Is there any way for Ultralytics to save the txt files by frame number? For example, frame1.txt only contains the predictions of the first frame.
Any help would be greatly appreciated!
1 Glenn JocherUltralytics
For per-frame TXT saving with tracking, you'll need to process results in your video loop and write custom frame-specific files. Here's a minimal adaptation of the Instance Segmentation and Tracking example:
frame_count = 0
while cap.isOpened():
    ret, im0 = cap.read()
    if not ret: break

    results = model.track(im0, persist=True)

    # Save current frame's tracked objects
    with open(f'frame{frame_count}.txt', 'w') as f:
        for box, mask, track_id in zip(results[0].boxes, results[0].masks, results[0].boxes.id.int().cpu().tolist()):
            f.write(f"{track_id} {box.cls.item()} {box.xywhn.tolist()} {mask.xy[0].tolist()}\n")

    frame_count += 1
This creates individual frameX.txt files with tracking IDs, class IDs, normalized boxes, and mask coordinates. The official documentation shows similar frame processing in the Instance Segmentation with Object Tracking examples.
Thank you!
- Glenn JocherUltralytics
For per-frame TXT saving during tracking, you'll need to process each frame individually in your video loop as shown in the Instance Segmentation with Object Tracking example. Here's a minimal adaptation that creates frame-specific files:
frame_count = 0
while cap.isOpened():
    ret, im0 = cap.read()
    if not ret: break

    results = model.track(im0, persist=True)

    with open(f'frame{frame_count}.txt', 'w') as f:
        for box, mask, track_id in zip(results[0].boxes, results[0].masks, results[0].boxes.id.int().cpu().tolist()):
            f.write(f"{track_id} {box.cls.item()} {box.xywhn.tolist()} {mask.xy[0].tolist()}\n")

    frame_count += 1
This creates individual frameX.txt files with tracking IDs, class IDs, normalized boxes, and mask coordinates per frame. The approach mirrors the frame processing shown in our official tracking documentation.
pedmindset
Been trying to figure this out for a while now. I want to ask, can I use object counting in regions with instance sementation and tracking? You want to count vehicles that cross two specific regions, like so Object 001 crossed region A and region B. Is this possible to do
1- Glenn JocherUltralytics
@pedmindset yes, it is possible to combine object counting in regions with instance segmentation and tracking using Ultralytics YOLO11. You can use the
trackmethod to assign consistent IDs to objects across frames and define regions to monitor their crossings. For guidance, refer to the segmentation and tracking examples in the Instance Segmentation and Tracking Guide. Let us know if you need further clarification!
DP1701
Cool, but I can't define an imgsz via solutions.InstanceSegmentation(…). Is there another option for this?
- Glenn JocherUltralytics
solutions.InstanceSegmentationis a higher-level wrapper and doesn’t currently exposeimgszdirectly; if you need to control input size, run segmentation+tracking via the coreYOLO(...).track()API (supportsimgsz) as shown in the Tracking mode docs and keep using the Instance Segmentation and Tracking guide for solution-level usage.from ultralytics import YOLO model = YOLO("yolo26n-seg.pt") results = model.track(source="path/to/video.mp4", imgsz=640, show=True, tracker="botsort.yaml")
Hello, I noticed that when using tracking mode compared to normal segmentation prediction, the number of features predicted decreased by quite a lot for feature dense videos even if I use the same parameters of confidence and maximum detection?
- Glenn JocherUltralytics
@CatFatOw great observation! This is actually expected behavior when using tracking mode compared to plain segmentation. Tracking algorithms apply additional filtering beyond confidence thresholds to maintain stable tracks, which can reduce the total number of detections.
Here are a few things that might help increase detections while maintaining tracking:
# Try adjusting these tracking-specific parameters
results = model.track(
    frame,
    persist=True,
    conf=0.3,  # Lower confidence threshold
    iou=0.5,   # Adjust IoU threshold for NMS
    max_det=1000,  # Increase max detections
    tracker="bytetrack.yaml"  # Try different trackers
)
You can also experiment with different tracking algorithms - ByteTrack tends to be more permissive with new track creation compared to BoTSORT. The trade-off is between detection sensitivity and tracking stability, where tracking prioritizes consistent object IDs over detecting every possible instance.
If you need maximum detection sensitivity, consider running both modes and using tracking results only when you need the temporal consistency.
Ok, thank you for the reply!
Mauricio566
Hello. Please, I need your help. I know exactly what segmenting an object is and how to do it. But I don't know what to do with an already segmented object or pixel mask. You can find a lot of information online about "how to segment a model or fit it to your dataset," but they don't tell you what to do with those masks in real projects. Can you give me some ideas or help, please? for r in results:
if r.masks is not None: mask = r.masks.data[0].cpu().numpy() there is the mask but honestly I don't know what to do. thankse-roe
Hello Glenn, thanks for the example! Actually, I had already figured it out—it was more of a suggestion for the documentation examples. []´s
- Glenn JocherUltralytics
Thank you for the suggestion! We always welcome community contributions to improve our documentation through GitHub Pull Requests. Feel free to submit any specific improvements you'd like to see in the Instance Segmentation with Object Tracking guide.
1
Hello, Wouldn't it be good to have a complete example showing how to extract the track ID, contour points, class, and confidence? These methods that handle everything automatically end up being of little practical use, and finding this information in the documentation is quite challenging—it's often easier to find from third-party sources. []´s
- Glenn JocherUltralytics(düzenlendi)
@e-roe thanks for your feedback! You can access track IDs, classes, masks, and confidence scores directly from the results object. Here's a concise example showing how to extract these details:
results = isegment(im0)
for i in range(len(isegment.clss)):
    track_id = isegment.track_ids[i]
    class_name = isegment.names[isegment.clss[i]]
    confidence = isegment.confs[i]
    mask = isegment.masks[i].data[0].numpy()  # Binary mask array
    contours, _ = cv2.findContours(mask.astype(np.uint8), cv2.RETR_EXTERNAL, cv2.CHAIN_APPROX_SIMPLE)
For full implementation details, see the InstanceSegmentation reference in our documentation. Let us know if you need further clarification!
expen6ve
Hi! I tried training a pretrained yolov8m-seg model on our custom 1 class dataset consisting of 1,307 images with 5 augmentations like:
Flip: Horizontal, Vertical Rotation: Between -15° and +15° Saturation: Between -25% and +25% Blur: Up to 1.4px Noise: Up to 1.49% of pixels
with these training configurations:
# Train the model
results = model.train(
    data="data6.yaml",
    epochs=250,
    imgsz=320,
    batch=8,
    workers=4,
    device=device,
    patience=18,
    copy_paste=0.1  # Add this line to enable copy-paste augmentation
)
this is my 16th model training as i tried testing out from 200+ images that and so on. In my val plots, i always get bad results. What can i further do to make a good model? it stopped training at 128 with the results below:
epoch,time,train/box_loss,train/seg_loss,train/cls_loss,train/dfl_loss,metrics/precision(B),metrics/recall(B),metrics/mAP50(B),metrics/mAP50-95(B),metrics/precision(M),metrics/recall(M),metrics/mAP50(M),metrics/mAP50-95(M),val/box_loss,val/seg_loss,val/cls_loss,val/dfl_loss,lr/pg0,lr/pg1,lr/pg2
126,4123.96,0.47628,0.76702,0.30532,0.85667,0.9862,0.96565,0.98972,0.94445,0.9775,0.97566,0.98923,0.83189,0.35178,0.67432,0.26286,0.89191,0.00101,0.00101,0.00101 127,4156.45,0.47613,0.76458,0.30439,0.85872,0.96877,0.98339,0.98913,0.94227,0.98701,0.96962,0.99053,0.83626,0.34228,0.67744,0.25083,0.88958,0.00100208,0.00100208,0.00100208
- Glenn JocherUltralytics(düzenlendi)
@expen6ve thank you for sharing your training details. For improved segmentation results with YOLO26, consider these adjustments:
- Dataset Size: 1.3k images may be insufficient for robust segmentation. Aim for ≥5k high-quality annotated images.
- Augmentation Tuning: Reduce rotation range (try ±5°) and remove noise augmentation, which can degrade mask precision.
- Hyperparameters: Increase imgsz to 640 (standard for segmentation tasks) and lower learning rate to 0.0001 with cosine scheduler.
- Model Selection: Try YOLO26s-seg instead of medium-sized models for better generalization on limited data.
For detailed guidance, see the Segmentation Training Tips in our documentation.
ShreyasChhetri
Hi can we implement a Reinforcement Learning function up above the Yolo training function for more accuracy can it happen ?
- Glenn JocherUltralytics
@ShreyasChhetri integrating reinforcement learning (RL) with YOLO training is an interesting idea, but YOLO models are not inherently designed for RL workflows. While it is theoretically possible, it would require substantial custom development outside the scope of the provided Ultralytics framework. You might consider exploring hybrid approaches combining RL and computer vision if your use case demands it. For standard training, refer to the existing YOLO training documentation: https://docs.ultralytics.com/modes/train.
ZhangAiyi
I have a question when run the code for Instance Segmentation with Object Tracking. The pycharm said UnicodeEncodeError: 'gbk' codec can't encode character '\u274c' in position 401: illegal multibyte sequence. Does anyone have the similar question? Thank you.
- Glenn JocherUltralytics
@ZhangAiyi it seems like you're encountering a Unicode encoding issue. You can try setting your environment's encoding to UTF-8 in PyCharm to resolve this. If the problem persists, please check the PyCharm settings or your system's locale configuration.