Ultralytics YOLO11 的 Sony IMX500 导出
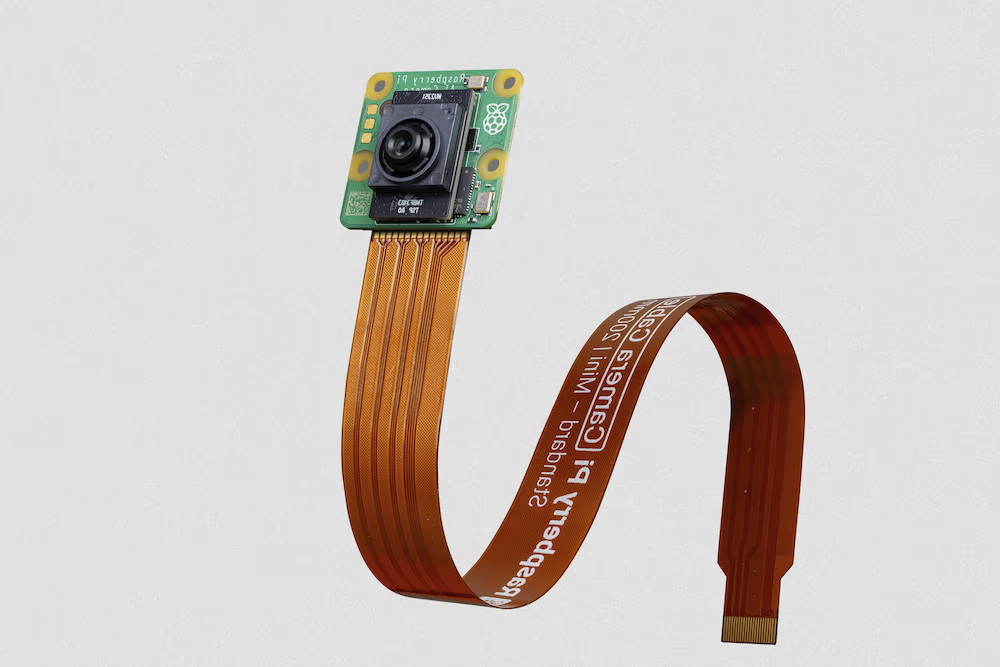
本指南介绍如何将 Ultralytics YOLOv8n 和 YOLO11n 模型导出并部署到搭载 Sony IMX500 传感器的 Raspberry Pi AI Camera。
在计算能力有限的设备(例如 Raspberry Pi AI Camera)上部署计算机视觉模型可能颇具挑战。使用针对更快性能优化的模型格式会带来显著差异。
IMX500 模型格式旨在以极低功耗为神经网络提供高速性能。它可以优化你的 Ultralytics YOLO11 模型,实现高速、低功耗推理。本指南将介绍如何将模型导出为 IMX500 格式,并部署到 Raspberry Pi AI Camera。
为什么要导出为 IMX500 格式?#
Sony 的 IMX500 智能视觉传感器可直接在传感器上运行 AI 处理,Sony 称这是智能视觉传感器领域的世界首创。它有助于克服常见的边缘 AI挑战,包括数据处理瓶颈、隐私问题和性能限制。 传统传感器只能传递图像和视频帧,而 IMX500 可以解读捕获的内容,让设备实时生成洞察。
Sony IMX500 对 YOLO11 模型的导出#
IMX500 旨在直接在传感器上处理数据,无需将数据发送到云端处理。
IMX500 可处理量化模型。量化可以缩小模型并提升速度,同时不会显著损失准确率。它适合边缘计算资源有限的特点,可通过降低延迟并在本地快速处理数据来加快应用响应,无需依赖云端。本地处理还可以保护用户数据的隐私和安全,因为数据不会发送到远程服务器。
IMX500 的主要特性:
- 元数据输出:IMX500 不仅可以传输图像,还可以同时输出图像和元数据(推理结果);也可以仅输出元数据,以尽量减小数据量、降低带宽占用和成本。
- 解决隐私问题:通过在设备上处理数据,IMX500 能够解决隐私问题,因此非常适合人数统计和占用情况跟踪等以人为中心的应用。
- 实时处理:快速的传感器端处理可支持自主系统等边缘 AI 应用进行实时决策。
开始之前:为获得最佳效果,请参照我们的模型训练指南、数据集概览和超参数调优指南,确保你的 YOLO11 模型已做好充分准备,可以导出。
支持的任务#
IMX500 导出支持 Ultralytics 七种任务中的四种,且仅适用于 YOLOv8n 和 YOLO11n:不支持其他模型系列、尺寸和架构;导出语义分割、OBB 或深度估计模型会引发错误。
使用示例#
将 Ultralytics YOLO11 模型导出为 IMX500 格式,并使用导出的模型运行推理。
IMX500 格式支持导出、预测和验证模式。Ultralytics 推理和验证会在主机 CPU 上运行导出的 model_imx.onnx。
此处的推理仅用于确认导出的模型运行符合预期,之后再将模型部署到 Raspberry Pi AI Camera。
from ultralytics import YOLO

# 加载 YOLO11n PyTorch 模型
model = YOLO("yolo11n.pt")

# 导出模型
model.export(format="imx", data="coco8.yaml")  # 默认使用 PTQ 量化进行导出

# 加载导出的模型
imx_model = YOLO("yolo11n_imx_model")

# 运行推理
results = imx_model("https://ultralytics.com/images/bus.jpg")from ultralytics import YOLO
# 加载 YOLO11n-pose PyTorch 模型
model = YOLO("yolo11n-pose.pt")
# 导出模型
model.export(format="imx", data="coco8-pose.yaml") # 默认使用 PTQ 量化进行导出
# 加载导出的模型
imx_model = YOLO("yolo11n-pose_imx_model")
# 运行推理
results = imx_model("https://ultralytics.com/images/bus.jpg")from ultralytics import YOLO
# 加载 YOLO11n-cls PyTorch 模型
model = YOLO("yolo11n-cls.pt")
# 导出模型
model.export(format="imx", data="imagenet10") # 默认使用 PTQ 量化进行导出
# 加载导出的模型
imx_model = YOLO("yolo11n-cls_imx_model")
# 运行推理
results = imx_model("https://ultralytics.com/images/bus.jpg", imgsz=224)from ultralytics import YOLO
# 加载 YOLO11n-seg PyTorch 模型
model = YOLO("yolo11n-seg.pt")
# 导出模型
model.export(format="imx", data="coco8-seg.yaml") # 默认使用 PTQ 量化进行导出
# 加载导出的模型
imx_model = YOLO("yolo11n-seg_imx_model")
# 运行推理
results = imx_model("https://ultralytics.com/images/bus.jpg")from ultralytics import YOLO
# 加载导出的 IMX500 模型
model = YOLO("yolo11n_imx_model")
# 在 COCO8 数据集上验证准确率
metrics = model.val(data="coco8.yaml")IMX 导出仅支持在 Linux 上使用 Python 3.10–3.12,且需要 Java 17 或更高版本。Ultralytics 包会在运行时安装额外的导出依赖。首次运行导出命令后,你可能需要重启控制台,以确保其正常工作。
导出参数#
| 参数 | 类型 | 默认值 | 说明 |
|---|---|---|---|
format | str | 'imx' | 导出模型的目标格式,用于定义与各种部署环境的兼容性。 |
imgsz | int 或 tuple | 640 | 模型输入所需的图像尺寸。正方形图像可使用整数;若要指定具体尺寸,则可使用元组 (height, width)。 |
quantize | int 或 str | 8/自动 | 量化精度。IMX500 要求使用 8 (INT8/PTQ),并会自动启用。不支持仅使用 FP32 或 FP16 导出。此设置取代已弃用的 half/int8 标志。 |
data | str | None | 数据集 YAML 文件的路径,是量化所必需的;分类任务则需要数据集目录或内置数据集名称。如果未指定,Ultralytics 会根据模型任务选择默认校准数据集。 |
fraction | float、int 或 list | 1.0 | 校准子集,可按比例、图像数量或 [train, val, test] 比例/数量指定。包含两个项目的列表会让 test 保持完整,而 0 会跳过它。 |
nms | bool,可选 | None | 选择原始输出(None,默认)、嵌入式 NMS(True)或无 NMS 检测头(False)。对于检测、分割和姿态任务,IMX 要求使用 nms=True,并会自动选择该选项。 |
device | str | None | 指定导出设备:GPU(device=0)、CPU(device=cpu)。 |
有关导出流程的更多详情,请访问 Ultralytics 导出文档页面。
导出过程会创建一个名为 <model-name>_imx_model 的目录。该目录包含用于量化验证的 model_imx.onnx,以及用于将模型打包并部署到 IMX500 硬件的必需文件 packerOut.zip。此外,<model-name>_imx_model 文件夹中会包含文本文件(labels.txt),列出与模型关联的所有标签。
yolo11n_imx_model
├── dnnParams.xml
├── labels.txt
├── packerOut.zip
├── model_imx.onnx
├── model_imx_MemoryReport.json
└── model_imx.pbtxt
在部署中使用 IMX500 导出#
将 Ultralytics YOLO11n 模型导出为 IMX500 格式后,你可以将其部署到 Raspberry Pi AI Camera 上进行推理。
硬件前提条件#
请确保你准备了以下硬件:
- Raspberry Pi 5 或 Raspberry Pi 4 Model B
- Raspberry Pi AI Camera
将 Raspberry Pi AI Camera 连接到 Raspberry Pi 上的 15 针 MIPI CSI 接口,然后为 Raspberry Pi 接通电源。
软件前提条件#
本指南已在运行 Raspberry Pi OS Bookworm 的 Raspberry Pi 5 上通过测试。
步骤 1:打开终端窗口,执行以下命令,将 Raspberry Pi 软件更新到最新版本。
sudo apt update && sudo apt full-upgrade步骤 2:安装运行 IMX500 传感器所需的 IMX500 固件。
sudo apt install imx500-all步骤 3:重启 Raspberry Pi,使更改生效。
sudo reboot步骤 4:安装 AITRIOS Raspberry Pi 应用模块库
pip install git+https://github.com/SonySemiconductorSolutions/aitrios-rpi-application-module-library.git步骤 5:使用以下脚本运行 YOLO11 目标检测、姿势估计、分类和分割任务;这些脚本位于 aitrios-rpi-application-module-library 示例中。
运行这些脚本之前,请根据你的环境替换 model_file 和 labels.txt 目录。
import numpy as np
from modlib.apps import Annotator
from modlib.devices import AiCamera
from modlib.models import COLOR_FORMAT, MODEL_TYPE, Model
from modlib.models.post_processors import pp_od_yolo_ultralytics

class YOLO(Model):
    """YOLO model for IMX500 deployment."""

    def __init__(self):
        """Initialize the YOLO model for IMX500 deployment."""
        super().__init__(
            model_file="yolo11n_imx_model/packerOut.zip",  # replace with proper directory
            model_type=MODEL_TYPE.CONVERTED,
            color_format=COLOR_FORMAT.RGB,
            preserve_aspect_ratio=False,
        )

        self.labels = np.genfromtxt(
            "yolo11n_imx_model/labels.txt",  # replace with proper directory
            dtype=str,
            delimiter="\n",
        )

    def post_process(self, output_tensors):
        """Post-process the output tensors for object detection."""
        return pp_od_yolo_ultralytics(output_tensors)

device = AiCamera(frame_rate=16)  # Optimal frame rate for maximum FPS of the YOLO model running on the AI Camera
model = YOLO()
device.deploy(model)

annotator = Annotator()

with device as stream:
    for frame in stream:
        detections = frame.detections[frame.detections.confidence > 0.55]
        labels = [f"{model.labels[class_id]}: {score:0.2f}" for _, score, class_id, _ in detections]

        annotator.annotate_boxes(frame, detections, labels=labels, alpha=0.3, corner_radius=10)
frame.display()基准测试#
以下 YOLOv8n、YOLO11n、YOLOv8n-pose、YOLO11n-pose、YOLOv8n-cls 和 YOLO11n-cls 基准测试由 Ultralytics 团队在 Raspberry Pi AI 摄像头上使用 imx 模型格式运行,测量速度和精度。
| 模型 | 格式 | 尺寸(像素) | packerOut.zip 的大小(MB) | mAP50-95(B) | 推理时间 (ms/im) |
|---|---|---|---|---|---|
| YOLOv8n | imx | 640 | 2.1 | 0.470 | 58.79 |
| YOLO11n | imx | 640 | 2.2 | 0.517 | 58.82 |
| YOLOv8n-pose | imx | 640 | 2.0 | 0.687 | 58.79 |
| YOLO11n-pose | imx | 640 | 2.1 | 0.788 | 62.50 |
| 模型 | 格式 | 尺寸(像素) | packerOut.zip 的大小(MB) | 准确率 (top1) | 准确率 (top5) | 推理时间 (ms/im) |
|---|---|---|---|---|---|---|
| YOLOv8n-cls | imx | 224 | 2.3 | 0.25 | 0.5 | 33.31 |
| YOLO11n-cls | imx | 224 | 2.3 | 0.25 | 0.417 | 33.31 |
上述基准测试验证使用的数据集包括:检测模型使用 COCO128,姿势估计模型使用 COCO8-Pose,分类模型使用 ImageNet10。
底层原理#
Sony 模型压缩工具包 (MCT)#
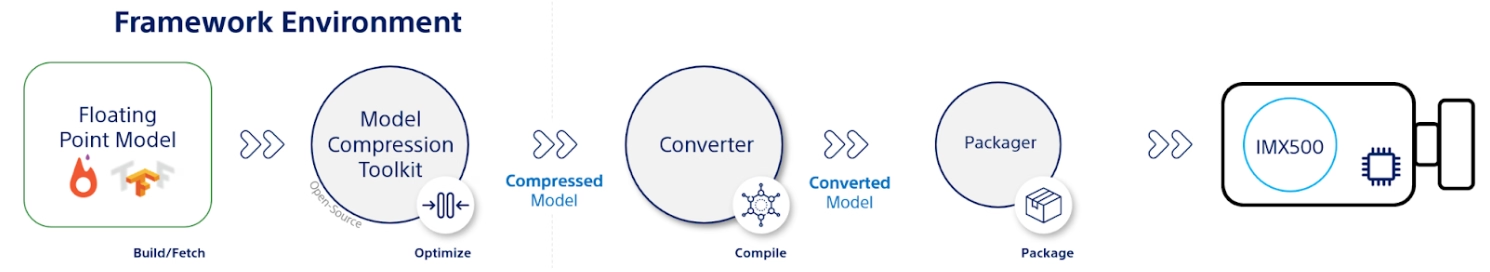
Sony 模型压缩工具包(MCT)是一款通过量化和剪枝优化深度学习模型的工具包。它支持多种量化方法,并提供高级算法,在不显著牺牲准确率的情况下缩小模型尺寸、降低计算复杂度。MCT 特别适合在资源受限的设备上部署模型,可实现高效推理并降低延迟。
MCT 支持的功能#
Sony 的 MCT 提供了多种功能,用于优化神经网络模型:
- 计算图优化:通过将批量归一化等层折叠到前序层中,把模型转换为更高效的版本。
- 量化参数搜索:使用均方误差、无裁剪和平均绝对误差等指标,将量化噪声降至最低。
- 高级量化算法:
- 负向偏移校正:解决对称激活量化导致的性能问题。
- 离群值过滤:使用 z 分数检测并移除离群值。
- 聚类:使用非均匀量化网格,以更好地匹配分布。
- 混合精度搜索:根据敏感度为每一层分配不同的量化位宽。
- 可视化:使用 TensorBoard 查看模型性能洞察、量化阶段和位宽配置。
量化#
MCT 支持多种量化方法,可缩小模型并提升推理速度:
- 训练后量化(PTQ):
- 可通过 Keras 和 PyTorch API 使用。
- 复杂度:低
- 计算成本:低(CPU 分钟级)
- 基于梯度的训练后量化(GPTQ):
- 可通过 Keras 和 PyTorch API 使用。
- 复杂度:中
- 计算成本:中等(2-3 GPU 小时)
- 量化感知训练(QAT):
- 复杂度:高
- 计算成本:高(12-36 GPU 小时)
MCT 还支持对权重和激活使用多种量化方案:
- 二的幂次(适合硬件)
- 对称
- 均匀
结构化剪枝#
MCT 引入了结构化、硬件感知的模型剪枝,专为特定硬件架构设计。该技术通过剪除 SIMD 组,利用目标平台的单指令多数据(SIMD)能力。它可以缩小模型尺寸并降低复杂度,同时优化通道利用率,使其与 SIMD 架构相匹配,从而有针对性地利用权重内存。可通过 Keras 和 PyTorch API 使用。
IMX500 转换工具(编译器)#
IMX500 Converter Tool 是 IMX500 工具集的重要组成部分,可编译模型并部署到 Sony 的 IMX500 传感器(例如 Raspberry Pi AI Camera)。它会将量化后的 Ultralytics YOLO11 模型编译为可在目标硬件上高效运行的格式。量化后,导出过程会生成包含模型数据和设备专用配置的二进制文件,以便部署到 Raspberry Pi AI Camera。
实际应用场景#
导出为 IMX500 格式适用于多个行业。以下是一些示例:
- 边缘 AI 和物联网:在无人机或安防摄像头上实现目标检测,这类场景需要在低功耗设备上进行实时处理。
- 可穿戴设备:在健康监测可穿戴设备上部署针对小规模 AI 处理进行优化的模型。
- 智慧城市:使用导出为 IMX500 格式的 YOLO11 模型进行交通监控和安全分析,实现更快的处理速度和更低的延迟。
- 零售分析:在销售点系统或智能货架中部署优化后的模型,提升店内监控能力。
结论#
将 Ultralytics YOLO11 模型导出为 Sony 的 IMX500 格式后,你就可以将模型部署到基于 IMX500 的摄像头上,实现高效推理。量化可以缩小模型尺寸并提升推理速度,同时只会轻微降低准确率。
如需了解更多信息和详细指南,请参阅 Sony 的 IMX500 网站。
常见问题#
要将 YOLO11 模型导出为 IMX500 格式,请使用 Python API 或 CLI 命令:
from ultralytics import YOLO

model = YOLO("yolo11n.pt")
model.export(format="imx")  # 默认使用 PTQ 量化导出
导出过程会创建一个目录,其中包含部署所需的文件,包括
packerOut.zip。IMX500 格式为边缘部署提供了多项重要优势:
- 芯片上的 AI 处理可降低延迟和功耗
- 同时输出图像和元数据(推理结果),而不只是图像
- 在本地处理数据,无需依赖云端,从而增强隐私保护
- 具备实时处理能力,适合对时效性要求高的应用
- 经过优化的量化方式,可在资源受限的设备上高效部署模型
要部署 IMX500 模型,你需要:
硬件:
- Raspberry Pi 5 或 Raspberry Pi 4 Model B
- 配备 IMX500 传感器的 Raspberry Pi AI Camera
软件:
- Raspberry Pi OS Bookworm
- IMX500 固件和工具(
sudo apt install imx500-all)
根据 Ultralytics 在 Raspberry Pi AI Camera 上进行的基准测试:
- YOLO11n 单张图像推理耗时为 58.82ms
- COCO128 数据集上的 mAP50-95 为 0.517
- 量化后模型大小仅为 2.2MB
这表明 IMX500 格式能够实现高效的实时推理,同时为边缘 AI 应用保持良好的精度。


评论86
提出问题、分享结果,或帮助其他人。
 Chad Walsh
where is the best place to get support on the IMX500. I am running into multiple issues: i. my first yolo11n model built fine and exported to imx500, no problem, but my second model with a LOT more training images build fine but crashed the imx500 export. ii. the output of the imx500 during inference is giving a lot of none outputs between solid recognitions. it seems like there is something interfering with or disrupting the inference outputs (e.g., good output, none, none, none, none, good output, ...). where is the best place to get help with these issues?
 Glenn JocherUltralytics
Please continue the discussion here so the Ultralytics team can help; for the export crash, share the exact export command, full text traceback, and output from
yolo checks, and for intermittentNoneresults include a minimal inference script, confidence threshold, and a short reproducible input sample. Note that IMX export uses the calibration dataset specified bydataand defaults to the full dataset, so testing a smallerfractionmay help isolate resource-related failures.
leeprevost
I've made considerable progress by moving conducting this model compression process with a Container using dtcooper/raspberrypi-os:python3.11 after considerable problems with dependencies. Now getting a container most of the way through the process of compressing my yolov11s model and its trained best.pt weights.
At the end of the process - I get a simple "killed" after the Calculation of quantization parameters step. I see memory spiking close to 100% on top and think I'm hitting OOM with my pi4 8gb.
root@a5e132f6b333:/app# yolo export model=./models/yolov11/best.pt data='Billfish-Breeds-1/data.yaml' format=imx verbos>
Ultralytics 8.3.221 🚀 Python-3.11.14 torch-2.9.0+cpu CPU (aarch64)
WARNING ⚠️ IMX export requires nms=True, setting nms=True.
YOLO11s summary (fused): 100 layers, 9,413,187 parameters, 0 gradients, 21.3 GFLOPs

PyTorch: starting from 'models/yolov11/best.pt' with input shape (1, 3, 640, 640) BCHW and output shape(s) ((1, 8400, 4>
IMX: collecting INT8 calibration images from 'data=Billfish-Breeds-1/data.yaml'
Fast image access ✅ (ping: 0.1±0.0 ms, read: 16.1±2.7 MB/s, size: 16.4 KB)
Scanning /app/Billfish-Breeds-1/valid/labels.cache... 268 images, 0 backgrounds, 0 corrupt: 100% ━━━━━━━━━━━━ 268/268 1>
WARNING ⚠️ IMX: >300 images recommended for INT8 calibration, found 268 images.

IMX: starting export with model_compression_toolkit 2.4.4...
representative_data_gen generates a batch size of 1 which can be slow for optimization: consider increasing the batch s>
WARNING:Model Compression Toolkit:OperatorSetNames.DEPTHWISE_CONV is not in model.
Statistics Collection: 268it [1:01:26, 13.76s/it]
Calculating quantization parameters: 100%|█████████████████████████████████████████████████████| 294/294 [12:44<00:00, >
Killed
Would appreciate any suggestion around this but think it probably pushes me over the edge to order my pi5? Or do I try to train on the yolov8 or yolov11n? I've not had very good success with the nano models. I've convinced myself the tradeoffs to the small is well worth it but that may be incompatible with this process?
@glenn-jocher am I posting at the right place? Put this in issues on gh?
- Glenn JocherUltralytics
@leeprevost you’re in the right place for discussion, but the OOM during IMX export is a new issue—please open a new issue for visibility. In the issue, include: the exact export command and full log,
yolo checksoutput (orultralytics.utils.checks.collect_system_info()), Java version (java --version), and the versions of IMX toolchain (pip freeze | grep -E "imx500|model-compression|sony-custom"). As immediate workarounds: export on a Linux x86_64 machine with more RAM, target YOLO11n/YOLOv8n (the IMX path is tuned for “n” models), and reduce calibration load withfraction(e.g., 0.25). Example:yolo export model=best.pt format=imx data=your.yaml imgsz=640 fraction=0.25IMX-specific knobs are summarized in the IMX500 export arguments here: Sony IMX500 export guide – Export arguments, and the exporter function requirements here: export_imx reference.
Thank you. I'll dig into the logs and see if I can add anything before opening new issue.
a few more questions and I will open an issue:
- Note that I was using a model trained on yolov11s rather than n as I've seen large degradation in the number of false positives in my model.
- I assume by "full log" you mean the output from the yolo export command with verbose at default (true). In other words, what I posted above?
- For some reason, I thought I read int he docs that i had to perform the model compression on the target machine. for me, the ultimate target is RpiZero2 but no way the model will export on that footprint . so, I went to the largest pi I have which is a Rpi4 -- that resulted in the OOM. So, am unsure by your guidance pointing me to the larger x86 linux machine. How will the process know the device limits if I perform it on that?
Trying to read these guides as best I can. I have not spent much time on the Sony site yet. If you'll point me, I don't want to start an issue that isn't an issue.
I opened an issue: https://github.com/ultralytics/ultralytics/issues/22512
Just tried the export again with the fraction=0.25 argument and got to "Optimal Solution Found" with objective measure of 0.94, then died with error:
Error x IMX: export failure 12662.7s: No module named 'onnxscript'
https://github.com/pytorch/pytorch/issues/166352 -- adding to my requirements.txt pointed to by Containerfile.
- Glenn JocherUltralytics(已编辑)
@leeprevost great progress. IMX export/quantization does not need to run on the target; it cross-compiles for IMX500, so doing it on a larger Linux host is recommended. “Full log” means the complete stdout/stderr from the export run.
The “No module named 'onnxscript'” failure is a missing dependency. Current Ultralytics installs the IMX toolchain (including
imx500-converterandmodel-compression-toolkit) itself, so upgrade withpip install -U ultralyticsand re-run the export rather than pinning old versions by hand. Let’s continue the deep-dive in the issue you opened for traceability. Ok -- @glenn-jocher: am moving this to my opened issue. Still trying this on my pi4 but can move to my dev machine with plenty of RAM + Cuda. Got further but still died with a torch error -- will post there.
- Glenn JocherUltralytics
Thanks—let’s continue in the issue for traceability. On the larger Linux host, try GPU-assisted export to reduce RAM pressure and speed up calibration; if needed, temporarily lower
imgszto validate the pipeline:yolo export model=path/to/best.pt format=imx data=path/to/data.yaml device=0 imgsz=640 # if memory is still tight during calibration yolo export model=path/to/best.pt format=imx data=path/to/data.yaml device=0 imgsz=512For a concise list of export options and behavior, see the Export mode docs at Ultralytics YOLO — Export.
Much thanks for posting this guide. Thank you.
I am having very solid success running the standard detection models right out of the box on the RpiZero 2 which is my target platform. I'm actually amazed at the power draw (ran detection/streaming for about 175 minutes on a 4400mahr battery using about 60% of its capacity). Also, very solid top/htop scores showing less than 1/8 of CPU utilization. Memory is still such a problem on a rpiz2 but not any more so than what is being used with streaming only on the pi. Still have about 50% of memory left over as I recall. I've got screen shots of top screens if needed.
But, I need to get a trained model working on my RpiZ2 and am running into problems. As the guide seemed to indicate (or perhaps Sony's), I need to do most of the quantization on my target platform. I assumed that meant my zero. I have a very good model trained with yolov11m or large. I've tried to reduce that to a nano but I'm getting too much loss of MAP scores and too much false positive rates. So, am now trying to get a yolov11s to work. On my quantization process (it was not clear how to do this with a custom model) but am first loading the yolov11s.pt and then loading my best.pt on top of that. Ultralytics successfully loads my data, gives me a warning prompt about my 290 images (< 300 not ideal) and then another about processing speed with 1 batch. The program then goes off the rails with no UI messages. I assume I'm running out of memory on the piz2. So, my next steps seem to be either:
- Start over and try with nano model.
- Do my quantization on a larger pi (i've got a spare pi4).
I guess another option would be to spend more time understanding Sony's under the hood tools to optimize those settings?
Would appreciate some guidance here down the right path.
One thing that would be very helpful is to show how to do this on something other than the target platform. i'm trying to get a small detection model to run on a rpi zero2 and hate to have to download all of my training data to the zero to do the quantization.
Idea: Have a step that allows collection of the "target_platform_capabilities" information using Sony's model compression toolkit you are using under the hood, pickle it, and then use that object to drive the model compression on a larger machine.
I could probably dig in and try to follow your code and follow the "imx" part of your export process...
bohlebots
Wie schaffe ich es, dass das Modell im Speicher des IMX500 bleibt? Die PICAM wurde ja angepriesen mit der Aussage, dass sie selbst an einem Pi zero-2 mit gleicher Geschwindigkeit läuft und in der Tat, das täte sie, aber das Modell muss jedes Mal neu aufgeladen werden, und das dauert beim Pi Zero ewig, ja selbst mit einem Pi5 dauert es Minuten. Grundsätzlich muss die imx500 aber ein Modell auch bei ausgeschaltetem Strom im Speicher halten können, so dass nach dem Anschalten das letzte Modell direkt zur Verfügung steht. Wie bekomme ich das hin?
Gruß Roland
Teo-treny
Hello ! When running object detection (step 5), I get the following error :
Exception in thread Thread-2 (_process_requests_func):
Traceback (most recent call last):
  File "/home/pi/.pyenv/versions/3.11.9/lib/python3.11/threading.py", line 1045, in _bootstrap_inner
    self.run()
  File "/home/pi/.pyenv/versions/3.11.9/lib/python3.11/threading.py", line 982, in run
    self._target(*self._args, **self._kwargs)
  File "/home/pi/Desktop/imx_test/venv/lib/python3.11/site-packages/modlib/devices/ai_camera/ai_camera.py", line 193, in _process_requests_func
    callback()
  File "/home/pi/Desktop/imx_test/venv/lib/python3.11/site-packages/modlib/devices/ai_camera/ai_camera.py", line 207, in _process_requests
    self._parse_request(req)
  File "/home/pi/Desktop/imx_test/venv/lib/python3.11/site-packages/modlib/devices/ai_camera/ai_camera.py", line 256, in _parse_request
    detections = self.model.post_process(outputs)
                 ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
  File "/home/pi/Desktop/imx_test/Test_1.py", line 23, in post_process
    return pp_od_yolo_ultralytics(output_tensors)
           ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
  File "/home/pi/Desktop/imx_test/venv/lib/python3.11/site-packages/modlib/models/post_processors/post_processors.py", line 129, in pp_od_yolo_ultralytics
    n_detections = int(output_tensors[3])
                   ^^^^^^^^^^^^^^^^^^^^^^
TypeError: only length-1 arrays can be converted to Python scalars
I'm running Python 3.11.9 and installed all the dependencies following the guide. My Raspberry PI is a 3B+ model with Bookworm 64 bits and is up to date.
aytacsekmen
In the official IMX500 documentation provided by Sony (https://developer.sony.com/tinyml-23/developer-tools/documentation/imx500-evaluation-kit-user-guide?version=2023-11-28&progLang=), they describe the process of generating the network.fpk and network_info.txt files that will be used to deploy the model to IMX500, using the Packager.sh script. However, when I attempt to apply the same procedure to the packerOut.zip file I created by following the tutorial on https://docs.ultralytics.com/integrations/sony-imx500, I am unable to run the model on the IMX500. Also I couldn't run your implementation because it says that some packages are not found which I believe is related to the version of the OS. Currently I use the Pi OS that is provided by SONY for compatibility issues. I could run some other deep learning models following the steps in the (https://developer.sony.com/tinyml-23/developer-tools/documentation/imx500-evaluation-kit-user-guide?version=2023-11-28&progLang=), but I believe, there must be something different related to the creation of packerOut.zip file.
Could you assist in resolving this issue with the conversion process? @glenn-jocher
HelloCigar
Hello, per picamera2 docs, creating apps with "a camera window embedded into the GUI is through Qt", is there no other way to embed the video feed in other GUI frameworks?
skim-sony
Hi, I followed the steps in this page to convert the yolov8n model with imx500 converter and tested it with raspberry ai camera. But I get 29.5 ms for the inference time with 640x640 input tensor size. So I wonder why my inference time is better than your result (58.82ms). Which version of imx500 converter did you use?
Also, how did you measure the inference time? Did you use imx500.get_kpi_info(metadata) or calculate the elapsed time of picam2.capture_metadata()?
- Glenn JocherUltralytics(已编辑)
@skim-sony congratulations on the faster result! Our documented figure (58.82 ms for YOLO11n, see the Benchmarks) was measured by the Ultralytics team on a Raspberry Pi AI Camera with the
imxformat. Differences can come from the converter version, firmware, hardware (Pi 5 vs Pi 4) or how the time is measured. Would you mind sharing which converter version and Raspberry Pi model you're using? This could help other community members. Hi, I have used Pi5 and tried both 3.14.3 and 3.16.1 for imx500-converter. And both produces 29.5ms for inference time. It seems like you also use Pi5, so I wonder why our results are different. I'd like to reproduce your results 58.82 ms to learn what improves the inference time. So it would be helpful if you could share some info how to sync with your environment. Thanks!
- Glenn JocherUltralytics(已编辑)
@skim-sony that's interesting you're seeing better performance! The discrepancy could be due to several factors:
- Measurement methodology: end-to-end time (pre/post-processing + inference) differs from model-only inference time
- Firmware and converter versions
- Image resolution and resizing
- Test conditions: background processes, temperature, and power settings
Our published numbers are in the Benchmarks. If you'd like to share more details about your implementation, the community would certainly benefit.
fracipriano
Hello, I'm trying to run the standard YOLOv8n model on a Raspberry Pi AI Camera. I followed the exemple in the documentation
from ultralytics import YOLO

# Load a YOLOv8n PyTorch model
model = YOLO("yolov8n.pt")

# Export the model
model.export(format="imx", data="coco8.yaml")  # exports with PTQ quantization by default

# Load the exported model
imx_model = YOLO("yolov8n_imx_model")

# Run inference
results = imx_model("https://ultralytics.com/images/bus.jpg")
I got a bunch of warnings during the execution (export_log.txt), but the imx_model seemed to work properly in the end.
I then packaged it via IMX500 Packager and test it using the imx500_object_detection_demo.py. The Network Firmware gets uploaded, the application starts, but I get no detection. I tried to lower the detection threshold, but it didn't help. Any idea on what could be the problem? Any suggestion would be much appreciated.
- Glenn JocherUltralytics
Thank you for the detailed issue. Let's troubleshoot step by step. First, ensure your Raspberry Pi AI Camera is correctly connected and recognized by running
libcamera-helloin the terminal. If the camera works, verify that thelabels.txtpath in your demo command matches the exported file. You can also try inference on a static image first withimx_model.predict("test.jpg")to isolate live feed issues. For further assistance, please share the full export log and a screenshot of your camera output.For additional guidance, refer to the Sony IMX500 and AITRIOS integration blog post which demonstrates successful deployment steps.
Hello @glenn-jocher,
libcamera-hello works fine as does the imx500_object_detection_demo.py when using the default model ("/usr/share/imx500-models/imx500_network_ssd_mobilenetv2_fpnlite_320x320_pp.rpk").
There seems to be no problem with the labels.txt file as, if a run the imx500_object_detection_demo.py specifying the path to my label.txt, it works fine.
The imx_model also works fine before the packaging.
Here a screenshot of the camera output:
You can find the full export log file in my first post. Do you think any of the errors and/or warnings there could cause any problem with the packaging process via the IMX500-Packager?
- Glenn JocherUltralytics
Thank you for sharing these details. The warnings in your export log about "No BN layers to fold" and quantization parameters are normal during IMX conversion and shouldn't affect packaging. Since your camera feed works with the default model but not your custom export, please verify:
- Your
imx500-packagecommand uses the exactpackerOut.zipfromyolov8n_imx_model - The input tensor shape in your exported model matches IMX500 expectations (640x640 by default)
If issues persist, we recommend trying the IMX500 conversion process with our pretrained YOLOv8n model from https://github.com/ultralytics/assets/releases as a validation step.
- Your
Hello @glenn-jocher , thank you for your answer.
- Yes, I'm the one specifying the packerOut.zip path when running imx500-package
- I think so. Here is the content of the dnnParams.xml file generated by the export function
<?xml version="1.0" encoding="UTF-8" standalone="yes"?>
<dnnParams>
    <networks>
        <network name="yolov8n_new_imx" ordinal="0" type="">
            <inputTensors>
                <inputTensor persistency="0" ordinal="0" name="Placeholder.input.uid1:0" l2Offset="260480" numOfDimensions="3" bitsPerElement="8" shift="0" scale="0.00390625" format="unsigned">
                    <dimensions>
                        <dimension size="3" serializationOrder="2" ordinal="0" padding="0"/>
                        <dimension size="640" serializationOrder="1" ordinal="1" padding="0"/>
                        <dimension size="640" serializationOrder="0" ordinal="2" padding="0"/>
                    </dimensions>
                </inputTensor>
            </inputTensors>
            <outputTensors>
                <outputTensor ordinal="1" name="transform-83-/MultiClassNMS:0" l2Offset="281984" numOfDimensions="1" bitsPerElement="8" shift="0" scale="0.00390625" format="unsigned">
                    <dimensions>
                        <dimension size="300" serializationOrder="0" ordinal="0" padding="0"/>
                    </dimensions>
                </outputTensor>
                <outputTensor ordinal="2" name="transform-84-/MultiClassNMS:0" l2Offset="280960" numOfDimensions="1" bitsPerElement="16" shift="0" scale="1.0" format="signed">
                    <dimensions>
                        <dimension size="300" serializationOrder="0" ordinal="0" padding="0"/>
                    </dimensions>
                </outputTensor>
                <outputTensor ordinal="3" name="transform-85-/MultiClassNMS:0" l2Offset="279936" numOfDimensions="1" bitsPerElement="16" shift="0" scale="1.0" format="signed">
                    <dimensions>
                        <dimension size="1" serializationOrder="0" ordinal="0" padding="0"/>
                    </dimensions>
                </outputTensor>
                <outputTensor ordinal="0" name="transform-86-/MultiClassNMS:0" l2Offset="260480" numOfDimensions="2" bitsPerElement="16" shift="0" scale="0.03125" format="signed">
                    <dimensions>
                        <dimension size="300" serializationOrder="0" ordinal="0" padding="0"/>
                        <dimension size="4" serializationOrder="1" ordinal="1" padding="0"/>
                    </dimensions>
                </outputTensor>
            </outputTensors>
        </network>
    </networks>
    <l2memory totalSize="8388480" coefficientsSize="2604544" reservedMemorySize="1024" networksRuntimeSize="5523456"/>
</dnnParams>
I downloaded the yolov8n.pt file from the Sep 29, 2024 Release and repeated the process from the beginning. Same result.
I'm adding here the terminal outputs I get when running the imx500-package: imx500-package_log.txt
- Glenn JocherUltralytics(已编辑)
Thanks for sharing the details. The
dnnParams.xmlshows correct 640x640 input dimensions. Since the default Mobilenet model works but your YOLOv8 export doesn't, please verify that your output tensor dimensions and ordering match the demo's expectations. YOLO IMX exports have a different output layout from Mobilenet, so the demo's post-processing must match. The deployment section of the IMX500 guide uses thepp_od_yolo_ultralyticspost-processor from the AITRIOS module library for Ultralytics YOLO IMX exports. Okay. So the problem was actually related to the output. The ordering is fine, as the scores and the classes. The problem are the bboxes. The values that I obtain are completely out of scale.
Example:
detection label: cup (0.56)
detection box: (396100, 107520, 0, 0)
whereas I would expect something like this:
detection label: cup (0.56)
detection box: (39, 459, 440, 177)
I'm not sure how to interpret this results. Is (396100, 107520, 0, 0) supposed to be the raw output of YOLOv8n? Also, in the dnnParams.xml posted above, I see that there is a scale="0.00390625" associated with the component of the output tensor relative to the bboxes. Should I renormalize my output using this factor?
Thank you for any insight you can provide.
- Glenn JocherUltralytics(已编辑)
The raw IMX500 outputs are quantized and need post-processing. Rather than decoding them by hand, use the
pp_od_yolo_ultralyticspost-processor shown in the deployment section of the IMX500 guide. Hello @glenn-jocher, a code snippet would be much appreciated for double-checking. Also, I can't find the documentation you mentioned—could you link it to me, please?
- Glenn JocherUltralytics(已编辑)
The IMX500 outputs are decoded for you by the AITRIOS module library, as shown in the deployment section of the IMX500 guide:
from modlib.models.post_processors import pp_od_yolo_ultralytics


def post_process(self, output_tensors):
    return pp_od_yolo_ultralytics(output_tensors)
Let us know if this resolves the coordinate scaling issue!
I think there’s been a misunderstanding. I thought there were other changes to be made besides rescaling. Scaling alone cannot be the solution since (396100, 107520, 0, 0) cannot become (39, 459, 440, 177) just by a scalar multiplication.
Also, I cannot find the "What's Under the Hood?" section anywhere here https://developer.sony.com/imx500. Could you be more precise about where I should look?
- Glenn JocherUltralytics(已编辑)
The "What's Under the Hood?" section refers to our Ultralytics IMX500 documentation, not Sony's site, but it describes the quantization and conversion toolchain, not output decoding. For box decoding use the post-processor from the deployment section:
from modlib.models.post_processors import pp_od_yolo_ultralytics def post_process(self, output_tensors): return pp_od_yolo_ultralytics(output_tensors) Hi @glenn-jocher , thank you very much for all the support. It finally works! There was no need to rescale the boxes by 0.03125. I was missing the --bbox-normalization flag when launching the script.
Once I added the flag, everything worked fine.
- Glenn JocherUltralytics(已编辑)
Great to hear you resolved it! For the current deployment workflow, including post-processing of the model outputs, see the IMX500 deployment guide. Happy detecting with your Raspberry Pi setup! 🚀