YOLO12:以注意力机制为核心的目标检测#
概述#
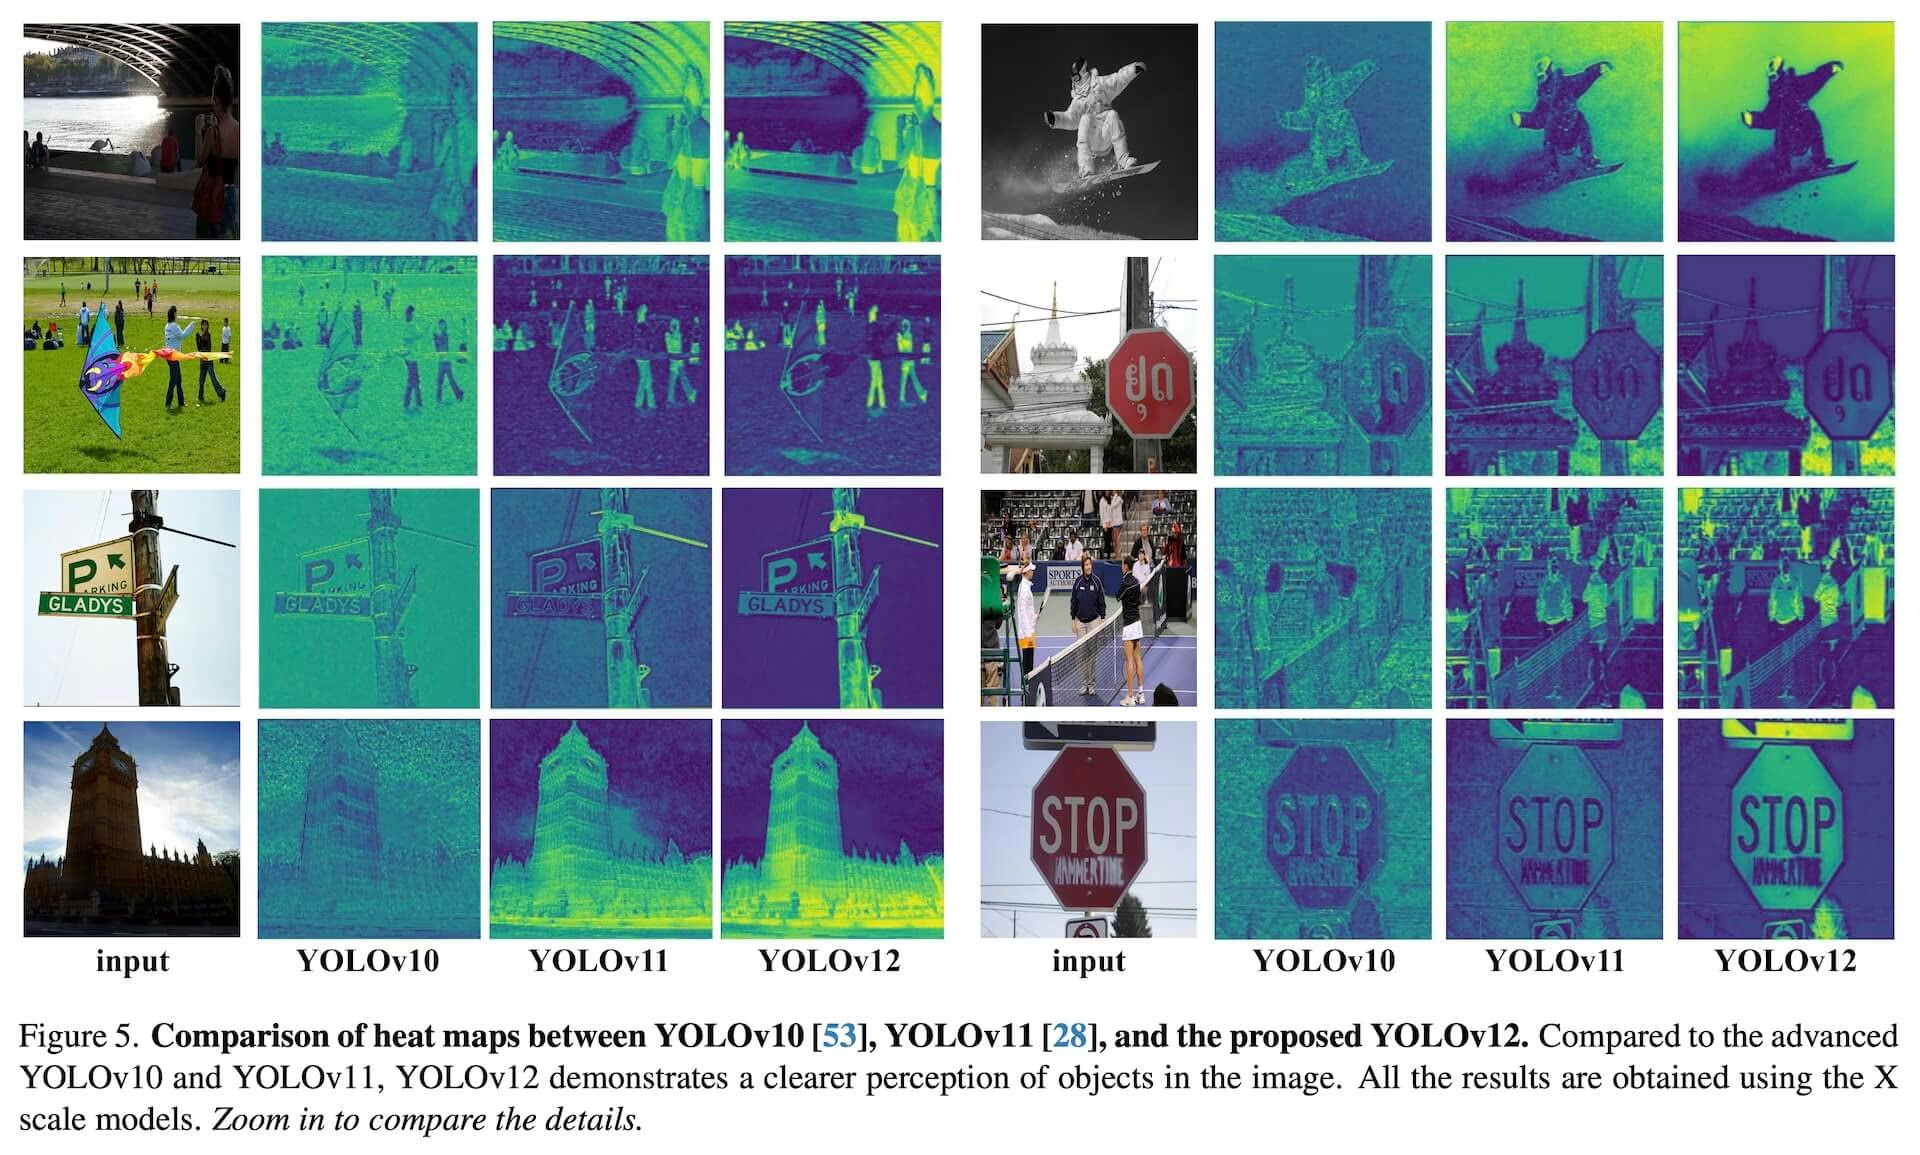
YOLO12 于 2025 年初发布,采用以注意力为中心的架构,不同于先前 YOLO 模型采用的传统 CNN架构,同时保留了许多应用所必需的实时推理速度。它通过改进注意力机制和整体网络架构,实现了较高的目标检测精度。尽管有这些优势,YOLO12 仍是一个由社区驱动发布的模型,可能会出现训练不稳定、内存占用较高以及 CPU 吞吐量较慢等问题,这些问题源于其计算量较大的注意力模块,因此 Ultralytics 建议大多数生产工作负载使用 YOLO11 或 YOLO26。
YOLO12 主要用于基准测试和研究。如果你需要稳定的训练、可预测的内存用量和经过优化的 CPU 推理,请选择 YOLO11 或 YOLO26 进行部署。
观看: 如何使用 Ultralytics Package 通过 YOLO12 进行目标检测 | YOLO12 的速度是快还是慢?
主要功能#
- 区域注意力机制:一种新的自注意力方法,可高效处理较大的感受野。它将特征图划分为 l 个大小相等的区域(默认为 4 个),方向为水平或垂直,从而避免复杂运算并保持较大的有效感受野。与标准自注意力相比,这显著降低了计算成本。
- 残差高效层聚合网络(R-ELAN):一种基于 ELAN 改进的特征聚合模块,旨在解决优化难题,尤其适用于更大规模、以注意力机制为核心的模型。R-ELAN 引入了:
- 带缩放的块级残差连接(类似于层缩放)。
- 重新设计的特征聚合方法,形成类似瓶颈的结构。
- 优化的注意力架构:YOLO12 精简了标准注意力机制,使其效率更高,并能更好地兼容 YOLO 框架。具体包括:
- 使用 FlashAttention 将内存访问开销降至最低。
- 移除位置编码,让模型更简洁、速度更快。
- 调整 MLP 比例(从通常的 4 调整为 1.2 或 2),更好地平衡注意力层和前馈层之间的计算量。
- 减少堆叠块的深度,以改善优化效果。
- 在适当情况下使用卷积运算,以提高计算效率。
- 在注意力机制中加入 7x7 可分离卷积(“位置感知器”),以隐式编码位置信息。
- 全面支持各类任务:YOLO12 支持多种计算机视觉核心任务:目标检测、实例分割、图像分类、姿态估计和有向目标检测(OBB)。
- 效率提升:与许多此前的模型相比,该模型以更少的参数实现了更高的精度,体现出速度和精度之间更出色的平衡。
- 灵活部署:专为在各种平台上部署而设计,涵盖边缘设备到云基础设施。
支持的任务和模式#
YOLO12 支持多种计算机视觉任务。下表展示了各项任务的支持情况,以及对应的操作模式(训练、验证、推理和导出):
ultralytics/assets 仅发布了检测权重(yolo12n.pt、yolo12s.pt、yolo12m.pt、yolo12l.pt、yolo12x.pt)。分割、分类、姿态和 OBB 架构定义在 ultralytics/cfg/models/12/ 中,因此这些变体支持使用 .yaml 配置从头开始训练,但目前没有可用的预训练 .pt 文件。对于预训练分割、姿态、分类或 OBB 检查点,Ultralytics 建议使用 YOLO11 或 YOLO26。
| 模型类型 | 任务 | 预训练权重 | 训练 | 验证 | 推理 | 导出 |
|---|---|---|---|---|---|---|
| YOLO12 | 检测 | ✅ | ✅ | ✅ | ✅ | ✅ |
| YOLO12-seg | 分割 | ❌ | ✅ | ✅ | ✅ | ✅ |
| YOLO12-cls | 分类 | ❌ | ✅ | ✅ | ✅ | ✅ |
| YOLO12-pose | 姿态 | ❌ | ✅ | ✅ | ✅ | ✅ |
| YOLO12-obb | OBB | ❌ | ✅ | ✅ | ✅ | ✅ |
所有 YOLO12 架构在有可用的训练后检查点时均支持所有模式。Pretrained Weights 列仅表示 Ultralytics 是否在 ultralytics/assets 发布了官方预训练 .pt:对于分割、姿态、分类和 OBB,你必须先根据相应的 .yaml 训练自己的检查点,然后才能运行推理、验证或导出。
性能指标#
YOLO12 在所有模型规模上都提升了精度,但与以往速度最快的 YOLO 模型相比,速度有所取舍。以下是基于 COCO 验证数据集的目标检测量化结果:
检测性能(COCO val2017)#
| 模型 | 尺寸 (像素) | mAPval50-95 | 速度 CPU ONNX (毫秒) | 速度 T4 TensorRT (毫秒) | 参数 (M) | FLOPs (B) | 对比 (mAP/速度) |
|---|---|---|---|---|---|---|---|
| YOLO12n | 640 | 40.6 | - | 1.64 | 2.6 | 7.5 | +2.1%/-9%(相较 YOLOv10n) |
| YOLO12s | 640 | 48.0 | - | 2.61 | 9.3 | 23.3 | +0.1%/+42%(相较 RT-DETRv2) |
| YOLO12m | 640 | 52.5 | - | 4.86 | 20.2 | 70.7 | +1.0%/-3%(相较 YOLO11m) |
| YOLO12l | 640 | 53.7 | - | 6.77 | 26.4 | 95.4 | +0.4%/-8%(相较 YOLO11l) |
| YOLO12x | 640 | 55.2 | - | 11.79 | 59.1 | 208.9 | +0.6%/-4%(相较 YOLO11x) |
- 推理速度是在配备 TensorRT 的 NVIDIA T4 GPU 上以 FP16 精度测得。
- 对比结果显示了 mAP 的相对提升以及速度的变化百分比(正值表示更快,负值表示更慢)。在有可用数据的情况下,对比采用 YOLOv10、YOLO11 和 RT-DETR 已发布的结果。
使用示例#
以下示例侧重于 YOLO12 Detect 模型(用于目标检测)。有关其他支持的任务(分割、分类、姿态估计和有向目标检测),请参阅相应的任务专属文档:Segment、Classify、Pose 和 OBB。
可以将预训练的 *.pt 模型(使用 PyTorch)和配置 *.yaml 文件传递给 YOLO() 类,以在 Python 中创建模型实例:
from ultralytics import YOLO

# 加载 COCO 预训练的 YOLO12n 模型
model = YOLO("yolo12n.pt")

# 使用 COCO8 示例数据集训练模型 100 个 epoch
results = model.train(data="coco8.yaml", epochs=100, imgsz=640)

# 使用 YOLO12n 模型对 'bus.jpg' 图像运行推理
results = model("path/to/bus.jpg")主要改进#
-
增强的特征提取:
- 区域注意力:高效处理较大的感受野,从而降低计算成本。
- 平衡优化:改善注意力计算与前馈网络计算之间的平衡。
- R-ELAN:通过 R-ELAN 架构增强特征聚合。
-
优化创新:
- 残差连接:引入带缩放的残差连接来稳定训练,尤其适用于较大的模型。
- 改进的特征融合:在 R-ELAN 中实现了改进的特征融合方法。
- FlashAttention:集成 FlashAttention,以减少内存访问开销。
-
架构效率:
- 减少参数:与许多此前的模型相比,在保持或提升精度的同时实现了更少的参数。
- 精简注意力机制:采用简化的注意力实现,避免使用位置编码。
- 优化 MLP 比例:调整 MLP 比例,以更有效地分配计算资源。
要求#
默认情况下,Ultralytics YOLO12 实现不需要 FlashAttention。不过,你可以选择编译 FlashAttention 并将其用于 YOLO12。要编译 FlashAttention,需要具备以下 NVIDIA GPU 之一:
- Turing GPU(例如 T4、Quadro RTX 系列)
- Ampere GPU(例如 RTX30 系列、A30/40/100)
- Ada Lovelace GPU(例如 RTX40 系列)
- Hopper GPU(例如 H100/H200)
引用与致谢#
如果你在研究中使用 YOLO12,请引用 布法罗大学和中国科学院大学的原始研究:
@inproceedings{tian2025yolov12,
  title={YOLOv12: Attention-Centric Real-Time Object Detectors},
  author={Tian, Yunjie and Ye, Qixiang and Doermann, David},
  booktitle={Advances in Neural Information Processing Systems},
  volume={38},
  pages={78433--78457},
  year={2025},
  url={https://proceedings.neurips.cc/paper_files/paper/2025/file/7103444259031cc58051f8c9a4868533-Paper-Conference.pdf}
}

@software{yolo12,
  author = {Tian, Yunjie and Ye, Qixiang and Doermann, David},
  title = {YOLO12: Attention-Centric Real-Time Object Detectors},
  year = {2025},
  url = {https://github.com/sunsmarterjie/yolov12},
  license = {AGPL-3.0}
}
YOLO12 论文已发表于 NeurIPS 2025 论文集,预印本可在 arXiv 查阅。
常见问题#
YOLO12 融入了多项关键创新,以平衡速度与精度。区域注意力机制可高效处理较大的感受野,与标准自注意力相比降低了计算成本。残差高效层聚合网络(R-ELAN)改进了特征聚合,解决了较大型注意力中心模型的优化难题。优化后的注意力架构(包括使用 FlashAttention 和移除位置编码)进一步提升了效率。这些特性让 YOLO12 在实现较高精度的同时,保持了许多应用所需的实时推理速度。
默认情况下,Ultralytics YOLO12 实现不需要 FlashAttention。不过,可以选择编译 FlashAttention 并将其用于 YOLO12,以最大限度地减少内存访问开销。要编译 FlashAttention,需要使用以下 NVIDIA GPU 之一:Turing GPU(例如 T4、Quadro RTX 系列)、Ampere GPU(例如 RTX30 系列、A30/40/100)、Ada Lovelace GPU(例如 RTX40 系列)或 Hopper GPU(例如 H100/H200)。这样一来,用户的硬件支持 FlashAttention 时,就能从中受益。
评论69
Zixuan-He I try use the YOLO12-seg, but with update to lastest version (> pip install -U ultralytics) it is still showing (No such file or directory: 'YOLO12n-seg.pt) with code (yolo segment train data=data.yaml model=YOLO12n-seg.pt epochs=200 batch=16 imgsz=640 patience=25 ). theYOLO12n.pt for obj is good. Is the code changed or need other input?
1Glenn JocherUltralytics @Zixuan-He Answer:
The YOLO12-seg model requires using its specific configuration file. Trymodel=yolo12-seg.yamlinstead of the.ptfile to initialize training. The segmentation weights are not yet released as pretrained.ptfiles, but you can train from scratch using the YAML configuration. For details, see the YOLO12-seg documentation.2LucasGenoud Hello, thank you for your answer ! Do you have any date estimation of when the pretrained segmentation models for YOLO12 will be available ? Thanks
Glenn JocherUltralytics We don't have an official release date for YOLO12-seg pretrained weights yet, but you can train segmentation models from scratch using the YOLO12-seg.yaml configuration. For updates, please monitor the YOLO12 documentation.
LucasGenoud Thank you for your response. Great work :)
Glenn JocherUltralytics Thank you for your kind words! We don't have a specific release date for YOLO12-seg pretrained weights yet, but you can monitor the YOLO12 documentation for updates. The team typically announces new model releases there first. For now, training from scratch using the YOLO12-seg.yaml configuration remains the recommended approach.
dolokbutarbutar24 Here are some sample images for the healthy class. I also attached some "results" images, hopefully can give more information so you guys can help me with the project.
Pada Sen, 30 Mar 2026 pukul 15.58 Glenn Jocher @.***> menulis:
Thanks for dropping this question here so the Ultralytics team can see it; for leaf-disease datasets, mAP50-95 usually improves more from cleaner labels, balanced class counts, harder negative samples, and reviewing per-class PR/confusion outputs than from pushing loss weights alone, so I’d next tune weight_decay, momentum, warmup_epochs, lrf, translate, shear, perspective, fliplr, and close_mosaic using the hyperparameter tuning guide https://docs.ultralytics.com/guides/hyperparameter-tuning/ and performance metrics guide https://docs.ultralytics.com/guides/yolo-performance-metrics/. If you can share a few sample images, labels, and training curves here, we can suggest a tighter search space, and it’s also worth benchmarking the same split with YOLO26 https://docs.ultralytics.com/models/yolo26/ since YOLO12 is mainly maintained as a community research model.
— Reply to this email directly, view it on GitHub https://github.com/orgs/ultralytics/discussions/19360?email_source=notifications&email_token=A23CVICPPIXOD6F3LMBB52T4TIZKDA5CNFSNUABIM5UWIORPF5TWS5BNNB2WEL2ENFZWG5LTONUW63SDN5WW2ZLOOQXTCNRTG44DGNRZUZZGKYLTN5XKOY3PNVWWK3TUUVSXMZLOOSWGM33PORSXEX3DNRUWG2Y#discussioncomment-16378369, or unsubscribe https://github.com/notifications/unsubscribe-auth/A23CVIG2PM2BD5335IFZQXT4TIZKDAVCNFSM6AAAAABXS26SR6VHI2DSMVQWIX3LMV43URDJONRXK43TNFXW4Q3PNVWWK3TUHMYTMMZXHAZTMOI . You are receiving this because you commented.Message ID: @.*** com>
Glenn JocherUltralytics Thanks, that helps; from those samples I’d next verify that the
healthylabels are fully consistent and that the class counts are not skewed, then please attach a few matching image/label.txtpairs plusresults.csvandconfusion_matrix_normalized.pngso we can check whether this is a data issue rather than a YOLO12 training issue, and if you recently fixed labels please delete anylabels/*.cachefiles before retraining.
dolokbutarbutar24 I am currently working on a project to detect cassava leaf diseases using YOLOv12. The focus of this research is to perform hyperparameter tuning and also determine the most suitable augmentation configuration to improve model performance. So far, the trained model is still hovering around the 0.5 range for the mAP@50-95 evaluation metric. Here are the hyperparameters I have used for tuning so far: epochs=100, patience=20, imgsz=1024, batch=8, optimizer='auto', lr0=0.00511, box=6.32971, cls=2.87957, dfl=2.12658, mosaic=0.25, scale=0.15, mixup=0.0, copy_paste=0.0, degrees=10.0, hsv_h=0.015, hsv_s=0.7, hsv_v=0.4.
What other strategies can I do to improve my model's performance, especially on the mAP@50-95 evaluation metric? Do you have any suggestions for other hyperparameters that need to be added to this project for tuning? I'm sure your experience and skills can answer that and help me hahaha.
Glenn JocherUltralytics Thanks for dropping this question here so the Ultralytics team can see it; for leaf-disease datasets, mAP50-95 usually improves more from cleaner labels, balanced class counts, harder negative samples, and reviewing per-class PR/confusion outputs than from pushing loss weights alone, so I’d next tune
weight_decay,momentum,warmup_epochs,lrf,translate,shear,perspective,fliplr, andclose_mosaicusing the hyperparameter tuning guide and performance metrics guide. If you can share a few sample images, labels, and training curves here, we can suggest a tighter search space, and it’s also worth benchmarking the same split with YOLO26 since YOLO12 is mainly maintained as a community research model.
Clousy 在5090 32G上使用yolo12l训练模型的时候,数据量大概7万左右,batch_size=24 内存占用在24G左右,为啥速度只有2-3it/s 是哪里设置有问题?下面是训练参数: rain_args = dict( data="data.yaml", epochs=500, imgsz=640, batch=24, device=device, workers=16,
    cache=False,
    amp=True,

    # --- 减少 CPU 负担 ---
    mosaic=0.0,        # 暂时关掉 Mosaic 看看速度是否飙升
    mixup=0.0,         # 同上
)
Glenn JocherUltralytics yolo12l本身是重注意力结构,吞吐会比同尺度的 CNN 系列低不少,所以你看到的2–3 it/s在batch=24下未必异常(折算大约是48–72 img/s);如果你目标是更高训练/CPU 端速度,建议直接换到更稳更快的 Ultralytics YOLO26(YOLO12 更偏研究/基准用途,见 YOLO12 文档)。想确认是不是环境/数据读取瓶颈的话,请把yolo checks输出和完整文本训练日志(含第一轮的进度条行、CUDA:/显卡名、DataLoader相关信息)贴在这里;另外你现在cache=False可能会被磁盘 IO 卡住、workers=16在部分系统上也会造成额外调度开销,建议先用下面这组参数做一次对照测试(同一数据/同一imgsz),看it/s是否明显变化:yolo checks yolo train model=yolo12l.pt data=data.yaml epochs=2 imgsz=640 batch=24 device=0 workers=8 cache=True mosaic=0.0 mixup=0.0
dolokbutarbutar24 is there any video (tutorial) about how to classify plant disease? i'm confused about how to do it because i need guidance to do classify task
Glenn JocherUltralytics(已编辑) Yes—plant disease is just a standard image classification workflow; please follow the Ultralytics YOLO classification guide (and drop any follow-up questions here in this discussion so the Ultralytics team can see them), then try:
from ultralytics import YOLO

# ImageNet-pretrained classifier backbone (recommended starting point)
model = YOLO("yolo26n-cls.pt")

# Your dataset folder should contain train/ and val/ with one subfolder per class
model.train(data="path/to/plant_disease_dataset", epochs=50, imgsz=224)
If you share your dataset folder layout (just the directory tree) and what’s confusing you, I can point you to the exact next step.
asad121101 Hello , this new yolo12 is using what architecture in neck ? pan or fpn ? or some thing else ?
Sourabh0052 while working on classification model using YOLO12-cls and i do not make any .yaml file, just simply provide the data source path then will it work same or not
radadiavasu I faced a problem that recently I put my model on training with yolo12x but at 98/100 epoch it stopped due to units are over on colab pro but when I start again and expect to start from 98 but it start from 1/100 instead of 98 even in results.csv I couldn't get anything. Why this problem occurs?
deldanr When resuming a training session started with Yolov12, after the AMP check, the training session downloads a Yolov11 model to continue, which I assume is an error.
Attached is part of the log: YOLOv12l summary: 488 layers, 26,389,875 parameters, 26,389,859 gradients, 89.4 GFLOPs
Transferred 1245/1245 items from pretrained weights Freezing layer 'model.21.dfl.conv.weight' AMP: Running Automatic Mixed Precision (AMP) checks... Downloading https://github.com/ultralytics/assets/releases/download/v8.3.0/yolo11n.pt to 'yolo11n.pt'... <-- Here's the error
pvurda Has anyone found a low-cost, low-latency way to generate a short semantic scene caption (e.g., “two people loading a van”) on top of YOLO12 detections in real time?