Scopri Ultralytics YOLOv8
Panoramica#
YOLOv8 è stato rilasciato da Ultralytics il 10 gennaio 2023 e offre maggiore precisione e velocità rispetto alle versioni YOLO precedenti. Basandosi su queste versioni, YOLOv8 ha introdotto nuove funzionalità e ottimizzazioni che lo rendono un’ottima scelta per il rilevamento di oggetti e altre attività di visione in un’ampia gamma di applicazioni. Per i nuovi progetti, Ultralytics consiglia YOLO26.
Guarda: Panoramica del modello Ultralytics YOLOv8
Esplora ed esegui i modelli YOLOv8 direttamente sulla piattaforma Ultralytics.
Caratteristiche principali di YOLOv8#
- Architetture backbone e neck avanzate: YOLOv8 utilizza architetture backbone e neck all’avanguardia, migliorando l’estrazione delle caratteristiche e le prestazioni di rilevamento degli oggetti.
- Testa Ultralytics suddivisa senza anchor: YOLOv8 adotta una testa Ultralytics suddivisa senza anchor, che contribuisce a una maggiore precisione e a un processo di rilevamento più efficiente rispetto agli approcci basati su anchor.
- Compromesso ottimizzato tra precisione e velocità: Puntando a mantenere un equilibrio ottimale tra precisione e velocità, YOLOv8 è adatto alle attività di rilevamento degli oggetti in tempo reale in diversi ambiti applicativi.
- Varietà di modelli pretrained: YOLOv8 offre una gamma di modelli pretrained per soddisfare diverse attività e requisiti prestazionali, semplificando la scelta del modello più adatto al tuo caso d'uso specifico.
Attività e modalità supportate#
La serie YOLOv8 offre un’ampia gamma di modelli, ciascuno specializzato per attività specifiche di visione artificiale. I modelli sono progettati per soddisfare esigenze diverse, dal rilevamento di oggetti ad attività più complesse come la segmentazione di istanze, la classificazione, il rilevamento della posa e dei punti chiave e il rilevamento di oggetti orientati.
Ogni variante della serie YOLOv8 è ottimizzata per la relativa attività. Tutte le varianti supportano le modalità di Addestramento, Convalida, Inferenza ed Esportazione, coprendo ogni fase, dallo sviluppo alla distribuzione.
| Modello | Nomi dei file | Attività | Addestramento | Validazione | Inferenza | Esporta |
|---|---|---|---|---|---|---|
| YOLOv8 | yolov8n.pt yolov8s.pt yolov8m.pt yolov8l.pt yolov8x.pt | Rilevamento | ✅ | ✅ | ✅ | ✅ |
| YOLOv8-seg | yolov8n-seg.pt yolov8s-seg.pt yolov8m-seg.pt yolov8l-seg.pt yolov8x-seg.pt | Segmentazione di istanze | ✅ | ✅ | ✅ | ✅ |
| YOLOv8-cls | yolov8n-cls.pt yolov8s-cls.pt yolov8m-cls.pt yolov8l-cls.pt yolov8x-cls.pt | Classificazione | ✅ | ✅ | ✅ | ✅ |
| YOLOv8-pose | yolov8n-pose.pt yolov8s-pose.pt yolov8m-pose.pt yolov8l-pose.pt yolov8x-pose.pt yolov8x-pose-p6.pt | Pose/Keypoint | ✅ | ✅ | ✅ | ✅ |
| YOLOv8-obb | yolov8n-obb.pt yolov8s-obb.pt yolov8m-obb.pt yolov8l-obb.pt yolov8x-obb.pt | Rilevamento orientato | ✅ | ✅ | ✅ | ✅ |
Questa tabella riepiloga le varianti del modello YOLOv8, le attività che svolgono e il supporto per le modalità di Addestramento, Convalida, Inferenza ed Esportazione.
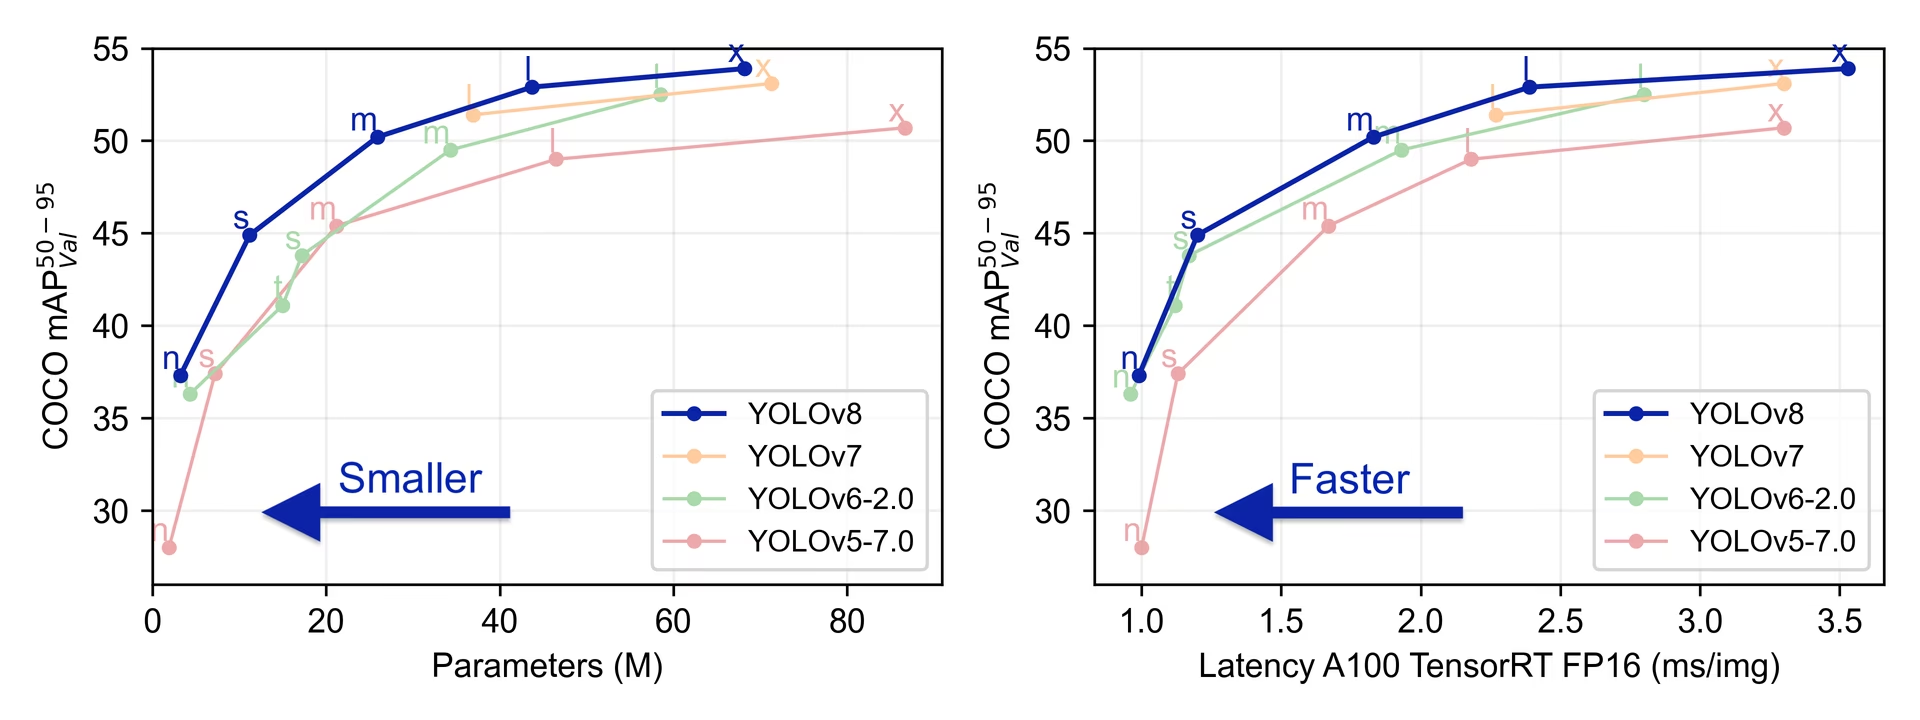
Metriche di prestazione#
Consulta la documentazione sul rilevamento per esempi d'uso di questi modelli addestrati su COCO, che includono 80 classi preaddestrate.
Esempi di utilizzo di YOLOv8#
Questo esempio fornisce semplici esempi di addestramento e inferenza con YOLOv8.
Nota: l'esempio seguente riguarda i modelli YOLOv8 Detect per il rilevamento degli oggetti. Per le altre attività supportate, consulta la documentazione Segment, Classify, Pose e OBB.
I modelli *.pt preaddestrati con PyTorch e i file di configurazione *.yaml possono essere passati alla classe YOLO() per creare un'istanza del modello in Python:
from ultralytics import YOLO

# Carica un modello YOLOv8n pretrained su COCO
model = YOLO("yolov8n.pt")

# Visualizza le informazioni sul modello (facoltativo)
model.info()

# Addestra il modello sul dataset di esempio COCO8 per 100 epoche
results = model.train(data="coco8.yaml", epochs=100, imgsz=640)

# Esegui l'inferenza con il modello YOLOv8n sull'immagine 'bus.jpg'
results = model("path/to/bus.jpg")
Citazioni e ringraziamenti#
Ultralytics non ha pubblicato un articolo di ricerca formale su YOLOv8, data la rapida evoluzione dei modelli. Ci concentriamo sul progresso della tecnologia e sulla facilità d'uso, anziché produrre documentazione statica. Per informazioni aggiornate sull'architettura, le funzionalità e l'utilizzo di YOLO, consulta il nostro repository GitHub e la documentazione.
Se utilizzi il modello YOLOv8 o qualsiasi altro software di questo repository nel tuo lavoro, citalo usando il seguente formato:
@software{yolov8_ultralytics,
  author = {Glenn Jocher and Ayush Chaurasia and Jing Qiu},
  title = {Ultralytics YOLOv8},
  version = {8.0.0},
  year = {2023},
  url = {https://github.com/ultralytics/ultralytics},
  orcid = {0000-0001-5950-6979, 0000-0002-7603-6750, 0000-0003-3783-7069},
  license = {AGPL-3.0}
}
I modelli YOLOv8 sono distribuiti con licenze AGPL-3.0 ed Enterprise.
Domande frequenti#
YOLOv8 è progettato per migliorare le prestazioni del rilevamento degli oggetti in tempo reale. A differenza delle versioni precedenti, YOLOv8 integra una testa Ultralytics suddivisa e senza anchor e architetture all'avanguardia per backbone e neck, e offre un compromesso ottimizzato tra precisione e velocità per applicazioni diverse.
YOLOv8 supporta un'ampia gamma di attività di visione artificiale, tra cui rilevamento degli oggetti, segmentazione delle istanze, classificazione, rilevamento della posa/dei keypoint e rilevamento di oggetti orientati. Ogni variante del modello è ottimizzata per la propria attività specifica e supporta le modalità di addestramento, convalida, inferenza ed esportazione.
Al momento del rilascio, i modelli YOLOv8 hanno ottenuto prestazioni all’avanguardia su diversi dataset di benchmark. Per esempio, il modello YOLOv8n raggiunge una precisione media (mAP) di 37,3 sul dataset COCO e una velocità di 0,99 ms su A100 TensorRT. Nella sezione Metriche delle prestazioni trovi metriche dettagliate per ciascuna variante del modello, nelle diverse attività e sui vari dataset.
Puoi addestrare un modello YOLOv8 usando Python o la CLI. Di seguito trovi alcuni esempi per addestrare un modello YOLOv8n preaddestrato su COCO sul dataset COCO8 per 100 epoche:
Esempiofrom ultralytics import YOLO # Carica un modello YOLOv8n pretrained su COCO model = YOLO("yolov8n.pt") # Addestra il modello sul dataset di esempio COCO8 per 100 epoche results = model.train(data="coco8.yaml", epochs=100, imgsz=640)Per maggiori dettagli, consulta la documentazione sull'addestramento.
Sì, è possibile eseguire il benchmark dei modelli YOLOv8 per misurarne velocità e precisione con diversi formati di esportazione, come PyTorch, ONNX e TensorRT. Di seguito trovi alcuni comandi di esempio per eseguire il benchmarking con Python e CLI:
Esempiofrom ultralytics.utils.benchmarks import benchmark # Esegui il benchmark su GPU benchmark(model="yolov8n.pt", data="coco8.yaml", imgsz=640, device=0)Per ulteriori informazioni, consulta la sezione Metriche di prestazione.


Commenti356
Fai una domanda, condividi i tuoi risultati o aiuta qualcun altro.
Yscream(modificato)
hey there! can you help me to handle error which i get every time when run train increasing batch and imgsz options, please? first of all, i have a powerful enough computer. RTX 3090 24gb, Ryzen 9 7950X3D 16-Core, 128gb RAM if i run train with following options
results = model.train(data=f'{database_foldername}data.yaml', cfg=cfg_filename, epochs=epochs, imgsz=640, batch=8, device=0)it works quit good, and it uses about 3-4gb GPU_MEM, but i want to change imgsz to 1280 to increase accuracy of model and when i run train with this changed option i always got different errors, like:RuntimeError: cuDNN error: CUDNN_STATUS_EXECUTION_FAILEDRuntimeError: CUDA error: device-side assert triggered Compile withTORCH_USE_CUDA_DSAto enable device-side assertions.RuntimeError: CUDA error: an illegal memory access was encountered Compile withTORCH_USE_CUDA_DSAto enable device-side assertions.RuntimeError: Pin memory thread exited unexpectedly terminate called without an active exceptionand as i wrote earlier it throw different every time. i tride run with CUDA_LAUNCH_BLOCKING=1, but nothing changed
help!!! i want to use all the power of my graphics card
2Any solutions please thank you
 Paula DerrengerUltralytics
@Yscream it sounds like you're encountering memory-related issues when increasing the image size during training. Given your powerful hardware, this is likely due to the increased memory demands of larger images. Here are a few suggestions to help mitigate these errors:
-
Reduce Batch Size: Try lowering the batch size when increasing the image size. For example, if you're using
imgsz=1280, you might need to reduce the batch size to 2 or even 1 to fit within the GPU memory limits. -
Mixed Precision Training: Enable mixed precision training by setting
amp=Truein your training arguments. This can help reduce memory usage and potentially improve training speed. -
Check for Software Updates: Ensure you are using the latest versions of PyTorch, CUDA, and cuDNN. Sometimes, updating these can resolve compatibility and performance issues.
-
Debugging: Use
CUDA_LAUNCH_BLOCKING=1to get more detailed error messages, which can help pinpoint the exact cause of the issue.
If the problem persists, please try these steps and let us know if you encounter any specific errors. This will help us provide more targeted assistance.
-
rohith-aiunika
Hi YOLO Team, I have a v8 segmentation model, i need to convert my pt file to TFlite, is it possible?
1xuan2261
"# Improved YOLOv8 with BiFormer, Fusion Blocks, MS-Block, DConv, ECA, Ghost Module, and Focal Loss
Parameters
nc: 9 # number of classes scales:
[depth, width, max_channels]
n: [0.33, 0.25, 1024]
s: [0.33, 0.50, 1024]
m: [0.67, 0.75, 768]
l: [1.00, 1.00, 512]
x: [1.00, 1.25, 512]Backbone (ensure specific feature sizes: 160×160×128, 80×80×256, 40×40×512, 20×20×512)
backbone:
[from, repeats, module, args]
- [-1, 1, GhostModule, [64, 3, 2]] # 0-P1/2 -> output 320×320×64, using Ghost Module to reduce computation
- [-1, 1, Conv, [128, 3, 2, Mish]] # 1-P2/4 -> output 160×160×128, using Mish activation
- [-1, 3, C2f_DM, [128, True]] # output 160×160×128
- [-1, 1, MS-Block, [128, 3, [3, 5, 7], True]] # MS-Block with residual connections for multi-scale feature extraction
- [-1, 1, Conv, [256, 3, 2, Mish]] # 3-P3/8 -> output 80×80×256, using Mish activation
- [-1, 6, C2f_DM, [256, True]] # output 80×80×256
- [-1, 1, MS-Block, [256, 3, [3, 5, 7], True]] # MS-Block for P3/8 with residual connections
- [-1, 1, Conv, [512, 3, 2, Mish]] # 5-P4/16 -> output 40×40×512, using Mish activation
- [-1, 6, C2f_DM, [512, True]] # output 40×40×512
- [-1, 1, MS-Block, [512, 3, [3, 5, 7], True]] # MS-Block for P4/16 with residual connections
- [-1, 1, Conv, [1024, 3, 2, Mish]] # 7-P5/32 -> output 20×20×512, using Mish activation
- [-1, 3, C2f_DM, [1024, True]] # output 20×20×512
- [-1, 1, MS-Block, [1024, 3, [3, 5, 7], True]] # MS-Block for P5/32 with residual connections
- [-1, 1, SPPF, [1024, 5]] # Spatial Pyramid Pooling Fast -> output 20×20×512
Neck with Fusion Blocks, MS-Block, BiFormer, DConv, and ECA (replacing Concat)
neck:
[from, repeats, module, args]
-
[-1, 1, nn.Upsample, [None, 2, 'nearest']]
-
[[-1, 6], 1, Fusion_Block, [512]] # Fusion Block replacing Concat for backbone P4
-
[-1, 3, C2f_Att, [512]] # C2F-Att with Attention Mechanism
-
[-1, 1, BiFormer, [512]] # BiFormer added for enhanced spatial relationships
-
[-1, 1, DConv, [512, 3]] # Adding Dynamic Convolution
-
[-1, 1, ECA, [512]] # Adding Efficient Channel Attention
-
[-1, 1, MS-Block, [512, 3, [3, 5, 7], True]] # MS-Block for multi-scale feature extraction in Neck
-
[-1, 1, nn.Upsample, [None, 2, 'nearest']]
-
[[-1, 4], 1, Fusion_Block, [256]] # Fusion Block replacing Concat for backbone P3
-
[-1, 3, C2f_Att, [256]] # P3/8-small
-
[-1, 1, BiFormer, [256]] # BiFormer added for P3
-
[-1, 1, DConv, [256, 3]] # Adding Dynamic Convolution for P3
-
[-1, 1, ECA, [256]] # Adding Efficient Channel Attention for P3
-
[-1, 1, MS-Block, [256, 3, [3, 5, 7], True]] # MS-Block for P3 in Neck
-
[-1, 1, Conv, [256, 3, 2, Mish]]
-
[[-1, 12], 1, Fusion_Block, [512]] # Fusion Block replacing Concat for head P4
-
[-1, 3, C2f_Att, [512]] # P4/16-medium
-
[-1, 1, BiFormer, [512]] # BiFormer added for P4
-
[-1, 1, DConv, [512, 3]] # Adding Dynamic Convolution for P4
-
[-1, 1, ECA, [512]] # Adding Efficient Channel Attention for P4
-
[-1, 1, MS-Block, [512, 3, [3, 5, 7], True]] # MS-Block for P4 in Neck
-
[-1, 1, Conv, [512, 3, 2, Mish]]
-
[[-1, 9], 1, Fusion_Block, [1024]] # Fusion Block replacing Concat for head P5
-
[-1, 3, C2f_Att, [1024]] # P5/32-large
-
[-1, 1, BiFormer, [1024]] # BiFormer added for P5
-
[-1, 1, DConv, [1024, 3]] # Adding Dynamic Convolution for P5
-
[-1, 1, ECA, [1024]] # Adding Efficient Channel Attention for P5
-
[-1, 1, MS-Block, [1024, 3, [3, 5, 7], True]] # MS-Block for P5 in Neck
Adding a fourth detecting head for improved detection at different scales
- [-1, 1, Conv, [128, 3, 2, Mish]]
- [[-1, 3], 1, Fusion_Block, [128]] # new Fusion Block for smaller objects
- [-1, 3, C2f_Att, [128]] # P6/64-smaller objects
- [-1, 1, BiFormer, [128]] # BiFormer added for P6
- [-1, 1, DConv, [128, 3]] # Adding Dynamic Convolution for P6
- [-1, 1, ECA, [128]] # Adding Efficient Channel Attention for P6
- [-1, 1, MS-Block, [128, 3, [3, 5, 7], True]] # MS-Block for P6 in Neck
Head
head:
- [[17, 21, 25, 29], 1, Detect, [nc]] # Detect(P3, P4, P5, P6)
Loss Function
loss: name: FocalLoss # Using Focal Loss for better handling of small object detection" If I change the new structure like this, then I can add code for new modules, blocks: GhostModule, C2f_DM, MS-Block, BiFormer, .... to which files?
1 Glenn JocherUltralytics
@xuan2261 to integrate new modules like GhostModule and BiFormer, you'll need to modify the model architecture files in the Ultralytics repository. Specifically, look into the
modelsdirectory where the architecture is defined, and add your custom modules there. Ensure you also update any relevant configuration files to reflect these changes.
Wenlong914
有没有人能为我解答一下,训练数据集过程中的权重文件也能用吗?为什么训练过程中的权重文件比训练结束后的大?
1- Paula DerrengerUltralytics
您好!在训练过程中保存的权重文件通常会比训练完成后的权重文件大,这是因为它们可能包含额外的信息,比如优化器状态和用于继续训练的其他元数据。完成训练后,通常只会保存用于推断的模型参数,不包含训练期间需要的额外信息。
对于在训练过程中的权重文件,您完全可以使用它们来继续训练或进行预测,这在处理意外中断的训练时特别有用。如果您想验证模型的性能,或者希望进行一些测试,加载这些权重然后运行验证或推理是非常合适的。
希望这能帮助您!如果有更多问题,欢迎随时提问。🙂
1
haolele123
作者您好,我想训练yolov8m-p2的版本,我在想能否使用yolov8的模型权重作为预训练权重,且我发现似乎没有yolov8-p2的m的版本这个怎末决解呢
1- Paula DerrengerUltralytics(modificato)
您好!😊 感谢您对 YOLOv8 模型的兴趣!
yolov8m-p2没有单独的预训练权重,但可以直接使用 P2 配置文件训练:yolov8-p2.yaml支持n/s/m/l/x各个规模,指定yolov8m-p2.yaml即可构建 m 规模的 P2 模型。同时可以用yolov8m.pt作为预训练权重,形状匹配的层会被加载,P2 新增的层则随机初始化:yolo train model=yolov8m-p2.yaml pretrained=yolov8m.pt data=your_dataset.yaml epochs=100 imgsz=640如果直接使用
model=yolov8m.pt,训练的是标准 YOLOv8m,没有 P2 检测头。如需新的项目,也建议考虑 YOLO26。希望这有所帮助!如果还有其他问题,欢迎随时提问。祝您训练顺利!🚀
chaobao
作者你好,请问海滩或者足球场,怎么才能提高对人的识别率?
- Glenn JocherUltralytics
可以,提升这类场景下
person识别率最有效的方法通常是用海滩/球场相似数据做微调,增大imgsz(如960或1280)提升远处小目标召回,适当降低conf,并优先尝试更强的模型如 Ultralytics YOLO26;如果你愿意,也欢迎把几张样例图和当前训练配置发到 Ultralytics Discussions,这样团队更容易帮你定位具体瓶颈。
yaoyuan20000111-web
感谢yolov8让我可以研究生毕业
siddannamd
I came to know that YOLOv8 is capable of tracking objects. I am currently working on a robotics model that includes object detection and object tracking. Can YOLOv8 perform both detection and tracking simultaneously? Also, you didn’t mention the benchmark for object tracking compared to other models.
- Glenn JocherUltralytics
Yes—YOLOv8 can do detection and tracking in the same run via
trackmode (it detects each frame, then assigns persistent IDs with a tracker); see the Multi-Object Tracking (Track mode) docs (works with YOLOv8 Detect/Seg/Pose models listed on the YOLOv8 page).yolo track model=yolov8n.pt source=path/to/video.mp4 tracker="bytetrack.yaml"We don’t publish a single “tracking benchmark vs other models” on the YOLOv8 model page because results vary a lot with tracker choice (
botsort.yamlvsbytetrack.yaml), input FPS/resolution, and the evaluation set; if you share your target objects + a short sample video (or which MOT-style benchmark you’re using) here in the discussion, we can suggest a solid baseline config to compare fairly.
AniruddhaAi
I am trying to use yolov8m.pt's backbone for feature extractor. Why does it force download the coco dataset? Is there a way I could just load the weights rather downloading the data? I need to extract the features from custom dataset
- Glenn JocherUltralytics
Loading
yolov8m.ptshould only download the weights; the COCO download is triggered when you runtrain()/val()(or anything that uses a COCOdata=...YAML, including defaults). For feature extraction on your own images, use embeddings directly (no dataset download) viaModel.embed()on your custom image folder/file:from ultralytics import YOLO model = YOLO("yolov8m.pt") # weights only embeddings = model.embed(source="path/to/images") # your custom data
liuna471658955
Hi,dears, i'm new of YoLoV8, can you help see is there any thing can be improved of my below code?
from PIL import Image from ultralytics import YOLO import glob import os import numpy as np from tqdm import tqdm import torch from concurrent.futures import ThreadPoolExecutor
class Predict def init(self, batch_size=8, imgsz=640, conf_thres=0.25, iou_thres=0.45, half=True, device=cuda0)
    初始化优化后的推理类
    param batch_size 批量推理大小(根据GPU显存调整)
    param imgsz 推理图片尺寸(建议为32的倍数)
    param conf_thres 置信度阈值(过滤低置信度预测)
    param iou_thres NMS的IOU阈值(控制重复框)
    param half 是否使用半精度推理(FP16,提速且不损失精度)
    param device 推理设备(cudacpumps)

    self.model_path = homejovyanworkstudentmodelsyolo_train4weightsbest.pt
    self.device = torch.device(device if torch.cuda.is_available() else cpu)
    self.model = YOLO(self.model_path).to(self.device)

    # 核心推理参数
    self.batch_size = batch_size
    self.imgsz = imgsz
    self.conf_thres = conf_thres
    self.iou_thres = iou_thres
    self.half = half and torch.cuda.is_available()  # 仅GPU支持半精度

    # 预热模型(首次推理加速)
    self._warmup_model()

def _warmup_model(self)
    模型预热:首次推理避免初始化耗时
    dummy_img = torch.randn(1, 3, self.imgsz, self.imgsz).to(self.device)
    if self.half
        dummy_img = dummy_img.half()
    self.model.predict(dummy_img, verbose=False, conf=self.conf_thres, iou=self.iou_thres, half=self.half)

def _load_image(self, img_path)
    单张图片加载(封装为线程池调用)
    try
        with Image.open(img_path) as img
            img = img.convert(RGB)
            return img_path, img, None
    except Exception as e
        return img_path, None, str(e)

def _batch_load_images(self, image_paths)
    批量加载图片(多线程提速)
    images = []
    valid_paths = []
    error_logs = []

    # 多线程加载图片(CPU密集型任务提速)
    with ThreadPoolExecutor(max_workers=4) as executor
        results = list(tqdm(executor.map(self._load_image, image_paths), total=len(image_paths), desc=Loading images))

    for path, img, err in results
        if err
            error_logs.append(fSkipping {path} {err})
            continue
        valid_paths.append(path)
        images.append(img)

    # 打印加载错误
    if error_logs
        for err in error_logs[5]  # 只打印前5个错误
            print(err)
    return valid_paths, images

def detect(self, image_dir)

    优化后的推理主函数
    param image_dir 图片目录
    param use_tta 是否启用TTA(测试时增强,提升准确率,小幅增加耗时)
    return 推理结果列表

    # 1. 获取所有图片路径
    exts = [.jpg, .jpeg, .png, .JPG, .JPEG, .PNG]
    image_paths = []
    for ext in exts
        image_paths.extend(glob.glob(os.path.join(image_dir, ext)))
    if not image_paths
        print(No images found in directory!)
        return []

    # 2. 批量加载图片(多线程)
    valid_paths, images = self._batch_load_images(image_paths)
    if not valid_paths
        return []

    # 3. 分批次推理
    all_results = []
    num_batches = (len(valid_paths) + self.batch_size - 1)  self.batch_size

    for batch_idx in tqdm(range(num_batches), desc=Inferencing batches)
        # 切分批次
        start = batch_idx  self.batch_size
        end = min((batch_idx + 1)  self.batch_size, len(valid_paths))
        batch_paths = valid_paths[startend]
        batch_imgs = images[startend]

        # 4. 执行推理(核心优化)
        try
            results = self.model.predict(
                source=batch_imgs,
                imgsz=self.imgsz,          # 统一推理尺寸
                conf=self.conf_thres,      # 置信度过滤
                iou=self.iou_thres,        # NMS阈值
                half=self.half,            # 半精度推理
                device=self.device,        # 指定设备
                verbose=False,             # 关闭日志
                batch=self.batch_size,     # 批量大小
              #  tta=use_tta,               # 测试时增强(可选)
                max_det=100,               # 单图最大检测数
                vid_stride=1,              # 视频步长(图片无效)
                retina_masks=False         # 掩码细化(无掩码时关闭)
            )
        except Exception as e
            print(fBatch {batch_idx} inference failed {e})
            continue

        # 5. 解析结果(减少CPUGPU数据拷贝)
        for idx, result in enumerate(results)
            img_path = batch_paths[idx]
            image_name = os.path.basename(img_path)
            detections = []

            if result.boxes is not None and len(result.boxes)  0
                # 批量转换数据(避免逐框循环拷贝)
                cls = result.boxes.cls.cpu().numpy().astype(int).tolist()
                boxes = result.boxes.xyxy.cpu().numpy().tolist()
                scores = result.boxes.conf.cpu().numpy().astype(float).tolist()

                # 生成检测结果
                for c, b, s in zip(cls, boxes, scores)
                    detections.append({
                        cls int(c),
                        box [float(x) for x in b],
                     score round(float(s), 3)  # 保留3位小数,减少存储
                    })

            all_results.append({
                image_name image_name,
                detections detections,
                image_path img_path
            })

    return all_results
使用示例
if name == main # 初始化优化后的推理器(根据GPU显存调整参数) pre = Predict( batch_size=16, # 批量大小(1080Ti建议8-16,A100建议32-64) imgsz=640, # 推理尺寸(训练时用640则保持一致) conf_thres=0.3, # 提高置信度阈值,过滤假阳性 iou_thres=0.4, # 降低IOU阈值,减少重复框 half=True, # 启用半精度推理 device=cuda0 # 指定GPU )
# 执行推理(use_tta=True 提升准确率,耗时增加~30%) results = pre.detect(image_dir=homejovyanworkstudenttest) # 打印结果 for idx, result in enumerate(results[3]) # 只打印前3个 print(fImage {result['image_name']}) print(fDetections {len(result['detections'])} objects) for det in result[detections] print(f - Class {det['cls']}, Box {det['box']}, Score {det['score']}) print(- 50) print(fTotal processed images {len(results)})- Glenn JocherUltralytics
Nice work putting this together; you can simplify it a lot by letting YOLO handle most of what you’re doing manually.
A few concrete suggestions:
- Use the built‑in directory + batch inference instead of your own loader and batching. YOLO already scans a folder, loads images in parallel and batches them:
from ultralytics import YOLO

model = YOLO("best.pt")

results = model.predict(
    source="path/to/images_dir",  # folder with images
    imgsz=640,
    conf=0.3,
    iou=0.4,
    device="cuda:0",             # or "cpu"
    batch=16,                    # batched inference
    half=True,                   # FP16 on GPU
    verbose=False
)
This gives you essentially the same effect as your
Predict.detect()without the customThreadPoolExecutor, manual slicing, or warmup.-
Don’t call
.to(self.device)on theYOLOobject; instead, just passdevice="cuda:0"(or"cpu") topredict()as above. That’s the supported pattern in the Python API. -
If you want to keep a small wrapper class, keep it thin and delegate everything to
model.predict():
class Predictor:
    def __init__(self, weights, device="cuda:0", imgsz=640, conf=0.3, iou=0.4, batch=16, half=True):
        self.model = YOLO(weights)
        self.device = device
        self.imgsz = imgsz
        self.conf = conf
        self.iou = iou
        self.batch = batch
        self.half = half and "cuda" in str(device)

    def __call__(self, image_dir):
        return self.model.predict(
            source=image_dir,
            imgsz=self.imgsz,
            conf=self.conf,
            iou=self.iou,
            device=self.device,
            batch=self.batch,
            half=self.half,
            verbose=False,
        )
If you share what problem you’re trying to optimize (speed, memory, or result format), I can suggest more targeted tweaks; in the meantime, the built‑in batch directory inference in the Predict mode docs will usually be both faster and simpler than a custom pipeline.