COCO-Seg Dataset
The COCO-Seg dataset provides COCO (Common Objects in Context) instance segmentation masks — 118,287 training and 5,000 validation images with polygon masks across 80 object categories — in the Ultralytics YOLO label format. It uses COCO's original images and native segmentation annotations, converted for YOLO training, making it a standard resource for researchers and developers working on instance segmentation tasks.
COCO-Seg Pretrained Models#
| Model | size (pixels) | mAPbox50-95 (e2e) | mAPmask50-95 (e2e) | Speed CPU ONNX (ms) | Speed T4 TensorRT10 (ms) | params (M) | FLOPs (B) |
|---|---|---|---|---|---|---|---|
| YOLO26n-seg | 640 | 39.6 | 33.9 | 53.3 ± 0.5 | 2.1 ± 0.0 | 2.7 | 9.3 |
| YOLO26s-seg | 640 | 47.3 | 40.0 | 118.4 ± 0.9 | 3.3 ± 0.0 | 10.4 | 34.5 |
| YOLO26m-seg | 640 | 52.5 | 44.1 | 328.2 ± 2.4 | 6.7 ± 0.1 | 23.6 | 121.7 |
| YOLO26l-seg | 640 | 54.4 | 45.5 | 387.0 ± 3.7 | 8.0 ± 0.1 | 28.0 | 140.1 |
| YOLO26x-seg | 640 | 56.5 | 47.0 | 787.0 ± 6.8 | 16.4 ± 0.1 | 62.8 | 314.0 |
Key Features#
- COCO-Seg provides instance segmentation masks for 123,287 labeled COCO train2017/val2017 images (118,287 train + 5,000 val), out of COCO's broader ~330K-image release.
- The dataset consists of the same 80 object categories found in the original COCO dataset.
- Annotations provide instance segmentation masks in the YOLO polygon label format.
- COCO-Seg provides standardized mAP and mAR metrics for evaluating instance segmentation performance, enabling effective comparison of model performance.
- Download size: ~20.3 GB on first use (
train2017.zip+val2017.zip+ labels). The 7 GBtest2017.zipis not fetched automatically, since those images have withheld ground truth and are only needed for a test-dev2017 submission.
Dataset Structure#
The COCO-Seg dataset is partitioned into three subsets:
- Train2017: 118,287 images for training instance segmentation models.
- Val2017: 5,000 images used for validation during model development.
- Test-dev2017: 20,288 of the 40,670 test2017 images, used for benchmarking. Ground-truth annotations for this subset are not publicly available, so predictions must be submitted to the COCO evaluation server for scoring.
For smaller experimentation needs, see the COCO128-Seg (128 images) and COCO8-Seg (8 images) subsets.
Applications#
COCO-Seg is widely used for training and evaluating deep learning models on instance segmentation, such as the YOLO models. The large number of annotated images, the diversity of object categories, and the standardized evaluation metrics make it a standard resource for computer vision researchers and practitioners. Full COCO-Seg annotations can also be browsed and managed on Ultralytics Platform.
Dataset YAML#
A YAML file is used to define the dataset configuration. It contains information about the dataset's paths, classes, and other relevant information. In the case of the COCO-Seg dataset, the coco.yaml file is maintained at https://github.com/ultralytics/ultralytics/blob/main/ultralytics/cfg/datasets/coco.yaml.
# Ultralytics 🚀 AGPL-3.0 License - https://ultralytics.com/license

# COCO 2017 dataset https://cocodataset.org by Microsoft
# Documentation: https://docs.ultralytics.com/datasets/detect/coco
# Example usage: yolo train data=coco.yaml
# parent
# ├── ultralytics
# └── datasets
#     └── coco ← downloads here (20.3 GB)

# Train/val/test sets as 1) dir: path/to/imgs, 2) file: path/to/imgs.txt, or 3) list: [path/to/imgs1, path/to/imgs2, ..]
path: coco # dataset root dir
train: train2017.txt # train images (relative to 'path') 118287 images
val: val2017.txt # val images (relative to 'path') 5000 images
test: test-dev2017.txt # 20288 of 40670 images, submit via https://cocodataset.org/#detection-eval

# Classes
names:
  0: person
  1: bicycle
  2: car
  3: motorcycle
  4: airplane
  5: bus
  6: train
  7: truck
  8: boat
  9: traffic light
  10: fire hydrant
  11: stop sign
  12: parking meter
  13: bench
  14: bird
  15: cat
  16: dog
  17: horse
  18: sheep
  19: cow
  20: elephant
  21: bear
  22: zebra
  23: giraffe
  24: backpack
  25: umbrella
  26: handbag
  27: tie
  28: suitcase
  29: frisbee
  30: skis
  31: snowboard
  32: sports ball
  33: kite
  34: baseball bat
  35: baseball glove
  36: skateboard
  37: surfboard
  38: tennis racket
  39: bottle
  40: wine glass
  41: cup
  42: fork
  43: knife
  44: spoon
  45: bowl
  46: banana
  47: apple
  48: sandwich
  49: orange
  50: broccoli
  51: carrot
  52: hot dog
  53: pizza
  54: donut
  55: cake
  56: chair
  57: couch
  58: potted plant
  59: bed
  60: dining table
  61: toilet
  62: tv
  63: laptop
  64: mouse
  65: remote
  66: keyboard
  67: cell phone
  68: microwave
  69: oven
  70: toaster
  71: sink
  72: refrigerator
  73: book
  74: clock
  75: vase
  76: scissors
  77: teddy bear
  78: hair drier
  79: toothbrush

# Download script/URL (optional)
download: |
  from pathlib import Path

  from ultralytics.utils import ASSETS_URL
  from ultralytics.utils.downloads import download

  # Download labels
  segments = True  # segment or box labels
  dir = Path(yaml["path"])  # dataset root dir
  urls = [ASSETS_URL + ("/coco2017labels-segments.zip" if segments else "/coco2017labels.zip")]  # labels
  download(urls, dir=dir.parent)

  # Download data (test2017.zip excluded: ground truth is withheld, only used for the eval-server test-dev split)
  urls = [
      "http://images.cocodataset.org/zips/train2017.zip",  # 19G, 118k images
      "http://images.cocodataset.org/zips/val2017.zip",  # 1G, 5k images
  ]
download(urls, dir=dir / "images", threads=3)Usage#
To train a YOLO26n-seg model on the COCO-Seg dataset for 100 epochs with an image size of 640, you can use the following code snippets.
from ultralytics import YOLO

# Load a model
model = YOLO("yolo26n-seg.pt")  # load a pretrained model (recommended for training)

# Train the model
results = model.train(data="coco.yaml", epochs=100, imgsz=640)
Sample Images and Annotations#
COCO-Seg contains the same diverse images, object categories, and complex scenes as COCO, with instance segmentation masks provided in the YOLO label format. Here are some examples of images from the dataset, along with their corresponding instance segmentation masks:
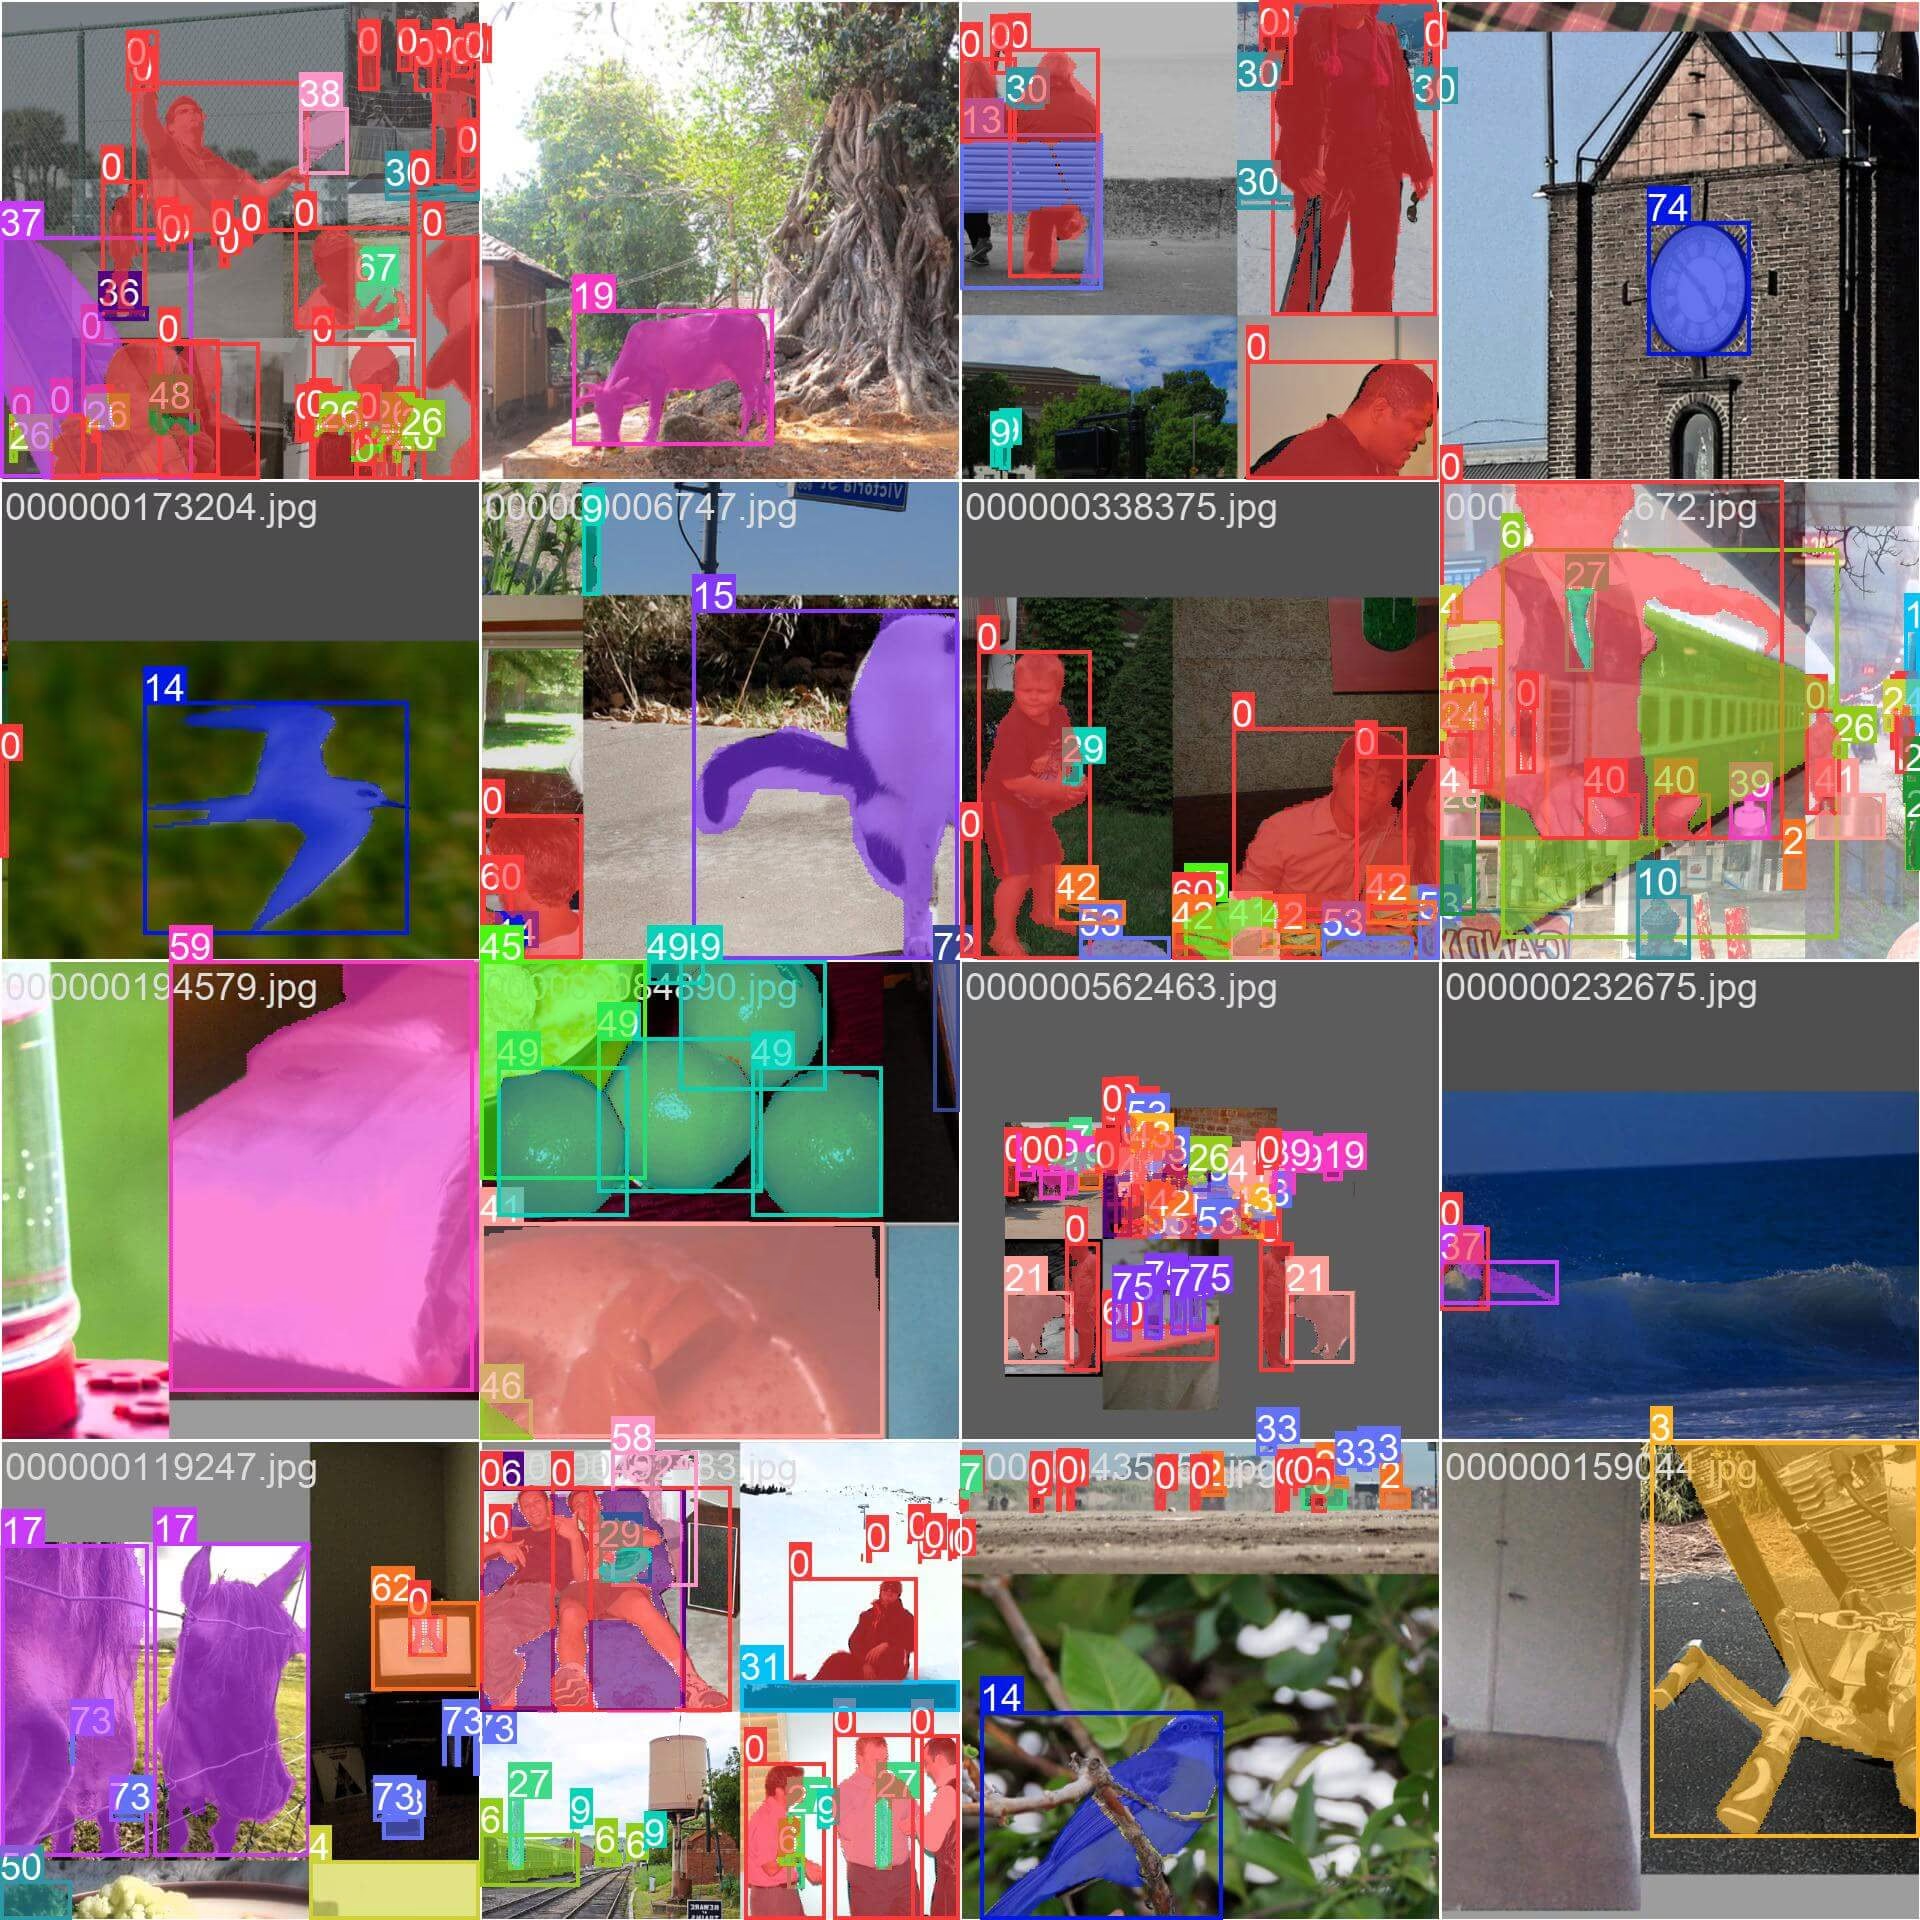
- Mosaiced Image: This image demonstrates a training batch composed of mosaiced dataset images. Mosaicing is a technique used during training that combines multiple images into a single image to increase the variety of objects and scenes within each training batch. This aids the model's ability to generalize to different object sizes, aspect ratios, and contexts.
Citations and Acknowledgments#
If you use the COCO-Seg dataset in your research or development work, please cite the original COCO paper and acknowledge the extension to COCO-Seg:
@misc{lin2015microsoft,
      title={Microsoft COCO: Common Objects in Context},
      author={Tsung-Yi Lin and Michael Maire and Serge Belongie and Lubomir Bourdev and Ross Girshick and James Hays and Pietro Perona and Deva Ramanan and C. Lawrence Zitnick and Piotr Dollár},
      year={2015},
      eprint={1405.0312},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}
We extend our thanks to the COCO Consortium for creating and maintaining this valuable resource for the computer vision community.
FAQ#
COCO-Seg is the Ultralytics YOLO-format packaging of COCO's (Common Objects in Context) native instance segmentation masks for the same 118,287 train2017 and 5,000 val2017 images. The original COCO annotations already include these polygon masks for all 80 object categories; COCO-Seg converts them to the YOLO label format used for object instance segmentation training.
To train a YOLO26n-seg model on the COCO-Seg dataset for 100 epochs with an image size of 640, you can use the following code snippets. For a detailed list of available training arguments, refer to the model Training page.
Train Examplefrom ultralytics import YOLO # Load a model model = YOLO("yolo26n-seg.pt") # load a pretrained model (recommended for training) # Train the model results = model.train(data="coco.yaml", epochs=100, imgsz=640)The COCO-Seg dataset includes several key features:
- Provides instance segmentation masks for 123,287 labeled COCO train2017/val2017 images (118,287 train + 5,000 val).
- Annotates the same 80 object categories found in the original COCO.
- Provides instance segmentation masks in the YOLO polygon label format.
- Uses standardized evaluation metrics such as mean Average Precision (mAP) and mean Average Recall (mAR) for instance segmentation tasks.
The COCO-Seg dataset supports multiple pretrained YOLO26 segmentation models with varying performance metrics. Here's a summary of the available models and their key metrics:
Model size
(pixels)mAPbox50-95
(e2e)mAPmask50-95
(e2e)Speed
CPU ONNX
(ms)Speed
T4 TensorRT10
(ms)params
(M)FLOPs
(B)YOLO26n-seg 640 39.6 33.9 53.3 ± 0.5 2.1 ± 0.0 2.7 9.3 YOLO26s-seg 640 47.3 40.0 118.4 ± 0.9 3.3 ± 0.0 10.4 34.5 YOLO26m-seg 640 52.5 44.1 328.2 ± 2.4 6.7 ± 0.1 23.6 121.7 YOLO26l-seg 640 54.4 45.5 387.0 ± 3.7 8.0 ± 0.1 28.0 140.1 YOLO26x-seg 640 56.5 47.0 787.0 ± 6.8 16.4 ± 0.1 62.8 314.0 These models range from the lightweight YOLO26n-seg to the more accurate YOLO26x-seg, offering different trade-offs between speed and accuracy to suit various application requirements.
The COCO-Seg dataset is partitioned into three subsets for specific training and evaluation needs:
- Train2017: Contains 118,287 images used primarily for training instance segmentation models.
- Val2017: Comprises 5,000 images used for validation during the training process.
- Test-dev2017: Contains 20,288 of the 40,670 test2017 images reserved for testing and benchmarking trained models. Note that ground truth annotations for this subset are not publicly available, and performance results are submitted to the COCO evaluation server for assessment.
For smaller experimentation needs, you might also consider the COCO128-Seg dataset (128 images) or the COCO8-Seg dataset, a compact version containing just 8 images from the COCO train 2017 set.


Comments10
Ask a question, share your results, or help someone else.
liujieKermit
what the label format if I want to train my custom dataset, please give the solution step by step like label, train, val, export, predict
 Glenn JocherUltralytics(edited)
@liujieKermit for custom segmentation training with YOLO26, follow these steps:
-
Label Format: Use YOLO segmentation format - one text file per image with class index and normalized polygon coordinates (minimum 3 points per object). Example:
<class> <x1> <y1> <x2> <y2> ... <xn> <yn> -
Dataset YAML: Create a YAML file (example
data.yaml):
path: /path/to/dataset train: images/train val: images/val names: 0: class1 1: class2- Train:
from ultralytics import YOLO model = YOLO('yolo26n-seg.pt') model.train(data='data.yaml', epochs=100, imgsz=640)- Export/Predict:
model.export(format='onnx')  # export
model.predict('image.jpg')  # predict
For full details see our Dataset Format Guide and Auto-Annotation Tools. For commercial use, review our license terms.
-
YingdiZhang
Thanks for the great work. I am new to YOLO and AI. How to download the COCO dataset? is just running python coco.yaml?
- Glenn JocherUltralytics(edited)
@YingdiZhang to download the COCO dataset, you can run
yolo segment train data=coco.yamlin your terminal. This will automatically download the dataset for you. For more details, you can visit the Ultralytics documentation.
SacherTorte280
Dear developpers, I need to build a much simpler case where I'll only need <=5 labels, can I remove the others that i'll never use ?
 Paula DerrengerUltralytics(edited)
@SacherTorte280 yes, you can customize the dataset to include only the labels you need. To do this, modify the
coco.yamlfile to include only the desired classes in thenamessection and adjust the dataset paths accordingly. Also make sure the class indices in your label files are remapped to match the newnames(0 to N-1) and remove labels of the dropped classes. This will allow you to train your model with a simplified set of labels. For more details on configuring the dataset, please refer to the COCO-Seg documentation.
MoAbbasid
i get a list out of index error when running convert_coco function please help
- Paula DerrengerUltralytics
Hi there! It looks like you're encountering a
list index out of rangeerror with theconvert_cocofunction. This can often happen if the script is trying to access an element that doesn't exist in a list. To help you resolve this issue, please ensure that:- The data paths in your
coco.yamlconfig file are correctly set and point to valid files. - The COCO dataset is correctly downloaded and structured as expected by the script.
If the paths and dataset structure are correct, it might be helpful to check if the specific segment of data causing the error is formatted correctly or missing elements.
Here's a quick check you can perform:
try:
    # Assuming convert_coco is called here
    convert_coco()
except IndexError as e:
    print("An index error occurred: ", e)
    # You can add more debugging information here to understand which part of the data is causing the problem
This snippet will catch the
IndexErrorand print it, potentially providing more insight on what's going wrong. If you need further assistance, please don't hesitate to share a snippet of the data or more details on the error! - The data paths in your
mohamed-ladjal
Greetings, I possess medical imagery depicting bone lesions. These images comprise 3D volumes of dimensions (256, 256, 128), with each volume containing 128 slices. Corresponding masks of identical dimensions are available. My objective is to either fine-tune or train a model using these slices to accurately segment the lesions mohamed mohamed.laadjel2019@gmail.com
- Glenn JocherUltralytics(edited)
Hello Mohamed,
Great to hear about your project on segmenting bone lesions from medical imagery! For your 3D volumes, you can approach this by treating each slice as a separate 2D image for segmentation.
Given your setup, you might consider using our YOLO26-seg models, which are well-suited for segmentation tasks. Here’s a basic example of how you could set up your training with YOLO26:
from ultralytics import YOLO

# Load a pretrained segmentation model
model = YOLO('yolo26n-seg.pt')  # Choose the appropriate model size

# Prepare your dataset in a compatible format
# Ensure your dataset directory structure and annotations are correctly set up

# Train the model
results = model.train(data='your_dataset_config.yaml', epochs=100, imgsz=640)
Make sure your dataset is annotated similarly to how COCO-Seg annotations are structured, with masks corresponding to each slice. You might need to adjust the
your_dataset_config.yamlto correctly point to your training, validation, and test images along with their annotations.For more detailed guidance on preparing your dataset and annotations, you can refer to our documentation on COCO-Seg Dataset.
If you have any more questions or need further assistance, feel free to ask. Happy training! 🚀