تقسيم المثيلات وتتبعها باستخدام Ultralytics YOLO26
ما تقسيم المثيلات؟#
تقسيم المثيلات مهمة في الرؤية الحاسوبية تتضمن تحديد الكائنات الفردية في الصورة ورسم حدودها على مستوى البكسل. وعلى خلاف التقسيم الدلالي، الذي يصنّف وحدات البكسل حسب الفئة فقط، يعيّن تقسيم المثيلات تسمية فريدة لكل مثيل كائن ويحدد حدوده بدقة، مما يجعله ضروريًا للتطبيقات التي تتطلب فهمًا مكانيًا مفصلًا، مثل التصوير الطبي والقيادة الذاتية والأتمتة الصناعية.
يحدد Ultralytics YOLO26 حدود الكائنات بدقة مع الحفاظ على السرعة والكفاءة اللتين تشتهر بهما نماذج YOLO.
يتوفر نوعان من تتبّع تقسيم المثيلات في حزمة Ultralytics:
-
تقسيم المثيلات باستخدام كائنات الفئات: يُخصَّص لون فريد لكل كائن فئة لتمييزه بصريًا بوضوح.
-
تقسيم المثيلات باستخدام مسارات الكائنات: يُمثَّل كل مسار بلون مميز، مما يسهّل تحديد الكائنات وتتبعها عبر إطارات الفيديو.
شاهد: تقسيم المثيلات مع تتبع الكائنات باستخدام Ultralytics YOLO26
العينات#
| تقسيم المثيلات | تقسيم المثيلات + تتبّع الكائنات |
|---|---|
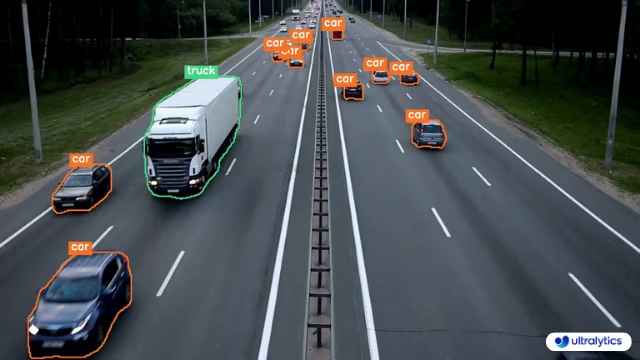 | 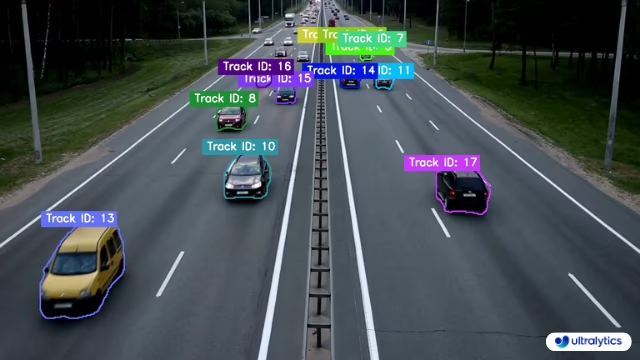 |
| تجزئة الكائنات الفردية في Ultralytics | تجزئة الكائنات الفردية في Ultralytics مع تتبع الكائنات |
قسّم الكائنات وتتبعها باستخدام YOLO26#
يشغّل الحل InstanceSegmentation نموذج تجزئة YOLO26 على كل إطار، ويرسم أقنعة لكل كائن، ويمنح كل كائن لونًا مستقلًا، ما يتيح لك تتبّع الكائنات الفردية عبر الفيديو. حمّل نموذج -seg مثل YOLO26n-seg، ثم شغّله على المصدر باستخدام واجهة Python البرمجية أو CLI.
# Instance segmentation using Ultralytics YOLO26
yolo solutions isegment show=True

# Pass a source video
yolo solutions isegment source="path/to/video.mp4"

# Monitor the specific classes
yolo solutions isegment classes="[0, 5]"
وسيطات InstanceSegmentation#
إليك جدولًا بمعاملات InstanceSegmentation:
| المعامل | النوع | الافتراضي | الوصف |
|---|---|---|---|
model | str | None | مسار ملف نموذج Ultralytics YOLO. |
line_width | int | 2 | سماكة الخط للصناديق والنقاط المفتاحية والعدادات التي يرسمها الحل. |
verbose | bool | True | يفعّل سجل الحل لكل إطار، ويشمل شكل المدخل وعدد الفئات وسرعة المعالجة. يظل استدعاء التتبع نفسه صامتًا دائمًا. |
يمكنك أيضًا استخدام وسيطات track ضمن الحل InstanceSegmentation:
| المعامل | النوع | الافتراضي | الوصف |
|---|---|---|---|
tracker | str | 'tracktrack.yaml' | يحدد خوارزمية التتبع المطلوب استخدامها. الخيارات المضمنة: botsort.yaml، bytetrack.yaml، ocsort.yaml، deepocsort.yaml، fasttrack.yaml، tracktrack.yaml. |
conf | float | 0.25 | يضبط عتبة الثقة للكشوفات؛ إذ تسمح القيم الأقل بتتبع مزيد من الكائنات، لكنها قد تتضمن إيجابيات كاذبة. |
iou | float | 0.5 | يضبط عتبة التقاطع على الاتحاد (IoU) لتصفية الكشوفات المتداخلة. |
classes | list | None | يصفّي النتائج حسب فهرس الفئة. على سبيل المثال، لا يتتبع classes=[0, 2, 3] إلا الفئات المحددة. |
device | str | None | يحدد الجهاز المستخدم للاستدلال (مثل cpu أو cuda:0 أو 0). ويتيح للمستخدمين الاختيار بين CPU أو GPU محددة أو أجهزة حوسبة أخرى لتنفيذ النموذج. |
imgsz | int or tuple | 640 | حجم صورة الاستدلال المستهدف: عدد صحيح لصورة مربعة، أو زوج (height, width). تُعدّل الأبعاد وفقًا لخطوة النموذج. |
max_det | int | 300 | الحد الأقصى لعدد الكشوفات التي يُحتفظ بها لكل إطار قبل التتبع، ما يحد من عدد الكائنات التي يعالجها الحل في المشاهد الكثيفة. |
quantize | int or str | None | دقة الاستدلال: 16 (FP16) أو 32/unset (FP32) لنماذج PyTorch وTorchScript خارج CPU؛ أما التنسيقات الأخرى فتستخدم الدقة التي يحددها الملف الاصطناعي وبيئة التشغيل. يحل هذا الوسيط محل الوسيطة half المهملة. |
بالإضافة إلى ذلك، تتوفر معاملات التصوّر التالية:
| المعامل | النوع | الافتراضي | الوصف |
|---|---|---|---|
show | bool | False | إذا كان True، يعرض الصور أو مقاطع الفيديو المشروحة في نافذة. يفيد ذلك في الحصول على ملاحظات مرئية فورية أثناء التطوير أو الاختبار. |
show_conf | bool | True | يعرض درجة الثقة لكل اكتشاف بجوار التسمية، ما يوضح مدى يقين النموذج بشأن كل اكتشاف. |
show_labels | bool | True | يعرض تسميات كل اكتشاف في المخرجات المرئية، ما يتيح فهم الكائنات المكتشفة فورًا. |
show_boxes | bool | True | يرسم صناديق إحاطة حول الكائنات المكتشفة. ويُعد ذلك ضروريًا للتعرف بصريًا على الكائنات وتحديد مواقعها في الصور أو إطارات الفيديو. |
تطبيقات تقسيم المثيلات#
لتقسيم المثيلات باستخدام YOLO26 تطبيقات عديدة في العالم الحقيقي عبر قطاعات مختلفة:
إدارة النفايات وإعادة التدوير#
يمكن استخدام YOLO26 في منشآت إدارة النفايات لتحديد أنواع المواد المختلفة وفرزها. يستطيع النموذج تقسيم النفايات البلاستيكية والكرتون والمعادن وغيرها من المواد القابلة لإعادة التدوير بدقة عالية، مما يتيح لأنظمة الفرز الآلي معالجة النفايات بكفاءة أكبر. وتكتسب هذه الإمكانية أهمية خاصة لأن نحو 10% فقط من أصل 7 مليارات طن من النفايات البلاستيكية المتولدة عالميًا يُعاد تدويرها.
المركبات ذاتية القيادة#
في السيارات ذاتية القيادة، تساعد تجزئة الكائنات الفردية على تحديد المشاة والمركبات وإشارات المرور وعناصر الطريق الأخرى وتتبعها على مستوى البكسل. ويُعد هذا الفهم الدقيق للبيئة ضروريًا لقرارات الملاحة والسلامة. تجعل السرعة الآنية التي يوفرها YOLO26 مناسبًا لهذه التطبيقات الحساسة للوقت.
التصوير الطبي#
يمكن لتقسيم المثيلات تحديد الأورام أو الأعضاء أو البنى الخلوية ورسم حدودها في الصور الطبية. وتجعل قدرة YOLO26 على ترسيم حدود الكائنات بدقة منه أداة قيّمة في التشخيص الطبي وتخطيط العلاج.
مراقبة مواقع الإنشاء#
في مواقع البناء، يمكن لتجزئة الكائنات الفردية تتبع الآليات الثقيلة والعاملين والمواد. ويساعد ذلك في ضمان السلامة من خلال مراقبة مواقع المعدات واكتشاف دخول العاملين إلى المناطق الخطرة، مع تحسين سير العمل وتوزيع الموارد أيضًا.
الأسئلة الشائعة#
لإجراء تجزئة الكائنات الفردية باستخدام Ultralytics YOLO26، ابدأ تهيئة الحل
InstanceSegmentationباستخدام نموذج تجزئة من YOLO26، ثم عالج إطارات الفيديو من خلاله. إليك مثالًا مبسطًا على الشيفرة:import cv2 from ultralytics import solutions cap = cv2.VideoCapture("path/to/video.mp4") assert cap.isOpened(), "Error reading video file" # كاتب الفيديو w, h, fps = (int(cap.get(x)) for x in (cv2.CAP_PROP_FRAME_WIDTH, cv2.CAP_PROP_FRAME_HEIGHT, cv2.CAP_PROP_FPS)) video_writer = cv2.VideoWriter("instance-segmentation.avi", cv2.VideoWriter_fourcc(*"mp4v"), fps, (w, h)) # تهيئة InstanceSegmentation isegment = solutions.InstanceSegmentation( show=True, # # اعرض الناتج model="yolo26n-seg.pt", # model="yolo26n-seg.pt" لتقسيم الكائنات باستخدام YOLO26. ) # معالجة الفيديو while cap.isOpened(): success, im0 = cap.read() if not success: print("Video frame is empty or processing is complete.") break results = isegment(im0) video_writer.write(results.plot_im) cap.release() video_writer.release() cv2.destroyAllWindows()تحدد تجزئة الكائنات الفردية الكائنات الفردية داخل الصورة وترسم حدودها، مانحةً كل كائن تسمية وقناعًا فريدين. ويضيف تتبع الكائنات إلى ذلك تعيين معرّفات متسقة للكائنات عبر إطارات الفيديو، ما يسهّل مواصلة تتبع الكائنات نفسها بمرور الوقت. وعند الجمع بينهما، كما في تطبيق YOLO26، يمكنك تحليل حركة الكائنات وسلوكها في مقاطع الفيديو مع الحفاظ على معلومات دقيقة عن الحدود.
يوفر Ultralytics YOLO26 أداءً آنيًا ودقة تنافسية وسهولة في الاستخدام مقارنةً بالنماذج ذات المرحلتين مثل Mask R-CNN أو Faster R-CNN. يعالج YOLO26 الصور بتمرير واحد (اكتشاف أحادي المرحلة)، ما يجعله أسرع بكثير مع الحفاظ على دقة عالية. كما يتكامل مع Ultralytics Platform لإدارة النماذج ومجموعات البيانات ومسارات التدريب. ويوفر YOLO26 توازنًا قويًا للتطبيقات التي تتطلب السرعة والدقة معًا.
نعم، توفر Ultralytics عدة مجموعات بيانات مناسبة لتدريب نماذج YOLO26 على تقسيم المثيلات، منها COCO-Seg وCOCO8-Seg (مجموعة فرعية أصغر للاختبار السريع) وPackage-Seg وCrack-Seg. تتضمن مجموعات البيانات هذه تعليقات توضيحية على مستوى البكسل، وهي ضرورية لمهام تقسيم المثيلات. وللتطبيقات الأكثر تخصصًا، يمكنك أيضًا إنشاء مجموعات بيانات مخصصة وفق تنسيق Ultralytics. تتوفر معلومات مجموعات البيانات الكاملة وتعليمات استخدامها في وثائق مجموعات بيانات Ultralytics.


التعليقات99
اطرح سؤالًا، وشارك نتائجك، أو ساعد شخصًا آخر.
CatFatOw
Hello, I am trying to analyze a video and see if features grow/shrink over time. I am currently trying to use instance segmentation with object tracking; however, specifying
save_txt=Trueparameter inmodel.tracksaves every single prediction into a single huge txt file. Trying to count the frames by going through this large txt apparently doesn't work as the class ID are not in order and sorting it would lose all information.Is there any way for Ultralytics to save the txt files by frame number? For example, frame1.txt only contains the predictions of the first frame.
Any help would be greatly appreciated!
1 Glenn JocherUltralytics
For per-frame TXT saving with tracking, you'll need to process results in your video loop and write custom frame-specific files. Here's a minimal adaptation of the Instance Segmentation and Tracking example:
frame_count = 0
while cap.isOpened():
    ret, im0 = cap.read()
    if not ret: break

    results = model.track(im0, persist=True)

    # Save current frame's tracked objects
    with open(f'frame{frame_count}.txt', 'w') as f:
        for box, mask, track_id in zip(results[0].boxes, results[0].masks, results[0].boxes.id.int().cpu().tolist()):
            f.write(f"{track_id} {box.cls.item()} {box.xywhn.tolist()} {mask.xy[0].tolist()}\n")

    frame_count += 1
This creates individual frameX.txt files with tracking IDs, class IDs, normalized boxes, and mask coordinates. The official documentation shows similar frame processing in the Instance Segmentation with Object Tracking examples.
Thank you!
- Glenn JocherUltralytics
For per-frame TXT saving during tracking, you'll need to process each frame individually in your video loop as shown in the Instance Segmentation with Object Tracking example. Here's a minimal adaptation that creates frame-specific files:
frame_count = 0
while cap.isOpened():
    ret, im0 = cap.read()
    if not ret: break

    results = model.track(im0, persist=True)

    with open(f'frame{frame_count}.txt', 'w') as f:
        for box, mask, track_id in zip(results[0].boxes, results[0].masks, results[0].boxes.id.int().cpu().tolist()):
            f.write(f"{track_id} {box.cls.item()} {box.xywhn.tolist()} {mask.xy[0].tolist()}\n")

    frame_count += 1
This creates individual frameX.txt files with tracking IDs, class IDs, normalized boxes, and mask coordinates per frame. The approach mirrors the frame processing shown in our official tracking documentation.
pedmindset
Been trying to figure this out for a while now. I want to ask, can I use object counting in regions with instance sementation and tracking? You want to count vehicles that cross two specific regions, like so Object 001 crossed region A and region B. Is this possible to do
1- Glenn JocherUltralytics
@pedmindset yes, it is possible to combine object counting in regions with instance segmentation and tracking using Ultralytics YOLO11. You can use the
trackmethod to assign consistent IDs to objects across frames and define regions to monitor their crossings. For guidance, refer to the segmentation and tracking examples in the Instance Segmentation and Tracking Guide. Let us know if you need further clarification!
DP1701
Cool, but I can't define an imgsz via solutions.InstanceSegmentation(…). Is there another option for this?
- Glenn JocherUltralytics
solutions.InstanceSegmentationis a higher-level wrapper and doesn’t currently exposeimgszdirectly; if you need to control input size, run segmentation+tracking via the coreYOLO(...).track()API (supportsimgsz) as shown in the Tracking mode docs and keep using the Instance Segmentation and Tracking guide for solution-level usage.from ultralytics import YOLO model = YOLO("yolo26n-seg.pt") results = model.track(source="path/to/video.mp4", imgsz=640, show=True, tracker="botsort.yaml")
Hello, I noticed that when using tracking mode compared to normal segmentation prediction, the number of features predicted decreased by quite a lot for feature dense videos even if I use the same parameters of confidence and maximum detection?
- Glenn JocherUltralytics
@CatFatOw great observation! This is actually expected behavior when using tracking mode compared to plain segmentation. Tracking algorithms apply additional filtering beyond confidence thresholds to maintain stable tracks, which can reduce the total number of detections.
Here are a few things that might help increase detections while maintaining tracking:
# Try adjusting these tracking-specific parameters
results = model.track(
    frame,
    persist=True,
    conf=0.3,  # Lower confidence threshold
    iou=0.5,   # Adjust IoU threshold for NMS
    max_det=1000,  # Increase max detections
    tracker="bytetrack.yaml"  # Try different trackers
)
You can also experiment with different tracking algorithms - ByteTrack tends to be more permissive with new track creation compared to BoTSORT. The trade-off is between detection sensitivity and tracking stability, where tracking prioritizes consistent object IDs over detecting every possible instance.
If you need maximum detection sensitivity, consider running both modes and using tracking results only when you need the temporal consistency.
Ok, thank you for the reply!
Mauricio566
Hello. Please, I need your help. I know exactly what segmenting an object is and how to do it. But I don't know what to do with an already segmented object or pixel mask. You can find a lot of information online about "how to segment a model or fit it to your dataset," but they don't tell you what to do with those masks in real projects. Can you give me some ideas or help, please? for r in results:
if r.masks is not None: mask = r.masks.data[0].cpu().numpy() there is the mask but honestly I don't know what to do. thankse-roe
Hello Glenn, thanks for the example! Actually, I had already figured it out—it was more of a suggestion for the documentation examples. []´s
- Glenn JocherUltralytics
Thank you for the suggestion! We always welcome community contributions to improve our documentation through GitHub Pull Requests. Feel free to submit any specific improvements you'd like to see in the Instance Segmentation with Object Tracking guide.
1
Hello, Wouldn't it be good to have a complete example showing how to extract the track ID, contour points, class, and confidence? These methods that handle everything automatically end up being of little practical use, and finding this information in the documentation is quite challenging—it's often easier to find from third-party sources. []´s
- Glenn JocherUltralytics(تم التعديل)
@e-roe thanks for your feedback! You can access track IDs, classes, masks, and confidence scores directly from the results object. Here's a concise example showing how to extract these details:
results = isegment(im0)
for i in range(len(isegment.clss)):
    track_id = isegment.track_ids[i]
    class_name = isegment.names[isegment.clss[i]]
    confidence = isegment.confs[i]
    mask = isegment.masks[i].data[0].numpy()  # Binary mask array
    contours, _ = cv2.findContours(mask.astype(np.uint8), cv2.RETR_EXTERNAL, cv2.CHAIN_APPROX_SIMPLE)
For full implementation details, see the InstanceSegmentation reference in our documentation. Let us know if you need further clarification!
expen6ve
Hi! I tried training a pretrained yolov8m-seg model on our custom 1 class dataset consisting of 1,307 images with 5 augmentations like:
Flip: Horizontal, Vertical Rotation: Between -15° and +15° Saturation: Between -25% and +25% Blur: Up to 1.4px Noise: Up to 1.49% of pixels
with these training configurations:
# Train the model
results = model.train(
    data="data6.yaml",
    epochs=250,
    imgsz=320,
    batch=8,
    workers=4,
    device=device,
    patience=18,
    copy_paste=0.1  # Add this line to enable copy-paste augmentation
)
this is my 16th model training as i tried testing out from 200+ images that and so on. In my val plots, i always get bad results. What can i further do to make a good model? it stopped training at 128 with the results below:
epoch,time,train/box_loss,train/seg_loss,train/cls_loss,train/dfl_loss,metrics/precision(B),metrics/recall(B),metrics/mAP50(B),metrics/mAP50-95(B),metrics/precision(M),metrics/recall(M),metrics/mAP50(M),metrics/mAP50-95(M),val/box_loss,val/seg_loss,val/cls_loss,val/dfl_loss,lr/pg0,lr/pg1,lr/pg2
126,4123.96,0.47628,0.76702,0.30532,0.85667,0.9862,0.96565,0.98972,0.94445,0.9775,0.97566,0.98923,0.83189,0.35178,0.67432,0.26286,0.89191,0.00101,0.00101,0.00101 127,4156.45,0.47613,0.76458,0.30439,0.85872,0.96877,0.98339,0.98913,0.94227,0.98701,0.96962,0.99053,0.83626,0.34228,0.67744,0.25083,0.88958,0.00100208,0.00100208,0.00100208
- Glenn JocherUltralytics(تم التعديل)
@expen6ve thank you for sharing your training details. For improved segmentation results with YOLO26, consider these adjustments:
- Dataset Size: 1.3k images may be insufficient for robust segmentation. Aim for ≥5k high-quality annotated images.
- Augmentation Tuning: Reduce rotation range (try ±5°) and remove noise augmentation, which can degrade mask precision.
- Hyperparameters: Increase imgsz to 640 (standard for segmentation tasks) and lower learning rate to 0.0001 with cosine scheduler.
- Model Selection: Try YOLO26s-seg instead of medium-sized models for better generalization on limited data.
For detailed guidance, see the Segmentation Training Tips in our documentation.
ShreyasChhetri
Hi can we implement a Reinforcement Learning function up above the Yolo training function for more accuracy can it happen ?
- Glenn JocherUltralytics
@ShreyasChhetri integrating reinforcement learning (RL) with YOLO training is an interesting idea, but YOLO models are not inherently designed for RL workflows. While it is theoretically possible, it would require substantial custom development outside the scope of the provided Ultralytics framework. You might consider exploring hybrid approaches combining RL and computer vision if your use case demands it. For standard training, refer to the existing YOLO training documentation: https://docs.ultralytics.com/modes/train.
ZhangAiyi
I have a question when run the code for Instance Segmentation with Object Tracking. The pycharm said UnicodeEncodeError: 'gbk' codec can't encode character '\u274c' in position 401: illegal multibyte sequence. Does anyone have the similar question? Thank you.
- Glenn JocherUltralytics
@ZhangAiyi it seems like you're encountering a Unicode encoding issue. You can try setting your environment's encoding to UTF-8 in PyCharm to resolve this. If the problem persists, please check the PyCharm settings or your system's locale configuration.