Segment Anything Model (SAM)#

The Segment Anything Model (SAM) from Meta introduced promptable image segmentation: given a point, box, or mask prompt, it returns a mask for the indicated object, with a lightweight decoder fast enough for interactive use.
Introduction to SAM: The Segment Anything Model#
The Segment Anything Model, or SAM, is an image segmentation model built for promptable segmentation across a wide range of image analysis tasks. SAM is the core of Meta's Segment Anything project, which introduced a new model, task, and dataset for image segmentation.
SAM's design allows it to adapt to new image distributions and tasks without prior knowledge, a capability known as zero-shot transfer. Trained on the SA-1B dataset, which contains more than 1 billion masks across 11 million curated images, SAM shows strong zero-shot performance that is often competitive with or better than prior fully supervised results.
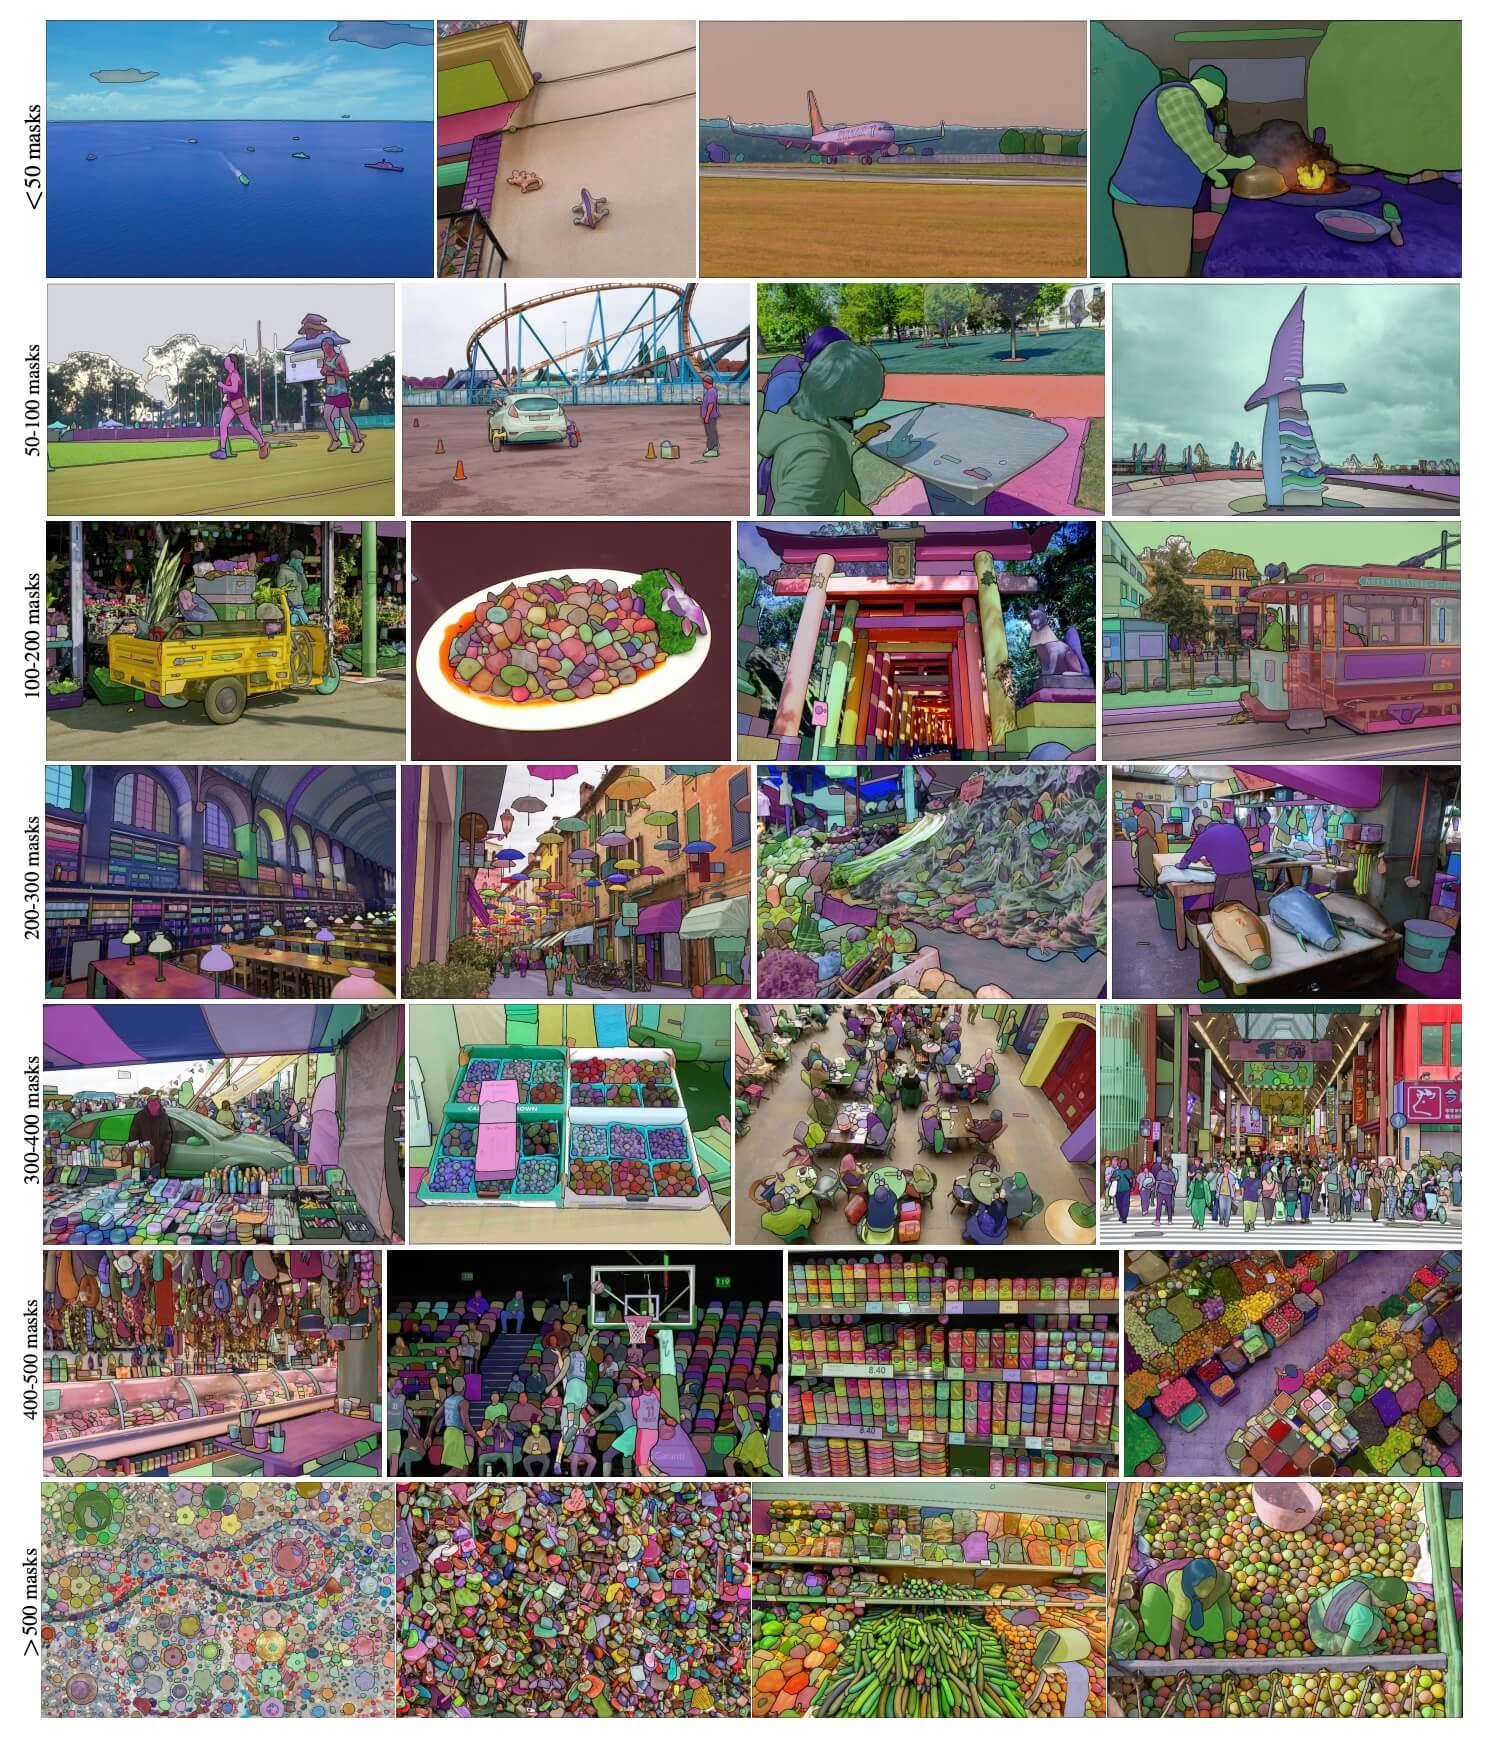 SA-1B example images. Images with overlaid masks from the SA-1B dataset. SA-1B contains 11M diverse, high-resolution, licensed, and privacy-protecting images and 1.1B high-quality segmentation masks. These masks were annotated fully automatically by SAM, and as verified by human ratings and numerous experiments, are of high quality and diversity. Images are grouped by number of masks per image for visualization (there are ∼100 masks per image on average).
Key Features of the Segment Anything Model (SAM)#
- Promptable Segmentation Task: SAM was designed with a promptable segmentation task in mind, allowing it to generate valid segmentation masks from any given prompt, such as spatial or text clues identifying an object.
- Advanced Architecture: The Segment Anything Model uses a heavyweight image encoder, a prompt encoder, and a lightweight mask decoder. This architecture enables flexible prompting, real-time mask computation, and ambiguity awareness in segmentation tasks.
- The SA-1B Dataset: Introduced by the Segment Anything project, the SA-1B dataset features over 1 billion masks on 11 million images. As the largest segmentation dataset at its release, it provides SAM with a diverse and large-scale training data source.
- Zero-Shot Performance: SAM displays strong zero-shot performance across various segmentation tasks, making it a ready-to-use tool for diverse applications with minimal need for prompt engineering.
For an in-depth look at the Segment Anything Model and the SA-1B dataset, please visit the Segment Anything GitHub and check out the research paper Segment Anything.
SAM-family models (SAM 2.1, SAM 3, and SAM 3.1) power the smart annotation feature on Ultralytics Platform, enabling click-based masking for fast dataset labeling.
Available Models, Supported Tasks, and Operating Modes#
This table presents the available models with their specific pretrained weights, the tasks they support, and their compatibility with different operating modes like Training, Validation, Inference, and Export. Supported modes are indicated by ✅ and unsupported modes by ❌.
| Model Type | Pretrained Weights | Tasks Supported | Training | Validation | Inference | Export |
|---|---|---|---|---|---|---|
| SAM base | sam_b.pt | Instance Segmentation | ❌ | ❌ | ✅ | ❌ |
| SAM large | sam_l.pt | Instance Segmentation | ❌ | ❌ | ✅ | ❌ |
How to Use SAM: Versatility and Power in Image Segmentation#
The Segment Anything Model can be used for many downstream tasks beyond its training data, including edge detection, object proposal generation, instance segmentation, and preliminary text-to-mask prediction. With prompt engineering, SAM can adapt to new tasks and data distributions in a zero-shot manner.
SAM prediction example#
Segment image with given prompts.
from ultralytics import SAM

# Load a model
model = SAM("sam_b.pt")

# Display model information (optional)
model.info()

# Run inference with bboxes prompt
results = model("ultralytics/assets/zidane.jpg", bboxes=[439, 437, 524, 709])

# Run inference with single point
results = model(points=[900, 370], labels=[1])

# Run inference with multiple points
results = model(points=[[400, 370], [900, 370]], labels=[1, 1])

# Run inference with multiple points prompt per object
results = model(points=[[[400, 370], [900, 370]]], labels=[[1, 1]])

# Run inference with negative points prompt
results = model(points=[[[400, 370], [900, 370]]], labels=[[1, 0]])
Segment the whole image.
from ultralytics import SAM

# Load a model
model = SAM("sam_b.pt")

# Display model information (optional)
model.info()

# Run inference
model("path/to/image.jpg")- SAM segments the whole image when you don't pass any prompts (bboxes/points/masks).
Set the image once, then run prompt inference multiple times without re-running the image encoder.
import cv2

from ultralytics.models.sam import Predictor as SAMPredictor

# Create SAMPredictor
overrides = {"conf": 0.25, "task": "segment", "mode": "predict", "imgsz": 1024, "model": "mobile_sam.pt"}
predictor = SAMPredictor(overrides=overrides)

# Set image
predictor.set_image("ultralytics/assets/zidane.jpg")  # set with image file
predictor.set_image(cv2.imread("ultralytics/assets/zidane.jpg"))  # set with np.ndarray
results = predictor(bboxes=[439, 437, 524, 709])

# Run inference with single point prompt
results = predictor(points=[900, 370], labels=[1])

# Run inference with multiple points prompt
results = predictor(points=[[400, 370], [900, 370]], labels=[1, 1])

# Run inference with negative points prompt
results = predictor(points=[[[400, 370], [900, 370]]], labels=[[1, 0]])

# Reset image
predictor.reset_image()
Segment everything with additional args.
from ultralytics.models.sam import Predictor as SAMPredictor

# Create SAMPredictor
overrides = {"conf": 0.25, "task": "segment", "mode": "predict", "imgsz": 1024, "model": "mobile_sam.pt"}
predictor = SAMPredictor(overrides=overrides)

# Segment with additional args
results = predictor(source="ultralytics/assets/zidane.jpg", crop_n_layers=1, points_stride=64, min_mask_region_area=100)All the returned results in the above examples are Results objects which provide access to the predicted masks and the source image.
- For more
Segment everythingargs, see thePredictor/generateReference.
SAM Comparison vs YOLO#
Here we compare Meta's SAM-b model with Ultralytics segmentation models, including YOLO26:
| Model | Size (MB) | Parameters (M) | Speed (CPU) (ms/im) |
|---|---|---|---|
| Meta SAM-b | 375 | 93.7 | 41703 |
| MobileSAM | 40.7 | 10.1 | 23802 |
| FastSAM-s with YOLOv8 backbone | 23.9 | 11.8 | 58.0 |
| Ultralytics YOLOv8n-seg | 7.1 (52.8x smaller) | 3.4 (27.6x less) | 24.8 (1682x faster) |
| Ultralytics YOLO11n-seg | 6.2 (60.5x smaller) | 2.9 (32.3x less) | 24.3 (1716x faster) |
| Ultralytics YOLO26n-seg | 6.7 (56.0x smaller) | 2.7 (34.7x less) | 25.2 (1655x faster) |
This comparison demonstrates the substantial differences in model sizes and speeds between SAM variants and YOLO segmentation models. While SAM provides unique automatic segmentation capabilities, YOLO models, particularly YOLOv8n-seg, YOLO11n-seg and YOLO26n-seg, are significantly smaller, faster, and more computationally efficient.
SAM speeds measured with PyTorch, YOLO speeds measured with ONNX Runtime. Tests run on a 2025 Apple M4 Air with 16GB of RAM using torch==2.10.0, ultralytics==8.4.31, and onnxruntime==1.24.4. To reproduce this test:
from ultralytics import ASSETS, SAM, YOLO, FastSAM

# Profile SAM-b, MobileSAM
for file in ["sam_b.pt", "mobile_sam.pt"]:
    model = SAM(file)
    model.info()
    model(ASSETS)

# Profile FastSAM-s
model = FastSAM("FastSAM-s.pt")
model.info()
model(ASSETS)

# Profile YOLO models (ONNX)
for file_name in ["yolov8n-seg.pt", "yolo11n-seg.pt", "yolo26n-seg.pt"]:
    model = YOLO(file_name)
    model.info()
    onnx_path = model.export(format="onnx", dynamic=True, nms=False)  # YOLO26 NMS-free head; no-op for YOLOv8/YOLO11
    model = YOLO(onnx_path)
    model(ASSETS)
Auto-Annotation: A Quick Path to Segmentation Datasets#
Auto-annotation is a key feature of SAM, allowing users to generate a segmentation dataset using a pretrained detection model. This feature enables rapid annotation of large numbers of images, bypassing time-consuming manual labeling.
Generate Your Segmentation Dataset Using a Detection Model#
To auto-annotate your dataset with the Ultralytics framework, use the auto_annotate function, which pairs a detector such as YOLO26x with SAM:
from ultralytics.data.annotator import auto_annotate

auto_annotate(data="path/to/images", det_model="yolo26x.pt", sam_model="sam_b.pt")| Argument | Type | Default | Description |
|---|---|---|---|
data | str | required | Path to directory containing target images for annotation or segmentation. |
det_model | str | 'yolo26x.pt' | YOLO detection model path for initial object detection. |
sam_model | str | 'sam_b.pt' | SAM model path for segmentation (supports SAM, SAM 2, MobileSAM, and SAM 3 weights). |
device | str | '' | Computation device (e.g., 'cuda:0', 'cpu', or '' for automatic device detection). |
conf | float | 0.25 | YOLO detection confidence threshold for filtering weak detections. |
iou | float | 0.45 | IoU threshold for Non-Maximum Suppression to filter overlapping boxes. |
imgsz | int | 640 | Input size for resizing images (rounded up to a multiple of 32 if needed). |
max_det | int | 300 | Maximum number of detections per image for memory efficiency. |
classes | list[int] | None | List of class indices to detect (e.g., [0, 1] for person & bicycle). |
output_dir | str | None | Save directory for annotations (default: <data>_auto_annotate_labels sibling). |
The auto_annotate function takes the path to your images, with optional arguments for specifying the pretrained detection and SAM segmentation models, the device to run the models on, and the output directory for saving the annotated results.
Auto-annotation with pretrained models greatly reduces the time and effort required to create segmentation datasets, letting teams with large image collections focus on model development and evaluation rather than manual annotation.
Citations and Acknowledgments#
If you find SAM useful in your research or development work, please consider citing the paper:
@misc{kirillov2023segment,
      title={Segment Anything},
      author={Alexander Kirillov and Eric Mintun and Nikhila Ravi and Hanzi Mao and Chloe Rolland and Laura Gustafson and Tete Xiao and Spencer Whitehead and Alexander C. Berg and Wan-Yen Lo and Piotr Dollár and Ross Girshick},
      year={2023},
      eprint={2304.02643},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}
We would like to express our gratitude to Meta AI for creating and maintaining this valuable resource for the computer vision community.
FAQ#
Meta's Segment Anything Model (SAM) is an image segmentation model designed for promptable segmentation tasks. It combines image and prompt encoders with a lightweight mask decoder to generate segmentation masks from prompts such as points, boxes, or masks. Trained on the SA-1B dataset, SAM performs well zero-shot, adapting to new image distributions and tasks without prior knowledge.
You can use the Segment Anything Model (SAM) for image segmentation by running inference with various prompts such as bounding boxes or points. Here's an example using Python:
from ultralytics import SAM

# Load a model
model = SAM("sam_b.pt")

# Segment with bounding box prompt
model("ultralytics/assets/zidane.jpg", bboxes=[439, 437, 524, 709])

# Segment with points prompt
model("ultralytics/assets/zidane.jpg", points=[900, 370], labels=[1])

# Segment with multiple points prompt
model("ultralytics/assets/zidane.jpg", points=[[400, 370], [900, 370]], labels=[1, 1])

# Segment with multiple points prompt per object
model("ultralytics/assets/zidane.jpg", points=[[[400, 370], [900, 370]]], labels=[[1, 1]])

# Segment with negative points prompt.
model("ultralytics/assets/zidane.jpg", points=[[[400, 370], [900, 370]]], labels=[[1, 0]])
Alternatively, you can run inference with SAM in the command line interface (CLI):
yolo predict model=sam_b.pt source=path/to/image.jpgCompared to YOLO models, SAM variants like SAM-b, MobileSAM, and FastSAM-s are typically larger and slower but offer unique zero-shot segmentation capabilities. For example, YOLO26n-seg is 56x smaller and over 1650x faster than Meta's original SAM-b model on CPU. This makes YOLO models ideal for applications requiring rapid, lightweight, and computationally efficient segmentation, while SAM models excel in flexible, promptable, and zero-shot segmentation tasks.
Ultralytics' SAM offers an auto-annotation feature that allows generating segmentation datasets using a pretrained detection model. Here's an example in Python:
from ultralytics.data.annotator import auto_annotate

auto_annotate(data="path/to/images", det_model="yolo26x.pt", sam_model="sam_b.pt")
This function takes the path to your images and optional arguments for pretrained detection and SAM segmentation models, along with device and output directory specifications. For a complete guide, see Auto-Annotation.
SAM is trained on the SA-1B dataset, which comprises over 1 billion masks across 11 million images. SA-1B was the largest segmentation dataset at its release, providing high-quality and diverse training data that underpins SAM's zero-shot performance across segmentation tasks.