YOLOE: Real-Time Open-Vocabulary Detection and Segmentation
Ultralytics YOLOE (Real-Time Seeing Anything) is an open-vocabulary detection and instance segmentation model: instead of a class list fixed at training time, it takes the categories you want at inference time, as a text prompt, a visual example, or a built-in 4,585-name vocabulary. Built on the Ultralytics YOLO architectures — YOLOv8, YOLO11 and YOLO26 — and inspired by YOLO-World, YOLOE reaches high zero-shot accuracy at close to closed-set YOLO speed.
Watch: How to use Ultralytics YOLOE-26 (New) | Open Vocabulary & Real-Time Seeing Anything
Quick Start#
Name the classes you want and run. YOLOE-26 returns boxes and instance segmentation masks for categories it was never trained on.
from ultralytics import YOLOE

model = YOLOE("yoloe-26s-seg.pt")

# "double-decker bus" is not a COCO class; YOLOE resolves it from the words alone
model.set_classes(["double-decker bus", "person"])

results = model.predict("https://ultralytics.com/images/bus.jpg")
results[0].show()
The first set_classes() call downloads a text encoder; see Installation and Requirements before deploying to a machine without network access.
Choosing a Prompting Mode#
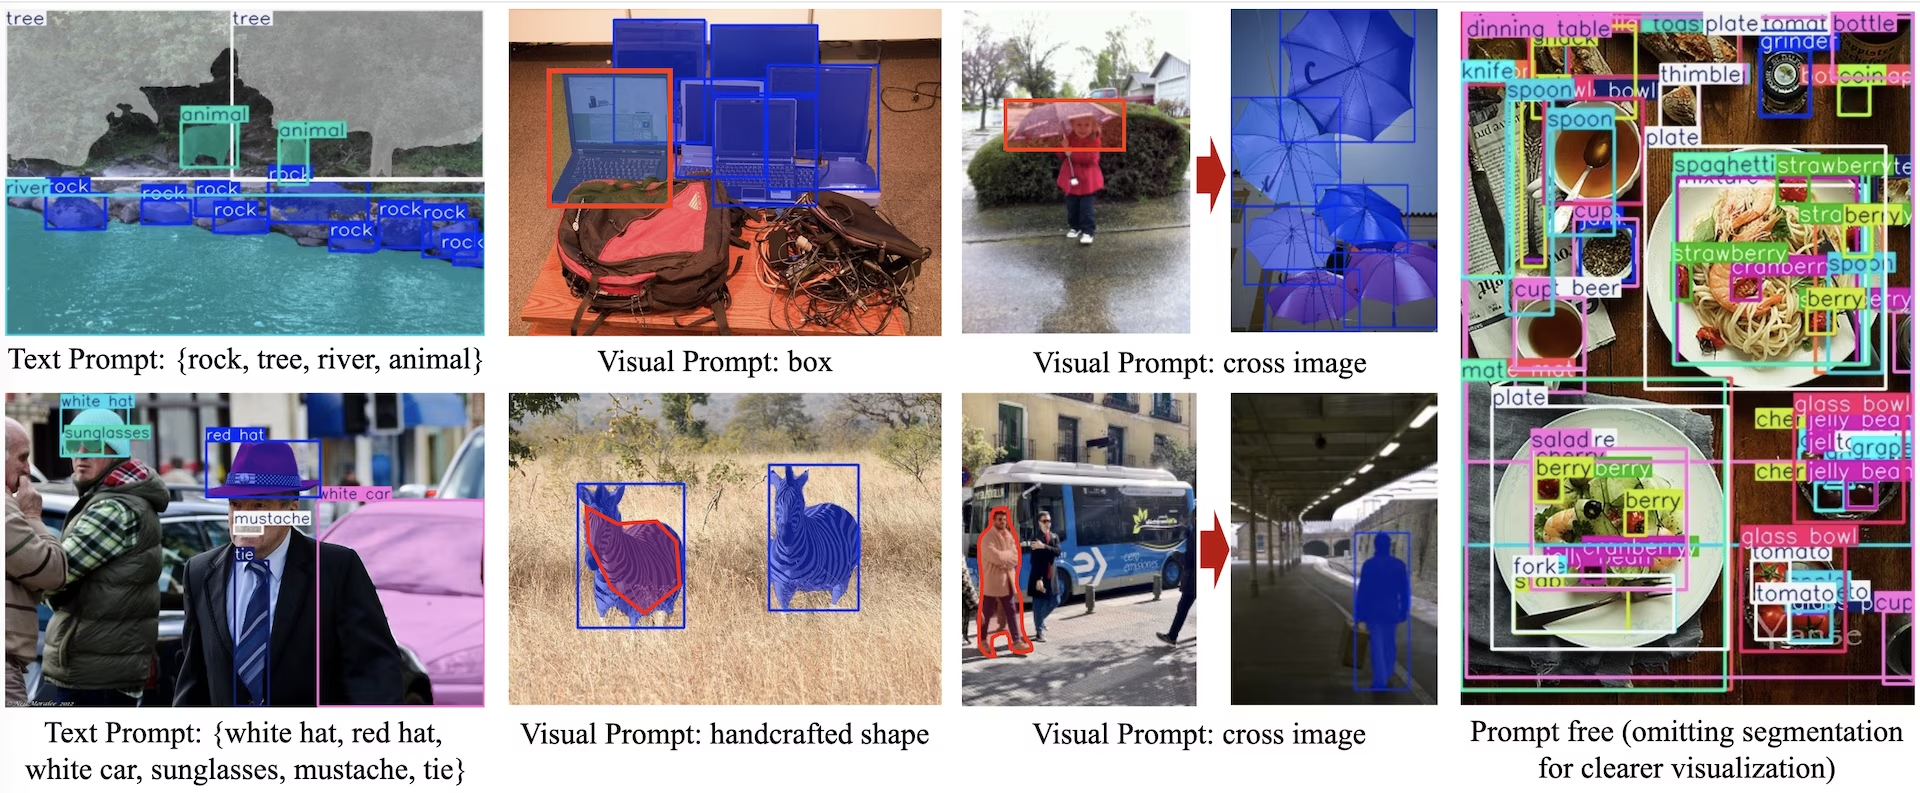
YOLOE supports three prompting modes, and the choice decides which checkpoint you load and what your class labels look like. Pick the row that matches what you can supply at inference time.
| Mode | Checkpoint | You supply | Class names in the results | Use it when |
|---|---|---|---|---|
| Text prompt | *-seg.pt | Class names as strings | Exactly the names you passed | You can describe the target in words — the usual choice |
| Visual prompt | *-seg.pt | Example boxes on a reference image | Generic object0, object1, … | You cannot put the target into words: a specific part, logo, or defect |
| Prompt-free | *-seg-pf.pt | Nothing | Names from the built-in 4,585-name vocabulary | You are cataloging or exploring and do not know what to look for in advance |
- Visual prompts do not carry your labels. The class IDs in
visual_promptsgroup examples together; the model reports them asobject0,object1, and so on. Map them back to your own names yourself. - Prompt-free checkpoints reject
set_classes(). Calling it on a*-seg-pf.ptmodel raisesAssertionError: Prompt-free model does not support setting classes. Please try with Text/Visual prompt models.Load a*-seg.ptcheckpoint instead when you need your own classes.
Installation and Requirements#
YOLOE ships in the main Ultralytics package:
pip install -U ultralyticsText prompting needs a text encoder on top of that, and it is fetched on first use rather than at install time:
- The first
set_classes()call installs ultralytics/CLIP from GitHub withpip(it provides the tokenizer) and downloads a TorchScript text encoder into the current working directory. YOLOE-26 pullsmobileclip2_b.ts, about 254 MB; YOLOE-11 and YOLOE-v8 pullmobileclip_blt.ts. Run the download once from the directory you will run from, or copy the file there, otherwise it is fetched again. - Both steps need network access, so run one prompted prediction before deploying to an offline or air-gapped machine.
- Visual prompts and prompt-free checkpoints need no text encoder at all.
The YOLOE-26 checkpoints require ultralytics 8.4.0 or newer; the YOLOE-11 and YOLOE-v8 families are available in earlier releases. One text-prompted prediction exercises the whole path — checkpoint download, CLIP install, text encoder, inference:
yolo predict model=yoloe-26s-seg.pt source="https://ultralytics.com/images/bus.jpg" classes="person"To skip the text-encoder download at inference time entirely, bake the prompts into the weights once and reuse them — see Reuse prompt embeddings.
Architecture Overview#

YOLOE keeps the standard YOLO structure — a convolutional backbone for feature extraction, a neck for multi-scale fusion, and an anchor-free, decoupled head predicting classes and boxes — and adds three modules, one per prompting mode:
- Re-parameterizable Region-Text Alignment (RepRTA) refines text embeddings from CLIP through a small auxiliary network. That network runs once per
set_classes()call and is folded away at export, so it costs nothing per frame. What does run on every forward pass is the comparison of the stored prompt embeddings against region features; see Limitations for what that costs with a large prompt set. - Semantic-Activated Visual Prompt Encoder (SAVPE) encodes semantic and activation features from an example box, conditioning the model on objects that look like it. This is the one-shot path for targets that are hard to name, such as a logo or a specific part.
- Lazy Region-Prompt Contrast (LRPC) matches region embeddings against a built-in 4,585-name vocabulary, so prompt-free checkpoints recognize objects with no external prompt and no text encoder.
Instance segmentation comes from a mask branch on the detection head, as in YOLOv8-Seg, and every prediction carries a mask on results[0].masks. Once the model is exported, the open-world modules are re-parameterized into a standard YOLO head, so the exported file runs the ordinary detect/segment path.
Available Models#
Every checkpoint below is an instance segmentation model and supports val, predict, export and track. Load a *-seg.pt file for text or visual prompting and a *-seg-pf.pt file for prompt-free inference; they are not interchangeable, see Choosing a Prompting Mode. Only the *-seg.pt files support train; a prompt-free checkpoint is produced from a trained text-prompt model, see Training the Official Models from Scratch.
| Model | Text / visual prompt | Prompt-free |
|---|---|---|
| YOLOE-26n | yoloe-26n-seg.pt | yoloe-26n-seg-pf.pt |
| YOLOE-26s | yoloe-26s-seg.pt | yoloe-26s-seg-pf.pt |
| YOLOE-26m | yoloe-26m-seg.pt | yoloe-26m-seg-pf.pt |
| YOLOE-26l | yoloe-26l-seg.pt | yoloe-26l-seg-pf.pt |
| YOLOE-26x | yoloe-26x-seg.pt | yoloe-26x-seg-pf.pt |
| YOLOE-11s | yoloe-11s-seg.pt | yoloe-11s-seg-pf.pt |
| YOLOE-11m | yoloe-11m-seg.pt | yoloe-11m-seg-pf.pt |
| YOLOE-11l | yoloe-11l-seg.pt | yoloe-11l-seg-pf.pt |
| YOLOE-v8s | yoloe-v8s-seg.pt | yoloe-v8s-seg-pf.pt |
| YOLOE-v8m | yoloe-v8m-seg.pt | yoloe-v8m-seg-pf.pt |
| YOLOE-v8l | yoloe-v8l-seg.pt | yoloe-v8l-seg-pf.pt |
YOLOE Performance on LVIS#
Zero-shot results on LVIS minival at 640 pixels, from the Ultralytics YOLO26 paper.
Text and visual prompts#
Each accuracy and parameter cell reads text prompt / visual prompt; FLOPs are given once. Parameters and FLOPs are for the detection configuration the paper evaluates. Accuracy is the paper's Non-E2E figure, the only protocol it reports for every model in the comparison; the YOLOE-26 end-to-end head trails it by at most 1.1 AP under text prompts and 2.6 AP under visual prompts.
| Model | mAP50-95 | mAPr | mAPc | mAPf | params (M) | FLOPs (B) |
|---|---|---|---|---|---|---|
| YOLOE-26n | 24.7 / 21.9 | 20.5 / 17.6 | 24.1 / 22.3 | 26.1 / 22.4 | 3.9 / 3.1 | 6.1 |
| YOLOE-26s | 30.8 / 28.6 | 23.9 / 25.1 | 29.6 / 27.8 | 33.0 / 29.9 | 10.7 / 11.0 | 21.9 |
| YOLOE-26m | 35.4 / 33.9 | 31.1 / 33.4 | 34.7 / 34.0 | 36.9 / 33.8 | 21.3 / 25.1 | 70.6 |
| YOLOE-26l | 37.8 / 36.3 | 35.1 / 37.6 | 37.6 / 36.2 | 38.5 / 36.1 | 25.5 / 29.3 | 89.0 |
| YOLOE-26x | 40.6 / 38.5 | 37.4 / 35.3 | 40.9 / 38.8 | 41.0 / 38.8 | 55.2 / 65.2 | 197.7 |
| YOLOE-11s | 27.5 / 26.3 | 21.4 / 22.5 | 26.8 / 27.1 | 29.3 / 26.4 | 10.7 / 10.9 | 22.7 |
| YOLOE-11m | 33.0 / 31.4 | 26.9 / 27.1 | 32.5 / 31.9 | 34.5 / 31.7 | 21.0 / 24.8 | 70.4 |
| YOLOE-11l | 35.2 / 33.7 | 29.1 / 28.1 | 35.0 / 34.6 | 36.5 / 33.8 | 26.0 / 29.8 | 89.5 |
| YOLOE-v8s | 27.9 / 26.2 | 22.3 / 21.3 | 27.8 / 27.7 | 29.0 / 25.7 | 12.3 / 12.6 | 29.8 |
| YOLOE-v8m | 32.6 / 31.0 | 26.9 / 27.0 | 31.9 / 31.7 | 34.4 / 31.1 | 26.4 / 28.4 | 80.7 |
| YOLOE-v8l | 35.9 / 34.2 | 33.2 / 33.2 | 34.8 / 34.6 | 37.3 / 34.1 | 43.5 / 47.3 | 167.6 |
Prompt-free#
The prompt-free checkpoints answer from their built-in vocabulary with no prompt supplied. Each accuracy cell reads end-to-end / Non-E2E, the two protocols the paper scores YOLOE-26 under; the YOLO26 page quotes the Non-E2E column.
| Model | mAP50-95 | mAPr | mAPc | mAPf | params (M) | FLOPs (B) |
|---|---|---|---|---|---|---|
| YOLOE-26n-pf | 16.6 / 17.7 | 15.7 / 15.8 | 15.3 / 16.4 | 17.9 / 19.2 | 2.3 | 5.3 |
| YOLOE-26s-pf | 21.4 / 22.6 | 16.2 / 20.2 | 20.1 / 20.9 | 23.5 / 24.5 | 9.0 | 20.8 |
| YOLOE-26m-pf | 25.7 / 26.4 | 26.7 / 24.5 | 24.0 / 25.0 | 26.9 / 27.9 | 19.4 | 68.4 |
| YOLOE-26l-pf | 27.2 / 28.0 | 26.3 / 25.7 | 25.7 / 26.8 | 28.7 / 29.5 | 23.6 | 86.8 |
| YOLOE-26x-pf | 29.9 / 31.1 | 27.5 / 28.9 | 29.1 / 30.7 | 31.1 / 31.7 | 53.1 | 194.4 |
Under text and visual prompts the YOLOE-26 models lead their YOLOE-11 and YOLOE-v8 counterparts at every matching scale on mAP50-95, while staying below the v8 line on parameters and FLOPs. On the same split the paper reports YOLO-Worldv2 at 24.4 (S), 32.4 (M) and 35.5 (L), and the transformer-based detectors GLIP-T at 26.0, GDINO-T at 27.4 and DetCLIP-T at 34.4, each carrying 155 to 232 M parameters. The original YOLOE paper adds two results for the v8-scale models it introduced. On LVIS, YOLOE-v8s beats YOLO-Worldv2-S by 3.5 AP at a third of the training cost and 1.4× the inference speed. Transferred to COCO, YOLOE-v8l gains 0.6 box AP and 0.4 mask AP over closed-set YOLOv8-L with nearly 4× less training time.
The YOLO26 paper evaluates a detection configuration. The released weights are segmentation checkpoints and carry a mask branch, SAVPE and the text projection on top, so a loaded yoloe-26l-seg.pt reports 35.4 M and 142.0 B rather than the 25.5 M and 89.0 B above. In both cases the FLOPs figure excludes the region-text similarity, so real cost grows with the size of the prompt set even though the column does not move; see Limitations.
Usage Examples#
Every YOLOE example below runs from the Python API. Text-prompt prediction, validation, export, tracking and plain training also work from the CLI; the fine-tuning recipes pass a trainer class and visual prompting passes NumPy prompt arrays, which only the Python API accepts.
Train Usage#
Fine-tune any released *-seg.pt checkpoint on your own YOLO dataset. This mostly follows the standard YOLO training procedure; the difference is which trainer you pass. YOLOEPESegTrainer fuses your class names into the head and fine-tunes from there, which is what you want on your own labels; the default trainer does not train against your class names. The resulting checkpoint predicts your dataset's classes directly: its head no longer reads prompts, so set_classes() raises an error if the classes change, and so do visual prompts. Prompt the original checkpoint for other classes.
Watch: How to Train YOLOE on Car Parts Segmentation Dataset | Open-Vocabulary Model, Prediction & Export
from ultralytics import YOLOE
from ultralytics.models.yolo.yoloe import YOLOEPESegTrainer

model = YOLOE("yoloe-26s-seg.pt")

results = model.train(
    data="coco128-seg.yaml",
    epochs=80,
    patience=10,
    trainer=YOLOEPESegTrainer,  # <- Important: the fine-tuning trainer, not the default
)Every released checkpoint is a segmentation model. To train a detector, build the model from the matching YAML, load the segmentation weights of the same scale, and swap in the detection trainer. Everything else is unchanged.
from ultralytics import YOLOE
from ultralytics.models.yolo.yoloe import YOLOEPETrainer

model = YOLOE("yoloe-26s.yaml").load("yoloe-26s-seg.pt")

results = model.train(data="coco128.yaml", epochs=80, patience=10, trainer=YOLOEPETrainer)
Predict Usage#
The text-prompt call is the one shown in Quick Start. Visual prompting adds a visual_prompts argument, and prompt-free prediction loads a -pf checkpoint instead:
Visual prompts show the model an example instead of describing one. visual_prompts takes a bboxes array of example boxes and a cls array of class IDs, one per box. The IDs are temporary groupings, not labels — they must be sequential from 0, and the results come back as object0, object1, … rather than under names you choose.
The example boxes can sit on the image you are predicting on:
import numpy as np

from ultralytics import YOLOE

model = YOLOE("yoloe-26l-seg.pt")

# One example box per target, each with its own class ID
visual_prompts = {
    "bboxes": np.array([[221.52, 405.8, 344.98, 857.54], [120, 425, 160, 445]]),  # person, glasses
    "cls": np.array([0, 1]),
}

results = model.predict(
    "ultralytics/assets/bus.jpg",
    visual_prompts=visual_prompts,
)
results[0].show()
Or on a separate reference image passed as refer_image, in which case bboxes and cls describe objects in that reference, not in the target:
import numpy as np

from ultralytics import YOLOE

model = YOLOE("yoloe-26l-seg.pt")

visual_prompts = {"bboxes": np.array([[221.52, 405.8, 344.98, 857.54]]), "cls": np.array([0])}  # person

results = model.predict(
    "ultralytics/assets/zidane.jpg",  # Target image
    refer_image="ultralytics/assets/bus.jpg",  # Where the example boxes live
    visual_prompts=visual_prompts,
)
results[0].show()

# refer_image also sets the classes permanently, so later calls need no prompts at all
results = model("ultralytics/assets/bus.jpg")
model.export(format="onnx") # And the export keeps themWhen source is a video or stream, the first frame becomes the refer_image automatically, so the prompts you pass are applied to that frame and carried through the rest of the video. Pass refer_image explicitly to choose a different frame.
Both source and refer_image accept torch tensors directly, which is useful when the images already come from an existing pipeline. Give the boxes in the tensor's own pixel coordinates:
import numpy as np
import torch

from ultralytics import YOLOE

model = YOLOE("yoloe-11l-seg.pt")

img_tensor = torch.rand(1, 3, 480, 480)  # (1, 3, H, W) float tensor in [0, 1]
visual_prompts = {"bboxes": np.array([[10, 10, 50, 50]]), "cls": np.array([0])}

results = model.predict(
    img_tensor,
    refer_image=img_tensor,
    visual_prompts=visual_prompts,
    imgsz=640,
)
To predict on several images at once, nest the prompts one level deeper: one bboxes array and one cls array per source image, in the same order as the sources.
import numpy as np

from ultralytics import YOLOE

model = YOLOE("yoloe-26l-seg.pt")

visual_prompts = {
    "bboxes": [
        np.array([[221.52, 405.8, 344.98, 857.54], [120, 425, 160, 445]]),  # bus.jpg: person, glasses
        np.array([[150, 200, 1150, 700]]),  # zidane.jpg: person
    ],
    "cls": [np.array([0, 1]), np.array([0])],
}

results = model.predict(
    ["ultralytics/assets/bus.jpg", "ultralytics/assets/zidane.jpg"],
    visual_prompts=visual_prompts,
)
results[0].show()
Val Usage#
Validation runs like any other model on a segmentation dataset:
from ultralytics import YOLOE

model = YOLOE("yoloe-26l-seg.pt")  # or yoloe-26s/m-seg.pt for other sizes

metrics = model.val(data="coco128-seg.yaml")
data can also be an NDJSON file or a Platform ul:// dataset URI; it is converted to YOLO format before the text or visual prompts are built.
Two variants of the same call cover the other prompting modes:
- Visual prompts —
model.val(data="coco128-seg.yaml", load_vp=True)extracts a visual embedding per category from the dataset itself. Addrefer_data="coco.yaml"to take the embeddings from a different dataset, which must carry exactly the same categories. - Prompt-free — load a
*-seg-pf.ptcheckpoint and passsingle_cls=True.
Export Usage#
Prompt embeddings can be saved once and reused when producing static exports such as ONNX, OpenVINO, TensorRT, CoreML, LiteRT, and RKNN. The NPZ profile is loaded by the original PyTorch model before export; it is not an additional runtime input, and the exported model does not require the NPZ file.
Classes configured with set_classes() (or via refer_image for visual prompts) are baked into the exported weights. Once exported, the model can no longer accept new prompts: calling set_classes() or passing visual_prompts=... to predict() on a loaded export will fail. To change the detected classes, re-export from the original .pt checkpoint with the new prompts configured. The exported file behaves like a standard YOLO model and can also be loaded with YOLO() instead of YOLOE().
from ultralytics import YOLOE

model = YOLOE("yoloe-26n-seg.pt")
model.set_classes(["person", "bus"])
model.save_prompt_embeddings("person-bus.npz")

# The profile is bound to the source checkpoint and can be reused for later exports.
model = YOLOE("yoloe-26n-seg.pt")
model.load_prompt_embeddings("person-bus.npz")
model.export(format="onnx")
The same prompt profile can also configure a detection-only model built from the matching YOLOE architecture. This removes the mask branch while retaining the prompted classes:
from ultralytics import YOLOE

model = YOLOE("yoloe-26n.yaml").load("yoloe-26n-seg.pt")
model.load_prompt_embeddings("person-bus.npz")
model.export(format="rknn", name="rk3588", quantize=16)
Track Usage#
Prompted classes carry straight into tracking, so you can follow objects the tracker was never trained on:
from ultralytics import YOLOE

model = YOLOE("yoloe-26s-seg.pt")
model.set_classes(["forklift", "pallet"])

# persist=True keeps track IDs stable across frames
for result in model.track("path/to/video.mp4", stream=True, persist=True):
    print(result.boxes.id)
How YOLOE Compares#
YOLOE sits between a closed-set detector and a heavyweight open-vocabulary model. Three comparisons decide whether it is the right choice:
- Against a closed-set YOLO. Once the prompts are set, YOLOE predicts through the ordinary detect/segment path and exports like any other model. What it adds is the ability to change the class list at inference time instead of retraining; what it costs is zero-shot accuracy well below a model trained on your own classes.
- Against the earlier YOLOE families. YOLOE-26 inherits YOLO26's NMS-free end-to-end head and covers five scales (n/s/m/l/x) against the earlier three (s/m/l), and leads at every matching scale in Performance.
- Against transformer-based open-vocabulary detectors. GLIP and OWL-ViT run a vision-language transformer at inference. YOLOE encodes the prompts once and then compares them against region features inside a convolutional head.
The nearest alternatives all take a text prompt, but only YOLOE and SAM 3 return masks, and the three answer different questions:
| YOLOE | SAM 3 | YOLO-World | |
|---|---|---|---|
| Built for | Real-time detection and segmentation of named classes | Concept segmentation and promptable tracking | Real-time open-vocabulary detection |
| Masks | Yes, with the *-seg.pt checkpoints | Yes | No, boxes only |
| Visual prompts | Yes (SAVPE) | Yes | No |
| Prompt-free mode | Yes, 4,585-name vocabulary | No | No |
| Pick it when | You need throughput and can name the classes | You need the strongest concept segmentation and can spend the compute | You are already on it — see the migration note below |
Coming from YOLO-World? The API is the same shape: swap YOLOWorld for YOLOE, load a *-seg.pt checkpoint, and keep your set_classes() call as it is. You gain masks and visual prompts; the export note about frozen classes applies to both.
Use Cases and Applications#
Open-vocabulary detection removes the retrain-per-class step, which matters most where the target list is not known up front:
- Open-world detection — robotics and security systems that meet objects nobody enumerated at training time.
- One-shot detection from an example — visual prompts pick up a specific part, logo or defect from a single reference box, useful in industrial inspection.
- Long-tail cataloging — the built-in 4,585-name vocabulary is broad enough for biodiversity monitoring or retail inventory sweeps.
- Dataset bootstrapping — pre-label images with boxes and masks before human review, then train a fast closed-set model on the result.
- Segmentation of arbitrary targets — the released
*-seg.ptcheckpoints return a mask with every prediction, so medical imaging and satellite analysis get pixel-precise output without a second model.
A common pattern combines two modes: run prompt-free once to discover what is present, then switch to text prompts for the categories that matter.
Limitations#
YOLOE trades accuracy for the ability to change classes at inference time. The consequences worth knowing before you commit:
- Zero-shot accuracy is well below a model trained on your classes. The prompted checkpoints land roughly in the 22-40 mAP band on LVIS minival; a closed-set YOLO trained on your own data will beat that on those classes. Reach for YOLOE to cover classes you cannot train for, not to replace training.
- Rare categories are the weak spot. The mAPr column in Performance reports accuracy on LVIS's rare classes specifically, and under text prompting it sits below the common and frequent columns in every row. Check it rather than the headline mAP when your targets are unusual.
- A prompt describes appearance, not relationships. Detection works by comparing region features against the prompt embedding, so prompts that depend on state, context or comparison — "damaged", "left-most", "the one being carried" — have no reliable handle to match on. Prefer wording close to everyday category names.
- Large prompt sets cost latency. The prompt embeddings are computed once, but they are compared against region features on every forward pass. Measured on CPU with
yoloe-26s-seg.pt, a forward pass grows about 19% going from 80 to 1,203 classes and about 89% at the full 4,585-name vocabulary. Reported FLOPs do not move at all, because the region-text similarity is not counted, so the profile will not warn you. - Class names are placeholders until you prompt. A freshly loaded
*-seg.ptcheckpoint reportsnc=80with numeric names ("0","1", …), so callset_classes()before reading labels. Prompt-free checkpoints ship the full vocabulary already populated.
Deployment Notes#
- Hardware. Inference needs an NVIDIA GPU with 4-8 GB of VRAM; the
nandsscales run on edge GPUs such as Jetson or on CPU at reduced resolution. Fine-tuning needs a single GPU. - NMS is class-agnostic by default. YOLOE predicts with
agnostic_nms=True. By default this suppresses lower-scoring overlapping boxes across different classes rather than only within the same class, which prevents duplicates when one object matches several categories. Withnms=False, YOLOE-26 applies no IoU suppression; agnostic mode only keeps the single best class per anchor instead of letting one anchor emit several class labels. Passagnostic_nms=Falseto override. - Visual prompts default to
conf=0.05. Visual-prompt boxes are correct more often than their scores suggest: on LVIS minival, with one instance of a class as the prompt,conf=0.25misses 44 to 55% of the other instances that YOLOE-26 finds atconf=0.05. Dense scenes of near-identical objects, such as retail shelves or cells, can need lower values, and withnms=Falsethe YOLOE-26 one-to-one head scores lower still, with its best threshold near0.01. Every other call keepsconf=0.25, including later calls, saved embeddings and exports that reuse classes set byrefer_image. Passconfto override. - Batching. Batch inference works directly, and visual prompts can differ per image in the same call.
Training the Official Models from Scratch#
Most readers never need this. It reproduces the published open-vocabulary checkpoints from Objects365, GQA and Flickr30k — about 1.4 M training samples on 8× RTX 4090 — and is unrelated to fine-tuning on your own data, which is covered under Train Usage above.
Every trainer that inherits YOLOETrainer refuses compile=True, including the default YOLOESegTrainer and all the from-scratch trainers below. Pass compile=False (the default). The two fine-tuning trainers used above, YOLOEPESegTrainer and YOLOEPETrainer, do not carry that restriction.
Training needs segment annotations. Either download the processed files below, or generate your own with the script provided by the official team, which is powered by SAM 2.1. Validation uses LVIS minival.
| Dataset | Type | Samples | Boxes | Processed segment annotations |
|---|---|---|---|---|
| Objects365v1 | Detection | 609k | 9621k | objects365_train_segm.json |
| GQA | Grounding | 621k | 3681k | final_mixed_train_no_coco_segm.json |
| Flickr30k | Grounding | 149k | 641k | final_flickr_separateGT_train_segm.json |
The text-prompt model is trained first, and the other two prompting modes are refinements of it:
from ultralytics import YOLOE
from ultralytics.models.yolo.yoloe import YOLOESegTrainerFromScratch

data = {
    "train": {
        "yolo_data": ["Objects365.yaml"],
        "grounding_data": [
            {
                "img_path": "flickr/full_images/",
                "json_file": "flickr/annotations/final_flickr_separateGT_train_segm.json",
            },
            {
                "img_path": "mixed_grounding/gqa/images",
                "json_file": "mixed_grounding/annotations/final_mixed_train_no_coco_segm.json",
            },
        ],
    },
    "val": {"yolo_data": ["lvis.yaml"]},
}

model = YOLOE("yoloe-26l-seg.yaml")
model.train(
    data=data,  # or the path to a YAML file holding the same structure
    batch=128,
    epochs=30,
    close_mosaic=2,
    optimizer="AdamW",
    lr0=2e-3,
    warmup_bias_lr=0.0,
    weight_decay=0.025,
    momentum=0.9,
    workers=4,
    trainer=YOLOESegTrainerFromScratch,
    device="0,1,2,3,4,5,6,7",
)
The visual-prompt and prompt-free checkpoints start from that trained text-prompt model and update one module each. YOLOESegVPTrainer is the visual-prompt recipe and YOLOEPEFreeTrainer the prompt-free one, but neither class freezes anything by itself: the selective training comes from the freeze list you pass alongside it, which names every head child except savpe (resp. every classification tower), and the prompt-free run additionally needs single_cls=True. The upstream YOLOE repository carries the full recipes for the v8-scale models.
A finished prompt-free run is re-parameterized into a checkpoint that reports its names with no prompt at inference, using get_vocab and set_vocab:
from ultralytics import YOLOE

# Weights written by the prompt-free run and by the text-prompt run it started from. Each
# rerun creates a new directory (train-2, train-3, ...), so take the paths the runs printed.
model = YOLOE("runs/segment/train-2/weights/best.pt")  # prompt-free run, its head is already fused
text_model = YOLOE("runs/segment/train/weights/best.pt")  # text-prompt run, its head is still unfused

names = list(YOLOE("yoloe-26l-seg-pf.pt").model.names.values())  # the 4,585-name vocabulary, or your own list
vocab = text_model.get_vocab(names)

model.set_vocab(vocab, names)
model.save("yoloe-26l-seg-pf-custom.pt")  # never overwrite the released checkpoint
get_vocab returns the branch that the model's end2end flag selects, and set_vocab re-parameterizes that one branch. The released YOLOE-26 files instead carry a vocabulary per branch, which is what keeps nms selecting between them; reproduce that by taking the second vocabulary from another copy of the text-prompt model. YOLOE-11 and YOLOE-v8 have a single branch, so they take the call above unchanged.
one2one_model = YOLOE("runs/segment/train/weights/best.pt")  # get_vocab fuses the head it reads, so load a second copy
one2one_model.model.end2end = True  # read the NMS-free branch

model.set_vocab(vocab, names, one2one_vocab=one2one_model.get_vocab(names))
Citations and Acknowledgments#
If YOLOE has contributed to your research or project, please cite the original paper by Ao Wang, Lihao Liu, Hui Chen, Zijia Lin, Jungong Han, and Guiguang Ding from Tsinghua University:
@misc{wang2025yoloerealtimeseeing,
      title={YOLOE: Real-Time Seeing Anything},
      author={Ao Wang and Lihao Liu and Hui Chen and Zijia Lin and Jungong Han and Guiguang Ding},
      year={2025},
      eprint={2503.07465},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2503.07465},
}
For further reading, the original YOLOE paper is available on arXiv. The project's source code and additional resources can be accessed via their GitHub repository.
FAQ#
Ultralytics YOLOE adds two capabilities YOLO-World does not have: visual prompts, where an example box replaces the class name, and prompt-free checkpoints that answer from a built-in 4,585-name vocabulary with no prompt at all. Every prediction from the released
*-seg.ptcheckpoints also carries an instance segmentation mask. On accuracy, the original YOLOE paper puts YOLOE-v8s ahead of YOLO-Worldv2-S by 3.5 AP on LVIS, at a third of the training cost and 1.4× the inference speed. Migrating is a one-line change — see How YOLOE Compares.Ultralytics YOLOE supports three prompting modes. A text prompt is class names as strings on a
*-seg.ptcheckpoint, and is the usual choice. A visual prompt is one or more example boxes on a reference image, for targets that are hard to put into words. Prompt-free inference uses a separate*-seg-pf.ptcheckpoint that answers from a built-in 4,585-name vocabulary with nothing supplied. Text and visual prompts share the same checkpoints; prompt-free ones are different files and rejectset_classes(). See Choosing a Prompting Mode for the full comparison.Start with
yoloe-26s-seg.pt: the YOLOE-26 family leads YOLOE-11 and YOLOE-v8 at every matching scale, and thesscale is the smallest one above 30 mAP on LVIS minival. Move up tom,lorxwhen accuracy on rare categories matters more than latency — the mAPr column in Performance is the one to compare. Drop tononly for edge deployment. Load the*-seg-pf.ptfile of the same scale instead when you want the built-in vocabulary rather than your own class names.Labels like
object0andobject1mean the prediction came from a visual prompt, which groups the example boxes into temporary numbered classes instead of carrying your names. The class IDs you pass invisual_prompts["cls"]only do that grouping. The model reports them asobject0,object1, and so on, in the order of the IDs you assigned, so map them back to your own labels on the result. If you want your names in the output, use a text prompt instead.Prompt-free checkpoints (
*-seg-pf.pt) resolve classes through their own built-in vocabulary and rejectset_classes()withAssertionError: Prompt-free model does not support setting classes. Please try with Text/Visual prompt models.Visual prompts raiseAssertionError: Visual prompts need an unfused YOLOE model.Load a*-seg.ptcheckpoint when you need your own class list. See Choosing a Prompting Mode.The first text prompt makes Ultralytics YOLOE install ultralytics/CLIP from GitHub with
pipand download a TorchScript text encoder into the current working directory — about 254 MB for YOLOE-26; see Installation and Requirements for the exact asset per model family. Visual prompts and prompt-free checkpoints need neither. To avoid the download on the target machine, set the prompts once and save them withsave_prompt_embeddings(), or export the model with the classes already configured.No — YOLOE bakes the prompted classes into the weights at export time, so a loaded export rejects both
set_classes()andvisual_prompts=. Re-export from the original.ptcheckpoint with the new prompts configured. The exported file behaves like a standard YOLO model and can be loaded withYOLO()as well asYOLOE().Use YOLOE when you need real-time throughput and can name the classes, and SAM 3 when segmentation quality on a concept matters more than speed. Both accept visual examples; only YOLOE has a prompt-free mode. The full comparison is in How YOLOE Compares.


Comments60
Ask a question, share your results, or help someone else.
daiyangyang945
I converted YOLOE to ONNX, but it only supports single-image input. How can I implement visual prompts?
1cyt1990cyt1990-dev
你好,请问怎么利用yoloe的视觉提示(结合SAM)功能进行自动标注(auto_annotate)?
 Glenn JocherUltralytics
你好,目前 YOLOE 的视觉提示能力是通过
model.predict(..., visual_prompts=..., refer_image=..., predictor=YOLOEVPSegPredictor)使用的,文档里还没有auto_annotate()直接接入这套流程的现成示例;另外yoloe-26*-seg.pt本身就会输出分割掩码,所以这类自动标注场景通常不需要再额外叠加 SAM,你可以先按 YOLOE 文档 和YOLOE.predict()参考 跑出提示式分割结果再保存为标签;如果你愿意,也欢迎把你的目标流程和样例数据贴在这个讨论里,方便团队一起看。
zhangxiancai
你好,请问yoloe如何使用多张图片里的视觉对象作为参考进行推理。因为一张图片不能全面反映要检测对象的特征,容易漏检。
 User
我也有想过建立一个供yoloe提取多角度多图片特征的小型数据库,但是发现效果并不好。官方通道似乎不支持多特征融合成一个标签。
q9card
Hello, I would like to ask about training YOLOE with a custom grounding dataset.
My current goal is to use YOLOE for open-vocabulary detection on remote-sensing small objects, and I am trying to integrate my own dataset, AI-TOD-v2, into the open-text / grounding training pipeline.
So far, I have completed the following steps:
- Converted AI-TOD-v2 from standard COCO detection annotations into a grounding-style JSON added caption for each image added tokens_positive for each instance
- Successfully ran generate_grounding_cache.py so the custom grounding JSON / cache generation itself seems to work
However, when I try to continue with the official open-text / from-scratch training pipeline, I run into many issues, for example:
(1)hard-coded checks in GroundingDataset.verify_labels() for official dataset names / instance counts (2)mismatch between yolo_data and grounding_data text slot / tensor shapes (3)later shape mismatch again in training loss / bbox decode
So I would like to ask:
Has anyone successfully trained YOLOE open-text / text-prompt models with a custom grounding dataset (not only the official Flickr/GQA/Objects365 data)? If yes, is there any recommended dataset organization or minimal working setup? Does the official pipeline currently support mixing custom grounding data with official grounding datasets such as Flickr/GQA? For a case like mine, would you recommend: continuing to adapt the current from-scratch training pipeline, or switching to another route based on official pretrained weights? If possible, could you share a minimal working example for training with a custom grounding dataset, even a very small toy example?
My current impression is that the main difficulty may not be the grounding JSON / cache generation itself, but rather that the current training code has strong assumptions about the official data pipeline. If there is any official recommendation or similar community experience, I would really appreciate it.
Thank you very much!
- Glenn JocherUltralytics
Thanks for the detailed report — the current public YOLOE from-scratch open-text pipeline is mainly validated around the official
Objects365/Flickr/GQArecipe shown in the YOLOE training docs, so a fully custom grounding dataset is not yet a documented plug-and-play path; for AI-TOD-v2, the safer route is usually to start from pretrainedyoloe-26*-seg.ptweights and the supported fine-tuning flow in the YOLOE usage docs rather than continuing from scratch. Please open a new issue with a minimal reproducible example, full traceback,yolo checks, and a tiny sample of the grounding JSON/cache so the team can check the dataset verification and shape assumptions directly. 我按照你说的用yoloe-s26-seg.pt进行微调,出现AttributeError: Can't get attribute 'YOLOESegment26' on <module 'ultralytics.nn.modules.head' from '/mnt/workspace/projects/yoloe/ultralytics/nn/modules/head.py'>错误,改用最新版 pip 安装的 Ultralytics 再试仍然存在这个问题。 目前我的yolo check输出如下: OS Linux-5.10.134-18.0.9.lifsea8.x86_64-x86_64-with-glibc2.35 Environment Linux Python 3.10.19 Install pip Path /root/miniconda3/envs/yoloe/lib/python3.10/site-packages/ultralytics RAM 31.34 GB Disk 94.8/97.9 GB CPU Intel Xeon Platinum 8163 CPU @ 2.50GHz CPU count 8 GPU Tesla V100-SXM2-16GB, 16144MiB GPU count 1 CUDA 12.8
numpy ✅ 2.2.6>=1.23.0 matplotlib ✅ 3.10.8>=3.3.0 opencv-python ✅ 4.13.0.92>=4.6.0 pillow ✅ 12.1.1>=7.1.2 pyyaml ✅ 6.0.3>=5.3.1 requests ✅ 2.32.5>=2.23.0 scipy ✅ 1.15.3>=1.4.1 torch ✅ 2.10.0>=1.8.0 torch ✅ 2.10.0!=2.4.0,>=1.8.0; sys_platform == "win32" torchvision ✅ 0.25.0>=0.9.0 psutil ✅ 7.2.2>=5.8.0 polars ✅ 1.39.3>=0.20.0 ultralytics-thop ✅ 2.0.18>=2.0.18
- Glenn JocherUltralytics
这个报错基本就是“权重版本和实际导入的代码版本不一致”:
yolo checks显示你用的是site-packages,但异常却来自/mnt/workspace/projects/yoloe/ultralytics/...,说明本地仓库覆盖了 pip 安装;而YOLOESegment26在当前head.py文档里是存在的,所以请先移除或重命名该本地ultralytics目录并重启 Python/Notebook 会话,确认ultralytics.__file__指向同一环境后再试;如果还报错,请贴完整 traceback 和精确训练命令。
- User
视觉提示只能支持一种类型吗,当我使用视觉提示进行检测之后,再次设置新的类别就会出现shape '[1, 66, -1]' is invalid for input of size 416000
- Glenn JocherUltralytics
视觉提示不只支持一种类别,
visual_prompts里可以给多组bboxes/cls(要求cls从0..N-1连续且与框数量一致),细节见中文 YOLOE 文档;你这个shape '[1, 66, -1]' is invalid...通常是跑过视觉提示(尤其用过refer_image)后又set_classes()切新类别导致旧的 prompt/embedding 状态残留,建议直接重新初始化一个新YOLOE(...)实例(Notebook 里也请重启 kernel)再设置新类别/新视觉提示。若仍复现,请把最小可复现代码、完整 traceback(文本)以及yolo checks输出贴在这里我们才能定位。 - User
好的,问题可以解决。不过衍生出相机模式下,反复创建销毁yoloe()实例,同时相机推理的帧率也很低。我会继续进行优化
- User
感谢,已经将初始化逻辑改成文本/视觉提示发送改变时触发,同时开启GPU加速,问题基本解决,再次感谢答疑
- Glenn JocherUltralytics
很好,感谢你回报进展;相机/视频场景下建议始终复用同一个
YOLOE实例,只在提示词变化时才更新set_classes()或visual_prompts,且注意传了visual_prompts时视频/流会自动用第一帧作为refer_image(详见 中文 YOLOE 文档),这样能避免反复构建带来的卡顿并提升 FPS。from ultralytics import YOLOE model = YOLOE("yoloe-26s-seg.pt") # 可按需求换更小尺度提升速度 # 仅在提示变化时调用:model.set_classes(...) 或传 visual_prompts for r in model.predict(source=0, stream=True, device=0, half=True, imgsz=640): pass # 在这里处理 r(不要每帧重新初始化模型) - User
在使用yoloe-26模型时出现模型加载错误Can't get attribute 'YOLOESegment26' on <module 'ultralytics.nn.modules.head' from 'd:\YOLO E\yoloe-main\ultralytics\nn\modules\head.py' YOLOE的库有进行开源更新吗
- Glenn JocherUltralytics
这个报错基本就是“权重文件里引用的模块/类名”和你当前导入的本地
ultralytics代码不一致导致的;从路径看你现在加载的是d:\YOLO E\yoloe-main\ultralytics\...这份源码,它不包含权重所需的YOLOESegment26,建议先排除本地目录把包“遮住”了的情况,改用最新版pip安装的 Ultralytics 再试(用法见中文 YOLOE 文档)。pip uninstall -y ultralytics pip install -U ultralytics yolo checks如果仍复现,请把“完整 traceback(文本)”、你是如何加载模型的最小代码(例如
YOLOE("yoloe-26s-seg.pt")/YOLO("yoloe-26s-seg.pt"))、以及上面yolo checks的输出贴出来;如果你刚升级过包且在 Notebook 里运行,也请先重启 kernel 再测。
qbig
Hello,
Can I ask why the exported Core ML model doesn't have labels metadata like normal YOLO or even exported YOLO-World models?
from ultralytics import YOLOE, YOLO from pathlib import Path from ultralytics.utils import YAML model_name = "yoloe-11m-seg.pt" file_name = "lvis.yaml" model = YOLOE(model_name) model.eval() # Please replace names with yours data = YAML.load(file_name) names = [n.split('/')[0] for n in data["names"].values()] model.set_classes(names, model.get_text_pe(names)) coreml_path = model.export(format='coreml', half=True, nms=False)- Glenn JocherUltralytics
That’s expected right now: YOLOE’s classes are prompt-defined (and can be changed via
set_classes()), so the CoreML exporter doesn’t reliably embed a fixed label list in the model metadata—especially when exporting “raw” outputs withnms=False; if you need labels inside the.mlmodel/.mlpackage, either export withnms=Trueor post-edit the CoreML package metadata after export (see the YOLOE export notes and theYOLOEAPI).
gstrat88
Is there any example to use it as a zero-shot logo detection?
tomer196
Hi, Is there a way to get the embeddings of each detection when I use model.predict? Similar to the way I can get the embeddings of the visual and text prompts.
ratom
I want to perform semantic segmentation with 6 classes (multi-class semantic segmentation task) using YOLOv8, YOLOv11, and YOLOe. My questions are is this possible with existing YOLO models? If yes, how can I create the data for YOLO format? I have the segmentation data with images in one folder and their respective masks in another format. @glenn-jocher
Hi @glenn-jocher, I want to perform semantic segmentation with 6 classes (multi-class semantic segmentation task) using YOLOv8, YOLOv11, and YOLOe. My questions are is this possible with existing YOLO models? If yes, how can I create the data for YOLO format? I have the segmentation data with images in one folder and their respective masks in another format.
- Glenn JocherUltralytics(edited)
@tomer196 Fine-tuning and open-vocabulary prompting are mutually exclusive in the current implementation: after fine-tuning with
YOLOEPESegTrainer, the checkpoint predicts your dataset’s classes directly andset_classes()raises an error, so keep the original checkpoint for prompting. Details are under Train Usage in the YOLOE docs; we can’t share timelines for other changes.@ram-from-tvl For production use you’ll need to choose between AGPL-3.0 compliance (open‑source your entire derivative) or an Enterprise License for proprietary deployment; see options and terms at the Ultralytics License page. For deployment hardening, benchmark and export to your target runtime (ONNX/TensorRT/CoreML/etc.) per the Export section in the YOLOE docs.
@ram-from-tvl To convert a UNet-style binary mask dataset to YOLO segmentation format, create one TXT per image with polygon coordinates per instance (normalized x,y). Format and examples are in the Segmentation task data format. Minimal conversion example for a single-class binary mask:
import cv2, numpy as np, os

def mask_to_yolo_segments(mask):
    h, w = mask.shape[:2]
    contours, _ = cv2.findContours(mask, cv2.RETR_EXTERNAL, cv2.CHAIN_APPROX_SIMPLE)
    segs = []
    for c in contours:
        if len(c) < 3:
            continue
        pts = c.squeeze(1).astype(float)
        pts[:, 0] /= w
        pts[:, 1] /= h
        segs.append(pts.reshape(-1))
    return segs

mask = cv2.imread("mask.png", 0) > 0
segs = mask_to_yolo_segments(mask.astype(np.uint8))
os.makedirs("labels", exist_ok=True)
with open("labels/image.txt", "w") as f:
    for seg in segs:
        f.write("0 " + " ".join(f"{v:.6f}" for v in seg.tolist()) + "\n")
@Swetha4545 YOLOE isn’t limited to 80 classes—text prompts are open‑vocab, and the prompt‑free variants use a large vocabulary; for harder concepts like “cotton” try synonyms (e.g., “cotton plant”, “cotton bale”, “fabric”) or switch to visual prompts with a clear reference exemplar; see Text/Visual/Prompt‑free usage in the YOLOE docs and the predictor API for visual prompts: YOLOEVPSegPredictor.
@ratom For per-pixel class maps (semantic segmentation), YOLO26 provides dedicated
-semmodels such asyolo26n-sem.pt(task=semantic); see the Semantic Segmentation docs. YOLOv8/YOLO11/YOLOE are instance segmentation models: if you use them, convert your masks to per‑instance polygons and save in YOLO segmentation TXT format (one line per instance:cls x1 y1 x2 y2 ..., normalized); the expected structure and examples are in the Segmentation task data format.
beichen2012
May I ask how to replace the YOLO11 backbone with DINOV3 distilled? Thanks.
- Glenn JocherUltralytics(edited)
@daiyangyang945 ONNX runtime doesn’t support passing visual prompts at inference; bake them before export by running one PyTorch pass with
refer_image(which fixes classes), then export the fused model; this preserves the same classes in ONNX and you can still use dynamic batch input: see Visual Prompting and Export sections in the YOLOE docs for details. Example:from ultralytics import YOLOE from ultralytics.models.yolo.yoloe import YOLOEVPSegPredictor m = YOLOE("yoloe-11l-seg.pt") visual_prompts = {"bboxes": ..., "cls": ...} # your examples m.predict("img.jpg", refer_image="ref.jpg", visual_prompts=visual_prompts, predictor=YOLOEVPSegPredictor) m.export(format="onnx", dynamic=True, simplify=True)For guidance see the YOLOE page under Predict and Export usage. Refer: YOLOE: Real‑Time Seeing Anything, YOLOEVPSegPredictor API.
@Chappie123 With bbox-only data, convert to YOLO detection TXT labels and train a detection model. Convert each box from
{minx,miny,maxx,maxy}to normalizedxc,yc,w,h:def to_yolo(minx, miny, maxx, maxy, W, H): xc = (minx + maxx) / 2 / W yc = (miny + maxy) / 2 / H w = (maxx - minx) / W h = (maxy - miny) / H return xc, yc, w, hDataset YAML (minimal):
path: /data/myset
train: images/train
val: images/val
names: {0: class0, 1: class1}
Train:
from ultralytics import YOLOE
model = YOLOE("yoloe-11s.yaml")
model.train(data="data.yaml", epochs=100, imgsz=640)
More in Train mode and Detection task.
@HLHSM The error is from installing the wrong
clippackage. Uninstall the PyPIclipand install the official CLIP (per its README), or use a compatible wheel likeclip-anytorch, then restart Python:pip uninstall -y clip pip install clip-anytorchIf it persists, please run
yolo checksand paste the full text output. Reference for the APIs you’re calling: YOLOE API reference.@Maya7991 Current ONNX exports accept a single
imagesinput; runtime text/visual prompts aren’t exposed as additional ONNX inputs. Use offline prompts: set and fuse classes before export, or use the prompt‑free path.from ultralytics import YOLOE m = YOLOE("yoloe-11s-seg.pt") names = ["person", "bus"] m.set_classes(names, m.get_text_pe(names)) # fuse prompts m.export(format="onnx", dynamic=True, simplify=True)With
dynamic=True, you can pass[N,3,H,W]batches in onnxruntime even though the input name is justimages. See Export mode and YOLOE Export examples on the docs page: YOLOE docs.@beichen2012 Swapping YOLO11’s CNN backbone for a DINOv3‑distilled ViT isn’t supported and would require a custom backbone module plus shape/plumbing changes; we recommend using YOLO26 as‑is or a transformer model like RT‑DETR. If you prototype this, please keep any PR minimal, well‑tested, and scoped to the new backbone only.