مجموعة بيانات xView#
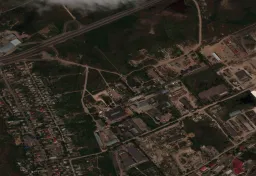
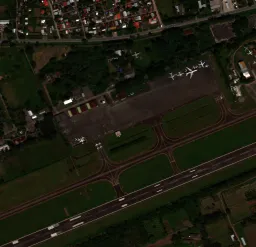
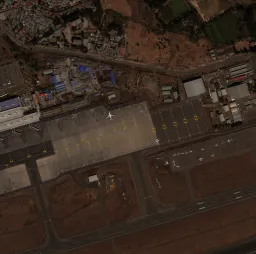
مجموعة بيانات xView أحد أكبر معايير الصور الساتلية المتاحة علنًا في مجال اكتشاف الكائنات، إذ توفر أكثر من مليون كائن ضمن 60 فئة، موسومة بـصناديق إحاطة عبر أكثر من 1,400 كم² من صور WorldView-3 بدقة 0.3 m. أصدرتها الوكالة الوطنية للاستخبارات الجغرافية المكانية الأمريكية (NGA) لمسابقة DIUx xView لعام 2018، ويتطلب تنزيلها يدويًا نحو 20.7 GB.
أُنشئت مجموعة البيانات لدفع أربعة من حدود الرؤية الحاسوبية إلى الأمام:
- خفض الحد الأدنى للدقة اللازمة للاكتشاف.
- تحسين كفاءة التعلّم.
- إتاحة اكتشاف مزيد من فئات الكائنات.
- تحسين اكتشاف الفئات الدقيقة.
انطلاقًا من معايير مثل COCO، تستهدف xView الصور الملتقطة من الأعلى، حيث تكون الكائنات أصغر بكثير وأكثر ازدحامًا مقارنةً بالصور الملتقطة من مستوى الأرض.
لا تُنزّل مجموعة بيانات xView تلقائيًا. سجّل في موقع تحدي DIUx xView لعام 2018 لتنزيل train_images.zip (~15 GB) وtrain_labels.zip وval_images.zip (~5 GB)، ثم فك ضغطها ضمن datasets/xView/ بحيث يحتوي على:
datasets/xView/
├── train_images/          # 847 TIF satellite images
├── val_images/            # 282 TIF images (no public labels)
└── xView_train.geojson    # bounding-box annotations
في أول تشغيل للتدريب، تحوّل Ultralytics التعليقات التوضيحية بتنسيق GeoJSON إلى تنسيق YOLO، وتقسم الصور الموسومة تلقائيًا إلى مجموعتي تدريب وتحقق بنسبة تقارب 90/10 — ولا حاجة إلى تحويل يدوي.
الميزات الرئيسية#
- الفئات الدقيقة: 60 فئة من الكائنات تشمل الطائرات والمركبات ومعدات السكك الحديدية والسفن البحرية ومعدات البناء والمباني — وكثير منها صغير ونادر ومتقارب بصريًا.
- دقة عالية: تبلغ دقة العينة الأرضية 0.3 m، وجُمعت الصور من أقمار WorldView-3 الصناعية.
- تعليقات توضيحية كثيفة: أكثر من مليون مثيل لكائنات ضمن أكثر من 1,400 km² من الصور، وكلها موسومة بمربعات إحاطة أفقية.
- تحويل تلقائي: يحوّل برنامج التنزيل في Ultralytics تسميات GeoJSON الأصلية إلى تنسيق YOLO، وينشئ تقسيم التدريب/التحقق عند الاستخدام الأول.
بنية مجموعة البيانات#
صور xView مشاهد أقمار صناعية كبيرة بتنسيق TIF، ولا تأتي إلا صور التدريب البالغ عددها 847 مع تسميات متاحة للعامة — أما مجموعة التحقق الخاصة بالتحدي، التي تضم 282 صورة، فلا تحتوي على تسميات. لذلك يقسم إعداد xView.yaml من Ultralytics الصور الموسومة تلقائيًا عند الاستخدام الأول:
| المجموعة الفرعية | الصور | الوصف |
|---|---|---|
| التدريب | ~90% من 847 | الصور الموسومة المدرجة في autosplit_train.txt، والتي تُنشأ عند التشغيل الأول |
| التحقق | ~10% من 847 | الصور الموسومة المدرجة في autosplit_val.txt، والمستخدمة في التقييم |
تشمل الفئات الستون تصنيفات دقيقة مثل الطائرات ثابتة الجناحين وطائرات الشحن والسيارات الصغيرة والحافلات والقاطرات والسفن البحرية والحفارات والمباني وحظائر الطائرات وخزانات التخزين؛ وترد القائمة الكاملة في ملف YAML لمجموعة البيانات أدناه. أثناء التحويل، تُعاد فهرسة معرّفات الفئات الأصلية في التحدي (11–94) لتصبح مؤشرات متصلة من 0 إلى 59.
التطبيقات#
تجعل الفئات الدقيقة في xView والمنظور عالي الدقة الملتقط من الأعلى منها معيارًا شائعًا لتدريب نماذج التعلّم العميق وتقييمها في الاستشعار عن بُعد. وتشمل التطبيقات الشائعة:
- الاستطلاع العسكري والدفاعي
- التخطيط الحضري والتطوير
- الرصد البيئي
- الاستجابة للكوارث وتقييمها
- رسم خرائط البنية التحتية وإدارتها
للاطلاع على معايير أخرى للصور الملتقطة من الأعلى، راجع مجموعة بيانات VisDrone المخصصة للطائرات المسيّرة أو مجموعة بيانات DOTA-v2 ذات المربعات الموجّهة.
ملف YAML لمجموعة البيانات#
يحدد الملف xView.yaml إعدادات مجموعة البيانات — مسارات مجموعة البيانات وأسماء الفئات الستين والبرنامج النصي للتنزيل الذي يحوّل التعليقات التوضيحية بتنسيق GeoJSON وينشئ التقسيم التلقائي. ويُصان الملف في مستودع Ultralytics على https://github.com/ultralytics/ultralytics/blob/main/ultralytics/cfg/datasets/xView.yaml.
# Ultralytics 🚀 AGPL-3.0 License - https://ultralytics.com/license

# DIUx xView 2018 Challenge dataset https://challenge.xviewdataset.org by U.S. National Geospatial-Intelligence Agency (NGA)
# --------  Download and extract data manually to `datasets/xView` before running the train command.  --------
# Documentation: https://docs.ultralytics.com/datasets/detect/xview
# Example usage: yolo train data=xView.yaml
# parent
# ├── ultralytics
# └── datasets
#     └── xView ← downloads here (20.7 GB)

# Train/val/test sets as 1) dir: path/to/imgs, 2) file: path/to/imgs.txt, or 3) list: [path/to/imgs1, path/to/imgs2, ..]
path: xView # dataset root dir
train: images/autosplit_train.txt # train images (relative to 'path') 90% of 847 train images
val: images/autosplit_val.txt # val images (relative to 'path') 10% of 847 train images

# Classes
names:
  0: Fixed-wing Aircraft
  1: Small Aircraft
  2: Cargo Plane
  3: Helicopter
  4: Passenger Vehicle
  5: Small Car
  6: Bus
  7: Pickup Truck
  8: Utility Truck
  9: Truck
  10: Cargo Truck
  11: Truck w/Box
  12: Truck Tractor
  13: Trailer
  14: Truck w/Flatbed
  15: Truck w/Liquid
  16: Crane Truck
  17: Railway Vehicle
  18: Passenger Car
  19: Cargo Car
  20: Flat Car
  21: Tank car
  22: Locomotive
  23: Maritime Vessel
  24: Motorboat
  25: Sailboat
  26: Tugboat
  27: Barge
  28: Fishing Vessel
  29: Ferry
  30: Yacht
  31: Container Ship
  32: Oil Tanker
  33: Engineering Vehicle
  34: Tower crane
  35: Container Crane
  36: Reach Stacker
  37: Straddle Carrier
  38: Mobile Crane
  39: Dump Truck
  40: Haul Truck
  41: Scraper/Tractor
  42: Front loader/Bulldozer
  43: Excavator
  44: Cement Mixer
  45: Ground Grader
  46: Hut/Tent
  47: Shed
  48: Building
  49: Aircraft Hangar
  50: Damaged Building
  51: Facility
  52: Construction Site
  53: Vehicle Lot
  54: Helipad
  55: Storage Tank
  56: Shipping container lot
  57: Shipping Container
  58: Pylon
  59: Tower

# Download script/URL (optional) ---------------------------------------------------------------------------------------
download: |
  import json
  from pathlib import Path
  import shutil

  import numpy as np
  from PIL import Image

  from ultralytics.utils import TQDM
  from ultralytics.data.split import autosplit
  from ultralytics.utils.ops import xyxy2xywhn

  def convert_labels(fname=Path("xView/xView_train.geojson")):
      """Convert xView GeoJSON labels to YOLO format (classes 0-59) and save them as text files."""
      path = fname.parent
      with open(fname, encoding="utf-8") as f:
          print(f"Loading {fname}...")
          data = json.load(f)

      # Make dirs
      labels = path / "labels" / "train"
      shutil.rmtree(labels, ignore_errors=True)
      labels.mkdir(parents=True, exist_ok=True)

      # xView classes 11-94 to 0-59
      xview_class2index = [-1, -1, -1, -1, -1, -1, -1, -1, -1, -1, -1, 0, 1, 2, -1, 3, -1, 4, 5, 6, 7, 8, -1, 9, 10, 11,
                           12, 13, 14, 15, -1, -1, 16, 17, 18, 19, 20, 21, 22, -1, 23, 24, 25, -1, 26, 27, -1, 28, -1,
                           29, 30, 31, 32, 33, 34, 35, 36, 37, -1, 38, 39, 40, 41, 42, 43, 44, 45, -1, -1, -1, -1, 46,
                           47, 48, 49, -1, 50, 51, -1, 52, -1, -1, -1, 53, 54, -1, 55, -1, -1, 56, -1, 57, -1, 58, 59]

      shapes = {}
      for feature in TQDM(data["features"], desc=f"Converting {fname}"):
          p = feature["properties"]
          if p["bounds_imcoords"]:
              image_id = p["image_id"]
              image_file = path / "train_images" / image_id
              if image_file.exists():  # 1395.tif missing
                  try:
                      box = np.array([int(num) for num in p["bounds_imcoords"].split(",")])
                      assert box.shape[0] == 4, f"incorrect box shape {box.shape[0]}"
                      cls = p["type_id"]
                      cls = xview_class2index[int(cls)]  # xView class to 0-59
                      assert 59 >= cls >= 0, f"incorrect class index {cls}"

                      # Write YOLO label
                      if image_id not in shapes:
                          shapes[image_id] = Image.open(image_file).size
                      box = xyxy2xywhn(box[None].astype(float), w=shapes[image_id][0], h=shapes[image_id][1], clip=True)
                      with open((labels / image_id).with_suffix(".txt"), "a", encoding="utf-8") as f:
                          f.write(f"{cls} {' '.join(f'{x:.6f}' for x in box[0])}\n")  # write label.txt
                  except Exception as e:
                      print(f"WARNING: skipping one label for {image_file}: {e}")

  # Download manually from https://challenge.xviewdataset.org
  dir = Path(yaml["path"])  # dataset root dir
  # urls = [
  #     "https://d307kc0mrhucc3.cloudfront.net/train_labels.zip",  # train labels
  #     "https://d307kc0mrhucc3.cloudfront.net/train_images.zip",  # 15G, 847 train images
  #     "https://d307kc0mrhucc3.cloudfront.net/val_images.zip",  # 5G, 282 val images (no labels)
  # ]
  # download(urls, dir=dir)

  # Convert labels
  convert_labels(dir / "xView_train.geojson")

  # Move images
  images = Path(dir / "images")
  images.mkdir(parents=True, exist_ok=True)
  Path(dir / "train_images").rename(dir / "images" / "train")
  Path(dir / "val_images").rename(dir / "images" / "val")

  # Split
autosplit(dir / "images" / "train")الاستخدام#
يتطلب التدريب فك ضغط التنزيل اليدوي الموضح أعلاه ضمن datasets/xView/؛ ثم يجري تحويل التعليقات التوضيحية وتقسيم التدريب/التحقق تلقائيًا.
لتدريب نموذج على مجموعة بيانات xView لمدة 100 حقبة وبحجم صورة 640، يمكنك استخدام مقتطفات الشيفرة التالية.
from ultralytics import YOLO
# تحميل نموذج
model = YOLO("yolo26n.pt") # تحميل نموذج مدرّب مسبقًا (موصى به للتدريب)
# تدريب النموذج
results = model.train(data="xView.yaml", epochs=100, imgsz=640)لتوسيم صور أقمار صناعية إضافية وإدارة عمليات تدريب xView في متصفحك، استخدم منصة Ultralytics.
البيانات النموذجية والتعليقات التوضيحية#
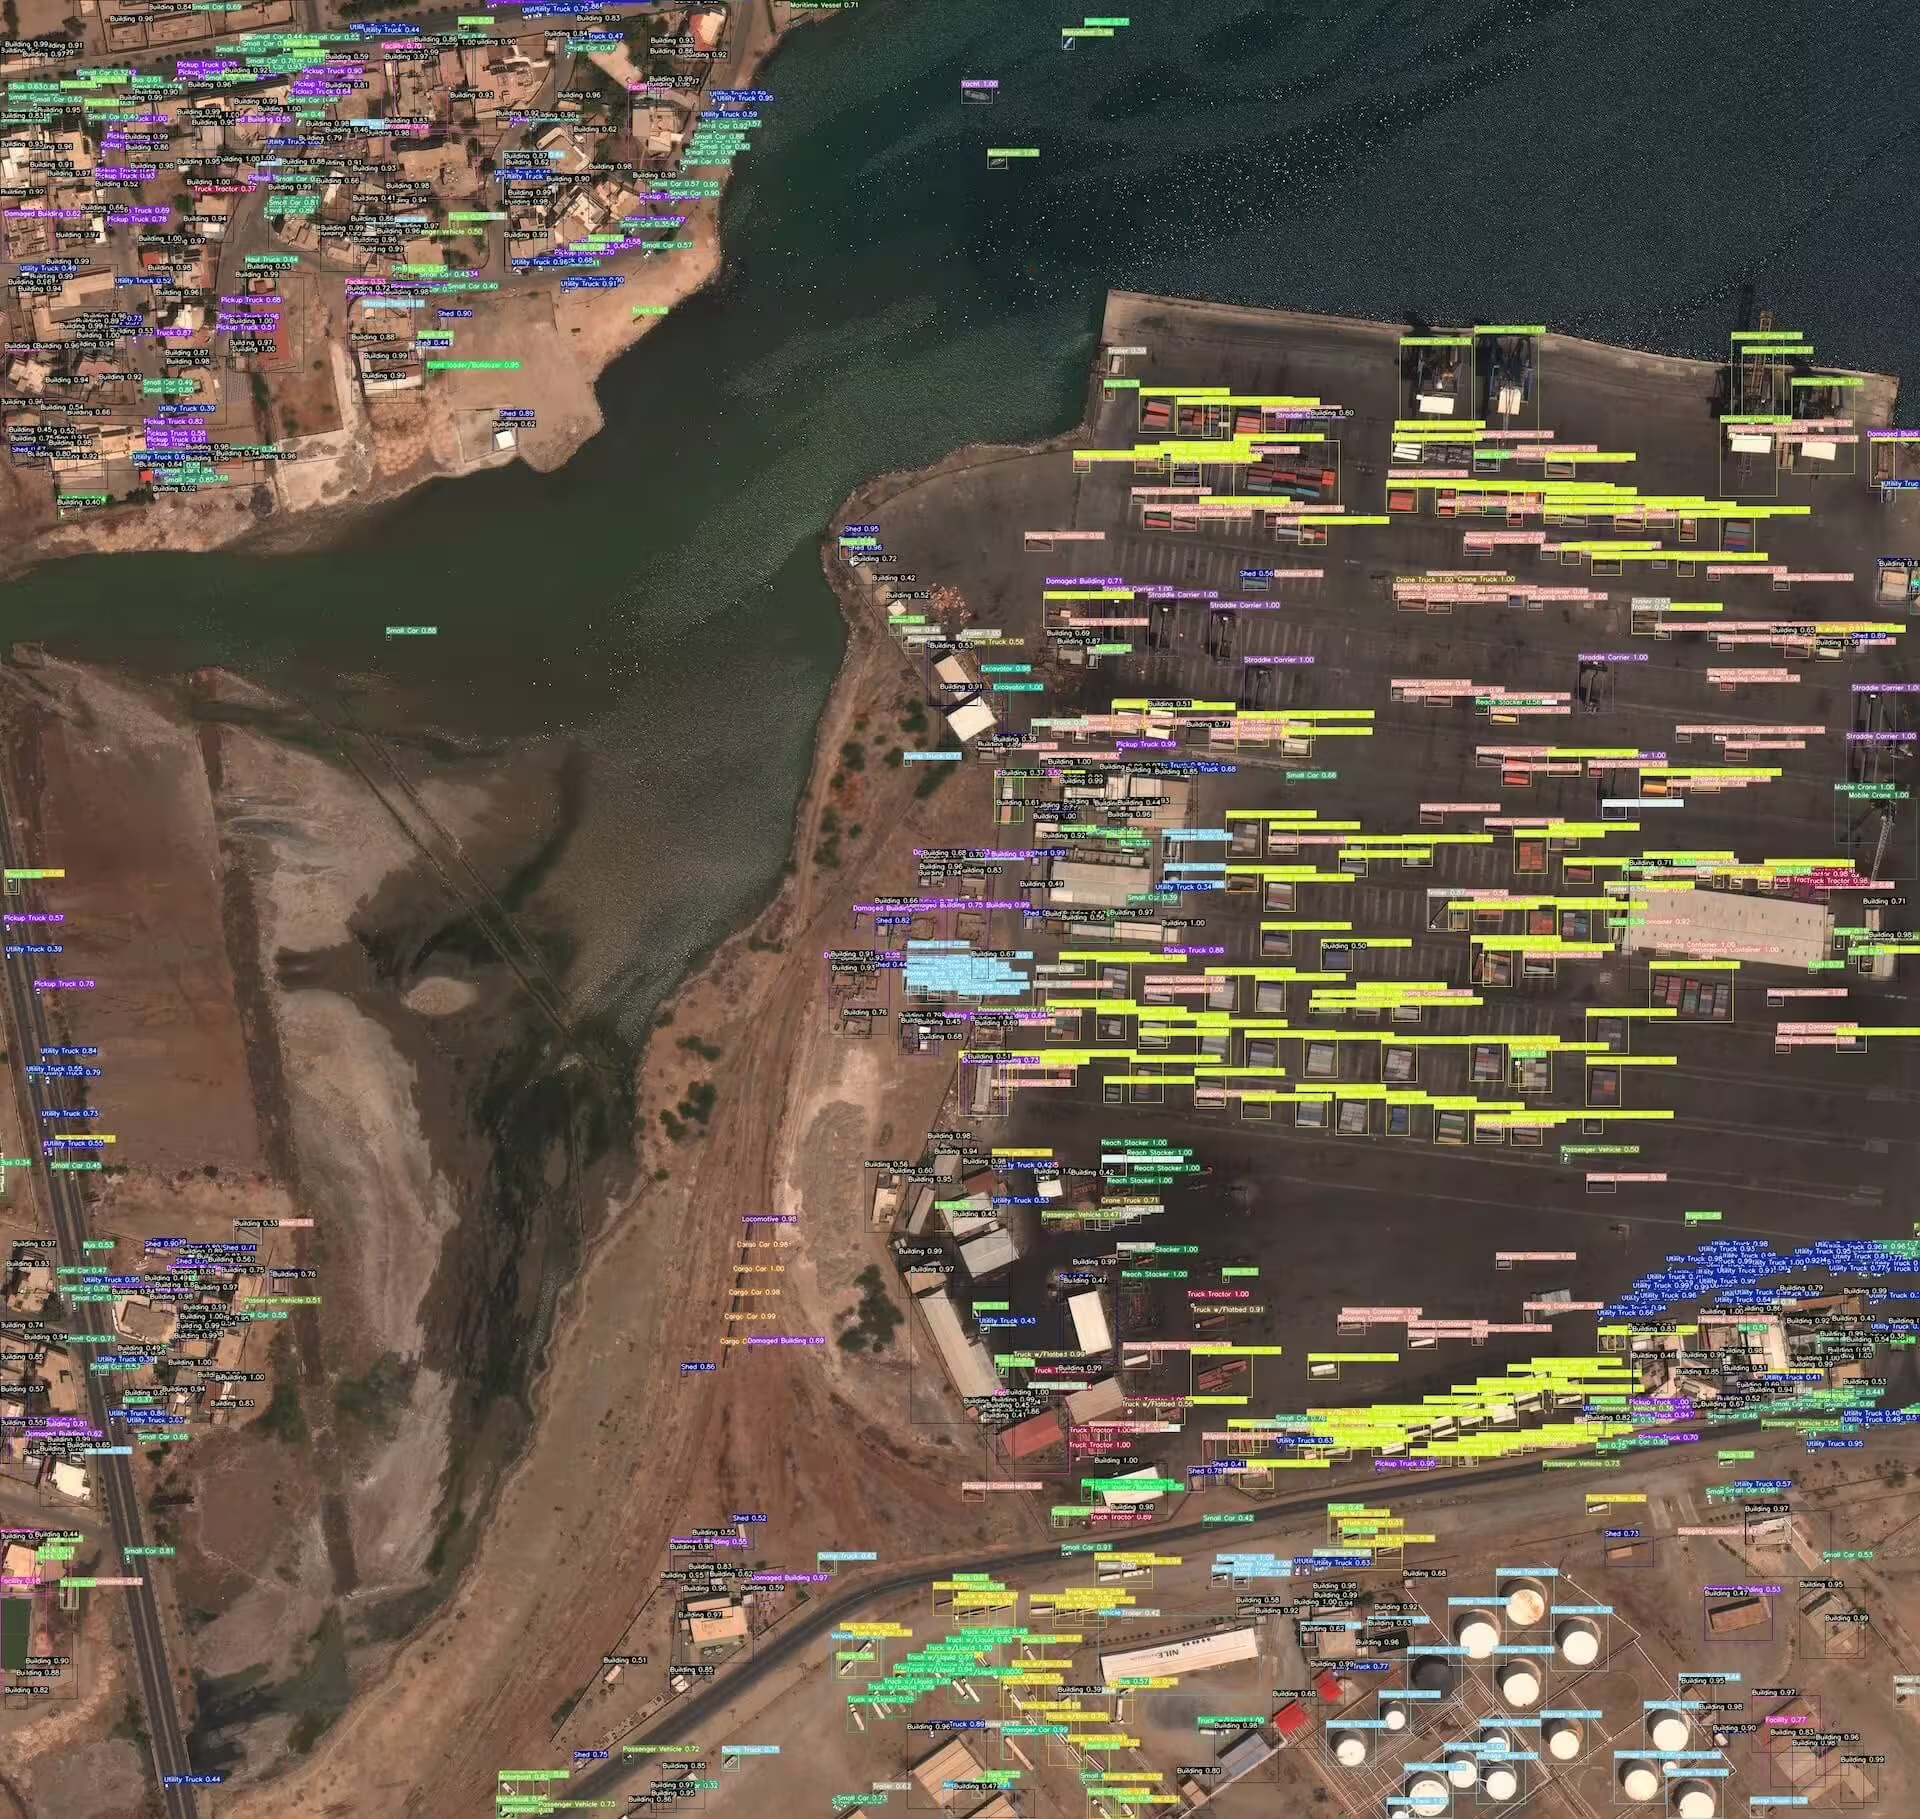
تعرض العينة أدناه مشهدًا نموذجيًا من xView: صورًا جوية عالية الدقة تُوسم فيها الكائنات الصغيرة، مثل المركبات والمباني، بمربعات إحاطة؛ ما يوضح سبب حاجة اكتشاف الكائنات في صور الأقمار الصناعية إلى تحديد مواقع دقيق.
الاستشهادات والشكر والتقدير#
إذا استخدمت مجموعة بيانات xView في أبحاثك أو أعمال التطوير، فيُرجى الاستشهاد بالورقة البحثية التالية:
@misc{lam2018xview,
      title={xView: Objects in Context in Overhead Imagery},
      author={Darius Lam and Richard Kuzma and Kevin McGee and Samuel Dooley and Michael Laielli and Matthew Klaric and Yaroslav Bulatov and Brendan McCord},
      year={2018},
      eprint={1802.07856},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}
نود أن نشكر وحدة الابتكار الدفاعي (DIU) والقائمين على إنشاء مجموعة بيانات xView على إسهامهم القيّم في مجتمع أبحاث الرؤية الحاسوبية. لمزيد من المعلومات، تفضل بزيارة موقع مجموعة بيانات xView.
الأسئلة الشائعة#
مجموعة بيانات xView معيار لصور الأقمار الصناعية أُصدر لتحدي DIUx xView لعام 2018 من قبل الوكالة الوطنية الأمريكية للاستخبارات الجغرافية المكانية، ويوفر أكثر من مليون مثيل لكائنات ضمن 60 فئة دقيقة في صور WorldView-3 بدقة 0.3 m. وتدعم المجموعة الأبحاث المتعلقة باكتشاف الكائنات الصغيرة والنادرة والدقيقة في المناظر الملتقطة من الأعلى، وهي أهداف أصعب بكثير من تلك الموجودة في الصور الملتقطة من مستوى الأرض.
يتطلب xView تنزيلًا يدويًا: سجّل في موقع تحدي DIUx xView لعام 2018، ونزّل
train_images.zip(~15 GB) وtrain_labels.zipوval_images.zip(~5 GB) — بحجم إجمالي يقارب 20.7 GB — ثم فك ضغطها ضمنdatasets/xView/وفق البنية الموضحة في التحذير أعلى هذه الصفحة. في أول تشغيل للتدريب، تحوّل Ultralytics التعليقات التوضيحية بتنسيق GeoJSON تلقائيًا إلى تنسيق YOLO، وتنشئ تقسيم التدريب/التحقق.تتضمن xView عدد 847 صورة تدريب موسومة و282 صورة تحقق بلا تسميات متاحة للعامة، وكلها ملتقطة بأقمار WorldView-3 الصناعية بدقة 0.3 m. وتغطي التعليقات التوضيحية أكثر من مليون مثيل لكائنات ضمن 60 فئة. وبما أن تسميات التدريب وحدها متاحة للعامة، يقسم إعداد
xView.yamlمن Ultralytics الصور الموسومة البالغ عددها 847 تلقائيًا إلى مجموعتي تدريب وتحقق بنسبة تقارب 90/10؛ راجع بنية مجموعة البيانات للاطلاع على التفاصيل.درّب نموذج YOLO26n على xView لمدة 100 حقبة وبحجم صورة 640:
مثال على التدريبfrom ultralytics import YOLO # تحميل نموذج model = YOLO("yolo26n.pt") # تحميل نموذج مدرّب مسبقًا (موصى به للتدريب) # تدريب النموذج results = model.train(data="xView.yaml", epochs=100, imgsz=640)للاطلاع على الوسائط والإعدادات التفصيلية، راجع صفحة تدريب النموذج.
استشهد بالورقة البحثية "xView: Objects in Context in Overhead Imagery" (Lam وآخرون، arXiv:1802.07856، 2018)؛ يتوفر إدخال BibTeX الكامل في قسم الاستشهادات والشكر أعلاه.
التعليقات25
اطرح سؤالًا، وشارك نتائجك، أو ساعد شخصًا آخر.
XiFromEY
Thank you for sharing the code @glenn-jocher and @Laughing-q. If I only want to detect building and damaged building, how should I modify the code above? Any hints? Thank you very much!
1I figured out using ChatGPT. However, I am looking at the imbalance issue.
 Glenn JocherUltralytics(تم التعديل)
@XiFromEY hey there! 👋 To focus on detecting buildings and damaged buildings, you'll want to modify your dataset's classes. The simplest way would be to create a script to update your *.txt labels to delete any rows that don't pertain to the classes you are interested in, and then train normally with your updated YAML that points to your modified labels:
yolo detect train data=xView.yaml model=yolo26n.pt epochs=100 imgsz=640This will train your model to detect just the building classes you're interested in. Happy coding! 🚀
chandan-chakma
after download the images i can not convert properly to yolo-format . datasets/xView/ images/train_images /val_images xView_train_geojson could you please share the conversion code?
- Glenn JocherUltralytics
The conversion code is already bundled in the
download:section of the dataset YAML—see the maintainedxView.yamlconversion script (also referenced from the xView dataset docs); place your manual download asdatasets/xView/train_images/,datasets/xView/val_images/, anddatasets/xView/xView_train.geojson(not underimages/), then run:yolo detect train data=xView.yaml model=yolo26n.pt imgsz=640 epochs=1If it still fails, please paste the full text traceback here (not a screenshot) and your
yolo checksoutput so we can pinpoint what’s off in the paths/GeoJSON. manual download as datasets/xView/train_images/, datasets/xView/val_images/, and datasets/xView/xView_train.geojson after run yolo detect train data=xView.yaml model=yolo26n.pt imgsz=640 epochs=1 can it formated or i need to do manually convert it?
i am getting this error. (.new) (base) alpha@alpha-HP-Z2-Tower-G9-Workstation-Desktop-PC:~/Desktop/chakma/test$ python train.py Ultralytics 8.4.7 🚀 Python-3.11.7 torch-2.9.1+cu128 CUDA:0 (NVIDIA GeForce RTX 3090, 24115MiB) engine/trainer: agnostic_nms=False, amp=True, angle=1.0, augment=False, auto_augment=randaugment, batch=16, bgr=0.0, box=7.5, cache=False, cfg=None, classes=None, close_mosaic=10, cls=0.5, compile=False, conf=None, copy_paste=0.0, copy_paste_mode=flip, cos_lr=False, cutmix=0.0, data=xView.yaml, degrees=0.0, deterministic=True, device=None, dfl=1.5, dnn=False, dropout=0.0, dynamic=False, embed=None, epochs=100, erasing=0.4, exist_ok=False, fliplr=0.5, flipud=0.0, format=torchscript, fraction=1.0, freeze=None, half=False, hsv_h=0.015, hsv_s=0.7, hsv_v=0.4, imgsz=640, int8=False, iou=0.7, keras=False, kobj=1.0, line_width=None, lr0=0.01, lrf=0.01, mask_ratio=4, max_det=300, mixup=0.0, mode=train, model=yolov8n.pt, momentum=0.937, mosaic=1.0, multi_scale=0.0, name=train16, nbs=64, nms=False, opset=None, optimize=False, optimizer=auto, overlap_mask=True, patience=100, perspective=0.0, plots=True, pose=12.0, pretrained=True, profile=False, project=None, rect=False, resume=False, retina_masks=False, rle=1.0, save=True, save_conf=False, save_crop=False, save_dir=/home/alpha/Desktop/chakma/test/runs/detect/train16, save_frames=False, save_json=False, save_period=-1, save_txt=False, scale=0.5, seed=0, shear=0.0, show=False, show_boxes=True, show_conf=True, show_labels=True, simplify=True, single_cls=False, source=None, split=val, stream_buffer=False, task=detect, time=None, tracker=botsort.yaml, translate=0.1, val=True, verbose=True, vid_stride=1, visualize=False, warmup_bias_lr=0.1, warmup_epochs=3.0, warmup_momentum=0.8, weight_decay=0.0005, workers=8, workspace=None
WARNING ⚠️ Dataset 'xView.yaml' images not found, missing path '/home/alpha/Desktop/chakma/test/datasets/xView/images/autosplit_val.txt' Traceback (most recent call last): File "/home/alpha/Desktop/chakma/test/.new/lib/python3.11/site-packages/ultralytics/engine/trainer.py", line 660, in get_dataset data = check_det_dataset(self.args.data) ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^ File "/home/alpha/Desktop/chakma/test/.new/lib/python3.11/site-packages/ultralytics/data/utils.py", line 471, in check_det_dataset exec(s, {"yaml": data}) File "", line 9, in ImportError: cannot import name 'autosplit' from 'ultralytics.data.utils' (/home/alpha/Desktop/chakma/test/.new/lib/python3.11/site-packages/ultralytics/data/utils.py)
The above exception was the direct cause of the following exception:
Traceback (most recent call last): File "/home/alpha/Desktop/chakma/test/train.py", line 7, in results = model.train(data="xView.yaml", epochs=100, imgsz=640) ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^ File "/home/alpha/Desktop/chakma/test/.new/lib/python3.11/site-packages/ultralytics/engine/model.py", line 769, in train self.trainer = (trainer or self._smart_load("trainer"))(overrides=args, _callbacks=self.callbacks) ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^ File "/home/alpha/Desktop/chakma/test/.new/lib/python3.11/site-packages/ultralytics/models/yolo/detect/train.py", line 63, in init super().init(cfg, overrides, _callbacks) File "/home/alpha/Desktop/chakma/test/.new/lib/python3.11/site-packages/ultralytics/engine/trainer.py", line 186, in init self.data = self.get_dataset() ^^^^^^^^^^^^^^^^^^ File "/home/alpha/Desktop/chakma/test/.new/lib/python3.11/site-packages/ultralytics/engine/trainer.py", line 664, in get_dataset raise RuntimeError(emojis(f"Dataset '{clean_url(self.args.data)}' error ❌ {e}")) from e RuntimeError: Dataset 'xView.yaml' error ❌ cannot import name 'autosplit' from 'ultralytics.data.utils' (/home/alpha/Desktop/chakma/test/.new/lib/python3.11/site-packages/ultralytics/data/utils.py) (.new) (base) alpha@alpha-HP-Z2-Tower-G9-Workstation-Desktop-PC:~/Desktop/chakma/test$
- Glenn JocherUltralytics
That
ImportError: cannot import name 'autosplit'means you’re running a stalexView.yamldownload:script that importsautosplitfrom the wrong module (it’s whyimages/autosplit_val.txtnever gets created), so you don’t need to manually convert—just update Ultralytics and ensure you’re using thexView.yamlthat ships with your installed package (not an older local copy); the dataset conversion is triggered automatically bycheck_det_dataset()when files are missing (see the dataset check/download logic).pip install -U ultralytics yolo checks yolo detect train data=xView.yaml model=yolo26n.pt imgsz=640 epochs=1If it still fails, paste your
yolo checksoutput and the first ~15 lines of thedownload:block from the exactxView.yamlfile your run is loading (plus the full traceback). thanks finally it working. i trained on yolov8n the result is quite low. map50 and map50-95 and recall low but prec is high is it normal or have some issue.here is the script and the result.
import os os.environ['OPENCV_LOG_LEVEL'] = 'ERROR' import warnings warnings.filterwarnings('ignore') from ultralytics import YOLO
Load a model
model = YOLO("yolov8n.pt") # load a pretrained model (recommended for training)
Train the model
results = model.train(data="xView.yaml", epochs=100, imgsz=640, batch=4,amp=True,workers=4,cache=False)
====================
Validating /home/alpha/Desktop/chakma/test/runs/detect/train46/weights/best.pt... Ultralytics 8.4.7 🚀 Python-3.11.7 torch-2.9.1+cu128 CUDA:0 (NVIDIA GeForce RTX 3090, 24115MiB) Model summary (fused): 73 layers, 3,017,348 parameters, 0 gradients, 8.1 GFLOPs Class Images Instances Box(P R mAP50 mAP50-95): 18% ━━────────── 2/11 1.1s/it 0.7s<9.8sWARNING ⚠️ NMS time limit 2.400s exceeded Class Images Instances Box(P R mAP50 mAP50-95): 100% ━━━━━━━━━━━━ 11/11 1.2it/s 9.5s all 86 64690 0.61 0.00241 0.0044 0.00219 Fixed-wing Aircraft 4 5 0 0 0 0 Small Aircraft 7 144 0 0 0 0 Cargo Plane 16 127 1 0 0 0 Helicopter 5 10 1 0 0 0 Passenger Vehicle 22 114 1 0 0 0 Small Car 71 24345 0 0 0 0 Bus 45 645 1 0 0 0 Pickup Truck 25 156 1 0 0 0 Utility Truck 33 410 0 0 0 0 Truck 49 1536 1 0 0 0 Cargo Truck 48 666 1 0 0 0 Truck w/Box 29 343 0 0 0 0 Truck Tractor 17 39 1 0 0 0 Trailer 36 977 1 0 0 0 Truck w/Flatbed 21 85 1 0 0 0 Truck w/Liquid 5 9 0 0 0 0 Crane Truck 8 17 1 0 0 0 Railway Vehicle 1 2 1 0 0 0 Passenger Car 5 72 1 0 0 0 Cargo Car 4 23 0 0 0 0 Locomotive 1 1 1 0 0 0 Maritime Vessel 10 80 1 0 0 0 Motorboat 11 47 0 0 0 0 Sailboat 2 2 1 0 0 0 Tugboat 4 25 1 0 0 0 Barge 5 25 0 0 0 0 Fishing Vessel 11 115 0 0 0 0 Ferry 7 33 0 0 0 0 Yacht 4 7 1 0 0 0 Container Ship 5 31 1 0 0 0 Oil Tanker 5 9 0 0 0 0 Engineering Vehicle 13 27 1 0 0 0 Tower crane 8 18 0 0 0 0 Container Crane 1 1 0 0 0 0 Reach Stacker 3 8 1 0 0 0 Straddle Carrier 1 1 1 0 0 0 Mobile Crane 11 34 0 0 0 0 Dump Truck 29 120 1 0 0 0 Haul Truck 3 33 1 0 0 0 Scraper/Tractor 3 3 0 0 0 0 Front loader/Bulldozer 23 86 0 0 0 0 Excavator 15 97 1 0 0 0 Cement Mixer 7 11 1 0 0 0 Ground Grader 4 5 1 0 0 0 Hut/Tent 8 40 1 0 0 0 Shed 24 124 1 0 0 0 Building 79 32296 0.398 0.14 0.199 0.0823 Aircraft Hangar 3 13 0 0 0 0 Damaged Building 14 98 0 0 0 0 Facility 21 85 1 0 0 0 Construction Site 20 160 1 0 0 0 Vehicle Lot 39 597 1 0 0 0 Helipad 4 5 0 0 0 0 Storage Tank 23 132 0 0 0 0 Shipping container lot 15 404 1 0 0.0557 0.0446 Shipping Container 14 174 0 0 0 0 Pylon 7 15 1 0 0 0 Tower 3 3 1 0 0 0 Speed: 0.4ms preprocess, 9.2ms inference, 0.0ms loss, 66.1ms postprocess per image Results saved to /home/alpha/Desktop/chakma/test/runs/detect/train46
- Glenn JocherUltralytics
Yes—on xView this “high precision, near-zero recall/mAP” usually means the model is producing very few usable detections, and your
WARNING ⚠️ NMS time limit ... exceededduringvalis a strong hint the evaluation is getting truncated on these very dense scenes (lots of tiny objects per image), so the reported metrics can look artificially awful; the most effective fix is to train/validate on tiled crops (so each image has fewer objects) and/or increaseimgsz, and for a stronger baseline start fromyolo26n.pt/yolo26s.ptrather thanyolov8n.pt(see the relevant knobs in the Train mode docs).
WARN:0@12.381] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 33922 (0x8482) encountered [ WARN:0@12.381] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 34735 (0x87af) encountered [ WARN:0@12.381] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 34736 (0x87b0) encountered [ WARN:0@12.381] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 34737 (0x87b1) encountered [ WARN:0@12.381] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 42112 (0xa480) encountered [ WARN:0@12.381] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 42113 (0xa481) encountered Plotting labels to /home/alpha/Desktop/MH/ultralytics/runs/detect/train8/labels.jpg... optimizer: 'optimizer=auto' found, ignoring 'lr0=0.01' and 'momentum=0.937' and determining best 'optimizer', 'lr0' and 'momentum' automatically... optimizer: AdamW(lr=0.000156, momentum=0.9) with parameter groups 110 weight(decay=0.0), 173 weight(decay=0.0005), 184 bias(decay=0.0) Image sizes 1024 train, 1024 val Using 8 dataloader workers Logging results to /home/alpha/Desktop/MH/ultralytics/runs/detect/train8 Starting training for 100 epochs...
Epoch GPU_mem box_loss cls_loss dfl_loss Instances Size0%| | 0/191 [00:00<?, ?it/s][ WARN:0@12.764] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 33550 (0x830e) encountered [ WARN:0@12.764] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 33922 (0x8482) encountered [ WARN:0@12.764] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 34735 (0x87af) encountered [ WARN:0@12.764] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 34736 (0x87b0) encountered [ WARN:0@12.764] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 34737 (0x87b1) encountered [ WARN:0@12.764] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 42112 (0xa480) encountered [ WARN:0@12.764] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 42113 (0xa481) encountered [ WARN:0@12.802] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 33550 (0x830e) encountered [ WARN:0@12.802] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 33922 (0x8482) encountered [ WARN:0@12.802] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 34735 (0x87af) encountered [ WARN:0@12.802] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 34736 (0x87b0) encountered [ WARN:0@12.802] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 34737 (0x87b1) encountered [ WARN:0@12.802] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 42112 (0xa480) encountered [ WARN:0@12.802] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 42113 (0xa481) encountered [ WARN:0@12.842] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 33550 (0x830e) encountered [ WARN:0@12.842] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 33922 (0x8482) encountered [ WARN:0@12.842] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 34735 (0x87af) encountered [ WARN:0@12.842] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 34736 (0x87b0) encountered [ WARN:0@12.842] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 34737 (0x87b1) encountered [ WARN:0@12.842] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 42112 (0xa480) encountered [ WARN:0@12.842] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 42113 (0xa481) encountered [ WARN:0@12.869] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 33550 (0x830e) encountered [ WARN:0@12.869] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 33922 (0x8482) encountered [ WARN:0@12.869] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 34735 (0x87af) encountered [ WARN:0@12.869] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 34736 (0x87b0) encountered [ WARN:0@12.870] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 34737 (0x87b1) encountered [ WARN:0@12.870] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 42112 (0xa480) encountered [ WARN:0@12.870] global grfmt_tiff.cpp:122 TIFF_Warning TIFFReadDirectory: Unknown field with tag 42113 (0xa481) encountered 0%| | 0/191 [00:00<?, ?it/s] why i am getting this error could you please tell how can i solve it?
- Glenn JocherUltralytics
Those are OpenCV/libtiff GeoTIFF metadata warnings from reading xView
.tiffiles (not a YOLO error), so if training continues you can ignore them; if your run actually stops, please paste the full text traceback plus the output of:yolo checksIf you just want to silence the warnings, you can run with:
OPENCV_LOG_LEVEL=ERROR yolo detect train data=xView.yaml model=yolo26n.pt imgsz=1024and if OpenCV can’t reliably read your TIFFs on your system, a practical workaround is to re-encode the
.tifto plain RGB (PNG/JPG) after confirming your folder layout matches the xView dataset guide. thank you very. so it will not effect model perfomance?
- Glenn JocherUltralytics
Yes—those GeoTIFF tag warnings are about metadata parsing and won’t affect model performance as long as the images decode correctly and training/validation completes; if you want to sanity-check decoding, run a quick inference on a few
.tiftiles (and if anything looks off, paste the full traceback +yolo checksoutput as in the Troubleshooting Common YOLO Issues guide).
Mahmoud-owais
New https://pypi.org/project/ultralytics/8.2.64 available 😃 Update with 'pip install -U ultralytics' Ultralytics YOLOv8.2.52 🚀 Python-3.10.12 torch-2.3.1+cu121 CUDA:0 (NVIDIA L4, 22700MiB) engine/trainer: task=detect, mode=train, model=yolov8n.pt, data=/content/drive/MyDrive/ultralytics-main/datasets/xView/xView.yaml, epochs=100, time=None, patience=100, batch=16, imgsz=640, save=True, save_period=-1, cache=False, device=None, workers=8, project=None, name=train63, exist_ok=False, pretrained=True, optimizer=auto, verbose=True, seed=0, deterministic=True, single_cls=False, rect=False, cos_lr=False, close_mosaic=10, resume=False, amp=True, fraction=1.0, profile=False, freeze=None, multi_scale=False, overlap_mask=True, mask_ratio=4, dropout=0.0, val=True, split=val, save_json=False, save_hybrid=False, conf=None, iou=0.7, max_det=300, half=False, dnn=False, plots=True, source=None, vid_stride=1, stream_buffer=False, visualize=False, augment=False, agnostic_nms=False, classes=None, retina_masks=False, embed=None, show=False, save_frames=False, save_txt=False, save_conf=False, save_crop=False, show_labels=True, show_conf=True, show_boxes=True, line_width=None, format=torchscript, keras=False, optimize=False, int8=False, dynamic=False, simplify=False, opset=None, workspace=4, nms=False, lr0=0.01, lrf=0.01, momentum=0.937, weight_decay=0.0005, warmup_epochs=3.0, warmup_momentum=0.8, warmup_bias_lr=0.1, box=7.5, cls=0.5, dfl=1.5, pose=12.0, kobj=1.0, label_smoothing=0.0, nbs=64, hsv_h=0.015, hsv_s=0.7, hsv_v=0.4, degrees=0.0, translate=0.1, scale=0.5, shear=0.0, perspective=0.0, flipud=0.0, fliplr=0.5, bgr=0.0, mosaic=1.0, mixup=0.0, copy_paste=0.0, auto_augment=randaugment, erasing=0.4, crop_fraction=1.0, cfg=None, tracker=botsort.yaml, save_dir=runs/detect/train63 Downloading https://ultralytics.com/assets/Arial.ttf to '/root/.config/Ultralytics/Arial.ttf'... 100%|██████████| 755k/755k [00:00<00:00, 123MB/s] Overriding model.yaml nc=80 with nc=60
from n params module arguments0 -1 1 464 ultralytics.nn.modules.conv.Conv [3, 16, 3, 2]
1 -1 1 4672 ultralytics.nn.modules.conv.Conv [16, 32, 3, 2]
2 -1 1 7360 ultralytics.nn.modules.block.C2f [32, 32, 1, True]
3 -1 1 18560 ultralytics.nn.modules.conv.Conv [32, 64, 3, 2]
4 -1 2 49664 ultralytics.nn.modules.block.C2f [64, 64, 2, True]
5 -1 1 73984 ultralytics.nn.modules.conv.Conv [64, 128, 3, 2]
6 -1 2 197632 ultralytics.nn.modules.block.C2f [128, 128, 2, True]
7 -1 1 295424 ultralytics.nn.modules.conv.Conv [128, 256, 3, 2]
8 -1 1 460288 ultralytics.nn.modules.block.C2f [256, 256, 1, True]
9 -1 1 164608 ultralytics.nn.modules.block.SPPF [256, 256, 5]
10 -1 1 0 torch.nn.modules.upsampling.Upsample [None, 2, 'nearest']
11 [-1, 6] 1 0 ultralytics.nn.modules.conv.Concat [1]
12 -1 1 148224 ultralytics.nn.modules.block.C2f [384, 128, 1]
13 -1 1 0 torch.nn.modules.upsampling.Upsample [None, 2, 'nearest']
14 [-1, 4] 1 0 ultralytics.nn.modules.conv.Concat [1]
15 -1 1 37248 ultralytics.nn.modules.block.C2f [192, 64, 1]
16 -1 1 36992 ultralytics.nn.modules.conv.Conv [64, 64, 3, 2]
17 [-1, 12] 1 0 ultralytics.nn.modules.conv.Concat [1]
18 -1 1 123648 ultralytics.nn.modules.block.C2f [192, 128, 1]
19 -1 1 147712 ultralytics.nn.modules.conv.Conv [128, 128, 3, 2]
20 [-1, 9] 1 0 ultralytics.nn.modules.conv.Concat [1]
21 -1 1 493056 ultralytics.nn.modules.block.C2f [384, 256, 1]
22 [15, 18, 21] 1 763012 ultralytics.nn.modules.head.Detect [60, [64, 128, 256]]
Model summary: 225 layers, 3022548 parameters, 3022532 gradients, 8.3 GFLOPsTransferred 319/355 items from pretrained weights TensorBoard: Start with 'tensorboard --logdir runs/detect/train63', view at http://localhost:6006/ Freezing layer 'model.22.dfl.conv.weight' AMP: running Automatic Mixed Precision (AMP) checks with YOLOv8n... AMP: checks passed ✅ train: Scanning /content/drive/MyDrive/ultralytics-main/datasets/xView/labels/train... 760 images, 0 backgrounds, 0 corrupt: 100%|██████████| 760/760 [02:31<00:00, 5.02it/s] train: New cache created: /content/drive/MyDrive/ultralytics-main/datasets/xView/labels/train.cache albumentations: Blur(p=0.01, blur_limit=(3, 7)), MedianBlur(p=0.01, blur_limit=(3, 7)), ToGray(p=0.01), CLAHE(p=0.01, clip_limit=(1, 4.0), tile_grid_size=(8, 8)) /usr/lib/python3.10/multiprocessing/popen_fork.py:66: RuntimeWarning: os.fork() was called. os.fork() is incompatible with multithreaded code, and JAX is multithreaded, so this will likely lead to a deadlock. self.pid = os.fork() val: Scanning /content/drive/MyDrive/ultralytics-main/datasets/xView/labels/train... 86 images, 0 backgrounds, 0 corrupt: 100%|██████████| 86/86 [00:16<00:00, 5.19it/s]val: New cache created: /content/drive/MyDrive/ultralytics-main/datasets/xView/labels/train.cache
Plotting labels to runs/detect/train63/labels.jpg... optimizer: 'optimizer=auto' found, ignoring 'lr0=0.01' and 'momentum=0.937' and determining best 'optimizer', 'lr0' and 'momentum' automatically... optimizer: AdamW(lr=0.000156, momentum=0.9) with parameter groups 57 weight(decay=0.0), 64 weight(decay=0.0005), 63 bias(decay=0.0) TensorBoard: model graph visualization added ✅ Image sizes 640 train, 640 val Using 8 dataloader workers Logging results to runs/detect/train63 Starting training for 100 epochs...
  Epoch    GPU_mem   box_loss   cls_loss   dfl_loss  Instances       Size
  1/100      18.3G      3.308      5.558      1.757  1.571e+04        640:   2%|▏         | 1/48 [00:05<04:33,  5.83s/it]
OutOfMemoryError Traceback (most recent call last) in <cell line: 7>() 5 6 # Train the model ----> 7 results = model.train(data="/content/drive/MyDrive/ultralytics-main/datasets/xView/xView.yaml", epochs=100, imgsz=640)
13 frames /content/drive/MyDrive/ultralytics-main/ultralytics/utils/tal.py in select_candidates_in_gts(xy_centers, gt_bboxes, eps) 225 bs, n_boxes, _ = gt_bboxes.shape 226 lt, rb = gt_bboxes.view(-1, 1, 4).chunk(2, 2) # left-top, right-bottom --> 227 bbox_deltas = torch.cat((xy_centers[None] - lt, rb - xy_centers[None]), dim=2).view(bs, n_boxes, n_anchors, -1) 228 # return (bbox_deltas.min(3)[0] > eps).to(gt_bboxes.dtype) 229 return bbox_deltas.amin(3).gt_(eps)
OutOfMemoryError: CUDA out of memory. Tried to allocate 8.63 GiB. GPU
 Paula DerrengerUltralytics
@Mahmoud-owais it looks like you're encountering an "Out of Memory" error during training. This can happen if the batch size or image size is too large for your GPU's memory. Try reducing the
batchsize orimgszto see if that resolves the issue. Additionally, ensure you're using the latest version of the Ultralytics package by runningpip install -U ultralytics. If the problem persists, please let us know. For more details on the xView dataset, you can visit xView Dataset Documentation.
Hello ! can help me What's the WARNING here ? New https://pypi.org/project/ultralytics/8.2.59 available 😃 Update with 'pip install -U ultralytics' Ultralytics YOLOv8.2.52 🚀 Python-3.10.12 torch-2.3.1+cu121 CPU (Intel Xeon 2.20GHz) engine/trainer: task=detect, mode=train, model=yolov8n.pt, data=xView.yaml, epochs=100, time=None, patience=100, batch=16, imgsz=640, save=True, save_period=-1, cache=False, device=None, workers=8, project=None, name=train8, exist_ok=False, pretrained=True, optimizer=auto, verbose=True, seed=0, deterministic=True, single_cls=False, rect=False, cos_lr=False, close_mosaic=10, resume=False, amp=True, fraction=1.0, profile=False, freeze=None, multi_scale=False, overlap_mask=True, mask_ratio=4, dropout=0.0, val=True, split=val, save_json=False, save_hybrid=False, conf=None, iou=0.7, max_det=300, half=False, dnn=False, plots=True, source=None, vid_stride=1, stream_buffer=False, visualize=False, augment=False, agnostic_nms=False, classes=None, retina_masks=False, embed=None, show=False, save_frames=False, save_txt=False, save_conf=False, save_crop=False, show_labels=True, show_conf=True, show_boxes=True, line_width=None, format=torchscript, keras=False, optimize=False, int8=False, dynamic=False, simplify=False, opset=None, workspace=4, nms=False, lr0=0.01, lrf=0.01, momentum=0.937, weight_decay=0.0005, warmup_epochs=3.0, warmup_momentum=0.8, warmup_bias_lr=0.1, box=7.5, cls=0.5, dfl=1.5, pose=12.0, kobj=1.0, label_smoothing=0.0, nbs=64, hsv_h=0.015, hsv_s=0.7, hsv_v=0.4, degrees=0.0, translate=0.1, scale=0.5, shear=0.0, perspective=0.0, flipud=0.0, fliplr=0.5, bgr=0.0, mosaic=1.0, mixup=0.0, copy_paste=0.0, auto_augment=randaugment, erasing=0.4, crop_fraction=1.0, cfg=None, tracker=botsort.yaml, save_dir=runs/detect/train8 Downloading https://ultralytics.com/assets/Arial.ttf to '/root/.config/Ultralytics/Arial.ttf'... 100%|██████████| 755k/755k [00:00<00:00, 15.5MB/s] Overriding model.yaml nc=80 with nc=60
from n params module arguments0 -1 1 464 ultralytics.nn.modules.conv.Conv [3, 16, 3, 2]
1 -1 1 4672 ultralytics.nn.modules.conv.Conv [16, 32, 3, 2]
2 -1 1 7360 ultralytics.nn.modules.block.C2f [32, 32, 1, True]
3 -1 1 18560 ultralytics.nn.modules.conv.Conv [32, 64, 3, 2]
4 -1 2 49664 ultralytics.nn.modules.block.C2f [64, 64, 2, True]
5 -1 1 73984 ultralytics.nn.modules.conv.Conv [64, 128, 3, 2]
6 -1 2 197632 ultralytics.nn.modules.block.C2f [128, 128, 2, True]
7 -1 1 295424 ultralytics.nn.modules.conv.Conv [128, 256, 3, 2]
8 -1 1 460288 ultralytics.nn.modules.block.C2f [256, 256, 1, True]
9 -1 1 164608 ultralytics.nn.modules.block.SPPF [256, 256, 5]
10 -1 1 0 torch.nn.modules.upsampling.Upsample [None, 2, 'nearest']
11 [-1, 6] 1 0 ultralytics.nn.modules.conv.Concat [1]
12 -1 1 148224 ultralytics.nn.modules.block.C2f [384, 128, 1]
13 -1 1 0 torch.nn.modules.upsampling.Upsample [None, 2, 'nearest']
14 [-1, 4] 1 0 ultralytics.nn.modules.conv.Concat [1]
15 -1 1 37248 ultralytics.nn.modules.block.C2f [192, 64, 1]
16 -1 1 36992 ultralytics.nn.modules.conv.Conv [64, 64, 3, 2]
17 [-1, 12] 1 0 ultralytics.nn.modules.conv.Concat [1]
18 -1 1 123648 ultralytics.nn.modules.block.C2f [192, 128, 1]
19 -1 1 147712 ultralytics.nn.modules.conv.Conv [128, 128, 3, 2]
20 [-1, 9] 1 0 ultralytics.nn.modules.conv.Concat [1]
21 -1 1 493056 ultralytics.nn.modules.block.C2f [384, 256, 1]
22 [15, 18, 21] 1 763012 ultralytics.nn.modules.head.Detect [60, [64, 128, 256]]
Model summary: 225 layers, 3022548 parameters, 3022532 gradientsTransferred 319/355 items from pretrained weights TensorBoard: Start with 'tensorboard --logdir runs/detect/train8', view at http://localhost:6006/ Freezing layer 'model.22.dfl.conv.weight' train: Scanning /content/drive/MyDrive/ultralytics-main/datasets/xView/labels/train/train_images... 0 images, 760 backgrounds, 0 corrupt: 100%|██████████| 760/760 [06:02<00:00, 2.09it/s]train: WARNING ⚠️ No labels found in /content/drive/MyDrive/ultralytics-main/datasets/xView/labels/train/train_images.cache. See https://docs.ultralytics.com/datasets for dataset formatting guidance.
train: New cache created: /content/drive/MyDrive/ultralytics-main/datasets/xView/labels/train/train_images.cache WARNING ⚠️ No labels found in /content/drive/MyDrive/ultralytics-main/datasets/xView/labels/train/train_images.cache, training may not work correctly. See https://docs.ultralytics.com/datasets for dataset formatting guidance. albumentations: Blur(p=0.01, blur_limit=(3, 7)), MedianBlur(p=0.01, blur_limit=(3, 7)), ToGray(p=0.01), CLAHE(p=0.01, clip_limit=(1, 4.0), tile_grid_size=(8, 8)) val: Scanning /content/drive/MyDrive/ultralytics-main/datasets/xView/labels/train/train_images... 0 images, 86 backgrounds, 0 corrupt: 100%|██████████| 86/86 [00:40<00:00, 2.14it/s]val: WARNING ⚠️ No labels found in /content/drive/MyDrive/ultralytics-main/datasets/xView/labels/train/train_images.cache. See https://docs.ultralytics.com/datasets for dataset formatting guidance. val: New cache created: /content/drive/MyDrive/ultralytics-main/datasets/xView/labels/train/train_images.cache WARNING ⚠️ No labels found in /content/drive/MyDrive/ultralytics-main/datasets/xView/labels/train/train_images.cache, training may not work correctly. See https://docs.ultralytics.com/datasets for dataset formatting guidance.
Plotting labels to runs/detect/train8/labels.jpg... zero-size array to reduction operation maximum which has no identity optimizer: 'optimizer=auto' found, ignoring 'lr0=0.01' and 'momentum=0.937' and determining best 'optimizer', 'lr0' and 'momentum' automatically... optimizer: AdamW(lr=0.000156, momentum=0.9) with parameter groups 57 weight(decay=0.0), 64 weight(decay=0.0005), 63 bias(decay=0.0) TensorBoard: model graph visualization added ✅ Image sizes 640 train, 640 val Using 0 dataloader workers Logging results to runs/detect/train8 Starting training for 100 epochs...
Epoch GPU_mem box_loss cls_loss dfl_loss Instances Size 1/100 0G 0 127.3 0 0 640: 17%|█▋ | 8/48 [04:40<22:42, 34.05s/it]- Glenn JocherUltralytics
@Mahmoud-owais the warning indicates that no labels were found in the specified directory for the xView dataset. This could be due to incorrect dataset formatting or missing label files. Please ensure that your dataset is correctly formatted and that the label files are in the expected location. For detailed guidance on dataset formatting, refer to the Ultralytics dataset documentation. Additionally, updating to the latest version of the Ultralytics package might resolve any underlying issues. You can update using
pip install -U ultralytics.1 thanks datasets/ └── xView/ ├── images/ │ ├── train/ │ └── val/ ├── labels/ │ ├── train/ │ └── val/ i have the dataset and xView_train.geojson how to by xView.yaml to extract the xView_train.geojson to this structure datasets/ └── xView/ ├── images/ │ ├── train/ │ └── val/ ├── labels/ │ ├── train/ │ └── val/
and i found this Error Transferred 319/355 items from pretrained weights TensorBoard: Start with 'tensorboard --logdir runs/detect/train28', view at http://localhost:6006/ Freezing layer 'model.22.dfl.conv.weight' train: Scanning /content/drive/MyDrive/ultralytics-main/datasets/xView/labels/train... 0 images, 760 backgrounds, 3 corrupt: 100%|██████████| 763/763 [06:10<00:00, 2.06it/s]train: WARNING ⚠️ /content/drive/MyDrive/ultralytics-main/datasets/xView/images/train/._100.tif: ignoring corrupt image/label: cannot identify image file '/content/drive/MyDrive/ultralytics-main/datasets/xView/images/train/._100.tif' train: WARNING ⚠️ /content/drive/MyDrive/ultralytics-main/datasets/xView/images/train/._102.tif: ignoring corrupt image/label: cannot identify image file '/content/drive/MyDrive/ultralytics-main/datasets/xView/images/train/._102.tif' train: WARNING ⚠️ /content/drive/MyDrive/ultralytics-main/datasets/xView/images/train/._109.tif: ignoring corrupt image/label: cannot identify image file '/content/drive/MyDrive/ultralytics-main/datasets/xView/images/train/._109.tif' train: WARNING ⚠️ No labels found in /content/drive/MyDrive/ultralytics-main/datasets/xView/labels/train.cache. See https://docs.ultralytics.com/datasets for dataset formatting guidance.
train: New cache created: /content/drive/MyDrive/ultralytics-main/datasets/xView/labels/train.cache WARNING ⚠️ No labels found in /content/drive/MyDrive/ultralytics-main/datasets/xView/labels/train.cache, training may not work correctly. See https://docs.ultralytics.com/datasets for dataset formatting guidance. albumentations: Blur(p=0.01, blur_limit=(3, 7)), MedianBlur(p=0.01, blur_limit=(3, 7)), ToGray(p=0.01), CLAHE(p=0.01, clip_limit=(1, 4.0), tile_grid_size=(8, 8)) val: Scanning /content/drive/MyDrive/ultralytics-main/datasets/xView/labels/train... 0 images, 86 backgrounds, 0 corrupt: 100%|██████████| 86/86 [00:41<00:00, 2.07it/s]val: WARNING ⚠️ No labels found in /content/drive/MyDrive/ultralytics-main/datasets/xView/labels/train.cache. See https://docs.ultralytics.com/datasets for dataset formatting guidance. val: New cache created: /content/drive/MyDrive/ultralytics-main/datasets/xView/labels/train.cache WARNING ⚠️ No labels found in /content/drive/MyDrive/ultralytics-main/datasets/xView/labels/train.cache, training may not work correctly. See https://docs.ultralytics.com/datasets for dataset formatting guidance.
Plotting labels to runs/detect/train28/labels.jpg... zero-size array to reduction operation maximum which has no identity optimizer: 'optimizer=auto' found, ignoring 'lr0=0.01' and 'momentum=0.937' and determining best 'optimizer', 'lr0' and 'momentum' automatically... optimizer: AdamW(lr=0.000156, momentum=0.9) with parameter groups 57 weight(decay=0.0), 64 weight(decay=0.0005), 63 bias(decay=0.0) TensorBoard: model graph visualization added ✅ Image sizes 640 train, 640 val Using 0 dataloader workers Logging results to runs/detect/train28 Starting training for 100 epochs...
Epoch GPU_mem box_loss cls_loss dfl_loss Instances Size- Glenn JocherUltralytics
@Mahmoud-owais it looks like the issue is related to corrupt image files and missing labels in your dataset. The warnings indicate that some images in your training set are not being recognized, and no labels were found in the specified directory. Please ensure that your dataset is correctly formatted and that all necessary label files are present. You can refer to the Ultralytics dataset documentation for detailed guidance on proper dataset formatting. Additionally, make sure to check if the issue persists with the latest version of the Ultralytics package.
1
goodbbboy
hello,I want to split original xView images with high-resolution into images with 800x800 resolution in multiscale way as DOTA, how should I modify "ultralytics/data/split_dota.py"? Now I have the .txt labels of xView by default YOLOv8 code, but their format is different from DOTA's txt file. Thanks a lot!!!
- Glenn JocherUltralytics(تم التعديل)
@goodbbboy hello!
To split the original xView images into 800x800 resolution tiles similar to the DOTA dataset, you'll need to modify the
ultralytics/data/split_dota.pyscript to handle the xView dataset format. Here are some steps to guide you through the process:-
Modify the Splitting Logic: Adjust the script to read the xView images and split them into 800x800 tiles. Ensure that the splitting logic handles the overlap and edge cases properly.
-
Adjust Label Conversion: Since the xView labels are in a different format, you'll need to convert them to match the DOTA format. This involves parsing the xView
.txtlabels and transforming them into the required format.
Here's a basic example to get you started:
import os from PIL import Image import numpy as np def split_image(image_path, output_dir, tile_size=800, overlap=200): image = Image.open(image_path) image_name = os.path.basename(image_path).split('.')[0] width, height = image.size for i in range(0, width, tile_size - overlap): for j in range(0, height, tile_size - overlap): box = (i, j, i + tile_size, j + tile_size) tile = image.crop(box) tile.save(os.path.join(output_dir, f"{image_name}_{i}_{j}.png")) def convert_labels(xview_label_path, output_dir, tile_size=800, overlap=200): with open(xview_label_path, 'r') as file: lines = file.readlines() for line in lines: # Parse the xView label format and convert to DOTA format # This is a placeholder; you'll need to implement the actual conversion logic pass # Example usage split_image('path/to/xview/image.tif', 'output/tiles') convert_labels('path/to/xview/label.txt', 'output/labels')- Integrate with Ultralytics YOLO: Ensure that the modified script integrates well with the Ultralytics YOLO training pipeline. You might need to adjust the dataset YAML file to point to the new split images and labels.
For more detailed guidance on creating a minimum reproducible example, please refer to our Minimum Reproducible Example documentation. Additionally, make sure you are using the latest version of the Ultralytics packages to benefit from the latest features and bug fixes.
Feel free to reach out if you have any further questions. Happy coding! 🚀
-
vonzo
Hello, the dataset is not being downloaded automaticaly when
yolo detect train data=xView.yaml model=yolov8n.pt epochs=100 imgsz=640I get
set 'xView.yaml' images not found ⚠️, missing path '/home/ltu-builder/GIT/datasets/xView/images/autosplit_val.txt'
Traceback (most recent call last):
  File "/home/ltu-builder/miniconda3/lib/python3.11/site-packages/ultralytics/engine/trainer.py", line 514, in get_dataset
    data = check_det_dataset(self.args.data)
           ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
  File "/home/ltu-builder/miniconda3/lib/python3.11/site-packages/ultralytics/data/utils.py", line 338, in check_det_dataset
    exec(s, {"yaml": data})
  File "<string>", line 63, in <module>
  File "<string>", line 16, in convert_labels
FileNotFoundError: [Errno 2] No such file or directory: '/home/ltu-builder/GIT/datasets/xView/xView_train.geojson'

The above exception was the direct cause of the following exception:

Traceback (most recent call last):
  File "/home/ltu-builder/miniconda3/bin/yolo", line 8, in <module>
    sys.exit(entrypoint())
             ^^^^^^^^^^^^
  File "/home/ltu-builder/miniconda3/lib/python3.11/site-packages/ultralytics/cfg/__init__.py", line 582, in entrypoint
    getattr(model, mode)(**overrides)  # default args from model
    ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
  File "/home/ltu-builder/miniconda3/lib/python3.11/site-packages/ultralytics/engine/model.py", line 649, in train
    self.trainer = (trainer or self._smart_load("trainer"))(overrides=args, _callbacks=self.callbacks)
                   ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
  File "/home/ltu-builder/miniconda3/lib/python3.11/site-packages/ultralytics/engine/trainer.py", line 129, in __init__
    self.trainset, self.testset = self.get_dataset()
                                  ^^^^^^^^^^^^^^^^^^
  File "/home/ltu-builder/miniconda3/lib/python3.11/site-packages/ultralytics/engine/trainer.py", line 518, in get_dataset
    raise RuntimeError(emojis(f"Dataset '{clean_url(self.args.data)}' error ❌ {e}")) from e
RuntimeError: Dataset 'xView.yaml' error ❌ [Errno 2] No such file or directory: '/home/ltu-builder/GIT/datasets/xView/xView_train.geojson'
Can I force dowload? or do it by hand?
- Paula DerrengerUltralytics
Hello! 👋 It looks like you're encountering an issue with the automatic download of the xView dataset. The xView dataset requires manual downloading due to its size and licensing.
For this dataset, you need to:
- Visit the xView dataset website and download the dataset files manually.
- Follow the instructions for downloading
train_images.zipandval_images.zip. - Unzip these files under
'datasets/xView'relative to your working directory.
After downloading and organizing the dataset, your file structure should look something like this:
ultralytics/
└── datasets/
    └── xView/
        ├── train_images/
        └── val_images/
Make sure to place
xView.yamlcorrectly in your project, specifying this file structure.If you have further issues or questions, feel free to ask. Happy training! 🚀