YOLOv10: Real-Time End-to-End Object Detection#
YOLOv10, released in May 2024 and built on the Ultralytics Python package by researchers at Tsinghua University, introduces a new approach to real-time object detection, addressing both the post-processing and model architecture deficiencies found in previous YOLO versions. By eliminating non-maximum suppression (NMS) and optimizing various model components, YOLOv10 achieved strong performance with significantly reduced computational overhead at its time of release. Its NMS-free end-to-end design pioneered an approach that has been further developed in YOLO26.
Watch: How to Train YOLOv10 on SKU-110k Dataset using Ultralytics | Retail Dataset
Overview#
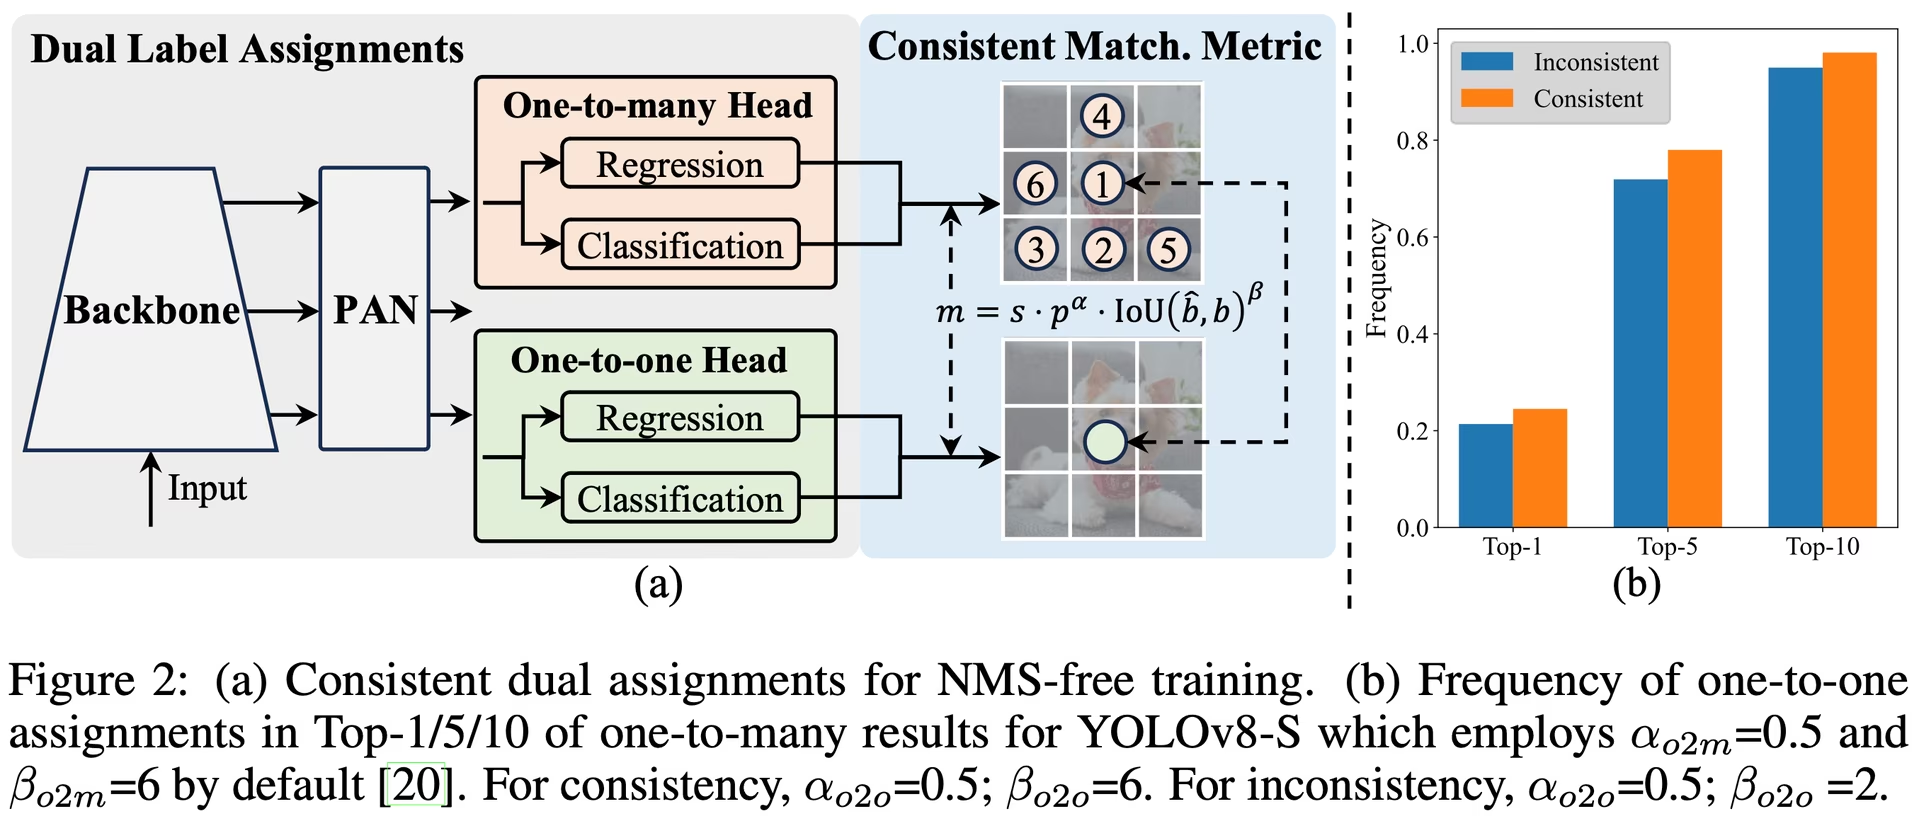
Real-time object detection aims to accurately predict object categories and positions in images with low latency. The YOLO series has been at the forefront of this research due to its balance between performance and efficiency. However, reliance on NMS and architectural inefficiencies have hindered optimal performance. YOLOv10 addresses these issues by introducing consistent dual assignments for NMS-free training and a holistic efficiency-accuracy driven model design strategy.
Architecture#
The architecture of YOLOv10 builds upon the strengths of previous YOLO models while introducing several key innovations. The model architecture consists of the following components:
- Backbone: Responsible for feature extraction, the backbone in YOLOv10 uses an enhanced version of CSPNet (Cross Stage Partial Network) to improve gradient flow and reduce computational redundancy.
- Neck: The neck is designed to aggregate features from different scales and passes them to the head. It includes PAN (Path Aggregation Network) layers for effective multiscale feature fusion.
- One-to-Many Head: Generates multiple predictions per object during training to provide rich supervisory signals and improve learning accuracy.
- One-to-One Head: Generates a single best prediction per object during inference to eliminate the need for NMS, thereby reducing latency and improving efficiency.
Key Features#
- NMS-Free Training: Utilizes consistent dual assignments to eliminate the need for NMS, reducing inference latency.
- Holistic Model Design: Comprehensive optimization of various components from both efficiency and accuracy perspectives, including lightweight classification heads, spatial-channel decoupled downsampling, and rank-guided block design.
- Enhanced Model Capabilities: Incorporates large-kernel convolutions and partial self-attention modules to improve performance without significant computational cost.
Model Variants#
YOLOv10 comes in various model scales to cater to different application needs:
- YOLOv10n: Nano version for extremely resource-constrained environments.
- YOLOv10s: Small version balancing speed and accuracy.
- YOLOv10m: Medium version for general-purpose use.
- YOLOv10b: Balanced version with increased width for higher accuracy.
- YOLOv10l: Large version for higher accuracy at the cost of increased computational resources.
- YOLOv10x: Extra-large version for maximum accuracy and performance.
Performance#
At release, YOLOv10 outperformed previous YOLO versions and other state-of-the-art models in accuracy and efficiency. For example, YOLOv10s is 1.8x faster than RT-DETR-R18 with similar AP on the COCO dataset, and YOLOv10b has 46% less latency and 25% fewer parameters than YOLOv9-C with the same performance.
Latency measured with TensorRT FP16 on T4 GPU.
| Model | Input Size | APval50-95 | FLOPs (G) | Latency (ms) |
|---|---|---|---|---|
| [YOLOv10n][1] | 640 | 38.5 | 6.7 | 1.84 |
| [YOLOv10s][2] | 640 | 46.3 | 21.6 | 2.49 |
| [YOLOv10m][3] | 640 | 51.1 | 59.1 | 4.74 |
| [YOLOv10b][4] | 640 | 52.5 | 92.0 | 5.74 |
| [YOLOv10l][5] | 640 | 53.2 | 120.3 | 7.28 |
| [YOLOv10x][6] | 640 | 54.4 | 160.4 | 10.70 |
Methodology#
Consistent Dual Assignments for NMS-Free Training#
YOLOv10 employs dual label assignments, combining one-to-many and one-to-one strategies during training to ensure rich supervision and efficient end-to-end deployment. Ultralytics prediction and validation default to the one-to-many head with NMS; set nms=False to select the NMS-free head. The consistent matching metric aligns the supervision between both strategies, enhancing the quality of predictions during inference.
Holistic Efficiency-Accuracy Driven Model Design#
Efficiency Enhancements#
- Lightweight Classification Head: Reduces the computational overhead of the classification head by using depth-wise separable convolutions.
- Spatial-Channel Decoupled Downsampling: Decouples spatial reduction and channel modulation to minimize information loss and computational cost.
- Rank-Guided Block Design: Adapts block design based on intrinsic stage redundancy, ensuring optimal parameter utilization.
Accuracy Enhancements#
- Large-Kernel Convolution: Enlarges the receptive field to enhance feature extraction capability.
- Partial Self-Attention (PSA): Incorporates self-attention modules to improve global representation learning with minimal overhead.
Experiments and Results#
YOLOv10 was evaluated on standard benchmarks such as COCO. At release, every variant improved the latency-accuracy trade-off compared to previous YOLO versions and other contemporary detectors.
Comparisons#
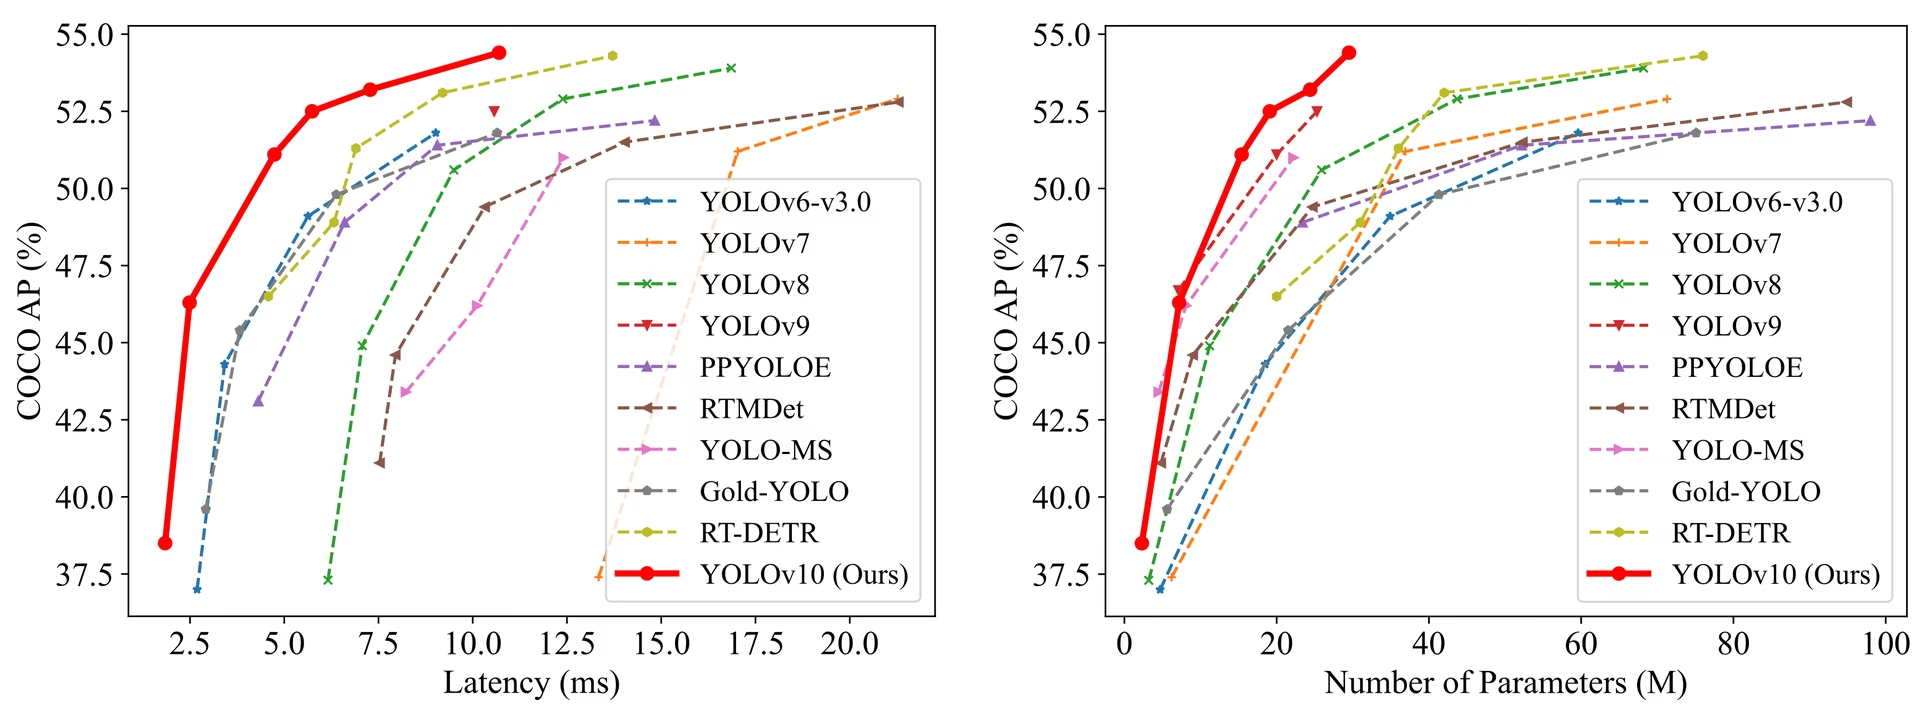
Compared to other state-of-the-art detectors:
- YOLOv10s / x are 1.8× / 1.3× faster than RT-DETR-R18 / R101 with similar accuracy
- YOLOv10b has 25% fewer parameters and 46% lower latency than YOLOv9-C at same accuracy
- YOLOv10l / x outperform YOLOv8l / x by 0.3 AP / 0.5 AP with 1.8× / 2.3× fewer parameters
Figures below are as reported in the YOLOv10 paper, measured under its own protocol, so they are not directly comparable with the values on Ultralytics model pages:
| Model | Params (M) | FLOPs (G) | mAPval50-95 | Latency (ms) | Latency-forward (ms) |
|---|---|---|---|---|---|
| YOLOv6-3.0-N | 4.7 | 11.4 | 37.0 | 2.69 | 1.76 |
| Gold-YOLO-N | 5.6 | 12.1 | 39.6 | 2.92 | 1.82 |
| YOLOv8n | 3.2 | 8.7 | 37.3 | 6.16 | 1.77 |
| YOLOv10n | 2.3 | 6.7 | 38.5 | 1.84 | 1.79 |
| YOLOv6-3.0-S | 18.5 | 45.3 | 44.3 | 3.42 | 2.35 |
| Gold-YOLO-S | 21.5 | 46.0 | 45.4 | 3.82 | 2.73 |
| YOLOv8s | 11.2 | 28.6 | 44.9 | 7.07 | 2.33 |
| YOLOv10s | 7.2 | 21.6 | 46.3 | 2.49 | 2.39 |
| RT-DETR-R18 | 20.0 | 60.0 | 46.5 | 4.58 | 4.49 |
| YOLOv6-3.0-M | 34.9 | 85.8 | 49.1 | 5.63 | 4.56 |
| Gold-YOLO-M | 41.3 | 87.5 | 49.8 | 6.38 | 5.45 |
| YOLOv8m | 25.9 | 78.9 | 50.6 | 9.50 | 5.09 |
| YOLOv10m | 15.4 | 59.1 | 51.1 | 4.74 | 4.63 |
| YOLOv6-3.0-L | 59.6 | 150.7 | 51.8 | 9.02 | 7.90 |
| Gold-YOLO-L | 75.1 | 151.7 | 51.8 | 10.65 | 9.78 |
| YOLOv8l | 43.7 | 165.2 | 52.9 | 12.39 | 8.06 |
| RT-DETR-R50 | 42.0 | 136.0 | 53.1 | 9.20 | 9.07 |
| YOLOv10l | 24.4 | 120.3 | 53.2 | 7.28 | 7.21 |
| YOLOv8x | 68.2 | 257.8 | 53.9 | 16.86 | 12.83 |
| RT-DETR-R101 | 76.0 | 259.0 | 54.3 | 13.71 | 13.58 |
| YOLOv10x | 29.5 | 160.4 | 54.4 | 10.70 | 10.60 |
Params and FLOPs values are for the fused model after model.fuse(), which merges Conv and BatchNorm layers and removes the auxiliary one-to-many detection head. Pretrained checkpoints retain the full training architecture and may show higher counts.
Usage Examples#
Models can also be trained on cloud GPUs through Ultralytics Platform. To predict on new images with YOLOv10:
from ultralytics import YOLO

# Load a pretrained YOLOv10n model
model = YOLO("yolov10n.pt")

# Perform object detection on an image
results = model("image.jpg")

# Display the results
results[0].show()
For training YOLOv10 on a custom dataset:
from ultralytics import YOLO

# Load YOLOv10n model from scratch
model = YOLO("yolov10n.yaml")

# Train the model
model.train(data="coco8.yaml", epochs=100, imgsz=640)
Supported Tasks and Modes#
The YOLOv10 model series offers a range of models, each optimized for object detection. The variants cover a range of computational budgets and accuracy requirements.
| Model | Filenames | Tasks | Training | Validation | Inference | Export |
|---|---|---|---|---|---|---|
| YOLOv10 | yolov10n.pt yolov10s.pt yolov10m.pt yolov10b.pt yolov10l.pt yolov10x.pt | Object Detection | ✅ | ✅ | ✅ | ✅ |
Exporting YOLOv10#
Due to the new operations introduced with YOLOv10, not all export formats provided by Ultralytics are currently supported. The following table lists the formats that Ultralytics has successfully converted for YOLOv10. Pull requests that add export support for additional formats are welcome.
| Export Format | Export Support | Exported Model Inference | Notes |
|---|---|---|---|
| TorchScript | ✅ | ✅ | Standard PyTorch model format. |
| ONNX | ✅ | ✅ | Widely supported for deployment. |
| OpenVINO | ✅ | ✅ | Optimized for Intel hardware. |
| TensorRT | ✅ | ✅ | Optimized for NVIDIA GPUs. |
| CoreML | ✅ | ✅ | Limited to Apple devices. |
| TF SavedModel | ✅ | ✅ | TensorFlow's standard model format. |
| TF GraphDef | ✅ | ✅ | Legacy TensorFlow format. |
| TF Edge TPU | ✅ | ✅ | Specific to Google's Edge TPU devices. |
| LiteRT | ✅ | ✅ | Optimized for mobile, embedded, and browser (LiteRT.js). |
| PaddlePaddle | ✅ | ✅ | Popular in China; less global support. |
| NCNN | ✅ | ✅ | Optimized for mobile and embedded devices. |
Conclusion#
At its release, YOLOv10 advanced real-time object detection by removing NMS post-processing and redesigning model components for both efficiency and accuracy. Its NMS-free approach pioneered end-to-end object detection in the YOLO family. YOLO26, the latest Ultralytics model, builds on this with improved performance and NMS-free inference.
Citations and Acknowledgments#
We would like to acknowledge the YOLOv10 authors from Tsinghua University for their extensive research and significant contributions to the Ultralytics framework:
@inproceedings{wang2024yolov10,
  title={YOLOv10: Real-Time End-to-End Object Detection},
  author={Wang, Ao and Chen, Hui and Liu, Lihao and Chen, Kai and Lin, Zijia and Han, Jungong and Ding, Guiguang},
  booktitle={Advances in Neural Information Processing Systems},
  doi = {10.52202/079017-3429},
  url = {https://proceedings.neurips.cc/paper_files/paper/2024/file/c34ddd05eb089991f06f3c5dc36836e0-Paper-Conference.pdf},
  volume={37},
  pages={107984--108011},
  year={2024}
}
For detailed implementation, architectural innovations, and experimental results, please refer to the YOLOv10 research paper and GitHub repository by the Tsinghua University team.
FAQ#
YOLOv10, developed by researchers at Tsinghua University, introduces several key innovations to real-time object detection. It eliminates the need for non-maximum suppression (NMS) by employing consistent dual assignments during training, and optimizes model components to reduce computational overhead.
Run inference with the Ultralytics Python API or the command line interface (CLI). Below are examples of predicting on new images with YOLOv10:
Examplefrom ultralytics import YOLO # Load the pretrained YOLOv10n model model = YOLO("yolov10n.pt") results = model("image.jpg") results[0].show()For more usage examples, visit our Usage Examples section.
YOLOv10 offers several model variants to cater to different use cases:
- YOLOv10n: Suitable for extremely resource-constrained environments
- YOLOv10s: Balances speed and accuracy
- YOLOv10m: General-purpose use
- YOLOv10b: Higher accuracy with increased width
- YOLOv10l: High accuracy at the cost of computational resources
- YOLOv10x: Maximum accuracy and performance
Each variant is designed for different computational needs and accuracy requirements, making them versatile for a variety of applications. Explore the Model Variants section for more information.
YOLOv10 trains with consistent dual assignments so that its one-to-one head produces a single best prediction per object, which removes the need for non-maximum suppression (NMS) at inference. Ultralytics prediction and validation default to the one-to-many head with NMS; set
nms=Falseto select the NMS-free head and drop the NMS pass. For a detailed explanation, see the Consistent Dual Assignments for NMS-Free Training section.YOLOv10 supports several export formats, including TorchScript, ONNX, OpenVINO, and TensorRT. However, not all export formats provided by Ultralytics are currently supported for YOLOv10 due to its new operations. For details on the supported formats and instructions on exporting, visit the Exporting YOLOv10 section.
At release, YOLOv10 outperformed previous YOLO versions and other state-of-the-art models in both accuracy and efficiency. For example, YOLOv10s is 1.8x faster than RT-DETR-R18 with a similar AP on the COCO dataset. YOLOv10b shows 46% less latency and 25% fewer parameters than YOLOv9-C with the same performance. Detailed benchmarks can be found in the Comparisons section.
Comments188
Ask a question, share your results, or help someone else.
 Glenn JocherUltralytics(edited)
I'm super excited about the groundbreaking work on YOLOv10 by the researchers at Tsinghua University. Just a week ago, @pderrenger and I had the privilege of presenting YOLO to ML graduate students at Tsinghua University in Shenzhen, and I was thoroughly impressed by their enthusiasm and expertise.
Now, seeing the remarkable advancements in real-time object detection with YOLOv10, I'm thrilled to collaborate with the Tsinghua team to officially bring YOLOv10 support to the Ultralytics Python package soon. The innovative approach to NMS-free training and holistic model design optimizations demonstrates their commitment to pushing the boundaries of what's possible.
Stay tuned for the official release of YOLOv10 support in the Ultralytics package, and get ready to experience the incredible capabilities of this revolutionary real-time object detector!
38jameslahm
Thank you so much for your great support for YOLOv10! We are truly grateful for your efforts to bring YOLOv10 to the Ultralytics package. ❤️
2
heynewyeah
您好。如果我想在训练结束后,以last.pt的模型权重继续训练(因为还未收敛),有什么办法能获取last epoch的优化器状态吗,用于继续训练。或者有什么其他方法能够完成继续训练吗?
alephpi(edited)
from ultralytics import YOLO

# Load a model
model = YOLO("path/to/last.pt")  # load a partially trained model

# Resume training
results = model.train(resume=True)
Anser1
Hello, I'm sorry to disturb you. I want to conduct the training for the segmentation task based on YOLOv10, but I found that there seems to be no YAML structure file for the segmentation model. What should I do?
zlj127
Does YOLOv10 have the pose function? Currently, I have only found a pre-trained model for gestures under the GitHub of the Hagrid dataset, but it is still used for detection.
- Glenn JocherUltralytics(edited)
@zlj127 YOLOv10 currently focuses on object detection tasks and does not include built-in pose estimation functionality. For pose/keypoint estimation, we recommend using YOLO26 which offers integrated support for pose estimation along with detection, segmentation, and classification. See the YOLO26 Pose documentation for implementation details and code examples.
ok,thank you
- Glenn JocherUltralytics(edited)
@zlj127 you're welcome! For pose estimation tasks, we recommend using YOLO26 which offers integrated support. Let us know if you need help getting started with the Pose documentation.
gniqeh
It is important to configure the correct threshold of dual label assignments in the paper. But how can we change the threshold in yolov10 of ultralytics module?
Es importante configurar el umbral correcto de asignaciones de etiquetas duales en el documento. pero ¿cómo podemos cambiar el umbral en yolov10 del módulo ultralytics?
- Glenn JocherUltralytics(edited)
@gniqeh the dual label assignment settings are not exposed in the model YAML or as training arguments. They are set in the loss code (
E2EDetectLossinultralytics/utils/loss.py), where the one-to-many branch usestal_topk=10and the one-to-one branch usestal_topk=1. To change them, edit those values in a local copy of the package. For details, see the YOLOv10 Ultralytics documentation. Let us know if you need further clarification! Thx for your reply my friend, I have checked the documentation and API ref. of yolov10 but there is only the basical introductiong about it. And i am pleasure if u can provide further implementation explaining. Thanks again!
- Glenn JocherUltralytics
Thank you for your feedback! For a deeper understanding of YOLOv10 implementation, you can explore the specifics of its architecture and features in the YOLOv10 documentation. If you have particular aspects or technical details you'd like clarified, feel free to let us know!
Ly2003ykjy
Are YOLOV10 and 11 really superior to v7 and v8 in small target detection?
- Glenn JocherUltralytics
YOLOv10 and YOLO11 introduce innovations like NMS-free training, which can enhance small target detection performance compared to YOLOv7 and YOLOv8, but results may vary based on specific use cases and datasets.
abaldanz
Hello, do you plan to provide weights for the pre-trained model on 1280p size images?
- Glenn JocherUltralytics
@abaldanz thank you for your interest. Currently, we don't have plans to provide pre-trained weights specifically for 1280p images. For updates, please keep an eye on our repository and documentation.
Yuwenliula
请问一下,yolov10是否内置了IOU计算的功能,在val结果中未见到IOU的输出,如果没有的话,能方便提供代码进行IOU计算吗?
- Glenn JocherUltralytics
@Yuwenliula yOLOv10 does not directly output IoU in validation results. You can calculate IoU using the bounding box coordinates from the model's predictions. If you need further assistance, please refer to the Ultralytics documentation for guidance.
qruiwu
what is the each parameter mean in results.csv after training a model?
- Glenn JocherUltralytics
@wuqrcn the
results.csvfile contains metrics such as precision, recall, mAP, and loss values for each epoch during training. These metrics help evaluate the model's performance and convergence. For more details, please refer to the documentation.
alifazeli00
Why do the weights uploaded here: https://github.com/THU-MIG/yolov10?tab=readme-ov-file#performance not give the same results on the dataset as the weights uploaded on Ultralytics? I checked their architectures, and they seem to be identical.
- Glenn JocherUltralytics
@alifazeli00 the difference in results might be due to variations in training data, hyperparameters, or preprocessing steps. Ensure both models are evaluated under identical conditions for accurate comparison.
They are all the same except for the val_period parameter, which is only present in the THU-MIG model. However, the Ultralytics model performs better. I tested x and noticed differences in the weights. Are you saying that these two models should produce identical results?
- Glenn JocherUltralytics
The differences in results could be due to variations in training data, hyperparameters, or preprocessing steps. Ensure both models are evaluated under identical conditions for accurate comparison.
-1