YOLO26-Modelle in das TFLite-Edge-TPU-Format exportieren
Die Bereitstellung von Computer-Vision-Modellen auf Geräten mit begrenzter Rechenleistung, etwa mobilen oder eingebetteten Systemen, kann knifflig sein. Ein für höhere Leistung optimiertes Modellformat vereinfacht diesen Prozess. Das Modellformat TensorFlow Lite Edge TPU oder TFLite Edge TPU ist darauf ausgelegt, neuronale Netze bei geringem Energieverbrauch schnell auszuführen.
Beim Export in das TFLite-Edge-TPU-Format kannst du deine Ultralytics YOLO26-Modelle für schnelle Inferenz bei geringem Energieverbrauch optimieren. In diesem Leitfaden zeigen wir dir, wie du deine Modelle in das TFLite-Edge-TPU-Format konvertierst, damit sie auf verschiedenen mobilen und eingebetteten Geräten leichter gute Leistung erzielen.
Warum solltest du in das TFLite-Edge-TPU-Format exportieren?#
Der Export von Modellen für TensorFlow Edge TPU macht Aufgaben des maschinellen Lernens schnell und effizient. Diese Technologie eignet sich für Anwendungen mit begrenzter Energieversorgung, Rechenleistung und Konnektivität. Die Edge TPU ist Googles Edge-Version des Hardwarebeschleunigers Tensor Processing Unit (TPU). Sie beschleunigt TensorFlow Lite-Modelle auf Edge-Geräten. Das Bild unten zeigt ein Beispiel des zugehörigen Ablaufs.
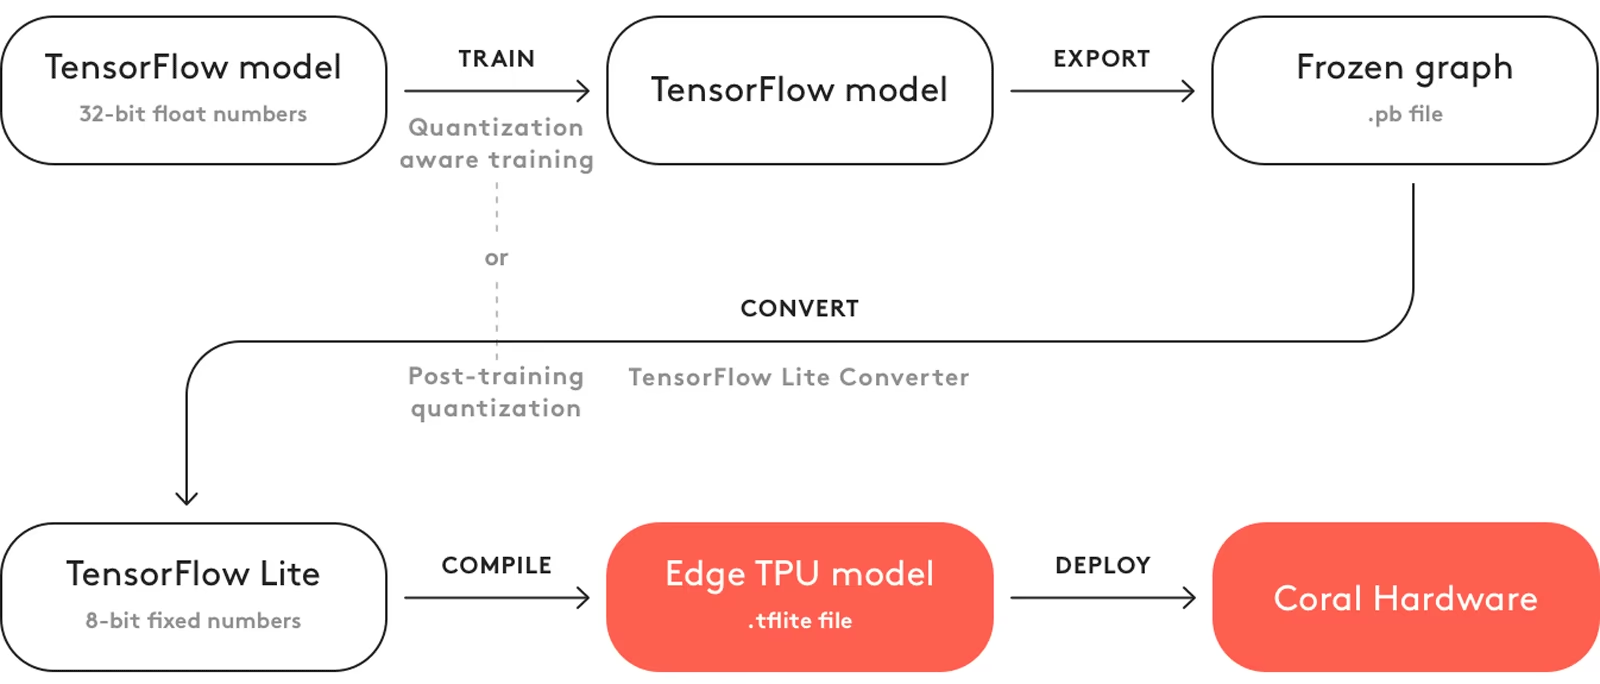
Die Edge TPU unterstützt quantisierte Modelle. Durch Quantisierung werden Modelle kleiner und schneller, ohne dass viel Genauigkeit verloren geht. Das ist ideal für die begrenzten Ressourcen des Edge-Computings: Anwendungen können schnell reagieren, weil die Latenz sinkt und Daten lokal zügig verarbeitet werden, ohne auf die Cloud angewiesen zu sein. Die lokale Verarbeitung schützt außerdem die Privatsphäre und Sicherheit der Nutzerdaten, da sie nicht an einen entfernten Server gesendet werden.
Wichtige Merkmale von TFLite Edge TPU#
Hier sind die wichtigsten Funktionen, die TFLite Edge TPU für Entwickler zu einer überzeugenden Wahl für ein Modellformat machen:
-
Optimierte Leistung auf Edge-Geräten: TFLite Edge TPU ermöglicht schnelle Inferenz neuronaler Netze durch Quantisierung, Modelloptimierung, Hardwarebeschleunigung und Compileroptimierung. Die minimalistische Architektur trägt zu geringerer Größe und Kosteneffizienz bei.
-
Hoher Rechendurchsatz: TFLite Edge TPU kombiniert spezialisierte Hardwarebeschleunigung mit effizienter Laufzeitausführung und erreicht so einen hohen Rechendurchsatz. Die Lösung eignet sich gut für die Bereitstellung von Machine-Learning-Modellen mit strengen Leistungsanforderungen auf Edge-Geräten.
-
Effiziente Matrixberechnungen: Die TensorFlow Edge TPU ist für Matrixoperationen optimiert, die für Berechnungen in neuronalen Netzen entscheidend sind. Diese Effizienz ist bei Machine-Learning-Modellen besonders wichtig, vor allem bei Modellen, die zahlreiche komplexe Matrixmultiplikationen und -transformationen erfordern.
Bereitstellungsoptionen für TFLite Edge TPU#
Bevor du YOLO26-Modelle in das TFLite-Edge-TPU-Format exportierst, solltest du wissen, wo diese Modelle üblicherweise eingesetzt werden.
TFLite Edge TPU bietet verschiedene Bereitstellungsoptionen für Machine-Learning-Modelle, darunter:
-
Bereitstellung auf dem Gerät: TensorFlow-Edge-TPU-Modelle lassen sich direkt auf Mobil- und eingebetteten Geräten bereitstellen. Bei der Bereitstellung auf dem Gerät werden die Modelle direkt auf der Hardware ausgeführt, sodass keine Cloud-Verbindung erforderlich ist. Dazu wird das Modell entweder in das Anwendungspaket eingebettet oder bei Bedarf heruntergeladen.
-
Hybride Bereitstellung: Ein hybrider Ansatz kombiniert die Bereitstellung auf dem Gerät mit der Bereitstellung in der Cloud und bietet eine vielseitige, skalierbare Lösung für Machine-Learning-Modelle. Zu den Vorteilen gehören die Verarbeitung auf dem Gerät für schnelle Reaktionen und Cloud Computing für komplexere Berechnungen.
Unterstützte Aufgaben#
Der Export auf Edge TPU unterstützt sechs der sieben Ultralytics-Aufgaben. Die semantische Segmentierung ist nur mit YOLO26 verfügbar, der einzigen Modellfamilie mit diesem Kopf. Die Tiefenschätzung wird nicht unterstützt, da das INT8-Modell den Operator EXP v2 ausgibt, den der Edge-TPU-Compiler nicht analysieren kann.
| Aufgabe | YOLOv8 | YOLO11 | YOLO26 |
|---|---|---|---|
| Erkennung | ✅ | ✅ | ✅ |
| Segmentierung | ✅ | ✅ | ✅ |
| Semantik | ❌ | ❌ | ✅ |
| Tiefe | ❌ | ❌ | ❌ |
| Klassifizierung | ✅ | ✅ | ✅ |
| Pose | ✅ | ✅ | ✅ |
| OBB | ✅ | ✅ | ✅ |
Der Edge-TPU-Compiler ordnet die unterstützten Operationen dem Beschleuniger zu und führt die übrigen auf der CPU aus. Die Unterstützung einer Aufgabe bedeutet also nicht, dass jede Operation auf der TPU ausgeführt wird.
YOLO26-Modelle in das TFLite-Edge-TPU-Format exportieren#
Du kannst die Modellkompatibilität und Bereitstellungsflexibilität erweitern, indem du YOLO26-Modelle in TensorFlow Edge TPU umwandelst.
Installation#
Führe zum Installieren des erforderlichen Pakets Folgendes aus:
# Install the required package for YOLO26
pip install ultralytics
Ausführliche Anweisungen und bewährte Vorgehensweisen zur Installation findest du in unserer Installationsanleitung von Ultralytics. Falls bei der Installation der für YOLO26 erforderlichen Pakete Probleme auftreten, findest du Lösungen und Tipps in unserer Anleitung zu häufigen Problemen.
Verwendung#
Alle Ultralytics YOLO26-Modelle sind so ausgelegt, dass sie sofort exportiert werden können. Dadurch lassen sie sich problemlos in deinen bevorzugten Bereitstellungsablauf integrieren. In der vollständigen Liste der unterstützten Exportformate und Konfigurationsoptionen findest du die passende Konfiguration für deine Anwendung.
Das TFLite-Edge-TPU-Format unterstützt die Modi Export, Predict und Validate. Inferenz und Validierung werden auf Coral-Edge-TPU-Hardware ausgeführt. Exportiere dein Modell und lade anschließend das exportierte Modell, um Inferenz auszuführen oder seine Genauigkeit zu validieren.
from ultralytics import YOLO

# Ein YOLO26-Modell laden
model = YOLO("yolo26n.pt")

# Modell in das TFLite-Edge-TPU-Format exportieren
model.export(format="edgetpu") # creates 'yolo26n_saved_model/yolo26n_full_integer_quant_edgetpu.tflite'from ultralytics import YOLO
# Exportiertes TFLite-Edge-TPU-Modell laden
model = YOLO("yolo26n_saved_model/yolo26n_full_integer_quant_edgetpu.tflite")
# Inferenz ausführen
results = model("https://ultralytics.com/images/bus.jpg")from ultralytics import YOLO
# Exportiertes TFLite-Edge-TPU-Modell laden
model = YOLO("yolo26n_saved_model/yolo26n_full_integer_quant_edgetpu.tflite")
# Die Genauigkeit anhand des COCO8-Datensatzes validieren
metrics = model.val(data="coco8.yaml")Exportargumente#
| Argument | Typ | Standard | Beschreibung |
|---|---|---|---|
format | str | 'edgetpu' | Zielformat des exportierten Modells, das die Kompatibilität mit verschiedenen Bereitstellungsumgebungen festlegt. |
imgsz | int oder tuple | 640 | Gewünschte Bildgröße für die Modelleingabe. Kann eine Ganzzahl für quadratische Bilder oder ein Tupel (height, width) für bestimmte Abmessungen sein. |
quantize | int oder str | 8/automatisch | Quantisierungsgenauigkeit. 8 (INT8) ist für Edge TPU erforderlich und wird automatisch aktiviert. Dadurch wird das Modell komprimiert und die Inferenz auf Edge-Geräten bei minimalem Genauigkeitsverlust beschleunigt. Ersetzt die veralteten Flags half/int8. |
opset | int | None | Gibt die ONNX-opset-Version für den Zwischen-ONNX-Graphen an. Wenn nicht angegeben, wird opset 18 verwendet (niedriger bei PyTorch < 2.4), höchstens jedoch die installierte Version onnx. |
data | str | None | Pfad zur YAML-Datei des Datensatzes, die für die Quantisierung erforderlich ist; bei der Klassifizierung wird stattdessen ein Datensatzverzeichnis oder der Name eines integrierten Datensatzes verwendet. Wenn quantize=8 nicht angegeben ist, wählt Ultralytics den Standard-Kalibrierungsdatensatz für die jeweilige Modellaufgabe aus. |
fraction | float, int oder list | 1.0 | Kalibrierungsteilstichprobe als Verhältnis, Bildanzahl oder [train, val, test]-Verhältnisse/-Anzahlen. Bei Listen mit zwei Elementen bleibt test vollständig erhalten, während 0 es überspringt. |
device | str | None | Gibt das Gerät für den Export an: CPU (device=cpu). |
Verwende beim Export für Edge TPU einen x86-Linux-Rechner.
Weitere Informationen zum Exportvorgang findest du auf der Ultralytics-Dokumentationsseite zum Export.
Exportierte YOLO26-TFLite-Edge-TPU-Modelle bereitstellen#
Nachdem du deine Ultralytics YOLO26-Modelle erfolgreich in das TFLite-Edge-TPU-Format exportiert hast, kannst du sie bereitstellen. Als ersten und empfohlenen Schritt zum Ausführen eines TFLite-Edge-TPU-Modells solltest du die Methode YOLO("model_edgetpu.tflite") verwenden, wie im vorherigen Codebeispiel zur Verwendung beschrieben.
Ausführliche Anleitungen zur Bereitstellung deiner TFLite-Edge-TPU-Modelle findest du in den folgenden Ressourcen:
-
Coral Edge TPU auf einem Raspberry Pi mit Ultralytics YOLO26: Erfahre, wie du Coral Edge TPUs mit Raspberry Pi integrierst, um die Machine-Learning-Funktionen zu erweitern.
-
Edge TPU Compiler: Erfahre, wie der Edge TPU-Compiler TensorFlow Lite-Modelle dem Beschleuniger zuordnet und welche Operationen unterstützt werden.
-
Inferenz auf der Edge TPU mit Python ausführen: Erfahre, wie du die TensorFlow-Lite-Python-API für Edge-TPU-Anwendungen verwendest, einschließlich Anleitungen zur Einrichtung und Nutzung.
Zusammenfassung#
In diesem Leitfaden haben wir gezeigt, wie du Ultralytics YOLO26-Modelle in das TFLite-Edge-TPU-Format exportierst. Mit den oben beschriebenen Schritten kannst du deine Computer-Vision-Anwendungen auf Edge-Geräten schneller und mit geringerem Energieverbrauch ausführen.
Weitere Informationen zur Verwendung findest du auf der offiziellen Website von Coral Edge TPU.
Häufig gestellte Fragen#
Führe zum Export eines YOLO26-Modells in das TFLite-Edge-TPU-Format die folgenden Schritte aus:
Verwendungfrom ultralytics import YOLO # Ein YOLO26-Modell laden model = YOLO("yolo26n.pt") # Modell in das TFLite-Edge-TPU-Format exportieren model.export(format="edgetpu") # creates 'yolo26n_saved_model/yolo26n_full_integer_quant_edgetpu.tflite' # Exportiertes TFLite-Edge-TPU-Modell laden edgetpu_model = YOLO("yolo26n_saved_model/yolo26n_full_integer_quant_edgetpu.tflite") # Inferenz ausführen results = edgetpu_model("https://ultralytics.com/images/bus.jpg")Ausführliche Informationen zum Export von Modellen in andere Formate findest du in unserer Exportanleitung.
Der Export von YOLO26-Modellen für TFLite Edge TPU bietet mehrere Vorteile:
- Optimierte Leistung: Erziele eine hohe Geschwindigkeit bei der Ausführung neuronaler Netze und verbrauche dabei nur wenig Energie.
- Geringere Latenz: Verarbeite Daten lokal und schnell, ohne auf die Cloud angewiesen zu sein.
- Mehr Datenschutz: Durch die lokale Verarbeitung bleiben Nutzerdaten privat und sicher.
Das macht das Format ideal für Anwendungen im Edge-Computing, bei denen Geräte nur über begrenzte Energieversorgung und Rechenleistung verfügen.
Ja, TensorFlow-Lite-Edge-TPU-Modelle lassen sich direkt auf Mobil- und eingebetteten Geräten bereitstellen. Bei diesem Ansatz werden die Modelle direkt auf der Hardware ausgeführt, was eine schnellere und effizientere Inferenz ermöglicht. Beispiele für die Integration findest du in unserer Anleitung zur Bereitstellung von Coral Edge TPU auf Raspberry Pi.
Zu den typischen Anwendungsfällen für TFLite-Edge-TPU-Modelle gehören:
- Intelligente Kameras: Echtzeitanalyse von Bildern und Videos verbessern.
- IoT-Geräte: Smart-Home- und Industrieautomatisierung ermöglichen.
- Gesundheitswesen: Medizinische Bildgebung und Diagnostik beschleunigen.
- Einzelhandel: Bestandsverwaltung und Analyse des Kundenverhaltens verbessern.
Diese Anwendungen profitieren von der hohen Leistung und dem geringen Energieverbrauch der TFLite-Edge-TPU-Modelle. Entdecke weitere Anwendungsszenarien.
Wenn beim Export oder bei der Bereitstellung von TFLite-Edge-TPU-Modellen Probleme auftreten, findest du Tipps zur Fehlerbehebung in unserer Anleitung zu häufigen Problemen. Diese Anleitung behandelt typische Probleme und Lösungen, damit du einen reibungslosen Betrieb sicherstellen kannst. Weitere Unterstützung erhältst du in unserem Hilfe-Center.


Kommentare30
Stell eine Frage, teile deine Ergebnisse oder hilf jemand anderem.
faizaanscnz
I am running a float32 TFLite model on Pixel 8a using the GPU. How can I run an Edge TPU model on the hardware to get faster FPS? I’m currently getting 8 FPS, but I need 20+. (Kivy app)
walissong
I would like to know if this tutorial works with yolov8n. I've been trying for many days and I'm not able to convert it to edgetpu.tflite.
dbro
Hello. This seems to be broken for yolo11, although it works for yolov8. After running these two commands in Google colab, the output file is less than 1kb and it generates an error.
! pip install ultralytics ! yolo mode=export model=yolo11n.pt format=edgetpu imgsz=320
The final step to run the EdgeTPU compiler seems to be where the problem is:
... TensorFlow SavedModel: export success ✅ 112.9s, saved as 'yolo11n_saved_model' (33.8 MB)
Edge TPU: starting export with Edge TPU compiler 16.0.384591198... Edge TPU: running 'edgetpu_compiler --out_dir "yolo11n_saved_model" --show_operations --search_delegate --delegate_search_step 30 --timeout_sec 180 "yolo11n_saved_model/yolo11n_full_integer_quant.tflite"' Edge TPU Compiler version 16.0.384591198 Searching for valid delegate with step 30 Try to compile segment with 677 ops ERROR: Didn't find op for builtin opcode 'CONV_2D' version '6'. An older version of this builtin might be supported. Are you using an old TFLite binary with a newer model?
ERROR: Registration failed.
Invalid model: yolo11n_saved_model/yolo11n_full_integer_quant.tflite Model could not be parsed Edge TPU: export success ✅ 0.0s, saved as 'yolo11n_saved_model/yolo11n_full_integer_quant_edgetpu.tflite' (0.0 MB) ...
tomcomtang
I am still studying edge computing(https://edgeone.ai/learning/edge-computing), while you have already delved into a deeper level.
 Glenn JocherUltralytics
@tomcomtang yes, TFLite Edge TPU is designed for optimized performance in edge computing, offering high-speed neural networking with minimal power, reduced latency, and enhanced privacy. For details see the TFLite Edge TPU docs: https://docs.ultralytics.com/integrations/edge-tpu/
manu13008
Hi, Once I exported my best.pt model into edgetpu tflite, I tried to run an inference on an image as the code above but I got the following error :
OSError: libedgetpu.so.1: cannot open shared object file: No such file or directory
Do you have any insights of how resolving this ?
Thanks :)
- Glenn JocherUltralytics
@manu13008 it seems like the error is due to the missing Edge TPU runtime library. Please ensure you have installed the Edge TPU runtime on your device. You can find installation instructions in the Edge TPU documentation. If you need further assistance, feel free to check the resources there.
Abdullah-Ory
Hi friends, i am using google colap to compile yolo11n.pt into edgetpu format, since i have orange pi 5 pro which is arm, so when i am trying to do it in my laptop i got this Ultralytics 8.3.9 🚀 Python-3.10.12 torch-2.4.1+cu121 CPU (Intel Xeon 2.20GHz) YOLO11n summary (fused): 238 layers, 2,616,248 parameters, 0 gradients, 6.5 GFLOPs
PyTorch: starting from '/content/yolo11n.pt' with input shape (1, 3, 640, 640) BCHW and output shape(s) (1, 84, 8400) (5.4 MB)
TensorFlow SavedModel: starting export with tensorflow 2.17.0...
ONNX: starting export with onnx 1.17.0 opset 19... ONNX: slimming with onnxslim 0.1.34... ONNX: export success ✅ 3.0s, saved as '/content/yolo11n.onnx' (10.3 MB) TensorFlow SavedModel: starting TFLite export with onnx2tf 1.22.3...
Automatic generation of each OP name started ======================================== Automatic generation of each OP name complete!
Model loaded ========================================================================
Model conversion started ============================================================ saved_model output started ========================================================== saved_model output complete! Float32 tflite output complete! Float16 tflite output complete! Dynamic Range Quantization tflite output complete! Input signature information for quantization signature_name: serving_default input_name.0: images shape: (1, 640, 640, 3) dtype: <dtype: 'float32'> INT8 Quantization tflite output complete! Full INT8 Quantization tflite output complete! Traceback (most recent call last): File "/usr/local/lib/python3.10/dist-packages/onnx2tf/onnx2tf.py", line 1566, in convert tflite_model = converter.convert() File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/lite.py", line 1231, in wrapper return self._convert_and_export_metrics(convert_func, *args, **kwargs) File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/lite.py", line 1183, in _convert_and_export_metrics result = convert_func(self, *args, **kwargs) File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/lite.py", line 1562, in convert return self._convert_from_saved_model(graph_def) File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/lite.py", line 1424, in _convert_from_saved_model return self._optimize_tflite_model( File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/convert_phase.py", line 215, in wrapper raise error from None # Re-throws the exception. File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/convert_phase.py", line 205, in wrapper return func(*args, **kwargs) File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/lite.py", line 1127, in _optimize_tflite_model model = self._quantize( File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/lite.py", line 767, in _quantize return calibrate_quantize.calibrate_and_quantize( File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/convert_phase.py", line 215, in wrapper raise error from None # Re-throws the exception. File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/convert_phase.py", line 205, in wrapper return func(*args, **kwargs) File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/optimize/calibrator.py", line 194, in calibrate_and_quantize return self._calibrator.QuantizeModel( RuntimeError: Quantized dimension for tensor property and quantization parameters do not match. Got 3 and 0 respectively.
WARNING: INT8 Quantization with int16 activations tflite output failed. Traceback (most recent call last): File "/usr/local/lib/python3.10/dist-packages/onnx2tf/onnx2tf.py", line 1597, in convert tflite_model = converter.convert() File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/lite.py", line 1231, in wrapper return self._convert_and_export_metrics(convert_func, *args, **kwargs) File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/lite.py", line 1183, in _convert_and_export_metrics result = convert_func(self, *args, **kwargs) File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/lite.py", line 1562, in convert return self._convert_from_saved_model(graph_def) File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/lite.py", line 1424, in _convert_from_saved_model return self._optimize_tflite_model( File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/convert_phase.py", line 215, in wrapper raise error from None # Re-throws the exception. File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/convert_phase.py", line 205, in wrapper return func(*args, **kwargs) File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/lite.py", line 1127, in _optimize_tflite_model model = self._quantize( File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/lite.py", line 767, in _quantize return calibrate_quantize.calibrate_and_quantize( File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/convert_phase.py", line 215, in wrapper raise error from None # Re-throws the exception. File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/convert_phase.py", line 205, in wrapper return func(*args, **kwargs) File "/usr/local/lib/python3.10/dist-packages/tensorflow/lite/python/optimize/calibrator.py", line 194, in calibrate_and_quantize return self._calibrator.QuantizeModel( RuntimeError: Quantized dimension for tensor property and quantization parameters do not match. Got 3 and 0 respectively.
WARNING: Full INT8 Quantization with int16 activations tflite output failed. TensorFlow SavedModel: export success ✅ 248.1s, saved as '/content/yolo11n_saved_model' (36.1 MB) Edge TPU: WARNING ⚠️ Edge TPU known bug https://github.com/ultralytics/ultralytics/issues/1185
Edge TPU: starting export with Edge TPU compiler 16.0.384591198... Edge TPU: running 'edgetpu_compiler -s -d -k 10 --out_dir "/content/yolo11n_saved_model" "/content/yolo11n_saved_model/yolo11n_full_integer_quant.tflite"' Edge TPU: export success ✅ 3.9s, saved as '/content/yolo11n_saved_model/yolo11n_full_integer_quant_edgetpu.tflite' (3.5 MB)
Export complete (252.6s) Results saved to /content Predict: yolo predict task=detect model=/content/yolo11n_saved_model/yolo11n_full_integer_quant_edgetpu.tflite imgsz=640 int8 Validate: yolo val task=detect model=/content/yolo11n_saved_model/yolo11n_full_integer_quant_edgetpu.tflite imgsz=640 data=/usr/src/ultralytics/ultralytics/cfg/datasets/coco.yaml int8 Visualize: https://netron.app /content/yolo11n_saved_model/yolo11n_full_integer_quant_edgetpu.tflite
- Glenn JocherUltralytics
@Abdullah-Ory it seems you're encountering an issue with INT8 quantization during the TFLite Edge TPU export. Please ensure your model is compatible with Edge TPU requirements, and consider checking the Ultralytics documentation for detailed guidance on exporting models to TFLite Edge TPU format. If the issue persists, reviewing the quantization parameters might help.
MECHAAMER
Hi,
I trained a YOLOv8l model with VisDrone dataset, and attempted to convert the best weights.pt to Edge TPU TFlite format using:
model = YOLO("best.pt") model.export(format="edgetpu")
my board is Coral dev board.
The conversion completed successfully, but the results indicate that 164 of operations will run on the CPU instead of the Edge TPU. only 223 operation will run using Edge TPU This CPU usage will likely cause performance delays.
I'm wondering if there are any strategies or techniques to improve Edge TPU utilization and minimize CPU usage during inference for this model. Any suggestions or insights would be greatly appreciated.
Thanks,
- Glenn JocherUltralytics
@MECHAAMER to improve Edge TPU utilization, ensure your model is fully quantized and compatible with Edge TPU operations. Consider simplifying the model architecture or using supported operations. For detailed guidance, please refer to the Ultralytics Edge TPU documentation.
Hi, thank you for your support, I follow the attached link, and apply it using: model.export(format="edgetpu") , and I get this output:
Number of operations that will run on Edge TPU: 133 Number of operations that will run on CPU: 364
more details in the attached photo.
I think with this big percent of ops that runs on the CPU, the model will be very slow and I will suffer from large latency.
Do you have any suggestions?
- Glenn JocherUltralytics
To improve Edge TPU utilization, ensure your model is fully quantized and uses supported operations. Simplifying the model architecture might help. For more details, please refer to the Ultralytics Edge TPU documentation.
Hi there,
I'm following the Ultralytics Edge TPU documentation to train a YOLO model for object detection. However, I'm encountering suboptimal results.
I suspect that the issue might lie in the model's compatibility with the TPU. It's possible that certain operations within the model are not optimized for the TPU, leading to delays.
To address this, I'm considering using a YOLO model that is specifically designed to run efficiently on the Edge TPU. Do you have any recommendations for such models?
- Glenn JocherUltralytics
For optimal Edge TPU performance, consider using a smaller YOLO model like YOLOv8n, which is more compatible with Edge TPU operations. Simplifying the model architecture can also help.
I'm encountering a "Segmentation fault" error while trying to run a segmented YOLOv5s model on my Coral Dev Board with an external Coral ML Accelerator (USB). I followed the recommended steps to export, compile, and segment the model using edgetpu_compiler.
I follow these steps:
I trained Yolov5su model, then I exported the model as tflite - 8int by using:
model.export()

then I use the edgetpu_compiler to compile the tflite model and segmented it into 2 models:
edgetpu_compiler model.tflite --num_segments=2

then I get 12 files, 8 models and 4 logs, the models are:
1- best_float32_segment_0_of_2.tflite
2- best_float32_segment_1_of_2.tflite
3- best_float32_segment_0_of_2_edgetpu.tflite
4- best_float32_segment_1_of_2_edgetpu.tflite
5- best_full_integer_quant_segment_0_of_2.tflite
6- best_full_integer_quant_segment_1_of_2.tflite
7- best_full_integer_quant_segment_0_of_2_edgetpu.tflite
8- best_full_integer_quant_segment_1_of_2_edgetpu.tflite
I transfer the "best_full_integer_quant_segment_0_of_2_edgetpu.tflite" and "best_full_integer_quant_segment_1_of_2_edgetpu.tflite" to the coral board and I tried to run the models to detect object in a video, the code:
import argparse
import re
import threading
import time

import numpy as np
import cv2

from pycoral.adapters import classify
from pycoral.adapters import common
import pycoral.pipeline.pipelined_model_runner as pipeline
from pycoral.utils.dataset import read_label_file
from pycoral.utils.edgetpu import list_edge_tpus
from pycoral.utils.edgetpu import make_interpreter


def _get_devices(num_devices):
  edge_tpus = list_edge_tpus()

  if len(edge_tpus) < num_devices:
    raise RuntimeError(
        'Not enough Edge TPUs detected, expected %d, detected %d.' %
        (num_devices, len(edge_tpus)))

  num_pci_devices = sum(1 for device in edge_tpus if device['type'] == 'pci')

  return ['pci:%d' % i for i in range(min(num_devices, num_pci_devices))] + [
      'usb:%d' % i for i in range(max(0, num_devices - num_pci_devices))
  ]


def _make_runner(model_paths, devices):
  """Constructs PipelinedModelRunner given model paths and devices."""
  print('Using devices: ', devices)
  print('Using models: ', model_paths)

  print("  hey runner   1")
  if len(model_paths) != len(devices):
    raise ValueError('# of devices and #of model_paths should match')

  print("  hey runner   2", model_paths[0], devices[1])

  interpreters = []
  interpreter = make_interpreter(model_paths[0], devices[0])
  print("  hey runner   3")
  interpreter.allocate_tensors()
  print("  hey runner   4")
  interpreters.append(interpreter)
  print("  hey runner   5", model_paths[1], devices[0])

  interpreter2 = make_interpreter(model_paths[1], devices[1])
  print("  hey runner   6")
  interpreter.allocate_tensors()
  interpreter2.allocate_tensors()
  print("  hey runner   7")
  interpreters.append(interpreter2)
  print("  hey runner   8")

  return pipeline.PipelinedModelRunner(interpreters)


def main():
  parser = argparse.ArgumentParser(
      formatter_class=argparse.ArgumentDefaultsHelpFormatter)
  parser.add_argument(
      '-m',
      '--models',
      required=True,
      help=('File path template of .tflite model segments, e.g.,'
            'inception_v3_299_quant_segment_%d_of_2_edgetpu.tflite'))
  parser.add_argument(
      '-i', '--input', required=True, help='Image to be classified.')
  parser.add_argument('-l', '--labels', help='File path of labels file.')
  parser.add_argument(
      '-k',
      '--top_k',
      type=int,
      default=1,
      help='Max number of classification results')
  parser.add_argument(
      '-t',
      '--threshold',
      type=float,
      default=0.0,
      help='Classification score threshold')
  parser.add_argument(
      '-c',
      '--count',
      type=int,
      default=1,
      help='Number of times to run inference')
  args = parser.parse_args()
  labels = {0:"pedestrian", 1:"people", 2:"bicycle", 3:"car", 4:"van", 5:"truck", 6:"tricycle", 7:"awning-tricycle", 8:"bus", 9:"motor"}
  print("hey lets begin   1")
  result = re.search(r'^.*_segment_%d_of_(?P<num_segments>[0-9]+)_.*.tflite',
                     args.models)
  print("hey lets begin   2")

  if not result:
    print("hey lets begin    3")

    raise ValueError(
        '--models should follow *_segment%d_of_[num_segments]_*.tflite pattern')
  print("hey lets begin    4")

  num_segments = int(result.group('num_segments'))
  model_paths = [args.models % i for i in range(num_segments)]
  print("hey lets begin    5")

  devices = _get_devices(num_segments)

  print("hey lets begin    6")

  runner = _make_runner(model_paths, devices)

  print("hey lets begin      7")


  # Get the input name and size
  size = common.input_size(runner.interpreters()[0])

  print("hey lets begin     8")

  name = common.input_details(runner.interpreters()[0], 'name')

  print("hey lets begin    9")

  cap = cv2.VideoCapture(args.input)

  print("hey lets begin    10")

  if not cap.isOpened():
      print("Error opening video capture device")
      return

  print("hey lets begin    11")

  while True:
      ret, frame = cap.read()
      if not ret:
          break

      # Preprocess the frame
      height, width, _ = frame.shape
      new_height = int(640 * height / width)
      image = cv2.resize(frame, (640, new_height))

      # Run inference
      runner.push({name: image})

      output_details = runner.interpreters()[-1].get_output_details()[0]
      scale, zero_point = output_details['quantization']

      result = runner.pop()

      if result:
          # Process the results
          values, = result.values()
          scores = scale * (values[0].astype(np.int64) - zero_point)
          classes, scores = classify.get_classes_from_scores(result[0], args.top_k, args.threshold)

          for klass in classes:
              print('%s: %.5f' % (labels.get(klass.id, klass.id), klass.score))

          print('-------RESULTS--------')
      else:
          print("No results")

if __name__ == '__main__':
  main()
then I try execute the python file:python3 test2tpu.py -m best_full_integer_quant_segment_%d_of_2_edgetpu.tflite -i "/coral/720p/Busy Road.mp4"
the output that I get:
hey lets begin 1 hey lets begin 2 hey lets begin 4 hey lets begin 5 hey lets begin 6 Using devices: ['pci:0', 'usb:0'] Using models: ['best_full_integer_quant_segment_0_of_2_edgetpu.tflite', 'best_full_integer_quant_segment_1_of_2_edgetpu.tflite'] hey runner 1 hey runner 2 best_full_integer_quant_segment_0_of_2_edgetpu.tflite usb:0 hey runner 3 hey runner 4 hey runner 5 best_full_integer_quant_segment_1_of_2_edgetpu.tflite pci:0 Segmentation fault
Note: pycoral version: 2.0.0
- Glenn JocherUltralytics
It seems like the segmentation fault might be due to compatibility issues with the model operations on the Edge TPU. Consider simplifying the model architecture or ensuring all operations are supported by the Edge TPU. You can also check the Common Issues guide for additional troubleshooting tips.
Can you help me to know more about: simplifying the model architecture or ensuring all operations are supported by the Edge TPU.
I don't have access now to the records because I am outside office, as I remember In yolov5su, there are more than 200 process depends in TPU and only 25 process use CPU, Also the model working well on 1 TPU (with no segmentation).
- Glenn JocherUltralytics
@MECHAAMER to improve Edge TPU compatibility, consider using a smaller model like YOLOv8n, which is more likely to use supported operations, or simplify the architecture by reducing layers and operations that are not TPU-optimized.
Taufiq-Ahmed
Hi, I have train my custom dataset for detect fire and smoke with yolov8 nano. it's best model size is around 6MB and after exporting it using "yolo export model=yolov8n.pt format=edgetpu". it's size reduced to 3MB. But have to integrate this model in XIAO RP2040 MCU. So I need more light weight model for my edge device. In this case what I should? Please give me a solution.
- Glenn JocherUltralytics
@Taufiq-Ahmed hi! It's great to hear that you've successfully trained your custom dataset with YOLOv8 nano. For further reducing the model size for your XIAO RP2040 MCU, you might want to explore additional quantization techniques. The TFLite Edge TPU format already applies full integer quantization, but you can experiment with pruning or other model compression techniques to further reduce the size. If you haven't already, ensure you're using the latest version of the Ultralytics package for the best optimization features. For more detailed guidance, you can check out our Edge TPU integration guide. Good luck with your deployment!
samphonic
So I have a tflite model and object detection is working, but I can't seem to figure out how to tell if (and how effectively) the model is actually using the Edge TPU hardware. Is there some way to confirm that the hardware is actually being used? Can I manually enable/disable it to compare inference time?
- Glenn JocherUltralytics
@Sammy1Am to confirm if your model is utilizing the Edge TPU hardware, you can check the inference time and compare it with and without the Edge TPU. Typically, when the Edge TPU is in use, you should see a significant reduction in inference time. You can manually enable or disable the Edge TPU by using the
edgetpuinterpreter for the Edge TPU and the standard TFLite interpreter otherwise. For more details on setting this up, you might find the Edge TPU documentation helpful. If you need further assistance, feel free to explore our Ultralytics documentation.
FearL0rd
How do I use YOLO with a Dual TPU card?
I have APEX_0 and APEX_1 devices.
Streamline segmentation during export https://coral.ai/docs/edgetpu/pipeline/
- Glenn JocherUltralytics
@FearL0rd thank you for your suggestion! Streamlining segmentation during export is indeed a valuable enhancement. For detailed guidance on exporting YOLOv8 models to TFLite Edge TPU format, you can refer to our documentation. This will help you optimize your models for high-speed, low-power inferencing on devices with limited computational power.
For more information on using YOLO with a Dual TPU card, you can leverage the APEX_0 and APEX_1 devices to distribute the workload effectively. This setup can significantly boost performance and efficiency in your machine learning tasks.
Feel free to explore the provided resources and let us know if you have any further questions! 🚀
@glenn-jocher where is the doc talking about segmentation using APEX_0 and APEX_1
- Glenn JocherUltralytics
Hi @FearL0rd,
For documentation on segmentation using APEX_0 and APEX_1, you can refer to the guide on exporting YOLOv8 models to TFLite Edge TPU format. This guide covers optimizing your models for high-speed, low-power inferencing on devices like the Coral Edge TPU.
To utilize both APEX_0 and APEX_1 devices, you can distribute the workload effectively across the dual TPU setup, enhancing performance and efficiency. For more detailed instructions, please visit the relevant sections in our documentation.
Feel free to reach out if you have any more questions! 😊