COCO-Seg 数据集
COCO-Seg 数据集以 COCO(上下文中的常见物体)实例分割掩码为基础,包含 118,287 张训练图像和 5,000 张验证图像,覆盖 80 个物体类别并提供多边形掩码,采用 Ultralytics YOLO 标签格式。该数据集使用 COCO 的原始图像和原生分割标注,并将其转换为适用于 YOLO 训练的格式,是研究人员和开发者处理实例分割任务时的标准资源。
COCO-Seg 预训练模型#
| 模型 | 尺寸 (像素) | mAP框50-95 (e2e) | mAP掩码50-95 (e2e) | 速度 CPU ONNX (毫秒) | 速度 T4 TensorRT10 (ms) | 参数 (M) | FLOPs (B) |
|---|---|---|---|---|---|---|---|
| YOLO26n-seg | 640 | 39.6 | 33.9 | 53.3 ± 0.5 | 2.1 ± 0.0 | 2.7 | 9.3 |
| YOLO26s-seg | 640 | 47.3 | 40.0 | 118.4 ± 0.9 | 3.3 ± 0.0 | 10.4 | 34.5 |
| YOLO26m-seg | 640 | 52.5 | 44.1 | 328.2 ± 2.4 | 6.7 ± 0.1 | 23.6 | 121.7 |
| YOLO26l-seg | 640 | 54.4 | 45.5 | 387.0 ± 3.7 | 8.0 ± 0.1 | 28.0 | 140.1 |
| YOLO26x-seg | 640 | 56.5 | 47.0 | 787.0 ± 6.8 | 16.4 ± 0.1 | 62.8 | 314.0 |
主要功能#
- COCO-Seg 为 123,287 张已标注的 COCO train2017/val2017 图像提供实例分割掩码(118,287 张训练图像 + 5,000 张验证图像);COCO 发布的图像总量约为 ~330K 张。
- 该数据集包含与原始 COCO 数据集相同的 80 个对象类别。
- 标注以 YOLO 多边形标签格式提供实例分割掩码。
- COCO-Seg 提供标准化的 mAP 和 mAR 指标,用于评估实例分割性能,从而有效比较模型性能。
- 下载大小:首次使用时约为 ~20.3 GB(
train2017.zip+val2017.zip+ 标签)。不会自动获取 7 GB 的test2017.zip,因为这些图像没有公开真实标注,仅在提交 test-dev2017 结果时才需要。
数据集结构#
COCO-Seg 数据集分为三个子集:
- Train2017:118,287 张图像,用于训练实例分割模型。
- Val2017:5,000 张图像,用于模型开发过程中的验证。
- Test-dev2017:40,670 张 test2017 图像中的 20,288 张,用于基准测试。该子集的真实标注不公开,因此必须将预测结果提交到 COCO 评估服务器进行评分。
对于规模较小的实验需求,请参阅 COCO128-Seg(128 张图像)和 COCO8-Seg(8 张图像)子集。
应用场景#
COCO-Seg 广泛用于训练和评估深度学习模型的实例分割能力,例如 YOLO 模型。丰富的标注图像、多样的物体类别和标准化的评估指标,使其成为计算机视觉研究人员和从业者的标准资源。你还可以在 Ultralytics Platform 上浏览和管理完整的 COCO-Seg 标注。
数据集 YAML#
使用 YAML 文件定义数据集配置。该文件包含数据集路径、类别和其他相关信息。对于 COCO-Seg 数据集,coco.yaml 文件保存在 https://github.com/ultralytics/ultralytics/blob/main/ultralytics/cfg/datasets/coco.yaml。
# Ultralytics 🚀 AGPL-3.0 License - https://ultralytics.com/license

# COCO 2017 dataset https://cocodataset.org by Microsoft
# Documentation: https://docs.ultralytics.com/datasets/detect/coco
# Example usage: yolo train data=coco.yaml
# parent
# ├── ultralytics
# └── datasets
#     └── coco ← downloads here (20.3 GB)

# Train/val/test sets as 1) dir: path/to/imgs, 2) file: path/to/imgs.txt, or 3) list: [path/to/imgs1, path/to/imgs2, ..]
path: coco # dataset root dir
train: train2017.txt # train images (relative to 'path') 118287 images
val: val2017.txt # val images (relative to 'path') 5000 images
test: test-dev2017.txt # 20288 of 40670 images, submit via https://cocodataset.org/#detection-eval

# Classes
names:
  0: person
  1: bicycle
  2: car
  3: motorcycle
  4: airplane
  5: bus
  6: train
  7: truck
  8: boat
  9: traffic light
  10: fire hydrant
  11: stop sign
  12: parking meter
  13: bench
  14: bird
  15: cat
  16: dog
  17: horse
  18: sheep
  19: cow
  20: elephant
  21: bear
  22: zebra
  23: giraffe
  24: backpack
  25: umbrella
  26: handbag
  27: tie
  28: suitcase
  29: frisbee
  30: skis
  31: snowboard
  32: sports ball
  33: kite
  34: baseball bat
  35: baseball glove
  36: skateboard
  37: surfboard
  38: tennis racket
  39: bottle
  40: wine glass
  41: cup
  42: fork
  43: knife
  44: spoon
  45: bowl
  46: banana
  47: apple
  48: sandwich
  49: orange
  50: broccoli
  51: carrot
  52: hot dog
  53: pizza
  54: donut
  55: cake
  56: chair
  57: couch
  58: potted plant
  59: bed
  60: dining table
  61: toilet
  62: tv
  63: laptop
  64: mouse
  65: remote
  66: keyboard
  67: cell phone
  68: microwave
  69: oven
  70: toaster
  71: sink
  72: refrigerator
  73: book
  74: clock
  75: vase
  76: scissors
  77: teddy bear
  78: hair drier
  79: toothbrush

# Download script/URL (optional)
download: |
  from pathlib import Path

  from ultralytics.utils import ASSETS_URL
  from ultralytics.utils.downloads import download

  # Download labels
  segments = True  # segment or box labels
  dir = Path(yaml["path"])  # dataset root dir
  urls = [ASSETS_URL + ("/coco2017labels-segments.zip" if segments else "/coco2017labels.zip")]  # labels
  download(urls, dir=dir.parent)

  # Download data (test2017.zip excluded: ground truth is withheld, only used for the eval-server test-dev split)
  urls = [
      "http://images.cocodataset.org/zips/train2017.zip",  # 19G, 118k images
      "http://images.cocodataset.org/zips/val2017.zip",  # 1G, 5k images
  ]
download(urls, dir=dir / "images", threads=3)用法#
如需在 COCO-Seg 数据集上以 640 的图像尺寸训练一个 YOLO26n-seg 模型,训练 100 个周期,可以使用以下代码片段。
from ultralytics import YOLO

# 加载模型
model = YOLO("yolo26n-seg.pt")  # 加载预训练模型(推荐用于训练)

# 训练模型
results = model.train(data="coco.yaml", epochs=100, imgsz=640)示例图像和标注#
COCO-Seg 包含与 COCO 相同的多样化图像、对象类别和复杂场景,并以 YOLO 标签格式提供实例分割掩码。以下是数据集中的一些图像示例及其对应的实例分割掩码:
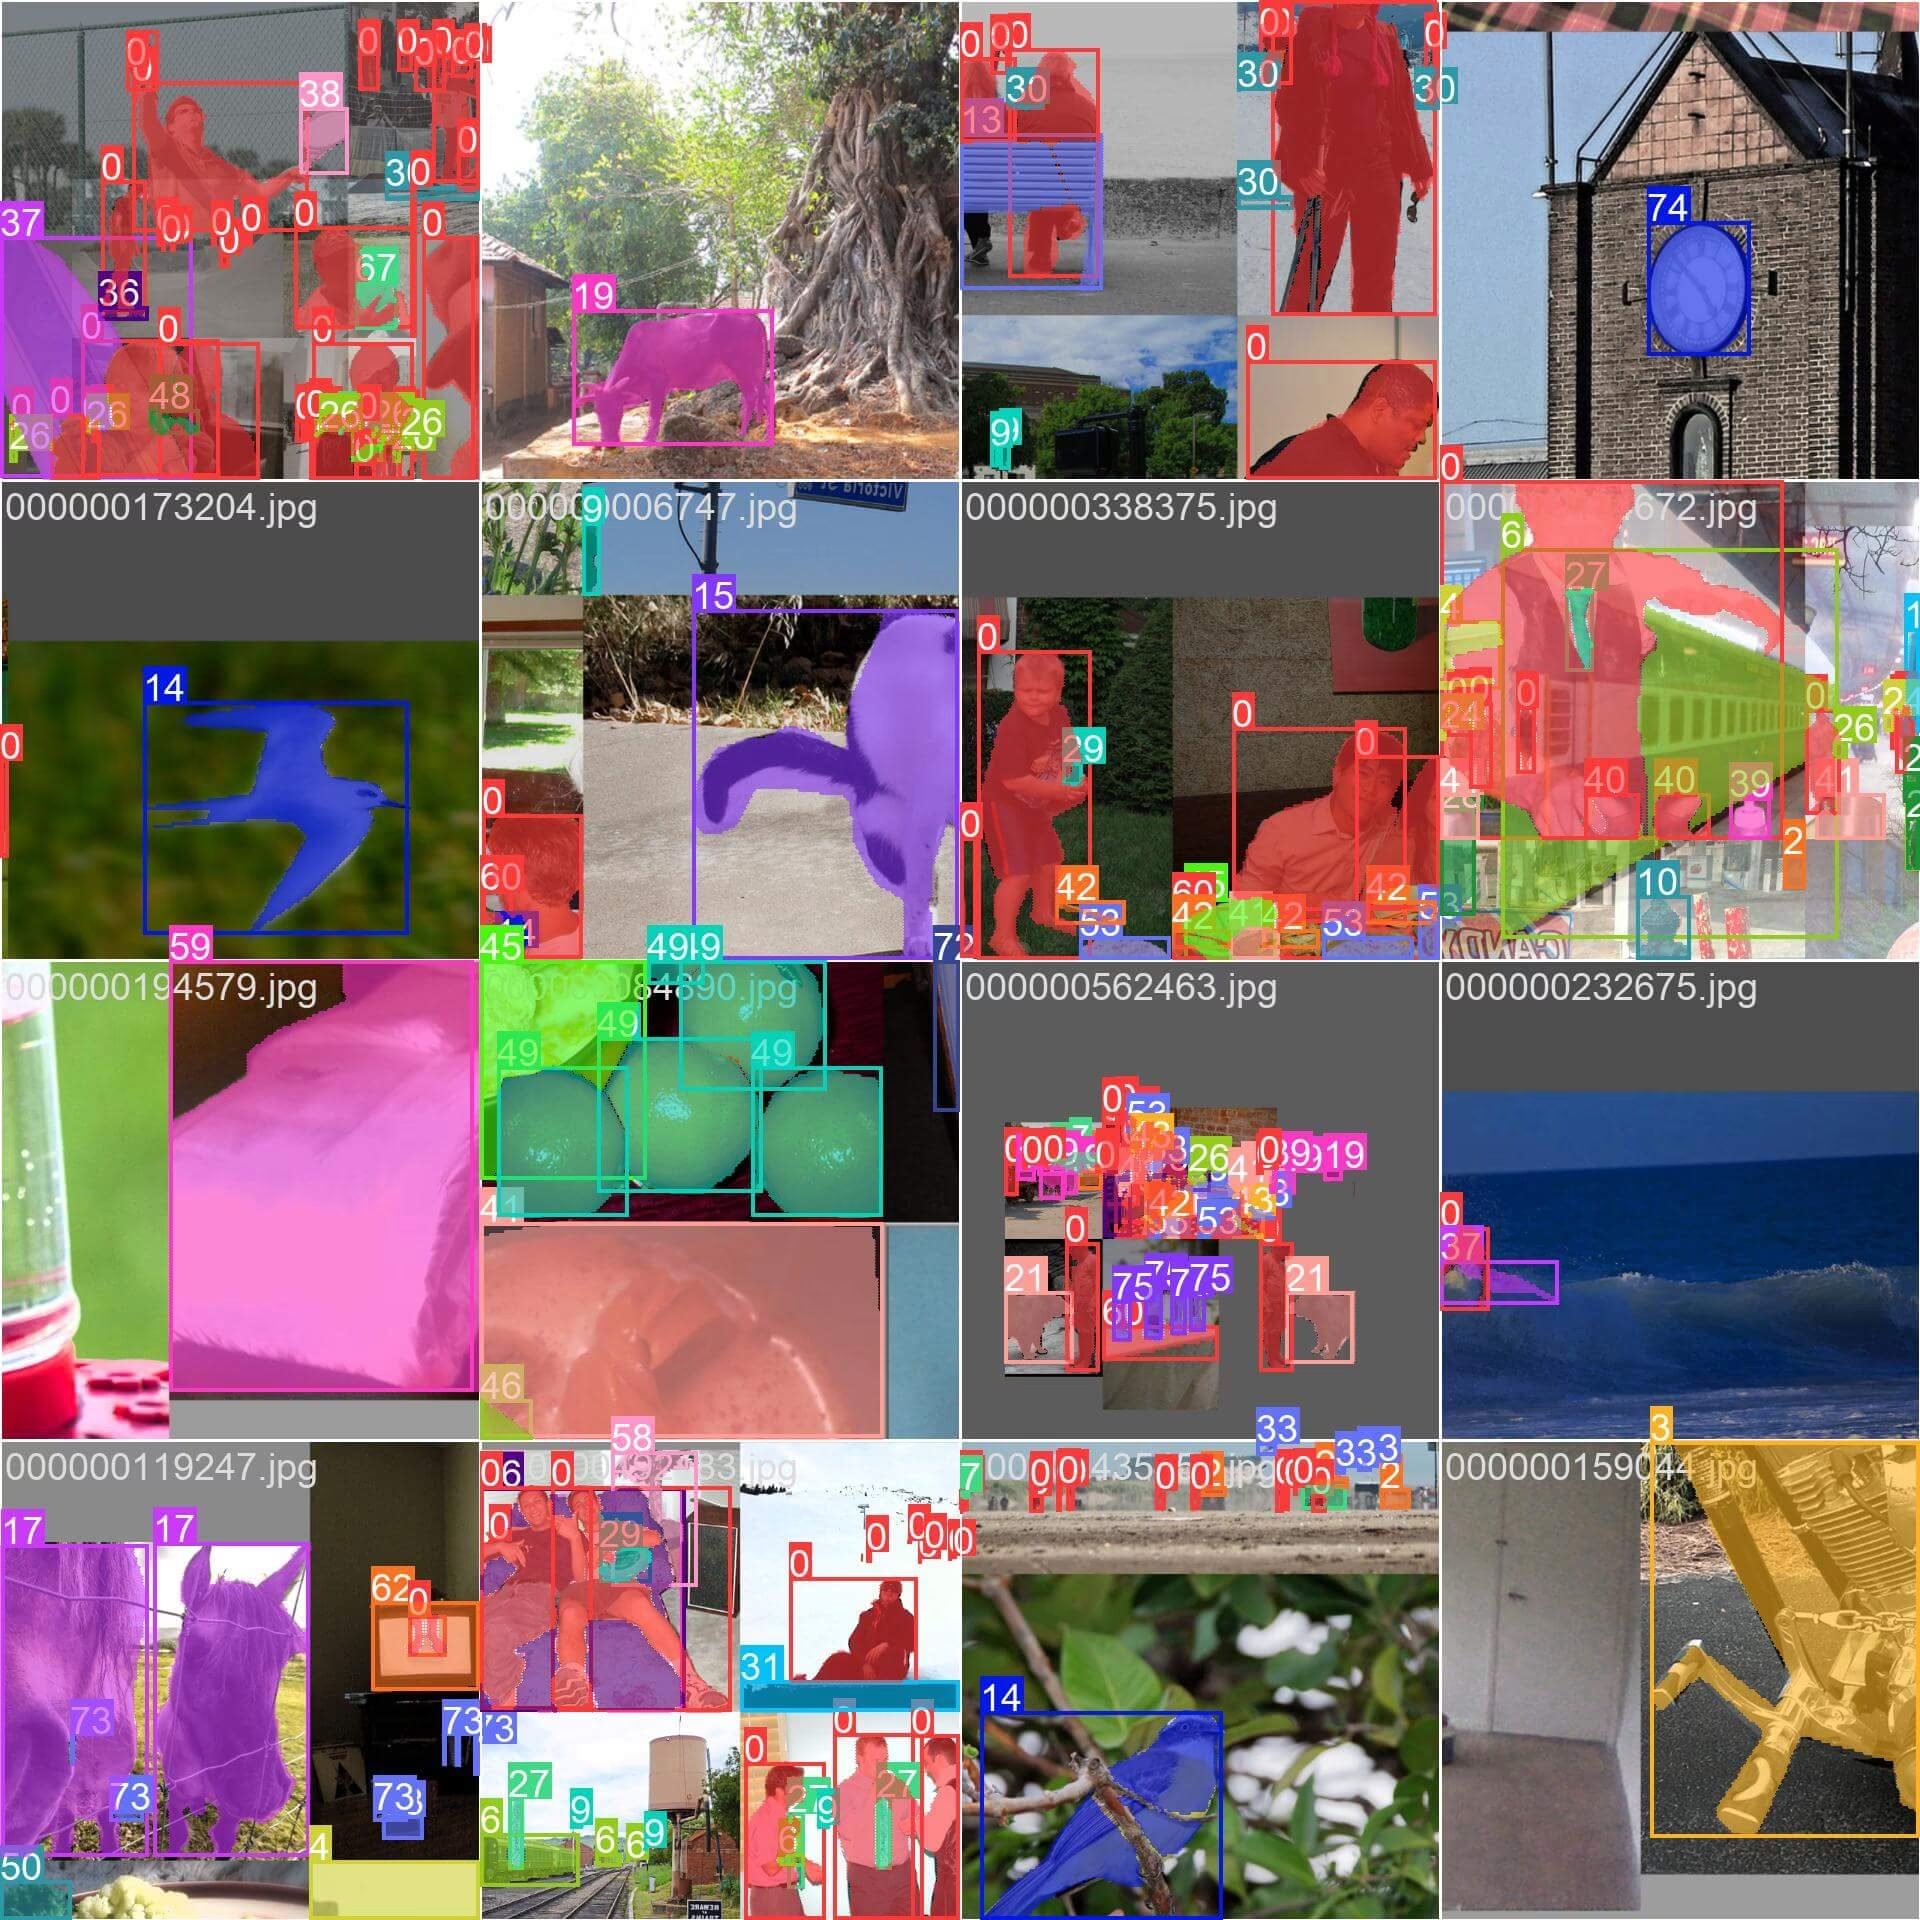
- 马赛克图像:此图展示了由数据集马赛克图像组成的训练批次。马赛克增强是一种在训练过程中使用的技术,它将多张图像合并成一张图像,以增加每个训练批次中对象和场景的多样性。这有助于模型泛化到不同的对象尺寸、宽高比和上下文。
引用与致谢#
如果你在研究或开发工作中使用 COCO-Seg 数据集,请引用原始 COCO 论文,并注明对 COCO-Seg 的扩展:
@misc{lin2015microsoft,
      title={Microsoft COCO: Common Objects in Context},
      author={Tsung-Yi Lin and Michael Maire and Serge Belongie and Lubomir Bourdev and Ross Girshick and James Hays and Pietro Perona and Deva Ramanan and C. Lawrence Zitnick and Piotr Dollár},
      year={2015},
      eprint={1405.0312},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}
我们谨向 COCO Consortium 致谢,感谢其为计算机视觉社区创建并维护这一宝贵资源。
常见问题#
COCO-Seg 是将 COCO(上下文中的常见物体)原生实例分割掩码打包为 Ultralytics YOLO 格式的数据集,包含相同的 118,287 张 train2017 图像和 5,000 张 val2017 图像。原始 COCO 标注已包含全部 80 个物体类别的多边形掩码;COCO-Seg 将这些掩码转换为用于物体实例分割训练的 YOLO 标签格式。
要在 COCO-Seg 数据集上训练 YOLO26n-seg 模型,训练 100 个轮次,图像尺寸设为 640,你可以使用以下代码片段。有关可用训练参数的详细列表,请参阅模型训练页面。
训练示例from ultralytics import YOLO # 加载模型 model = YOLO("yolo26n-seg.pt") # 加载预训练模型(推荐用于训练) # 训练模型 results = model.train(data="coco.yaml", epochs=100, imgsz=640)COCO-Seg 数据集包含以下几项主要特征:
- 为 123,287 张带标注的 COCO train2017/val2017 图像提供实例分割掩码(118,287 张训练图像 + 5,000 张验证图像)。
- 标注与原始 COCO 相同的 80 个对象类别。
- 以 YOLO 多边形标签格式提供实例分割掩码。
- 实例分割任务使用标准化评估指标,例如平均精度均值 (mAP)和平均召回率均值 (mAR)。
COCO-Seg 数据集支持多种预训练 YOLO26 分割模型,各模型的性能指标有所不同。以下是可用模型及其主要指标的汇总:
模型 尺寸
(像素)mAP框50-95
(e2e)mAP掩码50-95
(e2e)速度
CPU ONNX
(毫秒)速度
T4 TensorRT10
(ms)参数
(M)FLOPs
(B)YOLO26n-seg 640 39.6 33.9 53.3 ± 0.5 2.1 ± 0.0 2.7 9.3 YOLO26s-seg 640 47.3 40.0 118.4 ± 0.9 3.3 ± 0.0 10.4 34.5 YOLO26m-seg 640 52.5 44.1 328.2 ± 2.4 6.7 ± 0.1 23.6 121.7 YOLO26l-seg 640 54.4 45.5 387.0 ± 3.7 8.0 ± 0.1 28.0 140.1 YOLO26x-seg 640 56.5 47.0 787.0 ± 6.8 16.4 ± 0.1 62.8 314.0 这些模型的范围从轻量级的 YOLO26n-seg 到准确率更高的 YOLO26x-seg,在速度与准确率之间提供不同的权衡,以满足各种应用需求。
COCO-Seg 数据集分为三个子集,以满足特定的训练和评估需求:
- Train2017:包含 118,287 张图像,主要用于训练实例分割模型。
- Val2017:包含 5,000 张图像,用于训练过程中的验证。
- Test-dev2017:包含 40,670 张 test2017 图像中的 20,288 张,用于测试和对训练模型进行基准评测。请注意,此子集的真实标注不公开,性能结果需提交至 COCO 评估服务器进行评估。
对于规模较小的实验需求,你还可以考虑 COCO128-Seg 数据集(128 张图像),或 COCO8-Seg 数据集,这是一个精简数据集,仅包含 COCO train 2017 集中的 8 张图像。


评论10
提出问题、分享结果,或帮助其他人。
liujieKermit
what the label format if I want to train my custom dataset, please give the solution step by step like label, train, val, export, predict
 Glenn JocherUltralytics(已编辑)
@liujieKermit for custom segmentation training with YOLO26, follow these steps:
-
Label Format: Use YOLO segmentation format - one text file per image with class index and normalized polygon coordinates (minimum 3 points per object). Example:
<class> <x1> <y1> <x2> <y2> ... <xn> <yn> -
Dataset YAML: Create a YAML file (example
data.yaml):
path: /path/to/dataset train: images/train val: images/val names: 0: class1 1: class2- Train:
from ultralytics import YOLO model = YOLO('yolo26n-seg.pt') model.train(data='data.yaml', epochs=100, imgsz=640)- Export/Predict:
model.export(format='onnx')  # export
model.predict('image.jpg')  # predict
For full details see our Dataset Format Guide and Auto-Annotation Tools. For commercial use, review our license terms.
-
YingdiZhang
Thanks for the great work. I am new to YOLO and AI. How to download the COCO dataset? is just running python coco.yaml?
- Glenn JocherUltralytics(已编辑)
@YingdiZhang to download the COCO dataset, you can run
yolo segment train data=coco.yamlin your terminal. This will automatically download the dataset for you. For more details, you can visit the Ultralytics documentation.
SacherTorte280
Dear developpers, I need to build a much simpler case where I'll only need <=5 labels, can I remove the others that i'll never use ?
 Paula DerrengerUltralytics(已编辑)
@SacherTorte280 yes, you can customize the dataset to include only the labels you need. To do this, modify the
coco.yamlfile to include only the desired classes in thenamessection and adjust the dataset paths accordingly. Also make sure the class indices in your label files are remapped to match the newnames(0 to N-1) and remove labels of the dropped classes. This will allow you to train your model with a simplified set of labels. For more details on configuring the dataset, please refer to the COCO-Seg documentation.
MoAbbasid
i get a list out of index error when running convert_coco function please help
- Paula DerrengerUltralytics
Hi there! It looks like you're encountering a
list index out of rangeerror with theconvert_cocofunction. This can often happen if the script is trying to access an element that doesn't exist in a list. To help you resolve this issue, please ensure that:- The data paths in your
coco.yamlconfig file are correctly set and point to valid files. - The COCO dataset is correctly downloaded and structured as expected by the script.
If the paths and dataset structure are correct, it might be helpful to check if the specific segment of data causing the error is formatted correctly or missing elements.
Here's a quick check you can perform:
try:
    # Assuming convert_coco is called here
    convert_coco()
except IndexError as e:
    print("An index error occurred: ", e)
    # You can add more debugging information here to understand which part of the data is causing the problem
This snippet will catch the
IndexErrorand print it, potentially providing more insight on what's going wrong. If you need further assistance, please don't hesitate to share a snippet of the data or more details on the error! - The data paths in your
mohamed-ladjal
Greetings, I possess medical imagery depicting bone lesions. These images comprise 3D volumes of dimensions (256, 256, 128), with each volume containing 128 slices. Corresponding masks of identical dimensions are available. My objective is to either fine-tune or train a model using these slices to accurately segment the lesions mohamed mohamed.laadjel2019@gmail.com
- Glenn JocherUltralytics(已编辑)
Hello Mohamed,
Great to hear about your project on segmenting bone lesions from medical imagery! For your 3D volumes, you can approach this by treating each slice as a separate 2D image for segmentation.
Given your setup, you might consider using our YOLO26-seg models, which are well-suited for segmentation tasks. Here’s a basic example of how you could set up your training with YOLO26:
from ultralytics import YOLO

# Load a pretrained segmentation model
model = YOLO('yolo26n-seg.pt')  # Choose the appropriate model size

# Prepare your dataset in a compatible format
# Ensure your dataset directory structure and annotations are correctly set up

# Train the model
results = model.train(data='your_dataset_config.yaml', epochs=100, imgsz=640)
Make sure your dataset is annotated similarly to how COCO-Seg annotations are structured, with masks corresponding to each slice. You might need to adjust the
your_dataset_config.yamlto correctly point to your training, validation, and test images along with their annotations.For more detailed guidance on preparing your dataset and annotations, you can refer to our documentation on COCO-Seg Dataset.
If you have any more questions or need further assistance, feel free to ask. Happy training! 🚀