COCO-Datensatz
Der COCO-Datensatz (Alltagsobjekte im Kontext) ist ein umfangreicher Datensatz für Objekterkennung, Segmentierung und Bildbeschriftung. Er soll die Forschung zu einer Vielzahl von Objektkategorien fördern und wird häufig zum Benchmarking von Computer-Vision-Modellen verwendet. Für Forschende und Entwickler, die an Objekterkennung, Segmentierung und Posenschätzung arbeiten, ist er ein wichtiger Datensatz.
Ansehen: Überblick über den Ultralytics-COCO-Datensatz
Auf COCO vortrainierte Modelle#
| Modell | Größe (Pixel) | mAPval50-95 | mAPval50-95 (e2e) | Geschwindigkeit CPU ONNX (ms) | Geschwindigkeit T4 TensorRT10 (ms) | Parameter (M) | FLOPs (B) |
|---|---|---|---|---|---|---|---|
| YOLO26n | 640 | 40.9 | 40.1 | 38.9 ± 0.7 | 1.7 ± 0.0 | 2.4 | 5.5 |
| YOLO26s | 640 | 48.6 | 47.8 | 87.2 ± 0.9 | 2.5 ± 0.0 | 9.5 | 20.9 |
| YOLO26m | 640 | 53.1 | 52.5 | 220.0 ± 1.4 | 4.7 ± 0.1 | 20.4 | 68.4 |
| YOLO26l | 640 | 55.0 | 54.4 | 286.2 ± 2.0 | 6.2 ± 0.2 | 24.8 | 86.8 |
| YOLO26x | 640 | 57.5 | 56.9 | 525.8 ± 4.0 | 11.8 ± 0.2 | 55.7 | 194.4 |
Wichtige Funktionen#
- COCO enthält 330K Bilder, von denen 200K Annotationen für Aufgaben zur Objekterkennung, Segmentierung und Bildbeschreibung haben.
- Der Datensatz umfasst 80 Objektkategorien, darunter häufige Objekte wie Autos, Fahrräder und Tiere sowie spezifischere Kategorien wie Regenschirme, Handtaschen und Sportgeräte.
- Die Annotationen umfassen Objekt-Bounding-Boxen, Segmentierungsmasken und Bildbeschreibungen für jedes Bild.
- COCO bietet standardisierte Bewertungsmetriken wie mittlere durchschnittliche Präzision (mAP) und durchschnittlichen Recall (AR) für Objekterkennung und Segmentierung und eignet sich damit zum Vergleich der Modellleistung.
Datensatzstruktur#
Der COCO-Datensatz ist in drei Teilmengen unterteilt:
- Train2017: 118.287 Bilder zum Trainieren von Modellen für Objekterkennung, Segmentierung und Bildbeschriftung.
- Val2017: 5.000 Bilder, die während des Modelltrainings zur Validierung verwendet werden.
- Test2017: 20.288 Test-Dev-Bilder zum Benchmarking trainierter Modelle. Die Ground-Truth-Annotationen für diese Teilmenge sind nicht öffentlich verfügbar. Die Ergebnisse werden zur Leistungsbewertung beim COCO-Evaluierungsserver eingereicht.
Anwendungsfälle#
Der COCO-Datensatz wird häufig zum Trainieren und Bewerten von Modellen für Deep Learning in der Objekterkennung (z. B. Ultralytics YOLO, Faster R-CNN und SSD), Instanzsegmentierung (z. B. Mask R-CNN) und Keypoint-Erkennung (z. B. OpenPose ) verwendet. Die vielfältigen Objektkategorien, die große Zahl annotierter Bilder und die standardisierten Bewertungsmetriken machen den Datensatz zu einer unverzichtbaren Ressource für Forschende und Fachleute im Bereich Computer Vision.
Annotationen, die aus Beschriftungswerkzeugen im COCO-JSON-Format exportiert werden, folgen derselben Struktur. Informationen zum Trainieren mit deinen eigenen Daten im COCO-Format findest du unter COCO-Annotationen in YOLO konvertieren.
YAML-Datei des Datensatzes#
Eine YAML-Datei dient zum Definieren der Datensatzkonfiguration. Sie enthält Informationen zu den Pfaden, Klassen und weiteren relevanten Angaben des Datensatzes. Beim COCO-Datensatz wird die Datei coco.yaml unter https://github.com/ultralytics/ultralytics/blob/main/ultralytics/cfg/datasets/coco.yaml gepflegt.
# Ultralytics 🚀 AGPL-3.0 License - https://ultralytics.com/license

# COCO 2017 dataset https://cocodataset.org by Microsoft
# Documentation: https://docs.ultralytics.com/datasets/detect/coco
# Example usage: yolo train data=coco.yaml
# parent
# ├── ultralytics
# └── datasets
#     └── coco ← downloads here (20.3 GB)

# Train/val/test sets as 1) dir: path/to/imgs, 2) file: path/to/imgs.txt, or 3) list: [path/to/imgs1, path/to/imgs2, ..]
path: coco # dataset root dir
train: train2017.txt # train images (relative to 'path') 118287 images
val: val2017.txt # val images (relative to 'path') 5000 images
test: test-dev2017.txt # 20288 of 40670 images, submit via https://cocodataset.org/#detection-eval

# Classes
names:
  0: person
  1: bicycle
  2: car
  3: motorcycle
  4: airplane
  5: bus
  6: train
  7: truck
  8: boat
  9: traffic light
  10: fire hydrant
  11: stop sign
  12: parking meter
  13: bench
  14: bird
  15: cat
  16: dog
  17: horse
  18: sheep
  19: cow
  20: elephant
  21: bear
  22: zebra
  23: giraffe
  24: backpack
  25: umbrella
  26: handbag
  27: tie
  28: suitcase
  29: frisbee
  30: skis
  31: snowboard
  32: sports ball
  33: kite
  34: baseball bat
  35: baseball glove
  36: skateboard
  37: surfboard
  38: tennis racket
  39: bottle
  40: wine glass
  41: cup
  42: fork
  43: knife
  44: spoon
  45: bowl
  46: banana
  47: apple
  48: sandwich
  49: orange
  50: broccoli
  51: carrot
  52: hot dog
  53: pizza
  54: donut
  55: cake
  56: chair
  57: couch
  58: potted plant
  59: bed
  60: dining table
  61: toilet
  62: tv
  63: laptop
  64: mouse
  65: remote
  66: keyboard
  67: cell phone
  68: microwave
  69: oven
  70: toaster
  71: sink
  72: refrigerator
  73: book
  74: clock
  75: vase
  76: scissors
  77: teddy bear
  78: hair drier
  79: toothbrush

# Download script/URL (optional)
download: |
  from pathlib import Path

  from ultralytics.utils import ASSETS_URL
  from ultralytics.utils.downloads import download

  # Download labels
  segments = True  # segment or box labels
  dir = Path(yaml["path"])  # dataset root dir
  urls = [ASSETS_URL + ("/coco2017labels-segments.zip" if segments else "/coco2017labels.zip")]  # labels
  download(urls, dir=dir.parent)

  # Download data (test2017.zip excluded: ground truth is withheld, only used for the eval-server test-dev split)
  urls = [
      "http://images.cocodataset.org/zips/train2017.zip",  # 19G, 118k images
      "http://images.cocodataset.org/zips/val2017.zip",  # 1G, 5k images
  ]
download(urls, dir=dir / "images", threads=3)Verwendung#
Die COCO2017-Trainings- und Validierungsdaten (20,3 GB) werden beim ersten Trainingsstart automatisch heruntergeladen. Um YOLO26n 100 Epochen lang mit Bildgröße 640 auf COCO zu trainieren, kannst du die folgenden Codeausschnitte verwenden. Du kannst das COCO-Training auch mit der Ultralytics Platform in der Cloud ausführen.
from ultralytics import YOLO

# Ein Modell laden
model = YOLO("yolo26n.pt")  # ein vortrainiertes Modell laden (für das Training empfohlen)

# Das Modell trainieren
results = model.train(data="coco.yaml", epochs=100, imgsz=640)
Beispielbilder und Annotationen#
Der COCO-Datensatz enthält vielfältige Bilder mit unterschiedlichen Objektkategorien und komplexen Szenen. Hier sind einige Beispielbilder aus dem Datensatz mit den zugehörigen Annotationen:
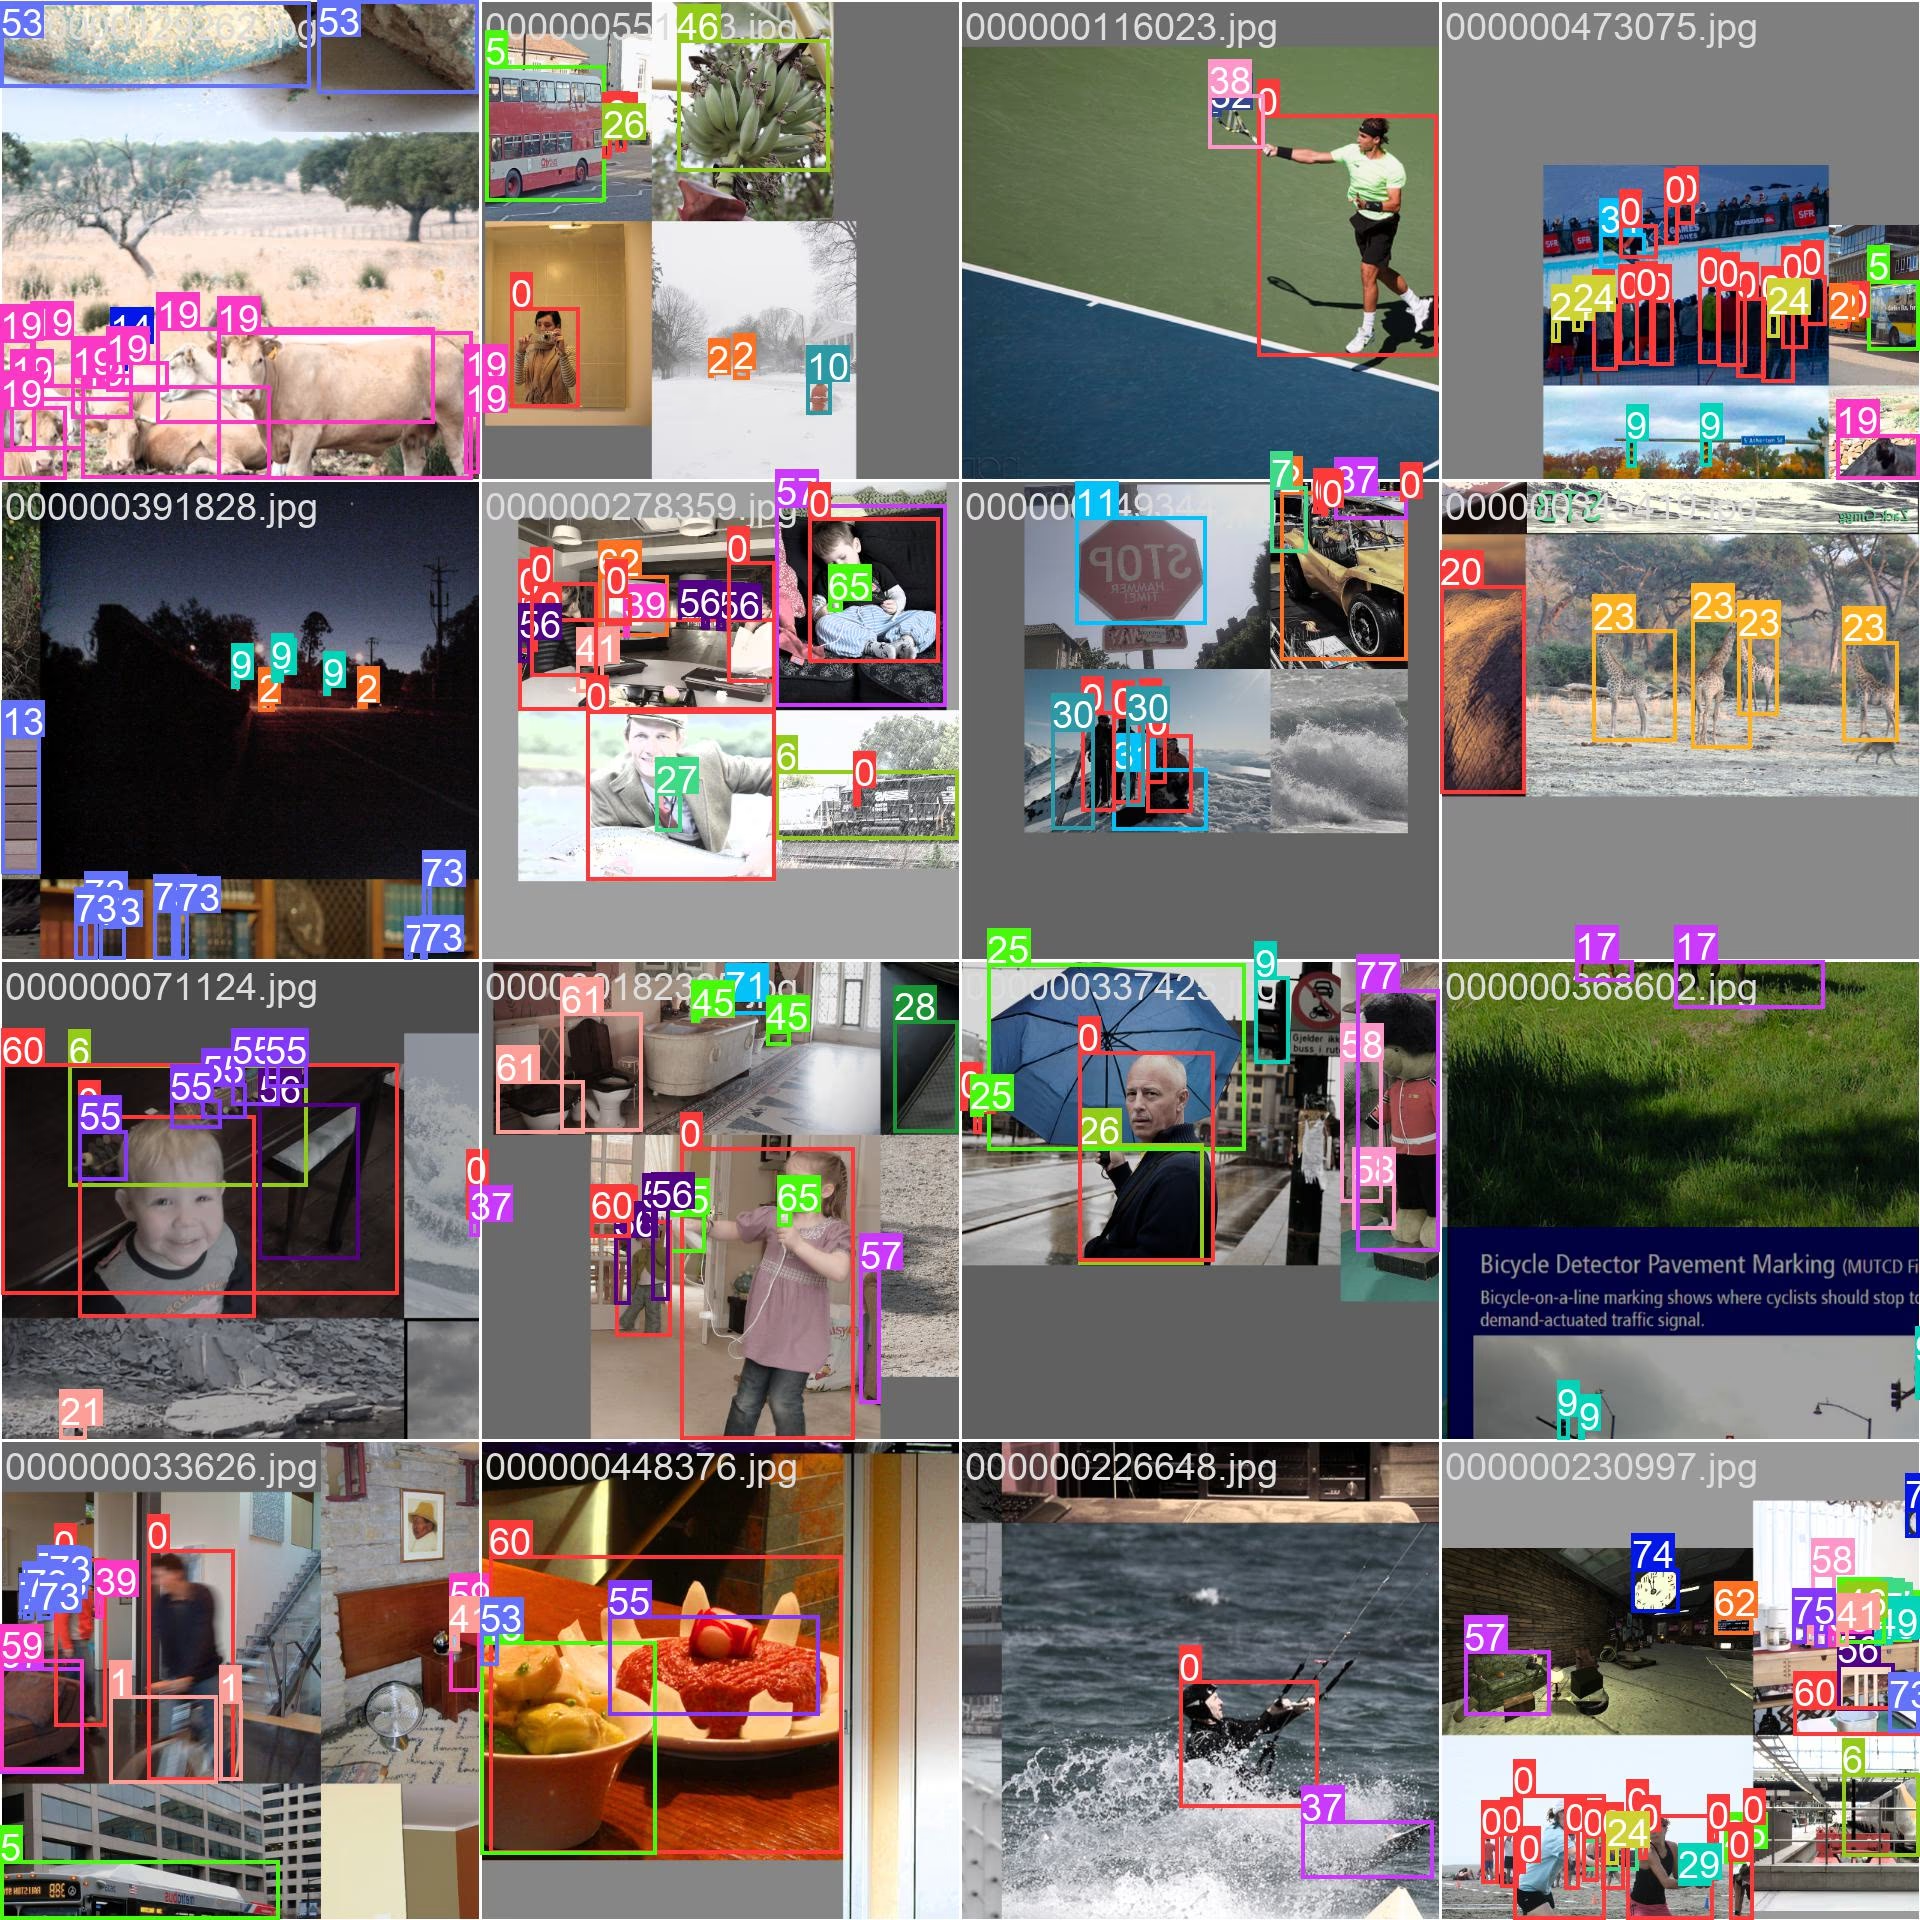
- Mosaikbild: Dieses Bild zeigt einen Trainingsbatch aus mosaikartig kombinierten Datensatzbildern. Beim Mosaikverfahren werden während des Trainings mehrere Bilder zu einem einzigen Bild kombiniert, um die Vielfalt der Objekte und Szenen in jedem Trainingsbatch zu erhöhen. Dadurch kann das Modell besser auf unterschiedliche Objektgrößen, Seitenverhältnisse und Kontexte generalisieren.
Das Beispiel zeigt die Vielfalt und Komplexität der Bilder im COCO-Datensatz und die Vorteile der Mosaiktransformation während des Trainings.
Zitate und Danksagungen#
Wenn du den COCO-Datensatz für deine Forschung oder Entwicklungsarbeit verwendest, zitiere bitte die folgende Arbeit:
@misc{lin2015microsoft,
      title={Microsoft COCO: Common Objects in Context},
      author={Tsung-Yi Lin and Michael Maire and Serge Belongie and Lubomir Bourdev and Ross Girshick and James Hays and Pietro Perona and Deva Ramanan and C. Lawrence Zitnick and Piotr Dollár},
      year={2015},
      eprint={1405.0312},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}
Wir möchten dem COCO Consortium dafür danken, dass es diese wertvolle Ressource für die Computer-Vision-Community geschaffen hat und pflegt. Weitere Informationen zum COCO-Datensatz und seinen Urhebern findest du auf der Website des COCO-Datensatzes.
Häufig gestellte Fragen#
Der COCO-Datensatz (Alltagsobjekte im Kontext) ist ein umfangreicher Datensatz für Objekterkennung, Segmentierung und Bildbeschriftung. Er umfasst 330.000 Bilder mit detaillierten Annotationen für 80 Objektkategorien und ist damit für das Benchmarking und Training von Computer-Vision-Modellen unverzichtbar. Forschende verwenden COCO wegen seiner vielfältigen Kategorien und standardisierten Bewertungskennzahlen wie der mittleren durchschnittlichen Präzision (mAP).
Mit den folgenden Codebeispielen kannst du ein YOLO26-Modell mit dem COCO-Datensatz trainieren:
Trainingsbeispielfrom ultralytics import YOLO # Ein Modell laden model = YOLO("yolo26n.pt") # ein vortrainiertes Modell laden (für das Training empfohlen) # Das Modell trainieren results = model.train(data="coco.yaml", epochs=100, imgsz=640)Weitere Informationen zu den verfügbaren Argumenten findest du auf der Seite zum Training.
Der COCO-Datensatz umfasst:
- 330.000 Bilder, davon 200.000 mit Annotationen für Objekterkennung, Segmentierung und Bildbeschriftung.
- 80 Objektkategorien – von häufigen Dingen wie Autos und Tieren bis hin zu spezifischen Kategorien wie Handtaschen und Sportausrüstung.
- Standardisierte Bewertungsmetriken (mAP und Average Recall) für Objekterkennung und Segmentierung.
- Das Mosaikverfahren in Trainingsbatches verbessert die Generalisierungsfähigkeit des Modells bei unterschiedlichen Objektgrößen und Kontexten.
Vortrainierte YOLO26-Modelle, die mit COCO trainiert wurden, sind auf der Ultralytics Platform verfügbar und werden bei der ersten Verwendung automatisch heruntergeladen:
Diese Modelle unterscheiden sich hinsichtlich Größe, mAP und Inferenzgeschwindigkeit und bieten Optionen für unterschiedliche Leistungs- und Ressourcenanforderungen.
Der COCO-Datensatz ist in drei Teilmengen unterteilt:
- Train2017: 118.287 Bilder zum Trainieren.
- Val2017: 5.000 Bilder zur Validierung während des Trainings.
- Test2017: 20.288 Test-Dev-Bilder zum Benchmarking trainierter Modelle. Die Ergebnisse müssen zur Leistungsbewertung beim COCO-Evaluierungsserver eingereicht werden.
Die YAML-Konfigurationsdatei des Datensatzes ist unter coco.yaml verfügbar. Sie definiert Pfade, Klassen und Datensatzdetails.


Kommentare40
Stell eine Frage, teile deine Ergebnisse oder hilf jemand anderem.
williamrojas8928-commits
If I want to train a custom model on COCO classes, such as person, car, and truck, do I need to train a new model from scratch? Or can I use a pre-trained model and just ignore the predictions of the other classes, even though this might involve more computational cost?
1aasharma90(bearbeitet)
Hello,
What is the pre-trained model
yolov8n.pttrained on? Since if it's already COCO dataset, I wonder why the new training is required.1 Glenn JocherUltralytics(bearbeitet)
Hello,
Great question! The pre-trained model
yolo26n.ptis indeed trained on the COCO dataset. This means it has already learned to detect the 80 object categories included in COCO, such as people, cars, animals, and more.However, there are several reasons why you might want to retrain or fine-tune this model:
-
Custom Dataset: If you have a custom dataset with different object categories or specific variations of the COCO categories, retraining the model will help it adapt to your specific data.
-
Improved Performance: Fine-tuning the model on your dataset can improve its performance, especially if your dataset has different characteristics (e.g., different lighting conditions, object sizes, or backgrounds) compared to the original COCO dataset.
-
Additional Classes: If you need to detect additional classes that are not included in the COCO dataset, you will need to retrain the model with your extended dataset.
-
Domain Adaptation: If your application involves a specific domain (e.g., medical imaging, industrial inspection), retraining the model on domain-specific data can significantly enhance its accuracy and reliability.
Here’s a quick example of how you can fine-tune the
yolo26n.ptmodel on your custom dataset using Python:from ultralytics import YOLO # Load the pre-trained model model = YOLO("yolo26n.pt") # Train the model on your custom dataset results = model.train(data="path/to/your/custom_dataset.yaml", epochs=100, imgsz=640)And using the CLI:
yolo detect train data=path/to/your/custom_dataset.yaml model=yolo26n.pt epochs=100 imgsz=640For more details on the COCO dataset and how to use it, you can refer to our COCO Dataset Documentation.
If you have any more questions or need further assistance, feel free to ask! 😊
-
Thanks for your detailed explanation and reply.
I understand the fine-tuning requirement for a custom dataset, but my question was about the fine-tuning part mentioned for the COCO dataset itself in the
Train Examplesegment above.Never mind, I think I have my answers. Thanks so much again :)
- Glenn JocherUltralytics
Hi @aasharma90,
Thank you for your follow-up! I appreciate your understanding regarding the fine-tuning process.
To clarify, the
Train Examplesegment for the COCO dataset is primarily included to demonstrate how to train a YOLO model from scratch or fine-tune it, even if it has already been pre-trained on COCO. This can be useful for several reasons:- Hyperparameter Tuning: Fine-tuning allows you to adjust hyperparameters specific to your use case, potentially improving model performance.
- Extended Training: Additional training can help the model refine its weights and improve accuracy, especially if you have more computational resources or time.
- Custom Augmentations: You might want to apply custom data augmentations that are more suited to your specific application or environment.
If you have any more questions or need further assistance, feel free to ask! 😊
JackEdoubleS
I have the same question. If retraining is for domain adaptation and learning new categories, the knowledge from learned model from COCO dataset will be catastrophic forgetting. This means it is the same between retraining with pretrained network and training from scratch.
- Glenn JocherUltralytics
Thank you for your insights. While catastrophic forgetting is a valid concern, fine-tuning with pre-trained weights often accelerates convergence and improves performance, especially when the new dataset shares similarities with COCO. Training from scratch may be suitable for entirely different domains, but pre-trained models retain valuable feature representations that are not fully overwritten during fine-tuning. Let me know if you'd like more resources or examples to explore this further.
So right now I need to run YOLO on real world application, but I only have coco dataset. Is it good if I train on coco and test on my application?
- Glenn JocherUltralytics
Running YOLO on real-world applications after training on the COCO dataset can work well if your application involves detecting objects similar to COCO's 80 categories. However, for domain-specific or unseen objects, fine-tuning on a custom dataset is recommended to improve performance. Let me know if you'd like guidance on fine-tuning.
Yes. Could you please give me the fine-tuning guidance?
- Glenn JocherUltralytics(bearbeitet)
To fine-tune the model for your application, load the pretrained model (e.g.,
yolo26n.pt) and train it on your dataset using thetrainmode. Ensure your dataset is formatted correctly (e.g., COCO format or YAML-configured). For example:from ultralytics import YOLO model = YOLO("yolo26n.pt") # Load the pretrained model results = model.train(data="your_dataset.yaml", epochs=50, imgsz=640)This process adapts the pretrained weights to your specific use case. For more, refer to the Ultralytics training documentation. Let me know if you need further assistance!
If I want to train a custom model on COCO classes, such as person, car, and truck, do I need to train a new model from scratch? Or can I use a pre-trained model and just ignore the predictions of the other classes, even though this might involve more computational cost?
xd775
In your code example for how the .yaml should be set up:
path: ../datasets/my_custom_dataset
train: images/train
val: images/val
test: images/test

# Classes
names:
  0: class1
  1: class2
  ...
How would I specify which of my annotation .jsons to use for the train and val datasets? Also, this thread is confusing me about whether YOLO can read in COCO datasets or if converting to another format is required.
- Glenn JocherUltralytics(bearbeitet)
@xd775 YOLO does not read COCO JSON annotations directly. The provided
coco.yamldownloads COCO already converted to YOLO format (images plus.txtlabel files), so no JSON paths are needed in the YAML. For your own COCO-format JSON, convert it to YOLO labels first withultralytics.data.converter.convert_coco, then point your dataset YAML at the resultingimages/andlabels/folders, as shown in the COCO dataset documentation.
mod777
Hello,
I want to add Goat and give class ID 80 into COOC.yaml data. set Would you mind to tell me in which file (s) i have to changes and how can i add that goat into coco.yaml data set with label and annotation etc etc
I have tried few times but totally unluck detail or step by step would be great full for me to understand. thanks
- Glenn JocherUltralytics
To add a new class like "Goat" to the COCO dataset, you'll need to modify the
coco.yamlfile by adding the class under thenamessection with the desired ID. Additionally, ensure your dataset includes the corresponding labels and annotations for this new class. For detailed guidance on dataset preparation, please refer to the Ultralytics documentation. I have added to goat and deer into coco.yaml file also have added them in annotated files both instances_train2017.json and instances_val2017.json
{
        "supercategory": "animal",
        "id": 91,
        "name": "goat"
    },
    {
        "supercategory": "animal",
        "id": 92,
        "name": "deer"
    },
this is a python code to check Classes in Training JSON: ID: 91, Name: goat, Supercategory: animal ID: 92, Name: deer, Supercategory: animal
Classes in Validation JSON: ID: 91, Name: goat, Supercategory: animal ID: 92, Name: deer, Supercategory: animal
Classes in COCO YAML: ID: 91, Name: goat ID: 92, Name: deer
Additional Information for Goat (ID 91): Annotation for ID 91: BBox: [100, 200, 50, 50], Area: 2500 Annotation for ID 91: BBox: [30.5, 65.3, 30.0, 30.0], Area: 2000.3
Additional Information for Deer (ID 92): Annotation for ID 92: BBox: [150, 250, 60, 60], Area: 3600 Annotation for ID 92: BBox: [45.0, 30.5, 35.5, 40.0], Area: 2500.5
after all these i cant see goat when i test and check my model. as 91: goat
can u please help me? if u want i give give files so u can have a llok is possible
i want to use coco.yaml file class as well as only to add goat in there nothing else
- Glenn JocherUltralytics(bearbeitet)
To add "Goat" to the COCO dataset, ensure you've updated both the
coco.yamlfile and the YOLO-format.txtlabel files correctly. If the class isn't appearing during testing, double-check that the model is trained with the updated dataset and verify the annotations are correctly formatted. If issues persist, consider reviewing the dataset preparation steps or consulting the Ultralytics documentation for further guidance. Hello glenn,
thanks for your reply.
I have change the annotation files instances_train2017.json and instances_val2017.json to assign annotation filed for goat 80 to following fileds
Annotation ID: Image ID: Segmentation: Area: Iscrowd: Category ID:
also add 80: goat at coco.yaml file
now what i should do next to recognize its goat by coco.yaml or yolov5? thanks
I have change the annotation files instances_train2017.json and instances_val2017.json to assign annotation filed for goat 80 to following fileds
Annotation ID: Image ID: Segmentation: Area: Iscrowd: Category ID:
this assigned is done using pythong code. is it ok
its really too hard to incorporate goat into existing coco.yaml file. i have spend long time to do but no luck. Is there any way to add goat only one object into coco.yaml. coz i have to use defauly cooc.yaml file no custom file. but its really hard. Is there a way out?
from ultralytics import YOLO
Load a pretrained model
model = YOLO("yolov5x.pt")
Train the model with your custom data
results = model.train(data="coco.yaml", epochs=100, imgsz=640)
this code is not works for me. i m tired. please help
- Glenn JocherUltralytics
I'm sorry to hear you're having trouble. Please ensure your dataset paths and annotations are correctly set up in the
coco.yamlfile and that your custom data is formatted correctly. If issues persist, reviewing the Ultralytics documentation or community forums may provide additional insights. I have seen few google documentation as well as Ultralytics documentation but everywhere is talk about how to set or train your owned object detection. I can't find anywhere how to include my object into coco.yaml data set. can u give me link for that? thx
- Glenn JocherUltralytics(bearbeitet)
To add a new class like "Goat" to the COCO dataset, ensure you've updated the
coco.yamlfile and the YOLO-format.txtlabel files correctly. Unfortunately, there isn't a specific guide for adding classes to COCO, but you can refer to general dataset preparation tutorials. If you encounter issues, consider checking community forums for additional support. If you encounter issues, consider checking community forums for additional support.
can u recommend few?
- Glenn JocherUltralytics
For community support, consider exploring forums like Stack Overflow, Reddit's r/computervision, or the Ultralytics YOLO GitHub Discussions page. These platforms can provide valuable insights and assistance from other users and developers.
dordanin
how can i train the model only on 5 classes from COCO data set ?
- Glenn JocherUltralytics(bearbeitet)
@dordanin to train on only 5 classes from COCO, use the
classestraining argument with the COCO class ids you want, for examplemodel.train(data="coco.yaml", classes=[0, 1, 2, 3, 5]), oryolo train data=coco.yaml classes=0,1,2,3,5. Editing only thenamesincoco.yamlwould not work because the label files still use the original class ids. For more details, visit COCO Dataset Documentation. Hoozt
This does not work anymore, the training script labels the images as corrupt and are ignored during training.
TanWeeKang
Hi, i used cvat to annotate my images and saved it as coco format. Then i need to convert it to yolov8 format for training. My question is what structure is the dataset format after converting to yolov8 format? From what i see, there will be images, annotations, labels, and yaml file. I dont understand what is that labels file, is it necessary to have in order to train the dataset using yolov8? Can you explain to me what is the labels file?
 Paula DerrengerUltralytics(bearbeitet)
@TanWeeKang hi there!
Great to hear that you're working with CVAT and YOLOv8! When converting your COCO annotations to the YOLOv8 format, the dataset structure will indeed include images, annotations, labels, and a YAML file. Here's a brief overview of each component:
- Images: This folder contains all the images used for training, validation, and testing.
- Annotations: This folder typically holds the original COCO annotations in JSON format.
- Labels: This is a crucial component for YOLO training. The labels folder contains text files where each file corresponds to an image and includes the bounding box coordinates and class labels in YOLO format.
- YAML File: This file (e.g.,
coco.yaml) defines the dataset configuration, including paths to the images and labels, and the class names.
Understanding the Labels File
The labels file is essential for training YOLO models. Each text file in the labels directory corresponds to an image and contains lines of annotations in the following format:
class_id x_center y_center width heightclass_id: The class index of the object.x_center,y_center: The normalized center coordinates of the bounding box (values between 0 and 1).width,height: The normalized width and height of the bounding box (values between 0 and 1).
Example
For an image
image1.jpg, the corresponding label fileimage1.txtmight look like this:0 0.5 0.5 0.2 0.4 1 0.3 0.7 0.1 0.2This indicates two objects: one of class 0 and another of class 1, with their respective bounding box coordinates.
Conversion Tools
To convert COCO annotations to YOLO format, you can use various tools and scripts available online. Ultralytics includes one:
from ultralytics.data.converter import convert_coco; convert_coco(labels_dir="path/to/coco/annotations/"), which writes YOLO labels for you.Training Example
Once your dataset is structured correctly, you can train your YOLOv8 model using the following command:
from ultralytics import YOLO

# Load a model
model = YOLO("yolo26n.pt")  # load a pretrained model (recommended for training)

# Train the model
results = model.train(data="coco.yaml", epochs=100, imgsz=640)
For more detailed information, you can refer to the Ultralytics COCO Dataset Documentation.
If you have any further questions or need additional assistance, feel free to ask. Happy training! 🚀
konstantinos-p
It is very unclear from your docs how to finetune your models. In particular, I would expect an example in the quickstart for the case of finetuning on a custom dataset. It is still unclear to me what should be the format of the labels of the finetuning dataset. I've seen some answers in the comments about the labels being "like COCO" but what does that even mean?
Ok, I've found the relevant page in the docs. I still think that it takes way to long to reach this page. Please consider adding some link in the quickstart.
- Paula DerrengerUltralytics(bearbeitet)
@konstantinos-p thank you for your feedback! Finetuning a YOLO model on a custom dataset involves a few key steps:
-
Dataset Preparation: Labels must be in YOLO format: one
*.txtfile per image, with one row per object inclass x_center y_center width heightformat (normalized 0-1, zero-indexed classes). Images and labels go in siblingimages/andlabels/directories. If your annotations are in COCO JSON format, you can convert them withultralytics.data.converter.convert_coco. See the dataset format guide. -
Dataset YAML Configuration: Create a YAML file that specifies the paths to your training, validation, and test images, as well as the class names:
path: ../datasets/my_custom_dataset train: images/train val: images/val test: images/test # Classes names: 0: class1 1: class2 -
Training the Model: Use the
traincommand to start training your model on the custom dataset:from ultralytics import YOLO # Load a pretrained model model = YOLO("yolo26n.pt") # Train the model on your custom dataset results = model.train(data="path/to/your_custom_dataset.yaml", epochs=100, imgsz=640)yolo detect train data=path/to/your_custom_dataset.yaml model=yolo26n.pt epochs=100 imgsz=640
For more on the COCO dataset itself, refer to our COCO Dataset Documentation. If you have any more questions, feel free to ask. 😊
-
FRAOTIAC
Thanks for the detailed instructions. Could you please clarify the exact directory structure for the train, val, and annotations folders? Specifically, where should these be placed within the dataset root directory?
- Paula DerrengerUltralytics(bearbeitet)
Hello!
For training, the COCO dataset uses this layout under the dataset root (see
coco.yaml):coco/ ├── images/ │ ├── train2017/ # Training images │ ├── val2017/ # Validation images │ └── test2017/ # Test images (optional) ├── labels/ │ ├── train2017/ # YOLO-format .txt labels, one per image │ └── val2017/ ├── train2017.txt # List of training image paths ├── val2017.txt # List of validation image paths └── test-dev2017.txt # List of test image paths (optional)The original COCO
annotations/*.jsonfiles are only needed if you convert the labels yourself withconvert_coco. Training withdata=coco.yamldownloads and prepares the dataset automatically. If you have any more questions, feel free to ask! 😊 casperking666
where do you put the coco.yaml file though?
- Paula DerrengerUltralytics(bearbeitet)
Hi there!
Great question! The
coco.yamlfile should be placed in a directory where your training script can easily access it. Typically, you would place it in the root directory of your project or in a dedicatedconfigsordatasetsfolder within your project structure.Here’s an example of how your project directory might look:
my_yolo_project/
├── coco.yaml
├── datasets/
│   ├── coco/
│   │   ├── annotations/
│   │   │   ├── instances_train2017.json
│   │   │   ├── instances_val2017.json
│   │   │   └── ...
│   │   ├── train2017/
│   │   ├── val2017/
│   │   └── test2017/
├── models/
│   ├── yolo26n.pt
│   └── ...
├── scripts/
│   ├── train.py
│   └── ...
└── ...
In your training script, you would reference the
coco.yamlfile like this:from ultralytics import YOLO # Load a model model = YOLO("yolo26n.pt") # load a pretrained model (recommended for training) # Train the model results = model.train(data="coco.yaml", epochs=100, imgsz=640)Or via the command line:
yolo detect train data=coco.yaml model=yolo26n.pt epochs=100 imgsz=640This setup ensures that the
coco.yamlfile is easily accessible and correctly referenced in your training scripts.If you have any more questions or need further assistance, feel free to ask! 😊
1