TensorRT Export for YOLO26 Models#
Deploying computer vision models in high-performance environments can require a format that maximizes speed and efficiency. This is especially true when you are deploying your model on NVIDIA GPUs.
By using the TensorRT export format, you can optimize your Ultralytics YOLO26 models for fast, efficient inference on NVIDIA hardware. This guide walks through the conversion process and shows how to get the most out of NVIDIA GPUs in your deep learning projects.
TensorRT#
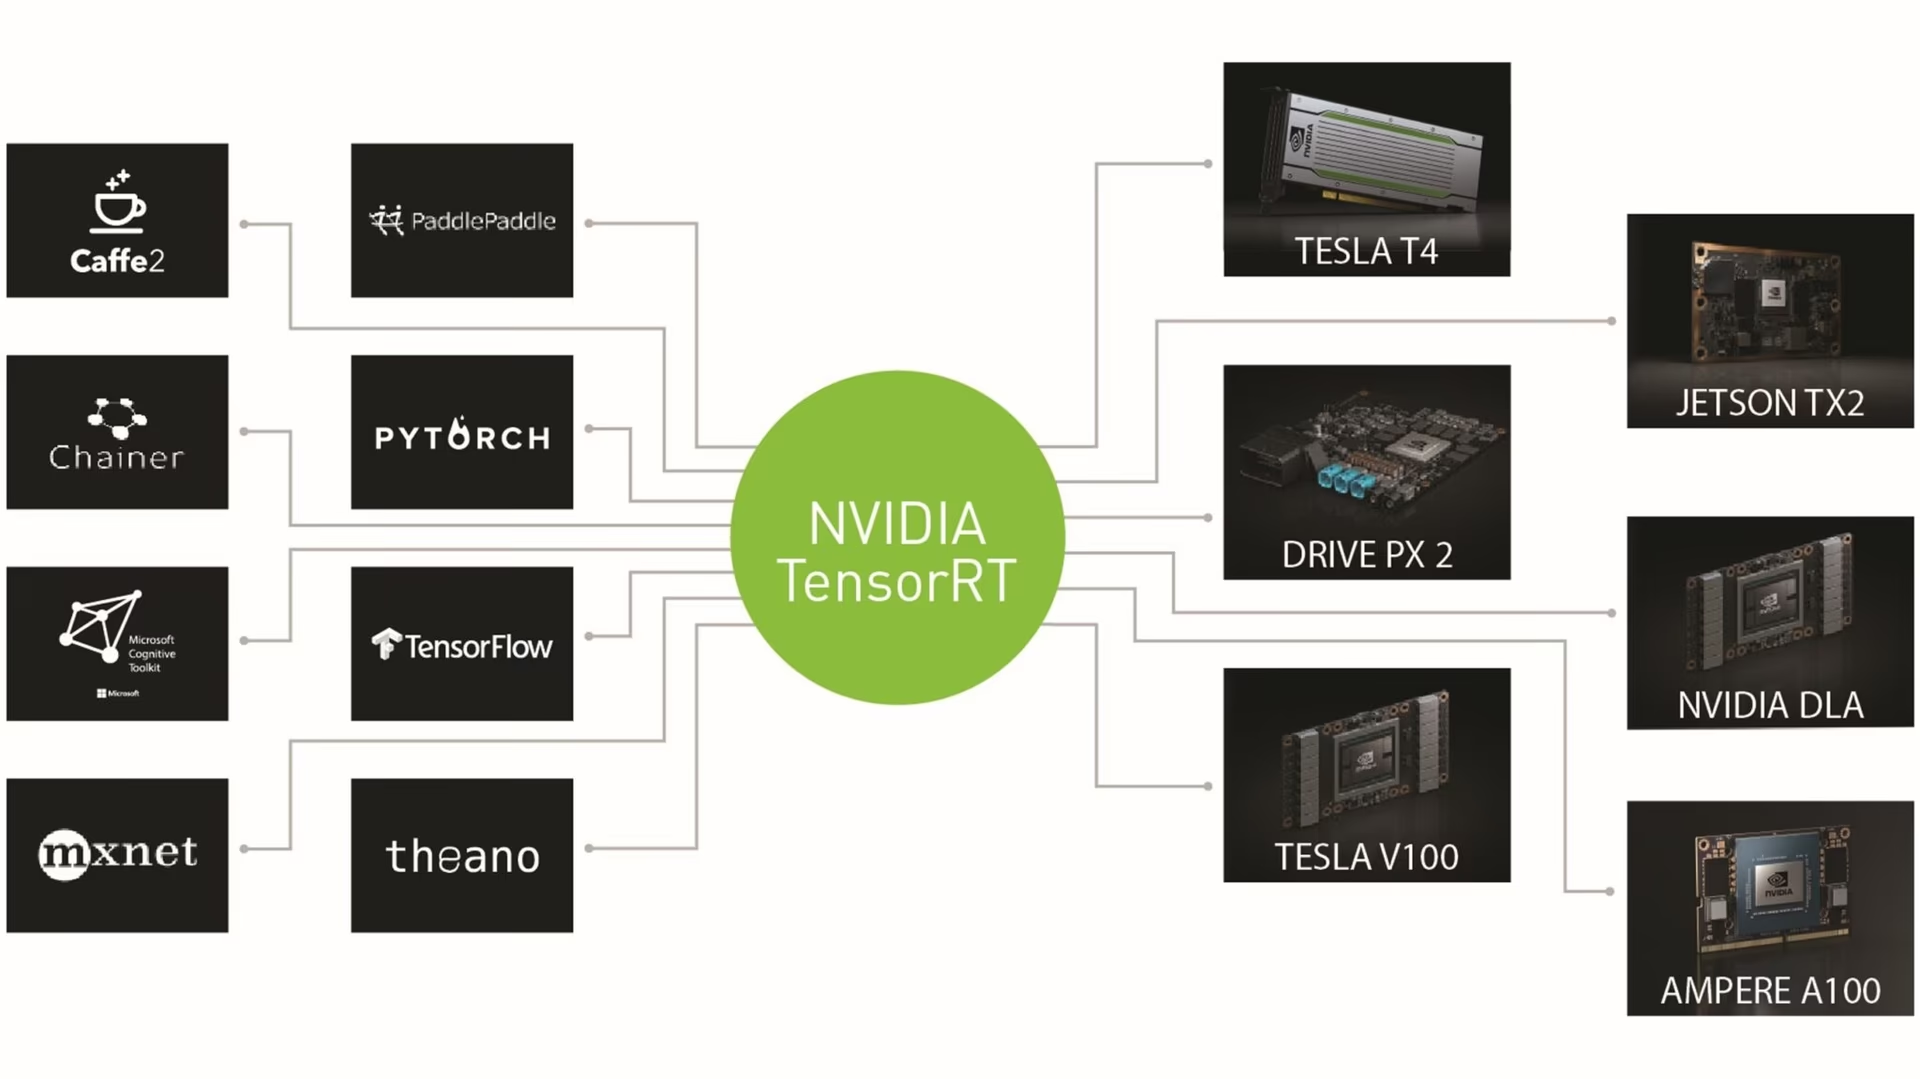
TensorRT, developed by NVIDIA, is an advanced software development kit (SDK) designed for high-speed deep learning inference. It's well-suited for real-time applications like object detection.
This toolkit optimizes deep learning models for NVIDIA GPUs and results in faster and more efficient operations. TensorRT models undergo TensorRT optimization, which includes techniques like layer fusion, precision calibration (INT8 and FP16), dynamic tensor memory management, and kernel auto-tuning. Converting deep learning models into the TensorRT format lets developers make full use of NVIDIA GPUs.
TensorRT is known for its compatibility with various model formats, including TensorFlow, PyTorch, and ONNX, providing developers with a flexible solution for integrating and optimizing models from different frameworks. This versatility enables efficient model deployment across diverse hardware and software environments.
TensorRT profiles and tunes an engine on its build GPU. Build for the deployment GPU architecture and match the TensorRT/CUDA runtime; do not treat an .engine file as a portable model format. For edge deployment, Ultralytics Platform offers eight Jetson target selections, with physical build and validation status documented for each, or you can export locally on the destination device.
Key Features of TensorRT Models#
TensorRT models offer a range of key features that contribute to their efficiency and effectiveness in high-speed deep learning inference:
-
Precision Calibration: TensorRT supports precision calibration, allowing models to be fine-tuned for specific accuracy requirements. This includes support for reduced precision formats like INT8 and FP16, which can further boost inference speed while maintaining acceptable accuracy levels.
-
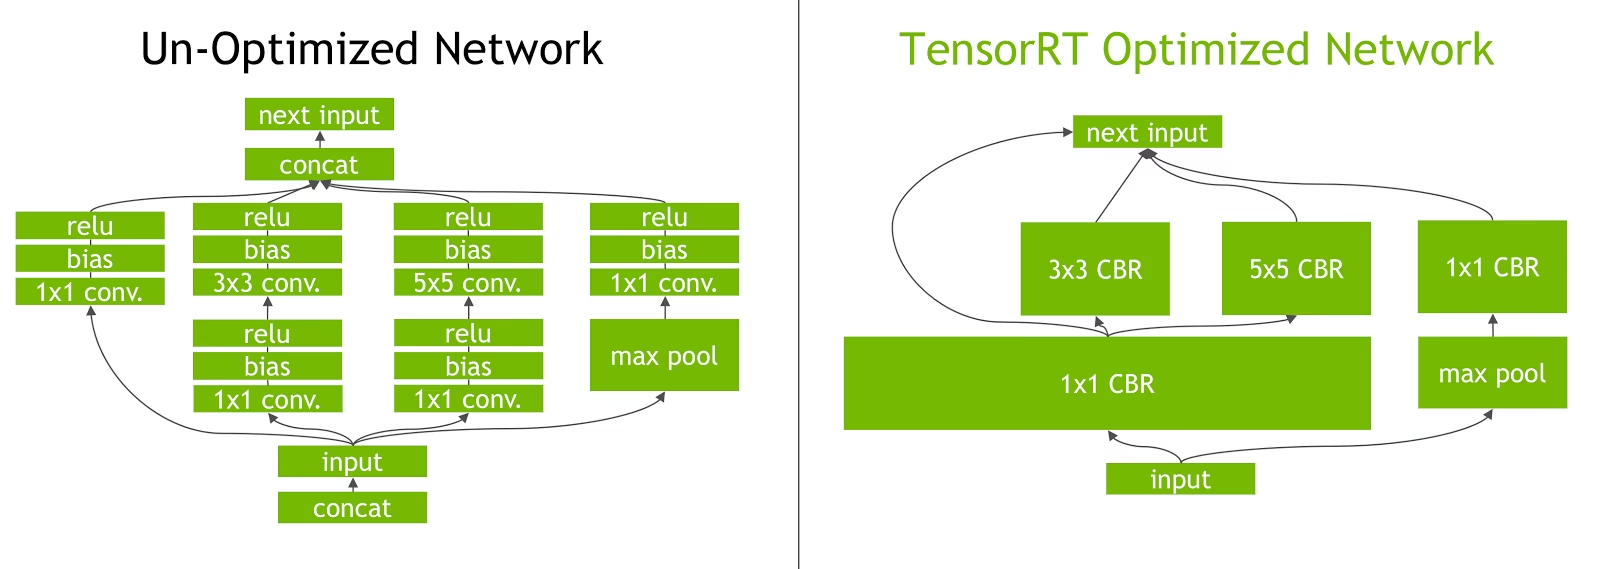
Layer Fusion: The TensorRT optimization process includes layer fusion, where multiple layers of a neural network are combined into a single operation. This reduces computational overhead and improves inference speed by minimizing memory access and computation.
-
Dynamic Tensor Memory Management: TensorRT efficiently manages tensor memory usage during inference, reducing memory overhead and optimizing memory allocation. This results in more efficient GPU memory utilization.
-
Automatic Kernel Tuning: TensorRT applies automatic kernel tuning to select the most optimized GPU kernel for each layer of the model. This adaptive approach ensures that the model takes full advantage of the GPU's computational power.
Deployment Options in TensorRT#
Before looking at the code for exporting YOLO26 models to the TensorRT format, here is where TensorRT models are typically used.
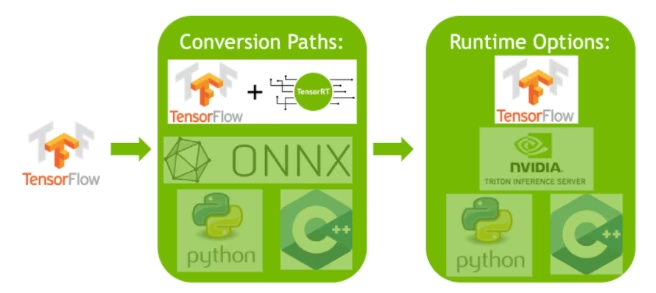
TensorRT offers several deployment options, and each option balances ease of integration, performance optimization, and flexibility differently:
- Deploying within TensorFlow: This method integrates TensorRT into TensorFlow, allowing optimized models to run in a familiar TensorFlow environment. It's useful for models with a mix of supported and unsupported layers, as TF-TRT can handle these efficiently.
-
Standalone TensorRT Runtime API: Offers granular control, ideal for performance-critical applications. It's more complex but allows for custom implementation of unsupported operators.
-
NVIDIA Triton Inference Server: An option that supports models from various frameworks. Particularly suited for cloud or edge inference, it provides features like concurrent model execution and model analysis.
Supported Tasks#
TensorRT export supports all seven Ultralytics tasks. Semantic segmentation and depth estimation are available only with YOLO26, the only family that ships those heads.
Exporting YOLO26 Models to TensorRT#
You can improve execution efficiency and optimize performance by converting YOLO26 models to TensorRT format.
Installation#
To install the required package, run:
# Install the required package for YOLO26
pip install ultralytics
For detailed instructions and best practices related to the installation process, check our YOLO26 Installation guide. While installing the required packages for YOLO26, if you encounter any difficulties, consult our Common Issues guide for solutions and tips.
Usage#
The TensorRT format supports the Export, Predict, and Validate modes. Inference and validation require an NVIDIA GPU. Export your model, then load the exported model to run inference or validate its accuracy.
from ultralytics import YOLO

# Load a YOLO26 model
model = YOLO("yolo26n.pt")

# Export the model to TensorRT format
model.export(format="engine") # creates 'yolo26n.engine'from ultralytics import YOLO
# Load the exported TensorRT model
model = YOLO("yolo26n.engine")
# Run inference
results = model("https://ultralytics.com/images/bus.jpg")from ultralytics import YOLO
# Load the exported TensorRT model
model = YOLO("yolo26n.engine")
# Validate accuracy on the COCO8 dataset
metrics = model.val(data="coco8.yaml")Export Arguments#
| Argument | Type | Default | Description |
|---|---|---|---|
format | str | 'engine' | Target format for the exported model, defining compatibility with various deployment environments. |
imgsz | int or tuple | 640 | Desired image size for the model input. Can be an integer for square images or a tuple (height, width) for specific dimensions. |
quantize | int or str | None | Quantization precision: 16 (FP16) or 8 (INT8/PTQ; needs calibration data/fraction); 32/unset is FP32. A checkpoint trained with quantize=8 always exports INT8 from the ranges it carries, without calibration. Replaces the deprecated half/int8 flags. |
dynamic | bool | False | Allows dynamic input sizes, enhancing flexibility in handling varying image dimensions. |
simplify | bool | True | Simplifies the model graph with onnxslim, potentially improving performance and compatibility. |
opset | int | None | Specifies the ONNX opset version for the intermediate ONNX graph. If not set, uses opset 18 (lower on PyTorch < 2.4), capped at the installed onnx version. |
workspace | float or None | None | Sets the maximum workspace size in GiB for TensorRT optimizations, balancing memory usage and performance; use None for auto-allocation by TensorRT up to device maximum. |
nms | bool, optional | None | Select raw output (None, default), embedded NMS (True), or the NMS-free head (False). |
batch | int | 1 | Specifies export model batch inference size or the max number of images the exported model will process concurrently in predict mode. |
data | str | None | Path to the dataset YAML, essential for quantization; classification instead takes a dataset directory or a built-in dataset name. If omitted with quantize=8, Ultralytics selects the default calibration dataset for the model task; a checkpoint trained with quantize=8 needs none. |
fraction | float, int, or list | 1.0 | Calibration subset as a ratio, image count, or [train, val, test] ratios/counts. Two-item lists leave test full, while 0 skips it. |
device | str | None | Specifies the device for exporting: GPU (device=0), DLA for NVIDIA Jetson (device=dla:0 or device=dla:1). |
Use a GPU with CUDA support when exporting to TensorRT.
TensorRT 11.2.1 does not support JetPack, including Thor; use the TensorRT 10.x runtime supported by your JetPack release. For device=dla:0 or device=dla:1, NVIDIA identifies TensorRT 10.7 as the last release with DLA support. TensorRT 11.x does not support DLA.
For more details about the export process, visit the Ultralytics documentation page on exporting.
Exporting TensorRT with INT8 Quantization#
Exporting Ultralytics YOLO models using TensorRT with INT8 precision executes post-training quantization (PTQ). TensorRT uses calibration for PTQ, which measures the distribution of activations within each activation tensor as the YOLO model processes inference on representative input data, and then uses that distribution to estimate scale values for each tensor. Each activation tensor that is a candidate for quantization has an associated scale that is deduced by a calibration process. A checkpoint fine-tuned with quantize=8 through quantization-aware training already carries its INT8 ranges, so its export uses them and skips calibration.
TensorRT 11 removed implicit quantization and the IInt8Calibrator interface. On TensorRT 11 and newer, Ultralytics performs INT8 quantization with NVIDIA ModelOpt explicit quantization, which inserts Q/DQ nodes into the ONNX graph before building a strongly-typed engine, and FP16 is applied with ModelOpt AutoCast mixed-precision conversion. The quantize=8, quantize=16, and data arguments work the same way; ModelOpt is installed automatically on first use. On TensorRT 7-10 the legacy calibrator described below is used instead.
When processing implicitly quantized networks, TensorRT uses INT8 opportunistically to optimize layer execution time. If a layer runs faster in INT8 and has assigned quantization scales on its data inputs and outputs, then a kernel with INT8 precision is assigned to that layer, otherwise TensorRT selects a precision of either FP32 or FP16 for the kernel based on whichever results in faster execution time for that layer.
It is critical to ensure that the same device that will use the TensorRT model weights for deployment is used for exporting with INT8 precision, as the calibration results can vary across devices.
Configuring INT8 Export#
The arguments provided when using export for an Ultralytics YOLO model will greatly influence the performance of the exported model. They will also need to be selected based on the device resources available, however the default arguments should work for most Ampere (or newer) NVIDIA discrete GPUs. The calibration algorithm used is "MINMAX_CALIBRATION" for GPU exports, while DLA exports on NVIDIA Jetson use "ENTROPY_CALIBRATION_2". You can read more details about the options available in the TensorRT Developer Guide. Ultralytics tests found "MINMAX_CALIBRATION" to be the best choice for GPU exports, and the algorithm is selected automatically based on the export device.
-
workspace: Controls the size (in GiB) of the device memory allocation while converting the model weights.-
Adjust the
workspacevalue according to your calibration needs and resource availability. While a largerworkspacemay increase calibration time, it allows TensorRT to explore a wider range of optimization tactics, potentially enhancing model performance and accuracy. Conversely, a smallerworkspacecan reduce calibration time but may limit the optimization strategies, affecting the quality of the quantized model. -
Default is
workspace=None, which lets TensorRT allocate memory automatically. When configuring manually, this value may need to be increased if calibration crashes (exits without warning). -
TensorRT will report
UNSUPPORTED_STATEduring export if the value forworkspaceis larger than the memory available to the device, which means the value forworkspaceshould be lowered or set toNone. -
If
workspaceis set to max value and calibration fails/crashes, consider usingNonefor auto-allocation or reducing the values forimgszandbatchto reduce memory requirements. -
Remember calibration for INT8 is specific to each device, borrowing a "high-end" GPU for calibration might result in poor performance when inference is run on another device.
-
-
batch: The maximum batch size that will be used for inference. Withdynamic=True, smaller batches can be used during inference, but inference will not accept batches any larger than what is specified.
Using small batches can lead to inaccurate scaling during INT8 calibration. This is because the process adjusts based on the data it sees. Small batches might not capture the full range of values, leading to issues with the final calibration. Using a larger batch size helps ensure more representative calibration results.
Experimentation by NVIDIA led them to recommend using at least 500 calibration images that are representative of the data for your model, with INT8 quantization calibration. This is a guideline and not a hard requirement, and you will need to experiment with what is required to perform well for your dataset. Because TensorRT INT8 export of a checkpoint not trained with quantize=8 uses post-training quantization, pass calibration data with the data argument, for example data="my_dataset.yaml", which uses the images from validation for calibration. A checkpoint trained with quantize=8 skips calibration, so omit data for it. When no value is passed for data with export to TensorRT with INT8 quantization, the default will be to use one of the "small" example datasets based on the model task instead of throwing an error.
from ultralytics import YOLO

model = YOLO("yolo26n.pt")
model.export(
    format="engine",
    dynamic=True,  # (1)!
    batch=8,  # (2)!
    workspace=4,  # (3)!
    quantize=8,
    data="coco.yaml",  # (4)!
)

# Load the exported TensorRT INT8 model
model = YOLO("yolo26n.engine", task="detect")

# Run inference
result = model.predict("https://ultralytics.com/images/bus.jpg")- Exports with dynamic axes, accepting input sizes from 32 pixels up to twice the export
imgsz;dynamicstaysFalseunless set explicitly. See export arguments for additional information. - Sets max batch size of 8 for exported model and INT8 calibration.
- Allocates 4 GiB of memory instead of allocating the entire device for conversion process.
- Uses the COCO dataset for calibration, specifically the images used for validation (5,000 total).
Advantages of using YOLO with TensorRT INT8#
-
Reduced model size: Quantization from FP32 to INT8 can reduce the model size by 4x (on disk or in memory), leading to faster download times, lower storage requirements, and reduced memory footprint when deploying a model.
-
Lower power consumption: Reduced precision operations for INT8 exported YOLO models can consume less power compared to FP32 models, especially for battery-powered devices.
-
Improved inference speeds: TensorRT optimizes the model for the target hardware, potentially leading to faster inference speeds on GPUs, embedded devices, and accelerators.
Note on Inference Speeds
The first few inference calls with a model exported to TensorRT INT8 can be expected to have longer than usual preprocessing, inference, and/or postprocessing times. This may also occur when changing imgsz during inference, especially when imgsz is not the same as what was specified during export (export imgsz is set as TensorRT "optimal" profile).
Drawbacks of using YOLO with TensorRT INT8#
-
Decreases in evaluation metrics: Using a lower precision will mean that mAP, precision, recall or any other metric used to evaluate model performance is likely to be somewhat worse. Sigmoid layers are kept at higher precision to preserve score calibration, but INT8 can still shift confidence values, so select the operating threshold from the INT8 model's own F1 curve.
-
Increased development times: Finding the "optimal" settings for INT8 calibration for dataset and device can take a significant amount of testing.
-
Hardware dependency: Calibration and performance gains could be highly hardware dependent and model weights are less transferable.
Ultralytics YOLO TensorRT Export Performance#
NVIDIA A100#
Tested with Ubuntu 22.04.3 LTS, python 3.10.12, ultralytics==8.2.4, tensorrt==8.6.1.post1
See Detection Docs for usage examples with these models trained on COCO, which include 80 pretrained classes.
Inference times shown for mean, min (fastest), and max (slowest) for each test using pretrained weights yolov8n.engine
| Precision | Eval test | mean (ms) | min | max (ms) | mAPval50(B) | mAPval50-95(B) | batch | size (pixels) |
|---|---|---|---|---|---|---|---|
| FP32 | Predict | 0.52 | 0.51 | 0.56 | 8 | 640 | ||
| FP32 | COCOval | 0.52 | 0.52 | 0.37 | 1 | 640 | |
| FP16 | Predict | 0.34 | 0.34 | 0.41 | 8 | 640 | ||
| FP16 | COCOval | 0.33 | 0.52 | 0.37 | 1 | 640 | |
| INT8 | Predict | 0.28 | 0.27 | 0.31 | 8 | 640 | ||
| INT8 | COCOval | 0.29 | 0.47 | 0.33 | 1 | 640 |
Consumer GPUs#
Tested with Windows 10.0.19045, python 3.10.9, ultralytics==8.2.4, tensorrt==10.0.0b6
Inference times shown for mean, min (fastest), and max (slowest) for each test using pretrained weights yolov8n.engine
| Precision | Eval test | mean (ms) | min | max (ms) | mAPval50(B) | mAPval50-95(B) | batch | size (pixels) |
|---|---|---|---|---|---|---|---|
| FP32 | Predict | 1.06 | 0.75 | 1.88 | 8 | 640 | ||
| FP32 | COCOval | 1.37 | 0.52 | 0.37 | 1 | 640 | |
| FP16 | Predict | 0.62 | 0.75 | 1.13 | 8 | 640 | ||
| FP16 | COCOval | 0.85 | 0.52 | 0.37 | 1 | 640 | |
| INT8 | Predict | 0.52 | 0.38 | 1.00 | 8 | 640 | ||
| INT8 | COCOval | 0.74 | 0.47 | 0.33 | 1 | 640 |
Embedded Devices#
Tested with JetPack 6.0 (L4T 36.3) Ubuntu 22.04.4 LTS, python 3.10.12, ultralytics==8.2.16, tensorrt==10.0.1
Inference times shown for mean, min (fastest), and max (slowest) for each test using pretrained weights yolov8n.engine
| Precision | Eval test | mean (ms) | min | max (ms) | mAPval50(B) | mAPval50-95(B) | batch | size (pixels) |
|---|---|---|---|---|---|---|---|
| FP32 | Predict | 6.11 | 6.10 | 6.29 | 8 | 640 | ||
| FP32 | COCOval | 6.17 | 0.52 | 0.37 | 1 | 640 | |
| FP16 | Predict | 3.18 | 3.18 | 3.20 | 8 | 640 | ||
| FP16 | COCOval | 3.19 | 0.52 | 0.37 | 1 | 640 | |
| INT8 | Predict | 2.30 | 2.29 | 2.35 | 8 | 640 | ||
| INT8 | COCOval | 2.32 | 0.46 | 0.32 | 1 | 640 |
See our quickstart guide on NVIDIA Jetson with Ultralytics YOLO to learn more about setup and configuration.
See our quickstart guide on NVIDIA DGX Spark with Ultralytics YOLO to learn more about setup and configuration.
Evaluation methods#
The tables above were measured with yolov8n models on ultralytics 8.2. Expand sections below for the same export, predict and validation configurations with current arguments.
Export configurations
See export mode for details regarding export configuration arguments.
from ultralytics import YOLO

model = YOLO("yolo26n.pt")

# TensorRT FP32
out = model.export(format="engine", imgsz=640, dynamic=True, verbose=False, batch=8, workspace=2)

# TensorRT FP16
out = model.export(format="engine", imgsz=640, dynamic=True, verbose=False, batch=8, workspace=2, quantize=16)

# TensorRT INT8 with calibration `data` (i.e. COCO, ImageNet, or DOTAv1 for appropriate model task)
out = model.export(
    format="engine", imgsz=640, dynamic=True, verbose=False, batch=8, workspace=2, quantize=8, data="coco8.yaml"
)
Predict loop
See predict mode for additional information.
import cv2

from ultralytics import YOLO

model = YOLO("yolo26n.engine")
img = cv2.imread("path/to/image.jpg")

for _ in range(100):
    result = model.predict(
        [img] * 8,  # batch=8 of the same image
        verbose=False,
        device="cuda",
    )
Validation configuration
See val mode to learn more about validation configuration arguments.
from ultralytics import YOLO

model = YOLO("yolo26n.engine")
results = model.val(
    data="data.yaml",  # COCO, ImageNet, or DOTAv1 for appropriate model task
    batch=1,
    imgsz=640,
    verbose=False,
    device="cuda",
)
Deploying Exported YOLO26 TensorRT Models#
Having successfully exported your Ultralytics YOLO26 models to TensorRT format, you're now ready to deploy them. For in-depth instructions on deploying your TensorRT models in various settings, take a look at the following resources:
-
Deploy Ultralytics with a Triton Server: Our guide on how to use NVIDIA's Triton Inference (formerly TensorRT Inference) Server specifically for use with Ultralytics YOLO models.
-
Deploying Deep Neural Networks with NVIDIA TensorRT: This article explains how to use NVIDIA TensorRT to deploy deep neural networks on GPU-based deployment platforms efficiently.
-
End-to-End AI for NVIDIA-Based PCs: NVIDIA TensorRT Deployment: This blog post explains the use of NVIDIA TensorRT for optimizing and deploying AI models on NVIDIA-based PCs.
-
GitHub Repository for NVIDIA TensorRT: This is the official GitHub repository that contains the source code and documentation for NVIDIA TensorRT.
Summary#
This guide covered converting Ultralytics YOLO26 models to NVIDIA's TensorRT model format. This conversion improves the efficiency and speed of YOLO26 models on NVIDIA hardware across diverse deployment environments.
For more information on usage details, take a look at the TensorRT official documentation.
FAQ#
To convert your Ultralytics YOLO26 models to TensorRT format for optimized NVIDIA GPU inference, follow these steps:
-
Install the required package:
pip install ultralytics -
Export your YOLO26 model:
from ultralytics import YOLO

model = YOLO("yolo26n.pt")
model.export(format="engine")  # creates 'yolo26n.engine'

# Run inference
model = YOLO("yolo26n.engine")
results = model("https://ultralytics.com/images/bus.jpg")
For more details, visit the YOLO26 Installation guide and the export documentation.
-
Using TensorRT to optimize YOLO26 models offers several benefits:
- Faster Inference Speed: TensorRT optimizes the model layers and uses precision calibration (INT8 and FP16) to speed up inference without significantly sacrificing accuracy.
- Memory Efficiency: TensorRT manages tensor memory dynamically, reducing overhead and improving GPU memory utilization.
- Layer Fusion: Combines multiple layers into single operations, reducing computational complexity.
- Kernel Auto-Tuning: Automatically selects optimized GPU kernels for each model layer, ensuring maximum performance.
To learn more, explore the official TensorRT documentation from NVIDIA and our in-depth TensorRT overview.
Yes, you can export YOLO26 models using TensorRT with INT8 quantization. This process involves post-training quantization (PTQ) and calibration, unless the checkpoint was trained with
quantize=8(quantization-aware training), in which case the ranges the checkpoint carries are exported without calibration:-
Export with INT8:
from ultralytics import YOLO model = YOLO("yolo26n.pt") model.export(format="engine", batch=8, workspace=4, quantize=8, data="coco.yaml") -
Run inference:
from ultralytics import YOLO

model = YOLO("yolo26n.engine", task="detect")
result = model.predict("https://ultralytics.com/images/bus.jpg")
For more details, refer to the exporting TensorRT with INT8 quantization section.
-
Deploying YOLO26 TensorRT models on an NVIDIA Triton Inference Server can be done using the following resources:
- Deploy Ultralytics YOLO26 with Triton Server: Step-by-step guidance on setting up and using Triton Inference Server.
- Deploying Deep Neural Networks with NVIDIA TensorRT: NVIDIA's guide on deploying deep learning models with TensorRT for detailed deployment options and configurations.
These guides will help you integrate YOLO26 models efficiently in various deployment environments.
Performance improvements with TensorRT can vary based on the model and hardware used. Here are typical benchmarks measured with YOLOv8n, which illustrate the relative gains from each precision:
-
NVIDIA A100:
- FP32 Inference: ~0.52 ms / image
- FP16 Inference: ~0.34 ms / image
- INT8 Inference: ~0.28 ms / image
- Slight reduction in mAP with INT8 precision, but significant improvement in speed.
-
Consumer GPUs (e.g., RTX 3080):
- FP32 Inference: ~1.06 ms / image
- FP16 Inference: ~0.62 ms / image
- INT8 Inference: ~0.52 ms / image
Detailed performance benchmarks for different hardware configurations can be found in the performance section.
-
Comments116
Ask a question, share your results, or help someone else.
AgbajeAyomipo
Hi Ultralytics team, I’ve trained a YOLOv11 model on (1024x1024) images from a camera feed and now I’m trying to run real-time inference on live streams using a Jetson Orin Nano. I want to maintain full resolution for inference because of accuracy requirements, but currently I'm getting only 1-2 FPS. When I reduce the input size, the FPS improves significantly, but it's not acceptable due to missed detections at lower resolutions. I attempted to export the model to TensorRT using:
model.export(format="engine", imgsz=(2592, 1944), half=True) but it fails silently. If I use a dynamic=true without specifying the imgsz parameter, the export succeeds and uses (1024, 1024). My questions:
Is TensorRT export for such high-resolution input supported/recommended with YOLOv11? If not, is there any known limitation or workaround? Are there ways to improve performance with high-res inference on Jetson Orin Nano? What hardware would you recommend for real-time inference on 1-3 camera streams with 5MP inputs, assuming we need at least ~15-20 FPS per stream? Device: AAEON BOXER-8621AI Module: NVIDIA® Jetson Orin Nano™ (4GB LPDDR5, Super Mode Enabled) Memory: 4 GB LPDDR5 I/O: USB 3.2 Gen 2, M.2 Expansion Operating System: JetPack 5.1.4 (L4T 35.6.0, Ubuntu 20.04) Use Case: Real-time multi-stream 5MP video inference
1martinmclee
Have you gotten any workaround? Perhaps with the YOLO26?
Hi Ultralytics team, I’ve trained a YOLOv11 model on full-size 5MP (2592x1944) images from a camera feed and now I’m trying to run real-time inference on live streams using a Jetson Orin Nano. I want to maintain full resolution for inference because of accuracy requirements, but currently I'm getting only 1-2 FPS. When I reduce the input size, the FPS improves significantly, but it's not acceptable due to missed detections at lower resolutions. I attempted to export the model to TensorRT using:
model.export(format="engine", imgsz=(2592, 1944), half=True)but it fails silently. If I use a dynamic=true, the export succeeds and uses (1024, 1024). My questions:- Is TensorRT export for such high-resolution input supported/recommended with YOLOv11? If not, is there any known limitation or workaround?
- Are there ways to improve performance with high-res inference on Jetson Orin Nano?
- What hardware would you recommend for real-time inference on 1-3 camera streams with 5MP inputs, assuming we need at least ~15-20 FPS per stream? Device: AAEON BOXER-8621AI Module: NVIDIA® Jetson Orin Nano™ (4GB LPDDR5, Super Mode Enabled) Memory: 4 GB LPDDR5 I/O: USB 3.2 Gen 2, M.2 Expansion Operating System: JetPack 5.1.4 (L4T 35.6.0, Ubuntu 20.04) Use Case: Real-time multi-stream 5MP video inference
1020423lzl
m的模型大小比n大的多,速度也慢了很多,输入图像尺寸越大,越吃显存,速度也越慢
李子乐控制工程 @.***
---Original--- From: @.> Date: Sat, May 9, 2026 10:30 AM To: @.>; Cc: @.@.>; Subject: Re: [ultralytics/ultralytics] zh/integrations/tensorrt/ (Discussion #9868)
现在有一个奇怪的现象,我导出的tensorrt模型的推理速度几乎和原来的.pt几乎没有差别甚至更慢,并且导出的tensorrt模型的推理结果和.pt模型的差别很大。 我的设备是i914900k+64G RAM+RTX A6000 我的环境是cuda12.4.131+tensorrt10.10.0.31+torch2.5.1+ultralytics8.3.252 导出命令: yolo export model=yolo11m.pt imgsz=1280 format='engine 推理代码为: model.predict(stream_path, imgsz=1280, classes=[14], conf=0.2, iou=0.5, stream=True, task='detect')
另外我试了下yolo11n.pt的640输入尺寸导出,推理速度就有明显提升,当然推理结果差别仍然较大。 请问这是什么道理,有什么解决办法?
— Reply to this email directly, view it on GitHub, or unsubscribe. Triage notifications on the go with GitHub Mobile for iOS or Android. You are receiving this because you commented.Message ID: @.***>
 User
能不能读完再说话,肯定是m和m比,n和n比,同样尺寸输入和同样尺寸输入的比啊。 该显卡的RT core算力是普通fp32算力的近两倍。
 Glenn JocherUltralytics
是的,性能应当在同一模型、同一
imgsz、同一batch、同一后处理参数下比较;m比n更大、1280比640更吃显存且更慢是正常现象。对 RTX A6000 来说,FP32的 TensorRT 往往不会比.pt明显更快,建议先按 TensorRT 导出文档 用half=True重新导出,并在相同输入上预热后再统计平均耗时;如果engine与.pt结果仍明显不一致,请贴出!yolo checks、完整控制台日志文本和一个最小可复现示例,我们好继续排查环境或后处理差异。
- User
现在有一个奇怪的现象,我导出的tensorrt模型的推理速度几乎和原来的.pt几乎没有差别甚至更慢,并且导出的tensorrt模型的推理结果和.pt模型的差别很大。 我的设备是i914900k+64G RAM+RTX A6000 我的环境是cuda12.4.131+tensorrt10.10.0.31+torch2.5.1+ultralytics8.3.252 导出命令:
yolo export model=yolo11m.pt imgsz=1280 format='engine推理代码为:model.predict(stream_path, imgsz=1280, classes=[14], conf=0.2, iou=0.5, stream=True, task='detect')另外我试了下yolo11n.pt的640输入尺寸导出,推理速度就有明显提升,当然推理结果差别仍然较大。 请问这是什么道理,有什么解决办法?
etson@yahboom:~/ultralytics/ultralytics$ yolo predict model=best.engine source=0 save=False show WARNING ⚠️ Unable to automatically guess model task, assuming 'task=detect'. Explicitly define task for your model, i.e. 'task=detect', 'segment', 'classify','pose' or 'obb'. Ultralytics 8.3.172 🚀 Python-3.10.12 torch-2.5.0a0+872d972e41.nv24.08 CUDA:0 (Orin, 7620MiB) Loading best.engine for TensorRT inference... [12/18/2025-17:11:05] [TRT] [I] Loaded engine size: 75 MiB [12/18/2025-17:11:05] [TRT] [I] [MS] Running engine with multi stream info [12/18/2025-17:11:05] [TRT] [I] [MS] Number of aux streams is 7 [12/18/2025-17:11:05] [TRT] [I] [MS] Number of total worker streams is 8 [12/18/2025-17:11:05] [TRT] [I] [MS] The main stream provided by execute/enqueue calls is the first worker stream [12/18/2025-17:11:05] [TRT] [I] [MemUsageChange] TensorRT-managed allocation in IExecutionContext creation: CPU +1, GPU +88, now: CPU 1, GPU 158 (MiB)
[ WARN:0@2.771] global cap_gstreamer.cpp:1777 open OpenCV | GStreamer warning: Cannot query video position: status=0, value=-1, duration=-1 1/1: 0... Success ✅ (inf frames of shape 1920x1080 at 5.00 FPS)
Traceback (most recent call last): File "/home/jetson/.local/bin/yolo", line 7, in sys.exit(entrypoint()) File "/home/jetson/Downloads/ultralytics-main/ultralytics/cfg/init.py", line 983, in entrypoint getattr(model, mode)(**overrides) # default args from model File "/home/jetson/Downloads/ultralytics-main/ultralytics/engine/model.py", line 555, in predict return self.predictor.predict_cli(source=source) if is_cli else self.predictor(source=source, stream=stream) File "/home/jetson/Downloads/ultralytics-main/ultralytics/engine/predictor.py", line 247, in predict_cli for _ in gen: # sourcery skip: remove-empty-nested-block, noqa File "/usr/local/lib/python3.10/dist-packages/torch/utils/_contextlib.py", line 36, in generator_context response = gen.send(None) File "/home/jetson/Downloads/ultralytics-main/ultralytics/engine/predictor.py", line 351, in stream_inference s[i] += self.write_results(i, Path(paths[i]), im, s) File "/home/jetson/Downloads/ultralytics-main/ultralytics/engine/predictor.py", line 434, in write_results string += f"{result.verbose()}{result.speed['inference']:.1f}ms" File "/home/jetson/Downloads/ultralytics-main/ultralytics/engine/results.py", line 694, in verbose return "".join(f"{n} {self.names[i]}{'s' * (n > 1)}, " for i, n in enumerate(counts) if n > 0) File "/home/jetson/Downloads/ultralytics-main/ultralytics/engine/results.py", line 694, in return "".join(f"{n} {self.names[i]}{'s' * (n > 1)}, " for i, n in enumerate(counts) if n > 0) KeyError: 171 terminate called without an active exception Aborted (core dumped) jetson@yahboom:~/ultralytics/ultralytics$ How to solve it
- Glenn JocherUltralytics
KeyError: 171表示模型输出了类别171,但当前names里没有这个索引(通常是自定义数据集的标签类别编号不在0..nc-1范围内、data.yaml里的names数量与nc不匹配,或导出/推理用的模型与数据配置不一致导致的元数据错配);请先把所有标注.txt的 class id 修正为连续的0..nc-1,同步修正data.yaml的nc/names,修正后删除数据集labels/下的*.cache,再用同一套环境从best.pt重新导出.engine(参考 TensorRT 导出文档),并在推理时显式加上task=detect。另外请把下面命令的完整输出(文本)贴在这个 discussion 里,以及你当时的导出命令,方便我们确认是否有多环境/路径冲突:yolo checks Thank you for your reply. The issue has been resolved. I was using the RT-DETR model, but I mistakenly used "from ultralytics import YOLO" when exporting
- Glenn JocherUltralytics
Glad you found it — RT-DETR models should be loaded/exported with
RTDETR(...)(mixing them withYOLO(...)can produce mismatched metadata likenames), see the RT-DETR model docs for details:from ultralytics import RTDETR model = RTDETR("best.pt") model.export(format="engine") # creates best.engine
fly2skyToEnjoy
May I ask : The following command exports the file, whether the box and mask are both nmsed at the same time ???
from ultralytics import YOLO
Load the YOLO11 model
model = YOLO("yolo11n.pt")
Export the model to TensorRT format
model.export(format="engine") # creates 'yolo11n.engine'
Load the exported TensorRT model
tensorrt_model = YOLO("yolo11n.engine")
Run inference
results = tensorrt_model("https://ultralytics.com/images/bus.jpg")
AK993
这个方法适用于rt-detr吗
dilanpatel195
I am trying to prediction model for the YOLOv11n-seg, I have exported the .py to .engine to back it run faster but keep getting a KEY error message:
KeyError Traceback (most recent call last) Cell In[4], line 109 106 # Inside the main loop after grabbing a frame 107 if inference_active and not inpainting_active: 108 # Perform YOLO inference --> 109 results = model(rgb_frame)[0] 110 masked_image = rgb_frame.copy() # Make a copy for masking 112 # Process YOLO masks (original functionality remains unchanged)
File c:\ProgramData\miniconda3\Lib\site-packages\ultralytics\engine\model.py:176, in Model.call(self, source, stream, **kwargs) 147 def call( 148 self, 149 source: Union[str, Path, int, Image.Image, list, tuple, np.ndarray, torch.Tensor] = None, 150 stream: bool = False, 151 **kwargs, 152 ) -> list: 153 """ 154 Alias for the predict method, enabling the model instance to be callable for predictions. 155 (...) 174 ... print(f"Detected {len(r)} objects in image") 175 """ --> 176 return self.predict(source, stream, **kwargs)
File c:\ProgramData\miniconda3\Lib\site-packages\ultralytics\engine\model.py:554, in Model.predict(self, source, stream, predictor, **kwargs) 552 if prompts and hasattr(self.predictor, "set_prompts"): # for SAM-type models 553 self.predictor.set_prompts(prompts) --> 554 return self.predictor.predict_cli(source=source) if is_cli else self.predictor(source=source, stream=stream)
File c:\ProgramData\miniconda3\Lib\site-packages\ultralytics\engine\predictor.py:168, in BasePredictor.call(self, source, model, stream, *args, **kwargs) 166 return self.stream_inference(source, model, *args, **kwargs) 167 else: --> 168 return list(self.stream_inference(source, model, *args, **kwargs))
File c:\ProgramData\miniconda3\Lib\site-packages\torch\utils_contextlib.py:36, in _wrap_generator..generator_context(*args, **kwargs) 33 try: 34 # Issuing None to a generator fires it up 35 with ctx_factory(): ---> 36 response = gen.send(None) 38 while True: 39 try: 40 # Forward the response to our caller and get its next request
File c:\ProgramData\miniconda3\Lib\site-packages\ultralytics\engine\predictor.py:274, in BasePredictor.stream_inference(self, source, model, *args, **kwargs) 268 self.results[i].speed = { 269 "preprocess": profilers[0].dt * 1e3 / n, 270 "inference": profilers[1].dt * 1e3 / n, 271 "postprocess": profilers[2].dt * 1e3 / n, 272 } 273 if self.args.verbose or self.args.save or self.args.save_txt or self.args.show: --> 274 s[i] += self.write_results(i, Path(paths[i]), im, s) 276 # Print batch results 277 if self.args.verbose:
File c:\ProgramData\miniconda3\Lib\site-packages\ultralytics\engine\predictor.py:334, in BasePredictor.write_results(self, i, p, im, s) 332 result = self.results[i] 333 result.save_dir = self.save_dir.str() # used in other locations --> 334 string += f"{result.verbose()}{result.speed['inference']:.1f}ms" 336 # Add predictions to image 337 if self.args.save or self.args.show:
File c:\ProgramData\miniconda3\Lib\site-packages\ultralytics\engine\results.py:663, in Results.verbose(self) 661 for c in boxes.cls.unique(): 662 n = (boxes.cls == c).sum() # detections per class --> 663 log_string += f"{n} {self.names[int(c)]}{'s' * (n > 1)}, " 664 return log_string
KeyError: 2
Any help would be greatly appreciated!
Ranjith3436
Now, My TensorRT Sengment model used for track. if any detections not there the processing FPS is 75-80 in jetson. But once the person or people detected suddenly reused to 15-20. processing time going to 40ms. only when the object detected. What's the issue in model.track(), could i run all the tracking thing on GPU.
- Glenn JocherUltralytics(edited)
@Ranjith3436 the performance drop when objects are detected is expected behavior, as tracking introduces additional computational overhead. When objects are detected, the model.track() method performs several CPU-bound operations including feature extraction, association, and trajectory management.
To improve performance:
- Try using a smaller model variant (like YOLO26n-seg instead of larger variants)
- Consider reducing the image resolution for tracking
- Optimize tracking parameters by setting
persist=Trueand adjustingconfthresholds higher to track fewer objects - Use
half=True(FP16) orint8=Truewhen exporting your model to TensorRT for maximum GPU acceleration
For the tracking components specifically, the BoT-SORT or ByteTrack algorithms used by Ultralytics do have some CPU-bound operations, but you can minimize their impact with the above optimizations. For more details on tracking optimization, check our tracking documentation.
1
I convert Classification model that i retrained. But it throw the error "amax(): Expected reduction dim 1 to have non-zero size."
- Glenn JocherUltralytics
@Ranjith3436 this error typically occurs when TensorRT encounters an empty dimension during model conversion. For classification models, this could happen if:
- Your model architecture was modified or if you're using a custom architecture
- There might be an issue with batch normalization layers during export
- The class count in your retrained model might be causing dimension mismatches
Try these solutions:
- Ensure your model's forward pass works correctly before export
- Try exporting with
simplify=Falseto preserve the original graph structure - Check if your classification model has the correct output dimension for your number of classes
If the issue persists, share more details about your model architecture and export command for better assistance. For more guidance, refer to our TensorRT integration documentation.
The model trained use yolov8l-cls.pt and the error come from jetson device.
(model): ClassificationModel( (model): Sequential( (0): Conv( (conv): Conv2d(3, 64, kernel_size=(3, 3), stride=(2, 2), padding=(1, 1), bias=False) (bn): BatchNorm2d(64, eps=1e-05, momentum=0.1, affine=True, track_running_stats=True) (act): SiLU(inplace=True) ) (1): Conv( (conv): Conv2d(64, 128, kernel_size=(3, 3), stride=(2, 2), padding=(1, 1), bias=False) (bn): BatchNorm2d(128, eps=1e-05, momentum=0.1, affine=True, track_running_stats=True) (act): SiLU(inplace=True) ) (2): C2f( (cv1): Conv( (conv): Conv2d(128, 128, kernel_size=(1, 1), stride=(1, 1), bias=False) (bn): BatchNorm2d(128, eps=1e-05, momentum=0.1, affine=True, track_running_stats=True) (act): SiLU(inplace=True) ) (cv2): Conv( (conv): Conv2d(320, 128, kernel_size=(1, 1), stride=(1, 1), bias=False) (bn): BatchNorm2d(128, eps=1e-05, momentum=0.1, affine=True, track_running_stats=True) (act): SiLU(inplace=True) ) (m): ModuleList( (0-2): 3 x Bottleneck( (cv1): Conv( (conv): Conv2d(64, 64, kernel_size=(3, 3), stride=(1, 1), padding=(1, 1), bias=False) (bn): BatchNorm2d(64, eps=1e-05, momentum=0.1, affine=True, track_running_stats=True) (act): SiLU(inplace=True) ) (cv2): Conv( (conv): Conv2d(64, 64, kernel_size=(3, 3), stride=(1, 1), padding=(1, 1), bias=False) (bn): BatchNorm2d(64, eps=1e-05, momentum=0.1, affine=True, track_running_stats=True) (act): SiLU(inplace=True) ) ) ) ) (3): Conv( (conv): Conv2d(128, 256, kernel_size=(3, 3), stride=(2, 2), padding=(1, 1), bias=False) (bn): BatchNorm2d(256, eps=1e-05, momentum=0.1, affine=True, track_running_stats=True) (act): SiLU(inplace=True) ) (4): C2f( (cv1): Conv( (conv): Conv2d(256, 256, kernel_size=(1, 1), stride=(1, 1), bias=False) (bn): BatchNorm2d(256, eps=1e-05, momentum=0.1, affine=True, track_running_stats=True) (act): SiLU(inplace=True) ) (cv2): Conv( (conv): Conv2d(1024, 256, kernel_size=(1, 1), stride=(1, 1), bias=False) (bn): BatchNorm2d(256, eps=1e-05, momentum=0.1, affine=True, track_running_stats=True) (act): SiLU(inplace=True) ) (m): ModuleList( (0-5): 6 x Bottleneck( (cv1): Conv( (conv): Conv2d(128, 128, kernel_size=(3, 3), stride=(1, 1), padding=(1, 1), bias=False) (bn): BatchNorm2d(128, eps=1e-05, momentum=0.1, affine=True, track_running_stats=True) (act): SiLU(inplace=True) ) (cv2): Conv( (conv): Conv2d(128, 128, kernel_size=(3, 3), stride=(1, 1), padding=(1, 1), bias=False) (bn): BatchNorm2d(128, eps=1e-05, momentum=0.1, affine=True, track_running_stats=True) (act): SiLU(inplace=True) ) ) ) ) (5): Conv( (conv): Conv2d(256, 512, kernel_size=(3, 3), stride=(2, 2), padding=(1, 1), bias=False) (bn): BatchNorm2d(512, eps=1e-05, momentum=0.1, affine=True, track_running_stats=True) (act): SiLU(inplace=True) ) (6): C2f( (cv1): Conv( (conv): Conv2d(512, 512, kernel_size=(1, 1), stride=(1, 1), bias=False) (bn): BatchNorm2d(512, eps=1e-05, momentum=0.1, affine=True, track_running_stats=True) (act): SiLU(inplace=True) ) (cv2): Conv( (conv): Conv2d(2048, 512, kernel_size=(1, 1), stride=(1, 1), bias=False) (bn): BatchNorm2d(512, eps=1e-05, momentum=0.1, affine=True, track_running_stats=True) (act): SiLU(inplace=True) ) (m): ModuleList( (0-5): 6 x Bottleneck( (cv1): Conv( (conv): Conv2d(256, 256, kernel_size=(3, 3), stride=(1, 1), padding=(1, 1), bias=False) (bn): BatchNorm2d(256, eps=1e-05, momentum=0.1, affine=True, track_running_stats=True) (act): SiLU(inplace=True) ) (cv2): Conv( (conv): Conv2d(256, 256, kernel_size=(3, 3), stride=(1, 1), padding=(1, 1), bias=False) (bn): BatchNorm2d(256, eps=1e-05, momentum=0.1, affine=True, track_running_stats=True) (act): SiLU(inplace=True) ) ) ) ) (7): Conv( (conv): Conv2d(512, 1024, kernel_size=(3, 3), stride=(2, 2), padding=(1, 1), bias=False) (bn): BatchNorm2d(1024, eps=1e-05, momentum=0.1, affine=True, track_running_stats=True) (act): SiLU(inplace=True) ) (8): C2f( (cv1): Conv( (conv): Conv2d(1024, 1024, kernel_size=(1, 1), stride=(1, 1), bias=False) (bn): BatchNorm2d(1024, eps=1e-05, momentum=0.1, affine=True, track_running_stats=True) (act): SiLU(inplace=True) ) (cv2): Conv( (conv): Conv2d(2560, 1024, kernel_size=(1, 1), stride=(1, 1), bias=False) (bn): BatchNorm2d(1024, eps=1e-05, momentum=0.1, affine=True, track_running_stats=True) (act): SiLU(inplace=True) ) (m): ModuleList( (0-2): 3 x Bottleneck( (cv1): Conv( (conv): Conv2d(512, 512, kernel_size=(3, 3), stride=(1, 1), padding=(1, 1), bias=False) (bn): BatchNorm2d(512, eps=1e-05, momentum=0.1, affine=True, track_running_stats=True) (act): SiLU(inplace=True) ) (cv2): Conv( (conv): Conv2d(512, 512, kernel_size=(3, 3), stride=(1, 1), padding=(1, 1), bias=False) (bn): BatchNorm2d(512, eps=1e-05, momentum=0.1, affine=True, track_running_stats=True) (act): SiLU(inplace=True) ) ) ) ) (9): Classify( (conv): Conv( (conv): Conv2d(1024, 1280, kernel_size=(1, 1), stride=(1, 1), bias=False) (bn): BatchNorm2d(1280, eps=1e-05, momentum=0.1, affine=True, track_running_stats=True) (act): SiLU(inplace=True) ) (pool): AdaptiveAvgPool2d(output_size=1) (drop): Dropout(p=0.0, inplace=True) (linear): Linear(in_features=1280, out_features=2, bias=True) ) ) ) )
model architecture
This error sorted out