Come eseguire Ultralytics YOLO26 su un Raspberry Pi con un Coral Edge TPU
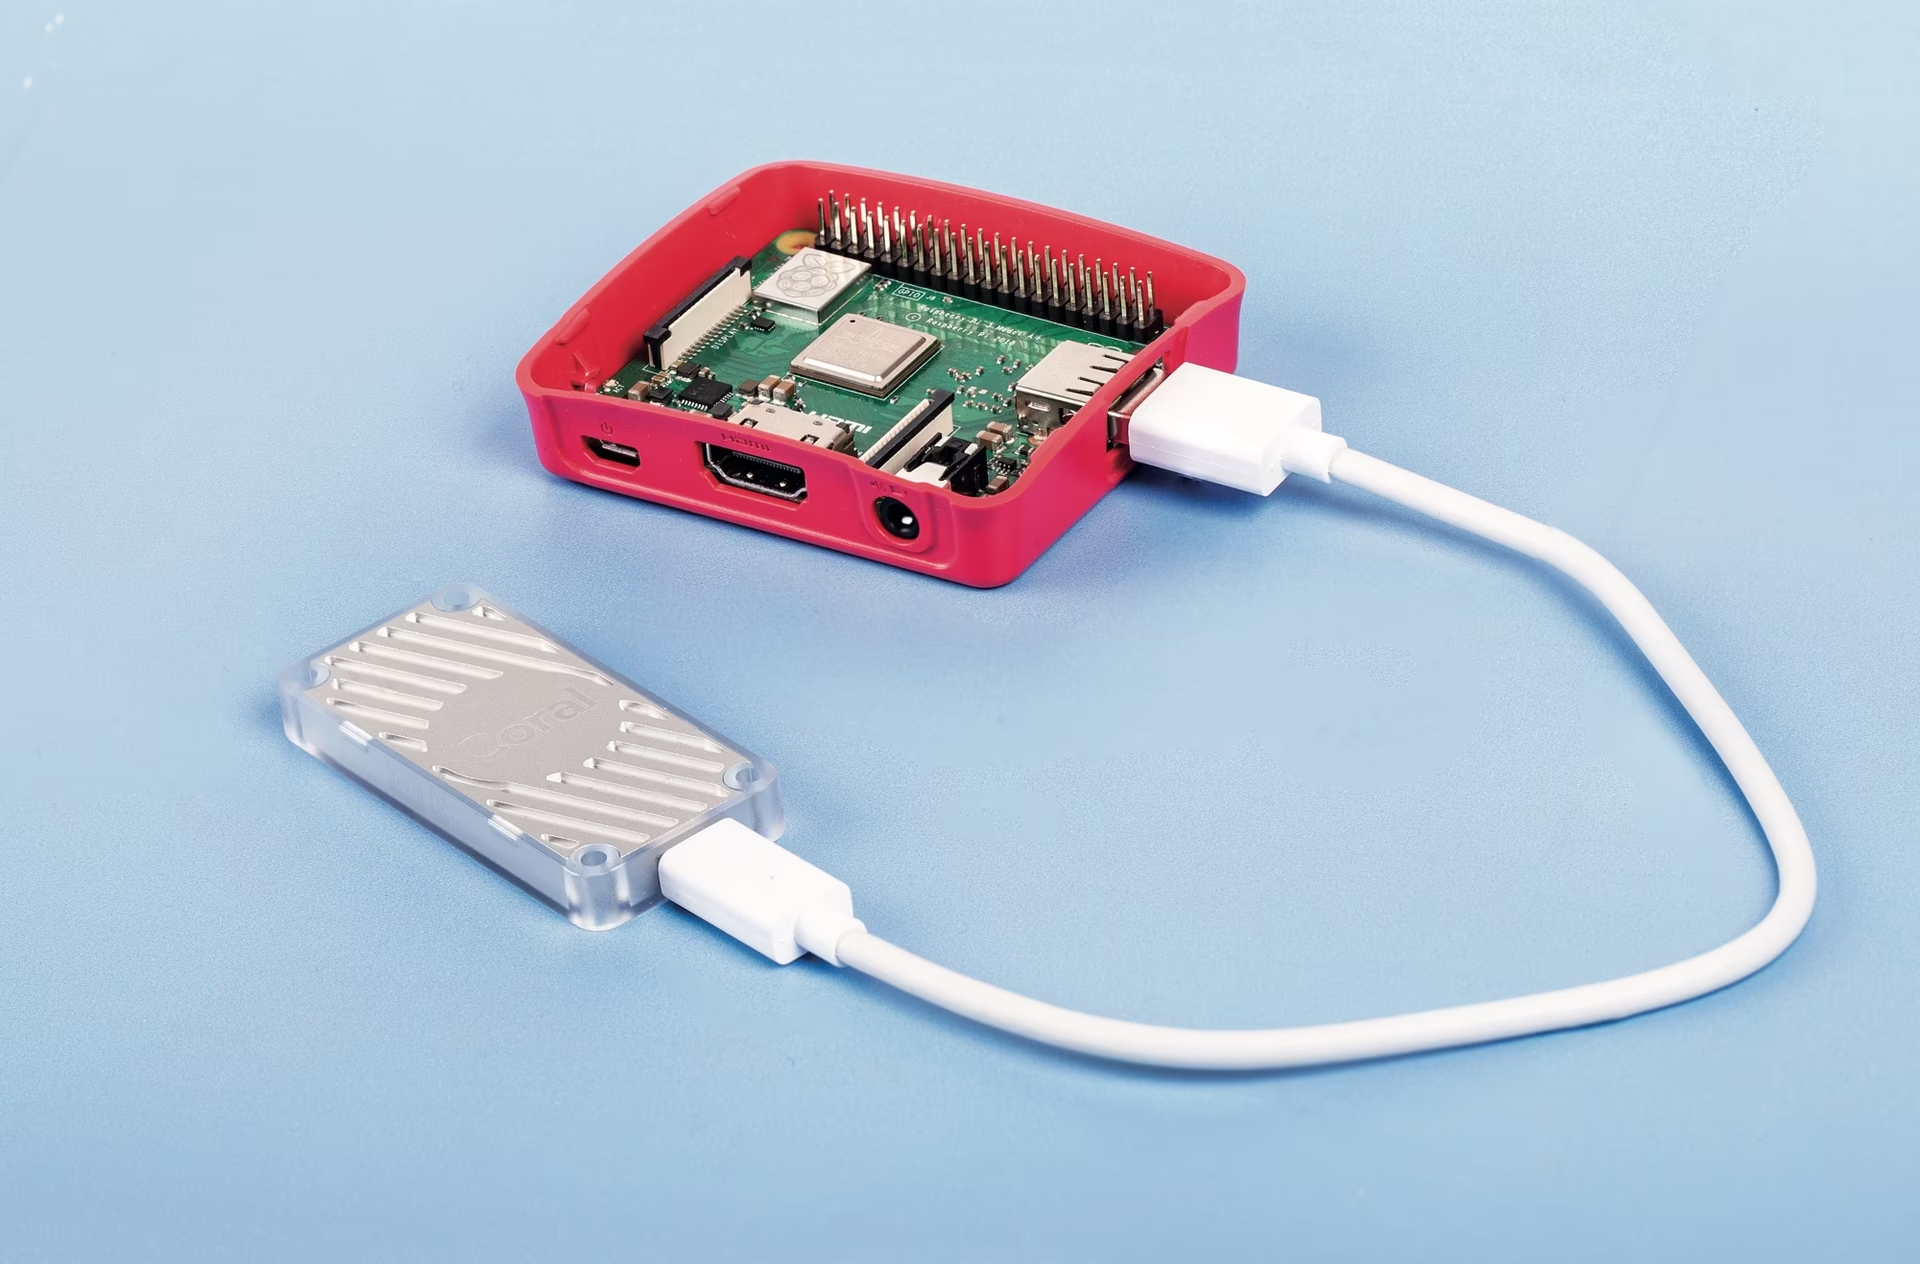
Raspberry Pi è una piattaforma efficiente dal punto di vista energetico ed economica per eseguire la visione artificiale all'edge, ma l'inferenza sul dispositivo è lenta anche con formati ottimizzati come ONNX o OpenVINO. Abbinando al Pi un coprocessore Coral Edge TPU, puoi delegare l'inferenza a hardware dedicato e accelerarla notevolmente. Questa guida mostra come installare il runtime, esportare un modello Ultralytics YOLO26 nel formato Edge TPU ed eseguire inferenze accelerate.
Guarda: Come eseguire inferenze su Raspberry Pi usando Google Coral Edge TPU
Perché usare un Coral Edge TPU?#
Coral Edge TPU è un dispositivo compatto che aggiunge al sistema un coprocessore Edge TPU, consentendo inferenze ML ad alte prestazioni e a basso consumo per i modelli TensorFlow Lite. È adatto alle distribuzioni embedded e mobili in cui una CPU da sola non riesce a tenere il passo:
- Inferenza più veloce — Edge TPU accelera i modelli quantizzati molto più di quanto possa fare da solo il processore CPU di Raspberry Pi.
- Basso consumo energetico — offre un throughput elevato per watt ed è ideale per le distribuzioni alimentate a batteria o a energia solare.
- Plug-and-play — USB Accelerator si collega tramite USB 3.0, quindi non è necessaria alcuna integrazione hardware aggiuntiva.
La guida ufficiale di Coral è obsoleta: le build del runtime originale di Coral non funzionano più con le versioni attuali del runtime TensorFlow Lite e il progetto non ha ricevuto aggiornamenti tra il 2021 e il 2025. Questa guida utilizza un runtime Edge TPU mantenuto attivamente e l'ultima versione di tflite-runtime, così l'acceleratore funziona con un'installazione aggiornata di Raspberry Pi OS.
Prerequisiti#
- Raspberry Pi 4B (consigliati 2 GB o più) oppure Raspberry Pi 5 (consigliato)
- Raspberry Pi OS Bullseye/Bookworm (64 bit) con desktop (consigliato)
- Coral USB Accelerator
- Una piattaforma Linux x86_64 (Google Colab, una macchina Linux x86_64 o il contenitore Docker di Ultralytics su un host x86_64) per esportare il modello, poiché il compilatore Edge TPU è disponibile solo su Linux x86_64
Questa guida presuppone che tu abbia già un'installazione funzionante di Raspberry Pi OS con ultralytics e le relative dipendenze installate. In caso contrario, segui prima la guida rapida.
Con i prerequisiti pronti, il flusso di lavoro prevede tre passaggi: installare il runtime Edge TPU sul Pi, esportare il modello su una macchina Linux x86_64 e eseguire l'inferenza sul Pi.
Installare il runtime Edge TPU#
Il runtime è disponibile in diverse build: scegli quella compatibile con il tuo sistema operativo. La build ad alta frequenza fa funzionare Edge TPU a una frequenza di clock maggiore per ottenere prestazioni migliori, ma può causare throttling termico: se la scegli, usa un sistema di raffreddamento.
| Raspberry Pi OS | Modalità ad alta frequenza | Versione da scaricare |
|---|---|---|
| Bullseye 32 bit | No | libedgetpu1-std_ ... .bullseye_armhf.deb |
| Bullseye 64 bit | No | libedgetpu1-std_ ... .bullseye_arm64.deb |
| Bullseye 32 bit | Sì | libedgetpu1-max_ ... .bullseye_armhf.deb |
| Bullseye 64 bit | Sì | libedgetpu1-max_ ... .bullseye_arm64.deb |
| Bookworm 32 bit | No | libedgetpu1-std_ ... .bookworm_armhf.deb |
| Bookworm 64 bit | No | libedgetpu1-std_ ... .bookworm_arm64.deb |
| Bookworm 32 bit | Sì | libedgetpu1-max_ ... .bookworm_armhf.deb |
| Bookworm 64 bit | Sì | libedgetpu1-max_ ... .bookworm_arm64.deb |
Scarica l'ultima build dalla pagina delle release di libedgetpu, quindi installa il pacchetto .deb:
sudo dpkg -i path/to/package.debDopo aver installato il runtime, collega Coral Edge TPU a una porta USB 3.0 del Raspberry Pi affinché la nuova regola udev possa entrare in vigore.
Prima rimuovi eventuali runtime esistenti
Se hai già installato il runtime Coral Edge TPU, disinstallalo prima di installare una nuova build.
# If you installed the standard version
sudo apt remove libedgetpu1-std

# If you installed the high-frequency version
sudo apt remove libedgetpu1-max
Esportare il modello nel formato Edge TPU#
Per usare Edge TPU, converti il modello nel formato Edge TPU. Esegui l'esportazione su Linux x86_64 — Google Colab, una macchina Linux x86_64, il container Docker ufficiale Ultralytics su un host x86_64 oppure Ultralytics Platform — poiché il compilatore Edge TPU è disponibile solo su Linux x86_64.
from ultralytics import YOLO

# Carica un modello
model = YOLO("path/to/model.pt")  # Carica un modello ufficiale o un modello personalizzato

# Esporta il modello
model.export(format="edgetpu")
Il modello esportato viene salvato nella cartella <model_name>_saved_model/ come <model_name>_full_integer_quant_edgetpu.tflite.
Il nome del file deve terminare con _edgetpu.tflite. Se lo rinomini in qualsiasi altro modo, Ultralytics lo caricherà come un normale modello LiteRT (.tflite), invece di rilevare Edge TPU, e l'acceleratore non verrà utilizzato.
Eseguire l'inferenza su Edge TPU#
Prima di eseguire il modello, installa le librerie corrette sul Raspberry Pi. Se TensorFlow è già installato, disinstallalo prima:
pip uninstall tensorflow tensorflow-aarch64Quindi installa o aggiorna tflite-runtime:
pip install -U tflite-runtimeOra puoi eseguire l'inferenza:
from ultralytics import YOLO

# Carica un modello
model = YOLO("path/to/yolo26n_full_integer_quant_edgetpu.tflite")  # Carica un modello ufficiale o un modello personalizzato

# Esegui la predizione
model.predict("path/to/source.png")
Trovi tutti i dettagli sulla modalità di predizione nella pagina Predizione.
Se hai più Edge TPU, puoi selezionarne una specifica con l'argomento device.
from ultralytics import YOLO

# Carica un modello
model = YOLO("path/to/yolo26n_full_integer_quant_edgetpu.tflite")  # Carica un modello ufficiale o un modello personalizzato

# Esegui la predizione
model.predict("path/to/source.png")  # Per impostazione predefinita, l'inferenza usa la prima TPU

model.predict("path/to/source.png", device="tpu:0")  # Seleziona la prima TPU

model.predict("path/to/source.png", device="tpu:1") # Seleziona la seconda TPUBenchmark#
Le misurazioni seguenti sono state effettuate con Raspberry Pi OS Bookworm a 64 bit e un Coral Edge TPU USB. Indicano solo il tempo di inferenza (escludendo pre e post-elaborazione) e forniscono un riferimento relativo all'accelerazione offerta da Edge TPU sui vari modelli di Pi e modalità.
Questi benchmark sono stati registrati con modelli YOLOv8. I tempi di inferenza assoluti variano in base alla versione del modello e alle dimensioni dell'immagine, ma i miglioramenti relativi della velocità tra i modelli di Pi e le modalità di clock rimangono invariati.
| Dimensioni immagine | Modello | Tempo di inferenza standard (ms) | Tempo di inferenza ad alta frequenza (ms) |
|---|---|---|---|
| 320 | YOLOv8n | 32.2 | 26.7 |
| 320 | YOLOv8s | 47.1 | 39.8 |
| 512 | YOLOv8n | 73.5 | 60.7 |
| 512 | YOLOv8s | 149.6 | 125.3 |
In media:
- Con la modalità standard, Raspberry Pi 5 è più veloce del 22% rispetto a Raspberry Pi 4B.
- Con la modalità ad alta frequenza, Raspberry Pi 5 è più veloce del 30,2% rispetto a Raspberry Pi 4B.
- La modalità ad alta frequenza è più veloce del 28,4% rispetto alla modalità standard.
Conclusione#
Coral Edge TPU trasforma un Raspberry Pi in un dispositivo di inferenza efficiente dal punto di vista energetico e performante per Ultralytics YOLO26. Esporta il modello su una macchina Linux x86_64, mantieni il suffisso _edgetpu.tflite ed eseguilo con tflite-runtime sul Pi per ottenere un'inferenza edge accelerata. Per ulteriori opzioni di distribuzione, consulta la guida Raspberry Pi.
Domande frequenti#
Coral Edge TPU è un dispositivo compatto che aggiunge al sistema un coprocessore Edge TPU. Questo coprocessore consente l'inferenza ML a basso consumo e alte prestazioni, ottimizzata in particolare per i modelli TensorFlow Lite. Su un Raspberry Pi, accelera l'inferenza ben oltre le prestazioni della sola CPU, migliorando notevolmente le prestazioni dei modelli Ultralytics YOLO26.
Scarica il pacchetto
.debappropriato per la tua versione di Raspberry Pi OS dalla pagina delle release di libedgetpu, quindi installalo:sudo dpkg -i path/to/package.debAssicurati di disinstallare tutte le versioni precedenti del runtime Coral Edge TPU seguendo i passaggi nella sezione Installare il runtime Edge TPU.
Sì. Esegui l'esportazione su Google Colab, una macchina Linux x86_64 o il contenitore Docker di Ultralytics; puoi usare anche Ultralytics Platform. Ecco come esportare con Python e CLI:
Esportazione del modellofrom ultralytics import YOLO # Carica un modello model = YOLO("path/to/model.pt") # Carica un modello ufficiale o un modello personalizzato # Esporta il modello model.export(format="edgetpu")Per ulteriori informazioni, consulta la documentazione della modalità di esportazione.
Se hai installato TensorFlow e devi passare a
tflite-runtime, disinstalla prima TensorFlow:pip uninstall tensorflow tensorflow-aarch64Quindi installa o aggiorna
tflite-runtime:pip install -U tflite-runtimePer istruzioni dettagliate, consulta la sezione Eseguire l'inferenza su Edge TPU.
Dopo aver esportato il modello YOLO26 in un formato compatibile con Edge TPU, esegui l'inferenza con i frammenti di codice seguenti. Il file del modello deve mantenere il suffisso
_edgetpu.tfliteaffinché Ultralytics lo carichi su Edge TPU:Esecuzione del modellofrom ultralytics import YOLO # Carica un modello model = YOLO("path/to/yolo26n_full_integer_quant_edgetpu.tflite") # Carica un modello ufficiale o un modello personalizzato # Esegui la predizione model.predict("path/to/source.png")Trovi tutti i dettagli sulla modalità di predizione nella pagina Predizione.


Commenti205
Fai una domanda, condividi i tuoi risultati o aiuta qualcun altro.
DAVIDNYARKO123
I encountered similar challenges and ultimately developed a "solution". I contribute to a PyPI package designed to support the Ultralytics community, specifically for Raspberry Pi users employing the EDGE TPU USB Accelerator. This package simplifies the setup process by ensuring the correct versions of necessary runtimes are installed with just a single pip and setup command. It also provides several default YOLO models for immediate download and experimentation.
I hope this information is useful to you.
GitHub:
https://github.com/DAVIDNYARKO123/edge-tpu-silva
PyPi:
https://pypi.org/project/edge-tpu-silva/
YouTube:
https://www.youtube.com/watch?v=sOxQTRRh9tw
I just posted the video above after seeing this post.
5 Paula DerrengerUltralytics
Hey there! 🌟 Thanks for sharing your work on the
edge-tpu-silvapackage - it sounds like a fantastic resource for the community, especially for those working with Raspberry Pi and the Coral Edge TPU. Your effort to simplify the setup process and provide readily available YOLO models is much appreciated. 🙏For anyone interested in leveraging the power of Coral's Edge TPU on a Raspberry Pi, this package could be a great starting point. I'll definitely check out your YouTube video for a deeper dive into how it all works. 📺💡
Please keep up the great work, and feel free to reach out if you think there are ways we could collaborate or further support your efforts. The link to our guide on using Ultralytics YOLOv8 with a Coral Edge TPU on a Raspberry Pi might also complement your solution: Coral Edge TPU on Raspberry Pi with Ultralytics YOLOv8.
Best of luck with your project, and looking forward to seeing more from you! 🚀
2Hey there! 🌟 Thanks for sharing your work on the
edge-tpu-silvapackage - it sounds like a fantastic resource for the community, especially for those working with Raspberry Pi and the Coral Edge TPU. Your effort to simplify the setup process and provide readily available YOLO models is much appreciated. 🙏For anyone interested in leveraging the power of Coral's Edge TPU on a Raspberry Pi, this package could be a great starting point. I'll definitely check out your YouTube video for a deeper dive into how it all works. 📺💡
Please keep up the great work, and feel free to reach out if you think there are ways we could collaborate or further support your efforts. The link to our guide on using Ultralytics YOLOv8 with a Coral Edge TPU on a Raspberry Pi might also complement your solution: Coral Edge TPU on Raspberry Pi with Ultralytics YOLOv8.
Best of luck with your project, and looking forward to seeing more from you! 🚀
Hello @pderrenger Thank you for the encouraging words! ✨I’m glad you found the edge-tpu-silva package interesting and I’m eager to explore the guide you provided. It was a great complement and inspiration to this work.
I’m open to collaborating and would love to discuss how we can support this project. Looking forward to connecting soon! 🚀
StefansAI
Hi David,
I tried your approach. I always start from a new SD card image of the 64bit Bookworm in the RPi5 and then run the suggested commands. In your case it is:
python3 -m venv .venv
source .venv/bin/activate
pip install edge-tpu-silva
silvatpu-linux-setup
Then I downloaded the first of your exported models and run this line:
silvatpu -p det -m Downloads/240_yolov8n_full_integer_quant_edgetpu.tflite -i /dev/video0 -z 240 -t 0.5 -v TrueThen I get this error:
(.venv) pi@pi5:~ $ silvatpu -p det -m Downloads/240_yolov8n_full_integer_quant_edgetpu.tflite -i /dev/video0 -z 240 -t 0.5 -v True
Traceback (most recent call last):
  File "/home/pi/.venv/lib/python3.11/site-packages/ultralytics/nn/autobackend.py", line 321, in __init__
    from tflite_runtime.interpreter import Interpreter, load_delegate
ModuleNotFoundError: No module named 'tflite_runtime'

During handling of the above exception, another exception occurred:

Traceback (most recent call last):
  File "/home/pi/.venv/bin/silvatpu", line 8, in <module>
    sys.exit(silvatpu())
             ^^^^^^^^^^
  File "/home/pi/.venv/lib/python3.11/site-packages/edge_tpu_silva/__main__.py", line 97, in silvatpu
    for _, _ in outs:
  File "/home/pi/.venv/lib/python3.11/site-packages/edge_tpu_silva/silva/silva_detect.py", line 38, in process_detection
    outs = model.predict(
           ^^^^^^^^^^^^^^
  File "/home/pi/.venv/lib/python3.11/site-packages/ultralytics/engine/model.py", line 445, in predict
    self.predictor.setup_model(model=self.model, verbose=is_cli)
  File "/home/pi/.venv/lib/python3.11/site-packages/ultralytics/engine/predictor.py", line 297, in setup_model
    self.model = AutoBackend(
                 ^^^^^^^^^^^^
  File "/home/pi/.venv/lib/python3.11/site-packages/torch/utils/_contextlib.py", line 115, in decorate_context
    return func(*args, **kwargs)
           ^^^^^^^^^^^^^^^^^^^^^
  File "/home/pi/.venv/lib/python3.11/site-packages/ultralytics/nn/autobackend.py", line 323, in __init__
    import tensorflow as tf
ModuleNotFoundError: No module named 'tensorflow'
I then tried to install tensorflow-aarch64==2.13.1, but ran into problems with dependencies of h5py. Any thoughts?
Hi @StefansAI I will be glad to assist. Please what was the terminal output after running the setup command:
silvatpu-linux-setupDid you see a message indicating successful installation, including the runtime version, at the end of the setup process?
Please list your Python version.
Be sure to use the recommended Python versions. As well as your apt-get is updated and upraded
sudo apt-get update
sudo apt-get upgrade
Decoo13
Hey David, thanks again for the information!
everything went smoothly for me I followed the README instructiions and everything worked well on my end. I would like to note that I did place everything in the home directory to make things simpler in terms of placing the correct path for each of the files.
- Paula DerrengerUltralytics
Hey David,
That's fantastic to hear! 🚀 Glad the setup went smoothly for you. Placing everything in the home directory can indeed simplify managing paths, especially for newcomers. It's a practical tip that could benefit many users, so thanks for highlighting it!
For anyone else following this thread, remember to check the Raspberry Pi model and OS compatibility, especially for tasks involving hardware accelerators like the Coral Edge TPU. Our documentation provides a detailed guide for setups like these, ensuring you get the best performance out of your Edge TPU and Raspberry Pi combo.
Keep exploring and sharing your insights, David! If you've got more questions or run into hiccups, feel free to drop them here. 🌟
suprimex
Any export above version 9 failed with message from edgetpu_compiler:
ERROR: Didn't find op for builtin opcode 'CONV_2D' version '6'. An older version of this builtin might be supported. Are you using an old TFLite binary with a newer model?
ERROR: Registration failed.
Invalid model: yolov10n_saved_model/yolov10n_full_integer_quant.tflite Model could not be parsed
1zoldaten
to get it working (USB Asselerator) on raspberry pi 4b (Bullseye or Bookworm):
- do not use https://github.com/feranick/libedgetpu, do not follow instruction from ultralytics on HOW TO INSTALL coral usb asselerator from this page - it leads to Segmentation fault (i checked it out on my pi).
follow official https://coral.ai/docs/accelerator/get-started/#requirements to install on Linux.
After that:
Download pycoral-2.0.0-cp39-cp39-linux_aarch64.whl and tflite_runtime-2.5.0.post1-cp39-cp39-linux_aarch64.whl from https://github.com/google-coral/pycoral/releases/tag/v2.0.0 pip install ./pycoral-2.0.0-cp39-cp39-linux_aarch64.whl pip install ./tflite_runtime-2.5.0.post1-cp39-cp39-linux_aarch64.whl
- i have updated example from @DAVIDNYARKO123 to use yolov8 with image not video file:
from edge_tpu_silva import process_detection
import cv2,time
import numpy as np
from ultralytics import YOLO

# Example Usage with Required Parameters
#model_path = '240_yolov8n_full_integer_quant_edgetpu.tflite'
#input_path = 'path/to/your/input/video.mp4'
input_path = 'obama.jpg'
imgsz = 240

model = YOLO(model='240_yolov8n_full_integer_quant_edgetpu.tflite', task="detect", verbose=False)

input_path=cv2.imread(input_path)
print(input_path.shape)
input_path = input_path[:,:,:3]
#image = cv2.resize(np_array, (240, 240))

#input_path = np.expand_dims(input_path, axis=0)

# Run the object detection process
start_time = time.time()
outs = model.predict(
    source=input_path,
    conf=0.5,
    imgsz=imgsz,
    verbose=False,
    stream=False,
    show=True,    )
#outs = process_detection(model_path, input_path, imgsz, show=True)


#frame_count = 0
start_time = time.time()
for out in outs:

    objs_lst = []
    for box in out.boxes:
        obj_cls, conf, bb = (
            box.cls.numpy()[0],
            box.conf.numpy()[0],
            box.xyxy.numpy()[0],
        )
        label = out.names[int(obj_cls)]
        ol = {
            "id": obj_cls,
            "label": label,
            "conf": conf,
            "bbox": bb,
        }
        objs_lst.append(ol)


        print(label)
        #print("  id:    ", obj_cls)
        #print("  score: ", conf)
        #print("  bbox:  ", bb)

    #frame_count += 1
    #elapsed_time = time.time() - start_time
    #fps = frame_count / elapsed_time

    #print (objs_lst, fps)
    print (objs_lst)
    print("--- %s seconds ---" % (time.time() - start_time))

    # Break the loop if 'esc' key is pressed for video or camera
    if cv2.waitKey(1) == 27:
        break
#for _, _ in outs:
  #pass
you can also see example with picamera2 on Bullseye - https://youtu.be/37PwrRVP9j4
- there is a problem with Coral USB on Raspbian Bookworm as it uses python3.11 as system default. It could be solved with pyenv or venv but there will be a problem with picamera2 as it uses libcamera. So only i got reached there - gstreamer using instead picamera2.
Have a nice day.
1i also tried to convert by hands yolov8m to edgetpu on another linux PC:
yolo export model=yolov8m.pt imgsz=640and got this:
Operation log: yolov8m_saved_model/yolov8m_full_integer_quant_edgetpu.log

Model successfully compiled but not all operations are supported by the Edge TPU. A percentage of the                                                       model will instead run on the CPU, which is slower. If possible, consider updating your model to use o                                                      nly operations supported by the Edge TPU. For details, visit g.co/coral/model-reqs.
Number of operations that will run on Edge TPU: 297
Number of operations that will run on CPU: 26

Operator                       Count      Status

PAD                            7          Mapped to Edge TPU
TRANSPOSE                      1          Mapped to Edge TPU
TRANSPOSE                      4          Operation is otherwise supported, but not mapped due to some                                                       unspecified limitation
STRIDED_SLICE                  2          More than one subgraph is not supported
STRIDED_SLICE                  16         Mapped to Edge TPU
STRIDED_SLICE                  2          Operation is otherwise supported, but not mapped due to some                                                       unspecified limitation
RESHAPE                        2          More than one subgraph is not supported
RESHAPE                        1          Mapped to Edge TPU
RESHAPE                        3          Operation is otherwise supported, but not mapped due to some                                                       unspecified limitation
MUL                            77         Mapped to Edge TPU
MUL                            2          More than one subgraph is not supported
SUB                            2          More than one subgraph is not supported
CONCATENATION                  16         Mapped to Edge TPU
CONCATENATION                  1          More than one subgraph is not supported
CONCATENATION                  2          Operation is otherwise supported, but not mapped due to some                                                       unspecified limitation
SOFTMAX                        1          More than one subgraph is not supported
RESIZE_NEAREST_NEIGHBOR        2          Mapped to Edge TPU
CONV_2D                        1          More than one subgraph is not supported
CONV_2D                        83         Mapped to Edge TPU
QUANTIZE                       1          Operation is otherwise supported, but not mapped due to some                                                       unspecified limitation
QUANTIZE                       2          Mapped to Edge TPU
MAX_POOL_2D                    3          Mapped to Edge TPU
ADD                            2          More than one subgraph is not supported
ADD                            12         Mapped to Edge TPU
LOGISTIC                       1          Operation is otherwise supported, but not mapped due to some                                                       unspecified limitation
LOGISTIC                       77         Mapped to Edge TPU
Compilation child process completed within timeout period.
Compilation succeeded!
after test on raspberry in the same code (as above):
Loading yolov8m_full_integer_quant_edgetpu.tflite for TensorFlow Lite Edge TPU inference...
F driver/usb/usb_driver.cc:857] transfer on tag 1 failed. Abort. Deadline exceeded: USB transfer error 2 [LibUsbDataOutCallback]

Process ended with exit code -6.
and leads to hang on Coral USB ...
ok. fixed issue with conversion. should be: yolo export model=yolov8m.pt imgsz=224 not yolo export model=yolov8m.pt imgsz=640
image size matter. hmm.
 Glenn JocherUltralytics
@zoldaten great catch on the image size adjustment for the model export! Indeed, the input size can significantly impact the compatibility and performance of the model on the Edge TPU. Using an image size of 224 for
yolov8m.ptseems to be more effective for your setup.Thanks for sharing this update; it's a valuable tip for others working in similar configurations. If you encounter any more insights or need further assistance, feel free to reach out. Happy coding! 🚀
SkillnoobUltralytics
Hey @zoldaten Im the one who wrote this guide and you getting a segmentation fault with this guide is unusual, since it is made to prevent the segmentation fault many people got because of the libedgetpu version that is out of date by 3 years. The version by feranic was specifically made to fix this issue and the changes are also now merged into the official libedgetpu repository. I am using feranic's version and it works fine for me on both my RPI 5 and 4B. The coral tpu doesn't work well with a imgsz of 640 and maps most of the OP's to the cpu. Additionally I had issues running models larger than s because they would exceed the 8MB cache limit of the tpu. Here's some benchmark results I posted: https://github.com/ultralytics/ultralytics/issues/8035 I always had to use a imgsz of 512 or lower for it to not run at CPU speeds.
reza8iucs(modificato)
Got the Coral working on a Raspberry Pi 5 / Debian 13 (Bookworm/Trixie) / Python 3.13 after the "parrot test" failed for weeks — here's the fix this guide is missing:
The No.1 reason Failed to load delegate from libedgetpu.so.1 happens (even when the device is detected and permissions are fine) is that libedgetpu and tflite-runtime must be built from the same TensorFlow version. This guide has you install them from two separate places (libedgetpu from Feranick's .deb, tflite-runtime from pip -U), and "latest + latest" almost never matches — so the delegate refuses to load. Pin both to the same TF version.
Working combo for me (June 2026):
- libedgetpu1-std tag 16.0TF2.17.1 (Feranick build, pick your Debian codename + arm64)
- tflite_runtime 2.17.1 (Feranick build)
- numpy < 2 (tflite-runtime 2.17.1 is compiled against NumPy 1.x and crashes on NumPy 2)
Two more gotchas on a modern Pi:
- Python 3.13 has no tflite-runtime/pycoral wheel (official tops out at 3.9; Feranick at 3.12). I ran the Coral stack on a separate Python 3.12 via uv (uv python install 3.12) and it worked perfectly.
- Debian 12/13 block system-wide pip (PEP 668) — use a venv.
Quick steps:
1. runtime (match the TF version!)
sudo apt install ./libedgetpu1-std_16.0tf2.17.1-1._arm64.deb # from github.com/feranick/libedgetpu
2. python 3.12 venv
uv python install 3.12 && uv venv ~/coral/venv --python 3.12
3. matching tflite-runtime + numpy<2 (wheel from github.com/feranick/TFlite-builds)
uv pip install --python ~/coral/venv/bin/python
tflite_runtime-2.17.1-cp312-cp312-linux_aarch64.whl "numpy<2" pillowThen the parrot test prints macaw and you're done. The rule to remember: same TF version on both halves, a Python the wheel exists for, and numpy<2.
Hope this helps
- Glenn JocherUltralytics
Thanks for sharing this here — the
libedgetpuandtflite-runtimeTensorFlow version match,numpy<2, and using a Python 3.12 venv on newer Debian/Pi setups are all useful notes, and we’ll review updating the Coral Edge TPU on Raspberry Pi guide to make those requirements clearer.1
kiven-mailbox
Hi, I am converting my Yolo11n model to edgetpu.tflite but the case is that when I run the yolo11n model in my pi it is very accurate but very slow it only got 2.50 fps so then I converted it to edgetpu.tflite it run smoothly with 10 fps with the coral usb accelerator but the detection loss its accuracy so then i tried retraining my model's dataset and set to 320 instead of 640 and then I converted it to edgetpu.tflite with imgsz=320 as they said to maintain the accuracy but the accuracy still not the same it detects object wrong object and not what it trained for.
Can you try adding the
dataargument when exporting and have it point to your dataset yaml so it can calibrate?... model.export(format='edgetpu', imgsz=320, data='data.yaml')1Oh okay, I’ll try adding the data argument and point it to my dataset YAML file. Hopefully that helps with the calibration. Thanks for the heads-up!
Hi the result is the same.
from ultralytics import YOLO

# Load the YOLO11 model
model = YOLO("yolo11n.pt")

# Export the model to TFLite Edge TPU format
model.export(format="edgetpu", imgsz=320, data='data.yaml')  # creates 'yolo11n_full_integer_quant_edgetpu.tflite'
Result
Creating new Ultralytics Settings v0.0.6 file ✅
View Ultralytics Settings with 'yolo settings' or at '/root/.config/Ultralytics/settings.json'
Update Settings with 'yolo settings key=value', i.e. 'yolo settings runs_dir=path/to/dir'. For help see https://docs.ultralytics.com/quickstart/#ultralytics-settings.
Ultralytics 8.3.152 🚀 Python-3.11.13 torch-2.6.0+cu124 CPU (Intel Xeon 2.20GHz)
💡 ProTip: Export to OpenVINO format for best performance on Intel CPUs. Learn more at https://docs.ultralytics.com/integrations/openvino/
YOLO11n summary (fused): 100 layers, 2,583,517 parameters, 0 gradients, 6.3 GFLOPs

PyTorch: starting from 'yolo11n.pt' with input shape (1, 3, 320, 320) BCHW and output shape(s) (1, 11, 2100) (5.2 MB)
requirements: Ultralytics requirements ['sng4onnx>=1.0.1', 'onnx_graphsurgeon>=0.3.26', 'ai-edge-litert>=1.2.0', 'onnx>=1.12.0,<1.18.0', 'onnx2tf>=1.26.3', 'onnxslim>=0.1.56', 'onnxruntime'] not found, attempting AutoUpdate...

requirements: AutoUpdate success ✅ 8.7s
WARNING ⚠️ requirements: Restart runtime or rerun command for updates to take effect


TensorFlow SavedModel: starting export with tensorflow 2.18.0...
Downloading https://github.com/ultralytics/assets/releases/download/v8.3.0/calibration_image_sample_data_20x128x128x3_float32.npy.zip to 'calibration_image_sample_data_20x128x128x3_float32.npy.zip'...
100%|██████████| 1.11M/1.11M [00:00<00:00, 163MB/s]
Unzipping calibration_image_sample_data_20x128x128x3_float32.npy.zip to /content/calibration_image_sample_data_20x128x128x3_float32.npy...: 100%|██████████| 1/1 [00:00<00:00, 34.85file/s]

ONNX: starting export with onnx 1.17.0 opset 19...
ONNX: slimming with onnxslim 0.1.56...
ONNX: export success ✅ 4.9s, saved as 'yolo11n.onnx' (10.0 MB)
TensorFlow SavedModel: collecting INT8 calibration images from 'data=data.yaml'
Downloading https://ultralytics.com/assets/Arial.ttf to '/root/.config/Ultralytics/Arial.ttf'...
100%|██████████| 755k/755k [00:00<00:00, 108MB/s]Fast image access ✅ (ping: 0.0±0.0 ms, read: 2612.2±485.1 MB/s, size: 560.8 KB)

Scanning /content/content/data/validation/labels... 129 images, 0 backgrounds, 0 corrupt: 100%|██████████| 129/129 [00:00<00:00, 1043.00it/s]New cache created: /content/content/data/validation/labels.cache
WARNING ⚠️ TensorFlow SavedModel: >300 images recommended for INT8 calibration, found 129 images.

TensorFlow SavedModel: starting TFLite export with onnx2tf 1.27.10...
Saved artifact at 'yolo11n_saved_model'. The following endpoints are available:

* Endpoint 'serving_default'
  inputs_0 (POSITIONAL_ONLY): TensorSpec(shape=(1, 320, 320, 3), dtype=tf.float32, name='images')
Output Type:
  TensorSpec(shape=(1, 11, 2100), dtype=tf.float32, name=None)
Captures:
  135841429101968: TensorSpec(shape=(4, 2), dtype=tf.int32, name=None)
  135841429100240: TensorSpec(shape=(3, 3, 3, 16), dtype=tf.float32, name=None)
  135841429102352: TensorSpec(shape=(16,), dtype=tf.float32, name=None)
  135841429103888: TensorSpec(shape=(4, 2), dtype=tf.int32, name=None)
  135841429106576: TensorSpec(shape=(3, 3, 16, 32), dtype=tf.float32, name=None)
  135841429107152: TensorSpec(shape=(32,), dtype=tf.float32, name=None)
  135841429106192: TensorSpec(shape=(1, 1, 32, 32), dtype=tf.float32, name=None)
  135841429107536: TensorSpec(shape=(32,), dtype=tf.float32, name=None)
  135841429108112: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841429107920: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841429110416: TensorSpec(shape=(3, 3, 16, 8), dtype=tf.float32, name=None)
  135841429109840: TensorSpec(shape=(8,), dtype=tf.float32, name=None)
  135841429107728: TensorSpec(shape=(3, 3, 8, 16), dtype=tf.float32, name=None)
  135841429107344: TensorSpec(shape=(16,), dtype=tf.float32, name=None)
  135841429108304: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841429108496: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841429109648: TensorSpec(shape=(1, 1, 48, 64), dtype=tf.float32, name=None)
  135841429109072: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841408582288: TensorSpec(shape=(4, 2), dtype=tf.int32, name=None)
  135841408582096: TensorSpec(shape=(3, 3, 64, 64), dtype=tf.float32, name=None)
  135841408581904: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841408582480: TensorSpec(shape=(1, 1, 64, 64), dtype=tf.float32, name=None)
  135841408582864: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841408583632: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841408583248: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841408584208: TensorSpec(shape=(3, 3, 32, 16), dtype=tf.float32, name=None)
  135841408585552: TensorSpec(shape=(16,), dtype=tf.float32, name=None)
  135841408583056: TensorSpec(shape=(3, 3, 16, 32), dtype=tf.float32, name=None)
  135841408583440: TensorSpec(shape=(32,), dtype=tf.float32, name=None)
  135841408582672: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841408583824: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841408585744: TensorSpec(shape=(1, 1, 96, 128), dtype=tf.float32, name=None)
  135841408585936: TensorSpec(shape=(128,), dtype=tf.float32, name=None)
  135841408584976: TensorSpec(shape=(4, 2), dtype=tf.int32, name=None)
  135841408584400: TensorSpec(shape=(3, 3, 128, 128), dtype=tf.float32, name=None)
  135841408584784: TensorSpec(shape=(128,), dtype=tf.float32, name=None)
  135841408586128: TensorSpec(shape=(1, 1, 128, 128), dtype=tf.float32, name=None)
  135841408586512: TensorSpec(shape=(128,), dtype=tf.float32, name=None)
  135841408587088: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841408586896: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841408587856: TensorSpec(shape=(1, 1, 64, 32), dtype=tf.float32, name=None)
  135841408589200: TensorSpec(shape=(32,), dtype=tf.float32, name=None)
  135841408589584: TensorSpec(shape=(3, 3, 32, 32), dtype=tf.float32, name=None)
  135841408589392: TensorSpec(shape=(32,), dtype=tf.float32, name=None)
  135841408586320: TensorSpec(shape=(3, 3, 32, 32), dtype=tf.float32, name=None)
  135841408588624: TensorSpec(shape=(32,), dtype=tf.float32, name=None)
  135841408589968: TensorSpec(shape=(3, 3, 32, 32), dtype=tf.float32, name=None)
  135841408590160: TensorSpec(shape=(32,), dtype=tf.float32, name=None)
  135841408588432: TensorSpec(shape=(3, 3, 32, 32), dtype=tf.float32, name=None)
  135841408586704: TensorSpec(shape=(1, 1, 64, 32), dtype=tf.float32, name=None)
  135841408590352: TensorSpec(shape=(32,), dtype=tf.float32, name=None)
  135841408588048: TensorSpec(shape=(32,), dtype=tf.float32, name=None)
  135841408590928: TensorSpec(shape=(1, 1, 64, 64), dtype=tf.float32, name=None)
  135841408590736: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841408587280: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841408587472: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841408591120: TensorSpec(shape=(1, 1, 192, 128), dtype=tf.float32, name=None)
  135841408589776: TensorSpec(shape=(128,), dtype=tf.float32, name=None)
  135841408591696: TensorSpec(shape=(4, 2), dtype=tf.int32, name=None)
  135841408591312: TensorSpec(shape=(3, 3, 128, 256), dtype=tf.float32, name=None)
  135841408591888: TensorSpec(shape=(256,), dtype=tf.float32, name=None)
  135841408590544: TensorSpec(shape=(1, 1, 256, 256), dtype=tf.float32, name=None)
  135841408592464: TensorSpec(shape=(256,), dtype=tf.float32, name=None)
  135841408592656: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841408592272: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841408593424: TensorSpec(shape=(1, 1, 128, 64), dtype=tf.float32, name=None)
  135841408594768: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841408595152: TensorSpec(shape=(3, 3, 64, 64), dtype=tf.float32, name=None)
  135841408594960: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841408592080: TensorSpec(shape=(3, 3, 64, 64), dtype=tf.float32, name=None)
  135841408594192: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841408595536: TensorSpec(shape=(3, 3, 64, 64), dtype=tf.float32, name=None)
  135841408595728: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841408594000: TensorSpec(shape=(3, 3, 64, 64), dtype=tf.float32, name=None)
  135841408591504: TensorSpec(shape=(1, 1, 128, 64), dtype=tf.float32, name=None)
  135841408595920: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841408593616: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841408596496: TensorSpec(shape=(1, 1, 128, 128), dtype=tf.float32, name=None)
  135841408596304: TensorSpec(shape=(128,), dtype=tf.float32, name=None)
  135841408592848: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841408593040: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841408596688: TensorSpec(shape=(1, 1, 384, 256), dtype=tf.float32, name=None)
  135841408595344: TensorSpec(shape=(256,), dtype=tf.float32, name=None)
  135841408596880: TensorSpec(shape=(1, 1, 256, 128), dtype=tf.float32, name=None)
  135841408597072: TensorSpec(shape=(128,), dtype=tf.float32, name=None)
  135841408597456: TensorSpec(shape=(1, 1, 512, 256), dtype=tf.float32, name=None)
  135841408597264: TensorSpec(shape=(256,), dtype=tf.float32, name=None)
  135841408597648: TensorSpec(shape=(1, 1, 256, 256), dtype=tf.float32, name=None)
  135841408596112: TensorSpec(shape=(256,), dtype=tf.float32, name=None)
  135841408597840: TensorSpec(shape=(1, 1, 128, 256), dtype=tf.float32, name=None)
  135841396982032: TensorSpec(shape=(256,), dtype=tf.float32, name=None)
  135841396983760: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396983568: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396982224: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396984144: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396984336: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396983376: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396983952: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396983184: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396982608: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396984720: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396984528: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396982800: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396984912: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396985104: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396985296: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396985488: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396985680: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396985872: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396986064: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396986256: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396986448: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396986640: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396986832: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396987024: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396987216: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396987408: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396987600: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396987792: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396987984: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396988176: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396988368: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396988560: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396988752: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396988944: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396989136: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396989328: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396989520: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396989712: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396989904: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396990096: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396990288: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396990480: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396990672: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396990864: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396991056: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396991248: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396991440: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396991632: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396991824: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396992016: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396992208: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396992400: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396992592: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396992784: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396992976: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396993168: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396993360: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396993552: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396993744: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396993936: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396994128: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396994320: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396994512: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396994704: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396994896: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396995088: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396995280: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396995472: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396995664: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396995856: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396996048: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396996240: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396996432: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396996624: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396996816: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396997008: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396997200: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396997392: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396997584: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396997776: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396997968: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388822608: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388822800: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388822992: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388823184: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388823376: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388823568: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388823760: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388823952: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388824144: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388824336: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388824528: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388824720: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388824912: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388825104: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388825296: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388825488: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388825680: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388825872: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388826064: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388826256: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388826448: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388826640: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388826832: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388827024: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388827216: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388827408: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388827600: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388827792: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388827984: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388828176: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388828368: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388828560: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388828752: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388828944: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388829136: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388829328: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388829520: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388829712: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388829904: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388830096: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388830288: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388830480: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388830672: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388830864: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388831056: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388831248: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841388831440: TensorSpec(shape=(3, 3, 1, 1), dtype=tf.float32, name=None)
  135841396982416: TensorSpec(shape=(128,), dtype=tf.float32, name=None)
  135841396982992: TensorSpec(shape=(1, 1, 128, 128), dtype=tf.float32, name=None)
  135841388832400: TensorSpec(shape=(128,), dtype=tf.float32, name=None)
  135841388834128: TensorSpec(shape=(1, 1, 128, 256), dtype=tf.float32, name=None)
  135841388832208: TensorSpec(shape=(256,), dtype=tf.float32, name=None)
  135841388833168: TensorSpec(shape=(1, 1, 256, 128), dtype=tf.float32, name=None)
  135841388832592: TensorSpec(shape=(128,), dtype=tf.float32, name=None)
  135841388832976: TensorSpec(shape=(1, 1, 256, 256), dtype=tf.float32, name=None)
  135841388831632: TensorSpec(shape=(256,), dtype=tf.float32, name=None)
  135841388832016: TensorSpec(shape=(1, 1, 384, 128), dtype=tf.float32, name=None)
  135841388834320: TensorSpec(shape=(128,), dtype=tf.float32, name=None)
  135841388833552: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841388833936: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841388834896: TensorSpec(shape=(3, 3, 64, 32), dtype=tf.float32, name=None)
  135841388836240: TensorSpec(shape=(32,), dtype=tf.float32, name=None)
  135841388833744: TensorSpec(shape=(3, 3, 32, 64), dtype=tf.float32, name=None)
  135841388833360: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841388832784: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841388834512: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841388836432: TensorSpec(shape=(1, 1, 192, 128), dtype=tf.float32, name=None)
  135841388836624: TensorSpec(shape=(128,), dtype=tf.float32, name=None)
  135841388835088: TensorSpec(shape=(1, 1, 256, 64), dtype=tf.float32, name=None)
  135841388835664: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841388837200: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841388837008: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841388838736: TensorSpec(shape=(3, 3, 32, 16), dtype=tf.float32, name=None)
  135841388836816: TensorSpec(shape=(16,), dtype=tf.float32, name=None)
  135841388838160: TensorSpec(shape=(3, 3, 16, 32), dtype=tf.float32, name=None)
  135841388838544: TensorSpec(shape=(32,), dtype=tf.float32, name=None)
  135841388837392: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841388837584: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841388837968: TensorSpec(shape=(1, 1, 96, 64), dtype=tf.float32, name=None)
  135841388835472: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841349337744: TensorSpec(shape=(4, 2), dtype=tf.int32, name=None)
  135841349337552: TensorSpec(shape=(3, 3, 64, 64), dtype=tf.float32, name=None)
  135841349337936: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841349339664: TensorSpec(shape=(1, 1, 192, 128), dtype=tf.float32, name=None)
  135841349339856: TensorSpec(shape=(128,), dtype=tf.float32, name=None)
  135841349340432: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841349341200: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841349343504: TensorSpec(shape=(3, 3, 64, 32), dtype=tf.float32, name=None)
  135841349341008: TensorSpec(shape=(32,), dtype=tf.float32, name=None)
  135841349343888: TensorSpec(shape=(3, 3, 32, 64), dtype=tf.float32, name=None)
  135841349343696: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841349341584: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841349341776: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841349344080: TensorSpec(shape=(1, 1, 192, 128), dtype=tf.float32, name=None)
  135841349345616: TensorSpec(shape=(128,), dtype=tf.float32, name=None)
  135841349344272: TensorSpec(shape=(4, 2), dtype=tf.int32, name=None)
  135841349345040: TensorSpec(shape=(3, 3, 128, 128), dtype=tf.float32, name=None)
  135841349344656: TensorSpec(shape=(128,), dtype=tf.float32, name=None)
  135841349346768: TensorSpec(shape=(1, 1, 384, 256), dtype=tf.float32, name=None)
  135841349346960: TensorSpec(shape=(256,), dtype=tf.float32, name=None)
  135841349347536: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841349348304: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841349350608: TensorSpec(shape=(1, 1, 128, 64), dtype=tf.float32, name=None)
  135841349348112: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841349351184: TensorSpec(shape=(3, 3, 64, 64), dtype=tf.float32, name=None)
  135841349350800: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841349352336: TensorSpec(shape=(3, 3, 64, 64), dtype=tf.float32, name=None)
  135841349352528: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841349353104: TensorSpec(shape=(3, 3, 64, 64), dtype=tf.float32, name=None)
  135841349351568: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841349352720: TensorSpec(shape=(3, 3, 64, 64), dtype=tf.float32, name=None)
  135841349349456: TensorSpec(shape=(1, 1, 128, 64), dtype=tf.float32, name=None)
  135841349345424: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841349349264: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841349353296: TensorSpec(shape=(1, 1, 128, 128), dtype=tf.float32, name=None)
  135841349352912: TensorSpec(shape=(128,), dtype=tf.float32, name=None)
  135841349348688: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841349348880: TensorSpec(shape=(4,), dtype=tf.int64, name=None)
  135841349351376: TensorSpec(shape=(1, 1, 384, 256), dtype=tf.float32, name=None)
  135841349351760: TensorSpec(shape=(256,), dtype=tf.float32, name=None)
  135841335984400: TensorSpec(shape=(3, 3, 256, 1), dtype=tf.float32, name=None)
  135841349346000: TensorSpec(shape=(3, 3, 128, 1), dtype=tf.float32, name=None)
  135841349338896: TensorSpec(shape=(3, 3, 64, 1), dtype=tf.float32, name=None)
  135841349344848: TensorSpec(shape=(256,), dtype=tf.float32, name=None)
  135841349344464: TensorSpec(shape=(128,), dtype=tf.float32, name=None)
  135841349338512: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841335984784: TensorSpec(shape=(1, 1, 256, 64), dtype=tf.float32, name=None)
  135841349346576: TensorSpec(shape=(1, 1, 128, 64), dtype=tf.float32, name=None)
  135841349339280: TensorSpec(shape=(1, 1, 64, 64), dtype=tf.float32, name=None)
  135841335984976: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841349346192: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841349338704: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841335985936: TensorSpec(shape=(3, 3, 64, 1), dtype=tf.float32, name=None)
  135841349351952: TensorSpec(shape=(3, 3, 256, 64), dtype=tf.float32, name=None)
  135841349347920: TensorSpec(shape=(3, 3, 64, 1), dtype=tf.float32, name=None)
  135841349342928: TensorSpec(shape=(3, 3, 128, 64), dtype=tf.float32, name=None)
  135841349340816: TensorSpec(shape=(3, 3, 64, 1), dtype=tf.float32, name=None)
  135841349338128: TensorSpec(shape=(3, 3, 64, 64), dtype=tf.float32, name=None)
  135841335985168: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841349352144: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841349347152: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841349345808: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841349340048: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841349338320: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841335986320: TensorSpec(shape=(1, 1, 64, 64), dtype=tf.float32, name=None)
  135841335984208: TensorSpec(shape=(3, 3, 64, 64), dtype=tf.float32, name=None)
  135841349348496: TensorSpec(shape=(1, 1, 64, 64), dtype=tf.float32, name=None)
  135841349346384: TensorSpec(shape=(3, 3, 64, 64), dtype=tf.float32, name=None)
  135841349342352: TensorSpec(shape=(1, 1, 64, 64), dtype=tf.float32, name=None)
  135841349339472: TensorSpec(shape=(3, 3, 64, 64), dtype=tf.float32, name=None)
  135841335985360: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841335984592: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841349349840: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841349345232: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841349342160: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841349339088: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841335986512: TensorSpec(shape=(1, 1, 64, 7), dtype=tf.float32, name=None)
  135841335985552: TensorSpec(shape=(1, 1, 64, 64), dtype=tf.float32, name=None)
  135841349350992: TensorSpec(shape=(1, 1, 64, 7), dtype=tf.float32, name=None)
  135841349347728: TensorSpec(shape=(1, 1, 64, 64), dtype=tf.float32, name=None)
  135841349341392: TensorSpec(shape=(1, 1, 64, 7), dtype=tf.float32, name=None)
  135841349340624: TensorSpec(shape=(1, 1, 64, 64), dtype=tf.float32, name=None)
  135841335985744: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841335986704: TensorSpec(shape=(7,), dtype=tf.float32, name=None)
  135841349347344: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841349350032: TensorSpec(shape=(7,), dtype=tf.float32, name=None)
  135841349340240: TensorSpec(shape=(64,), dtype=tf.float32, name=None)
  135841349342736: TensorSpec(shape=(7,), dtype=tf.float32, name=None)
  135841335989392: TensorSpec(shape=(3,), dtype=tf.int64, name=None)
  135841335987280: TensorSpec(shape=(3,), dtype=tf.int64, name=None)
  135841335989584: TensorSpec(shape=(1, 1, 16, 1), dtype=tf.float32, name=None)
  135841335986896: TensorSpec(shape=(1, 4, 2100), dtype=tf.float32, name=None)
  135841335991888: TensorSpec(shape=(3,), dtype=tf.int64, name=None)
  135841335992464: TensorSpec(shape=(3,), dtype=tf.int64, name=None)
  135841335988432: TensorSpec(shape=(3,), dtype=tf.int64, name=None)
  135841335990544: TensorSpec(shape=(3,), dtype=tf.int64, name=None)
  135841335992080: TensorSpec(shape=(1, 2, 2100), dtype=tf.float32, name=None)
  135841335991696: TensorSpec(shape=(1, 2, 2100), dtype=tf.float32, name=None)
  135841335986128: TensorSpec(shape=(3,), dtype=tf.int64, name=None)
  135841335989200: TensorSpec(shape=(3,), dtype=tf.int64, name=None)


TensorFlow SavedModel: export success ✅ 457.4s, saved as 'yolo11n_saved_model' (37.8 MB)

Edge TPU: export requires Edge TPU compiler. Attempting install from https://coral.ai/docs/edgetpu/compiler/

Edge TPU: starting export with Edge TPU compiler 16.0.384591198...
Edge TPU: running 'edgetpu_compiler --out_dir "yolo11n_saved_model" --show_operations --search_delegate --delegate_search_step 30 --timeout_sec 180 "yolo11n_saved_model/yolo11n_full_integer_quant.tflite"'
Edge TPU: export success ✅ 20.0s, saved as 'yolo11n_saved_model/yolo11n_full_integer_quant_edgetpu.tflite' (4.9 MB)

Export complete (478.2s)
Results saved to /content
Predict:         yolo predict task=detect model=yolo11n_saved_model/yolo11n_full_integer_quant_edgetpu.tflite imgsz=320 int8
Validate:        yolo val task=detect model=yolo11n_saved_model/yolo11n_full_integer_quant_edgetpu.tflite imgsz=320 data=/content/data.yaml int8
Visualize:       https://netron.app/
yolo11n_saved_model/yolo11n_full_integer_quant_edgetpu.tflite
This is the actual video below
Convert to edgetpu Video Link: https://drive.google.com/file/d/19iO5LlW2rXDCxuLeRsAEBI_fu1xhJyyo/view?usp=sharing
Testing on my RPI 4B 8GB With Coral USB Accelerator: https://drive.google.com/file/d/17KC1qK9PL9UBr7WJIpOAiGa6B2L2uXIH/view?usp=sharing
A large amount of accuracy loss is sadly expected with the coral TPU. You could otherwise maybe try exporting to NCNN with a imgsz of 320, that format is usually the 2nd fastest after the TPU.
if I have a bunch of dataset will it improve?
A better base model will result in a better quantized model, yes.
mingbka
I did the installations like described, run model = YOLO("yolo_weights_tflite/yolo_weights_full_integer_quant_edgetpu.tflite", task='detect') and this happened: Traceback (most recent call last): File "/home/Friday/SourceCode/yolo/detect.py", line 31, in results = model(img, stream=True, verbose=False) ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^ File "/home/Friday/SourceCode/yolo/venv/lib/python3.11/site-packages/ultralytics/engine/model.py", line 182, in call return self.predict(source, stream, **kwargs) ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^ File "/home/Friday/SourceCode/yolo/venv/lib/python3.11/site-packages/ultralytics/engine/model.py", line 545, in predict self.predictor.setup_model(model=self.model, verbose=is_cli) File "/home/Friday/SourceCode/yolo/venv/lib/python3.11/site-packages/ultralytics/engine/predictor.py", line 376, in setup_model self.model = AutoBackend( ^^^^^^^^^^^^ File "/home/Friday/SourceCode/yolo/venv/lib/python3.11/site-packages/torch/utils/_contextlib.py", line 116, in decorate_context return func(*args, **kwargs) ^^^^^^^^^^^^^^^^^^^^^ File "/home/Friday/SourceCode/yolo/venv/lib/python3.11/site-packages/ultralytics/nn/autobackend.py", line 419, in init interpreter = Interpreter( ^^^^^^^^^^^^ File "/home/Friday/SourceCode/yolo/venv/lib/python3.11/site-packages/tflite_runtime/interpreter.py", line 464, in init self._interpreter = _interpreter_wrapper.CreateWrapperFromFile( ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^ ValueError: Model provided has model identifier ' Can you please helpp!!
JohanJay20
from ultralytics import YOLO
Load a model
model = YOLO("path/to/model.pt") # Load an official model or custom model
Export the model
model.export(format="edgetpu")
why when i convert my model i only get metadata.json
The model should be located in a folder with the suffix "_saved_model". Can you share the log from the export?
It happens because any export starting YOLO10 gives an error from edgetpu_compiler:
Edge TPU Compiler version 16.0.384591198 ERROR: Didn't find op for builtin opcode 'CONV_2D' version '6'. An older version of this builtin might be supported. Are you using an old TFLite binary with a newer model? ERROR: Registration failed.
Only YOLO version 9 exported successfully for me.
- Glenn JocherUltralytics
@suprimex thank you for sharing this important finding. It appears you've identified a compatibility issue between newer YOLO models (YOLO10 and up) and the Edge TPU compiler. The error message about "builtin opcode 'CONV_2D' version '6'" suggests that newer models are using TensorFlow Lite operations that the current Edge TPU compiler doesn't support.
This is likely because the Edge TPU compiler hasn't been updated to support the newer TFLite operation set used in YOLO10+ models, which is unfortunate considering Google hasn't been actively maintaining the Coral project recently.
As a workaround, you can:
- Continue using YOLOv9 as you've found success with it
- Try downgrading your TensorFlow version when exporting (something like 2.10 or 2.11)
- Consider using alternatives like OpenVINO or ONNX Runtime on the Raspberry Pi if Edge TPU compatibility is proving too challenging
For anyone else encountering this issue, please share your experiences - documenting these compatibility issues helps the community develop better solutions. Thanks for bringing this to our attention!
benl4212
I have custom trained a yolo11n-seg model that I would like to fully optimize for a Coral USB. First, I noticed Coral's supported operations- Coral Supported Ops do not include SiLU, so I manually changed the activation function from SiLU to ReLU for all instances in conv.py and block.py. I also searched the other scripts in /nn/modules & /models/yolo/segment/ & cfg/models/11/yolo11-seg for SiLU activations. I retrained the previous SiLU model with the ReLU framework until "patience" stopped the training and lost no noticeable P/R/mAP50.
I have tried exporting to these formats with no success: edgetpu, tflite, and saved model. The only format that works is onnx.
So I made a custom export pipeline that gets me from ONNX -> TFLite INT8. Here is the end part of the output after my custom pipeline, suggesting my TFLite INT8 Quantization was successful: DEBUG: Yielding data with shape: (1, 3, 320, 320), dtype: float32 fully_quantize: 0, inference_type: 6, input_inference_type: INT8, output_inference_type: INT8 2025-04-20 19:15:05.628706: I tensorflow/compiler/mlir/lite/flatbuffer_export.cc:1989] Estimated count of arithmetic ops: 2.413 G ops, equivalently 1.206 G MACs
Estimated count of arithmetic ops: 2.413 G ops, equivalently 1.206 G MACs Conversion finished. Saving INT8 TFLite model to: C:/Users/benl4/project7/1_class_seg5_relu/weights/yolo11n-seg_int8.tflite TFLite INT8 model saved successfully.
Next, I need to use the Edge TPU Compiler- Edge TPU Compiler but it has failed several times during compilation due to large tensor sizes. I originally exported to ONNX with opset=12 and imgsz=640. After 1st compilation failure I tried exporting to ONXX with opset=12 and imgsz=320.
Again for the Edge TPU Compiler, I used the flags -s -a -d and got this output that eventually stopped running at 378 ops. Edge TPU Compiler version 16.0.384591198 Searching for valid delegate with step 1 Try to compile segment with 393 ops Started a compilation timeout timer of 180 seconds. ERROR: Restored original execution plan after delegate application failure. Compilation failed: Compilation failed due to large activation tensors in model. Compilation child process completed within timeout period. Compilation failed! Try to compile segment with 392 ops Intermediate tensors: onnx_tf_prefix_/model.23/Concat,onnx_tf_prefix_/model.23/Sigmoid1,onnx_tf_prefix_/model.23/Mul_2,PartitionedCall:1 Started a compilation timeout timer of 180 seconds. ERROR: Restored original execution plan after delegate application failure. Compilation failed: Compilation failed due to large activation tensors in model. Compilation child process completed within timeout period. Compilation failed! Try to compile segment with 391 ops Intermediate tensors: onnx_tf_prefix_/model.23/Concat,onnx_tf_prefix_/model.23/Sigmoid1,onnx_tf_prefix_/model.23/proto/cv3/act/Relu;Add_65;convolution_56;convolution_58;Const_87,onnx_tf_prefix_/model.23/Mul_2 Started a compilation timeout timer of 180 seconds. ERROR: Restored original execution plan after delegate application failure. Compilation failed: Compilation failed due to large activation tensors in model. Compilation child process completed within timeout period. Compilation failed! Try to compile segment with 390 ops Intermediate tensors: onnx_tf_prefix_/model.23/Sigmoid1,onnx_tf_prefix_/model.23/Mul_2,onnx_tf_prefix_/model.23/Reshape_1,onnx_tf_prefix_/model.23/Reshape1,onnx_tf_prefix_/model.23/Reshape_2,onnx_tf_prefix_/model.23/proto/cv3/act/Relu;Add_65;convolution_56;convolution_58;Const_87 Started a compilation timeout timer of 180 seconds. ERROR: Restored original execution plan after delegate application failure. Compilation failed: Compilation failed due to large activation tensors in model. Compilation child process completed within timeout period. Compilation failed!
Update: Exported to ONNX with imgsz=224 and got the compiler to work without the large tensor warning. However, only 1/393 ops were mapped. I believe the culprits could be Softmax, Div, Pack, SPLIT_V, STRIDED_SLICE, TRANSPOSE. Here is the new Edge TPU Compiler Output: Edge TPU Compiler version 16.0.384591198 Searching for valid delegate with step 1 Try to compile segment with 394 ops Started a compilation timeout timer of 180 seconds.
Model compiled successfully in 70 ms.
Input model: /content/yolo11n-seg_int8.tflite Input size: 3.02MiB Output model: yolo11n-seg_int8_edgetpu.tflite Output size: 3.11MiB On-chip memory used for caching model parameters: 56.00KiB On-chip memory remaining for caching model parameters: 6.54MiB Off-chip memory used for streaming uncached model parameters: 0.00B Number of Edge TPU subgraphs: 1 Total number of operations: 394 Operation log: yolo11n-seg_int8_edgetpu.log
Model successfully compiled but not all operations are supported by the Edge TPU. A percentage of the model will instead run on the CPU, which is slower. If possible, consider updating your model to use only operations supported by the Edge TPU. For details, visit g.co/coral/model-reqs. Number of operations that will run on Edge TPU: 1 Number of operations that will run on CPU: 393
Operator Count Status
FULLY_CONNECTED 4 More than one subgraph is not supported CONCATENATION 24 More than one subgraph is not supported PACK 2 More than one subgraph is not supported RESHAPE 23 More than one subgraph is not supported TRANSPOSE 135 More than one subgraph is not supported TRANSPOSE 15 Operation is otherwise supported, but not mapped due to some unspecified limitation SPLIT 4 For example, a fully-connected or softmax layer with 2D output SOFTMAX 2 More than one subgraph is not supported MUL 3 More than one subgraph is not supported SPLIT_V 11 More than one subgraph is not supported STRIDED_SLICE 2 More than one subgraph is not supported DEPTHWISE_CONV_2D 7 More than one subgraph is not supported LOGISTIC 1 More than one subgraph is not supported PAD 40 More than one subgraph is not supported PAD 1 Mapped to Edge TPU SUB 2 More than one subgraph is not supported ADD 16 More than one subgraph is not supported MAX_POOL_2D 3 More than one subgraph is not supported QUANTIZE 3 More than one subgraph is not supported CONV_2D 93 More than one subgraph is not supported TRANSPOSE_CONV 1 More than one subgraph is not supported RESIZE_NEAREST_NEIGHBOR 2 More than one subgraph is not supported Compilation child process completed within timeout period. Compilation succeeded!
- Glenn JocherUltralytics
@benl4212 thank you for sharing your thorough investigation. You've hit upon one of the core challenges when using YOLO11 models (especially segmentation variants) with the Edge TPU.
The "More than one subgraph is not supported" error that appears throughout your compiler output indicates that the Edge TPU compiler can't map most operations because they're split across multiple subgraphs. This is a fundamental limitation when working with complex models like YOLO11-seg.
Some suggestions that might help:
-
Try YOLOv8-seg instead of YOLO11-seg: As seen in earlier comments, YOLOv8 models tend to have better compatibility with the Edge TPU (275 ops on CPU for YOLO11 vs only 22 for YOLOv8).
-
Further reduce model complexity: Consider using a nano or smaller variant and reduce image size (224 or smaller). You might also try removing the segmentation head and just using detection if that's an option for your use case.
-
Model pruning: Try applying network pruning techniques to reduce the model's parameter count before conversion.
-
Alternative activation functions: While you've already replaced SiLU with ReLU, you might need to simplify other operations like Softmax, which often cause issues with Edge TPU compilation.
The Edge TPU has strict limitations on the operations it supports and how they're structured. For segmentation tasks specifically, you might consider exploring alternatives like running inference directly on the Raspberry Pi with optimized formats like ONNX or OpenVINO instead of Edge TPU if performance is insufficient.
Let me know if you'd like more specific guidance on any of these approaches!
-
Thank you @glenn-jocher but I managed to complete the Ultralytics export pipeline to edgetpu in google colab, and as I would expect it is much more efficient than my own, as now 208 ops are supported. From here, I'm not sure if I should say its good enough for my application-
I'm attempting to create a binary yolo11n-seg model for litter detection. The segmentation model performed much better on my litter dataset (2200 positive examples & 500 negative) than detection so I think I'm going to have to stick with segmentation in that regard. Also not sure if relevant but my calibration dataset consists of 524 images ~ 400 positive & 130 negative examples- per LiteRT guidelines of 5 images per class (while the model only detects 1 class, the dataset consists of around 80 different litter types). I have these 524 images copied into both the training and validation folders corresponding to the data.yaml file that I used to export to edgetpu format; maybe yourself or @Skillnoob can verify if I am correct in doing this for my calibration set.
If I wanted to further simplify the segmentation model, I could use the output from the Ultralytics export to change the necessary activation functions and fully optimize all operations for the Coral USB, correct?
(I used imgsz=224 for the following) Here is the Ultralytics pipeline export output after compilation:
Edge TPU: starting export with Edge TPU compiler 16.0.384591198... Edge TPU: running 'edgetpu_compiler --out_dir "/content/best_saved_model" --show_operations --search_delegate --delegate_search_step 30 --timeout_sec 180 "/content/best_saved_model/best_full_integer_quant.tflite"' Edge TPU Compiler version 16.0.384591198 Searching for valid delegate with step 30 Try to compile segment with 365 ops Started a compilation timeout timer of 180 seconds.
Model compiled successfully in 3170 ms.
Input model: /content/best_saved_model/best_full_integer_quant.tflite Input size: 3.29MiB Output model: /content/best_saved_model/best_full_integer_quant_edgetpu.tflite Output size: 3.43MiB On-chip memory used for caching model parameters: 1.38MiB On-chip memory remaining for caching model parameters: 6.33MiB Off-chip memory used for streaming uncached model parameters: 8.00KiB Number of Edge TPU subgraphs: 1 Total number of operations: 365 Operation log: /content/best_saved_model/best_full_integer_quant_edgetpu.log
Model successfully compiled but not all operations are supported by the Edge TPU. A percentage of the model will instead run on the CPU, which is slower. If possible, consider updating your model to use only operations supported by the Edge TPU. For details, visit g.co/coral/model-reqs. Number of operations that will run on Edge TPU: 208 Number of operations that will run on CPU: 157
Operator Count Status
SPLIT 4 For example, a fully-connected or softmax layer with 2D output SPLIT 1 Mapped to Edge TPU ADD 10 More than one subgraph is not supported ADD 7 Mapped to Edge TPU SOFTMAX 2 More than one subgraph is not supported STRIDED_SLICE 12 More than one subgraph is not supported STRIDED_SLICE 13 Mapped to Edge TPU QUANTIZE 3 More than one subgraph is not supported SUB 2 More than one subgraph is not supported CONCATENATION 8 Mapped to Edge TPU CONCATENATION 16 More than one subgraph is not supported MAX_POOL_2D 3 Mapped to Edge TPU RESHAPE 16 More than one subgraph is not supported RESHAPE 5 Mapped to Edge TPU CONV_2D 163 Mapped to Edge TPU CONV_2D 58 More than one subgraph is not supported TRANSPOSE_CONV 1 More than one subgraph is not supported MUL 3 More than one subgraph is not supported RESIZE_NEAREST_NEIGHBOR 2 More than one subgraph is not supported DEPTHWISE_CONV_2D 6 More than one subgraph is not supported FULLY_CONNECTED 4 More than one subgraph is not supported LOGISTIC 1 More than one subgraph is not supported PACK 2 More than one subgraph is not supported TRANSPOSE 3 Mapped to Edge TPU TRANSPOSE 13 More than one subgraph is not supported PAD 2 More than one subgraph is not supported PAD 5 Mapped to Edge TPU Compilation child process completed within timeout period. Compilation succeeded! Edge TPU: export success ✅ 23.4s, saved as '/content/best_saved_model/best_full_integer_quant_edgetpu.tflite' (3.4 MB)
Export complete (527.1s) Results saved to /content Predict: yolo predict task=segment model=/content/best_saved_model/best_full_integer_quant_edgetpu.tflite imgsz=224 int8 Validate: yolo val task=segment model=/content/best_saved_model/best_full_integer_quant_edgetpu.tflite imgsz=224 data=C:\Users\benl4\TrashBot\binary_segmentation\Custom_Litter_Segmentation\data.yaml int8 Visualize: https://netron.app 💡 Learn more at https://docs.ultralytics.com/modes/export
(EDIT) I will conduct my own testing with the base yolo11n-seg (COCO) model, but I guess my question is- did changing SiLU to ReLU improve compatibility to Edge TPU? As far as I can tell yolo11n-seg does not have a working pipeline to be fully optimized for Edge TPU format?
- Glenn JocherUltralytics
Yes, changing SiLU to ReLU typically improves Edge TPU compatibility because ReLU is explicitly supported in the Edge TPU's operation set, while SiLU/Swish is not. Your approach of manually changing the activation functions was a good optimization strategy.
The segmentation improvement you're seeing with your model (going from 1/393 to 208/365 ops on the TPU) is substantial and may be "good enough" depending on your inference speed requirements. Segmentation models are particularly challenging for the Edge TPU because they contain more complex operations and larger activation tensors than detection-only models.
Regarding your calibration dataset approach for int8 quantization, using 524 images with good class representation is more than sufficient. The recommendation of "5 images per class" is a minimum, and having more calibration data (especially covering the variety of litter types) should produce better quantization results.
For further optimization:
- Test actual inference speed with your current model to see if it meets your needs
- Consider reducing image size further (192x192 or even 160x160) if possible for your application
- If speed remains inadequate, you might need to simplify your model architecture or consider YOLOv8-seg as an alternative
The fact that the Edge TPU is handling 208 of 365 operations is actually quite good for a segmentation model. For comparison, most detection-only models achieve better TPU utilization percentages, but segmentation is inherently more complex.
Would you mind sharing your inference speed results once you've tested on the Raspberry Pi with the Edge TPU? That information would be valuable for the community.
1 Thank you again for your timely response @glenn-jocher, I have spent the last bit of time experimenting with these exports (with varying opset and imgsz) as the aforementioned custom ReLU model seemed completely corrupted when I tried to run inference (100-200 random segmentations).
*EDIT I have no explanation for this weird behavior other than the shape of my tensors [1 56 56 32] [1 37 1029]. When I ran a script to find these tensor shapes the Inference Time= 81 ms. This is for the ReLU activated yolo11n-seg Edge TPU compiled model, with input image size=224
I have tried using
yolo predictwith this compiled model and I get errors such as "Segmentation Fault."I had to find a workaround for my deployment anyway because the Picamera2 library is only compatible with Python 3.11 and pycoral with Python 3.9 so I used posix_ipc for connecting the incompatible processes. I have one script that uses the picamera and outputs the frames, and the other script preprocesses/runs inference/postprocesses/outputs live window. With this pipeline I get around 10 FPS with the same segmentation model!
I apologize if I am incorrect in any of my assumptions but this is my first AI / software project. I appreciate the extent of beginner friendly documentation from Ultralytics. I could not have done the amount of work I have done in 3 months without it.
i-saw
Hi! I have a standard yolo11n model quantized in google collaborate, along with Corel on raspberry pi 4B 8 gb, it makes an inference in about 450 ms. I think something is not working correctly. I will be glad for tips and hints.
- Glenn JocherUltralytics
@i-saw for optimal Coral Edge TPU performance on Raspberry Pi, ensure you've followed the Coral Edge TPU setup guide including high-frequency runtime installation and proper model export with
format='edgetpu'. Verify your quantized model ends with_edgetpu.tfliteand is using the TPU viadevice='tpu'in predict calls. Benchmark expectations for YOLO11n are ~25-70ms depending on image size and Pi model.
AI-07
The Title of the page is for YOLOv11 but the benchmark shows values for YOLOv8 ?
The benchmarks were done before yolo11 got released and were only recently added to the guide.
1