Ultralytics YOLO26을 사용한 인스턴스 세그멘테이션 및 추적
인스턴스 세그멘테이션이란 무엇인가요?#
인스턴스 세그멘테이션은 이미지에서 개별 객체를 픽셀 수준으로 식별하고 윤곽을 표시하는 컴퓨터 비전 작업입니다. 픽셀을 범주별로 분류하기만 하는 시맨틱 세그멘테이션과 달리, 인스턴스 세그멘테이션은 각 객체 인스턴스에 고유한 레이블을 지정하고 정확하게 구분합니다. 따라서 의료 영상, 자율 주행, 산업 자동화처럼 정밀한 공간 이해가 필요한 애플리케이션에 매우 중요합니다.
Ultralytics YOLO26은 YOLO 모델 특유의 속도와 효율성을 유지하면서 객체 경계를 정밀하게 구분합니다.
Ultralytics 패키지에서 사용할 수 있는 인스턴스 세그멘테이션 추적 유형은 두 가지입니다.
-
클래스 객체를 사용한 인스턴스 세그멘테이션: 시각적으로 명확하게 구분할 수 있도록 각 클래스 객체에 고유한 색상을 할당합니다.
-
객체 트랙을 사용한 인스턴스 세그멘테이션: 각 트랙을 서로 다른 색상으로 표시하여 비디오 프레임 전반에서 쉽게 식별하고 추적할 수 있습니다.
시청: Ultralytics YOLO26으로 객체 추적을 사용한 인스턴스 분할
샘플#
| 인스턴스 세그멘테이션 | 인스턴스 세그멘테이션 + 객체 추적 |
|---|---|
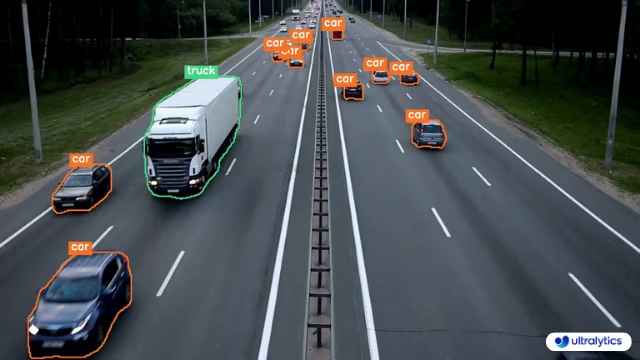 | 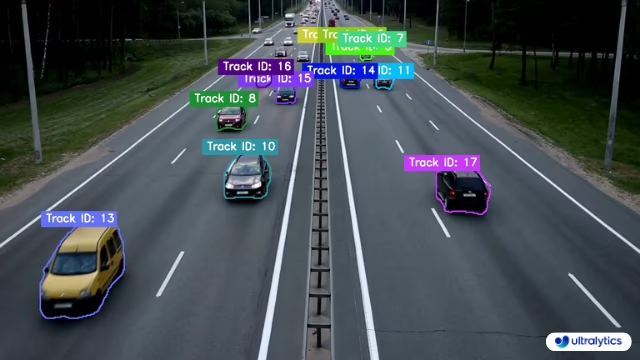 |
| Ultralytics 인스턴스 세그멘테이션 | 객체 추적을 지원하는 Ultralytics 인스턴스 세그멘테이션 |
YOLO26으로 세그먼트 및 추적하기#
InstanceSegmentation 솔루션은 각 프레임에서 YOLO26 세그멘테이션 모델을 실행하고 객체별 마스크를 그린 다음, 각 인스턴스에 서로 다른 색상을 적용하여 동영상에서 개별 객체를 추적할 수 있도록 합니다. YOLO26n-seg와 같은 -seg 모델을 불러온 다음, Python API 또는 CLI를 사용해 입력 소스에 적용합니다.
# Instance segmentation using Ultralytics YOLO26
yolo solutions isegment show=True

# Pass a source video
yolo solutions isegment source="path/to/video.mp4"

# Monitor the specific classes
yolo solutions isegment classes="[0, 5]"
InstanceSegmentation 인수#
다음은 InstanceSegmentation 인수 표입니다:
| 인수 | 유형 | 기본값 | 설명 |
|---|---|---|---|
model | str | None | Ultralytics YOLO 모델 파일의 경로입니다. |
line_width | int | 2 | Solution에서 그리는 상자, 키포인트 및 개수 표시의 선 두께입니다. |
verbose | bool | True | 프레임별 입력 형태, 클래스 개수 및 처리 속도 로그를 활성화합니다. 추적 호출 자체는 항상 로그를 출력하지 않습니다. |
InstanceSegmentation 솔루션에서 track 인수도 사용할 수 있습니다:
| 인수 | 유형 | 기본값 | 설명 |
|---|---|---|---|
tracker | str | 'tracktrack.yaml' | 사용할 추적 알고리즘을 지정합니다. 기본 제공 옵션: botsort.yaml, bytetrack.yaml, ocsort.yaml, deepocsort.yaml, fasttrack.yaml, tracktrack.yaml. |
conf | float | 0.25 | 탐지에 대한 신뢰도 임계값을 설정합니다. 값을 낮추면 추적할 수 있는 객체가 늘어나지만 오탐이 포함될 수 있습니다. |
iou | float | 0.5 | 중복 탐지를 필터링하기 위한 교집합 대비 합집합 (IoU) 임계값을 설정합니다. |
classes | list | None | 클래스 인덱스로 결과를 필터링합니다. 예를 들어 classes=[0, 2, 3]은 지정된 클래스만 추적합니다. |
device | str | None | 추론에 사용할 장치를 지정합니다(예: cpu, cuda:0 또는 0). 사용자는 모델 실행에 사용할 CPU, 특정 GPU 또는 기타 연산 장치를 선택할 수 있습니다. |
imgsz | int or tuple | 640 | 추론 대상 이미지 크기입니다. 정사각형을 나타내는 정수 또는 (height, width) 쌍을 지정합니다. 모델 stride에 맞춰 형태가 조정됩니다. |
max_det | int | 300 | 추적 전에 프레임별로 유지할 최대 탐지 수를 지정하여 밀집된 장면에서 솔루션이 처리하는 객체 수를 제한합니다. |
quantize | int or str | None | 추론 정밀도: CPU 이외의 환경에서 PyTorch 및 TorchScript 모델은 16(FP16) 또는 32/unset(FP32)을 사용하며, 다른 형식은 아티팩트와 런타임이 선택하는 정밀도를 사용합니다. 더 이상 사용되지 않는 half 인수를 대체합니다. |
또한 다음 시각화 인수를 사용할 수 있습니다:
| 인수 | 유형 | 기본값 | 설명 |
|---|---|---|---|
show | bool | False | True이면 주석이 추가된 이미지나 비디오를 창에 표시합니다. 개발 또는 테스트 중 즉각적인 시각적 피드백을 얻는 데 유용합니다. |
show_conf | bool | True | 각 감지 결과의 레이블 옆에 신뢰도 점수를 표시합니다. 각 감지 결과에 대한 모델의 확신도를 파악할 수 있습니다. |
show_labels | bool | True | 시각화 출력에 각 감지 결과의 레이블을 표시합니다. 감지된 객체를 즉시 파악할 수 있습니다. |
show_boxes | bool | True | 감지된 객체 주위에 경계 상자를 그립니다. 이미지나 비디오 프레임에서 객체를 시각적으로 식별하고 위치를 파악하는 데 필수적입니다. |
인스턴스 세그멘테이션의 응용 분야#
YOLO26을 사용한 인스턴스 세그멘테이션은 다양한 산업 분야에서 폭넓게 활용됩니다.
폐기물 관리 및 재활용#
YOLO26은 폐기물 관리 시설에서 다양한 종류의 자재를 식별하고 분류하는 데 사용할 수 있습니다. 이 모델은 플라스틱 폐기물, 판지, 금속 및 기타 재활용품을 높은 정밀도로 세그먼트화하여 자동 분류 시스템이 폐기물을 더 효율적으로 처리하도록 지원합니다. 전 세계에서 발생하는 70억 톤의 플라스틱 폐기물 중 약 10%만 재활용된다는 점을 고려하면 특히 유용합니다.
자율 주행 차량#
자율주행차에서 인스턴스 세그멘테이션은 보행자, 차량, 교통 표지판 및 기타 도로 요소를 픽셀 수준에서 식별하고 추적하는 데 도움이 됩니다. 이러한 정밀한 환경 인식은 주행 경로 탐색과 안전 관련 의사 결정에 매우 중요합니다. YOLO26의 실시간 성능은 시간에 민감한 이러한 애플리케이션에 적합합니다.
의료 영상#
인스턴스 세그멘테이션은 의료 스캔 이미지에서 종양, 장기 또는 세포 구조를 식별하고 윤곽을 표시할 수 있습니다. 객체 경계를 정밀하게 구분하는 YOLO26의 기능은 의료 진단과 치료 계획 수립에 유용합니다.
건설 현장 모니터링#
건설 현장에서 인스턴스 세그멘테이션을 사용하면 중장비, 작업자, 자재를 추적할 수 있습니다. 장비의 위치를 모니터링하고 작업자가 위험 구역에 진입하는지 감지하여 안전을 확보하는 동시에, 작업 흐름과 리소스 배분을 최적화할 수 있습니다.
자주 묻는 질문#
Ultralytics YOLO26으로 인스턴스 세그멘테이션을 수행하려면
InstanceSegmentation솔루션을 YOLO26 세그멘테이션 모델로 초기화하고 비디오 프레임을 입력해 처리합니다. 다음은 간단한 코드 예제입니다:import cv2 from ultralytics import solutions cap = cv2.VideoCapture("path/to/video.mp4") assert cap.isOpened(), "Error reading video file" # 비디오 작성기 w, h, fps = (int(cap.get(x)) for x in (cv2.CAP_PROP_FRAME_WIDTH, cv2.CAP_PROP_FRAME_HEIGHT, cv2.CAP_PROP_FPS)) video_writer = cv2.VideoWriter("instance-segmentation.avi", cv2.VideoWriter_fourcc(*"mp4v"), fps, (w, h)) # 인스턴스 세그멘테이션 초기화 isegment = solutions.InstanceSegmentation( show=True, # 출력을 표시합니다. model="yolo26n-seg.pt", # model="yolo26n-seg.pt" for object segmentation using YOLO26. ) # 비디오 처리 while cap.isOpened(): success, im0 = cap.read() if not success: print("Video frame is empty or processing is complete.") break results = isegment(im0) video_writer.write(results.plot_im) cap.release() video_writer.release() cv2.destroyAllWindows()인스턴스 세그멘테이션은 이미지 내의 개별 객체를 식별하고 윤곽을 표시하여 각 객체에 고유한 레이블과 마스크를 부여합니다. 객체 추적은 비디오 프레임 전반에 걸쳐 객체에 일관된 ID를 할당하여 시간이 지나도 동일한 객체를 연속적으로 추적할 수 있도록 합니다. YOLO26 구현처럼 두 기능을 결합하면 정밀한 경계 정보를 유지하면서 비디오 속 객체의 움직임과 동작을 분석할 수 있습니다.
Ultralytics YOLO26은 Mask R-CNN이나 Faster R-CNN 같은 2단계 모델과 비교해 실시간 성능, 경쟁력 있는 정확도, 사용 편의성을 제공합니다. YOLO26은 이미지를 단일 패스(1단계 감지)로 처리하므로 높은 정밀도를 유지하면서 훨씬 빠르게 작동합니다. 또한 모델, 데이터셋, 학습 파이프라인 관리를 위해 Ultralytics Platform과 통합됩니다. 속도와 정확도가 모두 필요한 애플리케이션에서 YOLO26은 뛰어난 균형을 제공합니다.
네. Ultralytics는 인스턴스 세그멘테이션용 YOLO26 모델 학습에 적합한 여러 데이터셋을 제공합니다. 여기에는 COCO-Seg, 빠른 테스트에 적합한 소규모 하위 집합인 COCO8-Seg, Package-Seg 및 Crack-Seg이 포함됩니다. 이러한 데이터셋에는 인스턴스 세그멘테이션 작업에 필요한 픽셀 수준 어노테이션이 포함되어 있습니다. 더 전문화된 애플리케이션의 경우 Ultralytics 형식에 따라 사용자 지정 데이터셋을 만들 수도 있습니다. 전체 데이터셋 정보와 사용 지침은 Ultralytics 데이터셋 문서에서 확인할 수 있습니다.


댓글99
질문을 하거나 결과를 공유하거나 다른 사람을 도와주세요.
CatFatOw
Hello, I am trying to analyze a video and see if features grow/shrink over time. I am currently trying to use instance segmentation with object tracking; however, specifying
save_txt=Trueparameter inmodel.tracksaves every single prediction into a single huge txt file. Trying to count the frames by going through this large txt apparently doesn't work as the class ID are not in order and sorting it would lose all information.Is there any way for Ultralytics to save the txt files by frame number? For example, frame1.txt only contains the predictions of the first frame.
Any help would be greatly appreciated!
1 Glenn JocherUltralytics
For per-frame TXT saving with tracking, you'll need to process results in your video loop and write custom frame-specific files. Here's a minimal adaptation of the Instance Segmentation and Tracking example:
frame_count = 0
while cap.isOpened():
    ret, im0 = cap.read()
    if not ret: break

    results = model.track(im0, persist=True)

    # Save current frame's tracked objects
    with open(f'frame{frame_count}.txt', 'w') as f:
        for box, mask, track_id in zip(results[0].boxes, results[0].masks, results[0].boxes.id.int().cpu().tolist()):
            f.write(f"{track_id} {box.cls.item()} {box.xywhn.tolist()} {mask.xy[0].tolist()}\n")

    frame_count += 1
This creates individual frameX.txt files with tracking IDs, class IDs, normalized boxes, and mask coordinates. The official documentation shows similar frame processing in the Instance Segmentation with Object Tracking examples.
Thank you!
- Glenn JocherUltralytics
For per-frame TXT saving during tracking, you'll need to process each frame individually in your video loop as shown in the Instance Segmentation with Object Tracking example. Here's a minimal adaptation that creates frame-specific files:
frame_count = 0
while cap.isOpened():
    ret, im0 = cap.read()
    if not ret: break

    results = model.track(im0, persist=True)

    with open(f'frame{frame_count}.txt', 'w') as f:
        for box, mask, track_id in zip(results[0].boxes, results[0].masks, results[0].boxes.id.int().cpu().tolist()):
            f.write(f"{track_id} {box.cls.item()} {box.xywhn.tolist()} {mask.xy[0].tolist()}\n")

    frame_count += 1
This creates individual frameX.txt files with tracking IDs, class IDs, normalized boxes, and mask coordinates per frame. The approach mirrors the frame processing shown in our official tracking documentation.
pedmindset
Been trying to figure this out for a while now. I want to ask, can I use object counting in regions with instance sementation and tracking? You want to count vehicles that cross two specific regions, like so Object 001 crossed region A and region B. Is this possible to do
1- Glenn JocherUltralytics
@pedmindset yes, it is possible to combine object counting in regions with instance segmentation and tracking using Ultralytics YOLO11. You can use the
trackmethod to assign consistent IDs to objects across frames and define regions to monitor their crossings. For guidance, refer to the segmentation and tracking examples in the Instance Segmentation and Tracking Guide. Let us know if you need further clarification!
DP1701
Cool, but I can't define an imgsz via solutions.InstanceSegmentation(…). Is there another option for this?
- Glenn JocherUltralytics
solutions.InstanceSegmentationis a higher-level wrapper and doesn’t currently exposeimgszdirectly; if you need to control input size, run segmentation+tracking via the coreYOLO(...).track()API (supportsimgsz) as shown in the Tracking mode docs and keep using the Instance Segmentation and Tracking guide for solution-level usage.from ultralytics import YOLO model = YOLO("yolo26n-seg.pt") results = model.track(source="path/to/video.mp4", imgsz=640, show=True, tracker="botsort.yaml")
Hello, I noticed that when using tracking mode compared to normal segmentation prediction, the number of features predicted decreased by quite a lot for feature dense videos even if I use the same parameters of confidence and maximum detection?
- Glenn JocherUltralytics
@CatFatOw great observation! This is actually expected behavior when using tracking mode compared to plain segmentation. Tracking algorithms apply additional filtering beyond confidence thresholds to maintain stable tracks, which can reduce the total number of detections.
Here are a few things that might help increase detections while maintaining tracking:
# Try adjusting these tracking-specific parameters
results = model.track(
    frame,
    persist=True,
    conf=0.3,  # Lower confidence threshold
    iou=0.5,   # Adjust IoU threshold for NMS
    max_det=1000,  # Increase max detections
    tracker="bytetrack.yaml"  # Try different trackers
)
You can also experiment with different tracking algorithms - ByteTrack tends to be more permissive with new track creation compared to BoTSORT. The trade-off is between detection sensitivity and tracking stability, where tracking prioritizes consistent object IDs over detecting every possible instance.
If you need maximum detection sensitivity, consider running both modes and using tracking results only when you need the temporal consistency.
Ok, thank you for the reply!
Mauricio566
Hello. Please, I need your help. I know exactly what segmenting an object is and how to do it. But I don't know what to do with an already segmented object or pixel mask. You can find a lot of information online about "how to segment a model or fit it to your dataset," but they don't tell you what to do with those masks in real projects. Can you give me some ideas or help, please? for r in results:
if r.masks is not None: mask = r.masks.data[0].cpu().numpy() there is the mask but honestly I don't know what to do. thankse-roe
Hello Glenn, thanks for the example! Actually, I had already figured it out—it was more of a suggestion for the documentation examples. []´s
- Glenn JocherUltralytics
Thank you for the suggestion! We always welcome community contributions to improve our documentation through GitHub Pull Requests. Feel free to submit any specific improvements you'd like to see in the Instance Segmentation with Object Tracking guide.
1
Hello, Wouldn't it be good to have a complete example showing how to extract the track ID, contour points, class, and confidence? These methods that handle everything automatically end up being of little practical use, and finding this information in the documentation is quite challenging—it's often easier to find from third-party sources. []´s
- Glenn JocherUltralytics(수정됨)
@e-roe thanks for your feedback! You can access track IDs, classes, masks, and confidence scores directly from the results object. Here's a concise example showing how to extract these details:
results = isegment(im0)
for i in range(len(isegment.clss)):
    track_id = isegment.track_ids[i]
    class_name = isegment.names[isegment.clss[i]]
    confidence = isegment.confs[i]
    mask = isegment.masks[i].data[0].numpy()  # Binary mask array
    contours, _ = cv2.findContours(mask.astype(np.uint8), cv2.RETR_EXTERNAL, cv2.CHAIN_APPROX_SIMPLE)
For full implementation details, see the InstanceSegmentation reference in our documentation. Let us know if you need further clarification!
expen6ve
Hi! I tried training a pretrained yolov8m-seg model on our custom 1 class dataset consisting of 1,307 images with 5 augmentations like:
Flip: Horizontal, Vertical Rotation: Between -15° and +15° Saturation: Between -25% and +25% Blur: Up to 1.4px Noise: Up to 1.49% of pixels
with these training configurations:
# Train the model
results = model.train(
    data="data6.yaml",
    epochs=250,
    imgsz=320,
    batch=8,
    workers=4,
    device=device,
    patience=18,
    copy_paste=0.1  # Add this line to enable copy-paste augmentation
)
this is my 16th model training as i tried testing out from 200+ images that and so on. In my val plots, i always get bad results. What can i further do to make a good model? it stopped training at 128 with the results below:
epoch,time,train/box_loss,train/seg_loss,train/cls_loss,train/dfl_loss,metrics/precision(B),metrics/recall(B),metrics/mAP50(B),metrics/mAP50-95(B),metrics/precision(M),metrics/recall(M),metrics/mAP50(M),metrics/mAP50-95(M),val/box_loss,val/seg_loss,val/cls_loss,val/dfl_loss,lr/pg0,lr/pg1,lr/pg2
126,4123.96,0.47628,0.76702,0.30532,0.85667,0.9862,0.96565,0.98972,0.94445,0.9775,0.97566,0.98923,0.83189,0.35178,0.67432,0.26286,0.89191,0.00101,0.00101,0.00101 127,4156.45,0.47613,0.76458,0.30439,0.85872,0.96877,0.98339,0.98913,0.94227,0.98701,0.96962,0.99053,0.83626,0.34228,0.67744,0.25083,0.88958,0.00100208,0.00100208,0.00100208
- Glenn JocherUltralytics(수정됨)
@expen6ve thank you for sharing your training details. For improved segmentation results with YOLO26, consider these adjustments:
- Dataset Size: 1.3k images may be insufficient for robust segmentation. Aim for ≥5k high-quality annotated images.
- Augmentation Tuning: Reduce rotation range (try ±5°) and remove noise augmentation, which can degrade mask precision.
- Hyperparameters: Increase imgsz to 640 (standard for segmentation tasks) and lower learning rate to 0.0001 with cosine scheduler.
- Model Selection: Try YOLO26s-seg instead of medium-sized models for better generalization on limited data.
For detailed guidance, see the Segmentation Training Tips in our documentation.
ShreyasChhetri
Hi can we implement a Reinforcement Learning function up above the Yolo training function for more accuracy can it happen ?
- Glenn JocherUltralytics
@ShreyasChhetri integrating reinforcement learning (RL) with YOLO training is an interesting idea, but YOLO models are not inherently designed for RL workflows. While it is theoretically possible, it would require substantial custom development outside the scope of the provided Ultralytics framework. You might consider exploring hybrid approaches combining RL and computer vision if your use case demands it. For standard training, refer to the existing YOLO training documentation: https://docs.ultralytics.com/modes/train.
ZhangAiyi
I have a question when run the code for Instance Segmentation with Object Tracking. The pycharm said UnicodeEncodeError: 'gbk' codec can't encode character '\u274c' in position 401: illegal multibyte sequence. Does anyone have the similar question? Thank you.
- Glenn JocherUltralytics
@ZhangAiyi it seems like you're encountering a Unicode encoding issue. You can try setting your environment's encoding to UTF-8 in PyCharm to resolve this. If the problem persists, please check the PyCharm settings or your system's locale configuration.