Ultralytics YOLO26 sur NVIDIA Jetson avec DeepStream SDK et TensorRT
À regarder : Comment utiliser les modèles Ultralytics YOLO26 avec NVIDIA DeepStream sur Jetson Orin NX 🚀
Ce guide explique comment déployer Ultralytics YOLO26 sur des appareils NVIDIA Jetson avec DeepStream SDK et TensorRT. Nous utilisons TensorRT pour optimiser les performances d’inférence sur la plateforme Jetson.
Ce guide explique la configuration de DeepStream pour YOLO26, la calibration INT8, la configuration multi-flux et les résultats des benchmarks.
Ce guide a été testé avec le NVIDIA Jetson Orin Nano Super Developer Kit exécutant la version JetPack de JP6.1, le Seeed Studio reComputer J4012, basé sur NVIDIA Jetson Orin NX 16 Go et exécutant la version JetPack de JP5.1.3, ainsi que le Seeed Studio reComputer J1020 v2, basé sur NVIDIA Jetson Nano 4 Go et exécutant la version JetPack de JP4.6.4. Le guide devrait fonctionner sur toute la gamme de matériel NVIDIA Jetson, y compris les modèles les plus récents et les anciens.
Qu’est-ce que NVIDIA DeepStream ?#
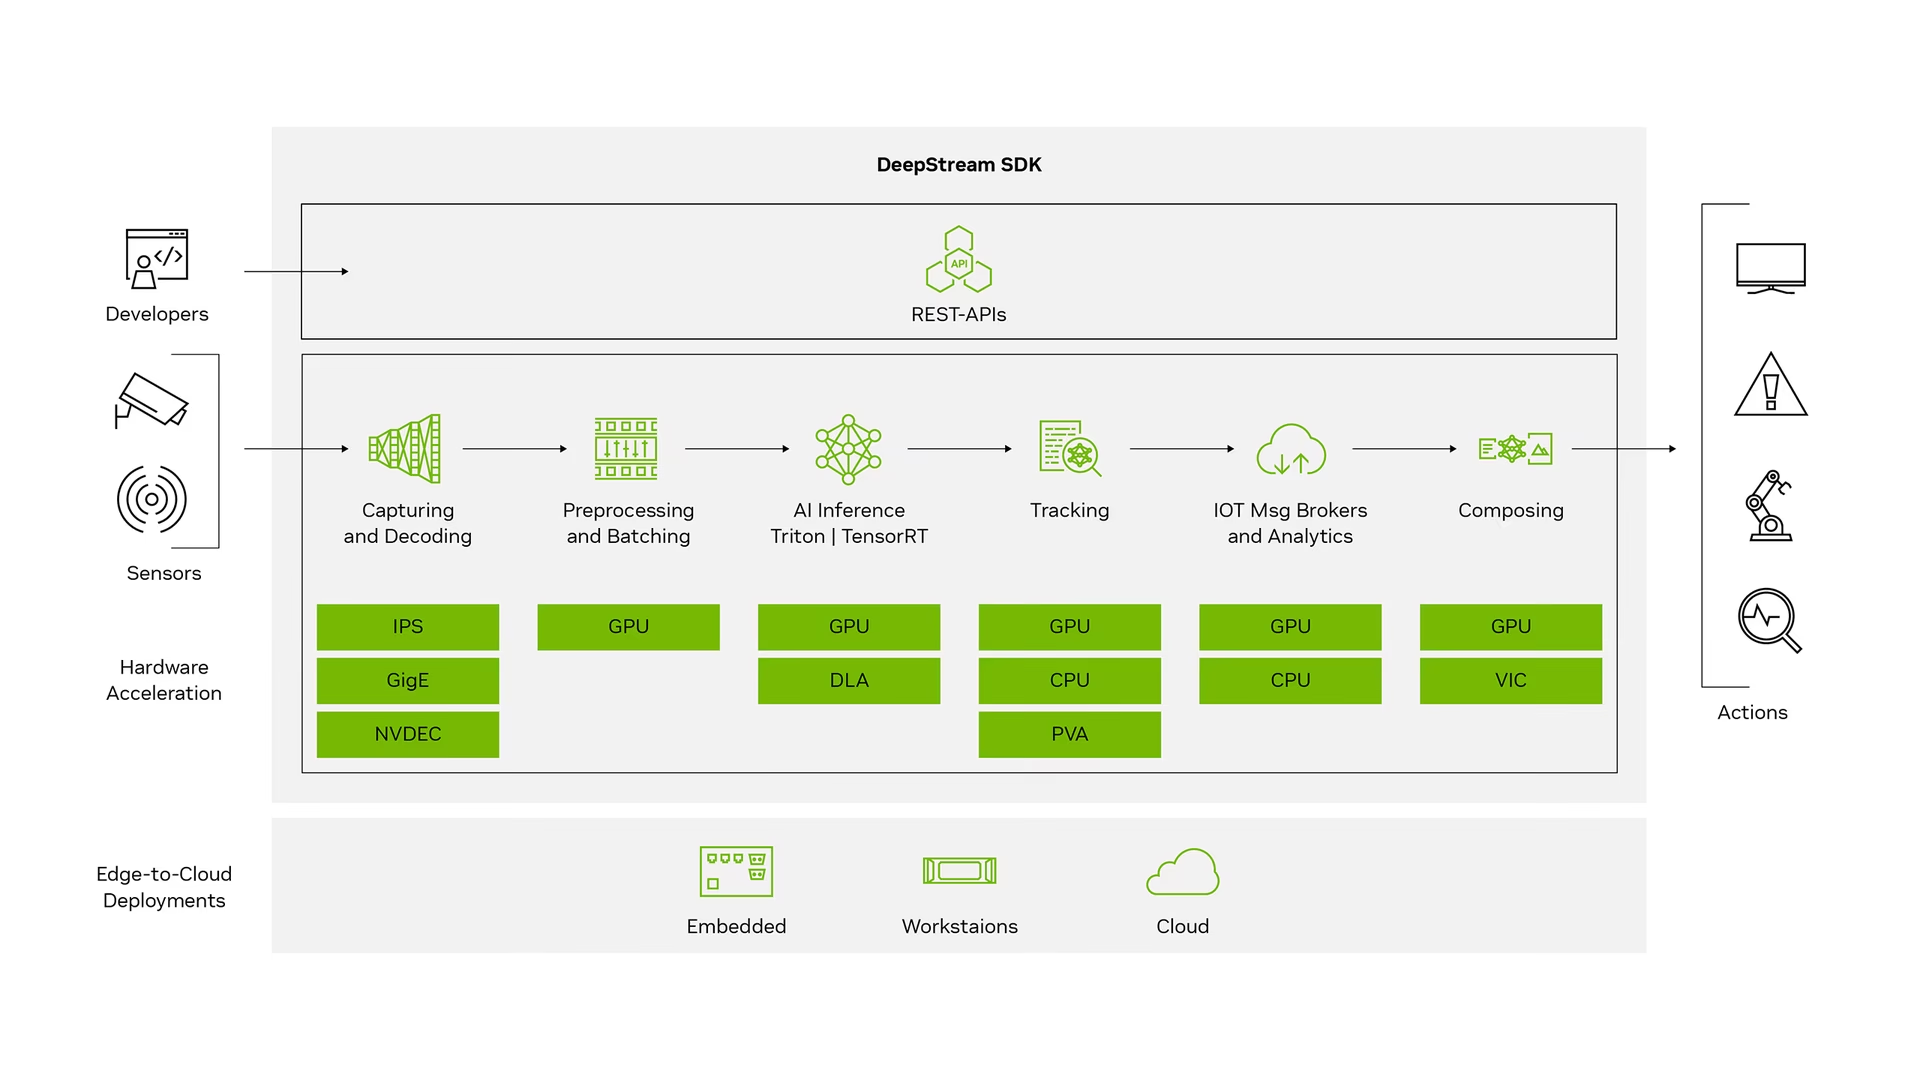
Le DeepStream SDK de NVIDIA est une boîte à outils complète d’analyse de flux basée sur GStreamer, destinée au traitement multisensoriel par IA et à la compréhension de vidéos, d’audio et d’images. Elle est idéale pour les développeurs en IA visuelle, les partenaires logiciels, les start-ups et les équipementiers qui créent des applications et services IVA (analyse vidéo intelligente). Tu peux créer des pipelines de traitement de flux intégrant des réseaux neuronaux et d’autres tâches de traitement complexes, comme le suivi, l’encodage et le décodage vidéo, ainsi que le rendu vidéo. Ces pipelines permettent l’analyse en temps réel de données vidéo, d’images et de capteurs. La prise en charge multiplateforme de DeepStream te permet de développer plus rapidement et plus facilement des applications et services d’IA visuelle sur site, à la périphérie et dans le cloud.
Prérequis#
Avant de suivre ce guide :
- Consulte notre documentation, le Guide de démarrage rapide : NVIDIA Jetson avec Ultralytics YOLO26, pour configurer ton appareil NVIDIA Jetson avec Ultralytics YOLO26.
- Installe DeepStream SDK en fonction de la version de JetPack.
- Pour JetPack 4.6.4, installe DeepStream 6.0.1.
- Pour JetPack 5.1.3, installe DeepStream 6.3.
- Pour JetPack 6.1, installe DeepStream 7.1.
- Pour JetPack 7.1, installe DeepStream 9.0.
Dans ce guide, nous avons utilisé la méthode du paquet Debian pour installer DeepStream SDK sur l’appareil Jetson. Tu peux également consulter DeepStream SDK sur Jetson (archivé) pour accéder aux anciennes versions de DeepStream.
Configuration de DeepStream pour YOLO26#
Nous utilisons ici le dépôt GitHub marcoslucianops/DeepStream-Yolo, qui inclut la prise en charge des modèles YOLO par NVIDIA DeepStream SDK. Nous remercions marcoslucianops pour ses contributions.
-
Installe Ultralytics avec les dépendances nécessaires.
pip install ultralytics onnx onnxslim -
Clone le dépôt DeepStream-Yolo.
cd ~ git clone https://github.com/marcoslucianops/DeepStream-Yolo -
Télécharge le modèle de détection Ultralytics YOLO26 (.pt) de ton choix depuis le projet YOLO26. Nous utilisons ici yolo26s.pt.
wget https://github.com/ultralytics/assets/releases/download/v8.4.0/yolo26s.pt
Tu peux également utiliser un modèle YOLO26 entraîné sur mesure.
-
Convertis le modèle au format ONNX et écris le fichier
labels.txtà partir duquel DeepStream lit les noms de classes.from ultralytics import YOLO model = YOLO("yolo26s.pt") model.export(format="onnx", nms=False, agnostic_nms=True) # crée 'yolo26s.onnx' with open("labels.txt", "w") as f: f.write("\n".join(model.names.values()))
nms=False exporte la tête sans NMS, et agnostic_nms=True conserve une seule classe par détection afin que cluster-mode=4 (sans regroupement) dans la configuration DeepStream ne dessine pas deux fois la même boîte. Ajoute imgsz=1280 pour modifier la taille d’inférence (par défaut : 640), batch=4 pour une taille de lot de 4 (le lot exporté est statique et doit donc correspondre à batch-size dans la configuration DeepStream), et opset=12 pour TensorRT 8.2 ou une version antérieure (DeepStream 6.0.1 et versions antérieures). Consulte la liste complète des arguments d’exportation.
-
Copie le fichier de modèle généré
.onnxet le fichierlabels.txtdans le dossierDeepStream-Yolo.cp yolo26s.onnx labels.txt ~/DeepStream-Yolo cd ~/DeepStream-Yolo -
Définis la version de CUDA en fonction de la version de JetPack installée.
Pour JetPack 4.6.4 :
export CUDA_VER=10.2Pour JetPack 5.1.3 :
export CUDA_VER=11.4Pour JetPack 6.1 :
export CUDA_VER=12.6Pour JetPack 7.1 :
export CUDA_VER=13.0 -
Compile la bibliothèque.
make -C nvdsinfer_custom_impl_Yolo clean && make -C nvdsinfer_custom_impl_Yolo -
Modifie le fichier
config_infer_primary_yolo26.txten fonction de ton modèle (pour YOLO26s avec 80 classes).[property] ... onnx-file=yolo26s.onnx ... num-detected-classes=80 ... parse-bbox-func-name=NvDsInferParseYolo ...
YOLO26 redimensionne l’entrée en ajoutant une marge centrée et s’exécute sans NMS. Pour obtenir la meilleure précision, ajoute les lignes suivantes à la section [property] de config_infer_primary_yolo26.txt :
[property]
...
maintain-aspect-ratio=1
symmetric-padding=1
cluster-mode=4
...-
Modifie le fichier
deepstream_app_config.... [primary-gie] ... config-file=config_infer_primary_yolo26.txt -
Tu peux également modifier la source vidéo dans le fichier
deepstream_app_config. Ici, un fichier vidéo par défaut est chargé.... [source0] ... uri=file:///opt/nvidia/deepstream/deepstream/samples/streams/sample_1080p_h264.mp4
Exécuter l’inférence#
deepstream-app -c deepstream_app_config.txtLa génération du fichier moteur TensorRT peut prendre beaucoup de temps avant le début de l’inférence.
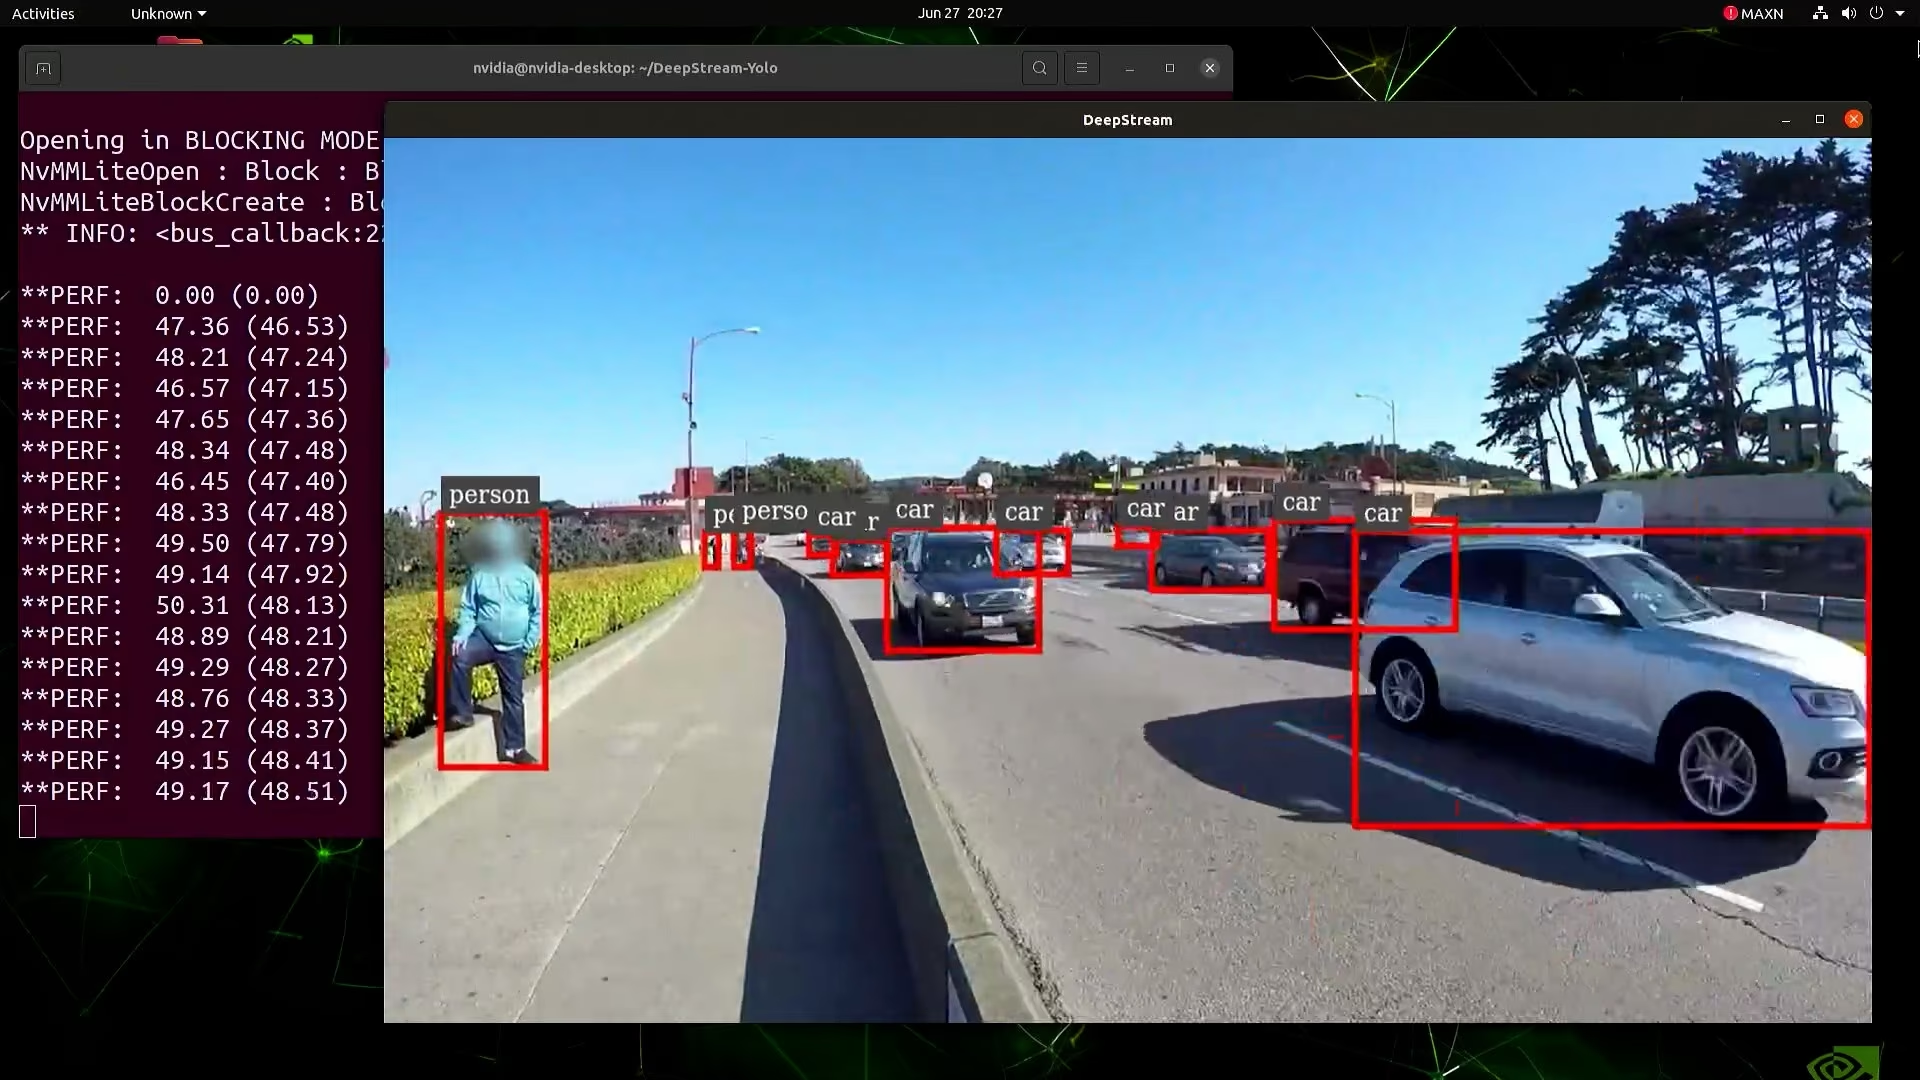
Pour convertir le modèle en précision FP16, définis model-engine-file=model_b1_gpu0_fp16.engine et network-mode=2 dans config_infer_primary_yolo26.txt
Calibration INT8#
Pour utiliser la précision INT8 pour l’inférence, suis ces étapes :
Actuellement, INT8 ne fonctionne pas avec TensorRT 10.x. Cette section du guide a été testée avec TensorRT 8.x, avec lequel elle devrait fonctionner.
-
Définis la variable d’environnement
OPENCV.export OPENCV=1 -
Compile la bibliothèque.
make -C nvdsinfer_custom_impl_Yolo clean && make -C nvdsinfer_custom_impl_Yolo -
Pour le jeu de données COCO, télécharge val2017, extrais-le et déplace-le dans le dossier
DeepStream-Yolo. -
Crée un nouveau répertoire pour les images de calibration.
mkdir calibration -
Exécute la commande suivante pour sélectionner 1 000 images aléatoires du jeu de données COCO et effectuer la calibration.
for jpg in $(ls -1 val2017/*.jpg | sort -R | head -1000); do
  cp ${jpg} calibration/
done
NVIDIA recommande d’utiliser au moins 500 images pour obtenir une bonne précision. Dans cet exemple, 1 000 images sont choisies pour améliorer la précision (en général, plus le nombre d’images est élevé, meilleure est la précision). Tu peux définir cette valeur à partir de head -1000. Par exemple, pour 2 000 images, utilise head -2000. Ce processus peut prendre beaucoup de temps.
-
Crée le fichier
calibration.txtcontenant toutes les images sélectionnées.realpath calibration/*jpg > calibration.txt -
Définis les variables d’environnement.
export INT8_CALIB_IMG_PATH=calibration.txt
export INT8_CALIB_BATCH_SIZE=1
Des valeurs INT8_CALIB_BATCH_SIZE plus élevées permettent une calibration plus précise et plus rapide. Choisis une valeur adaptée à la mémoire de ton GPU.
-
Mets à jour le fichier
config_infer_primary_yolo26.txt.De
...
model-engine-file=model_b1_gpu0_fp32.engine
#int8-calib-file=calib.table
...
network-mode=0
...
À
...
model-engine-file=model_b1_gpu0_int8.engine
int8-calib-file=calib.table
...
network-mode=1
...
Exécuter l’inférence INT8#
Exécute la même commande pour créer le moteur INT8 et démarrer l’inférence :
deepstream-app -c deepstream_app_config.txtConfiguration multi-flux#
À regarder : Comment effectuer une inférence sur plusieurs flux avec Ultralytics YOLO26 et NVIDIA DeepStream sur Jetson Orin 🚀
Pour configurer plusieurs flux dans une même application DeepStream, apporte les modifications suivantes au fichier deepstream_app_config.txt :
-
Modifie le nombre de lignes et de colonnes pour créer une grille d’affichage adaptée au nombre de flux souhaité. Par exemple, pour 4 flux, ajoute 2 lignes et 2 colonnes.
[tiled-display] rows=2 columns=2 -
Ajoute un groupe
[sourceN]distinct pour chaque flux, chacun avec ses propresurietnum-sources=1.[source0] enable=1 type=3 uri=file:///path/to/video1.mp4 num-sources=1 [source1] enable=1 type=3 uri=file:///path/to/video2.mp4 num-sources=1 [source2] enable=1 type=3 uri=file:///path/to/video3.mp4 num-sources=1 [source3] enable=1 type=3 uri=file:///path/to/video4.mp4 num-sources=1
Exécuter l’inférence multi-flux#
Exécute la même commande pour lancer tous les flux dans l’affichage en mosaïque :
deepstream-app -c deepstream_app_config.txt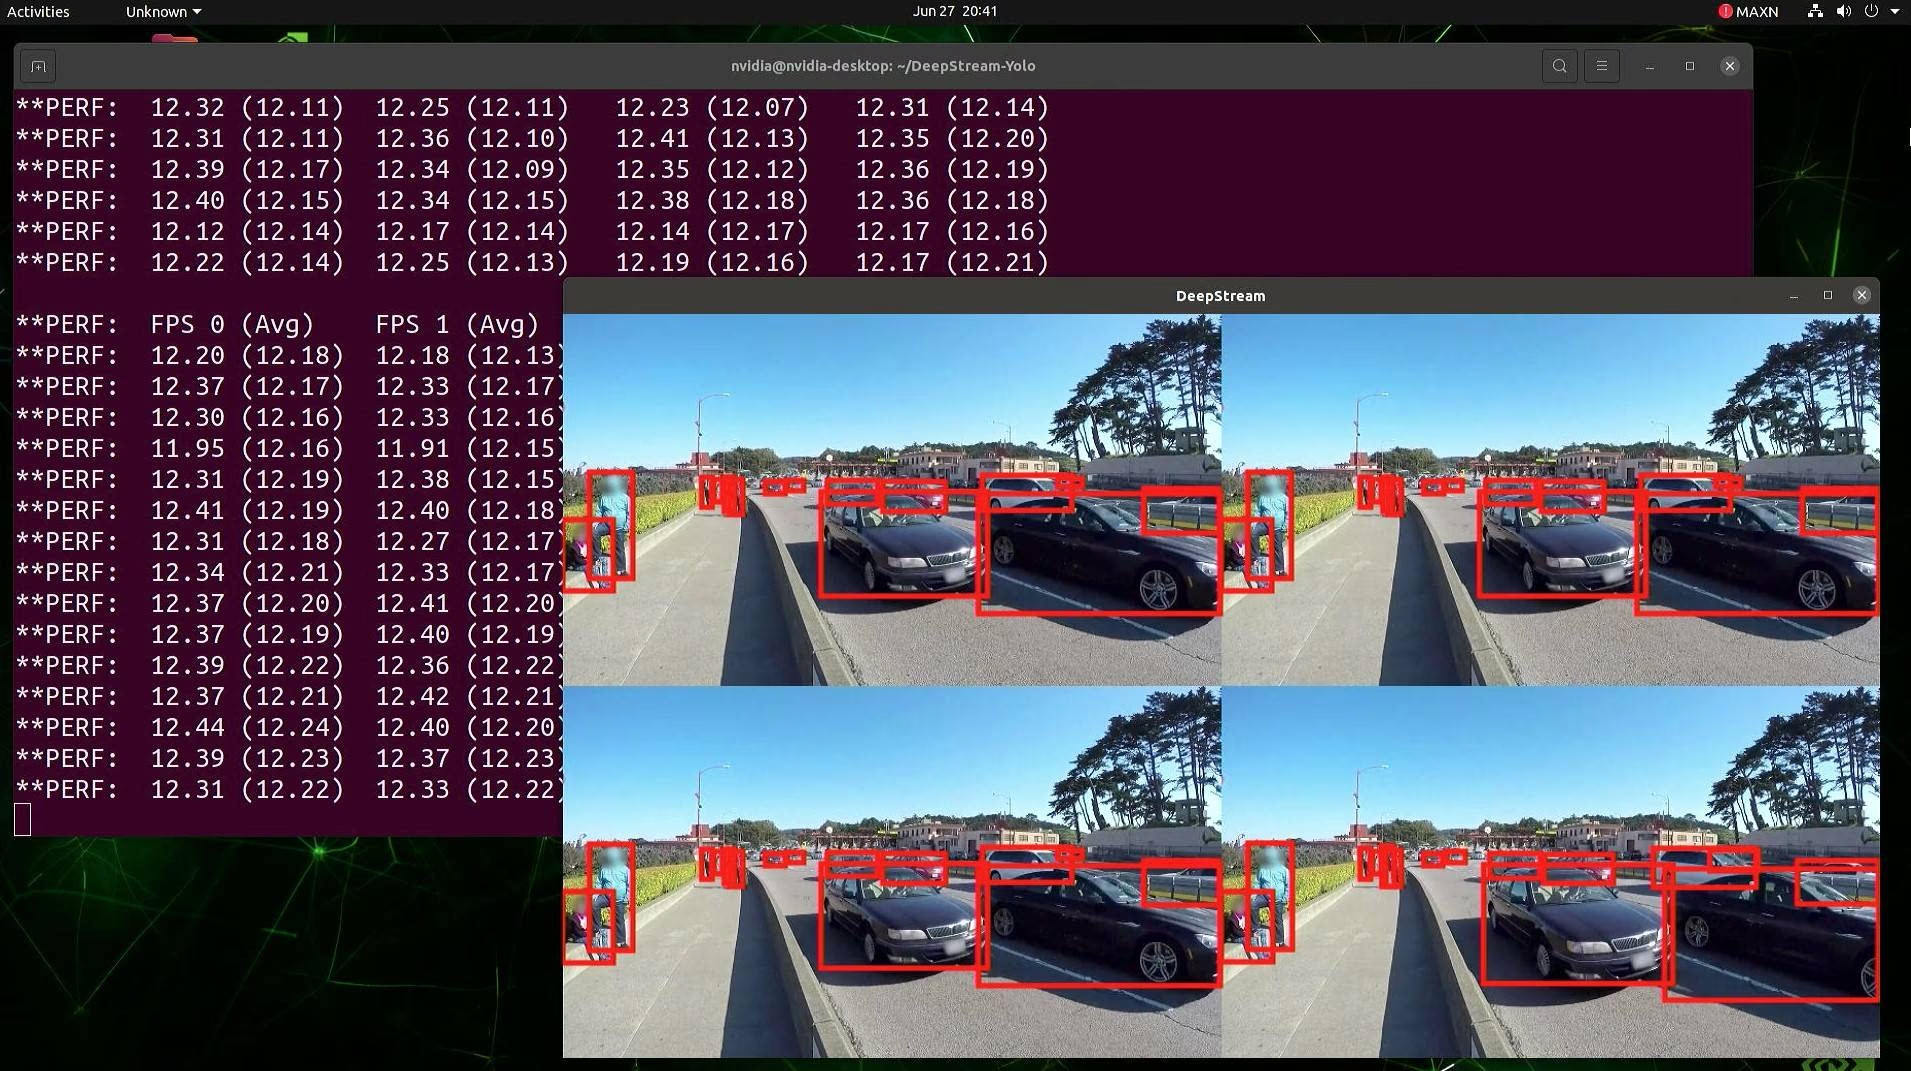
Résultats des benchmarks#
Les benchmarks suivants résument les performances des modèles YOLO11 avec différents niveaux de précision TensorRT, pour une taille d’entrée de 640x640 sur NVIDIA Jetson Orin NX 16 Go. YOLO26 utilise le même processus d’exportation et d’inférence DeepStream décrit ci-dessus.
Graphique comparatif#
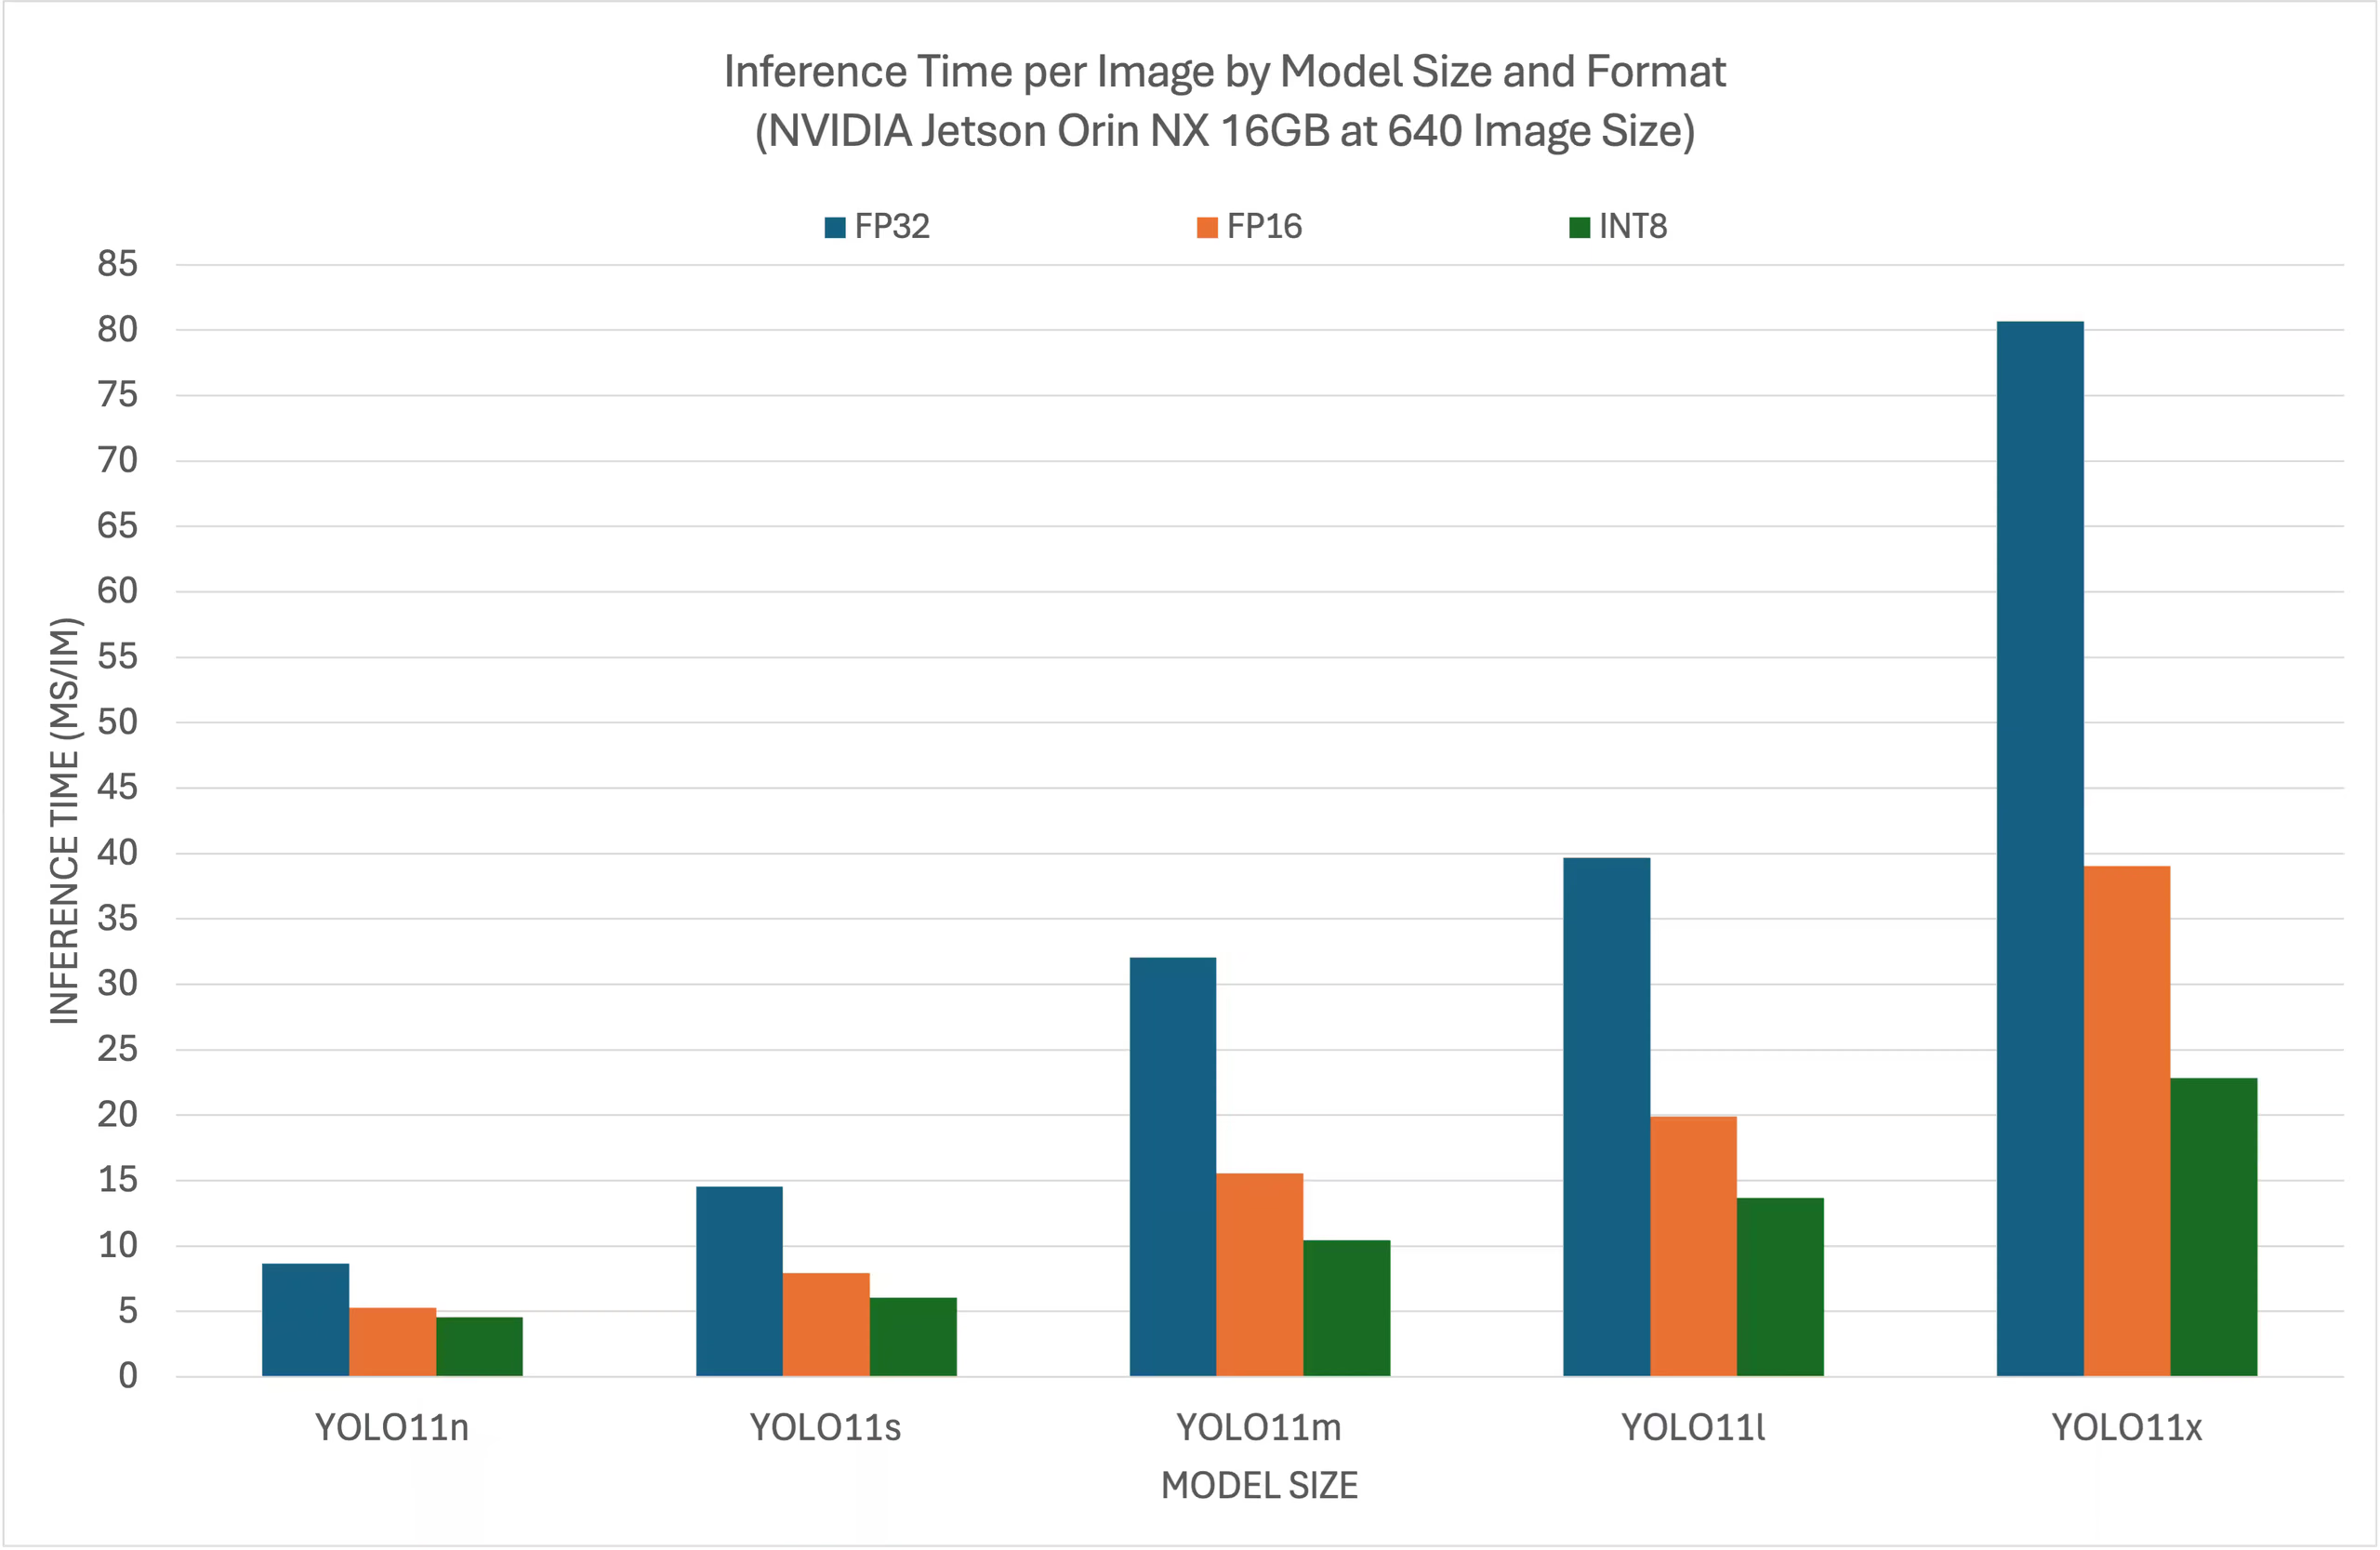
Tableau comparatif détaillé#
| Format | Statut | Temps d’inférence (ms/im) |
|---|---|---|
| TensorRT (FP32) | ✅ | 8.64 |
| TensorRT (FP16) | ✅ | 5.27 |
| TensorRT (INT8) | ✅ | 4.54 |
Remerciements#
Ce guide a été créé à l’origine par nos amis Lakshantha et Elaine, de Seeed Studio.
FAQ#
Pour configurer Ultralytics YOLO26 sur un appareil NVIDIA Jetson, tu dois d’abord installer DeepStream SDK, compatible avec ta version de JetPack. Suis les étapes détaillées de notre Guide de démarrage rapide pour configurer ton NVIDIA Jetson en vue du déploiement de YOLO26.
L’utilisation de TensorRT avec YOLO26 optimise le modèle pour l’inférence, ce qui réduit considérablement la latence et améliore le débit sur les appareils NVIDIA Jetson. TensorRT offre une inférence de deep learning à hautes performances et faible latence grâce à la fusion de couches, à la calibration de la précision et à l’optimisation automatique des noyaux. L’exécution est ainsi plus rapide et plus efficace, ce qui est particulièrement utile pour les applications en temps réel, comme l’analyse vidéo et les machines autonomes.
Oui, le guide de déploiement d’Ultralytics YOLO26 avec DeepStream SDK et TensorRT est compatible avec toute la gamme NVIDIA Jetson. Il couvre notamment les appareils Jetson Orin NX 16 Go avec JetPack 5.1.3 et Jetson Nano 4 Go avec JetPack 4.6.4. Consulte la section Configuration de DeepStream pour YOLO26 pour obtenir des instructions détaillées.
Exporte le modèle avec la tête sans NMS à l’aide de l’outil d’exportation Ultralytics, puis écris le fichier
labels.txtà partir duquel DeepStream lit les noms de classes :from ultralytics import YOLO model = YOLO("yolo26s.pt") model.export(format="onnx", nms=False, agnostic_nms=True) # crée 'yolo26s.onnx' with open("labels.txt", "w") as f: f.write("\n".join(model.names.values()))Ajoute
opset=12pour TensorRT 8.2 ou une version antérieure (DeepStream 6.0.1 et versions antérieures). Pour en savoir plus sur la conversion de modèles, consulte notre section sur l’exportation des modèles.Pour exécuter l’inférence INT8, calibre le modèle sur un ensemble représentatif d’images et passe la configuration DeepStream en mode INT8. Télécharge les images COCO val2017, sélectionne environ 1 000 images de calibration, définis les variables d’environnement
INT8_CALIB_IMG_PATHetINT8_CALIB_BATCH_SIZE, puis mets à jourconfig_infer_primary_yolo26.txtavecmodel-engine-file=model_b1_gpu0_int8.engine,int8-calib-file=calib.tableetnetwork-mode=1. Consulte la section Calibration INT8 pour suivre toutes les étapes. INT8 nécessite actuellement TensorRT 8.x.Pour traiter plusieurs flux dans une seule application DeepStream, modifie le fichier
deepstream_app_config.txtpour ajouter une grille d’affichage en mosaïque et répertorier l’URI de chaque source. Définisrowsetcolumnsdans[tiled-display]pour créer la grille, ajoute un groupe[sourceN]distinct pour chaque flux avec ses propresurietnum-sources=1, puis ajuste la grille en fonction du nombre de flux. Consulte la section Configuration multi-flux pour voir un exemple complet.Les performances des modèles YOLO11 sur NVIDIA Jetson Orin NX 16 Go varient selon le niveau de précision TensorRT. Par exemple, les modèles YOLO11s obtiennent les résultats suivants :
- Précision FP32 : 14.53 ms/im, 68.8 FPS
- Précision FP16 : 7.91 ms/im, 126 FPS
- Précision INT8 : 6.05 ms/im, 165 FPS
Ces résultats montrent dans quelle mesure les moteurs TensorRT FP16 et INT8 accélèrent les modèles YOLO11 sur le matériel NVIDIA Jetson.


Commentaires145
Pose une question, partage tes résultats ou aide quelqu’un d’autre.
Llinz24
hi!I encountered the following issue when using NVIDIA's official DeepStream 8.0 gc-triton-devel image to implement deepstream-yolo: I cannot compile the library, and it prompts that my Tensor version is too new. Is there any solution? Could it be that the current code hasn't fully adapted to DeepStream 8.0? ( root@LGDX:/workspace/DeepStream-Yolo# export CUDA_VER=12.8 root@LGDX:/workspace/DeepStream-Yolo# make -C nvdsinfer_custom_impl_Yolo clean && make -C nvdsinfer_custom_impl_Yolo make: Entering directory '/workspace/DeepStream-Yolo/nvdsinfer_custom_impl_Yolo' rm -rf libnvdsinfer_custom_impl_Yolo.so rm -rf nvdsinfer_yolo_engine.o nvdsparsebbox_Yolo.o utils.o yolo.o yoloPlugins.o layers/activation_layer.o layers/batchnorm_layer.o layers/channels_layer.o layers/convolutional_layer.o layers/deconvolutional_layer.o layers/implicit_layer.o layers/pooling_layer.o layers/reorg_layer.o layers/route_layer.o layers/sam_layer.o layers/shortcut_layer.o layers/slice_layer.o layers/upsample_layer.o nvdsparsebbox_Yolo_cuda.o yoloForward.o yoloForward_nc.o yoloForward_v2.o make: Leaving directory '/workspace/DeepStream-Yolo/nvdsinfer_custom_impl_Yolo' make: Entering directory '/workspace/DeepStream-Yolo/nvdsinfer_custom_impl_Yolo' g++ -c -o nvdsinfer_yolo_engine.o -Wall -std=c++11 -shared -fPIC -Wno-error=deprecated-declarations -I/opt/nvidia/deepstream/deepstream/sources/includes -I/usr/local/cuda-12.8/include nvdsinfer_yolo_engine.cpp g++ -c -o nvdsparsebbox_Yolo.o -Wall -std=c++11 -shared -fPIC -Wno-error=deprecated-declarations -I/opt/nvidia/deepstream/deepstream/sources/includes -I/usr/local/cuda-12.8/include nvdsparsebbox_Yolo.cpp In file included from nvdsparsebbox_Yolo.cpp:26: nvdsparsebbox_Yolo.cpp: In function 'void checkFunc_NvDsInferParseYolo(NvDsInferParseCustomFunc)': /opt/nvidia/deepstream/deepstream/sources/includes/nvdsinfer_custom_impl.h:221:17: warning: infinite recursion detected [-Winfinite-recursion] 221 | static void checkFunc_ ## customParseFunc (NvDsInferParseCustomFunc func = customParseFunc)
| ^~~~~~~~~~ nvdsparsebbox_Yolo.cpp:129:1: note: in expansion of macro 'CHECK_CUSTOM_PARSE_FUNC_PROTOTYPE' 129 | CHECK_CUSTOM_PARSE_FUNC_PROTOTYPE(NvDsInferParseYolo); | ^~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~ /opt/nvidia/deepstream/deepstream/sources/includes/nvdsinfer_custom_impl.h:222:41: note: recursive call 222 | { checkFunc_ ## customParseFunc (); };
| ~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~^~ nvdsparsebbox_Yolo.cpp:129:1: note: in expansion of macro 'CHECK_CUSTOM_PARSE_FUNC_PROTOTYPE' 129 | CHECK_CUSTOM_PARSE_FUNC_PROTOTYPE(NvDsInferParseYolo); | ^~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~ g++ -c -o utils.o -Wall -std=c++11 -shared -fPIC -Wno-error=deprecated-declarations -I/opt/nvidia/deepstream/deepstream/sources/includes -I/usr/local/cuda-12.8/include utils.cpp g++ -c -o yolo.o -Wall -std=c++11 -shared -fPIC -Wno-error=deprecated-declarations -I/opt/nvidia/deepstream/deepstream/sources/includes -I/usr/local/cuda-12.8/include yolo.cpp In file included from yolo.cpp:29: yoloPlugins.h:53:59: warning: 'IPluginV2DynamicExt' is deprecated [-Wdeprecated-declarations] 53 | nvinfer1::IPluginV2DynamicExt* clone() const noexcept override; | ^~~~~~~~ In file included from /usr/include/x86_64-linux-gnu/NvInfer.h:22, from /usr/include/x86_64-linux-gnu/NvOnnxParser.h:21, from yolo.cpp:26: /usr/include/x86_64-linux-gnu/NvInferRuntime.h:406:22: note: declared here 406 | class TRT_DEPRECATED IPluginV2DynamicExt : public nvinfer1::IPluginV2Ext | ^~~~~~~~~~~~~~~~~~~ yoloPlugins.h:124:9: warning: 'IPluginV2DynamicExt' is deprecated [-Wdeprecated-declarations] 124 | override { | ^~~~~~~~ /usr/include/x86_64-linux-gnu/NvInferRuntime.h:406:22: note: declared here 406 | class TRT_DEPRECATED IPluginV2DynamicExt : public nvinfer1::IPluginV2Ext | ^~~~~~~~~~~~~~~~~~~ yoloPlugins.h:130:18: warning: 'IPluginV2DynamicExt' is deprecated [-Wdeprecated-declarations] 130 | noexcept override { | ^~~~~~~~ /usr/include/x86_64-linux-gnu/NvInferRuntime.h:406:22: note: declared here 406 | class TRT_DEPRECATED IPluginV2DynamicExt : public nvinfer1::IPluginV2Ext | ^~~~~~~~~~~~~~~~~~~ yolo.cpp: In member function 'nvinfer1::ICudaEngine* Yolo::createEngine(nvinfer1::IBuilder*, nvinfer1::IBuilderConfig*)': yolo.cpp:71:76: error: 'kEXPLICIT_BATCH' is not a member of 'nvinfer1::NetworkDefinitionCreationFlag' 71 | tic_cast<uint32_t>(nvinfer1::NetworkDefinitionCreationFlag::kEXPLICIT_BATCH); | ^~~~~~~~~~~~~~~In file included from /usr/include/c++/13/cassert:44, from layers/../utils.h:32, from layers/route_layer.h:9, from yolo.h:39, from yolo.cpp:28: yolo.cpp:155:21: error: 'class nvinfer1::IBuilder' has no member named 'platformHasFastFp16' 155 | assert(builder->platformHasFastFp16()); | ^~~~~~~~~~~~~~~~~~~ yolo.cpp:156:44: error: 'kFP16' is not a member of 'nvinfer1::BuilderFlag' 156 | config->setFlag(nvinfer1::BuilderFlag::kFP16); | ^~~~~ yolo.cpp:159:21: error: 'class nvinfer1::IBuilder' has no member named 'platformHasFastInt8' 159 | assert(builder->platformHasFastInt8()); | ^~~~~~~~~~~~~~~~~~~ yolo.cpp:160:44: error: 'kINT8' is not a member of 'nvinfer1::BuilderFlag' 160 | config->setFlag(nvinfer1::BuilderFlag::kINT8); | ^~~~~ yolo.cpp: In member function 'NvDsInferStatus Yolo::buildYoloNetwork(std::vector&, nvinfer1::INetworkDefinition&)': yolo.cpp:481:36: warning: 'IPluginV2DynamicExt' is deprecated [-Wdeprecated-declarations] 481 | nvinfer1::IPluginV2DynamicExt* yoloPlugin = new YoloLayer(m_InputW, m_InputH, m_NumClasses, m_NewCoords, | ^~~~~~~~~~ /usr/include/x86_64-linux-gnu/NvInferRuntime.h:406:22: note: declared here 406 | class TRT_DEPRECATED IPluginV2DynamicExt : public nvinfer1::IPluginV2Ext | ^~~~~~~~~~~~~~~~~~~ yolo.cpp:484:31: warning: 'IPluginV2Layer' is deprecated [-Wdeprecated-declarations] 484 | nvinfer1::IPluginV2Layer* yolo = network.addPluginV2(yoloTensorInputs, m_YoloCount, yoloPlugin); | ^~~~ /usr/include/x86_64-linux-gnu/NvInfer.h:2542:22: note: declared here 2542 | class TRT_DEPRECATED IPluginV2Layer : public ILayer | ^~~~~~~~~~~~~~ yolo.cpp:484:57: warning: 'nvinfer1::IPluginV2Layer nvinfer1::INetworkDefinition::addPluginV2(nvinfer1::ITensor* const*, int32_t, nvinfer1::IPluginV2&)' is deprecated [-Wdeprecated-declarations] 484 | nvinfer1::IPluginV2Layer* yolo = network.addPluginV2(yoloTensorInputs, m_YoloCount, yoloPlugin); | ~~~~~~~~~~~~~~~~~~~^~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~ /usr/include/x86_64-linux-gnu/NvInfer.h:8859:36: note: declared here 8859 | TRT_DEPRECATED IPluginV2Layer addPluginV2(ITensor* const* inputs, int32_t nbInputs, IPluginV2& plugin) noexcept | ^~~~~~~~~~~ make: *** [Makefile:86: yolo.o] Error 1 make: Leaving directory '/workspace/DeepStream-Yolo/nvdsinfer_custom_impl_Yolo' root@LGDX:/workspace/DeepStream-Yolo#)
 Glenn JocherUltralytics
Yes, those build errors are from a TensorRT API mismatch, not your commands: the
DeepStream-Yolopath used in this doc was tested with the DeepStream/JetPack combinations listed in the Jetson + DeepStream guide, andDeepStream 8.0 gc-triton-develis using newer TensorRT APIs where symbols likekEXPLICIT_BATCH,kFP16, andplatformHasFastFp16()are gone, so it will not compile unchanged; for now please use a supported version combo from the guide or a direct TensorRT export workflow, and if you want to stay on DS 8.0 please share the exactDeepStream-Yolocommit plus your TensorRT version here so we can point out the required upstream patch areas.root@LGDX:/workspace/DeepStream-Yolo# dpkg -l | grep tensorrt ii tensorrt-dev 11.0.0.114-1+cuda13.2 amd64 Meta package for TensorRT development libraries
If I plan to use yolo11-pose and yolo26, what kind of adjustments do I need?
- Glenn JocherUltralytics(modifié)
For
YOLO11-pose, use DeepStream-Yolo-Pose withconfig_infer_primary_yolo11_pose.txt; forYOLO26detection, use the main DeepStream-Yolo repo and export through its updatedexport_yolo26.pypath or export with thenmsargument described in the End-to-End Detection guide for the classic DeepStream parser flow. The bigger blocker is your environment: DeepStream 8.0 on x86 is validated with TensorRT 10.9.0.34, while your container has TensorRT11.0.0, and TRT 11 removed the older builder-flag/calibrator APIs, so those external DeepStream custom libs need a TRT11 migration before they will compile; the quickest path is a TRT 10.9 DeepStream 8.0 stack plus the latest repo files, and the relevant Ultralytics export compatibility notes are in Export Settings.
 User
Why can't I see my class name in the block boxes with multiple RTSP video streams (like in the single-stream example)?
Is there a way to fix this?
- Glenn JocherUltralytics
Yes—if you’re using
deepstream-appin tiled multistream mode, bbox labels are often hidden unless you start it with-t, so trydeepstream-app -c deepstream_app_config.txt -t, then confirm[osd]hasdisplay-text=1and increasetext-sizeif the tiles are small; please keep Jetson/DeepStream questions here in Discussions so the team can track them, and the Jetson + DeepStream guide is the right reference alongside NVIDIA’s DeepStream reference app docs. (forums.developer.nvidia.com)
Is YOLO26-seg currently supported for direct deployment and execution in DeepStream? Are there any available tutorials or reference solutions?
- Glenn JocherUltralytics
Not in the published direct DeepStream flow yet—the current Jetson + DeepStream guide is detection-focused and uses
DeepStream-Yolo, while the available segmentation reference is DeepStream-Yolo-Seg, which currently listsYOLO11-SegandYOLOv8-Segsupport rather thanYOLO26-seg, so there isn’t an official YOLO26-seg DeepStream tutorial at the moment; feel free to keep the details here in Discussions and we can help with the closest path forward. (docs.ultralytics.com) I'm running into an issue with YOLO11-seg + DeepStream and could use some help 🙏 So I exported my YOLO11-seg model to ONNX and then to a TensorRT engine. When I run deepstream-app, it does find and load the engine just fine — but the segmentation part just doesn't work. I'm not seeing any masks or even bounding boxes on the video output. Any idea what might be going wrong here? Also, when I use the deepstream-yolo export script to get the ONNX file, the output only shows one node: 1 OUTPUT kFLOAT output 100x102406 But from what I've seen with official YOLO-seg exports (like from Ultralytics), there should usually be two outputs — one for boxes/classes and another for the masks. That mismatch feels like it might be part of the problem? Has anyone run into this before? Any tips on: How to export the ONNX correctly for YOLO-seg (maybe a flag I'm missing?) What to tweak in the DeepStream config (config_infer_primary.txt, parser settings, etc.) to make it actually show the segmentation results? Thanks in advance!
- Glenn JocherUltralytics
Yes, a single-output ONNX is very likely the blocker here: for YOLO11-seg, DeepStream needs the segmentation export with both detection and mask-proto outputs, so a detection-style ONNX/parser will often load the engine but show neither boxes nor masks; please re-export from the Ultralytics side using the workflow in the TensorRT export docs, make sure you are using the segmentation-specific DeepStream parser/config rather than the detection one, and if it still fails please paste the full
deepstream-applog plusyolo checksoutput here so we can verify the tensor names, parser, and engine match.
aneesarom
Below is the result from deepstream
**PERF: FPS 0 (Avg) **PERF: 53.80 (58.72) **PERF: 60.00 (59.38) **PERF: 60.00 (59.59) **PERF: 60.00 (59.69)
But i can get around 85 fps using ultralytics inference. why is that so. what is the need of using deepstream then. or i am doing anything wrong?
- Glenn JocherUltralytics
Those
PERFnumbers fromdeepstream-appare end-to-end pipeline FPS and are often capped by your input stream rate and/or display sync (so a steady ~60 usually means you’re running “real-time/render-limited,” not model-limited), while your Ultralytics run is likely closer to “pure inference throughput”; DeepStream’s value is when you need a full GStreamer pipeline (decode/scale/batching/multi-stream/OSD/encode/RTSP), so for a fair comparison try a headless config (disable OSD/tiler and use fakesink withsync=0) as described in the Ultralytics YOLO26 DeepStream on Jetson guide and make sure you’re matching TensorRT precision/imgszlike in the TensorRT export docs:[osd] enable=0 [tiled-display] enable=0 [sink0] type=1 sync=0If you paste your
deepstream_app_config.txt[source0]+[sink0]+[primary-gie]sections (and JetPack/DeepStream versions) here, we can point out what’s throttling it.1 @glenn-jocher Thank you so much for your reply. Now i understood and can see 120 Fps with this setting. But i have a doubt when do we need deepstream over normal ultralytics inferencing. Can you explain it
- Glenn JocherUltralytics
DeepStream is worth using when you need a production GStreamer pipeline around the model—hardware-accelerated decode/encode, zero-copy GPU memory, batching across multiple cameras/streams, RTSP ingest/egress, OSD/tiling, tracking, and easy composition with other DeepStream plugins—whereas “plain” Ultralytics inference is often the simplest/fastest path for single-stream or custom Python loops that just need model outputs; the DeepStream on Jetson guide and the TensorRT export docs are the best references, and feel free to drop your specific target pipeline (sources/sinks/stream count/latency needs) here so we can sanity-check the recommended setup.
Saarulog
Hello,
Thank you for all your help to my issues.
I have a usb camera with the below format and fails to run. How do I get deepstream to accept or convert the format below to the needed format for display.
Deepstream 7.1/Jetpack 6.2.1
deepstream app text file:
[soruce0] camera- camera-fps-n=9 camera-fps-d=1
v4l2-ctl -d /dev/video0 --list-formats-ext
ioctl: VIDIOC_ENUM_FMT Type: Video Capture
[0]: 'UYVY' (UYVY 4:2:2)
	Size: Discrete 80x60
		Interval: Discrete 0.111s (9.000 fps)
[1]: 'Y16 ' (16-bit Greyscale)
	Size: Discrete 80x60
		Interval: Discrete 0.111s (9.000 fps)
	Size: Discrete 80x63
		Interval: Discrete 0.111s (9.000 fps)
[2]: 'GREY' (8-bit Greyscale)
	Size: Discrete 80x60
		Interval: Discrete 0.111s (9.000 fps)
[3]: 'RGBP' (16-bit RGB 5-6-5)
	Size: Discrete 80x60
		Interval: Discrete 0.111s (9.000 fps)
[4]: 'BGR3' (24-bit BGR 8-8-8)
	Size: Discrete 80x60
		Interval: Discrete 0.111s (9.000 fps)
GST_DEBUG=3 deepstream-app -c deepstream_app_config_yolo26_1usbcam.txt
Setting min object dimensions as 16x16 instead of 1x1 to support VIC compute mode. WARNING: [TRT]: Using an engine plan file across different models of devices is not recommended and is likely to affect performance or even cause errors. 0:00:00.401328266 6238 0xaaaad1ab46c0 INFO nvinfer gstnvinfer.cpp:684:gst_nvinfer_logger:<primary_gie> NvDsInferContext[UID 1]: Info from NvDsInferContextImpl::deserializeEngineAndBackend() <nvdsinfer_context_impl.cpp:2092> [UID = 1]: deserialized trt engine from :/home/shamsee/DeepStream-Yolo/model_b1_gpu0_fp32.engine Implicit layer support has been deprecated INFO: [Implicit Engine Info]: layers num: 0
0:00:00.401518311 6238 0xaaaad1ab46c0 INFO nvinfer gstnvinfer.cpp:684:gst_nvinfer_logger:<primary_gie> NvDsInferContext[UID 1]: Info from NvDsInferContextImpl::generateBackendContext() <nvdsinfer_context_impl.cpp:2195> [UID = 1]: Use deserialized engine model: /home/shamsee/DeepStream-Yolo/model_b1_gpu0_fp32.engine 0:00:00.412604525 6238 0xaaaad1ab46c0 INFO nvinfer gstnvinfer_impl.cpp:343:notifyLoadModelStatus:<primary_gie> [UID 1]: Load new model:/home/shamsee/DeepStream-Yolo/config_infer_primary_yolo26_1usbcam_flir.txt sucessfully 0:00:00.414435142 6238 0xaaaad1cb8920 WARN basesrc gstbasesrc.c:3127:gst_base_src_loop:<src_elem> error: Internal data stream error. 0:00:00.414475340 6238 0xaaaad1cb8920 WARN basesrc gstbasesrc.c:3127:gst_base_src_loop:<src_elem> error: streaming stopped, reason not-negotiated (-4) 0:00:00.414521843 6238 0xaaaad1ab46c0 WARN v4l2src gstv4l2src.c:794:gst_v4l2src_query:<src_elem> Can't give latency since framerate isn't fixated ! nvstreammux: Successfully handled EOS for source_id=0
Runtime commands: h: Print this help q: Quit
p: Pause
r: Resume
NOTE: To expand a source in the 2D tiled display and view object details, left-click on the source. To go back to the tiled display, right-click anywhere on the window.
** INFO: <bus_callback:291>: Pipeline ready
ERROR from src_elem: Internal data stream error. Debug info: ../libs/gst/base/gstbasesrc.c(3127): gst_base_src_loop (): /GstPipeline:pipeline/GstBin:multi_src_bin/GstBin:src_sub_bin0/GstV4l2Src:src_elem: streaming stopped, reason not-negotiated (-4) ** INFO: <bus_callback:256>: incorrect camera parameters provided, please provide supported resolution and frame rate
** INFO: <bus_callback:277>: Pipeline running
** INFO: <bus_callback:334>: Received EOS. Exiting ...
Quitting 0:00:01.483704521 6238 0xaaaad1ab46c0 ERROR GST_BUS gstbus.c:1075:gst_bus_remove_watch: no bus watch was present App run failed
- Glenn JocherUltralytics
That
not-negotiated (-4)is coming fromv4l2srcnot being able to match the caps DeepStream requested (your snippet also has a typo: it must be[source0], and you needtype,camera-width, andcamera-heightset explicitly); please try a minimal V4L2 source config like this (and set[streammux] live-source=1for a USB cam), per the DeepStreamdeepstream-appsource-group keys in the NVIDIA reference app docs and our YOLO26 DeepStream Jetson guide:[source0] enable=1 type=1 camera-v4l2-dev-node=0 camera-width=80 camera-height=60 camera-fps-n=9 camera-fps-d=1 video-format=NV12If it still fails, first confirm GStreamer can negotiate your camera at
80x60@9inUYVY(then we can mirror that into DeepStream), and paste your full[source0]+[streammux]blocks here in this discussion along with the complete text log (not a screenshot). Thanks Glenn. Its working Sir!!!!
Hello I finally got everything else working but stuck in terms of wanting to extract deepstream metadata(inference results-frame, trackerID, detection class, bounding box and etc) and to allow my crewai agents to access for further processing/instructions. I Don't know where to start or what to create(config files or edit files), properties needed or mapping it within the deepstream_app_config.txt/config_infer_primary_yolo26 besides the custom crewai tool(python) to retrieve the needed metadata. I don't want to use cloud storage but locally to jetson orin nano. Any suggestion, direction PLEASE would be GREATLY appreciated. Thanks again for your help and time. SA
- Glenn JocherUltralytics
DeepStream already attaches detections/tracks as
NvDsBatchMeta(frame +NvDsObjectMetawithclass_id, bbox, andobject_idoncenvtrackeris enabled), butdeepstream-appisn’t really meant to be “extended” from Python—if you want to feed results into CrewAI locally on the Orin, the usual path is to build a small custom DeepStream app using the NVIDIA DeepStream Python sample apps and add a pad-probe on thenvinfer/nvtrackersrc pad to serialize metadata (e.g., JSON) and hand it directly to your agents.# inside a pad-probe callback import pyds batch_meta = pyds.gst_buffer_get_nvds_batch_meta(hash(gst_buffer)) l_frame = batch_meta.frame_meta_list while l_frame: frame_meta = pyds.NvDsFrameMeta.cast(l_frame.data) l_obj = frame_meta.obj_meta_list while l_obj: obj = pyds.NvDsObjectMeta.cast(l_obj.data) tid = int(obj.object_id) # tracker ID (requires nvtracker) cid = int(obj.class_id) # class r = obj.rect_params # bbox (left, top, width, height) conf = float(obj.confidence) # -> push to your local queue / file / socket for CrewAI l_obj = l_obj.next l_frame = l_frame.nextIf you reply with your JetPack/DeepStream versions and whether you’re currently running the stock
deepstream-appconfig or a custom GStreamer pipeline, I can point you to the closest matching sample to start from. Thanks Glen. I am using Jetpack 6.2.1 and DeepStream 7.1. Deepstream-Yolo(deepstream_app_config.txt). How would the "deepstream_app_config.txt/config_infer_primary_yolo26" be mapped or linked to the deepstream python example you provided above?
- Glenn JocherUltralytics
deepstream_app_config.txtis parsed only bydeepstream-app; the Python samples don’t “map” it automatically, so in Python you recreate the pipeline in code and simply reuse the samenvinferconfig by pointingnvinferat your existingconfig_infer_primary_yolo26.txt(which can keep all your DeepStream-Yolo settings like custom parser lib paths) as shown in the DeepStream on Jetson guide and the upstream DeepStream-Yolo project.# after you create the elements in your Python pipeline pgie = Gst.ElementFactory.make("nvinfer", "primary-gie") pgie.set_property("config-file-path", "config_infer_primary_yolo26.txt") tracker = Gst.ElementFactory.make("nvtracker", "tracker") # set tracker properties from your tracker config the same way (or load them via configparser)
AfaqKarim(modifié)
Title: Guidance Needed: Where to Modify Code to Add Custom Violation Logic and Modbus Output in DeepStream-YOLO Pipeline
Hello DeepStream-YOLO Team,
First of all, thank you for the excellent DeepStream-YOLO integration repository. I was able to successfully deploy a YOLO26 model using DeepStream on a Jetson Orin Nano (JetPack 6.1), and inference is working correctly using
deepstream-appwithconfig_infer_primary_yolo26.txt.
My Use Case
I am building an industrial safety system. After YOLO detection, if there is violation i have to send 0 or 1 through modbus to the plc: .
So I need to integrate custom logic after detection results.
My Question
In this DeepStream-YOLO setup, in which file or location should I add my custom logic?
Specifically, I want to know:
-
Should I modify:
nvdsparsebbox_Yolo.cppinsidenvdsinfer_custom_impl_Yolo?- Or write a custom DeepStream app (like
deepstream-test1/deepstream-test3)? - Or add a probe function after
nvinferin the pipeline?
Because I understand that:
- Parsing
.sois only for decoding bounding boxes, - But my requirement is to process detections and send a Modbus signal continuously.
So I want guidance on the recommended DeepStream architecture for this.
My Current Setup
- Jetson Orin Nano – JetPack 6.1
- DeepStream-YOLO repo working
- YOLO26 model inference OK
- Using
deepstream-app -c deepstream_app_config.txt
Goal
After detection → evaluate violation → send Modbus 0/1 signal in real-time.
I would really appreciate guidance on:
- Best file/place to implement this logic,
- Any example for accessing detection metadata in DeepStream-YOLO.
Thank you again for your great work 🙏
- Glenn JocherUltralytics
You generally shouldn’t put violation/Modbus logic inside
nvdsparsebbox_Yolo.cpp(keep the custom parser.sofocused on decoding tensors → boxes); the recommended DeepStream architecture is to write a small custom DeepStream app (C/C++ or Python) and attach a pad-probe afternvinfer(or afternvtrackerif you want stable IDs) to readNvDsObjectMetaand then publish your Modbus 0/1 in a non-blocking way (e.g., queue + worker thread), while still following the config/export flow in our Jetson DeepStream + TensorRT guide and the marcoslucianops/DeepStream-Yolo repository.// Probe callback (attach to a pad after nvinfer/nvtracker, e.g. OSD sink pad) static GstPadProbeReturn probe_cb(GstPad* pad, GstPadProbeInfo* info, gpointer user_data) { GstBuffer* buf = (GstBuffer*)info->data; NvDsBatchMeta* batch = gst_buffer_get_nvds_batch_meta(buf); for (NvDsMetaList* lf = batch->frame_meta_list; lf; lf = lf->next) { NvDsFrameMeta* f = (NvDsFrameMeta*)lf->data; for (NvDsMetaList* lo = f->obj_meta_list; lo; lo = lo->next) { NvDsObjectMeta* o = (NvDsObjectMeta*)lo->data; // o->class_id, o->confidence, o->rect_params; compute “violation” then enqueue Modbus 0/1 } } return GST_PAD_PROBE_OK; }If you share whether you need “violation” per-frame or latched with hysteresis (and whether you’re using
nvtracker), reply here and we can suggest the cleanest probe point and metadata fields to use. Hi @glenn-jocher — thanks, that makes sense.
My requirements:
Input: RTSP (H.264) on Jetson Orin Nano (JP 6.1 / DS 7.1)
Throughput: ~25 FPS
Tracking: Not using nvtracker (I only need a global safety signal, not per-person IDs)
Decision: Per-frame violation, but I’m open to latching / hysteresis if that’s the recommended way to avoid flicker.
Output: Modbus TCP to PLC; I need to continuously send 0/1 (currently planning to write a coil bit), e.g. modbus_write_bit(coil_addr, value) at ~25Hz (or “send on change” if better).
Violation rule (current):
I define a polygon zone (danger/no-go area).
Violation = 1 if a detected person bbox is fully inside the polygon (all 4 corners inside).
Violation = 0 otherwise.
Questions to confirm best architecture:
Probe location: since I’m not using tracker, is the best place a pad-probe on nvinfer src pad (or OSD sink pad)?
Metadata fields: I’m reading from NvDsObjectMeta → class_id, confidence, rect_params (left/top/width/height). Is that the correct/standard way?
Best practice for Modbus: should I publish every frame (25Hz), or only on state change with a small debounce/hysteresis window (e.g., require N consecutive frames to assert violation)?
If you can point to the cleanest DeepStream sample to start from (e.g., deepstream-test3 or deepstream-app custom plugin approach) and the recommended probe pad in that pipeline, I’ll follow that pattern.
Thanks again 🙏
-
Hello, Deepstream Clarity question please.
I notice the Nvidia Deepstream_python_app sample application use python file and one or more configuration text files. While Ultralytics Deepstream_Yolo uses two configuration text files.
-
Could you please explain why Deepstream_Yolo is different?
-
This command for Yolo26 "python3 export_yolo26.py -w yolo26s.pt" does not seem to generate a working .onnx model file but works with previous Yolo models(Ex. Yolo11). What are my options to get this to work?
Thank you for your help and time.
- Glenn JocherUltralytics(modifié)
DeepStream-Yolo isn’t fundamentally “different” from
deepstream_python_apps—it just splits configuration the waydeepstream-appexpects:deepstream_app_config.txtdescribes the full pipeline/sources/sinks, whileconfig_infer_primary_yolo26.txtis thenvinfer(GIE) config that points to the ONNX/engine and the custom YOLO parser library; the Python sample builds more of the pipeline in code so you’ll see fewer/different config files even though the same DeepStream components are in play (see the DeepStream on Jetson + Ultralytics YOLO26 guide).For the YOLO26 ONNX export, it almost always comes down to a JetPack/DeepStream compatibility mismatch with
--dynamic/--opset(DeepStream 6.0.1 and earlier needopset=12, while newer DeepStream uses the exports shown in the guide), so please paste the full terminal output from the export command (text, not a screenshot) and youryolo checksoutput so we can see your exact JetPack/DeepStream/Python/Ultralytics versions (also double-check you followed the Jetson setup in the Jetson quickstart). Hello. Thank you for the quick response. below is the terminal output.
Starting: yolo26s.pt Opening YOLO26 model YOLO26s summary (fused): 122 layers, 9,496,140 parameters, 0 gradients, 20.7 GFLOPs Creating labels.txt file Exporting the model to ONNX W0205 20:50:46.390000 684277 torch/onnx/_internal/exporter/_compat.py:125] Setting ONNX exporter to use operator set version 18 because the requested opset_version 17 is a lower version than we have implementations for. Automatic version conversion will be performed, which may not be successful at converting to the requested version. If version conversion is unsuccessful, the opset version of the exported model will be kept at 18. Please consider setting opset_version >=18 to leverage latest ONNX features W0205 20:50:48.526000 684277 torch/onnx/_internal/exporter/_schemas.py:455] Missing annotation for parameter 'input' from (input, boxes, output_size: 'Sequence[int]', spatial_scale: 'float' = 1.0, sampling_ratio: 'int' = -1, aligned: 'bool' = False). Treating as an Input. W0205 20:50:48.527000 684277 torch/onnx/_internal/exporter/_schemas.py:455] Missing annotation for parameter 'boxes' from (input, boxes, output_size: 'Sequence[int]', spatial_scale: 'float' = 1.0, sampling_ratio: 'int' = -1, aligned: 'bool' = False). Treating as an Input. W0205 20:50:48.528000 684277 torch/onnx/_internal/exporter/_schemas.py:455] Missing annotation for parameter 'input' from (input, boxes, output_size: 'Sequence[int]', spatial_scale: 'float' = 1.0). Treating as an Input. W0205 20:50:48.528000 684277 torch/onnx/_internal/exporter/_schemas.py:455] Missing annotation for parameter 'boxes' from (input, boxes, output_size: 'Sequence[int]', spatial_scale: 'float' = 1.0). Treating as an Input. The model version conversion is not supported by the onnxscript version converter and fallback is enabled. The model will be converted using the onnx C API (target version: 17). Failed to convert the model to the target version 17 using the ONNX C API. The model was not modified Traceback (most recent call last): File "/home/shamsee/Shamsee/lib/python3.10/site-packages/onnxscript/version_converter/init.py", line 127, in call converted_proto = _c_api_utils.call_onnx_api( File "/home/shamsee/Shamsee/lib/python3.10/site-packages/onnxscript/version_converter/_c_api_utils.py", line 65, in call_onnx_api result = func(proto) File "/home/shamsee/Shamsee/lib/python3.10/site-packages/onnxscript/version_converter/init.py", line 122, in _partial_convert_version return onnx.version_converter.convert_version( File "/home/shamsee/Shamsee/lib/python3.10/site-packages/onnx/version_converter.py", line 39, in convert_version converted_model_str = C.convert_version(model_str, target_version) RuntimeError: /github/workspace/onnx/version_converter/BaseConverter.h:65: adapter_lookup: Assertion
falsefailed: No Adapter To Version $17 for Resize Done: yolo26s.onnx- Glenn JocherUltralytics(modifié)
That log shows PyTorch is actually exporting at opset 18 and then failing to down-convert to opset 17 (
No Adapter To Version 17 for Resize), so the fix is to export with an opset that matches what the exporter is using (>=18) instead of forcing 17:python3 export_yolo26.py -w yolo26s.pt --opset 18If you’re on an older DeepStream/TensorRT stack that truly requires lower opset (e.g. DeepStream 6.0.1), you’ll need the DeepStream 6.0.1 and earlier setting from the guide (
opset=12) and typically an older PyTorch ONNX exporter that can produce opset 12 cleanly; please paste youryolo checksoutput and the exact DeepStreamnvinferONNX parsing error so we can align this to your JetPack/DeepStream version (see the DeepStream on Jetson + Ultralytics YOLO26 guide and the Jetson quickstart). smh, User Error. :-) I forgot about the steps at https://docs.ultralytics.com/guides/nvidia-jetson/ . It works after following steps!!!
One last issue for Segmentation ONNX conversion. Hopefully this is another user error. python3 export_yolo26.py -w yolo26s-seg.pt
I got these error:
Starting: yolo26s-seg.pt Opening YOLO26 model YOLO26s-seg summary (fused): 139 layers, 10,396,300 parameters, 0 gradients, 34.2 GFLOPs Creating labels.txt file Exporting the model to ONNX Traceback (most recent call last): File "/home/shamsee/ultralytics/export_yolo26.py", line 157, in main(args) File "/home/shamsee/ultralytics/export_yolo26.py", line 116, in main torch.onnx.export( File "/home/shamsee/Sentinel_yolo26/Sentinel_proj/lib/python3.10/site-packages/torch/onnx/utils.py", line 549, in export _export( File "/home/shamsee/Sentinel_yolo26/Sentinel_proj/lib/python3.10/site-packages/torch/onnx/utils.py", line 1641, in _export graph, params_dict, torch_out = _model_to_graph( File "/home/shamsee/Sentinel_yolo26/Sentinel_proj/lib/python3.10/site-packages/torch/onnx/utils.py", line 1184, in _model_to_graph graph, params, torch_out, module = _create_jit_graph(model, args) File "/home/shamsee/Sentinel_yolo26/Sentinel_proj/lib/python3.10/site-packages/torch/onnx/utils.py", line 1060, in _create_jit_graph graph, torch_out = _trace_and_get_graph_from_model(model, args) File "/home/shamsee/Sentinel_yolo26/Sentinel_proj/lib/python3.10/site-packages/torch/onnx/utils.py", line 964, in _trace_and_get_graph_from_model trace_graph, torch_out, inputs_states = torch.jit._get_trace_graph( File "/home/shamsee/Sentinel_yolo26/Sentinel_proj/lib/python3.10/site-packages/torch/jit/_trace.py", line 1502, in _get_trace_graph outs = ONNXTracedModule( File "/home/shamsee/Sentinel_yolo26/Sentinel_proj/lib/python3.10/site-packages/torch/nn/modules/module.py", line 1714, in _wrapped_call_impl return self._call_impl(*args, **kwargs) File "/home/shamsee/Sentinel_yolo26/Sentinel_proj/lib/python3.10/site-packages/torch/nn/modules/module.py", line 1725, in _call_impl return forward_call(*args, **kwargs) File "/home/shamsee/Sentinel_yolo26/Sentinel_proj/lib/python3.10/site-packages/torch/jit/_trace.py", line 141, in forward graph, out = torch._C._create_graph_by_tracing( File "/home/shamsee/Sentinel_yolo26/Sentinel_proj/lib/python3.10/site-packages/torch/jit/_trace.py", line 132, in wrapper outs.append(self.inner(*trace_inputs)) File "/home/shamsee/Sentinel_yolo26/Sentinel_proj/lib/python3.10/site-packages/torch/nn/modules/module.py", line 1714, in _wrapped_call_impl return self._call_impl(*args, **kwargs) File "/home/shamsee/Sentinel_yolo26/Sentinel_proj/lib/python3.10/site-packages/torch/nn/modules/module.py", line 1725, in _call_impl return forward_call(*args, **kwargs) File "/home/shamsee/Sentinel_yolo26/Sentinel_proj/lib/python3.10/site-packages/torch/nn/modules/module.py", line 1704, in _slow_forward result = self.forward(*input, **kwargs) File "/home/shamsee/Sentinel_yolo26/Sentinel_proj/lib/python3.10/site-packages/torch/nn/modules/container.py", line 249, in forward input = module(input) File "/home/shamsee/Sentinel_yolo26/Sentinel_proj/lib/python3.10/site-packages/torch/nn/modules/module.py", line 1714, in _wrapped_call_impl return self._call_impl(*args, **kwargs) File "/home/shamsee/Sentinel_yolo26/Sentinel_proj/lib/python3.10/site-packages/torch/nn/modules/module.py", line 1725, in _call_impl return forward_call(*args, **kwargs) File "/home/shamsee/Sentinel_yolo26/Sentinel_proj/lib/python3.10/site-packages/torch/nn/modules/module.py", line 1704, in _slow_forward result = self.forward(*input, **kwargs) File "/home/shamsee/ultralytics/export_yolo26.py", line 34, in forward x = x.transpose(1, 2) AttributeError: 'tuple' object has no attribute 'transpose'
Thanks for your help and time.
- Glenn JocherUltralytics
That traceback is expected with
yolo26*-seg: theexport_yolo26.pyyou’re using (from DeepStream-Yolo) is built around detection-only outputs, while segmentation models return multiple outputs (so you end up with a tuple and hit thetransposefailure); for DeepStream segmentation please use the dedicated DeepStream-Yolo-Seg project (its supported-model list currently covers YOLO11/YOLOv8 seg), and if you specifically need YOLO26-Seg in DeepStream please open a report in DeepStream-Yolo-Seg Issues with your JetPack/DeepStream versions plusyolo checksso it’s trackable.
-
lovechang1986
I'm working on integrating SAHI with YOLOv11 and deploying it on a Jetson device using DeepStream. The original image size is 14401080, and I plan to split it into 640640 sub-images with overlaps between different sub-images. Are there any good methods for this?
Additionally, I still hope to use DeepSort for inference and tracking after obtaining the final image.
- Glenn JocherUltralytics
SAHI-style slicing isn’t something DeepStream handles automatically, so you’ll either need to slice frames before they enter the DeepStream pipeline (then offset + merge all tile detections back into full-frame coordinates before tracking), or implement ROI/tiling as a DeepStream preprocess step (e.g., via
nvdspreprocessor a small custom plugin) so the primary GIE sees a batched set of crops; on Jetson it’s often simpler/faster to avoid slicing and instead run a single-pass TensorRT engine at a largerimgszif latency allows (and YOLO26 is the recommended starting point for new deployments). If you plan to track inside DeepStream, put the tracker after you’ve merged detections to full-frame coordinates; DeepStream’s built-innvtrackerworks out of the box, while DeepSORT specifically typically requires custom integration rather than a drop-in switch. If you paste your JetPack/DeepStream versions and your currentdeepstream_app_config.txtinto this discussion, we can suggest the cleanest path based on the exact pipeline; the baseline export + DeepStream wiring is in the Jetson DeepStream guide and Jetson quickstart.
metalpole-coder
Do you know how to get the detections to work within a ROI only in deepstream?