Object Detection Datasets Overview#
Training a robust and accurate object detection model requires a comprehensive dataset. This guide introduces various formats of datasets that are compatible with the Ultralytics YOLO model and provides insights into their structure, usage, and how to convert between different formats.
Supported Dataset Formats#
Ultralytics YOLO format#
The Ultralytics YOLO format is a dataset configuration format that allows you to define the dataset root directory, the relative paths to training/validation/testing image directories or *.txt files containing image paths, and a dictionary of class names. Here is an example:
# Ultralytics 🚀 AGPL-3.0 License - https://ultralytics.com/license

# COCO8 dataset (first 8 images from COCO train2017) by Ultralytics
# Documentation: https://docs.ultralytics.com/datasets/detect/coco8
# Example usage: yolo train data=coco8.yaml
# parent
# ├── ultralytics
# └── datasets
#     └── coco8 ← downloads here (1 MB)

# Train/val/test sets as 1) dir: path/to/imgs, 2) file: path/to/imgs.txt, or 3) list: [path/to/imgs1, path/to/imgs2, ..]
path: coco8 # dataset root dir
train: images/train # train images (relative to 'path') 4 images
val: images/val # val images (relative to 'path') 4 images
test: # test images (optional)

# Classes
names:
  0: person
  1: bicycle
  2: car
  3: motorcycle
  4: airplane
  5: bus
  6: train
  7: truck
  8: boat
  9: traffic light
  10: fire hydrant
  11: stop sign
  12: parking meter
  13: bench
  14: bird
  15: cat
  16: dog
  17: horse
  18: sheep
  19: cow
  20: elephant
  21: bear
  22: zebra
  23: giraffe
  24: backpack
  25: umbrella
  26: handbag
  27: tie
  28: suitcase
  29: frisbee
  30: skis
  31: snowboard
  32: sports ball
  33: kite
  34: baseball bat
  35: baseball glove
  36: skateboard
  37: surfboard
  38: tennis racket
  39: bottle
  40: wine glass
  41: cup
  42: fork
  43: knife
  44: spoon
  45: bowl
  46: banana
  47: apple
  48: sandwich
  49: orange
  50: broccoli
  51: carrot
  52: hot dog
  53: pizza
  54: donut
  55: cake
  56: chair
  57: couch
  58: potted plant
  59: bed
  60: dining table
  61: toilet
  62: tv
  63: laptop
  64: mouse
  65: remote
  66: keyboard
  67: cell phone
  68: microwave
  69: oven
  70: toaster
  71: sink
  72: refrigerator
  73: book
  74: clock
  75: vase
  76: scissors
  77: teddy bear
  78: hair drier
  79: toothbrush

# Download script/URL (optional)
download: https://github.com/ultralytics/assets/releases/download/v0.0.0/coco8.zip
Each of train, val, and test accepts a directory, a list of directories, or a UTF-8 *.txt file listing one image path per line (paths starting with ./ resolve relative to the *.txt file). A *.txt file is useful to train on a subset of a directory, skip unlabeled images, or combine images from multiple sources into one split.
path: datasets/coco8 # dataset root
train: train.txt # a directory, a list e.g. [images/a, images/b], or a *.txt file
val: val.txt
names:
  0: person
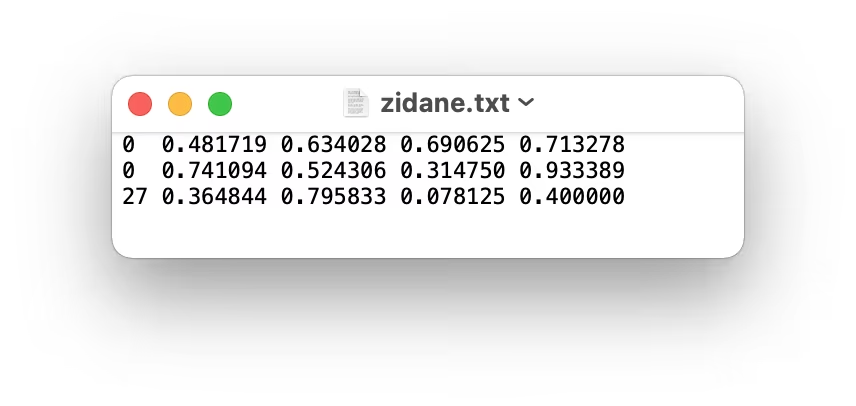
Labels for this format should be exported to YOLO format with one *.txt file per image. If there are no objects in an image, no *.txt file is required. The *.txt file should be formatted with one row per object in class x_center y_center width height format. Bounding box coordinates must be in normalized xywh format (from 0 to 1). If your boxes are in pixels, you should divide x_center and width by image width, and y_center and height by image height. Class numbers should be zero-indexed (start with 0).
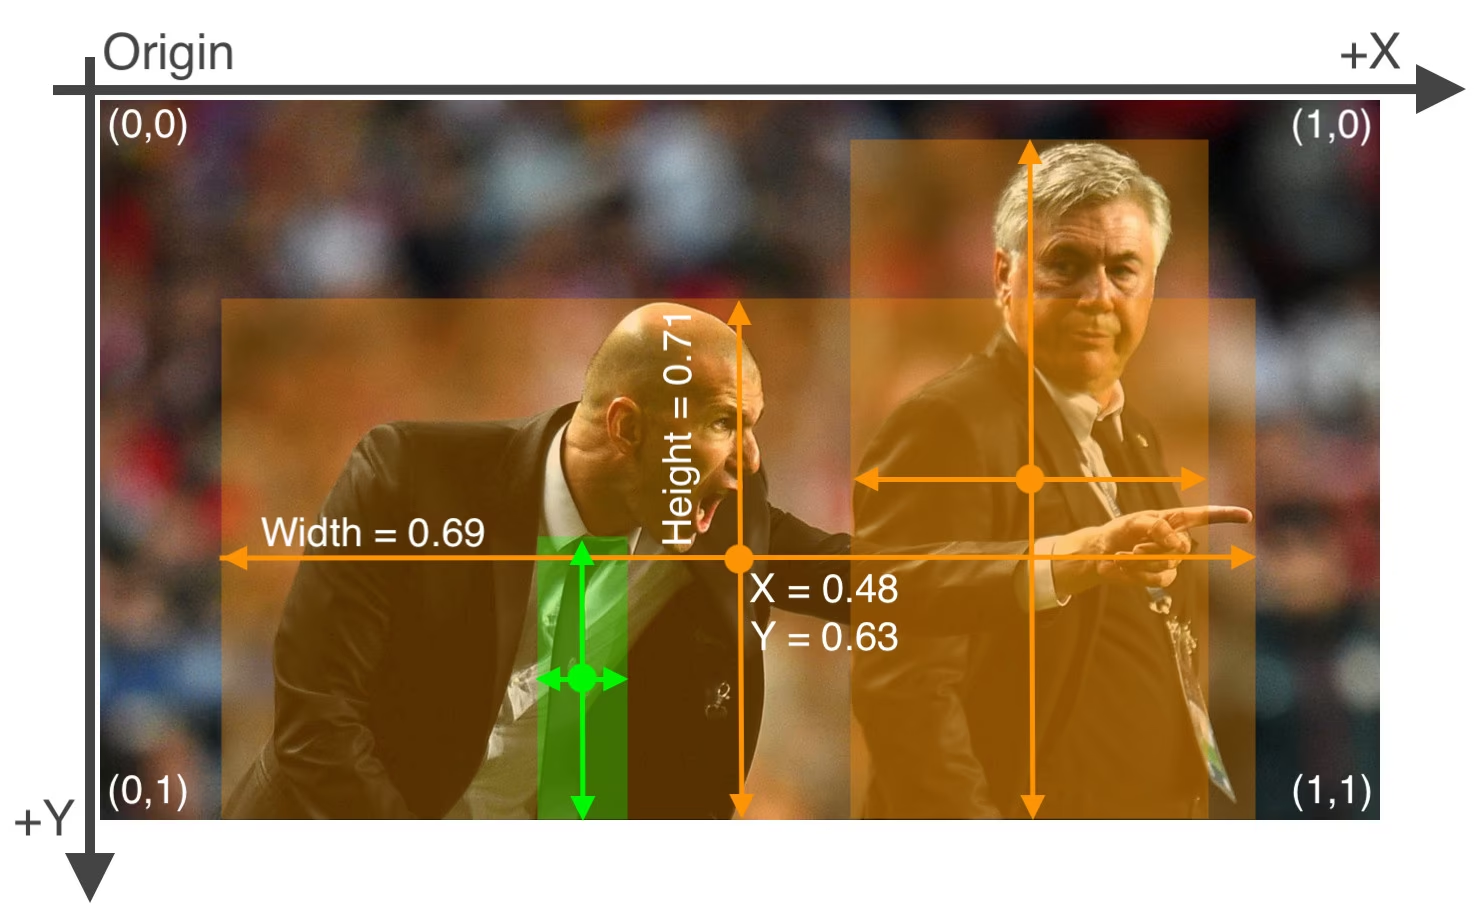
The label file corresponding to the above image contains 2 persons (class 0) and a tie (class 27):
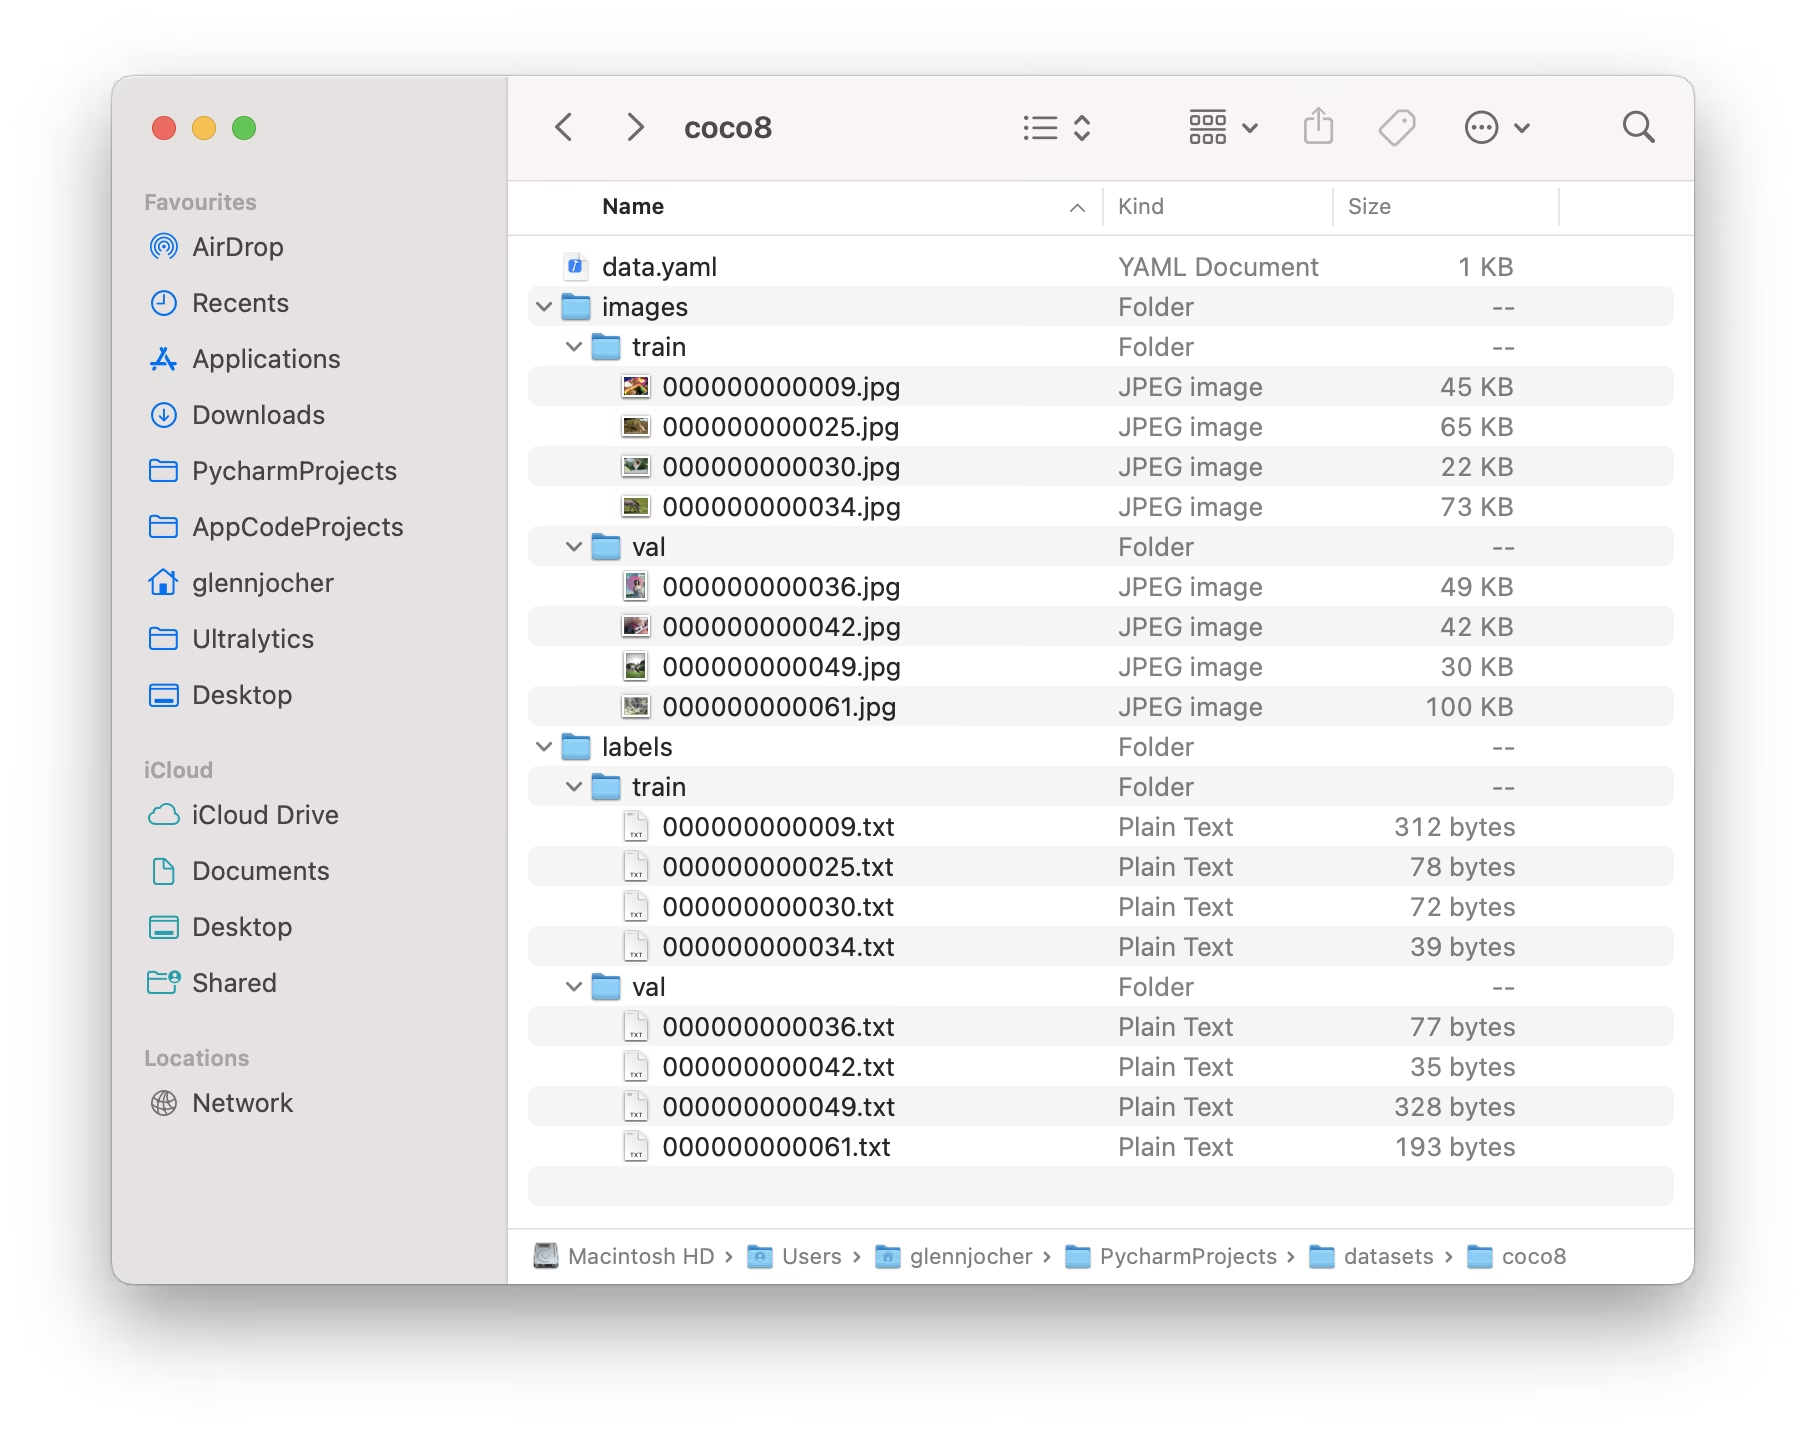
When using the Ultralytics YOLO format, organize your training and validation images and labels as shown in the COCO8 dataset example below.
Usage Example#
Here's how you can use YOLO format datasets to train your model:
from ultralytics import YOLO

# Load a model
model = YOLO("yolo26n.pt")  # load a pretrained model (recommended for training)

# Train the model
results = model.train(data="coco8.yaml", epochs=100, imgsz=640)
Ultralytics NDJSON format#
The NDJSON (Newline Delimited JSON) format provides an alternative way to define datasets for Ultralytics YOLO models. This format stores dataset metadata and annotations in a single file where each line contains a separate JSON object.
An NDJSON dataset file contains:
- Dataset record (first line): Contains dataset metadata including task type, class names, and general information
- Image records (subsequent lines): Contains individual image data including dimensions, annotations, and file paths
{
    "type": "dataset",
    "task": "detect",
    "name": "Example",
    "description": "COCO NDJSON example dataset",
    "url": "https://platform.ultralytics.com/user/datasets/example",
    "class_names": { "0": "person", "1": "bicycle", "2": "car" },
    "bytes": 426342,
    "version": 0,
    "created_at": "2024-01-01T00:00:00Z",
    "updated_at": "2025-01-01T00:00:00Z"
}
Custom image metadata#
Each image record may include a metadata JSON object for application-specific context such as capture conditions, equipment identifiers, or review status. Nested values are supported. When imported into Ultralytics Platform, the metadata is stored with that image and can be viewed or edited from its fullscreen information panel.
{
    "type": "image",
    "file": "airbus-wing.jpg",
    "url": "https://example.com/airbus-wing.jpg",
    "split": "train",
    "metadata": {
        "aircraft": { "family": "A350", "section": "wing" },
        "inspectionStatus": "reviewed"
    }
}
Platform limits top-level metadata keys to 128 characters, each image's serialized metadata object to 500,000 characters, and the combined effective metadata in one NDJSON import to 500,000 characters.
Usage Example#
To use an NDJSON dataset with YOLO26, simply specify the path to the .ndjson file:
from ultralytics import YOLO

# Load a model
model = YOLO("yolo26n.pt")

# Train using NDJSON dataset
results = model.train(data="path/to/dataset.ndjson", epochs=100, imgsz=640)
Advantages of NDJSON format#
- Single file: All dataset information contained in one file
- Streaming: Can process large datasets line-by-line without loading everything into memory
- Cloud integration: Supports remote image URLs for cloud-based training
- Extensible: Easy to add custom metadata fields
- Version control: Single file format works well with git and version control systems
Supported Datasets#
Here is a list of the supported datasets and a brief description for each. Most of these datasets are also hosted on Ultralytics Platform, where you can browse the images and annotations, view dataset statistics, and clone them for cloud training.
- African-wildlife: A dataset featuring images of African wildlife, including buffalo, elephant, rhino, and zebra.
- Argoverse: The Argoverse-HD 2D detection dataset of 54,446 urban autonomous-driving images across 8 road-object classes.
- Brain-tumor: A dataset for detecting brain tumors in MRI or CT scan images, labeled for tumor presence and location.
- COCO: Common Objects in Context (COCO) is a large-scale object detection, segmentation, and captioning dataset with 80 object categories.
- COCO8: A smaller subset of the first 8 images from COCO train2017, 4 for training and 4 for validation, suitable for quick tests.
- COCO8-Grayscale: A grayscale version of COCO8 created by converting RGB to grayscale, useful for single-channel model evaluation.
- COCO8-Multispectral: A 10-channel multispectral version of COCO8 created by interpolating RGB wavelengths, useful for spectral-aware model evaluation.
- COCO12-Formats: A test dataset with 12 images covering 12 supported image formats (AVIF, BMP, DNG, HEIC, JP2, JPEG, JPG, MPO, PNG, TIF, TIFF, WebP) for validating image loading pipelines.
- COCO16: A subset of the first 16 images from COCO train2017 (8 train + 8 val), suitable for quick tests.
- COCO32: A subset of the first 32 images from COCO train2017 (16 train + 16 val), suitable for quick tests.
- COCO64: A subset of the first 64 images from COCO train2017 (32 train + 32 val), suitable for quick tests.
- COCO128: A smaller subset of the first 128 images from COCO train2017, suitable for tests.
- Construction-PPE: A dataset featuring construction site workers with labeled safety gear such as helmets, vests, gloves, boots, and goggles, including missing-equipment annotations like no_helmet, no_goggle for real-world compliance monitoring.
- Global Wheat 2020: A dataset containing images of wheat heads for the Global Wheat Challenge 2020.
- HomeObjects-3K: A dataset of indoor household items including beds, chairs, TVs, and more—ideal for applications in smart home automation, robotics, augmented reality, and room layout analysis.
- KITTI: A dataset featuring real-world driving scenes with stereo, LiDAR, and GPS/IMU data, used here for 2D object detection tasks such as identifying cars, pedestrians, and cyclists in urban, rural, and highway environments.
- LVIS: A large-scale object detection and instance segmentation dataset with 1,203 object categories.
- Medical-pills: A dataset featuring images of medical pills, annotated for applications such as pharmaceutical quality assurance, pill sorting, and regulatory compliance.
- Objects365: A high-quality, large-scale dataset for object detection with 365 object categories and over 1.7M training images.
- OpenImagesV7: A comprehensive dataset by Google with 1.7M train images and 42k validation images.
- Roboflow 100: A diverse object detection benchmark with 100 datasets spanning seven imagery domains for comprehensive model evaluation.
- Signature: A dataset featuring images of various documents with annotated signatures, supporting document verification and fraud detection research.
- SKU-110K: A dataset featuring dense object detection in retail environments with over 11K images and 1.7 million bounding boxes.
- TT100K: The Tsinghua-Tencent 100K (TT100K) traffic sign dataset with 16,817 street-view images across 221 sign categories for detection and classification.
- Ultralytics Benchmark: A first-party benchmark suite of 37 curated detection datasets across medical, aerial, industrial, retail, and other domains, with a fixed protocol for measuring real-world model generalization.
- VisDrone: A dataset containing object detection and multi-object tracking data from drone-captured imagery with over 10K images and video sequences.
- VOC: The Pascal Visual Object Classes (VOC) dataset for object detection and segmentation with 20 object classes and over 11K images.
- xView: A dataset for object detection in overhead imagery with 60 object categories and over 1 million annotated objects.
Adding your own dataset#
If you have your own dataset and would like to use it for training detection models with Ultralytics YOLO format, ensure that it follows the format specified above under "Ultralytics YOLO format". Convert your annotations to the required format and specify the paths, number of classes, and class names in the YAML configuration file.
Port or Convert Label Formats#
COCO Dataset Format to YOLO Format#
You can convert labels from the popular COCO dataset format to the YOLO format using the following code snippet:
from ultralytics.data.converter import convert_coco

convert_coco(labels_dir="path/to/coco/annotations/")
This conversion tool can be used to convert the COCO dataset or any dataset in the COCO format to the Ultralytics YOLO format. The process transforms the JSON-based COCO annotations into the simpler text-based YOLO format, making it compatible with Ultralytics YOLO models. For the full workflow — including class ID mapping, directory layout, and segmentation or pose annotations — see Convert COCO Annotations to YOLO.
Remember to double-check if the dataset you want to use is compatible with your model and follows the necessary format conventions. Properly formatted datasets are crucial for training successful object detection models.
What's Next#
With your dataset formatted, start training your model. Not sure which pretrained model to start from? Compare options in the YOLO26 model family.
FAQ#
The Ultralytics YOLO format is a structured configuration for defining datasets in your training projects. It involves setting paths to your training, validation, and testing images and corresponding labels. For example:
# Ultralytics 🚀 AGPL-3.0 License - https://ultralytics.com/license

# COCO8 dataset (first 8 images from COCO train2017) by Ultralytics
# Documentation: https://docs.ultralytics.com/datasets/detect/coco8
# Example usage: yolo train data=coco8.yaml
# parent
# ├── ultralytics
# └── datasets
#     └── coco8 ← downloads here (1 MB)

# Train/val/test sets as 1) dir: path/to/imgs, 2) file: path/to/imgs.txt, or 3) list: [path/to/imgs1, path/to/imgs2, ..]
path: coco8 # dataset root dir
train: images/train # train images (relative to 'path') 4 images
val: images/val # val images (relative to 'path') 4 images
test: # test images (optional)

# Classes
names:
  0: person
  1: bicycle
  2: car
  3: motorcycle
  4: airplane
  5: bus
  6: train
  7: truck
  8: boat
  9: traffic light
  10: fire hydrant
  11: stop sign
  12: parking meter
  13: bench
  14: bird
  15: cat
  16: dog
  17: horse
  18: sheep
  19: cow
  20: elephant
  21: bear
  22: zebra
  23: giraffe
  24: backpack
  25: umbrella
  26: handbag
  27: tie
  28: suitcase
  29: frisbee
  30: skis
  31: snowboard
  32: sports ball
  33: kite
  34: baseball bat
  35: baseball glove
  36: skateboard
  37: surfboard
  38: tennis racket
  39: bottle
  40: wine glass
  41: cup
  42: fork
  43: knife
  44: spoon
  45: bowl
  46: banana
  47: apple
  48: sandwich
  49: orange
  50: broccoli
  51: carrot
  52: hot dog
  53: pizza
  54: donut
  55: cake
  56: chair
  57: couch
  58: potted plant
  59: bed
  60: dining table
  61: toilet
  62: tv
  63: laptop
  64: mouse
  65: remote
  66: keyboard
  67: cell phone
  68: microwave
  69: oven
  70: toaster
  71: sink
  72: refrigerator
  73: book
  74: clock
  75: vase
  76: scissors
  77: teddy bear
  78: hair drier
  79: toothbrush

# Download script/URL (optional)
download: https://github.com/ultralytics/assets/releases/download/v0.0.0/coco8.zip
Labels are saved in
*.txtfiles with one file per image, formatted asclass x_center y_center width heightwith normalized coordinates. For a detailed guide, see the COCO8 dataset example.You can convert a COCO dataset to the YOLO format using the Ultralytics conversion tools. Here's a quick method:
from ultralytics.data.converter import convert_coco

convert_coco(labels_dir="path/to/coco/annotations/")
This code converts your COCO annotations to YOLO format so you can train Ultralytics YOLO models on them.
Ultralytics YOLO supports a wide range of datasets, including:
Each dataset page provides detailed information on the structure and usage tailored for efficient YOLO26 training. Explore the full list in the Supported Datasets section.
To start training a YOLO26 model, ensure your dataset is formatted correctly and the paths are defined in a YAML file. Use the following script to begin training:
Examplefrom ultralytics import YOLO model = YOLO("yolo26n.pt") # Load a pretrained model results = model.train(data="path/to/your_dataset.yaml", epochs=100, imgsz=640)Ultralytics provides many examples and practical guides for using YOLO in diverse applications. Visit the Ultralytics Blog for case studies, detailed tutorials, and community stories covering object detection, segmentation, and more. For specific examples, check the Predict mode page in the documentation.
Comments54
Ask a question, share your results, or help someone else.
zcoolster11
Python Head Bop
 Paula DerrengerUltralytics
@zcoolster11, could you clarify what you mean by “Python Head Bop” and what you’d like to do with Ultralytics YOLO? Feel free to drop your dataset or Python questions here in the discussion so the Ultralytics team can help.
 Murat Raimbekov
hey @orz-serein, short answer: no, you don't need empty label files for background images - just leave the
.txtout.i verified this empirically on the current main branch. setup: 5 images, 2 with real labels, 1 with an empty
.txtfile, 2 without any.txtfile at all. building aYOLODatasetover them gives:Scanning /tmp/bgtest_full/labels... 3 images, 3 backgrounds, 0 corrupt: 100% 5/5all 5 images are kept. the 3 without labels (the empty-
.txtone and the two with no.txtat all) all end up with the same(0, 5)labels array - they are treated identically as background images.so both options work:
- no
.txtfile: counted as "missing" (nm=1), no labels -> background - empty
.txtfile: counted as "empty" (ne=1), no labels -> background
both end up in the same
backgrounds = nm + nebucket inultralytics/data/dataset.py.this is also stated in the detection dataset docs:
If there are no objects in an image, no
*.txtfile is required.how many background images: the yolov5 training tips recommend 0-10% of the dataset as background images to reduce false positives (coco has about 1% background).
hope this helps!
- no
 serein
Hello, I would like to ask a question. During the stage of preparing the training dataset, if some images do not have the target to be detected, do I need to add corresponding empty label files in the label folder?
Fatima-khanjar
Hello, I hope this message finds you well.
I have a question regarding fine-tuning a pre-trained YOLO model (e.g., trained on the COCO dataset) on my custom dataset. My dataset includes both new classes (not present in COCO) and the same existing classes (e.g., toothbrush, car), but with different layouts. Specifically, I would like to add my new classes starting from index 80, while still leveraging the pre-trained weights for the common classes, which are the same but with different layouts.
Is it possible to use the pre-trained weights for the common classes and only train the model on the new classes, while ensuring that the pre-trained knowledge for the common classes is preserved? If so, could you please guide me on how to proceed?
Thank you for your time and assistance. best regards,
bimal-gajera
Hello, I'm working on multiple dataset formats for object detection. For the YOLO dataset format, is there any way I can rename the labels directory and put it in yaml file? Something like this:
path: path_to_root_directory
train: train\images
val: val\images
test: test\images

labels_dir: yolo

nc: 1
names: ['object']
yolo directory has yolo annotations (*.txt files), and it's inside respective train, val and test directory.
 Glenn JocherUltralytics(edited)
@bimal-gajera currently, the
labels_dirkey is not supported in the YAML file. Ultralytics finds label files by replacing the last/images/directory in each image path with/labels/, so each split needs siblingimages/andlabels/directories (for exampletrain/imagesandtrain/labels). For more details, refer to the Object Detection Datasets Overview.1
nitya-pandey-astro
Hello Team, I am using YOLO for detecting trails of slow-moving astronomical objects in my images. While the model detects the trails, the bounding boxes predicted around the objects are not tight enough. The boxes tend to be too loose or not well-shaped to fit the elongated, irregular trails, resulting in inaccurate object localization. I suspect, YOLO's standard rectangular bounding box not being well-suited for the elongated, curving shapes of the trails. Could you provide guidance on how to improve bounding box accuracy for this specific use case?
- Glenn JocherUltralytics(edited)
@astronitya thank you for your question! For detecting elongated or irregular trails, consider using Oriented Bounding Boxes (OBB), which may better fit your objects' shapes compared to standard rectangular boxes. You can format your dataset in the YOLO OBB format and train a YOLO26 OBB model. Please refer to the Oriented Bounding Box (OBB) Datasets Overview for details on dataset formatting and training. Let me know if you need further clarification!
@glenn-jocher Thankyou very much for the prompt response. I am going to work on your suggestions.
Yuxuan1998
Hi team, I am a little bit confused with the dataset folder structure. For most dataset I used, it strunctured in the way that each of
train/andval/folders containsimages/andlabels/folders. However, the COCO8 dataset example shows the opposite way, each ofimages/andlabels/folder containstest/andval/folders. Does the folder structure matter here? Thanks in advance- Glenn JocherUltralytics(edited)
@Yuxuan1998 both layouts work, as long as each image has a sibling
labelsdirectory: Ultralytics finds the label for an image by replacing the last/images/in its path with/labels/(sotrain/images/img.jpgusestrain/labels/img.txt, andimages/train/img.jpguseslabels/train/img.txt). Set the paths in your dataset's YAML file to the image directories. For details, refer to the Object Detection Datasets Overview. Let us know if you need further clarification!1
milanaveed
Hello, can you please fix the broken images on this page? Can't see the label file example.
wgdcxy
Hello, my label and image files are stored according to the requirements, but they are still not recognized, and the following is an error message Thank you in advance
WARNING ⚠️ imgsz=[2448] must be multiple of max stride 32, updating to [2464] train: Scanning D:\Textile_testing\ultralytics-seg\cs\labels\ttb... 0 images, 30 backgrounds, 0 corrupt: 100%|██████████| 30/30 [00:00<00:00, 1138.41it/s] train: WARNING ⚠️ No labels found in D:\Textile_testing\ultralytics-seg\cs\labels\ttb.cache. See https://docs.ultralytics.com/datasets/detect for dataset formatting guidance. train: WARNING ⚠️ Cache directory D:\Textile_testing\ultralytics-seg\cs\labels is not writeable, cache not saved. WARNING ⚠️ No labels found in D:\Textile_testing\ultralytics-seg\cs\labels\ttb.cache, training may not work correctly. See https://docs.ultralytics.com/datasets/detect for dataset formatting guidance. val: Scanning D:\Textile_testing\ultralytics-seg\cs\labels\ttj... 0 images, 30 backgrounds, 0 corrupt: 100%|██████████| 30/30 [00:00<00:00, 1617.94it/s] val: WARNING ⚠️ No labels found in D:\Textile_testing\ultralytics-seg\cs\labels\ttj.cache. See https://docs.ultralytics.com/datasets/detect for dataset formatting guidance. val: WARNING ⚠️ Cache directory D:\Textile_testing\ultralytics-seg\cs\labels is not writeable, cache not saved. WARNING ⚠️ No labels found in D:\Textile_testing\ultralytics-seg\cs\labels\ttj.cache, training may not work correctly. See https://docs.ultralytics.com/datasets/detect for dataset formatting guidance. Plotting labels to runs\segment\train3\labels.jpg...
- Glenn JocherUltralytics
It seems like your dataset labels are not being recognized. Please ensure your label files are in the correct YOLO format and that the directory is writable. For detailed guidance, visit the dataset formatting section at https://docs.ultralytics.com/datasets/detect/.
Hi, but my file path is very accurate, and I checked it N times, so is there any otherreason? Thank you
- Glenn JocherUltralytics
@wgdcxy please ensure your label files are in the correct YOLO format, with one
.txtfile per image containing normalized coordinates. Also, verify that the directory permissions allow writing. For more details, refer to the dataset formatting guide linked earlier. Hello, I'm a student whose English is not particularly good, so some places may not be clear, and secondly, this is not an error but a warning.I don't know why it's the background that reads, not the images. The warnings are as follows: val: Scanning D:\Textile_testing\ultralytics-seg\cs\labels\ttj... 0 images, 30 backgrounds, 0 corrupt: 100%| 30/30 [00:00<00:00, 495.76it/s] val: WARNING ⚠️ No labels found in D:\Textile_testing\ultralytics-seg\cs\labels\ttj.cache. See https://docs.ultralytics.com/datasets/detect for dataset formatting guidance. val: WARNING ⚠️ Cache directory D:\Textile_testing\ultralytics-seg\cs\labels is not writeable, cache not saved. WARNING ⚠️ No labels found in D:\Textile_testing\ultralytics-seg\cs\labels\ttj.cache, training may not work correctly. See https://docs.ultralytics.com/datasets/detect for dataset formatting guidance. Plotting labels to runs\segment\train4\labels.jpg...
Then this warning tells me that the cache file is missing, and I don't know why I can't generate a cache file for the file I created, so I'm here to ask you guys. Below is my own yaml file: # Train/val/test sets as 1) dir: path/to/imgs, 2) file: path/to/imgs.txt, or 3) list: [path/to/imgs1, path/to/imgs2, ..] path: ../cs # dataset root dir train: images/ttb # train images (relative to 'path') 128 images val: images/ttj # val images (relative to 'path') 128 images test: # test images (optional) # Classes names : 0 : wf
Below is my label file: 0 0.6799428104575164 0.5005859375 0.6844771241830065 0.500537109375 0.6845996732026144 0.497265625 0.6802696078431373 0.497119140625 0 0.6803104575163399 0.4935546875 0.6848039215686275 0.493505859375 0.6847630718954248 0.497119140625 0.6802696078431373 0.49697265625 0 0.6802696078431373 0.49013671875 0.6849673202614379 0.490185546875 0.6849264705882353 0.49345703125 0.6803513071895425 0.493359375 0 0.6805555555555556 0.48662109375 0.6850898692810458 0.486767578125 0.6850490196078431 0.490234375 0.6803513071895425 0.490234375 0 0.6808415032679739 0.483447265625 0.6852941176470588 0.48349609375 0.6852124183006536 0.486767578125 0.6806781045751634 0.486669921875 0 0.6806372549019607 0.47998046875 0.6854166666666666 0.47998046875 0.6853349673202613 0.48349609375 0.6808415032679738 0.48359375
Finally, this yolo can be run, but I don't know why the result is 0. Here's how it works: Transferred 381/417 items from pretrained weights 195/200 8.73G 0 0 nan 0 0 2464: 100%|██████████| 8/8 [01:37<00:00, 12.13s/it] Class Images Instances Box(P R mAP50 mAP50-95) Mask(P R mAP50 mAP50-95): 100%|[00:31<00:00, 7.91s/it] all 30 0 0 0 0 0 0 0 0 0 Finally, thank you for explaining it to me
By the way, the size of my picture is 2448x2048, so the imgsz entered is 2448, and your code changed the size of my picture to 2464, is it related to this. imgsz=[2448] must be multiple of max stride 32, updating to [2464]
I apologize, I found a small mistake of mine. I wrote the file name as "labels" instead of "lables" which I intended to write.Please forgive my carelessness.After all, who doesn't make mistakes. I'll come back to you next time I have a problem. Thank you for your help.
Transferred 417/417 items from pretrained weights Freezing layer 'model.22.dfl.conv.weight' AMP: running Automatic Mixed Precision (AMP) checks with YOLOv8n... AMP: checks passed ✅ WARNING ⚠️ imgsz=[2448] must be multiple of max stride 32, updating to [2464] train: Scanning D:\Textile_testing\ultralytics-seg\cs\labels\ttb.cache... 30 images, 0 backgrounds, 0 corrupt: 100%|██████████| 30/30 [00:00<?, ?it/s] Hello, here I am again, with a new problem, how to solve this problem about image size?Ask for answers, thank you
- Glenn JocherUltralytics
@wgdcxy to address the image size issue, ensure your
imgszis a multiple of 32, as required by the model's architecture. This adjustment helps maintain compatibility with the model's stride. If you have further questions, feel free to ask! WARNING ⚠️ NMS time limit 0.900s exceeded. Hello, my teacher who has never met, what should I do with this warning?
- Glenn JocherUltralytics(edited)
@wgdcxy the "NMS time limit exceeded" warning is not controlled by an
nmsargument. It appears when too many candidate boxes need to be processed within the time limit, which is common early in training when validation uses a low confidence threshold. It usually stops as the model trains, and you can reduce it by raisingconfor loweringmax_detduring validation. If you have further questions, feel free to ask! Hello, I'm here again. The issue this time is still the same warning. I adjusted the max_time_img to 0.1 in ops. py, but I don't feel it's right. So I came to ask for your help because it still shows this warning. I hope you can tell me where to make the adjustment. Thank you again. WARNING ⚠️ NMS time limit 0.900s exceeded
How can these values be improved? We can only continue training or increase the training dataset. Epoch GPU_mem box_loss seg_loss cls_loss dfl_loss Instances Size 11/500 11G nan 6.21 nan nan 132 2464: 100%|██████████| 8/8 [01:56<00:00, 14.59s/it] Class Images Instances Box(P R mAP50 mAP50-95) Mask(P R mAP50 mAP50-95): 100%|██████████| 4/4 [00:54<00:00, 13.56s/it] all 30 664 0 0 0 0 0 0 0 0
- Glenn JocherUltralytics
To improve your model's performance, consider increasing the dataset size, enhancing data quality, or adjusting hyperparameters. If issues persist, reviewing the dataset for label accuracy and distribution might help.
WARNING ⚠️ imgsz=[2448] must be multiple of max stride 32, updating to [2464] train: Scanning D:\Textile_testing\ultralytics-seg\cs\labels\ttb... 0 images, 30 backgrounds, 0 corrupt: 100%|██████████| 30/30 [00:00<00:00, 1138.41it/s] train: WARNING ⚠️ No labels found in D:\Textile_testing\ultralytics-seg\cs\labels\ttb.cache. See https://docs.ultralytics.com/datasets/detect for dataset formatting guidance. train: WARNING ⚠️ Cache directory D:\Textile_testing\ultralytics-seg\cs\labels is not writeable, cache not saved. WARNING ⚠️ No labels found in D:\Textile_testing\ultralytics-seg\cs\labels\ttb.cache, training may not work correctly. See https://docs.ultralytics.com/datasets/detect for dataset formatting guidance. val: Scanning D:\Textile_testing\ultralytics-seg\cs\labels\ttj... 0 images, 30 backgrounds, 0 corrupt: 100%|██████████| 30/30 [00:00<00:00, 1617.94it/s] val: WARNING ⚠️ No labels found in D:\Textile_testing\ultralytics-seg\cs\labels\ttj.cache. See https://docs.ultralytics.com/datasets/detect for dataset formatting guidance. val: WARNING ⚠️ Cache directory D:\Textile_testing\ultralytics-seg\cs\labels is not writeable, cache not saved. WARNING ⚠️ No labels found in D:\Textile_testing\ultralytics-seg\cs\labels\ttj.cache, training may not work correctly. See https://docs.ultralytics.com/datasets/detect for dataset formatting guidance. Plotting labels to runs\segment\train3\labels.jpg...
这个问题该如何解决?
- Glenn JocherUltralytics
It looks like your dataset labels are missing or not formatted correctly. Please ensure your labels are in the YOLO format and check the directory permissions. For detailed guidance, visit the dataset formatting section at https://docs.ultralytics.com/datasets/detect/.