Brain Tumor Dataset
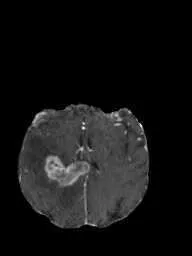
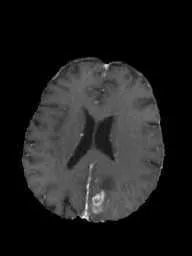
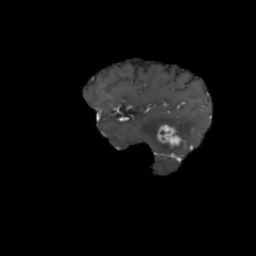

The Ultralytics Brain Tumor dataset is an object detection dataset of 1,115 brain MRI images (994 for training and 121 for validation) with 1,180 bounding boxes in a single class, tumor. Every image contains 1 to 3 tumor boxes. The validation split holds the images of 25 identified patients, and no identified patient appears in both splits. At 4.06 MB, it is a compact dataset for learning and prototyping computer vision models for healthcare applications, and it is not a clinically validated diagnostic resource.
Watch: Brain Tumor Detection using Ultralytics Platform with Ultralytics YOLO26 | Object Detection 🚀
Dataset Structure#
The Ultralytics Brain Tumor dataset contains 1,115 brain MRI images and 1,180 bounding boxes in two splits defined by the brain-tumor.yaml configuration:
| Split | Images | Bounding boxes | Patients |
|---|---|---|---|
| Train | 994 | 1,057 | 95 with an ID, plus 541 images without a patient ID |
| Validation | 121 | 123 | 25 |
| Total | 1,115 | 1,180 |
Every image contains 1 to 3 bounding boxes of the single class tumor, and image sizes range from 192x256 to 512x512 pixels. The configuration defines no separate test split.
The validation split is built by patient. Some file names start with a five-digit patient ID: for example, 00097_77.jpg belongs to patient 00097. The images carrying the IDs of 25 of these patients form the validation split and the images of the other 95 identified patients are in training, so no identified patient appears in both splits. The remaining 541 images have no patient ID in the file name and are all in the training split.
The dataset downloads automatically (4.06 MB) from Ultralytics GitHub assets the first time you train, so no manual download or preparation is required.
The dataset changed to a single tumor class in November 2026. If your local brain-tumor/images/train folder holds 893 images instead of 994, delete the brain-tumor folder in your datasets directory (see datasets_dir in yolo settings) and update the package with pip install -U ultralytics. The current version then downloads on the next training run.
Explore Brain Tumor on Ultralytics Platform to browse the images with their annotation overlays, view the class distribution and bounding-box heatmaps in the Charts tab, and clone it to train your own model in the cloud.
Applications#
Brain tumor detection models locate tumors in brain MRI images. With 1,115 images and a 4.06 MB download, the Ultralytics Brain Tumor dataset suits:
- Learning the workflow: running the full train, validate, and predict cycle on medical images with a small dataset.
- Prototyping: building and testing a tumor localization pipeline before moving to a larger clinical dataset.
- Evaluation on identified patients: measuring detection on the 25 validation patients. Because 541 training images carry no patient ID, overlap with these patients cannot be ruled out.
- Research and education: comparing detection models and studying medical image analysis and AI in radiology.
Models trained on this dataset are for research and education and are not validated for clinical diagnosis.
Dataset YAML#
The brain-tumor.yaml configuration defines the dataset path, the train and validation image folders, the single tumor class, and the download URL. Labels use the Ultralytics YOLO format.
# Ultralytics 🚀 AGPL-3.0 License - https://ultralytics.com/license

# Brain-tumor dataset by Ultralytics
# Documentation: https://docs.ultralytics.com/datasets/detect/brain-tumor
# Example usage: yolo train data=brain-tumor.yaml
# parent
# ├── ultralytics
# └── datasets
#     └── brain-tumor ← downloads here (4.06 MB)

# Train/val/test sets as 1) dir: path/to/imgs, 2) file: path/to/imgs.txt, or 3) list: [path/to/imgs1, path/to/imgs2, ..]
path: brain-tumor # dataset root dir
train: images/train # train images (relative to 'path') 994 images
val: images/val # val images (relative to 'path') 121 images

# Classes
names:
  0: tumor

# Download script/URL (optional)
download: https://github.com/ultralytics/assets/releases/download/v0.0.0/brain-tumor.zipUsage#
To train a YOLO26n model on the brain tumor dataset for 100 epochs with an image size of 640, use the code snippets below.
from ultralytics import YOLO

# Load a model
model = YOLO("yolo26n.pt")  # load a pretrained model (recommended for training)

# Train the model
results = model.train(data="brain-tumor.yaml", epochs=100, imgsz=640)from ultralytics import YOLO
# Load a model
model = YOLO("path/to/best.pt") # load a brain-tumor fine-tuned model
# Inference using the model
results = model.predict("https://ultralytics.com/assets/brain-tumor-sample.jpg")Sample Images and Annotations#
Below are sample images from the Ultralytics Brain Tumor dataset with their annotations:
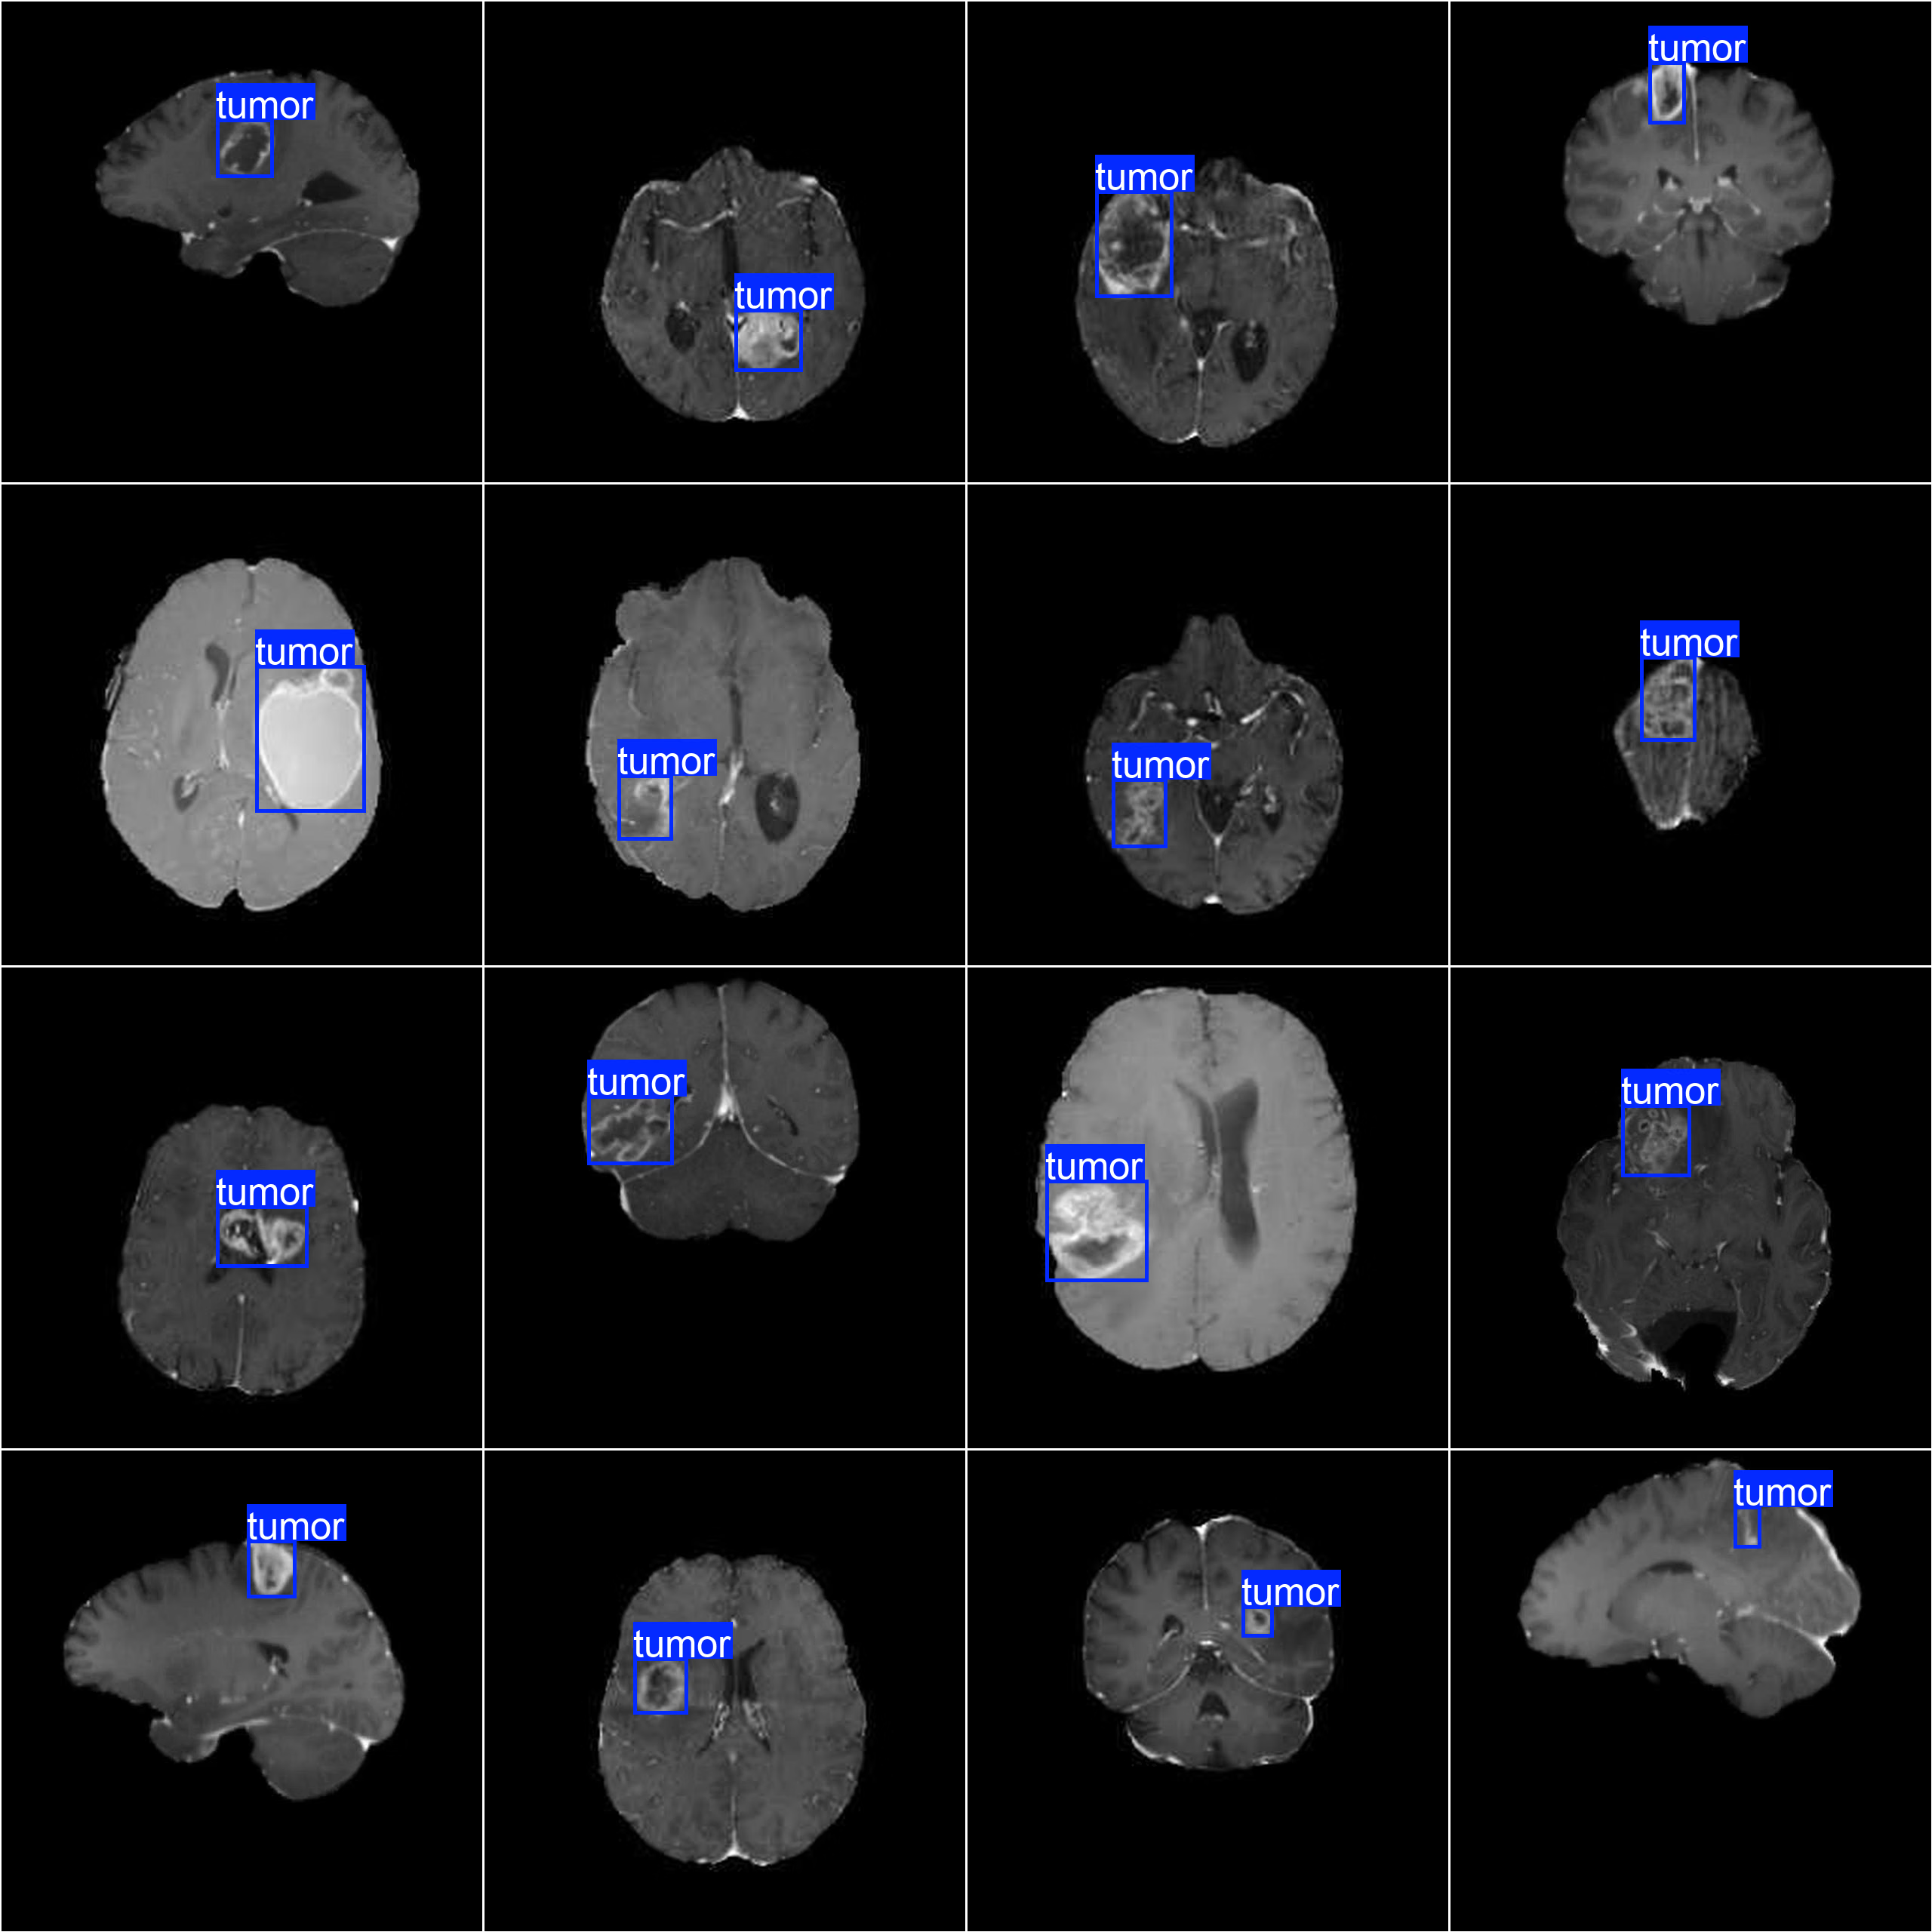
- Annotated Images: The grid shows 16 training images, each with a
tumorbounding box around the lesion. Tumors vary in size, shape, and location across the dataset, which helps a detection model generalize.
Citations and Acknowledgments#
The dataset is available under the AGPL-3.0 License.
If you use the brain tumor dataset in your research or development work, please cite it:
@dataset{Ultralytics_Brain_Tumor_Dataset_2023,
    author = {Ultralytics},
    title = {Brain Tumor Detection Dataset},
    year = {2023},
    publisher = {Ultralytics},
    url = {https://docs.ultralytics.com/datasets/detect/brain-tumor}
}FAQ#
The Ultralytics Brain Tumor dataset has 1,115 brain MRI images and 1 class,
tumor: 994 training images with 1,057 bounding boxes and 121 validation images with 123 bounding boxes. Every image has 1 to 3 boxes, and there is no separate test split. See Dataset Structure for the split details.The Ultralytics Brain Tumor dataset contains brain MRI images and no CT scans. Image sizes range from 192x256 to 512x512 pixels, and each image is labeled with 1 to 3
tumorbounding boxes in Ultralytics YOLO format.No, the Ultralytics Brain Tumor dataset contains no tumor-free images and no negative class. All 1,115 images have 1 to 3
tumorbounding boxes, so a model trained on it learns where a tumor is, not whether a scan is healthy. Models trained on this dataset are for research and education, not clinical diagnosis.The Ultralytics Brain Tumor dataset is split by patient: the 121 validation images carry the IDs of 25 patients, and no identified patient appears in both splits. Patients are identified by the five-digit prefix of the file name, such as
00097_77.jpg. The training set holds the other 95 identified patients plus 541 images whose file names carry no patient ID.The Ultralytics Brain Tumor dataset (4.06 MB) downloads automatically from Ultralytics GitHub assets the first time you train with
data="brain-tumor.yaml", so no manual download is required. If an earlier copy with 893 training images is already on disk, delete itsbrain-tumorfolder and update theultralyticspackage first so the current single-class version downloads. For another small medical imaging dataset, see the Medical Pills detection dataset.To train YOLO26 on the Ultralytics Brain Tumor dataset, pass
data="brain-tumor.yaml"to the train command, and the dataset downloads automatically. The examples below train YOLO26n for 100 epochs at an image size of 640:Train Examplefrom ultralytics import YOLO # Load a model model = YOLO("yolo26n.pt") # load a pretrained model (recommended for training) # Train the model results = model.train(data="brain-tumor.yaml", epochs=100, imgsz=640)For a detailed list of available arguments, refer to the Training page.
To run inference with a YOLO26 model fine-tuned on the Ultralytics Brain Tumor dataset, load your
best.ptweights and call predict on a brain MRI image. Each result contains thetumorbounding boxes with confidence scores:Inference Examplefrom ultralytics import YOLO # Load a model model = YOLO("path/to/best.pt") # load a brain-tumor fine-tuned model # Inference using the model results = model.predict("https://ultralytics.com/assets/brain-tumor-sample.jpg")The Ultralytics Brain Tumor dataset was created by Ultralytics and is released under the AGPL-3.0 License.


Comments11
Ask a question, share your results, or help someone else.
ZoltinZyc
how can i download this datasett??
1 Paula DerrengerUltralytics(edited)
Hey there! 😊 The easiest way is to train with
data=brain-tumor.yaml, which downloads the dataset automatically the first time. To download it manually, use:wget https://github.com/ultralytics/assets/releases/download/v0.0.0/brain-tumor.zip unzip brain-tumor.zip -d path/to/destinationReplace
path/to/destinationwith the directory where you'd like the dataset stored. Once you have the dataset, you're all set to start training or inferencing with YOLO models on brain tumor images!Should you need further guidance, feel free to ask. Happy coding! 🚀
G-qingqian
Thank you for your reply. I noticed that in the original dataset, the images in the train folder do have ID prefixes, but the images in the val folder are all prefixed with val1_, making it impossible to distinguish which patient the data belongs to. Therefore, I cannot redivide the dataset. Could you please provide data with complete identifiers? ---- Replied Message ---- FromGlenn @.>Date1/18/2026 @.>@.>, @.>SubjectRe: [ultralytics/ultralytics] zh/datasets/detect/brain-tumor/ (Discussion #9988) The packaged brain-tumor dataset split is provided at the image-folder level and doesn’t ship patient IDs/metadata, so we can’t guarantee a patient-disjoint (no same patient in both train/val) split; if you need patient-wise separation, you’ll need to rebuild the split from patient identifiers and point a custom YAML to *.txt image lists (supported by Ultralytics YOLO), e.g. see the provided config in the Brain Tumor dataset docs and the brain-tumor.yaml in the repo.
my-brain-tumor.yaml path: /data/brain-tumor train: splits/train.txt # one image path per line (ideally grouped by patient ID when you create it) val: splits/val.txt names: 0: negative 1: positive
— Reply to this email directly, view it on GitHub, or unsubscribe. You are receiving this because you commented.Message ID: @.***>
 Glenn JocherUltralytics
The packaged
brain-tumorzip only includes image-level labels with anonymized filenames (no patient IDs/metadata), so we can’t provide “complete identifiers” or guarantee a patient-disjoint re-split; for patient-wise splitting you’ll need to rebuild from a source that includes patient IDs (e.g., your DICOM/NIfTI originals) and then generatetrain.txt/val.txt, and if you just need stronger evaluation without IDs you can use our K-Fold Cross Validation guide—please keep follow-ups here in the GitHub discussion (we can’t provide support over email/DM).
Can your dataset ensure that the data are independently and identically distributed by patient? That is, there will be no data from the same patient in both the training set and the validation set.
- Glenn JocherUltralytics
The packaged
brain-tumordataset split is provided at the image-folder level and doesn’t ship patient IDs/metadata, so we can’t guarantee a patient-disjoint (no same patient in both train/val) split; if you need patient-wise separation, you’ll need to rebuild the split from patient identifiers and point a custom YAML to*.txtimage lists (supported by Ultralytics YOLO), e.g. see the provided config in the Brain Tumor dataset docs and the brain-tumor.yaml in the repo.# my-brain-tumor.yaml path: /data/brain-tumor train: splits/train.txt # one image path per line (ideally grouped by patient ID when you create it) val: splits/val.txt names: 0: negative 1: positive
pizzas17
How could I download this dataset on COCO format or how could I convert it? (Since I wish to have an EDA on it
xySun17
How can i train the yoloV8 using this dataset without loading the pre-trained weights?
- Paula DerrengerUltralytics(edited)
@xySun17 hello!
To train YOLO26 without loading the pre-trained weights, you can initialize the model from scratch by specifying the model architecture file (e.g.,
yolo26n.yaml) instead of the pre-trained weights file. Here’s how you can do it:Python
from ultralytics import YOLO

# Load a model architecture without pre-trained weights
model = YOLO("yolo26n.yaml")  # build a new model from YAML

# Train the model
results = model.train(data="brain-tumor.yaml", epochs=100, imgsz=640)
CLI
# Train from scratch using the model architecture file
yolo detect train data=brain-tumor.yaml model=yolo26n.yaml epochs=100 imgsz=640
This approach ensures that the model starts training with random weights rather than pre-trained ones. If you encounter any issues, please ensure you are using the latest version of the Ultralytics package and provide a minimum reproducible example if the problem persists. You can find more details on creating a reproducible example here.
Feel free to reach out if you have any further questions. Happy training! 🚀
1 Thank you!! However, there is another problem, that is, why it says the path of dataset is not found? I already downloaded the dataset files and changed the path in "brain-tumor.yaml" file.
The threw error was follows: "Dataset 'brain-tumor.yaml' images not found ⚠️, missing path '/valid/images' Note dataset download directory is '/home/ros/datasets'. You can update this in '/home/ros/.config/Ultralytics/settings.yaml'"
- Paula DerrengerUltralytics(edited)
Hello @xySun17,
Thank you for reaching out! It looks like the issue might be related to the dataset path configuration in your
brain-tumor.yamlfile. Here are a few steps to troubleshoot and resolve this:-
Verify Dataset Path: Ensure that the paths specified in your
brain-tumor.yamlfile correctly point to the locations of your dataset images. For example:path: /home/ros/datasets/brain-tumor train: images/train val: images/val -
Check Directory Structure: Confirm that the directory structure matches what is specified in the YAML file. The
images/trainandimages/valdirectories should exist within/home/ros/datasets/brain-tumor. -
Update Configuration: If the dataset is located in a different directory, update the
pathin the YAML file accordingly. For instance, if your dataset is in/home/ros/my-datasets/brain-tumor, update thepathto:path: /home/ros/my-datasets/brain-tumor -
Reproducible Example: If the issue persists, providing a minimum reproducible example can greatly help in diagnosing the problem. You can find guidance on creating a reproducible example here.
-
Latest Version: Ensure you are using the latest version of the Ultralytics package. You can update it using:
pip install --upgrade ultralytics
Here’s an example of how your
brain-tumor.yamlshould look:# Ultralytics 🚀 AGPL-3.0 License - https://ultralytics.com/license # Brain-tumor dataset by Ultralytics # Documentation: https://docs.ultralytics.com/datasets/detect/brain-tumor/ # Example usage: yolo train data=brain-tumor.yaml path: /home/ros/datasets/brain-tumor # dataset root dir train: images/train # train images (relative to 'path') val: images/val # val images (relative to 'path') # Classes names: 0: negative 1: positive # Download script/URL (optional) download: https://github.com/ultralytics/assets/releases/download/v0.0.0/brain-tumor.zipIf you follow these steps and still encounter issues, please share more details or any error messages you receive. This will help us assist you better.
Best regards and happy coding! 🚀
-