The PASCAL VOC (Visual Object Classes) dataset is a classic object detection benchmark with 20 everyday object classes. The Ultralytics VOC.yaml configuration combines the VOC2007 and VOC2012 trainval splits into a 16,551-image training set, validates on the 4,952 publicly annotated VOC2007 test images, and downloads everything automatically (2.8 GB) on first use.
Watch: How to Train Ultralytics YOLO on the Pascal VOC Dataset | Object Detection | Computer Vision 🚀
The PASCAL VOC challenges ran from 2005 to 2012 and shaped how object detection models are evaluated: the benchmark spans image classification, detection, and segmentation tasks, and popularized mean Average Precision (mAP) as the standard detection metric. The Ultralytics VOC.yaml configuration uses the detection annotations, converting the original XML bounding boxes to YOLO format during download.
The same VOC2007 test images — the config defines no separate held-out split
VOC2007 test annotations were released publicly after that year's challenge, which is what allows this split to serve as a labeled validation set. VOC2012 test annotations remain withheld — results on them can only be scored through the official PASCAL evaluation server — so they are not part of this configuration.
Difficult objects excluded
The automatic converter skips objects flagged difficult in the original VOC XML annotations, so per-class instance counts differ slightly from official VOC statistics.
Explore VOC on Ultralytics Platform to browse the images with their annotation overlays, view the class distribution and bounding-box heatmaps in the Charts tab, and clone it to train your own model in the cloud.
PASCAL VOC was the primary benchmark for object detection research in the years before the larger COCO dataset: detectors such as Faster R-CNN and SSD reported their original results on it, and Ultralytics YOLO models train on it out of the box. Today it remains popular for:
Benchmarking new detection architectures against a long history of published baselines
Fast experiments and coursework — at 16,551 training images it trains far quicker than COCO
Transfer learning studies on a compact, well-understood set of everyday classes
VOC downloads automatically the first time you train — three archives totaling 2.8 GB — and needs roughly 6 GB of free disk space during extraction and conversion.
To train a YOLO26n model on the VOC dataset for 100 epochs with an image size of 640, you can use the following code snippets.
Train Example
from ultralytics import YOLO

# Load a model
model = YOLO("yolo26n.pt")  # load a pretrained model (recommended for training)

# Train the model - dataset will auto-download on first run
results = model.train(data="VOC.yaml", epochs=100, imgsz=640)
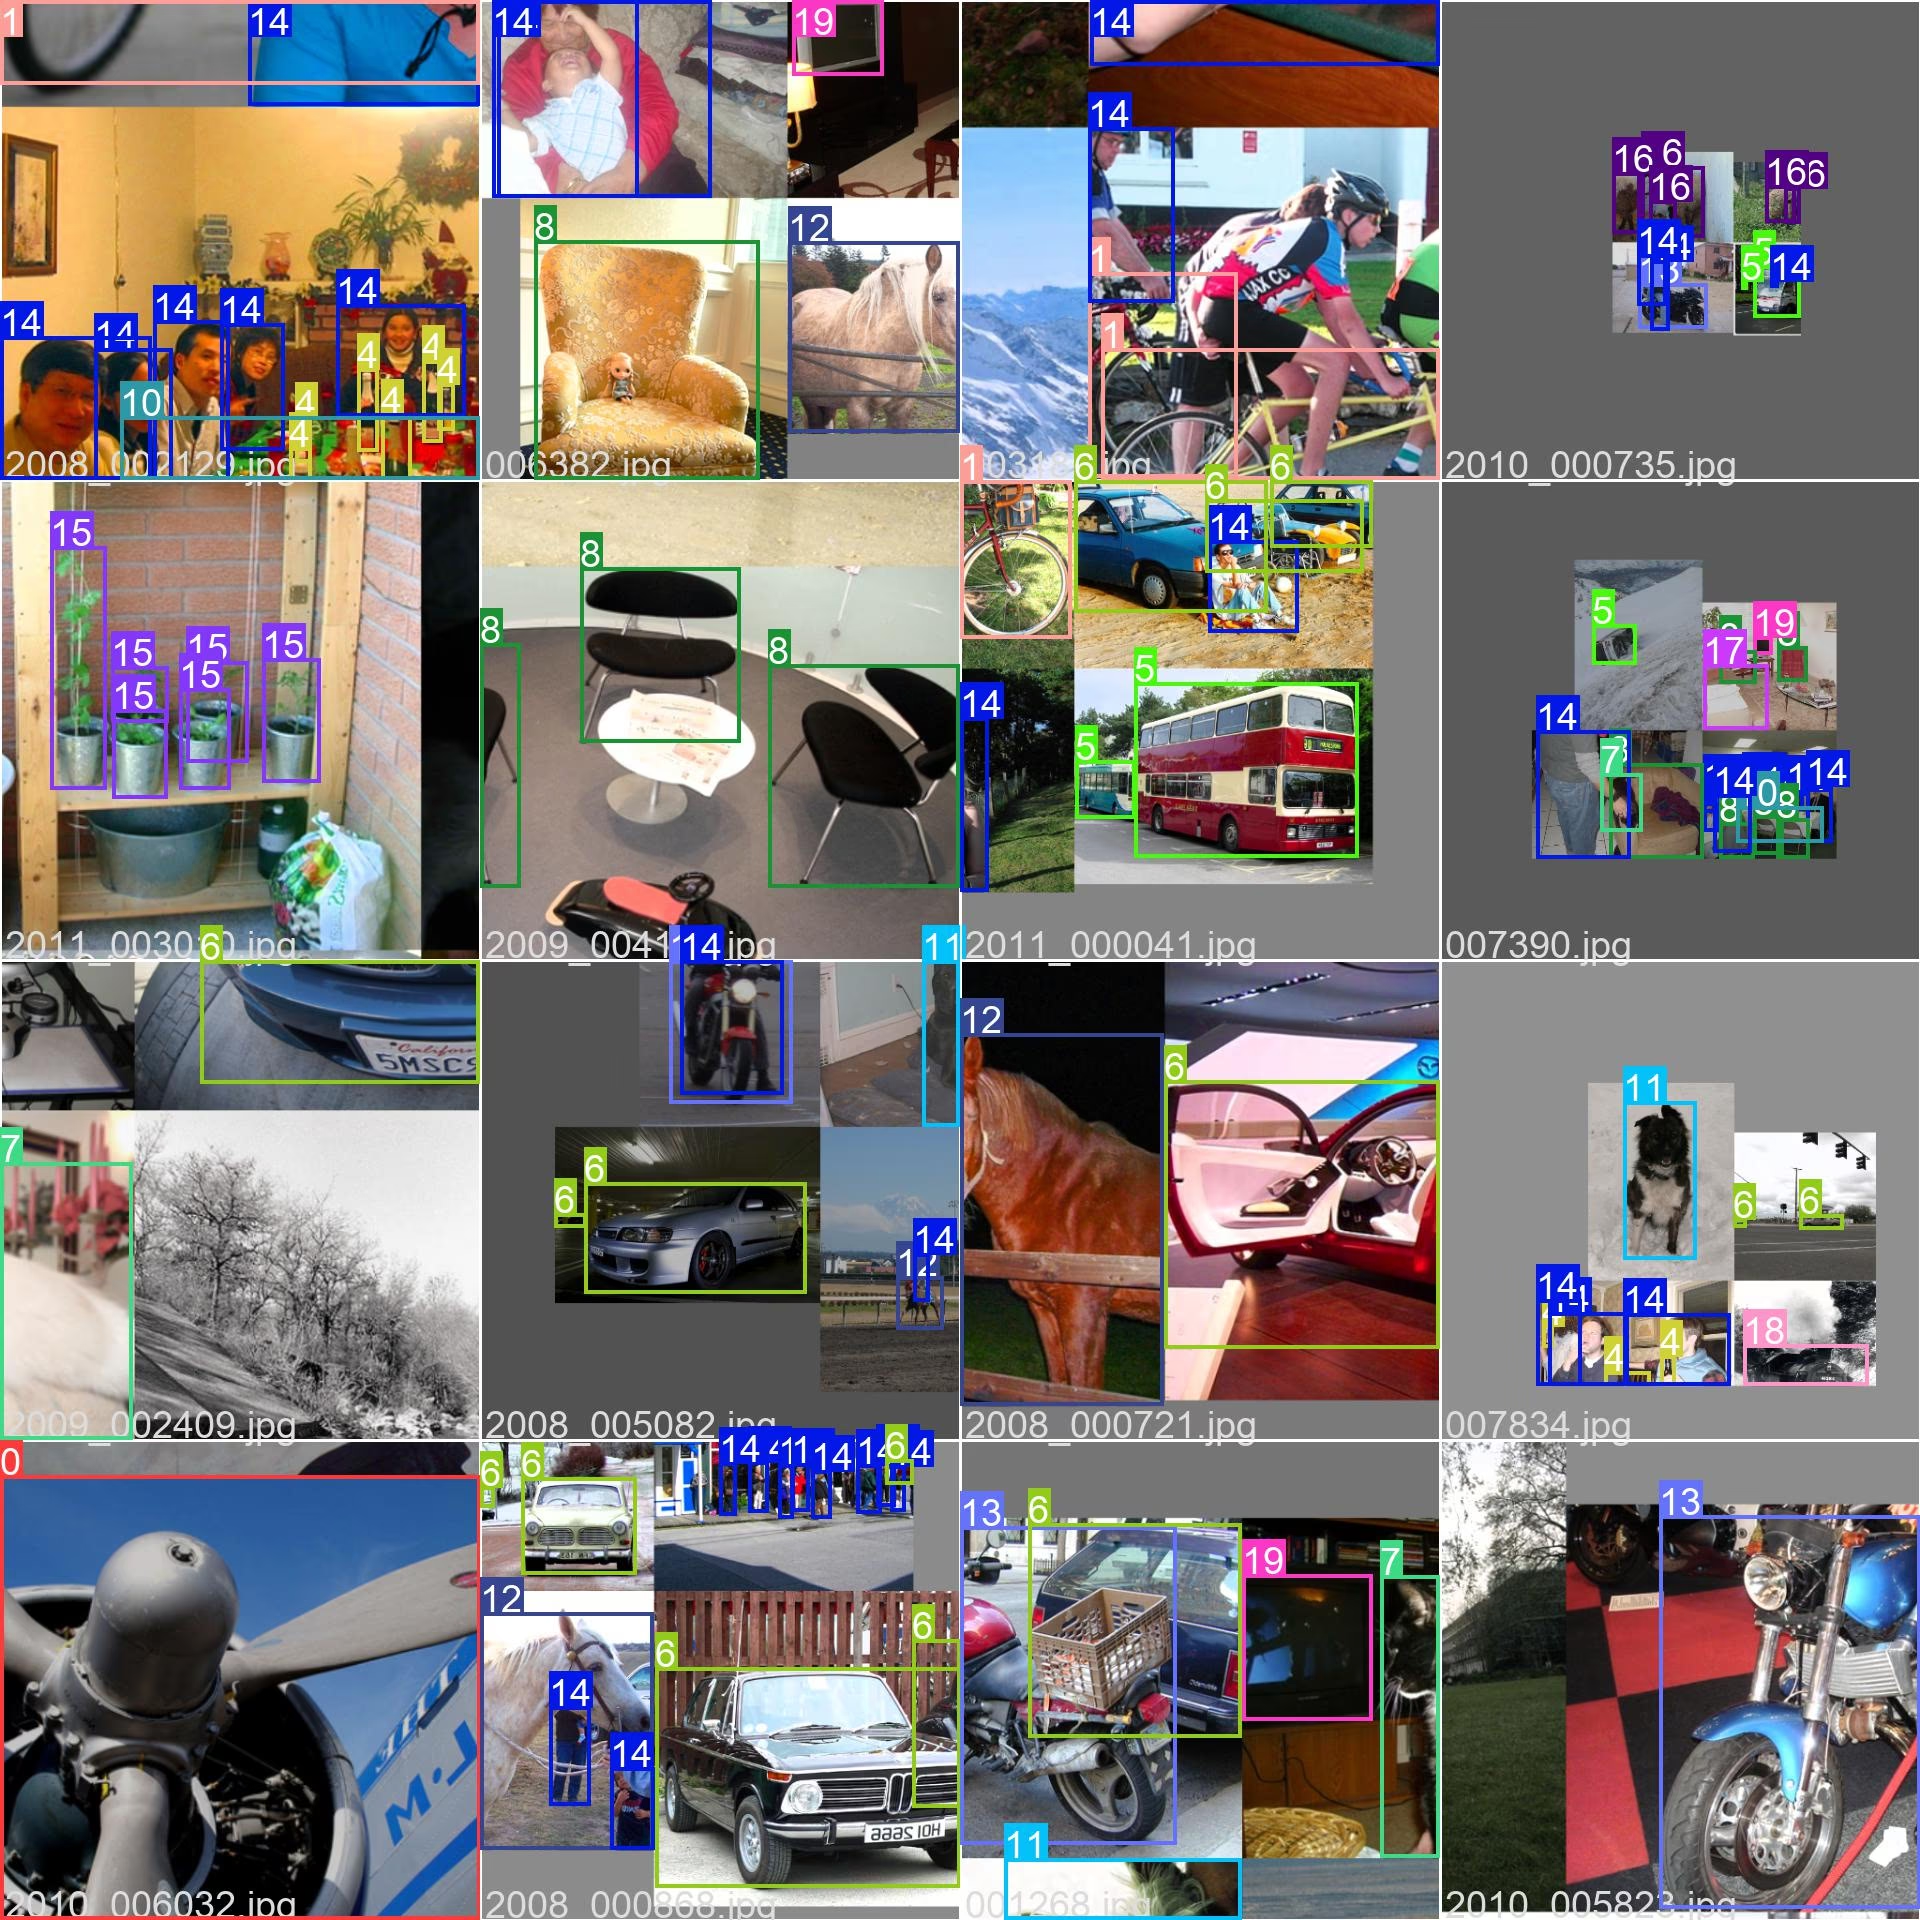
The image below shows a mosaiced training batch from the VOC dataset. Mosaicing combines multiple images into a single training sample, increasing the variety of objects, scales, and scene contexts the model sees in each batch — see the YOLO data augmentation guide for details.
If you use the VOC dataset in your research or development work, please cite the following paper:
Citation
@article{everingham2010pascal,
  author={Everingham, Mark and Van Gool, Luc and Williams, Christopher K. I. and Winn, John and Zisserman, Andrew},
  journal={International Journal of Computer Vision},
  title={The Pascal Visual Object Classes (VOC) Challenge},
  year={2010},
  volume={88},
  number={2},
  pages={303-338},
  doi={10.1007/s11263-009-0275-4}}
We would like to acknowledge the PASCAL VOC Consortium for creating and maintaining this valuable resource for the computer vision community. For more information about the VOC dataset and its creators, visit the PASCAL VOC dataset website.
PASCAL VOC is used to train and benchmark object detection models on 20 everyday object classes such as person, car, dog, and chair. Because it is compact, fully labeled, and backed by years of published baselines, it is a common choice for validating new architectures, running coursework experiments, and quick transfer learning studies.
The Ultralytics VOC configuration contains 21,503 images: 16,551 for training (VOC2007 trainval + VOC2012 trainval) and 4,952 for validation (the VOC2007 test set). All splits share the same 20 classes. See Dataset Structure for the full breakdown.
VOC downloads automatically the first time you train with data="VOC.yaml" — no manual steps are required. The script fetches three archives (2.8 GB) from Ultralytics GitHub release assets and converts the XML annotations to YOLO format.
Train a YOLO26n model on VOC for 100 epochs at an image size of 640:
Train Example
from ultralytics import YOLO

# Load a model
model = YOLO("yolo26n.pt")  # load a pretrained model (recommended for training)

# Train the model
results = model.train(data="VOC.yaml", epochs=100, imgsz=640)
Both challenges share the same 20 classes but contribute different images. VOC2007 provides 5,011 trainval images plus a 4,952-image test set whose annotations are public; VOC2012 provides 11,540 trainval images, while its test annotations are withheld and scored only by the official evaluation server. The Ultralytics VOC.yaml merges both trainval sets for training and validates on VOC2007 test.
VOC is smaller and simpler: 20 classes and 21,503 images versus COCO's 80 classes and 330K images. VOC results are traditionally reported as mAP at 0.5 IoU, while COCO averages mAP over IoU thresholds from 0.5 to 0.95. VOC trains much faster and suits quick experiments; the COCO dataset is the standard for production-scale benchmarking.
No — VOC.yaml is a detection-only configuration: its converter extracts bounding boxes from the VOC XML annotations, and the segmentation masks included in the original benchmark are not converted. To train an instance segmentation model, use a dataset with polygon labels such as COCO-Seg with a YOLO26n-seg model.
raise RuntimeError(emojis(f"Dataset '{clean_url(self.args.data)}' error ❌ {e}")) from e
RuntimeError: Dataset 'VOC.yaml' error ❌ [Errno 2] No such file or directory: '/home/diana/Code/test/datasets/VOC/images/VOCdevkit/VOC2007/ImageSets/Main/train.txt'
Nice find on the root cause. To clean things up, delete the incomplete datasets/VOC folder and run your yolo ... data=VOC.yaml command again so the download/conversion script can fully re-download and unpack everything; if you still hit a path error after that, please share the full command and complete traceback so we can take a closer look.
Respectively, "xmin/ymin" and "xmax/ymax" are the coordinates of the upper-left and lower-right corners of the object.
How can I use this dataset to train the YoloV11 neural network?
@YustasDev to train YOLO26 on your Pascal VOC dataset, you need to convert the XML annotations to YOLO format (class, x_center, y_center, width, height in normalized coordinates). Use the conversion script provided in the VOC.yaml file under the "Download script/URL" section. Once converted, define a custom YAML file for your dataset paths and run the training using:
from ultralytics import YOLO

model = YOLO("yolo26n.pt")
model.train(data="your_dataset.yaml", epochs=100, imgsz=640)
Respectively, "xmin/ymin" and "xmax/ymax" are the coordinates of the upper-left and lower-right corners of the object.
How can I use this dataset to train the YoloV11 neural network?
@YustasDev to use your Pascal VOC dataset for YOLO26 training, you need to convert the XML annotations to YOLO format (class, x_center, y_center, width, height with normalized coordinates). You can adapt the XML-to-YOLO conversion script from the VOC dataset documentation here: https://docs.ultralytics.com/datasets/detect/voc/. Once converted, create a dataset YAML file similar to VOC.yaml, specifying your paths and classes, and then start training using yolo detect train data=your_dataset.yaml model=yolo26n.pt. Let me know if you encounter any issues!
Cookies help us see which docs, models, and features you find useful, so we can keep improving them. Choose what you share in , or read our Privacy Policy.
mengdxiran
 Glenn JocherUltralytics
YustasDev