SKU-110K Dataset
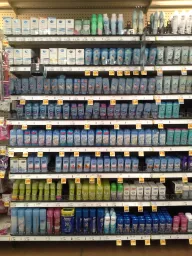
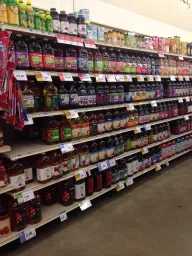
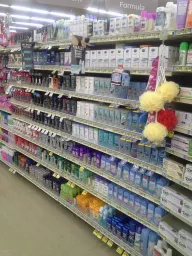
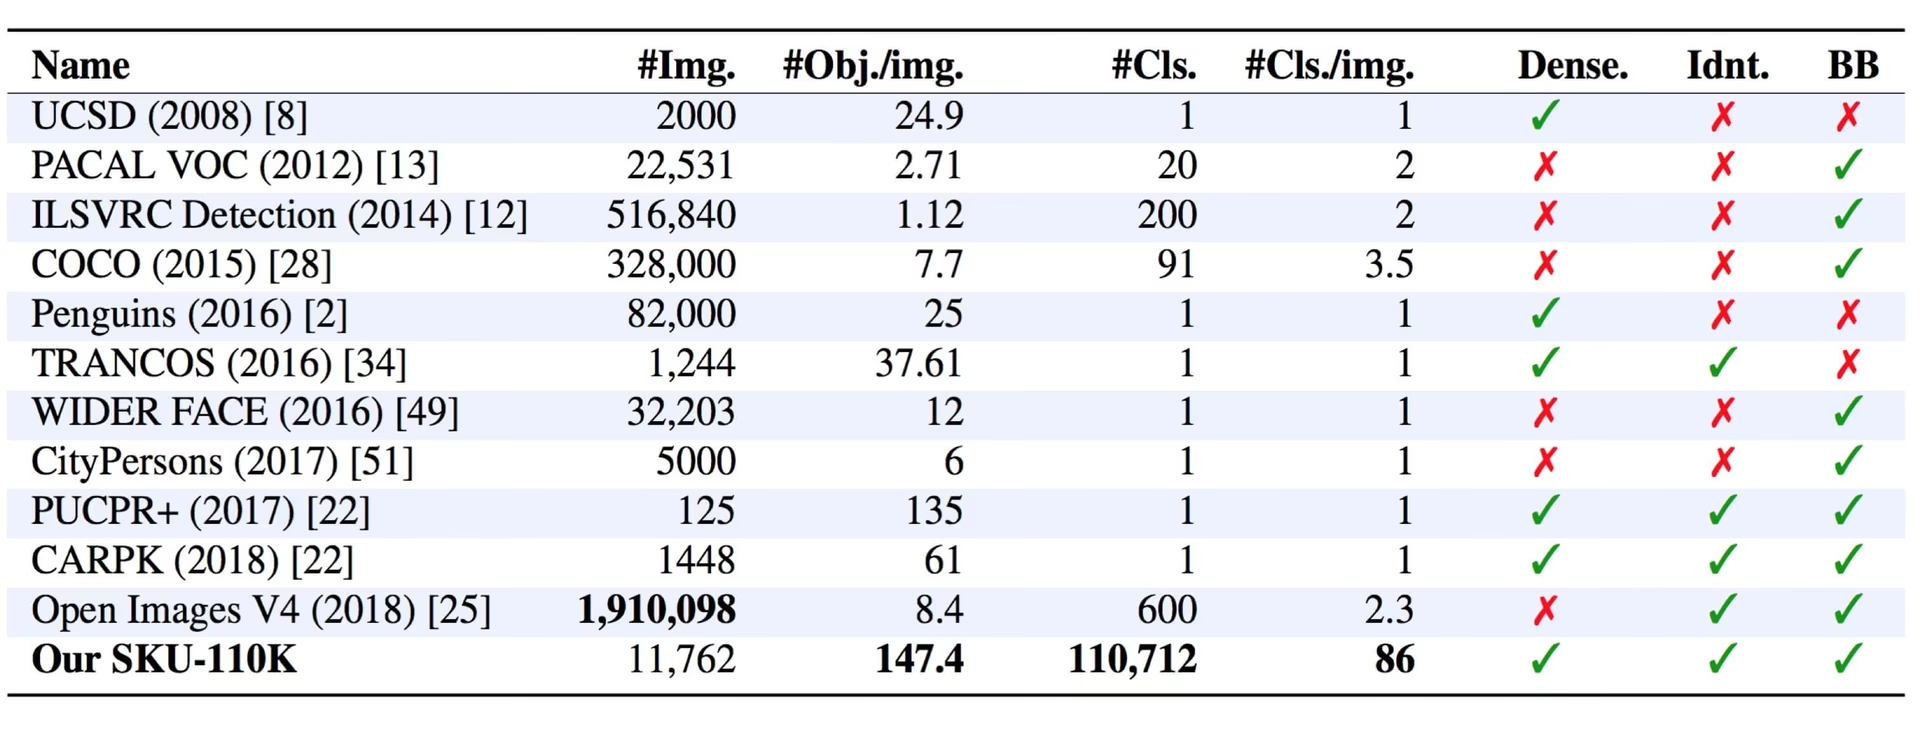
The SKU-110K dataset is a single-class object detection dataset of 11,743 densely packed retail-shelf images, split into 8,219 training, 588 validation, and 2,936 test images. Every product is annotated with one bounding box under a single class, object — the name refers to the more than 110,000 unique stock-keeping units (SKUs) pictured across the scenes, not to 110,000 detection classes. Created by Eran Goldman et al. for the CVPR 2019 paper Precise Detection in Densely Packed Scenes, it carries over 1.7 million annotated products — an average of roughly 147 per image — making it a demanding benchmark for computer vision models in crowded retail environments.
Watch: How to Train Ultralytics YOLO26 to Detect Every Product on a Retail Shelf | SKU-110K 🛒
Key Features#
- Single-class detection: Every product is labeled with one bounding box under a single class,
object(names: {0: object}) — the annotations carry no per-SKU category labels. - Extreme object density: Store-shelf images from around the world average about 147 tightly packed products each, with objects that often look similar or even identical positioned in close proximity.
- Large scale: More than 110,000 unique SKUs and over 1.7 million annotated bounding boxes across 11,743 images challenge state-of-the-art object detectors.
Dataset Structure#
The SKU-110K dataset is split into three subsets, all sharing the single object class:
| Split | Images | Description |
|---|---|---|
| Train | 8,219 | Images and annotations for model training |
| Validation | 588 | Held-out images for evaluation during training |
| Test | 2,936 | Images for final evaluation of the trained model |
Applications#
The SKU-110K dataset is widely used for training and evaluating deep learning models in object detection tasks, especially in densely packed scenes such as retail shelf displays. Its applications include:
- Retail inventory management and automation
- Product recognition in e-commerce platforms
- Planogram compliance verification
- Self-checkout systems in stores
- Robotic picking and sorting in warehouses
To annotate your own shelf images, train, and manage retail-detection datasets in your browser, run the full workflow with Ultralytics Platform.
Dataset YAML#
The SKU-110K.yaml file defines the dataset configuration — the dataset paths, class names, and other metadata. It is maintained in the Ultralytics repository at https://github.com/ultralytics/ultralytics/blob/main/ultralytics/cfg/datasets/SKU-110K.yaml.
# Ultralytics 🚀 AGPL-3.0 License - https://ultralytics.com/license

# SKU-110K retail items dataset https://github.com/eg4000/SKU110K_CVPR19 by Trax Retail
# Documentation: https://docs.ultralytics.com/datasets/detect/sku-110k
# Example usage: yolo train data=SKU-110K.yaml
# parent
# ├── ultralytics
# └── datasets
#     └── SKU-110K ← downloads here (13.6 GB)

# Train/val/test sets as 1) dir: path/to/imgs, 2) file: path/to/imgs.txt, or 3) list: [path/to/imgs1, path/to/imgs2, ..]
path: SKU-110K # dataset root dir
train: train.txt # train images (relative to 'path') 8219 images
val: val.txt # val images (relative to 'path') 588 images
test: test.txt # test images (optional) 2936 images

# Classes
names:
  0: object

# Download script/URL (optional) ---------------------------------------------------------------------------------------
download: |
  import shutil
  from pathlib import Path

  import numpy as np
  import polars as pl

  from ultralytics.utils import TQDM
  from ultralytics.utils.downloads import download
  from ultralytics.utils.ops import xyxy2xywh

  # Download
  dir = Path(yaml["path"])  # dataset root dir
  parent = Path(dir.parent)  # download dir
  urls = ["http://trax-geometry.s3.amazonaws.com/cvpr_challenge/SKU110K_fixed.tar.gz"]
  download(urls, dir=parent)

  # Rename directories
  if dir.exists():
      shutil.rmtree(dir)
  (parent / "SKU110K_fixed").rename(dir)  # rename dir
  (dir / "labels").mkdir(parents=True, exist_ok=True)  # create labels dir

  # Convert labels
  names = "image", "x1", "y1", "x2", "y2", "class", "image_width", "image_height"  # column names
  for d in "annotations_train.csv", "annotations_val.csv", "annotations_test.csv":
      x = pl.read_csv(dir / "annotations" / d, has_header=False, new_columns=names, infer_schema_length=None).to_numpy()  # annotations
      images, unique_images = x[:, 0], np.unique(x[:, 0])
      with open((dir / d).with_suffix(".txt").__str__().replace("annotations_", ""), "w", encoding="utf-8") as f:
          f.writelines(f"./images/{s}\n" for s in unique_images)
      for im in TQDM(unique_images, desc=f"Converting {dir / d}"):
          cls = 0  # single-class dataset
          with open((dir / "labels" / im).with_suffix(".txt"), "a", encoding="utf-8") as f:
              for r in x[images == im]:
                  w, h = r[6], r[7]  # image width, height
                  xywh = xyxy2xywh(np.array([[r[1] / w, r[2] / h, r[3] / w, r[4] / h]]))[0]  # instance
f.write(f"{cls} {xywh[0]:.5f} {xywh[1]:.5f} {xywh[2]:.5f} {xywh[3]:.5f}\n") # write labelUsage#
SKU-110K downloads automatically the first time you train and requires about 13.6 GB of free disk space for its 11,743 images. The download script also fetches the original annotations and converts them to YOLO format, which can take a few minutes.
To train a YOLO26n model on the SKU-110K dataset for 100 epochs with an image size of 640, you can use the following code snippets.
from ultralytics import YOLO

# Load a model
model = YOLO("yolo26n.pt")  # load a pretrained model (recommended for training)

# Train the model
results = model.train(data="SKU-110K.yaml", epochs=100, imgsz=640)
Sample Data and Annotations#
SKU-110K images capture densely packed products on real store shelves, where dozens of near-identical items sit side by side. Here is an example image with its annotations:
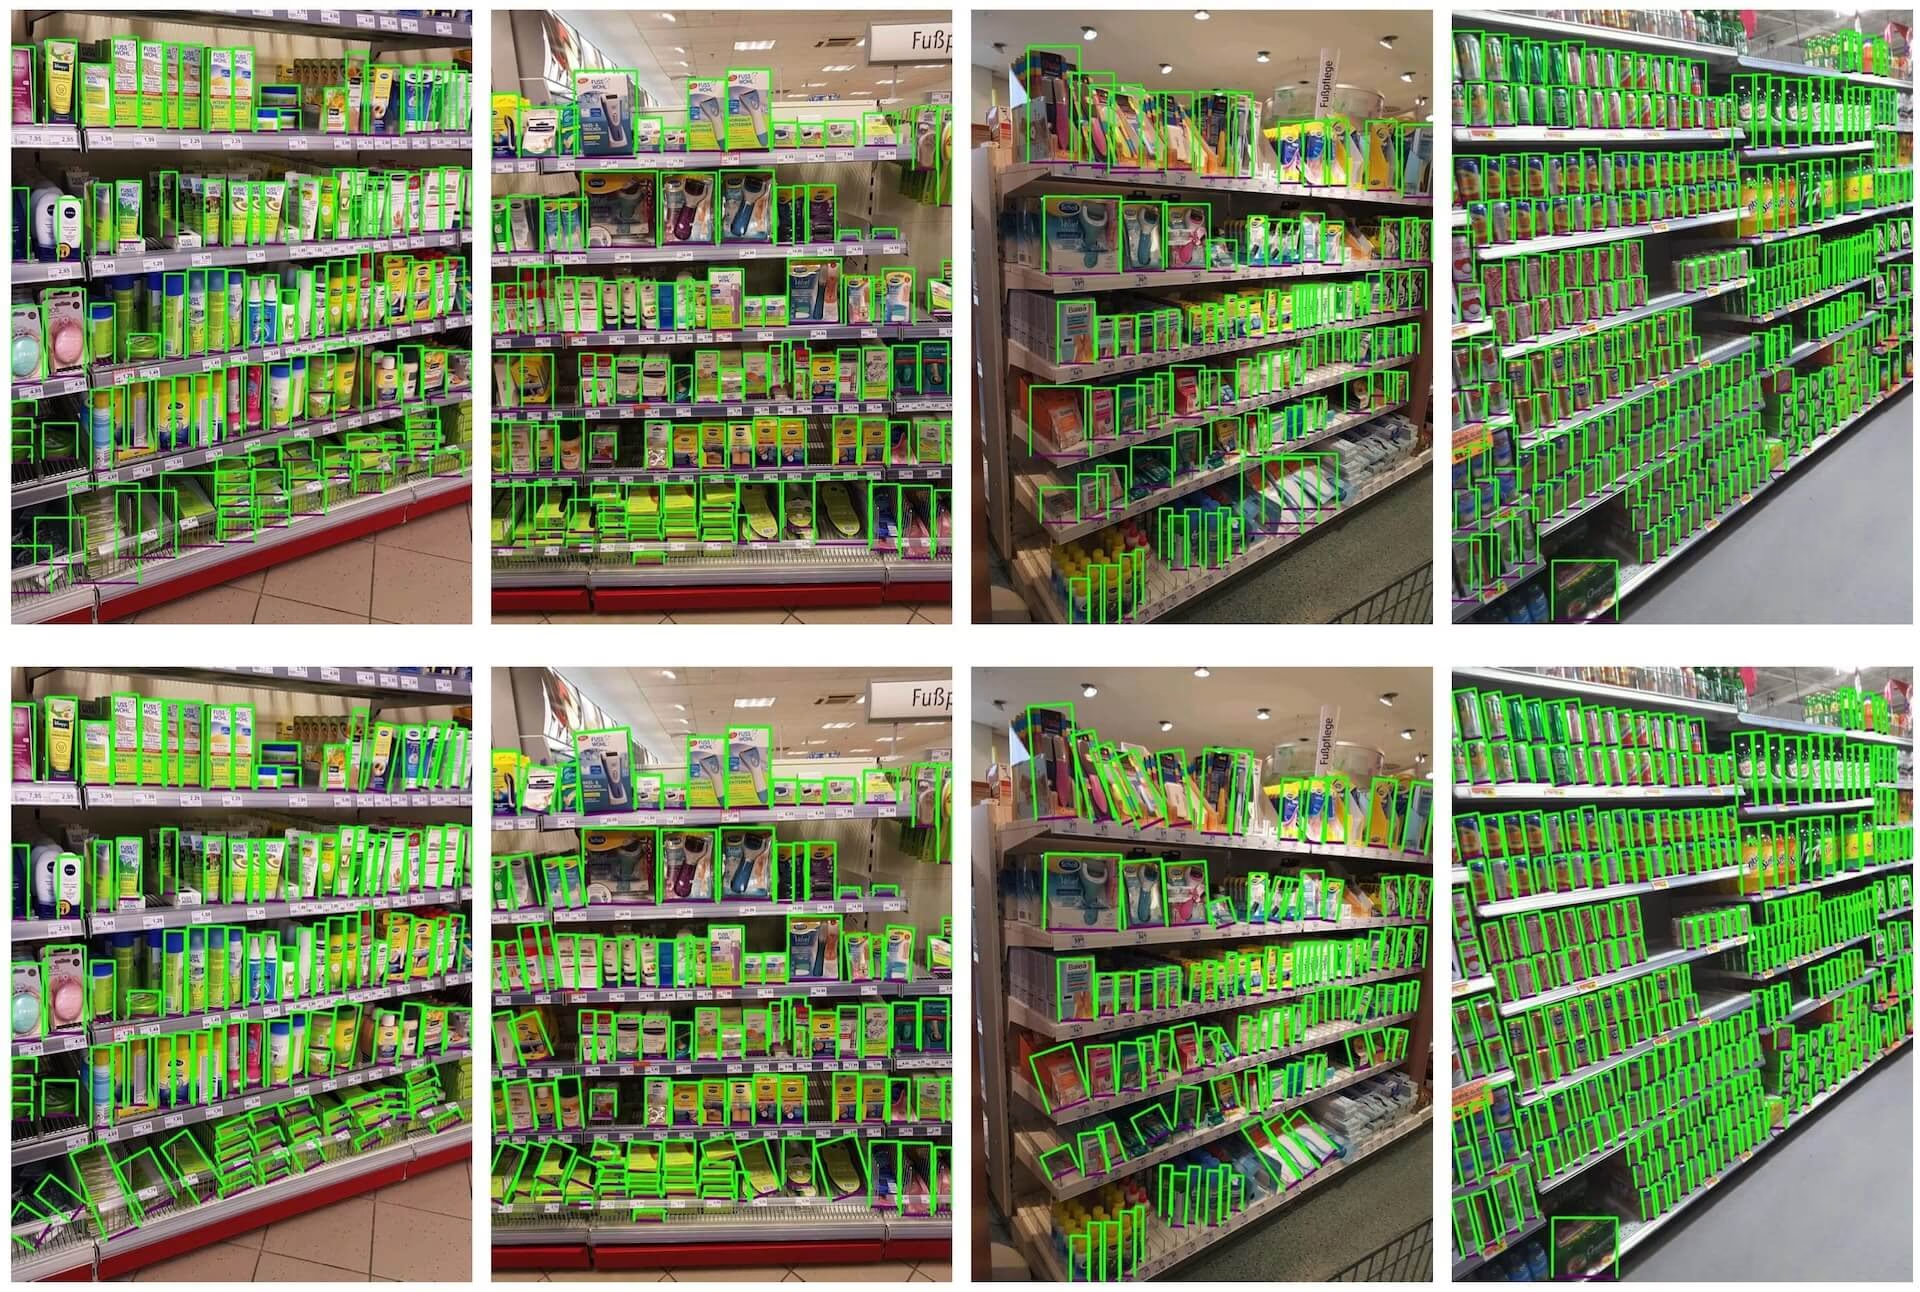
- Densely packed retail shelf image: This image demonstrates an example of densely packed objects in a retail shelf setting. Objects are annotated with bounding boxes under the single
objectclass.
The dense arrangement of products makes SKU-110K particularly valuable for developing robust retail-focused computer vision solutions, as the high object count per image pushes detectors well beyond typical benchmarks.
Citations and Acknowledgments#
If you use the SKU-110K dataset in your research or development work, please cite the following paper:
@inproceedings{goldman2019dense,
  author    = {Eran Goldman and Roei Herzig and Aviv Eisenschtat and Jacob Goldberger and Tal Hassner},
  title     = {Precise Detection in Densely Packed Scenes},
  booktitle = {Proc. Conf. Comput. Vision Pattern Recognition (CVPR)},
  year      = {2019}
}
We would like to acknowledge Eran Goldman et al. for creating and maintaining the SKU-110K dataset as a valuable resource for the computer vision research community. For more information about the SKU-110K dataset and its creators, visit the SKU-110K dataset GitHub repository.
FAQ#
The SKU-110K dataset is a single-class object detection dataset of 11,743 densely packed retail-shelf images, created by Eran Goldman et al. for their CVPR 2019 paper. Every product is labeled with one
objectbounding box, and the imagery spans more than 110,000 unique stock-keeping units (SKUs), making it a strong benchmark for detecting objects in crowded scenes and for building retail computer vision systems.No. SKU-110K is single-class: every product is annotated with one bounding box under the class
object(names: {0: object}). The "110K" in the name refers to the number of unique stock-keeping units (SKUs) pictured across the images, not to the number of detection classes.The SKU-110K dataset contains 11,743 images — 8,219 for training, 588 for validation, and 2,936 for testing — and a single detection class,
object. See the Dataset Structure section and theSKU-110K.yamlconfiguration for details.SKU-110K is about 13.6 GB and downloads automatically the first time you train with
data="SKU-110K.yaml"— no manual download is required. To browse smaller options, see the detection datasets overview.Training a YOLO26 model on the SKU-110K dataset is straightforward. Here's an example to train a YOLO26n model for 100 epochs with an image size of 640:
Train Examplefrom ultralytics import YOLO # Load a model model = YOLO("yolo26n.pt") # load a pretrained model (recommended for training) # Train the model results = model.train(data="SKU-110K.yaml", epochs=100, imgsz=640)


Comments6
Ask a question, share your results, or help someone else.
syafiqmuda
Hi, newbie here, I try to use this dataset to compare and see the accuracy for this dataset with my own, but during training almost all the file were show
Corrupt JPEG data: 786 extraneous bytes before marker 0xd9and sometimesCorrupt JPEG data: premature end of data segment. can I know why? my code look like this:training.py
from ultralytics import YOLO, checks, hub checks() def main(): hub.login('something') model = YOLO('https://hub.ultralytics.com/models/ukr3hHHq88WJASNn3aUz') results = model.train(device=[0,1,2,3]) if __name__ == '__main__': main() Glenn JocherUltralytics
Those messages are PIL JPEG warnings from a handful of non-standard images in SKU-110K; Ultralytics usually auto-recovers/filters these during dataloading via
ultralytics.data.utils.verify_image()(see theverify_image()reference), so if training continues it’s safe to ignore—if it actually crashes, re-download/re-extract the dataset (or re-encode the specific bad JPGs), then delete any*.cacheunder yourlabels/folder and rerun; if you share the text output ofyolo checksplus the full traceback (not a screenshot) we can pinpoint whether it’s data corruption or an environment issue.
ApodiAlsurihi
Hi, thank you for this amazing and detailed explanation! Your work is incredibly helpful and inspiring. I would deeply appreciate it if you could share the trained model after the training process. It would make a significant difference in advancing my project and learning. Thank you so much for your generosity and support!
- Glenn JocherUltralytics
@ApodiAlsurihi thank you for your kind words! Unfortunately, we cannot share trained models directly. However, you can train your own model using the SKU-110K dataset by following the instructions provided in the documentation.
serna01
Are this warnings OK, when training? the batch=0.1 I used it to avoid a memory error. yolo detect train data=SKU-110K.yaml model=yolov8n.pt epochs=50 imgsz=640 batch=0.1
AutoBatch: Using batch-size 2 for CUDA:0 0.49G/3.81G (13%) ✅ train: Scanning /home/asm/cv_cornia/parking_mgmt/datasets/SKU-110K/labels... 8216 train: WARNING ⚠️ /home/asm/cv_cornia/parking_mgmt/datasets/SKU-110K/images/train_1797.jpg: 3 duplicate labels removed train: WARNING ⚠️ /home/asm/cv_cornia/parking_mgmt/datasets/SKU-110K/images/train_4222.jpg: ignoring corrupt image/label: image file is truncated (23 bytes not processed) train: WARNING ⚠️ /home/asm/cv_cornia/parking_mgmt/datasets/SKU-110K/images/train_882.jpg: ignoring corrupt image/label: image file is truncated (3 bytes not processed) train: WARNING ⚠️ /home/asm/cv_cornia/parking_mgmt/datasets/SKU-110K/images/train_924.jpg: ignoring corrupt image/label: image file is truncated (10 bytes not processed)
al: Scanning /home/asm/cv_cornia/parking_mgmt/datasets/SKU-110K/labels... 588 ima val: New cache created: /home/asm/cv_cornia/parking_mgmt/datasets/SKU-110K/labels.cache Corrupt JPEG data: 305 extraneous bytes before marker 0xd9 Corrupt JPEG data: 786 extraneous bytes before marker 0xd9 Plotting labels to runs/detect/train5/labels.jpg... optimizer: 'optimizer=auto' found, ignoring 'lr0=0.01' and 'momentum=0.937' and determining best 'optimizer', 'lr0' and 'momentum' automatically... optimizer: AdamW(lr=0.002, momentum=0.9) with parameter groups 57 weight(decay=0.0), 64 weight(decay=0.0005), 63 bias(decay=0.0) TensorBoard: model graph visualization added ✅ Image sizes 640 train, 640 val Using 8 dataloader workers Logging results to runs/detect/train5 Starting training for 50 epochs...
  Epoch    GPU_mem   box_loss   cls_loss   dfl_loss  Instances       Size
   1/50      1.14G      2.504      3.041       1.53        378        640:   5Corrupt JPEG data: premature end of data segment
   1/50      1.15G      2.382      2.658      1.454        331        640:   7Corrupt JPEG data: 562 extraneous bytes before marker 0xd9
   1/50      1.42G      2.273      2.314      1.382        314        640:  11Corrupt JPEG data: bad Huffman code
   1/50      1.42G      2.266      2.295      1.378        578        64       1/50      1.42G      2.266      2.293      1.377        678        64       1/50      1.42G      2.266      2.293      1.377        678        64       1/50      1.42G      2.265      2.292      1.377        723        64       1/50      1.42G      2.265      2.292      1.377        723        64       1/50      1.42G      2.266       2.29      1.377        695        64       1/50      1.42G      2.266          1/50      1.42G      2.255      2.2       1/50      1.42G      2.254      2.247       1.3       1/50      1       1/50              1/50                          1/50      1.42G      2.232      2.187      1.358        608        640:  13Corrupt JPEG data: bad Huffman code
   1/50      1.42G      2.216      2.138      1.347        437        640:  14Corrupt JPEG data: premature end of data segment
   1/50      1.42G      2.164      1.993      1.318        478        640:  17Corrupt JPEG data: 41 extraneous bytes before marker 0xd9
   1/50      1.42G      2.157      1.967      1.312        308        640:  17Corrupt JPEG data: premature end of data segment
   1/50      1.42G      2.011       1.61      1.239        173        640:  30Corrupt JPEG data: premature end of data segment
   1/50      1.42G      1.987      1.556      1.227        461        640:  33Corrupt JPEG data: 96 extraneous bytes before marker 0xd9
   1/50      1.42G      1.978      1.537      1.223        214        640:  34Corrupt JPEG data: bad Huffman code
   1/50      1.42G      1.959      1.497      1.215        250        640:  37Corrupt JPEG data: bad Huffman code
   1/50      1.42G      1.915      1.403      1.197        500        640:  46Corrupt JPEG data: premature end of data segment
   1/50      1.42G      1.888      1.345      1.185        616        640:  52Corrupt JPEG data: premature end of data segment
Thanks.
- Glenn JocherUltralytics
@serna01 the warnings you see are generally okay and indicate that the training process is handling issues like duplicate labels and corrupt images. Using
batch=0.1to avoid memory errors is fine, but consider adjusting your batch size to better utilize your GPU memory. If the warnings persist or cause issues, ensure you're using the latest version of the package. For more details on the SKU-110k dataset, visit SKU-110k Dataset Documentation.