Fast Segment Anything Model (FastSAM)
The Fast Segment Anything Model (FastSAM) is a real-time, CNN-based solution for the Segment Anything task. This task is designed to segment any object within an image based on various possible user interaction prompts. FastSAM significantly reduces computational demands while maintaining competitive performance, making it a practical choice for a variety of vision tasks.
Watch: Object Tracking using FastSAM with Ultralytics
Model Architecture#
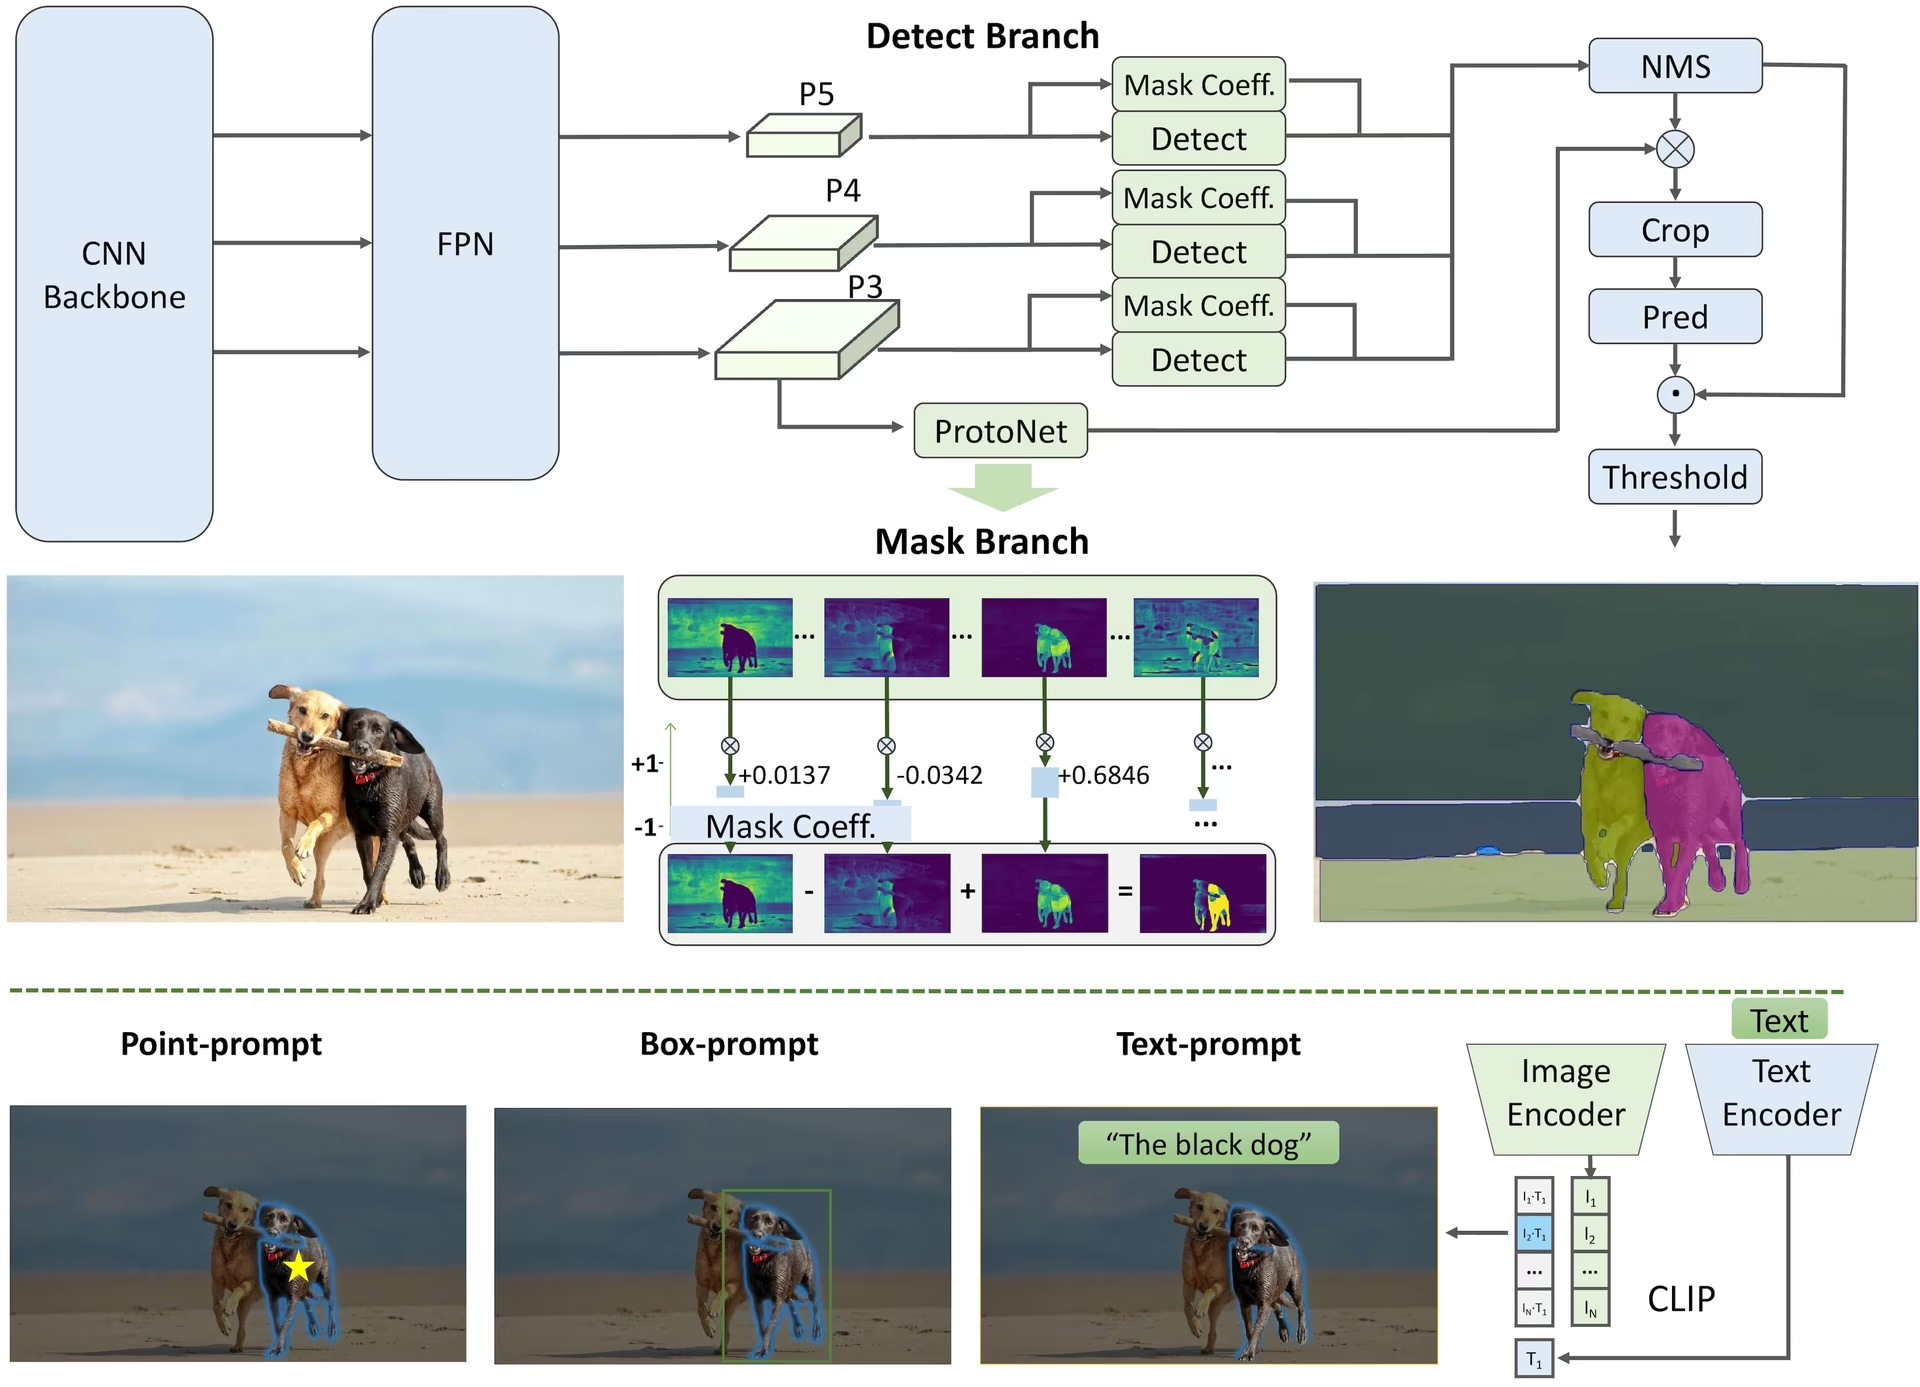
Overview#
FastSAM is designed to address the limitations of the Segment Anything Model (SAM), a heavy Transformer model with substantial computational resource requirements. FastSAM decouples the segment anything task into two sequential stages: all-instance segmentation and prompt-guided selection. The first stage uses YOLOv8-seg to produce the segmentation masks of all instances in the image. In the second stage, it outputs the region of interest corresponding to the prompt.
Key Features#
-
Real-time Solution: By leveraging the computational efficiency of CNNs, FastSAM provides a real-time solution for the segment anything task, making it valuable for industrial applications that require quick results.
-
Efficiency and Performance: FastSAM significantly reduces computational and resource demands while achieving performance comparable to SAM, enabling real-time applications.
-
Prompt-guided Segmentation: FastSAM can segment any object within an image guided by various user interaction prompts, providing flexibility and adaptability in different scenarios.
-
Based on YOLOv8-seg: FastSAM is based on YOLOv8-seg, an object detector equipped with an instance segmentation branch. This allows it to effectively produce the segmentation masks of all instances in an image.
-
Competitive Results on Benchmarks: On the object proposal task on MS COCO, FastSAM achieves high scores at a significantly faster speed than SAM on a single NVIDIA RTX 3090, demonstrating its efficiency and capability.
-
Practical Applications: The approach provides a practical solution for many vision tasks, running tens to hundreds of times faster than earlier segment anything methods.
-
Model Compression Feasibility: FastSAM demonstrates the feasibility of a path that can significantly reduce the computational effort by introducing an artificial prior to the structure, thus opening new possibilities for large model architecture for general vision tasks.
Available Models, Supported Tasks, and Operating Modes#
This table presents the available models with their specific pretrained weights, the tasks they support, and their compatibility with different operating modes like Training, Validation, Inference, and Export. Supported modes are indicated by ✅ and unsupported modes by ❌.
| Model Type | Pretrained Weights | Tasks Supported | Training | Validation | Inference | Export |
|---|---|---|---|---|---|---|
| FastSAM-s | FastSAM-s.pt | Instance Segmentation | ❌ | ✅ | ✅ | ✅ |
| FastSAM-x | FastSAM-x.pt | Instance Segmentation | ❌ | ✅ | ✅ | ✅ |
FastSAM Comparison vs YOLO#
Here we compare FastSAM-s with Meta's SAM variants and Ultralytics segmentation models, including YOLO26:
| Model | Size (MB) | Parameters (M) | Speed (CPU) (ms/im) |
|---|---|---|---|
| Meta SAM-b | 375 | 93.7 | 41703 |
| Meta SAM2-b | 162 | 80.8 | 28867 |
| Meta SAM2-t | 78.1 | 38.9 | 23430 |
| MobileSAM | 40.7 | 10.1 | 23802 |
| FastSAM-s with YOLOv8 backbone | 23.9 | 11.8 | 58.0 |
| Ultralytics YOLOv8n-seg | 7.1 (11.0x smaller) | 3.4 (11.4x less) | 24.8 (945x faster) |
| Ultralytics YOLO11n-seg | 6.2 (12.6x smaller) | 2.9 (13.4x less) | 24.3 (964x faster) |
| Ultralytics YOLO26n-seg | 6.7 (11.7x smaller) | 2.7 (14.4x less) | 25.2 (930x faster) |
This comparison demonstrates the substantial differences in model sizes and speeds between SAM variants and YOLO segmentation models. While SAM provides unique automatic segmentation capabilities, YOLO models, particularly YOLOv8n-seg, YOLO11n-seg and YOLO26n-seg, are significantly smaller, faster, and more computationally efficient.
SAM speeds measured with PyTorch, YOLO speeds measured with ONNX Runtime. Tests run on a 2025 Apple M4 Air with 16GB of RAM using torch==2.10.0, ultralytics==8.4.31, and onnxruntime==1.24.4. To reproduce this test:
from ultralytics import ASSETS, SAM, YOLO, FastSAM

# Profile SAM2-t, SAM2-b, SAM-b, MobileSAM
for file in ["sam_b.pt", "sam2_b.pt", "sam2_t.pt", "mobile_sam.pt"]:
    model = SAM(file)
    model.info()
    model(ASSETS)

# Profile FastSAM-s
model = FastSAM("FastSAM-s.pt")
model.info()
model(ASSETS)

# Profile YOLO models (ONNX)
for file_name in ["yolov8n-seg.pt", "yolo11n-seg.pt", "yolo26n-seg.pt"]:
    model = YOLO(file_name)
    model.info()
    onnx_path = model.export(format="onnx", dynamic=True, nms=False)  # YOLO26 NMS-free head; no-op for YOLOv8/YOLO11
    model = YOLO(onnx_path)
    model(ASSETS)
Usage Examples#
The FastSAM models are easy to integrate into your Python applications. Ultralytics provides both a Python API and CLI commands.
Predict Usage#
To segment an image, use the predict method as shown below:
from ultralytics import FastSAM

# Define an inference source
source = "path/to/bus.jpg"

# Create a FastSAM model
model = FastSAM("FastSAM-s.pt")  # or FastSAM-x.pt

# Run inference on an image
everything_results = model(source, device="cpu", retina_masks=True, imgsz=1024, conf=0.4, iou=0.9)

# Run inference with bboxes prompt
results = model(source, bboxes=[439, 437, 524, 709])

# Run inference with points prompt
results = model(source, points=[[200, 200]], labels=[1])

# Run inference with texts prompt
results = model(source, texts="a photo of a dog")

# Run inference with bboxes and points and texts prompt at the same time
results = model(source, bboxes=[439, 437, 524, 709], points=[[200, 200]], labels=[1], texts="a photo of a dog")
This snippet demonstrates the simplicity of loading a pretrained model and running a prediction on an image.
Run inference on an image once to get all segment results, then apply prompts to those results multiple times without re-running inference.
from ultralytics.models.fastsam import FastSAMPredictor

# Create FastSAMPredictor
overrides = {"conf": 0.25, "task": "segment", "mode": "predict", "model": "FastSAM-s.pt", "save": False, "imgsz": 1024}
predictor = FastSAMPredictor(overrides=overrides)

# Segment everything
everything_results = predictor("ultralytics/assets/bus.jpg")

# Prompt inference
bbox_results = predictor.prompt(everything_results, bboxes=[[200, 200, 300, 300]])
point_results = predictor.prompt(everything_results, points=[200, 200])
text_results = predictor.prompt(everything_results, texts="a photo of a dog")All the returned results in the above examples are Results objects which provide access to the predicted masks and the source image.
Val Usage#
FastSAM only supports detection and segmentation of a single object class, so it recognizes and segments all objects as the same class. When preparing the dataset, convert all object category IDs to 0.
Validation of the model on a dataset can be done as follows:
from ultralytics import FastSAM

# Create a FastSAM model
model = FastSAM("FastSAM-s.pt")  # or FastSAM-x.pt

# Validate the model
results = model.val(data="coco8-seg.yaml")
Track Usage#
To perform object tracking on an image, use the track method as shown below:
from ultralytics import FastSAM

# Create a FastSAM model
model = FastSAM("FastSAM-s.pt")  # or FastSAM-x.pt

# Track with a FastSAM model on a video
results = model.track(source="path/to/video.mp4", imgsz=640)
FastSAM official Usage#
FastSAM is also available directly from the CASIA-LMC-Lab/FastSAM repository. Here is a brief overview of the typical steps you might take to use FastSAM:
Installation#
-
Clone the FastSAM repository:
git clone https://github.com/CASIA-LMC-Lab/FastSAM.git -
Create and activate a Conda environment with Python 3.9:
conda create -n FastSAM python=3.9 conda activate FastSAM -
Navigate to the cloned repository and install the required packages:
cd FastSAM pip install -r requirements.txt -
Install the CLIP model:
pip install git+https://github.com/ultralytics/CLIP.git
Example Usage#
-
Download a model checkpoint.
-
Use FastSAM for inference. Example commands:
-
Segment everything in an image:
python Inference.py --model_path ./weights/FastSAM.pt --img_path ./images/dogs.jpg -
Segment specific objects using text prompt:
python Inference.py --model_path ./weights/FastSAM.pt --img_path ./images/dogs.jpg --text_prompt "the yellow dog" -
Segment objects within a bounding box (provide box coordinates in xywh format):
python Inference.py --model_path ./weights/FastSAM.pt --img_path ./images/dogs.jpg --box_prompt "[570,200,230,400]" -
Segment objects near specific points:
python Inference.py --model_path ./weights/FastSAM.pt --img_path ./images/dogs.jpg --point_prompt "[[520,360],[620,300]]" --point_label "[1,0]"
-
Additionally, you can try FastSAM through the CASIA-LMC-Lab Colab demo.
Citations and Acknowledgments#
We would like to acknowledge the FastSAM authors for their significant contributions in the field of real-time instance segmentation:
@misc{zhao2023fast,
      title={Fast Segment Anything},
      author={Xu Zhao and Wenchao Ding and Yongqi An and Yinglong Du and Tao Yu and Min Li and Ming Tang and Jinqiao Wang},
      year={2023},
      eprint={2306.12156},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}
The original FastSAM paper can be found on arXiv. The authors have made their work publicly available, and the codebase can be accessed on GitHub. We appreciate their efforts in advancing the field and making their work accessible to the broader community.
FAQ#
FastSAM, short for Fast Segment Anything Model, is a real-time convolutional neural network (CNN)-based solution designed to reduce computational demands while maintaining high performance in object segmentation tasks. Unlike the Segment Anything Model (SAM), which uses a heavier Transformer-based architecture, FastSAM uses Ultralytics YOLOv8-seg for efficient instance segmentation in two stages: all-instance segmentation followed by prompt-guided selection.
FastSAM achieves real-time segmentation by decoupling the segmentation task into all-instance segmentation with YOLOv8-seg and prompt-guided selection stages. By utilizing the computational efficiency of CNNs, FastSAM offers significant reductions in computational and resource demands while maintaining competitive performance. This two-stage approach enables FastSAM to deliver fast, efficient segmentation suitable for applications requiring quick results.
FastSAM is practical for a variety of computer vision tasks that require real-time segmentation performance. Applications include:
- Industrial automation for quality control and assurance
- Real-time video analysis for security and surveillance
- Autonomous vehicles for object detection and segmentation
- Medical imaging for precise and quick segmentation tasks
Its ability to handle various user interaction prompts makes FastSAM adaptable and flexible for diverse scenarios.
To use FastSAM for inference in Python, you can follow the example below:
from ultralytics import FastSAM

# Define an inference source
source = "path/to/bus.jpg"

# Create a FastSAM model
model = FastSAM("FastSAM-s.pt")  # or FastSAM-x.pt

# Run inference on an image
everything_results = model(source, device="cpu", retina_masks=True, imgsz=1024, conf=0.4, iou=0.9)

# Run inference with bboxes prompt
results = model(source, bboxes=[439, 437, 524, 709])

# Run inference with points prompt
results = model(source, points=[[200, 200]], labels=[1])

# Run inference with texts prompt
results = model(source, texts="a photo of a dog")

# Run inference with bboxes and points and texts prompt at the same time
results = model(source, bboxes=[439, 437, 524, 709], points=[[200, 200]], labels=[1], texts="a photo of a dog")
For more details on inference methods, check the Predict Usage section of the documentation.
FastSAM supports multiple prompt types for guiding the segmentation tasks:
- Everything Prompt: Generates segmentation for all visible objects.
- Bounding Box (BBox) Prompt: Segments objects within a specified bounding box. A box that overlaps no detected mask selects nothing.
- Text Prompt: Uses a descriptive text to segment objects matching the description.
- Point Prompt: Segments objects near specific user-defined points.
This flexibility allows FastSAM to adapt to a wide range of user interaction scenarios, enhancing its utility across different applications. For more information on using these prompts, refer to the Key Features section.


Comments26
Ask a question, share your results, or help someone else.
qinfendekaizhou
why is the postprocess times is so long
PrashantDixit0(edited)
@qinfendekaizhou, can you share the reproducible code for it? Or the reference from where u noticed this.
In general, post-process time gets increased because of the post-processes involved to show the results, like
- NMS
- filtering by confidence score/ labels
- Scaling results to the original given inputs
- Number of objects to be annotated,
- Type of annotation, like BB or Segmentation
juliopchile
Will someone try to do a FastSAM for SAM2?
shahedmomenzadeh
Hi, I have a question Can I use the generated bbox cordinates by a yolo detection model like yolov11 as bboxes prompt for FastSAM ?
 Glenn JocherUltralytics
@shahedmomenzadeh yes, you can use YOLO detection model-generated bbox coordinates as prompts for FastSAM. The FastSAM documentation shows examples of passing bbox coordinates directly to the model using either the Python API or CLI. Just ensure your coordinates are in XYXY format as shown in the examples.
ismailwale
How can I make an inference of a video using frame by frame in loop using FastSam ?because I tried multiple times making inference directly with video predictor I constantly running out of memory despite setting stream =True since SAM is trying to keep the memory of 2000 frames of the video at ones . I will appreciate any ideal on how to predict and segment the video as a single frame image at every instance and put everything in a loop.
Similar question win MobileSam
- Glenn JocherUltralytics
@ismailwale to process a video frame by frame and avoid memory overload with FastSAM or MobileSAM, load the video as a frame sequence using a tool like OpenCV. Loop through each frame, run inference on it individually, and clear any cached results to free up memory between frames. For reference on frame-wise usage, consult OpenCV and FastSAM integration. Let me know if you need further clarifications!
Thanks so much for your guide .I appreciate it sir.
llu025
Thank you all for your great work! I am having troubles with prompting with a bounding box, it seems the FastSAM model ignores it and detects objects all over the video frames. This is how I obtain the results:
results = model(
    input_filename,
    device=device,
    imgsz=(736, 1280),
    verbose=False,
    stream=True,
    bboxes=[0, 0, 360, 640],
    retina_masks=True,
    conf=0.4,
    iou=0.9,
)
I also tried with
bboxes=[[0, 0, 360, 640]],without success. The model should detect objects in the top left quadrant of the video, instead it detects everywhere. Also, it oddly does not raise any error or warnings, both withbboxesas list of integers orbboxesas list of lists of integers.- Glenn JocherUltralytics
It seems the bounding box prompts aren't being applied as expected. Ensure the
bboxesformat is correct (e.g.,[[x1, y1, x2, y2]]as a list of lists). Additionally, try using theFastSAMPredictorapproach for more controlled prompt application, as shown in this example. Let me know if the issue persists! Thank you @glenn-jocher for the "prompt" response ;-)
I need to use
stream=Truesince I am working with large videos. I cannot use it coupled withFastSAMPredictor, because it does not support it. My only alternative is to grab frames on my own with OpenCV, is that correct?By the way, in your examples in here
bboxesis passed as a list of integers, I followed those in the beginning. I see in the examples withFastSAMPredictorthat a list of lists is used instead. In any case, I ensured that I was using a list of lists, and it did not work anyway.Here's a minimal example of what I am trying to do, i.e., detecting objects in the top left part of the video:
from ultralytics import FastSAM import os import ffmpeg input_filename = "test_video.mp4" base_name = os.path.splitext(os.path.basename(input_filename))[0] output_filename = os.path.join("output", f"{base_name}.avi") model = FastSAM("models/FastSAM-x.pt") process2 = ( ffmpeg.input( "pipe:", format="rawvideo", pix_fmt="rgb24", s="1280x720", loglevel="-8", ) .output( output_filename, pix_fmt="yuv420p", vcodec="libx264", loglevel="-8", crf=17, ) .overwrite_output() .run_async(pipe_stdin=True) ) results = model( input_filename, device="cuda", imgsz=(736, 1280), verbose=False, stream=True, bboxes=[[0, 0, 360, 640]], retina_masks=True, conf=0.4, iou=0.9, ) for result in results: frame = result.plot() # Save on disk with process2 process2.stdin.write(frame.tobytes()) process2.stdin.close() process2.wait()- Glenn JocherUltralytics
Thank you for the detailed explanation and example. Yes, you're correct—using OpenCV to manually grab frames is a valid and efficient approach, especially when working with
stream=Truefor large videos, as it avoids memory issues. Regardingbboxes, FastSAM expects a list of lists in the format[[x1, y1, x2, y2]]. If this still doesn't work as intended, please ensure your bounding box coordinates are correct and within the frame dimensions. Let us know if you encounter any further issues! I still encounter the same issue. I used
bboxes=[[20, 20, 500, 500]]just to be 100% sure the coordinates are within the the frame dimensions (1280x720), nothing changed. Since I have to grab frames with OpenCV anyway, I will just crop them myself, but I am quite sure this option is not working as intended.- Glenn JocherUltralytics
@llu025 thank you for the update. If you’re certain the
bboxesparameter is properly configured and still not working as intended, cropping frames manually with OpenCV before passing them to the model is indeed a reliable workaround. It may also be worth checking the latest FastSAM updates or reporting this as a potential issue to ensure the bounding box prompt functionality is reviewed. Let us know if you need further assistance!
chongkuiqi
Thanks for your great work! I'm using FastSAM-x with bboxes prompt, the original image shape is [720, 1280], and I set 'imgsz' 1024. However, the results mask shape is [576, 1024], but I remembered in ultralytics-8.2.10, I can get masks with the same shape as the original image. May I ask why this change happened ?
Sorry, I forgot to set 'Retina_masks', problem solved, thanks again.
feiwenxiong
how many boxes are supported in thsi api, it cound only segment 2 boxes at most.
- Glenn JocherUltralytics
@feiwenxiong fastSAM should support multiple boxes. If you're experiencing limitations, please ensure your input format is correct. For further assistance, you might want to check the latest updates or documentation.
YuechengLiu
Thanks the authors for the great work!
I'm using FastSAM-x for instance segmentation (bboxes as the prompt), but I find that the shape of the predicted masks mismatch with the bounding box number. (e.g. the model takes 18 bboxes as input, but the shape of the predicted mask is (17, H, W)) . I tried to set
conf=0.01andiou=0.999, but it doesn't work. How can I solve that? Thanks!- Glenn JocherUltralytics
@YuechengLiu thank you for your kind words! The issue you're experiencing might be due to a mismatch in the bounding box prompts and the segmentation results. Please ensure you're using the latest version of the FastSAM model. If the problem persists, consider checking the input format and the bounding box coordinates. For further assistance, you can refer to the FastSAM documentation: https://docs.ultralytics.com/models/fast-sam/.
Thanks for your kind reply! The bounding boxes I'm using are predicted by yolov10x (result.boxes.xyxy), so I think the input format might be right. I also tried the same bounding boxes for
mobile_sam, and the output dimension is as expected (same as the input dimension). The problem does not always occur. Do you have any idea about that? Thanks!And I'm using the latest version of ultralytics
- Glenn JocherUltralytics
Thanks for confirming you're using the latest version. Given that the issue is intermittent, it might be related to the specific bounding boxes or the image content. Please try running the model with a different set of bounding boxes or images to see if the issue persists. If it does, consider opening an issue on the GitHub repository with detailed information for further investigation.
nguyenvandang1998
Hi! I am using the FastSAM model and trying to obtain information about the bounding box and mask image of the object, but I don't know how to do it. I hope you can help me. Thank you very much!!
Currently, I can obtain information about the bounding box, but I still don't know how to get the mask image!!
- Glenn JocherUltralytics(edited)
Hi there! 🙌 To extract both bounding boxes and mask images using the FastSAM model, you would typically work with the
resultsobject returned by the model's prediction method. For the bounding boxes, you can access them directly as shown in the documentation or examples provided. For the mask images, since FastSAM is designed for real-time segmentation, the results should also include segmentation masks corresponding to detected objects.Here's a simplified way to access both:
from ultralytics import FastSAM

# Define your image source
source = 'path/to/your/image.jpg'

# Load the FastSAM model (ensure you've chosen the correct model path)
model = FastSAM('FastSAM-s.pt')  # or another appropriate model

# Perform inference
results = model(source)

# Accessing bounding boxes (assuming XYXY format)
boxes = results[0].boxes.xyxy

# Accessing segmentation masks
# The masks are directly associated with detected objects in the results
masks = results[0].masks

# To visualize or further process masks and boxes, you would iterate through these objects
To visualize or save the masks, you'd typically iterate over the
masksobject, and each mask can be processed according to your requirements (e.g., overlaying on the original image or saving as separate mask images).Remember, the exact attribute names (
boxes,masks) and methods might vary based on the model output specification, so it's always good to refer to the specific documentation or example codes for guidance.Hope this helps! Let us know if you have more questions. 😊
2