Intel OpenVINO Export
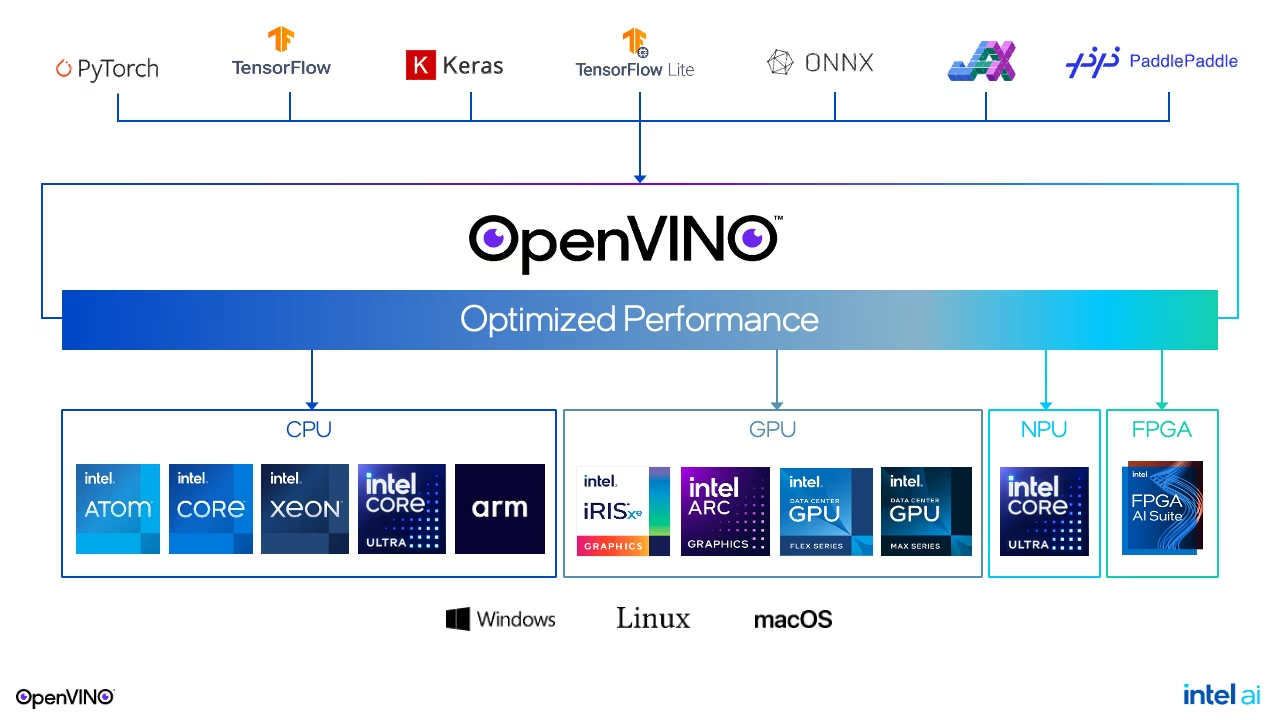
This guide covers exporting Ultralytics YOLO26 models to the OpenVINO format, which can provide up to 3x CPU speedup, as well as accelerating YOLO inference on Intel GPU and NPU hardware.
OpenVINO, short for Open Visual Inference & Neural Network Optimization toolkit, is Intel's toolkit for optimizing and deploying AI inference models. Even though the name contains Visual, OpenVINO also supports various additional tasks including language, audio, time series, etc.
Watch: How to Export Ultralytics YOLO26 to Intel OpenVINO Format for Faster Inference 🚀
Supported Tasks#
OpenVINO export supports all seven Ultralytics tasks. Semantic segmentation and depth estimation are available only with YOLO26, the only family that ships those heads.
Installation#
Install the OpenVINO export dependencies with:
pip install "ultralytics[export-openvino]"These dependencies are also included in ultralytics[export] and installed automatically when required by an export.
Usage Examples#
The OpenVINO format supports the Export, Predict, and Validate modes. Export your model, then load the exported model to run inference or validate its accuracy on Intel CPU, integrated/discrete GPU, or NPU.
from ultralytics import YOLO

# Load a YOLO26 model
model = YOLO("yolo26n.pt")

# Export the model to OpenVINO format
model.export(format="openvino") # creates 'yolo26n_openvino_model/'from ultralytics import YOLO
# Load the exported OpenVINO model
model = YOLO("yolo26n_openvino_model/")
# Run inference
results = model("https://ultralytics.com/images/bus.jpg")
# Run inference on a specific device, available devices: ["intel:gpu", "intel:npu", "intel:cpu"]
results = model("https://ultralytics.com/images/bus.jpg", device="intel:gpu")from ultralytics import YOLO
# Load the exported OpenVINO model
model = YOLO("yolo26n_openvino_model/")
# Validate accuracy on the COCO8 dataset
metrics = model.val(data="coco8.yaml")Export Arguments#
| Argument | Type | Default | Description |
|---|---|---|---|
format | str | 'openvino' | Target format for the exported model, defining compatibility with various deployment environments. |
imgsz | int or tuple | 640 | Desired image size for the model input. Can be an integer for square images or a tuple (height, width) for specific dimensions. |
quantize | int or str | None | Quantization precision: 16 (FP16) or 8 (INT8/PTQ; needs calibration data/fraction); 32/unset is FP32. Replaces the deprecated half/int8 flags. |
dynamic | bool | False | Allows dynamic input sizes, enhancing flexibility in handling varying image dimensions. |
nms | bool, optional | None | Select raw output (None, default), embedded NMS (True), or the NMS-free head (False). |
batch | int | 1 | Specifies export model batch inference size or the max number of images the exported model will process concurrently in predict mode. |
data | str | None | Path to the dataset YAML, essential for quantization; classification instead takes a dataset directory or a built-in dataset name. If omitted with quantize=8, Ultralytics selects the default calibration dataset for the model task. |
fraction | float, int, or list | 1.0 | Calibration subset as a ratio, image count, or [train, val, test] ratios/counts. Two-item lists leave test full, while 0 skips it. |
device | str | None | Specifies the device for exporting: CPU (device=cpu), MPS for Apple silicon (device=mps). |
For more details about the export process, visit the Ultralytics documentation page on exporting.
OpenVINO™ is compatible with most Intel® processors, but to ensure optimal performance:
-
Verify OpenVINO™ support Check whether your Intel® chip is officially supported by OpenVINO™ using Intel's compatibility list.
-
Identify your accelerator Determine if your processor includes an integrated NPU (Neural Processing Unit) or integrated GPU by consulting Intel's hardware guide.
-
Install the latest drivers If your chip supports an NPU or GPU but OpenVINO™ isn't detecting it, you may need to install or update the associated drivers. Follow the driver‑installation instructions to enable full acceleration.
By following these three steps, you can ensure OpenVINO™ runs optimally on your Intel® hardware.
Benefits of OpenVINO#
- Performance: OpenVINO delivers high-performance inference on Intel CPUs, integrated and discrete GPUs, and NPUs.
- Support for Heterogeneous Execution: OpenVINO provides an API to write once and deploy on any supported Intel hardware (CPU, GPU, NPU).
- Model Conversion: OpenVINO's model conversion API imports, converts, and optimizes models from popular deep learning frameworks such as PyTorch, TensorFlow, TensorFlow Lite, ONNX, and PaddlePaddle.
- Ease of Use: The toolkit comes with a large collection of tutorial notebooks (including YOLO26 optimization) teaching different aspects of the toolkit.
OpenVINO Export Structure#
When you export a model to OpenVINO format, it results in a directory containing the following:
- XML file: Describes the network topology.
- BIN file: Contains the weights and biases binary data.
- Metadata file:
metadata.yamlholds model metadata such as class names, image size, and task, which Ultralytics reads when loading the model.
You can use these files to run inference with the OpenVINO Runtime.
Using OpenVINO Export in Deployment#
Once your model is successfully exported to the OpenVINO format, you have two primary options for running inference:
-
Use the
ultralyticspackage, which provides a high-level API and wraps the OpenVINO Runtime. -
Use the native
openvinopackage for more advanced or customized control over inference behavior.
Inference with Ultralytics#
The ultralytics package runs inference on the exported OpenVINO model via the predict method. You can also specify the target device (e.g., intel:gpu, intel:npu, intel:cpu) using the device argument.
from ultralytics import YOLO

# Load the exported OpenVINO model
ov_model = YOLO("yolo26n_openvino_model/")  # the path of your exported OpenVINO model
# Run inference with the exported model
ov_model.predict(device="intel:gpu")  # specify the device you want to run inference on
This approach suits fast prototyping or deployment when you don't need full control over the inference pipeline.
Inference with OpenVINO Runtime#
The OpenVINO Runtime provides a unified API for inference across all supported Intel hardware. It also provides advanced capabilities like load balancing across Intel hardware and asynchronous execution.
Remember, you'll need the XML and BIN files as well as any application-specific settings like input size, scale factor for normalization, etc., to correctly set up and use the model with the Runtime.
In your deployment application, you would typically do the following steps:
- Initialize OpenVINO by creating
core = Core(). - Load the model using the
core.read_model()method. - Compile the model using the
core.compile_model()function. - Prepare the input (image, text, audio, etc.).
- Run inference using
compiled_model(input_data).
For more detailed steps and code snippets, refer to the OpenVINO documentation or API tutorial.
OpenVINO YOLO26 Benchmarks#
The Ultralytics team benchmarked YOLO26 across various model formats and precisions (FP32, FP16, and INT8), evaluating speed and accuracy on different Intel devices compatible with OpenVINO.
-
The benchmarking results below are for reference and might vary based on the exact hardware and software configuration of a system, as well as the current workload of the system at the time the benchmarks are run.
-
All benchmarks were run with
openvinoPython package version 2026.2.1. -
YOLO26 models on NPU are only supported on Intel® Core™ Ultra™ systems with 2xxV series and 3xx series and above.
Intel® Core™ Ultra#
The Intel® Core™ Ultra™ series combines CPU cores, an integrated GPU, and a dedicated Neural Processing Unit (NPU) in a single chip, so one system can handle traditional processing, GPU-accelerated workloads, and on-device AI inference.
This hybrid design lets OpenVINO run inference on the CPU, GPU, or NPU depending on the latency, throughput, and power needs of an application. The lineup ranges from energy-efficient designs to high-power variants marked by the "H" designation for laptops and compact form factors that need more compute.
Benchmarks below run on Intel® Core™ Ultra™ X7 358H, Intel® Core™ Ultra™ 7 258V and Intel® Core™ Ultra™ 7 155H at FP32, FP16 and INT8 precision.
Intel® Core™ Ultra™ X7 358H#
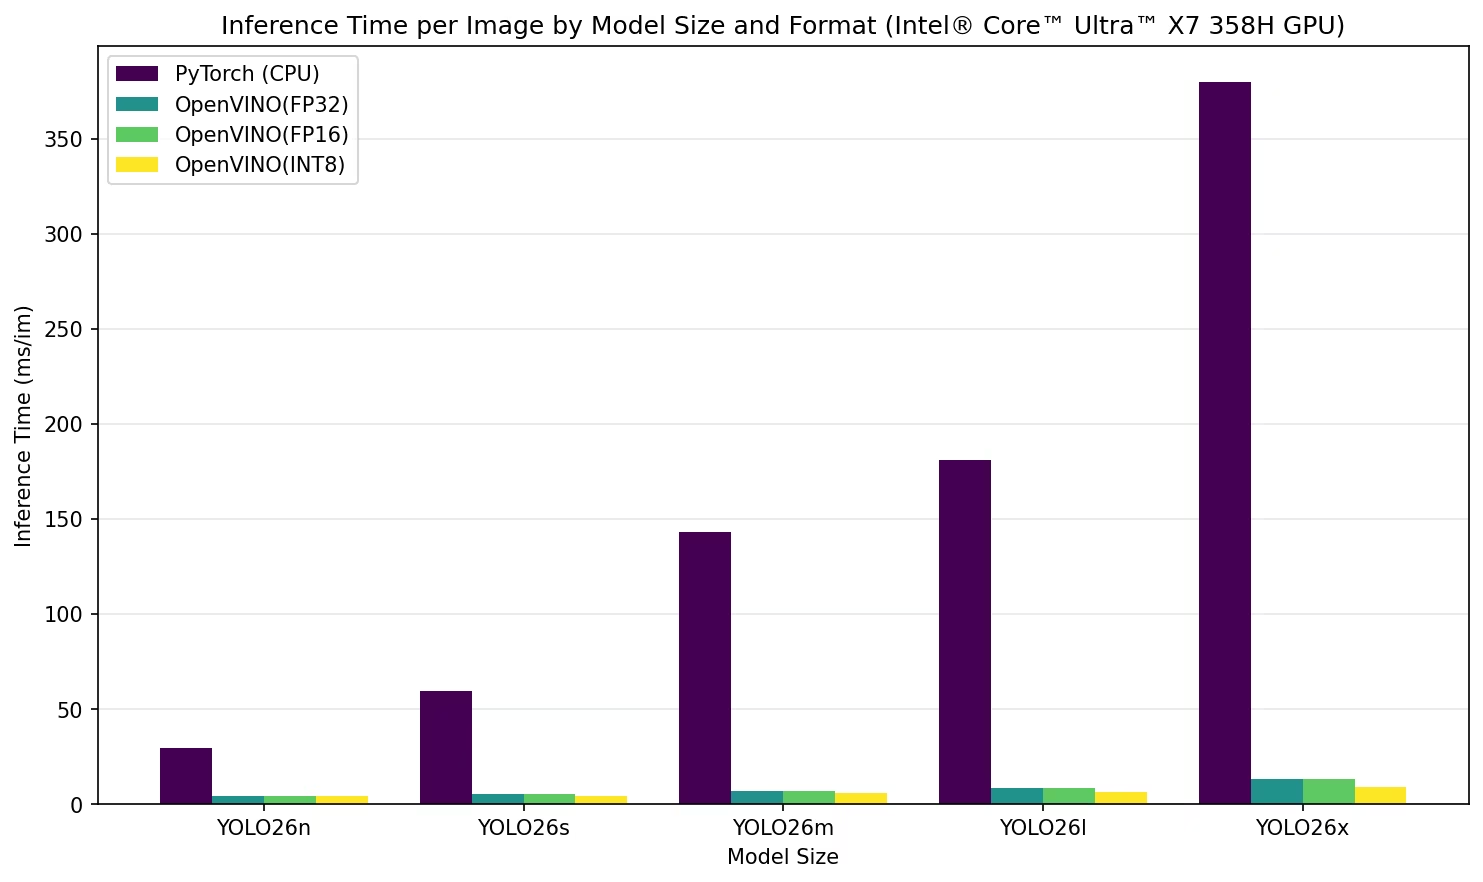
Detailed Benchmark Results
| Model | Format | Precision | Status | Size (MB) | metrics/mAP50-95(B) | Inference time (ms/im) |
|---|---|---|---|---|---|---|
| YOLO26n | PyTorch (CPU) | FP32 | ✅ | 5.3 | 0.4765 | 29.28 |
| YOLO26n | OpenVINO | FP32 | ✅ | 9.7 | 0.4762 | 4.09 |
| YOLO26n | OpenVINO | FP16 | ✅ | 5.1 | 0.4762 | 4.03 |
| YOLO26n | OpenVINO | INT8 | ✅ | 3.2 | 0.4634 | 4.24 |
| YOLO26s | PyTorch (CPU) | FP32 | ✅ | 19.5 | 0.5703 | 59.32 |
| YOLO26s | OpenVINO | FP32 | ✅ | 36.7 | 0.5616 | 5.08 |
| YOLO26s | OpenVINO | FP16 | ✅ | 18.7 | 0.5616 | 5.14 |
| YOLO26s | OpenVINO | INT8 | ✅ | 10.0 | 0.5462 | 4.47 |
| YOLO26m | PyTorch (CPU) | FP32 | ✅ | 42.2 | 0.6196 | 143.21 |
| YOLO26m | OpenVINO | FP32 | ✅ | 78.4 | 0.6166 | 7.1 |
| YOLO26m | OpenVINO | FP16 | ✅ | 39.5 | 0.6166 | 7.06 |
| YOLO26m | OpenVINO | INT8 | ✅ | 20.6 | 0.6055 | 5.61 |
| YOLO26l | PyTorch (CPU) | FP32 | ✅ | 50.7 | 0.6215 | 181.16 |
| YOLO26l | OpenVINO | FP32 | ✅ | 95.3 | 0.6205 | 8.45 |
| YOLO26l | OpenVINO | FP16 | ✅ | 48.1 | 0.6205 | 8.49 |
| YOLO26l | OpenVINO | INT8 | ✅ | 25.2 | 0.5938 | 6.25 |
| YOLO26x | PyTorch (CPU) | FP32 | ✅ | 113.2 | 0.6512 | 379.75 |
| YOLO26x | OpenVINO | FP32 | ✅ | 213.3 | 0.6568 | 13.03 |
| YOLO26x | OpenVINO | FP16 | ✅ | 107.1 | 0.6568 | 12.98 |
| YOLO26x | OpenVINO | INT8 | ✅ | 54.8 | 0.6385 | 8.74 |
Intel® Core™ Ultra™ 7 258V#
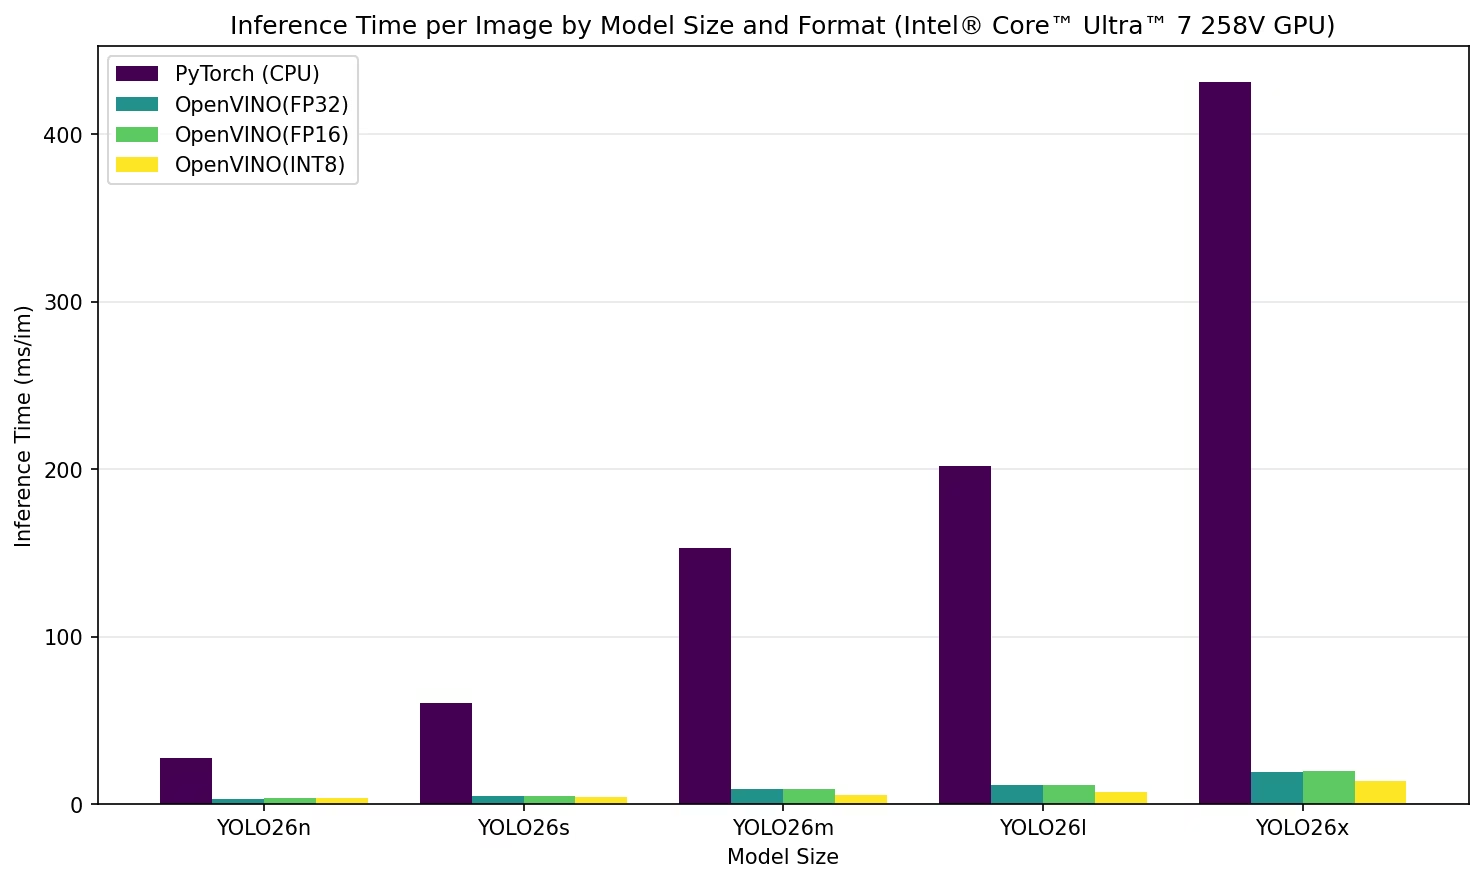
Detailed Benchmark Results
| Model | Format | Precision | Status | Size (MB) | metrics/mAP50-95(B) | Inference time (ms/im) |
|---|---|---|---|---|---|---|
| YOLO26n | PyTorch (CPU) | FP32 | ✅ | 5.3 | 0.4765 | 27.33 |
| YOLO26n | OpenVINO | FP32 | ✅ | 9.6 | 0.4764 | 3.33 |
| YOLO26n | OpenVINO | FP16 | ✅ | 5.1 | 0.4764 | 3.34 |
| YOLO26n | OpenVINO | INT8 | ✅ | 3.2 | 0.4634 | 3.46 |
| YOLO26s | PyTorch (CPU) | FP32 | ✅ | 19.5 | 0.5703 | 60.2 |
| YOLO26s | OpenVINO | FP32 | ✅ | 36.7 | 0.5616 | 4.66 |
| YOLO26s | OpenVINO | FP16 | ✅ | 18.6 | 0.5616 | 4.65 |
| YOLO26s | OpenVINO | INT8 | ✅ | 10.0 | 0.5462 | 3.99 |
| YOLO26m | PyTorch (CPU) | FP32 | ✅ | 42.2 | 0.6196 | 152.87 |
| YOLO26m | OpenVINO | FP32 | ✅ | 78.4 | 0.6168 | 9.03 |
| YOLO26m | OpenVINO | FP16 | ✅ | 39.5 | 0.6168 | 8.98 |
| YOLO26m | OpenVINO | INT8 | ✅ | 20.6 | 0.6055 | 5.7 |
| YOLO26l | PyTorch (CPU) | FP32 | ✅ | 50.7 | 0.6215 | 201.57 |
| YOLO26l | OpenVINO | FP32 | ✅ | 95.3 | 0.6203 | 11.32 |
| YOLO26l | OpenVINO | FP16 | ✅ | 48.1 | 0.6203 | 11.36 |
| YOLO26l | OpenVINO | INT8 | ✅ | 25.2 | 0.5938 | 7.45 |
| YOLO26x | PyTorch (CPU) | FP32 | ✅ | 113.2 | 0.6512 | 431.04 |
| YOLO26x | OpenVINO | FP32 | ✅ | 213.2 | 0.6568 | 19.08 |
| YOLO26x | OpenVINO | FP16 | ✅ | 107.1 | 0.6568 | 19.63 |
| YOLO26x | OpenVINO | INT8 | ✅ | 54.8 | 0.6385 | 13.69 |
Intel® Core™ Ultra™ 7 155H#
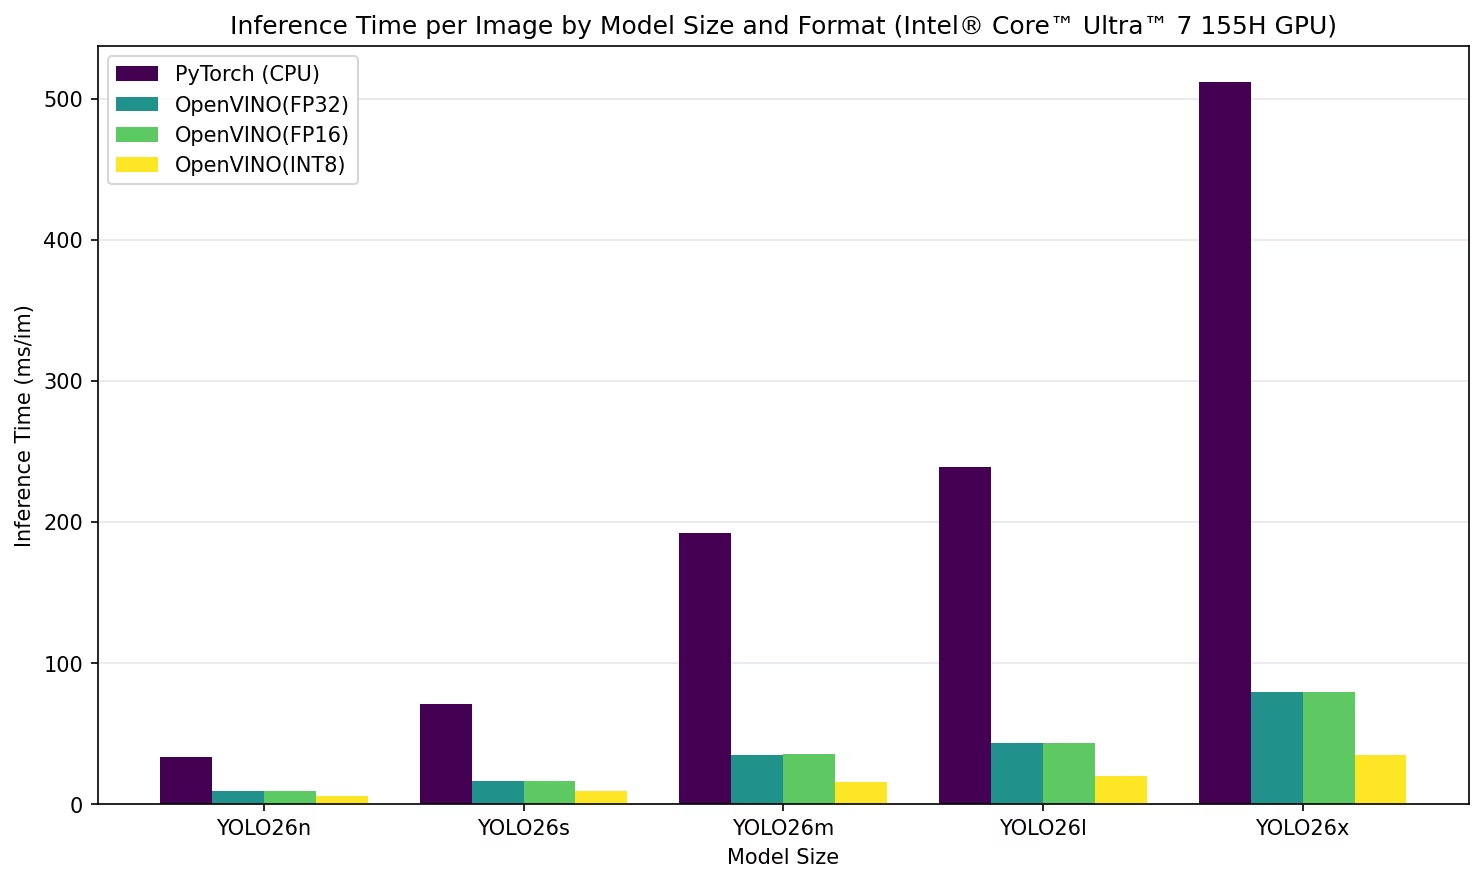
Detailed Benchmark Results
| Model | Format | Precision | Status | Size (MB) | metrics/mAP50-95(B) | Inference time (ms/im) |
|---|---|---|---|---|---|---|
| YOLO26n | PyTorch (CPU) | FP32 | ✅ | 5.3 | 0.4765 | 33.19 |
| YOLO26n | OpenVINO | FP32 | ✅ | 9.6 | 0.4758 | 9.13 |
| YOLO26n | OpenVINO | FP16 | ✅ | 5.1 | 0.4758 | 9.07 |
| YOLO26n | OpenVINO | INT8 | ✅ | 3.2 | 0.4573 | 5.79 |
| YOLO26s | PyTorch (CPU) | FP32 | ✅ | 19.5 | 0.5703 | 70.92 |
| YOLO26s | OpenVINO | FP32 | ✅ | 36.7 | 0.5616 | 16.37 |
| YOLO26s | OpenVINO | FP16 | ✅ | 18.6 | 0.5616 | 16.65 |
| YOLO26s | OpenVINO | INT8 | ✅ | 10.0 | 0.545 | 9.27 |
| YOLO26m | PyTorch (CPU) | FP32 | ✅ | 42.2 | 0.6196 | 192.45 |
| YOLO26m | OpenVINO | FP32 | ✅ | 78.4 | 0.6167 | 34.47 |
| YOLO26m | OpenVINO | FP16 | ✅ | 39.5 | 0.6167 | 35.71 |
| YOLO26m | OpenVINO | INT8 | ✅ | 20.6 | 0.6039 | 15.46 |
| YOLO26l | PyTorch (CPU) | FP32 | ✅ | 50.7 | 0.6215 | 239.19 |
| YOLO26l | OpenVINO | FP32 | ✅ | 95.3 | 0.621 | 43.24 |
| YOLO26l | OpenVINO | FP16 | ✅ | 48.1 | 0.621 | 43.4 |
| YOLO26l | OpenVINO | INT8 | ✅ | 25.2 | 0.5999 | 19.72 |
| YOLO26x | PyTorch (CPU) | FP32 | ✅ | 113.2 | 0.6512 | 511.89 |
| YOLO26x | OpenVINO | FP32 | ✅ | 213.2 | 0.6552 | 79.49 |
| YOLO26x | OpenVINO | FP16 | ✅ | 107.1 | 0.6552 | 79.45 |
| YOLO26x | OpenVINO | INT8 | ✅ | 54.8 | 0.642 | 34.66 |
Reproduce Our Results#
To reproduce the Ultralytics benchmarks above on all export formats, run this code:
from ultralytics import YOLO

# Load a YOLO26n PyTorch model
model = YOLO("yolo26n.pt")

# Benchmark YOLO26n speed and accuracy on the COCO128 dataset for all export formats
results = model.benchmark(data="coco128.yaml")
Note that benchmarking results might vary based on the exact hardware and software configuration of a system, as well as the current workload of the system at the time the benchmarks are run. For the most reliable results, use a dataset with a large number of images, such as COCO (data='coco.yaml', 5000 val images).
Conclusion#
The benchmarking results show the benefits of exporting YOLO26 models to the OpenVINO format. Across model sizes and Intel hardware, OpenVINO runs inference much faster than PyTorch while maintaining comparable accuracy.
By converting models to the OpenVINO format, developers can achieve significant performance improvements on Intel CPUs, GPUs, and NPUs, making it easier to deploy these models in real-world applications.
For more detailed information and instructions on using OpenVINO, refer to the official OpenVINO documentation.
FAQ#
Exporting YOLO26 models to the OpenVINO format can significantly enhance CPU speed and enable GPU and NPU accelerations on Intel hardware. To export, you can use either Python or CLI as shown below:
Examplefrom ultralytics import YOLO # Load a YOLO26n PyTorch model model = YOLO("yolo26n.pt") # Export the model model.export(format="openvino") # creates 'yolo26n_openvino_model/'For more information, refer to the export formats documentation.
Using Intel's OpenVINO toolkit with YOLO26 models offers several benefits:
- Performance: Achieve up to 3x speedup on CPU inference and use Intel GPUs and NPUs for acceleration.
- Model Conversion: Convert, optimize, and execute models from popular frameworks like PyTorch, TensorFlow, and ONNX.
- Ease of Use: A large collection of tutorial notebooks is available to help users get started, including ones for YOLO26.
- Heterogeneous Execution: Deploy models on various Intel hardware with a unified API.
For detailed performance comparisons, visit our benchmarks section.
After exporting a YOLO26n model to OpenVINO format, you can run inference using Python or CLI:
Examplefrom ultralytics import YOLO # Load the exported OpenVINO model ov_model = YOLO("yolo26n_openvino_model/") # Run inference results = ov_model("https://ultralytics.com/images/bus.jpg")Refer to our predict mode documentation for more details.
Ultralytics YOLO26 is optimized for real-time object detection with high accuracy and speed. Specifically, when combined with OpenVINO, YOLO26 provides:
- Up to 3x speedup on Intel CPUs
- Deployment on Intel GPUs and NPUs
- Consistent and comparable accuracy across various export formats
For in-depth performance analysis, check our detailed YOLO26 benchmarks on different hardware.
Yes, you can benchmark YOLO26 models in various formats including PyTorch, TorchScript, ONNX, and OpenVINO. Use the following code snippet to run benchmarks on your chosen dataset:
Examplefrom ultralytics import YOLO # Load a YOLO26n PyTorch model model = YOLO("yolo26n.pt") # Benchmark YOLO26n speed and accuracy on the COCO8 dataset for all export formats results = model.benchmark(data="coco8.yaml")For detailed benchmark results, refer to our benchmarks section and export formats documentation.


Comments23
Ask a question, share your results, or help someone else.
Heyujie96
how can i export a trained cls or obb kind model to openvino kind
EduardoNew
I encountered some difficulties while trying to run the official video demo. Here is my code:
from ultralytics import YOLO
def main(): # Load a YOLOv8n PyTorch model model = YOLO("yolov8n.pt")
# Export the model
model.export(format="openvino")  # creates 'yolov8n_openvino_model/'

# Load the exported OpenVINO model with explicit task definition
ov_model = YOLO("yolov8n_openvino_model\\", task='detect')  # Explicitly define task as 'detect'

# Run inference
results_original = model("D:\\python_YOLO_test\\bus.jpg")

# Run ov inference
results_ov = ov_model("D:\\python_YOLO_test\\bus.jpg")
if name == "main": main() Additional notes: My environment is openvino==2024.0.0, and I executed pip install --upgrade torch ultralytics.
The issue I encountered is as follows:
Results saved to D:\python_YOLO_test Ultralytics YOLOv8.2.57 🚀 Python-3.11.9 torch-2.1.1+cu118 CPU (11th Gen Intel Core(TM) i7-11800H 2.30GHz) YOLOv8n summary (fused): 168 layers, 3,151,904 parameters, 0 gradients, 8.7 GFLOPs
PyTorch: starting from 'yolov8n.pt' with input shape (1, 3, 640, 640) BCHW and output shape(s) (1, 84, 8400) (6.2 MB)
OpenVINO: starting export with openvino 2024.0.0-14509-34caeefd078-releases/2024/0... OpenVINO: export success ✅ 2.8s, saved as 'yolov8n_openvino_model' (12.3 MB)
Export complete (5.2s) Results saved to D:\python_YOLO_test Predict: yolo predict task=detect model=yolov8n_openvino_model imgsz=640
Validate: yolo val task=detect model=yolov8n_openvino_model imgsz=640 data=coco.yaml
Visualize: https://netron.appimage 1/1 D:\python_YOLO_test\bus.jpg: 640x480 4 persons, 1 bus, 1 stop sign, 324.0ms Speed: 24.0ms preprocess, 324.0ms inference, 21.0ms postprocess per image at shape (1, 3, 640, 480) Loading yolov8n_openvino_model for OpenVINO inference... Using OpenVINO LATENCY mode for batch=1 inference...
Process finished with exit code -1073741819 (0xC0000005)
Process finished with exit code -1073740791 (0xC0000409) The model was successfully exported but did not perform inference, instead, it terminated directly. How should I resolve this issue?
 Glenn JocherUltralytics(edited)
@EduardoNew the exit code 0xC0000005 often indicates a memory access violation. Let's address this step-by-step:
-
Path Format: Try using forward slashes in your OpenVINO model path:
"yolov8n_openvino_model/"instead of backslashes. -
OpenVINO Version: Ultralytics requires
openvino>=2024.0.0. Try upgrading to a recent release:
pip install -U openvino- Hardware Compatibility: Ensure you have the latest Intel drivers installed from Intel's official site.
If issues persist, please create a Minimum Reproducible Example and open a GitHub Issue following our bug report guidelines. We'll be happy to investigate further!
-
Ranjith3436
You mentioned that the core CPU inference model takes 23.53 ms. I would like to know if the processing time decreases when we increase the number of CPU cores ? currently i am using 12 thread CPU.
- Glenn JocherUltralytics
@Ranjith3436 increasing the number of CPU cores can potentially reduce processing time, as it allows for parallel processing, but the actual speedup will depend on the model's ability to leverage multi-threading effectively.
how do i can know about model's ability?
- Glenn JocherUltralytics
To assess a model's ability to utilize multiple CPU cores, you can check its support for multi-threading or parallel processing in the documentation or by running benchmarks on your hardware configuration.
kimchi2020
hey i am working on object detection in videos and came across openvino that helps in increasing speed. how can i use openvino and yolov8 together to find objects in a video
- Glenn JocherUltralytics
@kimchi2020 hi there! It's great to hear that you're exploring OpenVINO to enhance the speed of your object detection tasks in videos. OpenVINO can indeed provide significant performance improvements, especially on Intel hardware.
To get started with using YOLOv8 and OpenVINO together, follow these steps:
Exporting YOLOv8 to OpenVINO Format
-
Export the Model: You can export your YOLOv8 model to the OpenVINO format using the following Python code:
from ultralytics import YOLO

# Load a YOLOv8n PyTorch model
model = YOLO("yolov8n.pt")

# Export the model to OpenVINO format
model.export(format="openvino")  # creates 'yolov8n_openvino_model/'
Alternatively, you can use the CLI:
yolo export model=yolov8n.pt format=openvino # creates 'yolov8n_openvino_model/' -
Run Inference with the Exported Model: After exporting, you can run inference using the exported OpenVINO model. Here’s how you can do it in Python:
from ultralytics import YOLO

# Load the exported OpenVINO model
ov_model = YOLO("yolov8n_openvino_model/")

# Run inference
results = ov_model("https://ultralytics.com/images/bus.jpg")
Or using the CLI:
yolo predict model=yolov8n_openvino_model source='https://ultralytics.com/images/bus.jpg'
Running Inference on Videos
To process videos, you can modify the inference code to read frames from a video file and run the model on each frame. Here’s an example in Python:
import cv2
from ultralytics import YOLO

# Load the exported OpenVINO model
model = YOLO("yolov8n_openvino_model/")

# Open the video file
video_path = "path/to/your/video.mp4"
cap = cv2.VideoCapture(video_path)

# Loop through the video frames
while cap.isOpened():
    ret, frame = cap.read()
    if not ret:
        break

    # Run inference on the frame
    results = model(frame)

    # Visualize the results on the frame
    annotated_frame = results[0].plot()

    # Display the annotated frame
    cv2.imshow("YOLOv8 OpenVINO Inference", annotated_frame)

    # Break the loop if 'q' is pressed
    if cv2.waitKey(1) & 0xFF == ord('q'):
        break

# Release the video capture object and close the display window
cap.release()
cv2.destroyAllWindows()
Additional Resources
For more detailed information and advanced usage, you can refer to the OpenVINO documentation. This guide covers everything from exporting models to running inference and optimizing performance.
Feel free to reach out if you have any more questions. Happy coding! 🚀
-
Traceback (most recent call last): File "/home/kimchi/Desktop/yolov8/onnx.py", line 18, in results = model(frame) ^^^^^^^^^^^^ File "/home/kimchi/Desktop/yolov8/myvenv/lib/python3.12/site-packages/ultralytics/engine/model.py", line 174, in call return self.predict(source, stream, **kwargs) ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^ File "/home/kimchi/Desktop/yolov8/myvenv/lib/python3.12/site-packages/ultralytics/engine/model.py", line 442, in predict return self.predictor.predict_cli(source=source) if is_cli else self.predictor(source=source, stream=stream) ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^ File "/home/kimchi/Desktop/yolov8/myvenv/lib/python3.12/site-packages/ultralytics/engine/predictor.py", line 168, in call return list(self.stream_inference(source, model, *args, **kwargs)) # merge list of Result into one ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^ File "/home/kimchi/Desktop/yolov8/myvenv/lib/python3.12/site-packages/torch/utils/_contextlib.py", line 35, in generator_context response = gen.send(None) ^^^^^^^^^^^^^^ File "/home/kimchi/Desktop/yolov8/myvenv/lib/python3.12/site-packages/ultralytics/engine/predictor.py", line 234, in stream_inference self.model.warmup(imgsz=(1 if self.model.pt or self.model.triton else self.dataset.bs, 3, *self.imgsz)) File "/home/kimchi/Desktop/yolov8/myvenv/lib/python3.12/site-packages/ultralytics/nn/autobackend.py", line 626, in warmup import torchvision # noqa (import here so torchvision import time not recorded in postprocess time) ^^^^^^^^^^^^^^^^^^ File "/home/kimchi/Desktop/yolov8/myvenv/lib/python3.12/site-packages/torchvision/init.py", line 6, in from torchvision import _meta_registrations, datasets, io, models, ops, transforms, utils File "/home/kimchi/Desktop/yolov8/myvenv/lib/python3.12/site-packages/torchvision/models/init.py", line 2, in from .convnext import * File "/home/kimchi/Desktop/yolov8/myvenv/lib/python3.12/site-packages/torchvision/models/convnext.py", line 8, in from ..ops.misc import Conv2dNormActivation, Permute File "/home/kimchi/Desktop/yolov8/myvenv/lib/python3.12/site-packages/torchvision/ops/init.py", line 1, in from ._register_onnx_ops import _register_custom_op File "/home/kimchi/Desktop/yolov8/myvenv/lib/python3.12/site-packages/torchvision/ops/_register_onnx_ops.py", line 5, in from torch.onnx import symbolic_opset11 as opset11 File "/home/kimchi/Desktop/yolov8/myvenv/lib/python3.12/site-packages/torch/onnx/init.py", line 59, in from ._internal.onnxruntime import ( File "/home/kimchi/Desktop/yolov8/myvenv/lib/python3.12/site-packages/torch/onnx/_internal/onnxruntime.py", line 36, in import onnx File "/home/kimchi/Desktop/yolov8/onnx.py", line 18, in results = model(frame) ^^^^^^^^^^^^ File "/home/kimchi/Desktop/yolov8/myvenv/lib/python3.12/site-packages/ultralytics/engine/model.py", line 174, in call return self.predict(source, stream, **kwargs) ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^ File "/home/kimchi/Desktop/yolov8/myvenv/lib/python3.12/site-packages/ultralytics/engine/model.py", line 442, in predict return self.predictor.predict_cli(source=source) if is_cli else self.predictor(source=source, stream=stream) ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^ File "/home/kimchi/Desktop/yolov8/myvenv/lib/python3.12/site-packages/ultralytics/engine/predictor.py", line 168, in call return list(self.stream_inference(source, model, *args, **kwargs)) # merge list of Result into one ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^ File "/home/kimchi/Desktop/yolov8/myvenv/lib/python3.12/site-packages/torch/utils/_contextlib.py", line 35, in generator_context response = gen.send(None) ^^^^^^^^^^^^^^ File "/home/kimchi/Desktop/yolov8/myvenv/lib/python3.12/site-packages/ultralytics/engine/predictor.py", line 261, in stream_inference self.results = self.postprocess(preds, im, im0s) ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^ File "/home/kimchi/Desktop/yolov8/myvenv/lib/python3.12/site-packages/ultralytics/models/yolo/detect/predict.py", line 25, in postprocess preds = ops.non_max_suppression( ^^^^^^^^^^^^^^^^^^^^^^^^ File "/home/kimchi/Desktop/yolov8/myvenv/lib/python3.12/site-packages/ultralytics/utils/ops.py", line 291, in non_max_suppression i = torchvision.ops.nms(boxes, scores, iou_thres) # NMS ^^^^^^^^^^^^^^^ AttributeError: partially initialized module 'torchvision' has no attribute 'ops' (most likely due to a circular import). Did you mean: 'os'?
I am getting this error, how to get rid of it and what does it mean
- Glenn JocherUltralytics
Hi @kimchi2020,
Thank you for reaching out! The error you're encountering seems to be related to a circular import issue with the
torchvisionlibrary. This can happen if there's a naming conflict or an import loop in your code.Steps to Resolve the Issue:
-
Check for Naming Conflicts: Ensure that your script name (
onnx.py) is not conflicting with any library names. Rename your script to something unique, likerun_inference.py. -
Verify Installation: Make sure you have the latest versions of
torch,torchvision, andultralyticsinstalled. You can update them using:pip install --upgrade torch torchvision ultralytics -
Reproduce the Issue: If the issue persists, please provide a minimum reproducible example. This helps us diagnose the problem more effectively. You can refer to our guide on creating a reproducible example here: Minimum Reproducible Example.
Example Code for Inference with OpenVINO:
Here's a quick example of how to export your YOLOv8 model to OpenVINO and run inference on a video:
import cv2
from ultralytics import YOLO

# Load a YOLOv8n PyTorch model
model = YOLO("yolov8n.pt")

# Export the model to OpenVINO format
model.export(format="openvino")  # creates 'yolov8n_openvino_model/'

# Load the exported OpenVINO model
ov_model = YOLO("yolov8n_openvino_model/")

# Open the video file
video_path = "path/to/your/video.mp4"
cap = cv2.VideoCapture(video_path)

# Loop through the video frames
while cap.isOpened():
    ret, frame = cap.read()
    if not ret:
        break

    # Run inference on the frame
    results = ov_model(frame)

    # Visualize the results on the frame
    annotated_frame = results[0].plot()

    # Display the annotated frame
    cv2.imshow("YOLOv8 OpenVINO Inference", annotated_frame)

    # Break the loop if 'q' is pressed
    if cv2.waitKey(1) & 0xFF == ord('q'):
        break

# Release the video capture object and close the display window
cap.release()
cv2.destroyAllWindows()
For more detailed information on exporting and using OpenVINO, please refer to our OpenVINO Integration Guide.
Feel free to reach out if you have any more questions or need further assistance. Happy coding! 🚀
-
YA12SHYAM
Hi @glenn-jocher , what if i want to use intel GPU's for the inference, using device=GPU doesn't seems to works , it looks for cuda i.e nvidia gpu
- Glenn JocherUltralytics(edited)
To use Intel GPUs for inference, export your YOLOv8 model to OpenVINO format with
model.export(format="openvino"), then run inference with the exported model and select the GPU withdevice="intel:gpu", for exampleov_model("bus.jpg", device="intel:gpu"). For more details, please refer to the OpenVINO integration guide. ok, just to confirm i can't use ultralytics python api for inference with intel gpu like i usually do within the ultralytics ecosystem for example ?
from ultralytics import YOLO
model =  YOLO(path/to/model)
here the path/to/model works with onnx, engine, opnevino;s xml , but it use cpu in case of openvino , i want to use my intel GPU
- Glenn JocherUltralytics(edited)
@YA12SHYAM to use Intel GPUs with YOLOv8, export your model to OpenVINO format and select the GPU at inference with
device="intel:gpu", e.g.model("bus.jpg", device="intel:gpu"). For detailed steps, refer to the OpenVINO integration guide.
kanishkasw
Hi Im getting the following error when attempting to convert the model to openVino. Tried with both 2024.1.0 and 2024.0.0. Im on ubuntu 20.04 with python 3.8 $ yolo export model=runs/classify/train/weights/best.pt format=openvino Ultralytics YOLOv8.2.31 🚀 Python-3.8.10 torch-2.3.1+cu121 CPU (Intel Core(TM) i9-7900X 3.30GHz) YOLOv8n-cls summary (fused): 73 layers, 1438723 parameters, 0 gradients, 3.3 GFLOPs
PyTorch: starting from 'runs/classify/train/weights/best.pt' with input shape (1, 3, 320, 320) BCHW and output shape(s) (1, 3) (2.8 MB) OpenVINO: export failure ❌ 0.0s: module 'openvino' has no attribute 'version' Traceback (most recent call last): File "/home/Kanishka/v5.0/YOLOV8_classification/.venv/bin/yolo", line 8, in sys.exit(entrypoint()) File "/home/Kanishka/v5.0/YOLOV8_classification/.venv/lib/python3.8/site-packages/ultralytics/cfg/init.py", line 591, in entrypoint getattr(model, mode)(**overrides) # default args from model File "/home/Kanishka/v5.0/YOLOV8_classification/.venv/lib/python3.8/site-packages/ultralytics/engine/model.py", line 602, in export return Exporter(overrides=args, _callbacks=self.callbacks)(model=self.model) File "/home/Kanishka/v5.0/YOLOV8_classification/.venv/lib/python3.8/site-packages/torch/utils/_contextlib.py", line 115, in decorate_context return func(*args, **kwargs) File "/home/Kanishka/v5.0/YOLOV8_classification/.venv/lib/python3.8/site-packages/ultralytics/engine/exporter.py", line 308, in call f[3], _ = self.export_openvino() File "/home/Kanishka/v5.0/YOLOV8_classification/.venv/lib/python3.8/site-packages/ultralytics/engine/exporter.py", line 142, in outer_func raise e File "/home/Kanishka/v5.0/YOLOV8_classification/.venv/lib/python3.8/site-packages/ultralytics/engine/exporter.py", line 137, in outer_func f, model = inner_func(*args, **kwargs) File "/home/Kanishka/v5.0/YOLOV8_classification/.venv/lib/python3.8/site-packages/ultralytics/engine/exporter.py", line 454, in export_openvino LOGGER.info(f"\n{prefix} starting export with openvino {ov.version}...") AttributeError: module 'openvino' has no attribute 'version'
 Paula DerrengerUltralytics(edited)
@kanishkasw hi there,
Thank you for reaching out and providing detailed information about the issue you're encountering. It looks like you're experiencing an error when attempting to export your model to OpenVINO format. Let's work through this together.
First, let's ensure that you are using the latest versions of
torchandultralytics. Please run the following commands to update your packages:pip install --upgrade torch ultralyticsNext, it seems the error is related to the OpenVINO package. The error message
module 'openvino' has no attribute '__version__'suggests there might be an issue with the OpenVINO installation. Please make sure you have a recent version of OpenVINO installed (Ultralytics requiresopenvino>=2024.0.0). You can install it using the following command:pip install -U openvinoOnce you've updated the packages, try exporting the model again:
yolo export model=runs/classify/train/weights/best.pt format=openvinoIf the issue persists, could you please provide a minimum reproducible example? This will help us investigate the problem more effectively. You can find guidance on creating a minimum reproducible example here: Minimum Reproducible Example.
Additionally, here's a Python example to ensure everything is set up correctly:
from ultralytics import YOLO

# Load a YOLOv8n PyTorch model
model = YOLO("runs/classify/train/weights/best.pt")

# Export the model to OpenVINO format
model.export(format="openvino")  # creates 'best_openvino_model/'

# Load the exported OpenVINO model
ov_model = YOLO("best_openvino_model/")

# Run inference
results = ov_model("https://ultralytics.com/images/bus.jpg")
For more detailed instructions on using OpenVINO, please refer to our OpenVINO Integration Guide.
Feel free to reach out if you have any further questions or run into any other issues. We're here to help! 😊
renato-rodrig
hello everything is fine? I have a question about the results exposed in the article above. Is the time shown in the graphs in relation to the inference time that the model takes to return the detections or is it the time for image reading, image pre-processing and model inference? I ask this because on my computer (intel core i7 12 generation CPU) the yolov8n model ran with an inference time of 40ms and the gain from using OpenVINO was not that great.
- Paula DerrengerUltralytics
@renato-rodrig hello! 👋 Regarding your question about the times shown in the graphs, they typically refer to the total inference time, which includes the actual model inference as well as the time taken for pre-processing the input data (like image reading and resizing).
The difference you observed with OpenVINO on your Intel Core i7 may vary due to several factors such as the specific configuration of your system, the type of tasks being run, and the optimizations that the YOLOv8n model can leverage on that platform. Generally, OpenVINO tends to show more significant performance gains on integrated Intel GPUs and some specific CPU configurations.
If you haven't seen a major performance improvement, you might want to look into further tuning your OpenVINO deployment or explore using other optimization techniques provided by OpenVINO. Additionally, ensure all drivers and software components are up to date for optimal performance.
Here’s a quick example of ensuring you're using the model in the most optimized manner:
from ultralytics import YOLO

# Load YOLOv8n PyTorch model
model = YOLO('yolov8n.pt')

# Export the model to OpenVINO
model.export(format='openvino')  # Creates 'yolov8n_openvino_model/'

# Load the exported OpenVINO model
ov_model = YOLO('yolov8n_openvino_model/')

# Run inference to see if performance improves
results = ov_model('https://ultralytics.com/images/bus.jpg')
Feel free to experiment with different configurations and settings! 😊
1
YouROS12
I wanna do inferences with my exported pre-trained yolov8 model using Raspberry PI with a Neural Network Computing 2 (NCS2) plugged in.. but its doesn't support opset 11 or above.. only opset10.. I specified onnx opset to 10 and convert it to Openvino but it didn't work.
Anyway please to export openvino model directly in opset10 ? Does even yolov8 support this specified opset format ?
Thank you.
- Glenn JocherUltralytics(edited)
@YouROS12 the current OpenVINO export no longer goes through ONNX: Ultralytics converts the PyTorch model directly to OpenVINO IR with
openvino.convert_model, so the ONNXopsetargument does not apply and the oldmoModel Optimizer step isn't needed. Export with:from ultralytics import YOLO # Load a pretrained YOLOv8 model model = YOLO('yolov8n.pt') # Export the model to OpenVINO model.export(format='openvino') # creates 'yolov8n_openvino_model/'The export requires
openvino>=2024.0.0. If your target requires an older OpenVINO that cannot load these models, you can still trymodel.export(format='onnx', opset=10)and convert the ONNX file with that toolkit's own tools, but some YOLOv8 operations may not be supported in older opsets, which could lead to errors during export or inference. Where can I find documentation about YOLOv8's operations with opset 10 ? Updating OpenVINO toolkit is not an option because NCS2 works only at opset 10 and lower.
- Paula DerrengerUltralytics
@YouROS12 the documentation for ONNX opset versions and the operations they support can be found on the ONNX GitHub repository or the official ONNX documentation. However, there isn't specific documentation for YOLOv8's operations with opset 10, as this would be a combination of YOLOv8's implementation details and ONNX's opset specifications.
To check which operations are supported in opset 10, you can refer to the ONNX Operators documentation for that specific version. This documentation lists all the operators available in opset 10 and their details.
For YOLOv8, you would need to look at the model's architecture and identify which operations are used. Then, cross-reference these operations with the ONNX opset 10 documentation to see if they are supported. If certain operations are not supported in opset 10, you might need to modify the model or the export script to use alternative operations that are compatible with opset 10.
Since updating OpenVINO is not an option for you, if you find that YOLOv8 uses operations not supported in opset 10, you might need to consider using a different model architecture that is compatible with opset 10, or reach out to the community or Ultralytics for further assistance on how to proceed with your specific use case and hardware constraints.