xView 데이터셋#
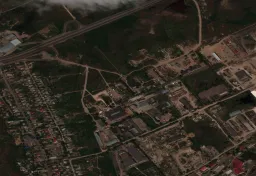
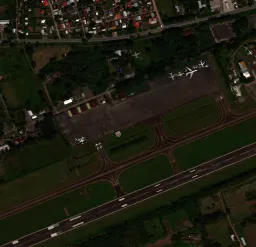
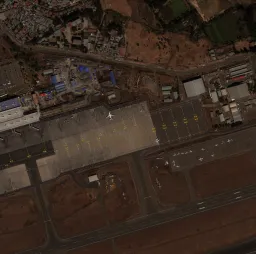
xView 데이터셋은 공개적으로 이용 가능한 최대 규모의 위성 이미지 벤치마크 중 하나입니다. 객체 탐지를 위해 1,400km²가 넘는 0.3m WorldView-3 이미지에서 60개 클래스에 걸쳐 100만 개 이상의 객체 인스턴스를 제공하며, 바운딩 박스 주석이 지정되어 있습니다. 미국 국가지리정보국(NGA)이 DIUx xView 2018 Challenge를 위해 공개했으며, 약 20.7GB를 수동으로 다운로드해야 합니다.
이 데이터셋은 네 가지 컴퓨터 비전 분야의 한계를 넓히기 위해 제작되었습니다:
- 탐지에 필요한 최소 해상도 낮추기
- 학습 효율성 향상
- 더 많은 객체 클래스 발견 지원
- 세분화된 클래스 탐지 개선
COCO와 같은 벤치마크를 기반으로 하는 xView는 지상 사진보다 객체가 훨씬 작고 빽빽하게 분포하는 항공 시점 이미지를 대상으로 합니다.
xView 데이터셋은 자동으로 다운로드되지 않습니다. DIUx xView 2018 Challenge 웹사이트에 가입하여 train_images.zip (~15 GB), train_labels.zip, val_images.zip (~5 GB)를 다운로드한 다음, datasets/xView/ 아래에 압축을 풀어 다음 항목이 포함되도록 하세요:
datasets/xView/
├── train_images/          # 847 TIF satellite images
├── val_images/            # 282 TIF images (no public labels)
└── xView_train.geojson    # bounding-box annotations
첫 학습 실행 시 Ultralytics는 GeoJSON 주석을 YOLO 형식으로 변환하고, 라벨이 지정된 이미지를 학습 세트와 검증 세트로 약 90/10 비율에 따라 자동 분할하므로 수동 변환이 필요하지 않습니다.
주요 기능#
- 세분화된 클래스: 항공기, 차량, 철도 차량, 선박, 건설 장비, 건물에 걸친 60개 객체 클래스이며, 이 중 상당수는 크기가 작고 드물며 시각적으로 서로 유사합니다.
- 고해상도: WorldView-3 위성에서 수집한 지상 표본 거리 0.3m 이미지입니다.
- 고밀도 주석: 1,400km²가 넘는 이미지에서 100만 개 이상의 객체 인스턴스에 모두 수평 바운딩 박스 라벨이 지정되어 있습니다.
- 자동 변환: Ultralytics 다운로드 스크립트는 처음 사용할 때 원본 GeoJSON 라벨을 YOLO 형식으로 변환하고 학습/검증 세트를 생성합니다.
데이터셋 구조#
xView 이미지는 TIF 형식의 대형 위성 장면이며, 공개 라벨이 포함된 이미지는 학습 이미지 847장뿐입니다. 챌린지 검증 이미지 282장에는 라벨이 없습니다. 따라서 Ultralytics xView.yaml 구성은 처음 사용할 때 라벨이 지정된 이미지를 자동으로 분할합니다:
| 분할 | 이미지 | 설명 |
|---|---|---|
| 학습 | 847장의 약 90% | autosplit_train.txt에 나열되며 첫 실행 시 생성되는 라벨 지정 이미지 |
| 검증 | 847장의 약 10% | autosplit_val.txt에 나열되며 평가에 사용되는 라벨 지정 이미지 |
60개 클래스에는 Fixed-wing Aircraft, Cargo Plane, Small Car, Bus, Locomotive, Maritime Vessel, Excavator, Building, Aircraft Hangar, Storage Tank와 같은 세분화된 카테고리가 포함됩니다. 전체 목록은 아래의 데이터셋 YAML에 있습니다. 변환 중에는 원본 챌린지 클래스 ID(11–94)를 연속된 인덱스 0–59로 다시 매핑합니다.
응용 분야#
xView의 세분화된 클래스와 고해상도 항공 시점은 원격 탐사 분야의 딥러닝 모델 학습 및 평가를 위한 표준 벤치마크로 활용됩니다. 일반적인 응용 분야는 다음과 같습니다:
- 군사 및 방위 정찰
- 도시 계획 및 개발
- 환경 모니터링
- 재해 대응 및 평가
- 인프라 매핑 및 관리
다른 항공 이미지 벤치마크는 드론에 초점을 둔 VisDrone 데이터셋 또는 방향성 박스를 사용하는 DOTA-v2 데이터셋을 참조하세요.
데이터셋 YAML#
xView.yaml 파일은 데이터셋 구성, 즉 데이터셋 경로, 60개 클래스 이름, GeoJSON 주석을 변환하고 자동 분할을 생성하는 다운로드 스크립트를 정의합니다. 이 파일은 https://github.com/ultralytics/ultralytics/blob/main/ultralytics/cfg/datasets/xView.yaml의 Ultralytics 저장소에서 관리됩니다.
# Ultralytics 🚀 AGPL-3.0 License - https://ultralytics.com/license

# DIUx xView 2018 Challenge dataset https://challenge.xviewdataset.org by U.S. National Geospatial-Intelligence Agency (NGA)
# --------  Download and extract data manually to `datasets/xView` before running the train command.  --------
# Documentation: https://docs.ultralytics.com/datasets/detect/xview
# Example usage: yolo train data=xView.yaml
# parent
# ├── ultralytics
# └── datasets
#     └── xView ← downloads here (20.7 GB)

# Train/val/test sets as 1) dir: path/to/imgs, 2) file: path/to/imgs.txt, or 3) list: [path/to/imgs1, path/to/imgs2, ..]
path: xView # dataset root dir
train: images/autosplit_train.txt # train images (relative to 'path') 90% of 847 train images
val: images/autosplit_val.txt # val images (relative to 'path') 10% of 847 train images

# Classes
names:
  0: Fixed-wing Aircraft
  1: Small Aircraft
  2: Cargo Plane
  3: Helicopter
  4: Passenger Vehicle
  5: Small Car
  6: Bus
  7: Pickup Truck
  8: Utility Truck
  9: Truck
  10: Cargo Truck
  11: Truck w/Box
  12: Truck Tractor
  13: Trailer
  14: Truck w/Flatbed
  15: Truck w/Liquid
  16: Crane Truck
  17: Railway Vehicle
  18: Passenger Car
  19: Cargo Car
  20: Flat Car
  21: Tank car
  22: Locomotive
  23: Maritime Vessel
  24: Motorboat
  25: Sailboat
  26: Tugboat
  27: Barge
  28: Fishing Vessel
  29: Ferry
  30: Yacht
  31: Container Ship
  32: Oil Tanker
  33: Engineering Vehicle
  34: Tower crane
  35: Container Crane
  36: Reach Stacker
  37: Straddle Carrier
  38: Mobile Crane
  39: Dump Truck
  40: Haul Truck
  41: Scraper/Tractor
  42: Front loader/Bulldozer
  43: Excavator
  44: Cement Mixer
  45: Ground Grader
  46: Hut/Tent
  47: Shed
  48: Building
  49: Aircraft Hangar
  50: Damaged Building
  51: Facility
  52: Construction Site
  53: Vehicle Lot
  54: Helipad
  55: Storage Tank
  56: Shipping container lot
  57: Shipping Container
  58: Pylon
  59: Tower

# Download script/URL (optional) ---------------------------------------------------------------------------------------
download: |
  import json
  from pathlib import Path
  import shutil

  import numpy as np
  from PIL import Image

  from ultralytics.utils import TQDM
  from ultralytics.data.split import autosplit
  from ultralytics.utils.ops import xyxy2xywhn

  def convert_labels(fname=Path("xView/xView_train.geojson")):
      """Convert xView GeoJSON labels to YOLO format (classes 0-59) and save them as text files."""
      path = fname.parent
      with open(fname, encoding="utf-8") as f:
          print(f"Loading {fname}...")
          data = json.load(f)

      # Make dirs
      labels = path / "labels" / "train"
      shutil.rmtree(labels, ignore_errors=True)
      labels.mkdir(parents=True, exist_ok=True)

      # xView classes 11-94 to 0-59
      xview_class2index = [-1, -1, -1, -1, -1, -1, -1, -1, -1, -1, -1, 0, 1, 2, -1, 3, -1, 4, 5, 6, 7, 8, -1, 9, 10, 11,
                           12, 13, 14, 15, -1, -1, 16, 17, 18, 19, 20, 21, 22, -1, 23, 24, 25, -1, 26, 27, -1, 28, -1,
                           29, 30, 31, 32, 33, 34, 35, 36, 37, -1, 38, 39, 40, 41, 42, 43, 44, 45, -1, -1, -1, -1, 46,
                           47, 48, 49, -1, 50, 51, -1, 52, -1, -1, -1, 53, 54, -1, 55, -1, -1, 56, -1, 57, -1, 58, 59]

      shapes = {}
      for feature in TQDM(data["features"], desc=f"Converting {fname}"):
          p = feature["properties"]
          if p["bounds_imcoords"]:
              image_id = p["image_id"]
              image_file = path / "train_images" / image_id
              if image_file.exists():  # 1395.tif missing
                  try:
                      box = np.array([int(num) for num in p["bounds_imcoords"].split(",")])
                      assert box.shape[0] == 4, f"incorrect box shape {box.shape[0]}"
                      cls = p["type_id"]
                      cls = xview_class2index[int(cls)]  # xView class to 0-59
                      assert 59 >= cls >= 0, f"incorrect class index {cls}"

                      # Write YOLO label
                      if image_id not in shapes:
                          shapes[image_id] = Image.open(image_file).size
                      box = xyxy2xywhn(box[None].astype(float), w=shapes[image_id][0], h=shapes[image_id][1], clip=True)
                      with open((labels / image_id).with_suffix(".txt"), "a", encoding="utf-8") as f:
                          f.write(f"{cls} {' '.join(f'{x:.6f}' for x in box[0])}\n")  # write label.txt
                  except Exception as e:
                      print(f"WARNING: skipping one label for {image_file}: {e}")

  # Download manually from https://challenge.xviewdataset.org
  dir = Path(yaml["path"])  # dataset root dir
  # urls = [
  #     "https://d307kc0mrhucc3.cloudfront.net/train_labels.zip",  # train labels
  #     "https://d307kc0mrhucc3.cloudfront.net/train_images.zip",  # 15G, 847 train images
  #     "https://d307kc0mrhucc3.cloudfront.net/val_images.zip",  # 5G, 282 val images (no labels)
  # ]
  # download(urls, dir=dir)

  # Convert labels
  convert_labels(dir / "xView_train.geojson")

  # Move images
  images = Path(dir / "images")
  images.mkdir(parents=True, exist_ok=True)
  Path(dir / "train_images").rename(dir / "images" / "train")
  Path(dir / "val_images").rename(dir / "images" / "val")

  # Split
autosplit(dir / "images" / "train")사용법#
학습을 시작하려면 위에서 설명한 수동 다운로드 파일을 datasets/xView/ 아래에 압축 해제해야 합니다. 그러면 주석 변환과 학습/검증 세트 분할이 자동으로 실행됩니다.
xView 데이터셋에서 이미지 크기 640으로 100 epochs 동안 모델을 학습하려면 다음 코드 스니펫을 사용할 수 있습니다. 사용 가능한 인수 전체 목록은 모델 Training 페이지를 참조하세요.
from ultralytics import YOLO

# 모델 로드
model = YOLO("yolo26n.pt")  # 사전 학습된 모델을 불러옵니다(학습에 권장).

# 모델 학습
results = model.train(data="xView.yaml", epochs=100, imgsz=640)
추가 위성 이미지에 라벨을 지정하고 브라우저에서 xView 학습 실행을 관리하려면 Ultralytics Platform을 사용하세요.
샘플 데이터 및 어노테이션#
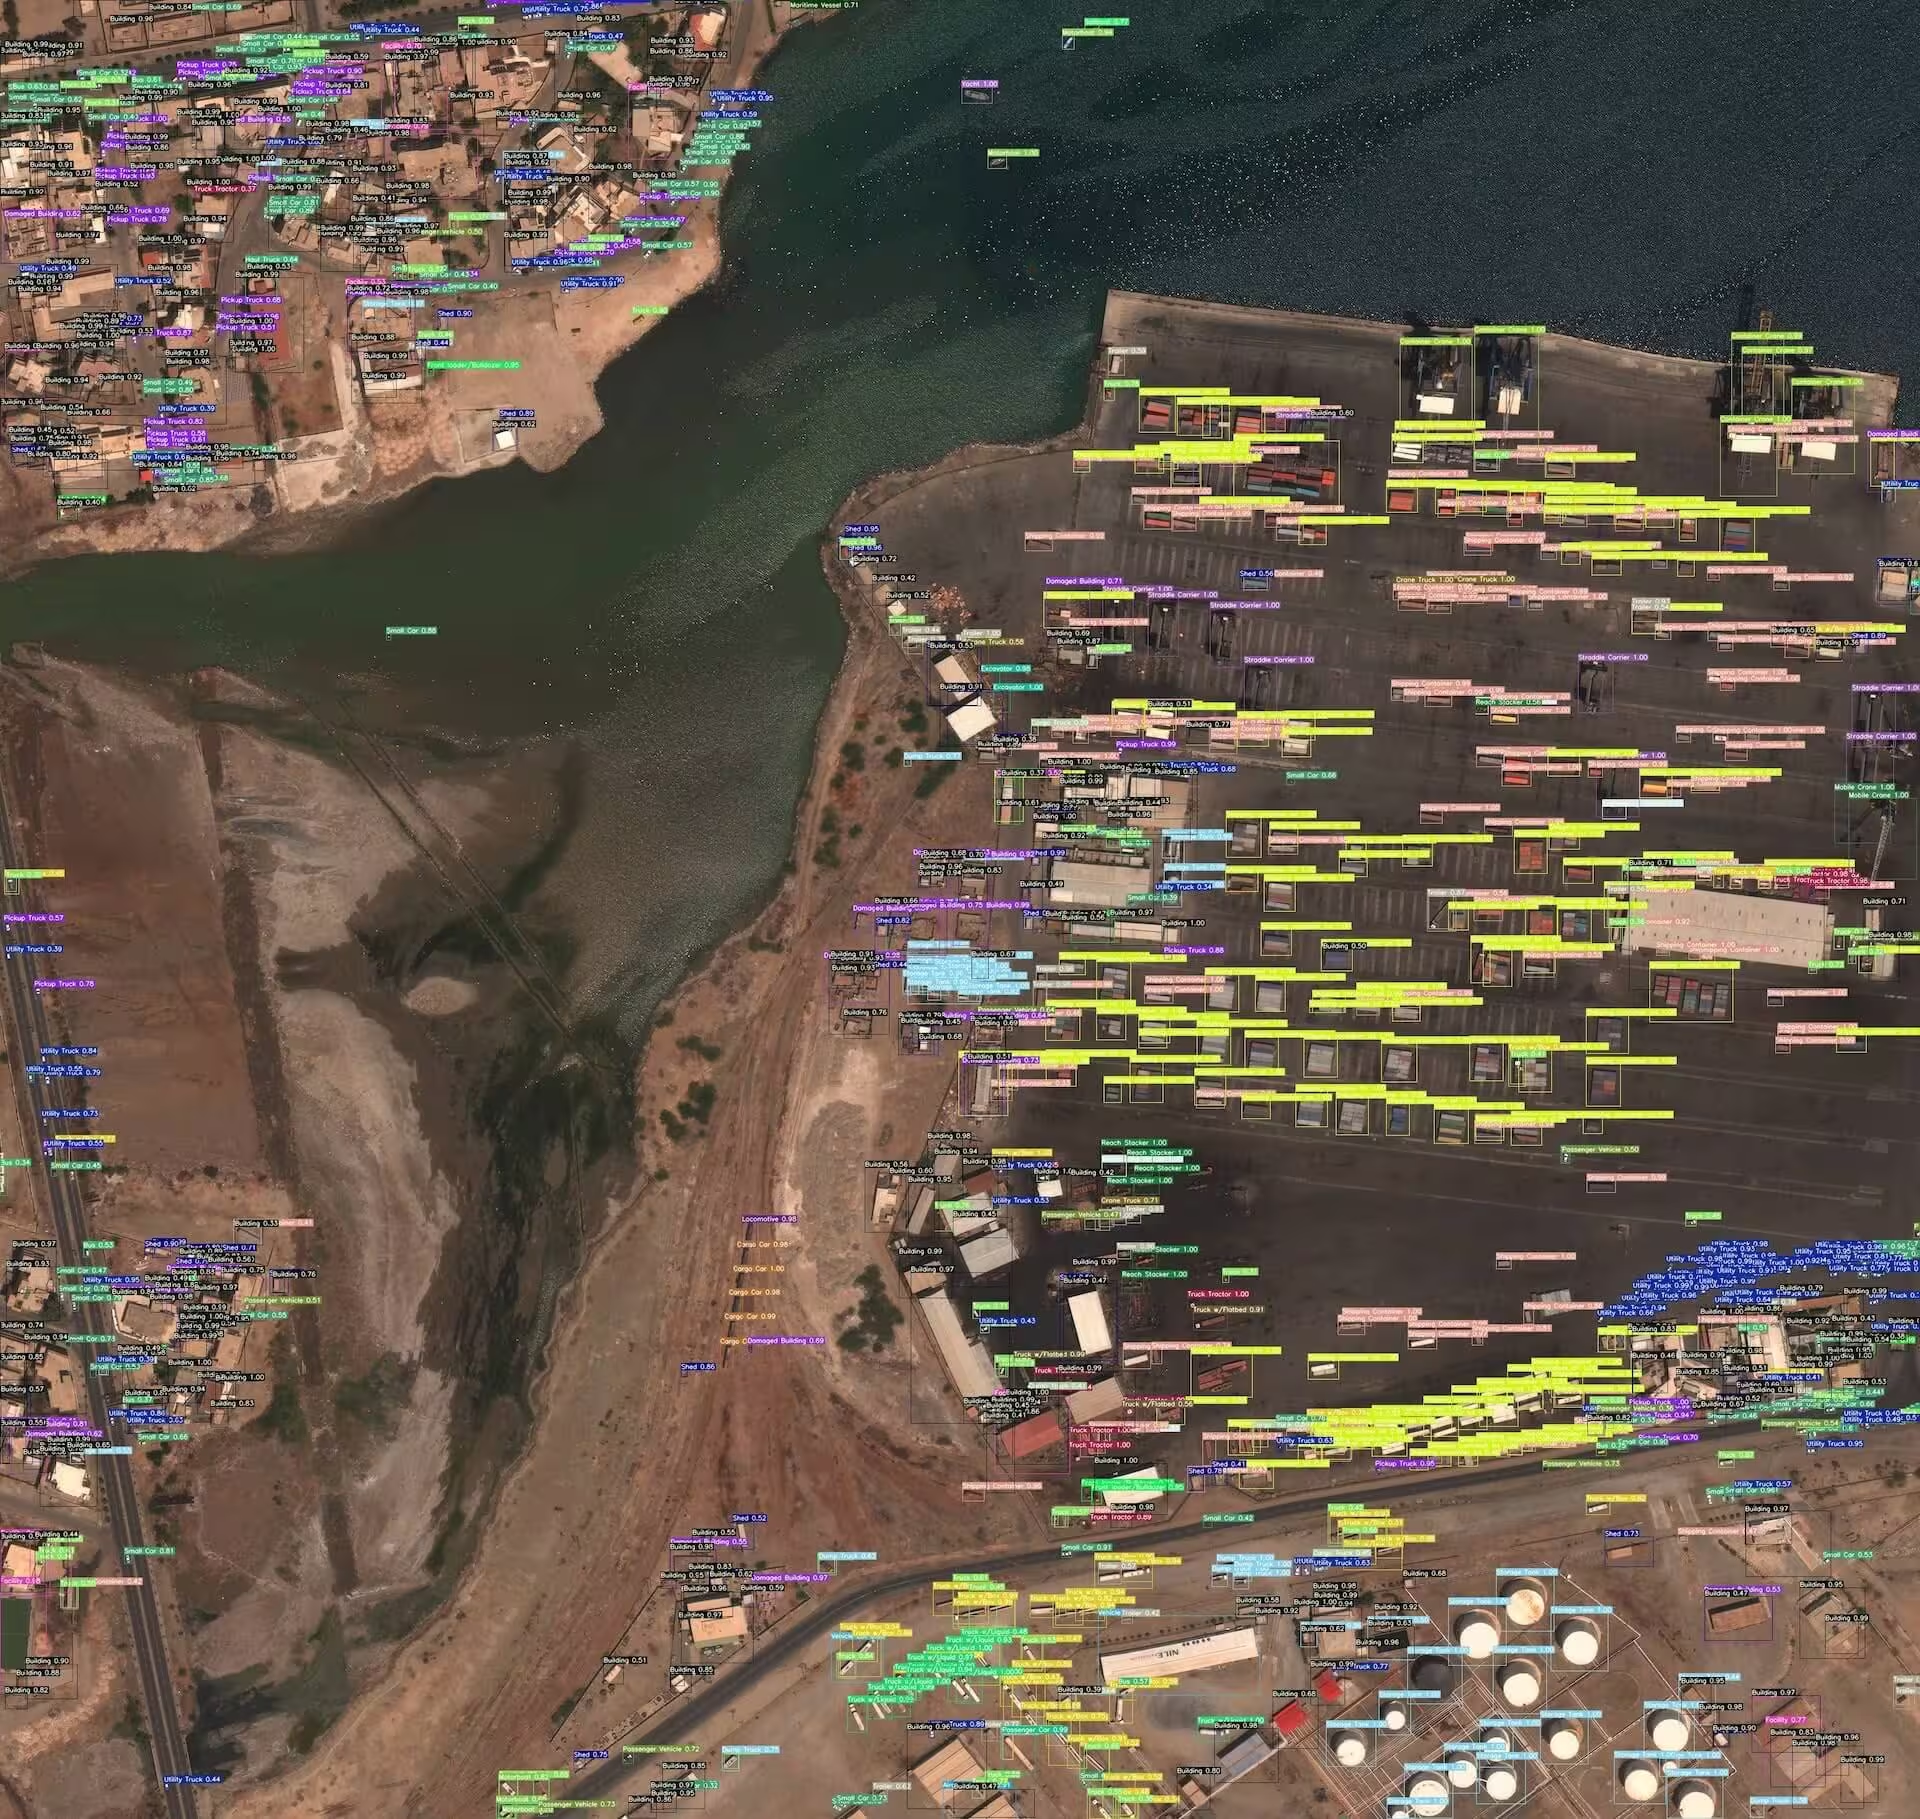
아래 샘플은 차량과 건물 같은 작은 객체에 바운딩 박스가 지정된 고해상도 항공 이미지를 보여주는 전형적인 xView 장면입니다. 이 예시는 위성 이미지의 객체 탐지에 세분화된 위치 파악이 필요한 이유를 보여줍니다.
인용 및 감사의 글#
연구 또는 개발 작업에 xView 데이터셋을 사용하는 경우 다음 논문을 인용해 주세요:
@misc{lam2018xview,
      title={xView: Objects in Context in Overhead Imagery},
      author={Darius Lam and Richard Kuzma and Kevin McGee and Samuel Dooley and Michael Laielli and Matthew Klaric and Yaroslav Bulatov and Brendan McCord},
      year={2018},
      eprint={1802.07856},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}국방혁신단(DIU)과 xView 데이터셋 제작자들이 컴퓨터 비전 연구 커뮤니티에 기여한 점에 감사드립니다. 자세한 내용은 xView 데이터셋 웹사이트를 방문하세요.
자주 묻는 질문#
xView 데이터셋은 미국 국가지리정보국이 DIUx xView 2018 Challenge를 위해 공개한 위성 이미지 벤치마크입니다. 0.3m WorldView-3 이미지에서 60개 세분화 클래스에 걸쳐 100만 개 이상의 객체 인스턴스를 제공합니다. 항공 시점에서 작고 드물며 세분화된 객체를 탐지하는 연구를 지원하며, 이러한 객체는 지상 사진의 객체보다 탐지하기 훨씬 어렵습니다.
xView는 수동으로 다운로드해야 합니다. DIUx xView 2018 Challenge 웹사이트에 가입하고
train_images.zip(~15 GB),train_labels.zip,val_images.zip(~5 GB)를 다운로드하세요. 총 용량은 약 20.7GB입니다. 이 페이지 상단 경고에 표시된 디렉터리 구조에 맞춰datasets/xView/아래에 압축을 풉니다. 첫 학습 실행 시 Ultralytics가 GeoJSON 주석을 YOLO 형식으로 자동 변환하고 학습/검증 세트를 생성합니다.xView에는 라벨이 지정된 학습 이미지 847장과 공개 라벨이 없는 검증 이미지 282장이 있으며, 모두 WorldView-3 위성이 0.3m 해상도로 촬영한 이미지입니다. 주석에는 60개 클래스에 걸쳐 100만 개 이상의 객체 인스턴스가 포함됩니다. 학습 라벨만 공개되어 있으므로 Ultralytics
xView.yaml구성은 라벨이 지정된 이미지 847장을 학습 세트와 검증 세트로 약 90/10 비율에 따라 분할합니다. 자세한 내용은 데이터셋 구조를 참조하세요."xView: Objects in Context in Overhead Imagery" 논문(Lam 외, arXiv:1802.07856, 2018)을 인용하세요. 전체 BibTeX 항목은 위의 인용 및 감사의 글 섹션에 있습니다.