빠른 시작 가이드: Ultralytics YOLO26을 NVIDIA Jetson에서 사용하기
이 가이드에서는 NVIDIA Jetson 디바이스에 Ultralytics YOLO26을 배포하는 방법과, 소형·고효율 디바이스에서 YOLO26의 성능을 보여주는 벤치마크를 소개합니다.
최대 2070 FP4 TFLOPS의 AI 연산 성능과 128 GB 메모리를 제공하며 전력을 40 W에서 130 W 사이로 설정할 수 있는 최신 NVIDIA Jetson AGX Thor Developer Kit에 맞춰 이 가이드를 업데이트했습니다. NVIDIA Jetson AGX Orin보다 AI 연산 성능은 7.5배 이상 높고, 가장 널리 사용되는 AI 모델을 실행할 때 에너지 효율은 3.5배 더 뛰어납니다.
시청: NVIDIA Jetson 디바이스에서 Ultralytics YOLO26으로 더 빠른 추론 성능을 활용하세요 🚀
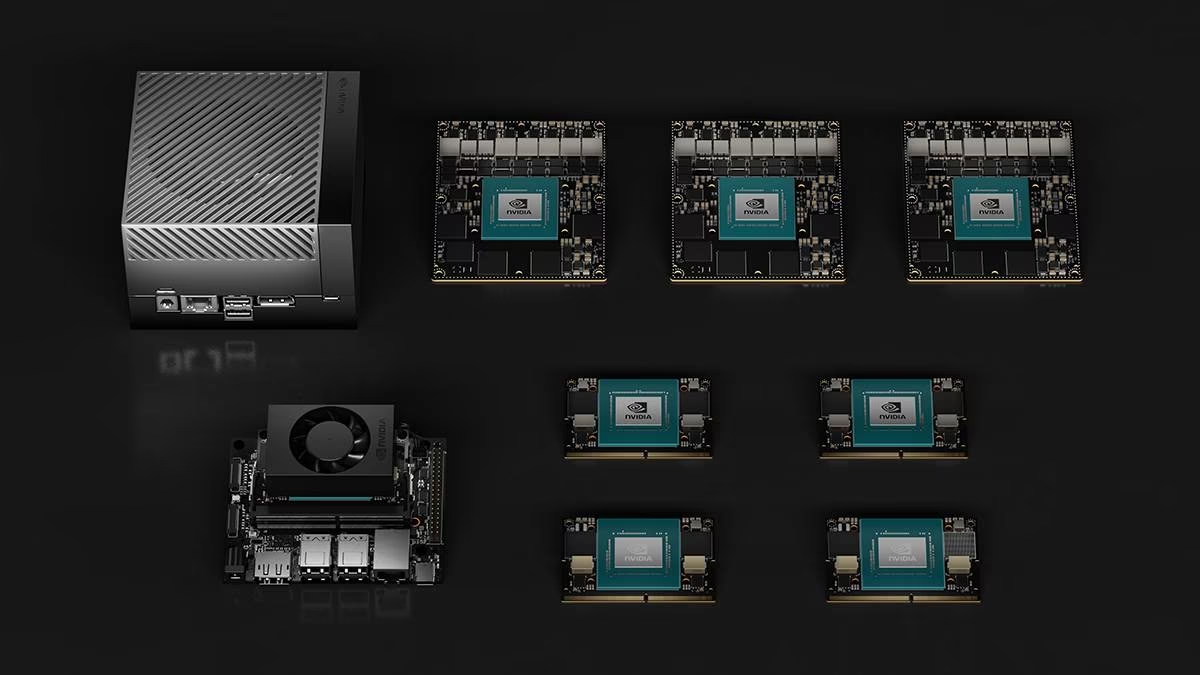
이 가이드는 최신 안정 버전인 JetPack 7.2를 실행하는 NVIDIA Jetson AGX Thor Developer Kit (Jetson T5000) 및 NVIDIA Jetson AGX Orin Developer Kit (64GB), JetPack 릴리스 JP6.1을 실행하는 NVIDIA Jetson Orin Nano Super Developer Kit, JetPack 릴리스 JP6.0/JP5.1.3을 실행하는 NVIDIA Jetson Orin NX 16GB 기반 Seeed Studio reComputer J4012, JetPack 릴리스 JP4.6.1을 실행하는 NVIDIA Jetson Nano 4GB 기반 Seeed Studio reComputer J1020 v2에서 테스트되었습니다. 최신 장치와 구형 장치를 포함한 모든 NVIDIA Jetson 하드웨어 제품군에서 작동할 것으로 예상됩니다.
NVIDIA Jetson이란 무엇인가요?#
NVIDIA Jetson은 가속 AI(인공지능) 컴퓨팅을 엣지 디바이스에 제공하도록 설계된 임베디드 컴퓨팅 보드 제품군입니다. 이 소형 고성능 디바이스는 NVIDIA GPU 아키텍처를 기반으로 하며, 클라우드 컴퓨팅 리소스에 의존하지 않고 디바이스에서 직접 복잡한 AI 알고리즘과 딥러닝 모델을 실행할 수 있습니다. Jetson 보드는 로보틱스, 자율주행차, 산업 자동화 등 AI 추론을 낮은 지연 시간과 높은 효율로 로컬에서 수행해야 하는 애플리케이션에 자주 사용됩니다. 또한 ARM64 아키텍처를 기반으로 하며 기존 GPU 컴퓨팅 디바이스보다 낮은 전력으로 작동합니다.
NVIDIA Jetson 시리즈 비교#
NVIDIA Jetson AGX Thor는 NVIDIA Blackwell 아키텍처를 기반으로 한 최신 NVIDIA Jetson 제품군으로, 이전 세대보다 훨씬 높은 AI 성능을 제공합니다. 아래 표에서는 생태계의 일부 Jetson 디바이스를 비교합니다.
| Jetson AGX Thor (T5000) | Jetson AGX Orin 64GB | Jetson Orin NX 16GB | Jetson Orin Nano Super | Jetson AGX Xavier | Jetson Xavier NX | Jetson Nano | |
|---|---|---|---|---|---|---|---|
| AI 성능 | 2070 TFLOPS | 275 TOPS | 100 TOPS | 67 TOPS | 32 TOPS | 21 TOPS | 472 GFLOPS |
| GPU | 96개의 Tensor Core를 탑재한 2560코어 NVIDIA Blackwell 아키텍처 GPU | 64개의 Tensor Core를 탑재한 2048코어 NVIDIA Ampere 아키텍처 GPU | 32개의 Tensor Core를 탑재한 1024코어 NVIDIA Ampere 아키텍처 GPU | 32개의 Tensor Core를 탑재한 1024코어 NVIDIA Ampere 아키텍처 GPU | 64개의 Tensor Core를 탑재한 512코어 NVIDIA Volta 아키텍처 GPU | 48개의 Tensor Core를 탑재한 384코어 NVIDIA Volta™ 아키텍처 GPU | 128코어 NVIDIA Maxwell™ 아키텍처 GPU |
| GPU 최대 주파수 | 1.57 GHz | 1.3 GHz | 918 MHz | 1020 MHz | 1377 MHz | 1100 MHz | 921MHz |
| CPU | 14코어 Arm® Neoverse®-V3AE 64비트 CPU, 1MB L2 + 16MB L3 | 12코어 NVIDIA Arm® Cortex A78AE v8.2 64비트 CPU, 3MB L2 + 6MB L3 | 8코어 NVIDIA Arm® Cortex A78AE v8.2 64비트 CPU, 2MB L2 + 4MB L3 | 6코어 Arm® Cortex®-A78AE v8.2 64비트 CPU 1.5MB L2 + 4MB L3 | 8코어 NVIDIA Carmel Arm®v8.2 64비트 CPU 8MB L2 + 4MB L3 | 6코어 NVIDIA Carmel Arm®v8.2 64비트 CPU 6MB L2 + 4MB L3 | 쿼드 코어 Arm® Cortex®-A57 MPCore 프로세서 |
| CPU 최대 주파수 | 2.6 GHz | 2.2 GHz | 2.0 GHz | 1.7 GHz | 2.2 GHz | 1.9 GHz | 1.43GHz |
| 메모리 | 128GB 256비트 LPDDR5X 273GB/s | 64GB 256비트 LPDDR5 204.8GB/s | 16GB 128비트 LPDDR5 102.4GB/s | 8GB 128비트 LPDDR5 102 GB/s | 32GB 256비트 LPDDR4x 136.5GB/s | 8GB 128비트 LPDDR4x 59.7GB/s | 4GB 64비트 LPDDR4 25.6GB/s |
NVIDIA JetPack이란 무엇인가요?#
NVIDIA JetPack SDK는 Jetson 모듈을 구동하며 엔드투엔드 가속 AI 애플리케이션 개발을 위한 전체 개발 환경을 제공합니다. JetPack에는 부트로더, Linux 커널, Ubuntu 데스크톱 환경이 포함된 Jetson Linux와 GPU 컴퓨팅, 멀티미디어, 그래픽 및 컴퓨터 비전 가속을 위한 라이브러리 전체가 포함됩니다. 호스트 컴퓨터와 개발자 키트용 샘플, 문서, 개발자 도구도 제공하며, 스트리밍 비디오 분석을 위한 DeepStream, 로보틱스용 Isaac, 대화형 AI용 Riva와 같은 상위 수준 SDK도 지원합니다.
NVIDIA Jetson에 JetPack 플래시하기#
NVIDIA Jetson 장치를 받은 후 가장 먼저 해야 할 일은 장치에 NVIDIA JetPack을 플래시하는 것입니다. NVIDIA Jetson 장치를 플래시하는 방법은 여러 가지입니다.
- 공식 Jetson AGX Thor, AGX Orin 또는 Orin Nano Developer Kit에 JetPack 7.2를 설치하려면 통합 Jetson ISO를 다운로드해 USB 플래시 드라이브에 기록한 다음, AGX Thor, AGX Orin 또는 Orin Nano에 해당하는 빠른 시작 안내를 따르세요. JetPack 7.2부터 Orin Nano는 다운로드 가능한 SD 카드 이미지를 더 이상 사용하지 않습니다. ISO가 기록된 USB를 사용하면 장치의 microSD 카드 또는 NVMe SSD에 Jetson Linux가 설치됩니다.
- Jetson Orin Nano Developer Kit에서 의도적으로 JetPack 6을 사용하는 경우, NVIDIA의 JetPack 6.x 업데이트 및 SD 카드 안내를 따르세요.
- 다른 NVIDIA 개발자 키트를 보유하고 있다면 SDK Manager를 사용해 장치에 JetPack을 플래시할 수 있습니다.
- Seeed Studio reComputer J4012 장치를 보유하고 있다면 포함된 SSD에 JetPack을 플래시할 수 있습니다. Seeed Studio reComputer J1020 v2 장치를 보유하고 있다면 eMMC/ SSD에 JetPack을 플래시할 수 있습니다.
- NVIDIA Jetson 모듈을 탑재한 다른 타사 장치를 보유하고 있다면 명령줄 플래시 방법을 따르는 것이 좋습니다.
위의 방법 1, 4, 5에서는 시스템을 플래싱하고 디바이스를 부팅한 다음, 디바이스 터미널에서 sudo apt update && sudo apt install nvidia-jetpack -y을 실행하여 필요한 나머지 JetPack 구성 요소를 설치합니다.
Jetson 장치별 JetPack 지원#
아래 표에는 다양한 NVIDIA Jetson 장치에서 지원하는 NVIDIA JetPack 버전이 나와 있습니다.
| JetPack 4 | JetPack 5 | JetPack 6 | JetPack 7 | |
|---|---|---|---|---|
| Jetson Nano | ✅ | ❌ | ❌ | ❌ |
| Jetson TX2 | ✅ | ❌ | ❌ | ❌ |
| Jetson Xavier NX | ✅ | ✅ | ❌ | ❌ |
| Jetson AGX Xavier | ✅ | ✅ | ❌ | ❌ |
| Jetson AGX Orin | ❌ | ✅ | ✅ | ✅ |
| Jetson Orin NX | ❌ | ✅ | ✅ | ✅ |
| Jetson Orin Nano | ❌ | ✅ | ✅ | ✅ |
| Jetson AGX Thor | ❌ | ❌ | ❌ | ✅ |
Docker로 빠르게 시작하기#
NVIDIA Jetson에서 Ultralytics YOLO26을 가장 빠르게 시작하려면 Jetson용 사전 빌드 Docker 이미지를 실행하세요. 위 표를 참조해 보유한 Jetson 디바이스에 맞는 JetPack 버전을 선택합니다.
t=ultralytics/ultralytics:latest-jetson-jetpack4
sudo docker pull $t && sudo docker run -it --ipc=host --runtime=nvidia $tlatest-nvidia-arm64 이미지는 CUDA 13.4 및 TensorRT 11.4를 포함하는 NVIDIA PyTorch 26.10을 사용합니다. NVIDIA는 호환성 표에서 PyTorch용 JetPack 7.1을 명시하지만, Thor를 포함해 TensorRT 11은 JetPack을 지원하지 않습니다. 이 이미지는 지원되는 호스트에서 PyTorch 워크로드를 실행할 때만 사용하세요. Jetson TensorRT 내보내기에는 아래의 네이티브 설치를 사용하고, 사용 중인 JetPack 릴리스에서 지원하는 TensorRT 10.x 런타임을 이용하세요. Thor 또는 Orin에서 JetPack 7.2를 사용하려면 별도로 컨테이너 검증을 수행해야 합니다. 대상 GPU 및 TensorRT 버전에 맞춰 엔진을 다시 빌드하세요.
JetPack 4, 5, 6 이미지의 경우 NVIDIA Jetson에서 TensorRT 사용하기를 계속 진행하세요. 위의 JetPack 7.1 이미지는 PyTorch 워크로드 전용입니다.
기본 설치 시작하기#
Docker 없이 기본 설치를 진행하려면 아래 단계를 참조하세요.
JetPack 7.2에서 실행하기#
Ultralytics 패키지 설치#
Jetson에 Ultralytics 패키지를 설치합니다. 모델을 처음 내보낼 때 내보내기 종속 항목이 자동 설치되므로 여기서는 기본 패키지만 필요합니다. 이 가이드에서는 Jetson 디바이스에서 최고의 성능을 제공하는 NVIDIA TensorRT 내보내기에 초점을 맞춥니다.
-
패키지 목록을 업데이트하고 pip를 설치한 뒤 최신 버전으로 업그레이드합니다
sudo apt update sudo apt install python3-pip -y pip install -U pip -
ultralyticspip 패키지를 설치합니다pip install ultralytics -
장치를 재부팅합니다
sudo reboot
PyTorch 및 Torchvision 설치#
위의 ultralytics 설치 과정에서 Torch와 Torchvision이 설치됩니다. 하지만 pip로 설치한 이 두 패키지는 CUDA 13을 실행하는 JetPack 7.2 디바이스와 호환되지 않으므로 수동으로 설치해야 합니다.
JP7.2에 맞는 torch 및 torchvision을 설치합니다
pip install torch torchvision --index-url https://download.pytorch.org/whl/cu130onnxruntime-gpu 설치#
JetPack, Python, CUDA 버전에 맞는 ONNX Runtime GPU 휠을 사용하세요. 현재 PyPI 릴리스에는 ARM64 휠이 포함되어 있지만, 모든 JetPack 릴리스에 필요한 장치별 패키지를 대체하지는 않습니다.
Python3.12 지원을 포함한 onnxruntime-gpu 1.24.0을 다운로드하고 설치합니다.
pip install https://github.com/ultralytics/assets/releases/download/v0.0.0/onnxruntime_gpu-1.24.0-cp312-cp312-linux_aarch64.whlJetPack 6.1에서 실행하기#
Ultralytics 패키지 설치#
Jetson에 Ultralytics 패키지를 설치합니다. 모델을 처음 내보낼 때 내보내기 종속 항목이 자동 설치되므로 여기서는 기본 패키지만 필요합니다. 이 가이드에서는 Jetson 디바이스에서 최고의 성능을 제공하는 NVIDIA TensorRT 내보내기에 초점을 맞춥니다.
-
패키지 목록을 업데이트하고 pip를 설치한 뒤 최신 버전으로 업그레이드합니다
sudo apt update sudo apt install python3-pip -y pip install -U pip -
ultralyticspip 패키지를 설치합니다pip install ultralytics -
장치를 재부팅합니다
sudo reboot
PyTorch 및 Torchvision 설치#
위의 ultralytics 설치 과정에서 Torch와 Torchvision이 설치됩니다. 하지만 pip로 설치한 이 두 패키지는 ARM64 아키텍처 기반인 Jetson 플랫폼과 호환되지 않으므로, 사전 빌드된 PyTorch pip wheel을 수동으로 설치하고 Torchvision을 소스에서 컴파일하거나 설치해야 합니다.
JP6.1에 맞는 torch 2.10.0 및 torchvision 0.25.0을 설치합니다
pip install https://github.com/ultralytics/assets/releases/download/v0.0.0/torch-2.10.0-cp310-cp310-linux_aarch64.whl
pip install https://github.com/ultralytics/assets/releases/download/v0.0.0/torchvision-0.25.0-cp310-cp310-linux_aarch64.whlJetson용 PyTorch 페이지에서 다양한 JetPack 버전에 맞는 모든 PyTorch 버전을 확인하세요. PyTorch와 Torchvision의 호환성에 대한 자세한 목록은 PyTorch 및 Torchvision 호환성 페이지를 참조하세요.
torch 2.10.0의 종속성 문제를 해결하려면 cuDSS을 설치하세요.
wget https://developer.download.nvidia.com/compute/cudss/0.7.1/local_installers/cudss-local-tegra-repo-ubuntu2204-0.7.1_0.7.1-1_arm64.deb
sudo dpkg -i cudss-local-tegra-repo-ubuntu2204-0.7.1_0.7.1-1_arm64.deb
sudo cp /var/cudss-local-tegra-repo-ubuntu2204-0.7.1/cudss-*-keyring.gpg /usr/share/keyrings/
sudo apt-get update
sudo apt-get -y install cudss
onnxruntime-gpu 설치#
JetPack, Python, CUDA 버전에 맞는 ONNX Runtime GPU 휠을 사용하세요. 현재 PyPI 릴리스에는 ARM64 휠이 포함되어 있지만, 모든 JetPack 릴리스에 필요한 장치별 패키지를 대체하지는 않습니다.
JetPack 버전, Python 버전 및 기타 호환성 세부 정보별로 구성된 모든 onnxruntime-gpu 패키지는 Jetson Zoo ONNX Runtime 호환성 매트릭스에서 확인할 수 있습니다.
Python 3.10을 지원하는 JetPack 6의 경우 onnxruntime-gpu 1.23.0을 설치할 수 있습니다:
pip install https://github.com/ultralytics/assets/releases/download/v0.0.0/onnxruntime_gpu-1.23.0-cp310-cp310-linux_aarch64.whl또는 onnxruntime-gpu 1.20.0의 경우:
pip install https://github.com/ultralytics/assets/releases/download/v0.0.0/onnxruntime_gpu-1.20.0-cp310-cp310-linux_aarch64.whlJetPack 5.1.2에서 실행하기#
Ultralytics 패키지 설치#
Jetson에 Ultralytics 패키지를 설치합니다. 모델을 처음 내보낼 때 내보내기 종속 항목이 자동 설치되므로 여기서는 기본 패키지만 필요합니다. 이 가이드에서는 Jetson 디바이스에서 최고의 성능을 제공하는 NVIDIA TensorRT 내보내기에 초점을 맞춥니다.
-
패키지 목록을 업데이트하고 pip를 설치한 뒤 최신 버전으로 업그레이드합니다
sudo apt update sudo apt install python3-pip -y pip install -U pip -
ultralyticspip 패키지를 설치합니다pip install ultralytics -
장치를 재부팅합니다
sudo reboot
PyTorch 및 Torchvision 설치#
위의 ultralytics 설치 과정에서 Torch와 Torchvision이 설치됩니다. 하지만 pip로 설치한 이 두 패키지는 ARM64 아키텍처 기반인 Jetson 플랫폼과 호환되지 않으므로, 사전 빌드된 PyTorch pip wheel을 수동으로 설치하고 Torchvision을 소스에서 컴파일하거나 설치해야 합니다.
-
현재 설치된 PyTorch와 Torchvision을 제거합니다
pip uninstall torch torchvision -
JP5.1.2에 맞는
torch 2.1.0및torchvision 0.16.2을 설치합니다pip install https://github.com/ultralytics/assets/releases/download/v0.0.0/torch-2.1.0a0+41361538.nv23.06-cp38-cp38-linux_aarch64.whl pip install https://github.com/ultralytics/assets/releases/download/v0.0.0/torchvision-0.16.2+c6f3977-cp38-cp38-linux_aarch64.whl
Jetson용 PyTorch 페이지에서 다양한 JetPack 버전에 맞는 모든 PyTorch 버전을 확인하세요. PyTorch와 Torchvision의 호환성에 대한 자세한 목록은 PyTorch 및 Torchvision 호환성 페이지를 참조하세요.
onnxruntime-gpu 설치#
JetPack, Python, CUDA 버전에 맞는 ONNX Runtime GPU 휠을 사용하세요. 현재 PyPI 릴리스에는 ARM64 휠이 포함되어 있지만, 모든 JetPack 릴리스에 필요한 장치별 패키지를 대체하지는 않습니다.
JetPack 버전, Python 버전 및 기타 호환성 정보별로 정리된 모든 onnxruntime-gpu 패키지는 Jetson Zoo ONNX Runtime 호환성 매트릭스에서 확인할 수 있습니다. Python3.8 지원을 포함한 onnxruntime-gpu 1.17.0를 다운로드하고 설치합니다.
wget https://nvidia.box.com/shared/static/zostg6agm00fb6t5uisw51qi6kpcuwzd.whl -O onnxruntime_gpu-1.17.0-cp38-cp38-linux_aarch64.whl
pip install onnxruntime_gpu-1.17.0-cp38-cp38-linux_aarch64.whlonnxruntime-gpu은 NumPy를 최신 버전으로 자동 업그레이드하므로, 이로 인해 발생하는 문제를 해결하려면 NumPy 1.23.5을 다시 설치합니다.
pip install numpy==1.23.5
NVIDIA Jetson에서 TensorRT 사용하기#
Ultralytics가 지원하는 모든 모델 내보내기 형식 중 TensorRT는 NVIDIA Jetson 디바이스에서 가장 높은 추론 성능을 제공하므로, Jetson 배포에 가장 권장하는 형식입니다. 내보내기 전에 사용 중인 JetPack 릴리스에 제공된 TensorRT Python 바인딩을 설치하고 python3 -c "import tensorrt; print(tensorrt.__version__)"으로 확인하세요. JetPack 6/7에서는 지원되는 TensorRT 10.x 런타임을 사용하고, TensorRT 11로 교체하지 마세요. 설정 방법과 고급 사용법은 TensorRT 전용 통합 가이드를 참조하세요.
로컬에서 빌드 환경을 구성하지 않고도 브라우저에서 내보낼 수 있습니다. Ultralytics Platform 모델 내보내기 탭에서 TensorRT와 대상 Jetson을 선택하세요. Thor 옵션은 실제 Thor 하드웨어에서 검증됩니다. 현재 6개의 Orin 옵션은 AGX-Orin에서 빌드된 후보 엔진을 생성하므로, 배포 전에 대상 Orin SKU에서 검증하세요.
TensorRT는 엔진을 빌드한 GPU에서 프로파일링과 튜닝을 수행합니다. 대상 디바이스의 GPU 아키텍처와 TensorRT/CUDA 런타임을 일치시키고, 다운로드한 모든 엔진을 배포 디바이스에서 검증하세요. 동일한 아키텍처를 사용하는 Orin SKU라고 해서 자동으로 이식성이 보장되지는 않으며, 최상의 결과를 얻으려면 INT8 보정을 대상 디바이스에서 수행해야 합니다.
모델을 TensorRT로 변환하고 추론 실행하기#
PyTorch 형식의 YOLO26n 모델을 TensorRT로 변환한 다음, 내보낸 모델로 추론을 실행합니다.
from ultralytics import YOLO

# YOLO26n PyTorch 모델 로드
model = YOLO("yolo26n.pt")

# 모델을 TensorRT로 내보내기
model.export(format="engine")  # 'yolo26n.engine' 생성

# 내보낸 TensorRT 모델 로드
trt_model = YOLO("yolo26n.engine")

# 추론 실행
results = trt_model("https://ultralytics.com/images/bus.jpg")
NVIDIA Deep Learning Accelerator(DLA) 사용하기#
NVIDIA 딥 러닝 가속기(DLA)는 NVIDIA Jetson 장치에 내장된 특수 하드웨어 구성 요소로, 에너지 효율과 성능을 높이도록 딥 러닝 추론을 최적화합니다. GPU에서 작업을 오프로드해 GPU를 더 집중적인 처리에 활용할 수 있도록 하며, 이를 통해 DLA는 높은 처리량을 유지하면서 전력 소비를 줄여 모델을 실행합니다. 따라서 임베디드 시스템과 실시간 AI 애플리케이션에 적합합니다.
NVIDIA는 DLA를 지원하는 마지막 릴리스로 TensorRT 10.7을 명시하며, TensorRT 11.x는 DLA를 지원하지 않습니다. 사용 중인 JetPack 버전에서 지원하는 DLA 호환 TensorRT 릴리스를 사용하세요. TensorRT 11은 GPU 전용 내보내기를 포함해 JetPack을 지원하지 않습니다.
다음 Jetson 장치에는 DLA 하드웨어가 탑재되어 있습니다:
| Jetson 장치 | DLA 코어 수 | DLA 최대 주파수 |
|---|---|---|
| Jetson AGX Orin 시리즈 | 2 | 1.6 GHz |
| Jetson Orin NX 16GB | 2 | 614 MHz |
| Jetson Orin NX 8GB | 1 | 614 MHz |
| Jetson AGX Xavier 시리즈 | 2 | 1.4 GHz |
| Jetson Xavier NX 시리즈 | 2 | 1.1 GHz |
from ultralytics import YOLO

# YOLO26n PyTorch 모델 로드
model = YOLO("yolo26n.pt")

# DLA를 활성화해 모델을 TensorRT로 내보내기(FP16 또는 INT8에서만 작동)
model.export(format="engine", device="dla:0", quantize=16)  # dla:0 또는 dla:1은 DLA 코어를 나타냅니다

# 내보낸 TensorRT 모델 로드
trt_model = YOLO("yolo26n.engine")

# 추론 실행
results = trt_model("https://ultralytics.com/images/bus.jpg")DLA 내보내기를 사용할 때 일부 레이어는 DLA에서 실행되지 않을 수 있으며 GPU에서 실행되도록 대체 처리됩니다. 이러한 대체 처리로 인해 지연 시간이 추가되고 전체 추론 성능에 영향을 줄 수 있습니다. 따라서 DLA는 GPU에서만 실행되는 TensorRT와 비교해 추론 지연 시간을 줄이는 용도로 주로 설계된 것이 아닙니다. 대신 처리량을 늘리고 에너지 효율을 개선하는 것이 주된 목적입니다.
NVIDIA Jetson YOLO26 벤치마크#
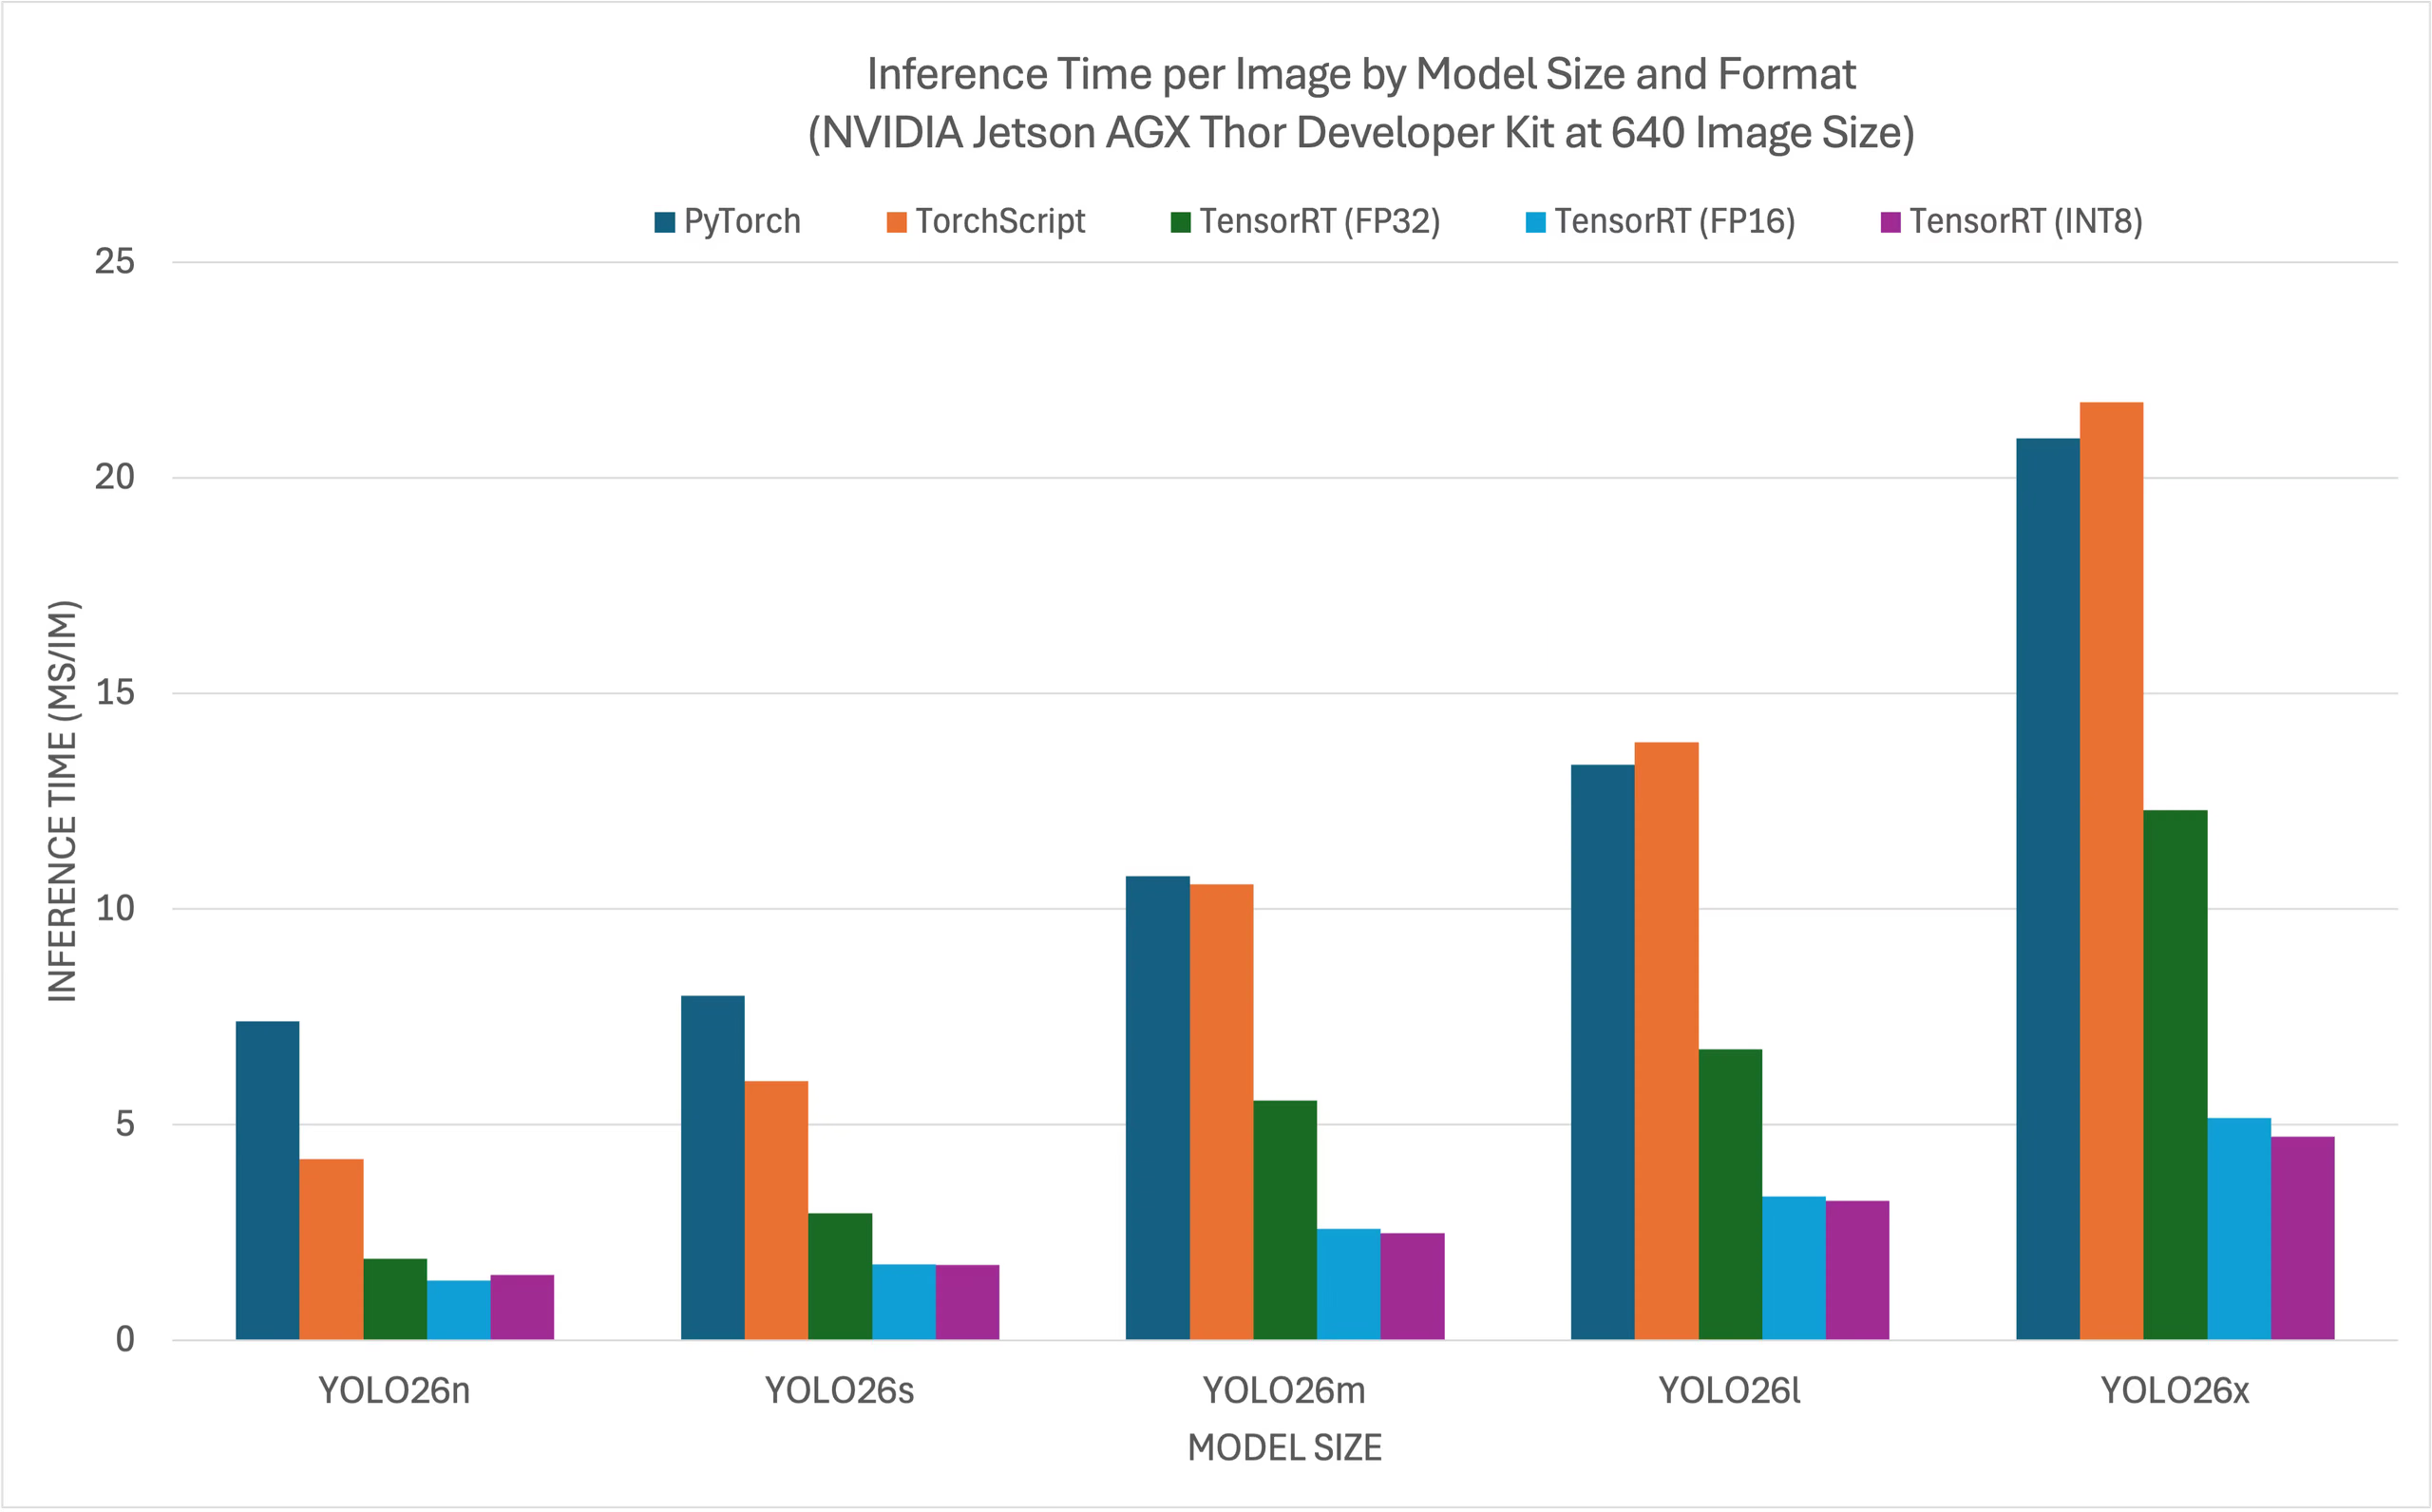
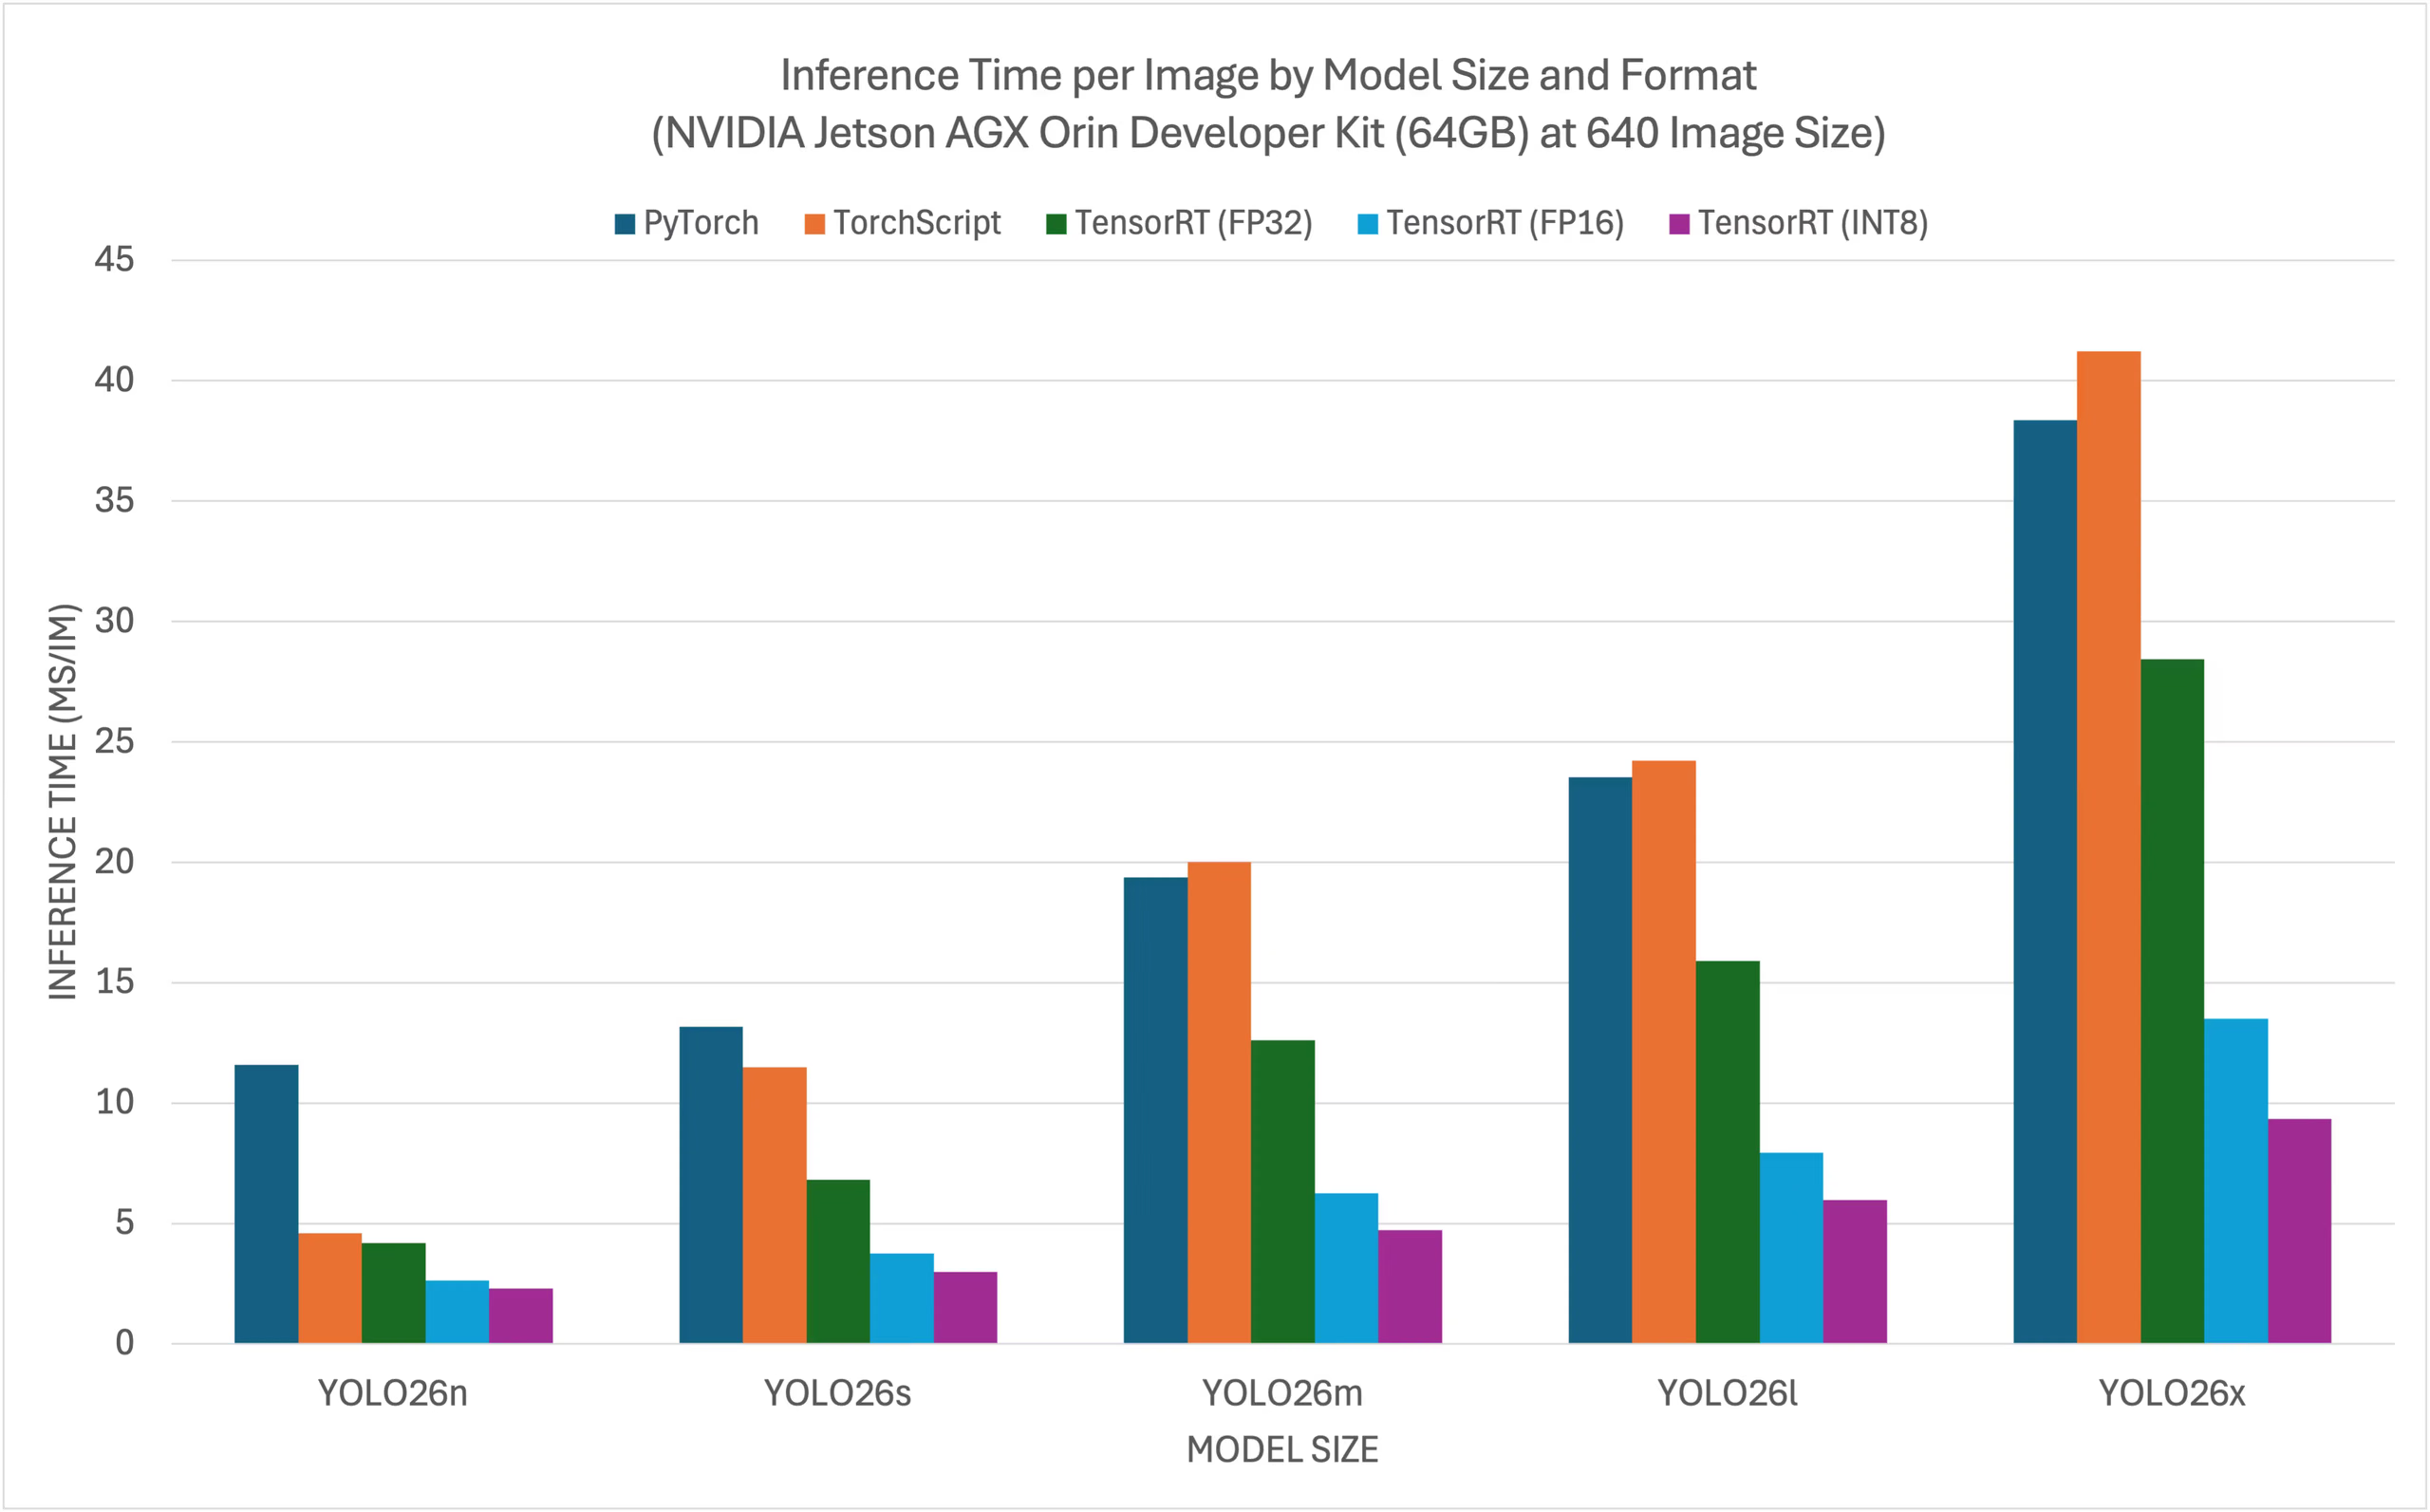
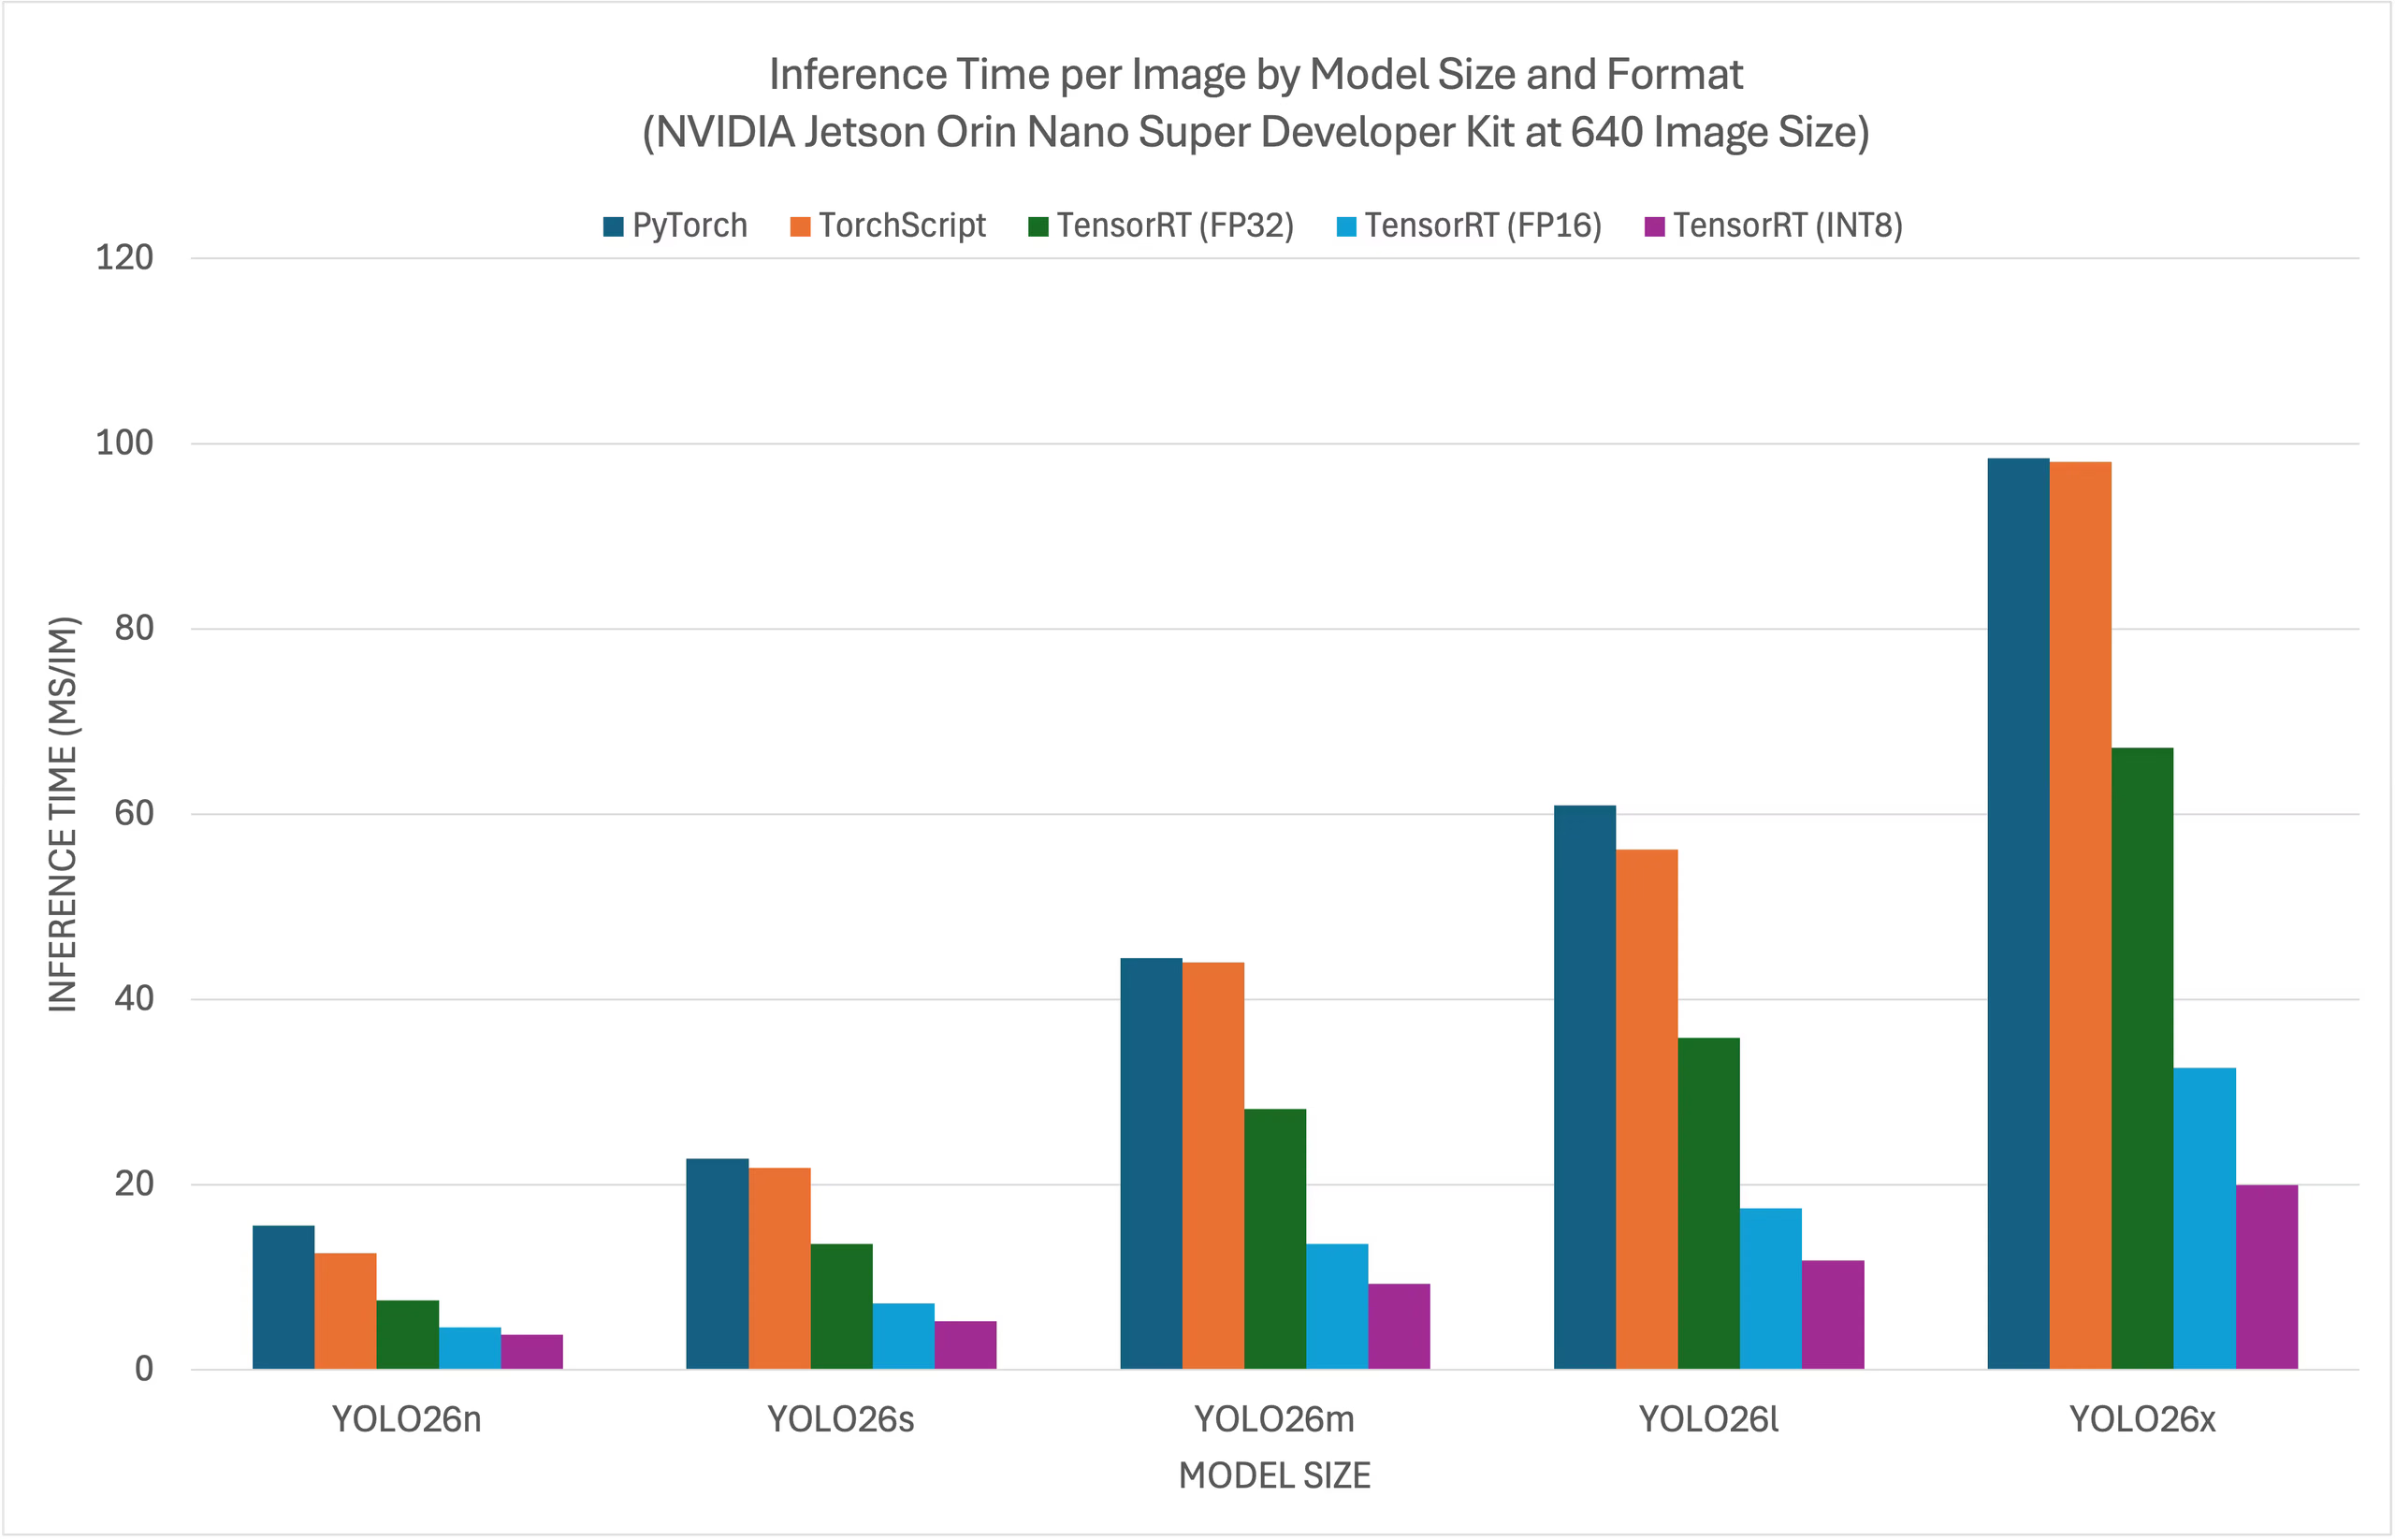
Ultralytics 팀은 속도와 정확도를 측정하기 위해 11가지 모델 형식(PyTorch, TorchScript, ONNX, OpenVINO, TensorRT, TF SavedModel, TF GraphDef, TF Lite, MNN, NCNN, ExecuTorch)에서 YOLO26 벤치마크를 실행했습니다. 벤치마크는 NVIDIA Jetson AGX Thor Developer Kit, NVIDIA Jetson AGX Orin Developer Kit(64GB), NVIDIA Jetson Orin Nano Super Developer Kit 및 Jetson Orin NX 16GB를 탑재한 Seeed Studio reComputer J4012에서 기본 입력 이미지 크기 640, FP32 정밀도로 실행했습니다.
비교 차트#
모든 모델 내보내기 형식이 NVIDIA Jetson에서 작동하지만, 아래 비교 차트에는 PyTorch, TorchScript, TensorRT만 포함되어 있습니다. 모든 내보내기 형식의 벤치마크는 이 차트 다음 섹션에서 확인할 수 있습니다.
NVIDIA Jetson AGX Thor 개발자 키트#
NVIDIA Jetson AGX Orin 개발자 키트(64GB)#
NVIDIA Jetson Orin Nano Super 개발자 키트#
NVIDIA Jetson Orin NX 16GB#
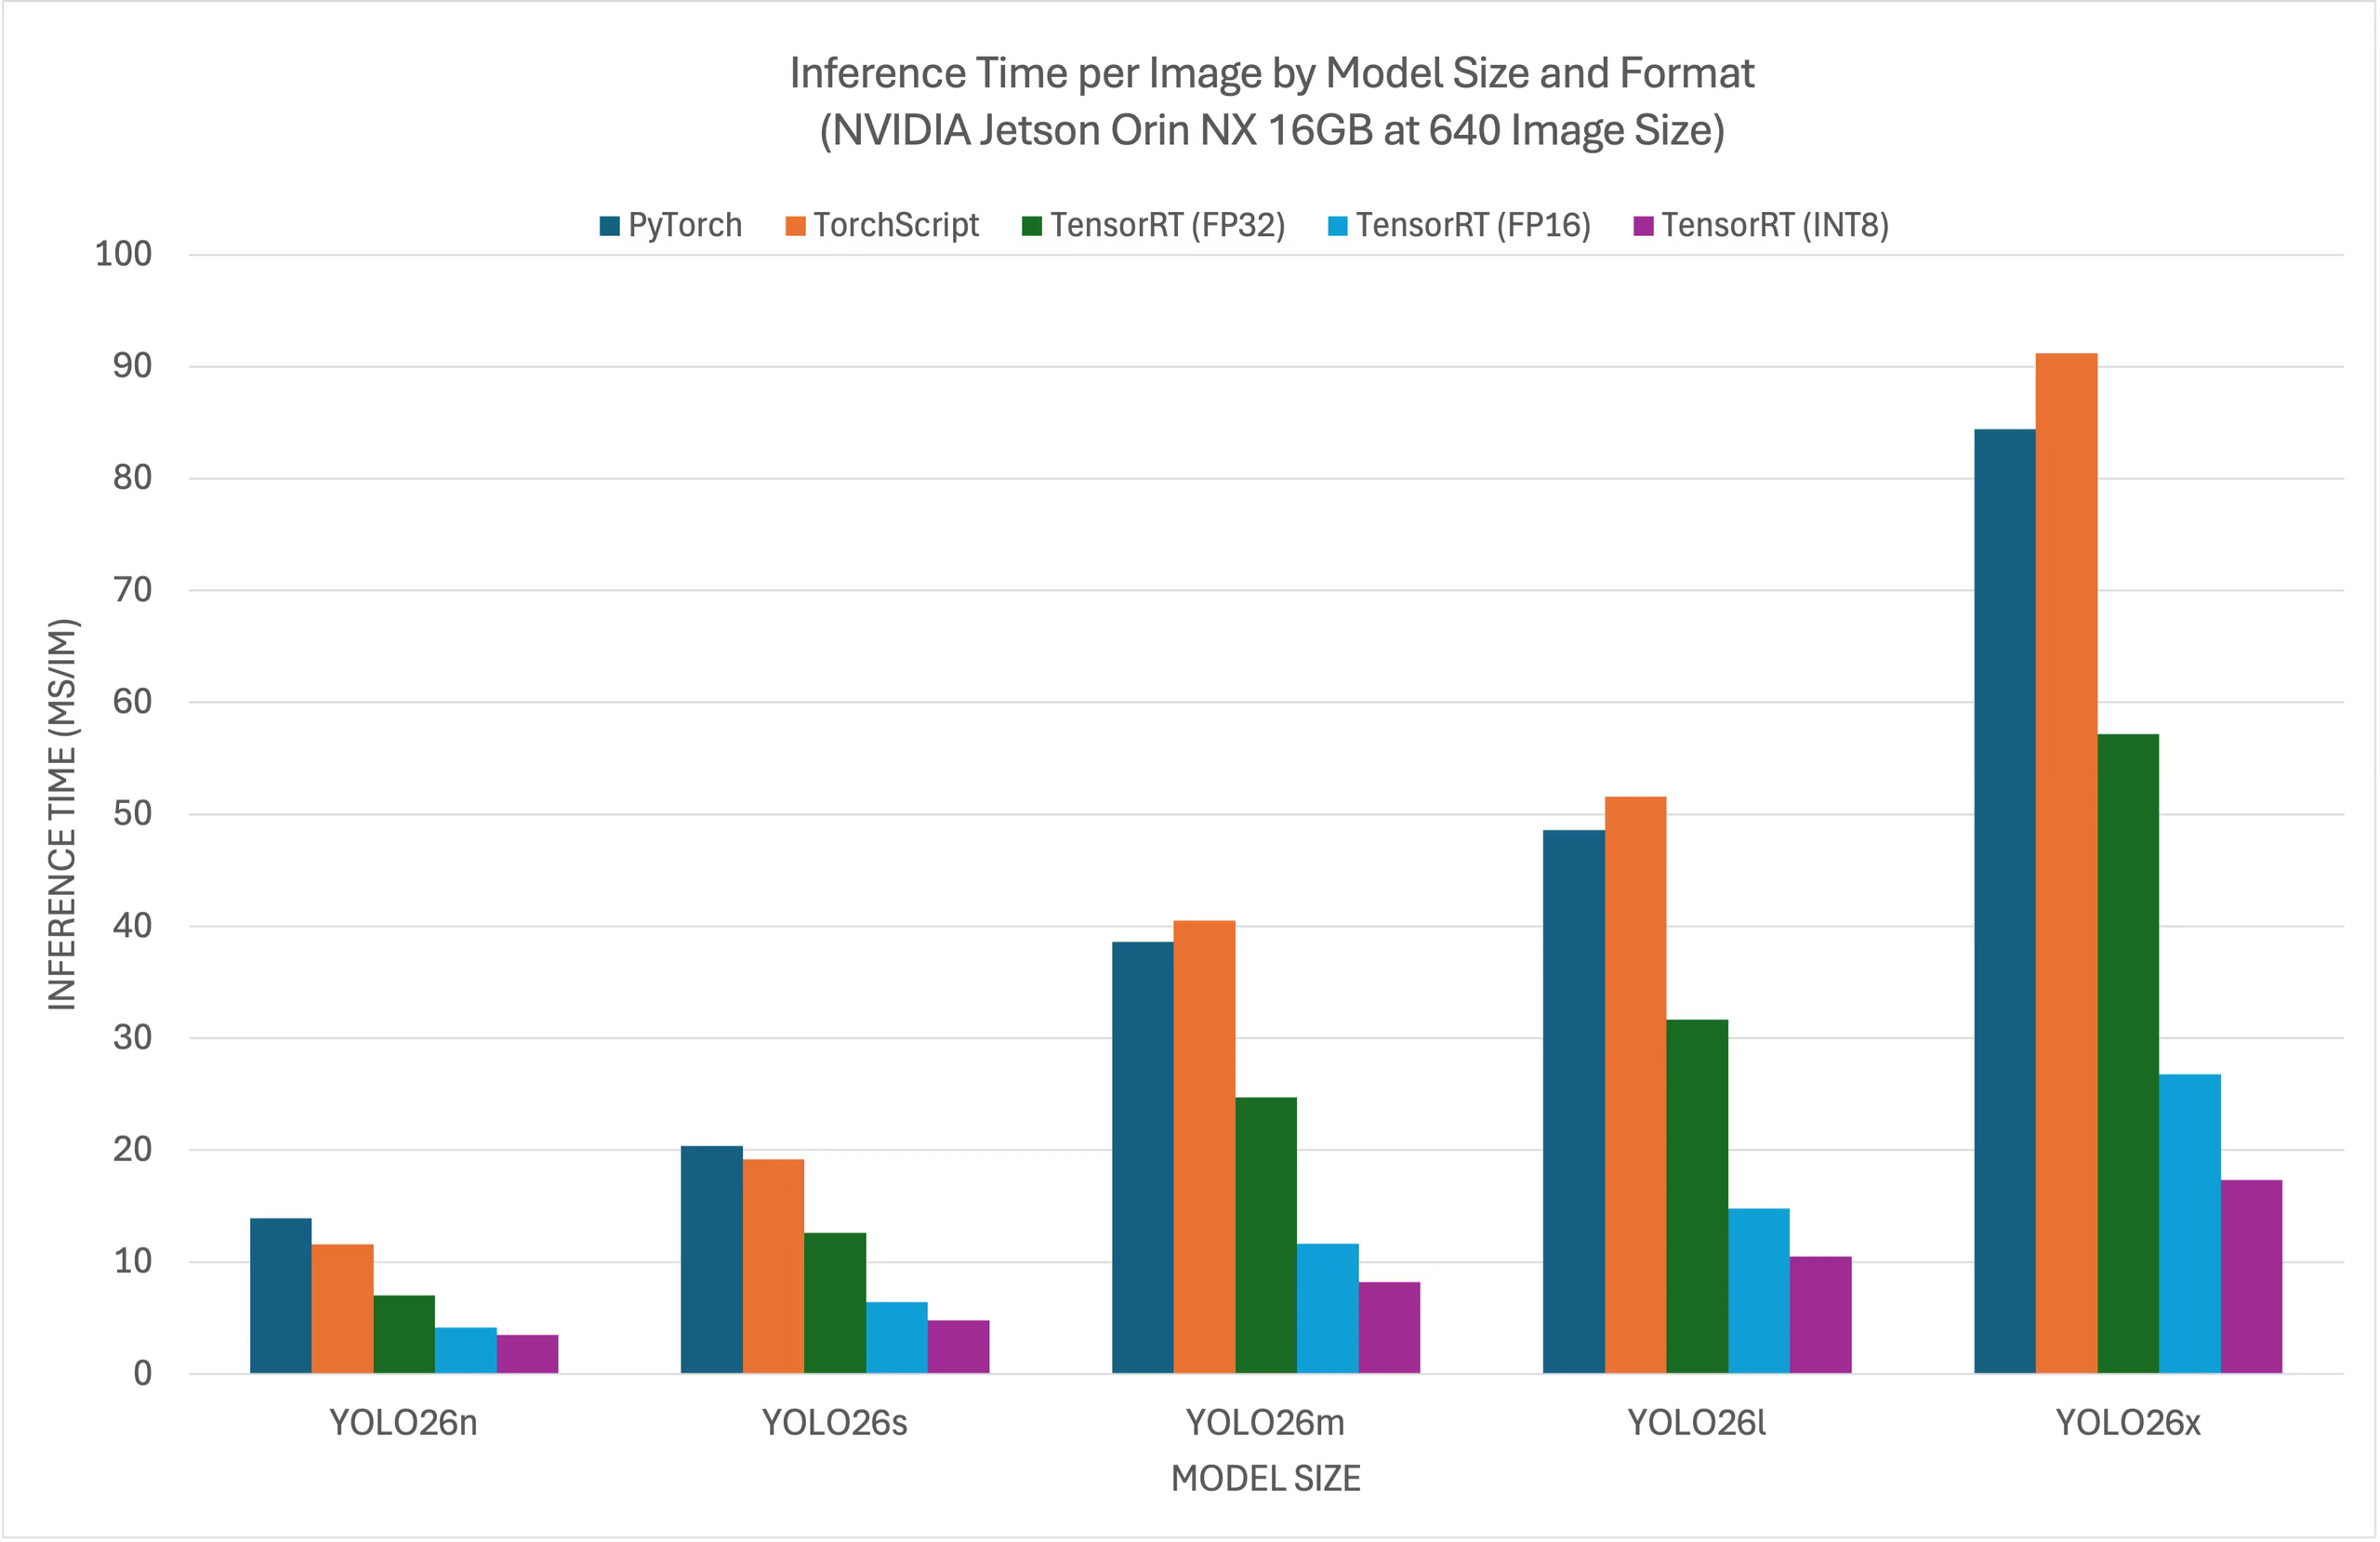
상세 비교 표#
아래 표는 11가지 형식(PyTorch, TorchScript, ONNX, OpenVINO, TensorRT, TF SavedModel, TF GraphDef, TF Lite, MNN, NCNN, ExecuTorch)에서 서로 다른 YOLO26 모델 5개(YOLO26n, YOLO26s, YOLO26m, YOLO26l, YOLO26x)의 벤치마크 결과를 보여줍니다. 각 조합의 상태, 크기, mAP50-95(B) 지표와 추론 시간이 포함됩니다.
NVIDIA Jetson AGX Thor 개발자 키트#
| 형식 | 상태 | 디스크 사용량(MB) | mAP50-95(B) | 추론 시간(ms/이미지) |
|---|---|---|---|---|
| PyTorch | ✅ | 5.3 | 0.4798 | 7.39 |
| TorchScript | ✅ | 9.8 | 0.4789 | 4.21 |
| ONNX | ✅ | 9.5 | 0.4767 | 6.58 |
| OpenVINO | ✅ | 10.1 | 0.4794 | 17.50 |
| TensorRT(FP32) | ✅ | 13.9 | 0.4791 | 1.90 |
| TensorRT(FP16) | ✅ | 7.6 | 0.4797 | 1.39 |
| TensorRT(INT8) | ✅ | 6.5 | 0.4273 | 1.52 |
| TF SavedModel | ✅ | 25.7 | 0.4764 | 47.24 |
| TF GraphDef | ✅ | 9.5 | 0.4764 | 45.98 |
| TF Lite | ✅ | 9.9 | 0.4764 | 182.04 |
| MNN | ✅ | 9.4 | 0.4784 | 21.83 |
Ultralytics 8.4.7로 벤치마크 수행
추론 시간에는 전처리 및 후처리가 포함되지 않습니다.
NVIDIA Jetson AGX Orin 개발자 키트(64GB)#
| 형식 | 상태 | 디스크 사용량(MB) | mAP50-95(B) | 추론 시간(ms/이미지) |
|---|---|---|---|---|
| PyTorch | ✅ | 5.3 | 0.4790 | 11.58 |
| TorchScript | ✅ | 9.8 | 0.4770 | 4.60 |
| ONNX | ✅ | 9.5 | 0.4770 | 9.87 |
| OpenVINO | ✅ | 9.6 | 0.4820 | 28.80 |
| TensorRT(FP32) | ✅ | 11.5 | 0.4770 | 4.18 |
| TensorRT(FP16) | ✅ | 7.9 | 0.4789 | 2.62 |
| TensorRT(INT8) | ✅ | 5.4 | 0.4640 | 2.30 |
| TF SavedModel | ✅ | 24.6 | 0.4760 | 71.10 |
| TF GraphDef | ✅ | 9.5 | 0.4760 | 70.02 |
| TF Lite | ✅ | 9.9 | 0.4760 | 227.94 |
| MNN | ✅ | 9.4 | 0.4760 | 32.46 |
| NCNN | ✅ | 9.3 | 0.4810 | 29.93 |
Ultralytics 8.4.32로 벤치마크 수행
추론 시간에는 전처리 및 후처리가 포함되지 않습니다.
NVIDIA Jetson Orin Nano Super 개발자 키트#
| 형식 | 상태 | 디스크 사용량(MB) | mAP50-95(B) | 추론 시간(ms/이미지) |
|---|---|---|---|---|
| PyTorch | ✅ | 5.3 | 0.4790 | 15.60 |
| TorchScript | ✅ | 9.8 | 0.4770 | 12.60 |
| ONNX | ✅ | 9.5 | 0.4760 | 15.76 |
| OpenVINO | ✅ | 9.6 | 0.4820 | 56.23 |
| TensorRT(FP32) | ✅ | 11.3 | 0.4770 | 7.53 |
| TensorRT(FP16) | ✅ | 8.1 | 0.4800 | 4.57 |
| TensorRT(INT8) | ✅ | 5.3 | 0.4490 | 3.80 |
| TF SavedModel | ✅ | 24.6 | 0.4760 | 118.33 |
| TF GraphDef | ✅ | 9.5 | 0.4760 | 116.30 |
| TF Lite | ✅ | 9.9 | 0.4760 | 286.00 |
| MNN | ✅ | 9.4 | 0.4760 | 68.77 |
| NCNN | ✅ | 9.3 | 0.4810 | 47.50 |
Ultralytics 8.4.33으로 벤치마크 수행
추론 시간에는 전처리 및 후처리가 포함되지 않습니다.
NVIDIA Jetson Orin NX 16GB#
| 형식 | 상태 | 디스크 사용량(MB) | mAP50-95(B) | 추론 시간(ms/이미지) |
|---|---|---|---|---|
| PyTorch | ✅ | 5.3 | 0.4799 | 13.90 |
| TorchScript | ✅ | 9.8 | 0.4787 | 11.60 |
| ONNX | ✅ | 9.5 | 0.4763 | 14.18 |
| OpenVINO | ✅ | 9.6 | 0.4819 | 40.19 |
| TensorRT(FP32) | ✅ | 11.4 | 0.4770 | 7.01 |
| TensorRT(FP16) | ✅ | 8.0 | 0.4789 | 4.13 |
| TensorRT(INT8) | ✅ | 5.5 | 0.4489 | 3.49 |
| TF SavedModel | ✅ | 24.6 | 0.4764 | 92.34 |
| TF GraphDef | ✅ | 9.5 | 0.4764 | 92.06 |
| TF Lite | ✅ | 9.9 | 0.4764 | 254.43 |
| MNN | ✅ | 9.4 | 0.4760 | 48.55 |
| NCNN | ✅ | 9.3 | 0.4805 | 34.31 |
Ultralytics 8.4.33으로 벤치마크 수행
추론 시간에는 전처리 및 후처리가 포함되지 않습니다.
다양한 버전의 NVIDIA Jetson 하드웨어에서 실행한 Seeed Studio의 추가 벤치마크 작업 살펴보기.
결과 재현하기#
모든 내보내기 형식에서 위 Ultralytics 벤치마크를 재현하려면 다음 코드를 실행하세요.
from ultralytics import YOLO

# YOLO26n PyTorch 모델 로드
model = YOLO("yolo26n.pt")

# 모든 내보내기 형식에서 COCO128 데이터셋으로 YOLO26n의 속도와 정확도 벤치마크 수행
results = model.benchmark(data="coco128.yaml", imgsz=640)
벤치마크 결과는 시스템의 정확한 하드웨어 및 소프트웨어 구성과 벤치마크 실행 시점의 시스템 워크로드에 따라 달라질 수 있습니다. 가장 신뢰할 수 있는 결과를 얻으려면 data='coco.yaml'(검증 이미지 5000개)과 같이 이미지 수가 많은 데이터셋을 사용하세요.
NVIDIA Jetson 사용 모범 사례#
NVIDIA Jetson에서 YOLO26의 성능을 최대한 끌어내려면 다음 모범 사례를 따르세요.
-
MAX 전원 모드 활성화
Jetson에서 MAX Power Mode를 활성화하면 모든 CPU 및 GPU 코어가 켜집니다.
sudo nvpmodel -m 0 -
Jetson Clocks 활성화
Jetson Clocks를 활성화하면 모든 CPU 및 GPU 코어가 최대 주파수로 작동합니다.
sudo jetson_clocks -
Jetson Stats 애플리케이션 설치
jetson-stats 애플리케이션을 사용하면 시스템 구성 요소의 온도를 모니터링하고, CPU, GPU 및 RAM 사용률을 확인하고, 전원 모드를 변경하고, 최대 클록을 설정하고, JetPack 정보를 확인할 수 있습니다.
sudo apt update
sudo pip install jetson-stats
sudo reboot
jtop
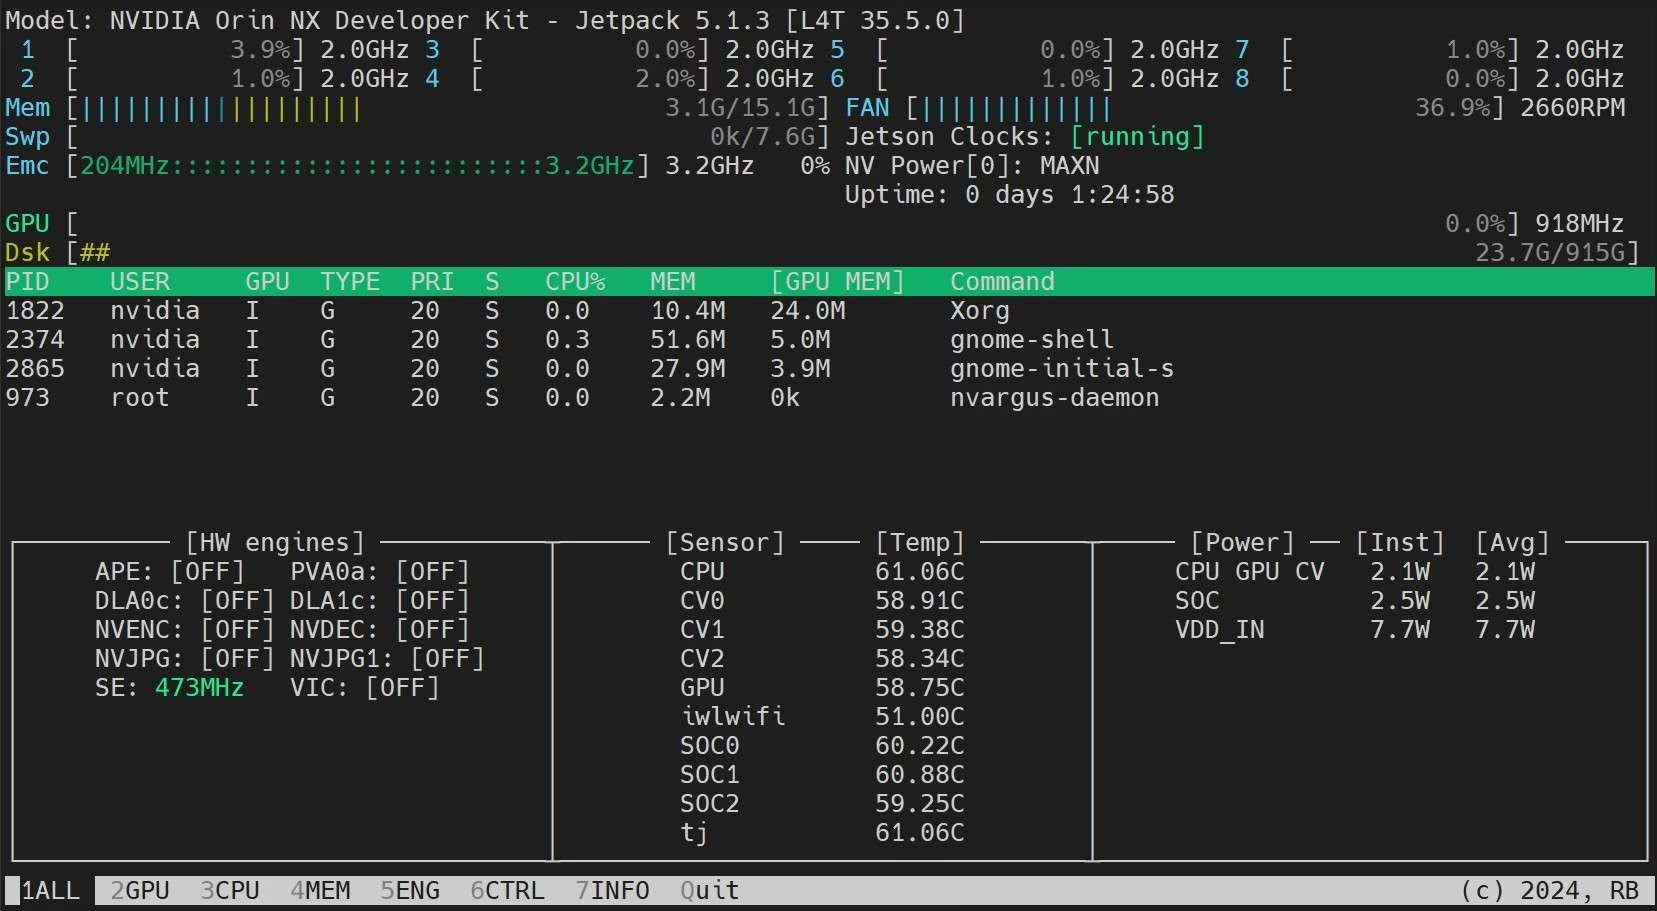
NVIDIA Jetson 메모리 최적화 팁#
사용 가능한 메모리는 Jetson 장치에서 성능을 제한하는 경우가 많으며, 특히 Jetson Orin Nano(8 GB) 또는 Orin NX 8 GB와 같이 메모리가 적은 모델에서 그렇습니다. 아래 팁은 위험 부담이 적고 실용적인 변경 사항으로, 함께 적용하면 수백 MB의 메모리를 확보하여 더 큰 YOLO 모델을 실행하거나 추가 병렬 워크로드를 지원할 수 있습니다. 자세한 내용은 Jetson에서 메모리 효율을 극대화하는 NVIDIA 블로그를 참조하세요.
1. 헤드리스(그래픽 UI 없음) 부팅으로 전환#
Jetson에 SSH로 연결하거나 디스플레이 없이 프로덕션 장치로 실행하는 경우, 데스크톱 환경과 디스플레이 서버를 제거하면 최대 865 MB의 RAM을 확보할 수 있습니다.
sudo systemctl set-default multi-user.target
sudo reboot
나중에 데스크톱 환경을 복원하려면 다음을 실행하세요.
sudo systemctl set-default graphical.target
sudo reboot
2. 사용하지 않는 시스템 서비스 비활성화#
필수적이지 않은 백그라운드 서비스(Bluetooth, 연결 관리자, 사용하지 않는 하드웨어 데몬)는 합쳐서 약 32 MB를 사용합니다. 활성 서비스를 나열하고 배포에 필요하지 않은 서비스를 비활성화하세요.
# List running services
systemctl list-units --type=service --state=running

# Disable a service
sudo systemctl disable SERVICE_NAME
3. 메모리 사용량 프로파일링#
최적화하기 전에 실제로 RAM을 사용하는 프로세스를 확인하세요. procrank은 PSS(비례 집합 크기) 기준으로 프로세스를 정렬합니다. PSS는 RSS(상주 집합 크기, 다른 프로세스와 공유하는 페이지를 포함해 프로세스가 매핑한 전체 물리 RAM 페이지)보다 프로세스별 실제 메모리 사용량을 더 정확하게 나타냅니다.
git clone https://github.com/csimmonds/procrank_linux.git
cd procrank_linux && make
sudo ./procrank
프로세스별 GPU 및 NvMap(CUDA/비디오 파이프라인) 할당량을 확인하려면 다음을 실행하세요.
sudo cat /sys/kernel/debug/nvmap/iovmm/clients4. 프로덕션 환경에서 디스플레이 없이 추론 실행#
실시간 미리 보기가 필요하지 않은 추론 파이프라인에서는 디스플레이 관련 구성 요소(Tiler, OSD, DisplaySink)를 비활성화하는 것만으로 파이프라인에서 200+ MB를 절약할 수 있습니다. Ultralytics YOLO에서는 뷰어를 표시하지 않고 결과를 디스크에 저장하세요.
from ultralytics import YOLO

model = YOLO("yolo26n.engine")

# show=False는 디스플레이 창을 표시하지 않고, save=True는 주석이 추가된 출력을 디스크에 저장합니다.
results = model.predict(source="video.mp4", show=False, save=True)
누적 효과#
| 최적화 | 예상 메모리 절감량 |
|---|---|
| 데스크톱 GUI 비활성화 | ~865 MB |
| 사용하지 않는 OS 서비스 비활성화 | ~32 MB |
| 헤드리스 추론 파이프라인(디스플레이 없음) | ~200+ MB |
| 합계(간단히 적용할 수 있는 최적화) | ~1 GB 이상 |
이러한 변경 사항을 함께 적용하면 메모리가 제한된 장치에서 TensorRT INT8 모델을 사용할 때 특히 유용합니다. 더 큰 모델 변형을 메모리에 적재할 수 있는지 여부를 좌우할 수 있습니다.
다음 단계#
추가 학습 자료와 지원은 Ultralytics YOLO26 문서를 참조하세요.
자주 묻는 질문#
NVIDIA Jetson 디바이스에 Ultralytics YOLO26을 배포하려면 먼저 NVIDIA JetPack SDK로 Jetson 디바이스를 플래싱합니다. 그런 다음 빠르게 설정하려면 사전 빌드된 Docker 이미지를 사용하거나 필요한 패키지를 수동으로 설치합니다.
YOLO26 모델은 NVIDIA Jetson AGX Thor, AGX Orin, Orin Nano Super, Orin NX 장치에서 벤치마크를 수행했으며, TensorRT 형식이 가장 높은 추론 성능을 제공합니다. 상세 비교 표 섹션에는 각 모델과 내보내기 형식의 mAP50-95 및 추론 시간이 나와 있습니다.
NVIDIA Jetson에서 YOLO26 모델을 배포할 때는 TensorRT를 권장합니다. TensorRT는 Jetson GPU에 맞게 모델을 최적화하여 모든 내보내기 형식 중 가장 빠른 추론 속도를 제공합니다.
NVIDIA Jetson에 PyTorch와 Torchvision을 설치하려면 먼저 pip를 통해 설치했을 수 있는 기존 버전을 제거하세요. 그런 다음 Jetson의 ARM64 아키텍처와 호환되는 PyTorch 및 Torchvision 버전을 직접 설치하세요. 자세한 설치 방법은 PyTorch와 Torchvision 설치하기 섹션에 안내되어 있습니다.
YOLO26을 사용하는 NVIDIA Jetson의 성능을 극대화하려면 다음 모범 사례를 따르세요.
- 모든 CPU 및 GPU 코어를 활용하려면 MAX 전원 모드를 활성화하세요.
- 모든 코어를 최대 주파수로 실행하려면 Jetson Clocks를 활성화하세요.
- 시스템 지표를 모니터링하려면 Jetson Stats 애플리케이션을 설치하세요.
명령어와 추가 세부 정보는 NVIDIA Jetson 사용 모범 사례 섹션을 참조하세요.
메모리가 적은 Jetson 장치에서는 사용 가능한 RAM이 병목이 되는 경우가 많습니다. 다음 세 가지 방법을 함께 적용하면 1 GB 이상을 쉽게 확보할 수 있습니다.
- 헤드리스 부팅으로 전환(
sudo systemctl set-default multi-user.target)하여 데스크톱 GUI를 제거합니다(약 865 MB 절약). - Bluetooth 또는 연결 관리자와 같이 사용하지 않는 서비스를 비활성화합니다(약 32 MB 절약).
- YOLO
predict호출에서show=False을 설정해 디스플레이 없이 추론을 실행하면 디스플레이 파이프라인에 할당되는 메모리를 방지할 수 있습니다(200+ MB 절약).
procrank을 사용해 프로세스별 RAM 사용량을 프로파일링하고,sudo cat /sys/kernel/debug/nvmap/iovmm/clients을 사용해 GPU 할당량을 확인하세요. 자세한 내용은 메모리 최적화 팁 섹션을 참조하세요.- 헤드리스 부팅으로 전환(
JetPack 6와 함께 제공된 TensorRT 10.3.0에는 NMS가 없는(
nms=False) 출력 또는 NMS가 내장된(nms=True) 출력을 사용해 INT8 엔진을 빌드하지 못하게 하는 알려진 문제가 있습니다. Ultralytics는 이러한 조합을 감지하면 NMS가 없는 내보내기에는 one-to-many 헤드를 선택하고nms=True내보내기는 오류와 함께 중단합니다.이러한 INT8 내보내기를 다시 사용하려면 TensorRT를 최신 버전(예: 10.7.0 이상)으로 업그레이드하세요:
wget https://developer.download.nvidia.com/compute/cuda/repos/ubuntu2204/arm64/cuda-keyring_1.1-1_all.deb
sudo dpkg -i cuda-keyring_1.1-1_all.deb
sudo apt-get update
sudo apt-get install -y tensorrt
업그레이드한 후 내보내기를 다시 실행하세요. 자세한 내용은 GitHub 이슈 #23841 및 이슈 #26655을 참조하세요.


댓글194
질문을 하거나 결과를 공유하거나 다른 사람을 도와주세요.
LG973641114
您好,如何用c++在jetson上部署YOLO26,有相关例子吗
1pknowler
Struggling with this on a new Jetson Orin Nano JP6.1. All good following the steps and installs to give torch.cuda.is_available as TRUE. The TensorRT export fails though with a number of dependency errors and I can’t re-install it with anything. Any pointers please?
1 Glenn JocherUltralytics
@pknowler it seems like the dependency errors during TensorRT export might stem from compatibility issues. Please ensure you’ve installed the required JetPack-compatible versions of PyTorch, Torchvision, and TensorRT as outlined in the Jetson Quick Start Guide. Additionally, verify that
onnxruntime-gpuandcuSPARSELtare correctly installed per the guide. If the issue persists, you can try reinstalling TensorRT using the NVIDIA SDK Manager for your JetPack version. Let me know if you need further clarification!Thank you. I will try again working through all of the steps and let you know how it goes!
I’ve tried again but this as far as I get… I have followed everything carefully.
WARNING ⚠️ TensorRT requires GPU export, automatically assigning device=0 Ultralytics 8.3.57 🚀 Python-3.10.16 torch-2.5.0a0+872d972e41.nv24.08 CUDA:0 (Orin, 7620MiB) YOLO11n summary (fused): 238 layers, 2,616,248 parameters, 0 gradients, 6.5 GFLOPs
PyTorch: starting from 'yolo11n.pt' with input shape (1, 3, 640, 640) BCHW and output shape(s) (1, 84, 8400) (5.4 MB)
ONNX: starting export with onnx 1.17.0 opset 19... ONNX: slimming with onnxslim 0.1.46... ONNX: export success ✅ 3.1s, saved as 'yolo11n.onnx' (10.2 MB) requirements: Ultralytics requirement ['tensorrt>7.0.0,!=10.1.0'] not found, attempting AutoUpdate... error: subprocess-exited-with-error
× python setup.py egg_info did not run successfully. │ exit code: 1 ╰─> [6 lines of output] Traceback (most recent call last): File "", line 2, in File "", line 34, in File "/tmp/pip-install-d0ljzl60/tensorrt-cu12_db0552ac431148489703f6f75df6764f/setup.py", line 71, in raise RuntimeError("TensorRT does not currently build wheels for Tegra systems") RuntimeError: TensorRT does not currently build wheels for Tegra systems [end of output]
note: This error originates from a subprocess, and is likely not a problem with pip. error: metadata-generation-failed
× Encountered error while generating package metadata. ╰─> See above for output.
note: This is an issue with the package mentioned above, not pip. hint: See above for details. Retry 1/2 failed: Command 'pip install --no-cache-dir "tensorrt>7.0.0,!=10.1.0" ' returned non-zero exit status 1. error: subprocess-exited-with-error
× python setup.py egg_info did not run successfully. │ exit code: 1 ╰─> [6 lines of output] Traceback (most recent call last): File "", line 2, in File "", line 34, in File "/tmp/pip-install-782zjqf9/tensorrt-cu12_44d261aea7c5489db3e9ce15cec8ee64/setup.py", line 71, in raise RuntimeError("TensorRT does not currently build wheels for Tegra systems") RuntimeError: TensorRT does not currently build wheels for Tegra systems [end of output]
note: This error originates from a subprocess, and is likely not a problem with pip. error: metadata-generation-failed
× Encountered error while generating package metadata. ╰─> See above for output.
note: This is an issue with the package mentioned above, not pip. hint: See above for details.
And I have TensorRT 10.7.0.23-1+cuda12.6
- Glenn JocherUltralytics
@pknowler it seems your TensorRT version is not compatible with the Jetson's ARM64 architecture. TensorRT does not provide pre-built Python wheels for Tegra systems. Please ensure you have TensorRT installed via the NVIDIA SDK Manager as part of the JetPack installation, and confirm compatibility with your JetPack version. The Jetson Quick Start Guide might also help clarify setup specifics. Let me know if further assistance is needed!
@glenn-jocher thank you. I have found the issue now. I am using miniconda and for some reason TensorRT Python bindings are not available in conda envs. So I can import Torch with no problem but the import TensorRT fails. I have re-installed without conda and all works as expected! 👍🏻
RasoulZardeyni
Which one reduce inference time using TensorRT or deepstream?
1 Paula DerrengerUltralytics(수정됨)
In terms of reducing inference time on your NVIDIA Jetson device, using TensorRT is generally recommended. TensorRT is specifically designed to provide high performance for NVIDIA hardware by optimizing deep learning models for inference. It accelerates models by fusing layers, pruning unused layers, and quantizing variables, among other optimizations. 🚀
DeepStream, on the other hand, is more focused on streaming analytics and can utilize TensorRT-optimized models. For most cases, directly using TensorRT for model optimization is your go-to for minimizing inference times.
Here's a quick example of exporting a YOLO model to TensorRT and running inference, tailored for your convenience:
from ultralytics import YOLO

# Load your YOLO model
model = YOLO('yolo26n.pt')

# Export to TensorRT format
model.export(format='engine')

# Load the TensorRT model
trt_model = YOLO('yolo26n.engine')

# Run inference using the TensorRT model
results = trt_model('your_image_or_video.jpg')
Feel free to explore more about deploying on NVIDIA Jetson with our Quick Start Guide for NVIDIA Jetson. Happy inferencing! 🌟
2Thanks!
1- Paula DerrengerUltralytics(수정됨)
Hey there! 😊 It looks like you're interested in speeding up your inference times. Between TensorRT and DeepStream on NVIDIA Jetson devices, TensorRT typically offers more direct optimization for reducing inference time for individual models by providing lower-level optimizations and quantization options.
DeepStream is a comprehensive framework for building end-to-end video analytics applications, which utilizes TensorRT under the hood for model inference. DeepStream excels in scenarios involving video streams, multi-stream input, and complex pipelines involving multiple AI models and analytics. If your primary goal is solely to minimize inference time for a specific model, direct optimization via TensorRT can provide more focused improvements.
A quick example of exporting a YOLO model to TensorRT:
from ultralytics import YOLO

# Load your YOLO model
model = YOLO('yolo26n.pt')

# Export to TensorRT format
model.export(format='engine')  # This creates 'yolo26n.engine'

# Done! Now you can use 'yolo26n.engine' for faster inference.
However, if your application benefits from a broader video analytics pipeline, incorporating DeepStream into your workflow can optimize and streamline these processes on top of efficiently handling inference with TensorRT optimized models. 🚀
Hope this gives you a clearer picture! If you have more questions, feel free to ask.
1
 Yufeng Wu(수정됨)
Hi, ultralytics team. I'm trying yolo26n-pose on Jetson orin agx 64gb and have this problem: I tried building engine with dynamic=true but failed, with the log saying ForeignNode[/model.23/Sigmoid.../model.23/Flatten] (Myelin) Skipping tactic ... Incompatible effective shapes in operation /model_23/Sub between: Unsqueeze_18_output_0 f32[1,2,33600] and Slice_output_0 f32[1,2,21504] Could not find any implementation for node {ForeignNode[/model.23/Sigmoid.../model.23/Flatten]} Is there a way to fix it?
- Glenn JocherUltralytics
This indicates a TensorRT dynamic-shape profile failure in the pose head. As a workaround, export a fixed-resolution engine, e.g.
yolo export model=yolo26n-pose.pt format=engine imgsz=640 batch=1 dynamic=False; build separate engines if multiple resolutions are required. If dynamic shapes are essential, please open a new issue with the full text log,yolo checksoutput, and JetPack/TensorRT/Ultralytics versions so we can reproduce it; see the TensorRT export guide.
 Haotian Gong(수정됨)
Hi, everyone,
I'd like to flag two issues with the Jetson installation guide that may need updating.
1. PyTorch 2.10.0 / Torchvision 0.25.0 doesn't work on JetPack 6.1
Following the "Start with naive installation" and "Run on JetPack 6.1" sections, I installed Pytorch 2.10.0 and Torchvision 0.25.0 as instructed.
Running my script then throws:
ImportError: libcublas.so.13: cannot open shared object file: No such file or directorySo I have to install Pytorch 2.8.0 with the guide:
https://forums.developer.nvidia.com/t/jetson-orin-nano-issues-running-yolo-ultralytics-due-to-pytorch-torchvision-compatibility-jetpack-6-x-cuda-12-6/365683/9And this version of Pytorch works. So maybe is the guide on Jetson obsolete or mistaken?
2. CSI camera requires the JetPack-bundled OpenCV, not the PyPI one
On Jetson, using a CSI camera (via
nvarguscamerasrc) requires the OpenCV that ships with JetPack, because the PyPIopencv-pythonwheel on aarch64 is built without GStreamer support.However,
pip install ultralyticspulls inopencv-pythonas a dependency, which shadows the JetPack-bundled version and silently breaks CSI camera pipelines.pip uninstall -y opencv-python opencv-python-headless sudo apt install -y python3-opencv # JetPack-bundled OpenCV with GStreamerThanks!
 Lakshantha DissanayakeUltralytics
Hi @ZephyrKeXiner Could you please double check whether you are using JetPack 6.1 system with CUDA 12.6? I have just verified on my JetPack 6.1 system with CUDA 12.6 with
torch-2.10.0andtorchvision-0.25.0as mentioned in the Ultralytics Jetson Guide and it works well.For JetPack 6.1, output of
cat /etc/nv_tegra_releaseshould look like below:(env) nvidia@ubuntu:~/yolo26/ultralytics$ cat /etc/nv_tegra_release # R36 (release), REVISION: 4.3, GCID: 38968081, BOARD: generic, EABI: aarch64, DATE: Wed Jan 8 01:49:37 UTC 2025 # KERNEL_VARIANT: oot TARGET_USERSPACE_LIB_DIR=nvidia TARGET_USERSPACE_LIB_DIR_PATH=usr/lib/aarch64-linux-gnu/nvidiaCould you also share yours please? Thanks!
cc: @raimbekovm
1- Haotian Gong
Hi @lakshanthad,
My output of
cat /etc/nv_tegra_releaseis below:$ cat /etc/nv_tegra_release # R36 (release), REVISION: 5.0, GCID: 43688277, BOARD: generic, EABI: aarch64, DATE: Fri Jan 16 03:50:45 UTC 2026 # KERNEL_VARIANT: oot TARGET_USERSPACE_LIB_DIR=nvidia TARGET_USERSPACE_LIB_DIR_PATH=usr/lib/aarch64-linux-gnu/nvidiaI notice that the revision is 5.0 not 4.3. Maybe does it cause the error?
smbunn(수정됨)
I would have thought the Jetson Orin Nano could do more than 5 streams, the deepstream examples with cars handles 16 streams of 1080p at what appears to be full framerate.
As a control systems engineer by training, edge devices seem a much better way to go so I prefer your jetson design. Even if one Jetson has an issue you are still processing 45 streams whereas a problem on your centralised server in option 2 takes everything down.
Are you going to set up an MQTT feed for alerts from each stream? Maybe consider secondary processing and a buffer, so the edge device detects what it thinks is an issue and a centralised server grabs 5 seconds of video of the incident and double checks.
Simon BUNN
General
From: Yash Patel @.> Sent: Friday, 22 May 2026 4:00 am To: ultralytics/ultralytics @.> Cc: Bunn, Simon @.>; Mention @.> Subject: Re: [ultralytics/ultralytics] guides/nvidia-jetson/ (Discussion #9942)
Hi, I am designing an AI-based CCTV surveillance system for a residential society with 50 RTSP camera streams. My current architecture uses multiple NVIDIA Jetson Orin Nano Super Developer Kit devices for distributed inference processing. I ZjQcmQRYFpfptBannerStart Attention The sender's identity could not be verified and someone may be impersonating the sender. L'identité de l'expéditeur n'a pas pu être vérifiée et quelqu'un pourrait se faire passer pour l'expéditeur.
ZjQcmQRYFpfptBannerEnd
Hi, I am designing an AI-based CCTV surveillance system for a residential society with 50 RTSP camera streams. My current architecture uses multiple NVIDIA Jetson Orin Nano Super Developer Kit devices for distributed inference processing. I estimate that one Jetson Orin Nano Super (8GB) can process around 5 RTSP streams at usable real-time FPS. This requires approximately 10 Jetson devices for the full deployment. Each device costs around ₹33,000 (~USD 395). The total estimated hardware cost is ₹330,000 (~USD 3,950). I want to compare this setup against a centralized Linux-based custom PC/server with NVIDIA GPU acceleration under the same budget. The comparison focuses on AI inference performance, scalability, reliability, and 24/7 operational efficiency. The workload mainly includes multi-stream YOLO/object detection inference on live RTSP feeds. I want to determine which architecture provides the best computation-to-cost ratio for this surveillance use case.
— Reply to this email directly, view it on GitHubhttps://urldefense.com/v3/__https://github.com/orgs/ultralytics/discussions/9942*discussioncomment-17006943__;Iw!!ElGdukoduuk!URiPjKkgDoMT_k2Y6pEd3XMEBGMDjhwgtQmwWXR9F4R4L7ymNloZD79NanOjYVg9YYmaARqyZGbgFv7U15KzgdcU$, or unsubscribehttps://urldefense.com/v3/__https://github.com/notifications/unsubscribe-auth/ABAAMILYUP7PPODNHDR3HC3434RYLAVCNFSM6AAAAABGAK2IGGVHI2DSMVQWIX3LMV43URDJONRXK43TNFXW4Q3PNVWWK3TUHMYTOMBQGY4TIMY__;!!ElGdukoduuk!URiPjKkgDoMT_k2Y6pEd3XMEBGMDjhwgtQmwWXR9F4R4L7ymNloZD79NanOjYVg9YYmaARqyZGbgFv7U1zjhi4YU$. Triage notifications on the go with GitHub Mobile for iOShttps://urldefense.com/v3/__https://apps.apple.com/app/apple-store/id1477376905?ct=notification-email&mt=8&pt=524675__;!!ElGdukoduuk!URiPjKkgDoMT_k2Y6pEd3XMEBGMDjhwgtQmwWXR9F4R4L7ymNloZD79NanOjYVg9YYmaARqyZGbgFv7U13gOq1qb$ or Androidhttps://urldefense.com/v3/__https://play.google.com/store/apps/details?id=com.github.android&referrer=utm_campaign*3Dnotification-email*26utm_medium*3Demail*26utm_source*3Dgithub__;JSUlJSU!!ElGdukoduuk!URiPjKkgDoMT_k2Y6pEd3XMEBGMDjhwgtQmwWXR9F4R4L7ymNloZD79NanOjYVg9YYmaARqyZGbgFv7U1zOl3XaF$. You are receiving this because you were mentioned.Message ID: @.***>
- Glenn JocherUltralytics
5streams on an Orin Nano Super is just a conservative YOLO/Python estimate; with a headless TensorRT or DeepStream pipeline, MAX power mode, andjetson_clocks, higher 1080p stream counts are definitely possible and depend heavily on the model size, input resolution, decode/encode, and any tracking or alert logic you add, so please drop your exactmodel,imgsz, FPS target, and RTSP resolution here and we can help size it more accurately using the Jetson deployment guide and DeepStream Jetson guide.
yashpatel2010
Hi, I am designing an AI-based CCTV surveillance system for a residential society with 50 RTSP camera streams. My current architecture uses multiple NVIDIA Jetson Orin Nano Super Developer Kit devices for distributed inference processing. I estimate that one Jetson Orin Nano Super (8GB) can process around 5 RTSP streams at usable real-time FPS. This requires approximately 10 Jetson devices for the full deployment. Each device costs around ₹33,000 (~USD 395). The total estimated hardware cost is ₹330,000 (~USD 3,950). I want to compare this setup against a centralized Linux-based custom PC/server with NVIDIA GPU acceleration under the same budget. The comparison focuses on AI inference performance, scalability, reliability, and 24/7 operational efficiency. The workload mainly includes multi-stream YOLO/object detection inference on live RTSP feeds. I want to determine which architecture provides the best computation-to-cost ratio for this surveillance use case.
RotatingGiraffe
Hi there, I am trying to run a fine-tuned YOLO26 based model for an OBB task on a Xavier NX running JetPack 5. I am using your container (ultralytics/ultralytics:latest-jetson-jetpack5) and trying to compile from PyTorch to TensorRT. I get the error: "mymodel.pt requires numpy>=1.26.1, however numpy==1.23.5 is installed."
Previously I have successfully the file on my host machine from PT to ONNX, copied ONNX to Jetson and then used tensorrtexec to compile to Engine. But the resulting models did not create any bounding boxes.
I wanted to ask if JetPack 5 even supports Yolo26 or if the model contains some incompatible layers? YOLO11 OBB works fine which I find extra-weird. Or is there likely an error somewhere else in my script?
- Glenn JocherUltralytics
Thanks for posting this here—JetPack 5 on Xavier NX is supported for YOLO26/TensorRT in our Jetson guide, so the
numpy>=1.26.1error points more to an environment/checkpoint mismatch than unsupported OBB layers; please paste the full text traceback andyolo checksoutput, and note that an engine built withtensorrtexeccan still produce empty OBB results if the Ultralytics export metadata/postprocessing is not preserved. Hi there, I tried to create a minimal reproducible example for you, based on what I am doing. I hope it helps with debugging.
The yolo checks you asked for is in the script output, along with the export script. I've also included the bit where I export via trtexex just for the sake of completion - it might very well be possible that I omit required metadata with this. My prefered goal would be that everything works via the Ultralytics Python API, but I had to search for workaround due to the NumPy error when compiling PT files.
I am now using the Ultralytics base image in the MRE which I hoped would be easier to debug for us. The NumPy error persists on the new image. Previously I was using something built upon l4t-ml.
Additionally, ONNX fails with an error ( `GLIBCXX_3.4.29' not found I think it was) but that is not a concern to me since I engine would be my prefered way to go. I have not installed any additional packages and kept it very vanilla (see dockerfile). The MRE also weirdly produced a new error during engine inference, but I'd say lets just focus on getting the Ultralytics native pipeline to work and then maybe all the other issues were just from my workarounds and disappear.
Execution Command
sudo docker compose up --buildDirectory Structure
obb-test-repro/
 ┣ 📂data/
 ┃ ┗ 📜mydataset.yaml
 ┣ 📂models/
 ┃ ┣ 📜my-yolo26m-model.onnx
 ┃ ┗ 📜my-yolo26m-model.pt
 ┣ 📂src/
 ┃ ┗ 📜main.py
 ┣ 📜docker-compose.yml
 ┣ 📜Dockerfile
 ┗ 📜requirements.txt
Dockerfile
FROM ultralytics/ultralytics:latest-jetson-jetpack5

WORKDIR /app

# Copy the test app
COPY src/ ./src/

# Run the test
CMD ["python3", "src/main.py"]
docker-compose.yml
version: '3.8'

services:
  obb-test-jp5:
    image: obb-test:latest
    container_name: obb_test_jp5
    build:
      context: .
      dockerfile: Dockerfile
    runtime: nvidia
    network_mode: host
    ipc: host
    restart: "no"
    volumes:
      - ./models:/app/models
      - ./data:/app/data
    environment:
      - NVIDIA_VISIBLE_DEVICES=all
      - NVIDIA_DRIVER_CAPABILITIES=all
main.py
"""
Minimal OBB model test script.

Behavior:
- Runs `yolo checks` to output environment details.
- Uses files in `/app/models` (container path mapped from `obb-test/models`).
- Expects two files (hard-coded):
  - `/app/models/my-yolo26m-model.pt` (optional) — used for Ultralytics native export
  - `/app/models/my-yolo26m-model.onnx` (optional) — used for trtexec compilation
- Runs both export methods (if files exist) and validates inference on each compiled engine using mydataset dataset.
"""

import logging
import sys
import subprocess
import os
from pathlib import Path
from ultralytics import YOLO

# Configure logging
logging.basicConfig(
    level=logging.INFO,
    format='%(asctime)s - %(levelname)s - %(message)s'
)
logger = logging.getLogger(__name__)


def run_yolo_checks():
    """Execute yolo checks via CLI to log environment details."""
    logger.info("=" * 60)
    logger.info("Environment Verification (yolo checks)")
    logger.info("=" * 60)
    try:
        res = subprocess.run(["yolo", "checks"], capture_output=True, text=True, check=True)
        logger.info("\n" + res.stdout.strip())
    except subprocess.CalledProcessError as e:
        logger.error(f"yolo checks failed:\n{e.stderr}")
    except FileNotFoundError:
        logger.error("yolo CLI command not found. Ensure ultralytics is installed in this environment.")


def test_export_to_engine():
    models_dir = Path("/app/models")
    pt_path = models_dir / "my-yolo26m-model.pt"
    onnx_path = models_dir / "my-yolo26m-model.onnx"
    dataset_yaml = "/app/data/mydataset.yaml"

    logger.info("=" * 60)
    logger.info("Minimal OBB Test - Export & Validation")
    logger.info("=" * 60)

    engines_tested = []

    # Part 1: Ultralytics native export (PT -> Engine)
    if pt_path.exists():
        try:
            logger.info(f"\nRunning Ultralytics native export for: {pt_path.name}")
            model = YOLO(str(pt_path))
            exported = model.export(format="engine", imgsz=1024, device=0, half=True)

            # Resolve the exported engine path
            native_engine = str(exported) if isinstance(exported, (str, Path)) else str(pt_path.with_suffix('.engine'))

            if os.path.exists(native_engine):
                logger.info(f"Ultralytics export successfully produced: {native_engine}")
                engines_tested.append(native_engine)
            else:
                logger.error(f"Ultralytics export completed, but engine file was not found at {native_engine}")
        except Exception as e:
            logger.error(f"Ultralytics native export failed: {e}", exc_info=True)
    else:
        logger.info(f"PT file not found ({pt_path}); skipping Ultralytics native export.")

    # Part 2: trtexec compilation (ONNX -> Engine)
    if onnx_path.exists():
        try:
            logger.info(f"\nRunning trtexec to compile ONNX: {onnx_path.name}")
            trt_engine = str(onnx_path.with_suffix('.trt.engine'))
            cmd = [
                "/usr/src/tensorrt/bin/trtexec",
                f"--onnx={onnx_path}",
                f"--saveEngine={trt_engine}",
                "--fp16",
                "--memPoolSize=workspace:768", # Prevents Out of Memory
            ]
            logger.info(f"Running command: {' '.join(cmd)}")
            res = subprocess.run(cmd, capture_output=True, text=True)

            if res.returncode != 0:
                logger.error("trtexec compilation failed.")
                logger.error(f"trtexec stderr:\n{res.stderr}")
            else:
                if os.path.exists(trt_engine):
                    logger.info(f"trtexec successfully saved engine to {trt_engine}")
                    engines_tested.append(trt_engine)
                else:
                    logger.error(f"trtexec returned success, but engine file was not found at {trt_engine}")
        except Exception as e:
            logger.error(f"trtexec execution failed: {e}", exc_info=True)
    else:
        logger.info(f"ONNX file not found ({onnx_path}); skipping trtexec compilation.")

    if not engines_tested:
        logger.error("\nNo engines are available to test. Exiting validation phase.")
        return False

    # Part 3: Inference Validation
    validation_success = True
    for eng in engines_tested:
        try:
            logger.info(f"\nValidating inference with engine: {eng}")

            model = YOLO(eng, task="obb")
            metrics = model.val(data=dataset_yaml, imgsz=1024, batch=1, verbose=False)

            logger.info(f"Validation metrics for {eng}: mAP50-95={metrics.box.map:.4f}, mAP50={metrics.box.map50:.4f}")
        except Exception as e:
            logger.error(f"Validation failed on {eng}: {e}", exc_info=True)
            validation_success = False

    logger.info("\nExecution complete.")
    return validation_success


if __name__ == "__main__":
    run_yolo_checks()

    try:
        success = test_export_to_engine()
        logger.info("\n" + "=" * 60)
        if success:
            logger.info("✓ Test passed")
        else:
            logger.info("✗ Test failed")
        logger.info("=" * 60)
        sys.exit(0 if success else 1)
    except Exception as e:
        logger.error(f"Unhandled script exception: {e}", exc_info=True)
        sys.exit(1)
Output
obb_test_jp5  | Creating new Ultralytics Settings v0.0.6 file ✅
obb_test_jp5  | View Ultralytics Settings with 'yolo settings' or at '/root/.config/Ultralytics/settings.json'
obb_test_jp5  | Update Settings with 'yolo settings key=value', i.e. 'yolo settings runs_dir=path/to/dir'. For help see https://docs.ultralytics.com/quickstart/#ultralytics-settings.
obb_test_jp5  | 2026-05-14 12:51:35,392 - INFO - ============================================================
obb_test_jp5  | 2026-05-14 12:51:35,392 - INFO - Environment Verification (yolo checks)
obb_test_jp5  | 2026-05-14 12:51:35,392 - INFO - ============================================================
obb_test_jp5  | 2026-05-14 12:51:50,554 - INFO -
obb_test_jp5  | Ultralytics 8.4.50 🚀 Python-3.8.10 torch-2.1.0a0+41361538.nv23.06 CUDA:0 (Xavier, 6833MiB)
obb_test_jp5  | Setup complete ✅ (2 CPUs, 6.7 GB RAM, 91.7/107.6 GB disk)
obb_test_jp5  |
obb_test_jp5  | OS                     Linux-5.10.216-tegra-aarch64-with-glibc2.29
obb_test_jp5  | Environment            Docker
obb_test_jp5  | Python                 3.8.10
obb_test_jp5  | Install                git
obb_test_jp5  | Path                   /ultralytics/ultralytics
obb_test_jp5  | RAM                    6.67 GB
obb_test_jp5  | Disk                   91.7/107.6 GB
obb_test_jp5  | CPU                    ARMv8 Processor rev 0 (v8l)
obb_test_jp5  | CPU count              2
obb_test_jp5  | GPU                    Xavier, 6833MiB
obb_test_jp5  | GPU count              1
obb_test_jp5  | CUDA                   11.4
obb_test_jp5  |
obb_test_jp5  | numpy                  ✅ 1.23.5>=1.23.0
obb_test_jp5  | matplotlib             ✅ 3.7.5>=3.3.0
obb_test_jp5  | opencv-python-headless ✅ 4.13.0.92>=4.6.0
obb_test_jp5  | pillow                 ✅ 10.4.0>=7.1.2
obb_test_jp5  | pyyaml                 ✅ 6.0.3>=5.3.1
obb_test_jp5  | requests               ✅ 2.32.4>=2.23.0
obb_test_jp5  | scipy                  ✅ 1.10.1>=1.4.1
obb_test_jp5  | torch                  ✅ 2.1.0a0+41361538.nv23.6>=1.8.0
obb_test_jp5  | torchvision            ✅ 0.16.2+c6f3977>=0.9.0
obb_test_jp5  | psutil                 ✅ 7.2.2>=5.8.0
obb_test_jp5  | polars                 ✅ 1.8.2>=0.20.0
obb_test_jp5  | ultralytics-thop       ✅ 2.0.19>=2.0.18
obb_test_jp5  | torch                  ✅ 2.1.0a0+41361538.nv23.6!=2.4.0,>=1.8.0; sys_platform == "win32"
obb_test_jp5  | 2026-05-14 12:51:50,562 - INFO - ============================================================
obb_test_jp5  | 2026-05-14 12:51:50,563 - INFO - Minimal OBB Test - Export & Validation
obb_test_jp5  | 2026-05-14 12:51:50,564 - INFO - ============================================================
obb_test_jp5  | 2026-05-14 12:51:50,565 - INFO -
obb_test_jp5  | Running Ultralytics native export for: my-yolo26m-model.pt
obb_test_jp5  | 2026-05-14 12:51:51,353 - ERROR - Ultralytics native export failed: ERROR ❌️ /app/models/my-yolo26m-model.pt requires numpy>=1.26.1, however numpy==1.23.5 is installed.
obb_test_jp5  | Traceback (most recent call last):
obb_test_jp5  |   File "/ultralytics/ultralytics/nn/tasks.py", line 1466, in torch_safe_load
obb_test_jp5  |     ckpt = _load()
obb_test_jp5  |   File "/ultralytics/ultralytics/nn/tasks.py", line 1463, in _load
obb_test_jp5  |     return torch_load(file, map_location="cpu")
obb_test_jp5  |   File "/ultralytics/ultralytics/utils/patches.py", line 181, in torch_load
obb_test_jp5  |     return torch.load(*args, **kwargs)
obb_test_jp5  |   File "/usr/local/lib/python3.8/dist-packages/torch/serialization.py", line 877, in load
obb_test_jp5  |     return _load(opened_zipfile, map_location, pickle_module, **pickle_load_args)
obb_test_jp5  |   File "/usr/local/lib/python3.8/dist-packages/torch/serialization.py", line 1253, in _load
obb_test_jp5  |     result = unpickler.load()
obb_test_jp5  |   File "/usr/local/lib/python3.8/dist-packages/torch/serialization.py", line 1246, in find_class
obb_test_jp5  |     return super().find_class(mod_name, name)
obb_test_jp5  | ModuleNotFoundError: No module named 'numpy._core'
obb_test_jp5  |
obb_test_jp5  | The above exception was the direct cause of the following exception:
obb_test_jp5  |
obb_test_jp5  | Traceback (most recent call last):
obb_test_jp5  |   File "src/minimal.py", line 58, in test_export_to_engine
obb_test_jp5  |     model = YOLO(str(pt_path))
obb_test_jp5  |   File "/ultralytics/ultralytics/models/yolo/model.py", line 76, in __init__
obb_test_jp5  |     super().__init__(model=model, task=task, verbose=verbose)
obb_test_jp5  |   File "/ultralytics/ultralytics/engine/model.py", line 144, in __init__
obb_test_jp5  |     self._load(model, task=task)
obb_test_jp5  |   File "/ultralytics/ultralytics/engine/model.py", line 283, in _load
obb_test_jp5  |     self.model, self.ckpt = load_checkpoint(weights)
obb_test_jp5  |   File "/ultralytics/ultralytics/nn/tasks.py", line 1537, in load_checkpoint
obb_test_jp5  |     ckpt, weight = torch_safe_load(weight)  # load ckpt
obb_test_jp5  |   File "/ultralytics/ultralytics/nn/tasks.py", line 1489, in torch_safe_load
obb_test_jp5  |     raise ModuleNotFoundError(
obb_test_jp5  | ModuleNotFoundError: ERROR ❌️ /app/models/my-yolo26m-model.pt requires numpy>=1.26.1, however numpy==1.23.5 is installed.
obb_test_jp5  | 2026-05-14 12:51:51,382 - INFO -
obb_test_jp5  | Running trtexec to compile ONNX: my-yolo26m-model.onnx
obb_test_jp5  | 2026-05-14 12:51:51,382 - INFO - Running command: /usr/src/tensorrt/bin/trtexec --onnx=/app/models/my-yolo26m-model.onnx --saveEngine=/app/models/my-yolo26m-model.trt.engine --fp16 --memPoolSize=workspace:768
obb_test_jp5  | 2026-05-14 13:21:39,214 - INFO - trtexec successfully saved engine to /app/models/my-yolo26m-model.trt.engine
obb_test_jp5  | 2026-05-14 13:21:39,217 - INFO -
obb_test_jp5  | Validating inference with engine: /app/models/my-yolo26m-model.trt.engine
obb_test_jp5  | Ultralytics 8.4.50 🚀 Python-3.8.10 torch-2.1.0a0+41361538.nv23.06 CUDA:0 (Xavier, 6833MiB)
obb_test_jp5  | Loading /app/models/my-yolo26m-model.trt.engine for TensorRT inference...
obb_test_jp5  | [05/14/2026-13:21:41] [TRT] [I] Loaded engine size: 43 MiB
obb_test_jp5  | [05/14/2026-13:21:45] [TRT] [I] [MemUsageChange] Init cuBLAS/cuBLASLt: CPU +260, GPU +306, now: CPU 648, GPU 5277 (MiB)
obb_test_jp5  | [05/14/2026-13:21:46] [TRT] [I] [MemUsageChange] Init cuDNN: CPU +82, GPU +156, now: CPU 730, GPU 5433 (MiB)
obb_test_jp5  | [05/14/2026-13:21:46] [TRT] [I] [MemUsageChange] TensorRT-managed allocation in engine deserialization: CPU +0, GPU +41, now: CPU 0, GPU 41 (MiB)
obb_test_jp5  | [05/14/2026-13:21:46] [TRT] [I] [MemUsageChange] Init cuBLAS/cuBLASLt: CPU +0, GPU +28, now: CPU 687, GPU 5422 (MiB)
obb_test_jp5  | [05/14/2026-13:21:46] [TRT] [I] [MemUsageChange] Init cuDNN: CPU +0, GPU +32, now: CPU 687, GPU 5454 (MiB)
obb_test_jp5  | [05/14/2026-13:21:46] [TRT] [I] [MemUsageChange] TensorRT-managed allocation in IExecutionContext creation: CPU +0, GPU +92, now: CPU 0, GPU 133 (MiB)
obb_test_jp5  | Setting batch=1 input of shape (1, 3, 1024, 1024)
obb_test_jp5  | 2026-05-14 13:21:54,562 - INFO - generated new fontManager
obb_test_jp5  | val: Fast image access ✅ (ping: 1.1±0.9 ms, read: 479.2±146.1 MB/s, size: 2563.4 KB)
val: Scanning /app/data/labels/rec26.cache... 2940 images, 26 backgrounds, 0 corrupt: 100% ━━━━━━━━━━━━ 2940/2940 14.4Mit/s 0.0s
obb_test_jp5  | 2026-05-14 13:22:01,033 - ERROR - Validation failed on /app/models/my-yolo26m-model.trt.engine: CUDA error: no kernel image is available for execution on the device
obb_test_jp5  | CUDA kernel errors might be asynchronously reported at some other API call, so the stacktrace below might be incorrect.
obb_test_jp5  | For debugging consider passing CUDA_LAUNCH_BLOCKING=1.
obb_test_jp5  | Compile with `TORCH_USE_CUDA_DSA` to enable device-side assertions.
obb_test_jp5  | Traceback (most recent call last):
obb_test_jp5  |   File "src/minimal.py", line 114, in test_export_to_engine
obb_test_jp5  |     metrics = model.val(data=dataset_yaml, imgsz=1024, batch=1, verbose=False)
obb_test_jp5  |   File "/ultralytics/ultralytics/engine/model.py", line 615, in val
obb_test_jp5  |     validator(model=self.model)
obb_test_jp5  |   File "/usr/local/lib/python3.8/dist-packages/torch/utils/_contextlib.py", line 115, in decorate_context
obb_test_jp5  |     return func(*args, **kwargs)
obb_test_jp5  |   File "/ultralytics/ultralytics/engine/validator.py", line 210, in __call__
obb_test_jp5  |     model.warmup(imgsz=(1 if pt else self.args.batch, self.data["channels"], imgsz, imgsz))  # warmup
obb_test_jp5  |   File "/ultralytics/ultralytics/nn/autobackend.py", line 313, in warmup
obb_test_jp5  |     non_max_suppression(warmup_boxes)  # warmup NMS
obb_test_jp5  |   File "/ultralytics/ultralytics/utils/nms.py", line 154, in non_max_suppression
obb_test_jp5  |     i = torchvision.ops.nms(boxes, scores, iou_thres)
obb_test_jp5  |   File "/usr/local/lib/python3.8/dist-packages/torchvision/ops/boxes.py", line 41, in nms
obb_test_jp5  |     return torch.ops.torchvision.nms(boxes, scores, iou_threshold)
obb_test_jp5  |   File "/usr/local/lib/python3.8/dist-packages/torch/_ops.py", line 646, in __call__
obb_test_jp5  |     return self._op(*args, **kwargs or {})
obb_test_jp5  | RuntimeError: CUDA error: no kernel image is available for execution on the device
obb_test_jp5  | CUDA kernel errors might be asynchronously reported at some other API call, so the stacktrace below might be incorrect.
obb_test_jp5  | For debugging consider passing CUDA_LAUNCH_BLOCKING=1.
obb_test_jp5  | Compile with `TORCH_USE_CUDA_DSA` to enable device-side assertions.
obb_test_jp5  |
obb_test_jp5  | 2026-05-14 13:22:01,521 - INFO -
obb_test_jp5  | Execution complete.
obb_test_jp5  | 2026-05-14 13:22:01,524 - INFO -
obb_test_jp5  | ============================================================
obb_test_jp5  | 2026-05-14 13:22:01,526 - INFO - ✗ Test failed
obb_test_jp5  | 2026-05-14 13:22:01,529 - INFO - ============================================================
obb_test_jp5 exited with code 1
Export Device
This is a bit of info on where my ONNX files come from and what my PC environment looks like where I compiled them.
Yolo Checks on the ONNX Export Device
Ultralytics 8.4.48 🚀 Python-3.13.9 torch-2.11.0+cu130 CPU (AMD Ryzen 5 5600G with Radeon Graphics)
Setup complete ✅ (12 CPUs, 15.0 GB RAM, 744.1/878.1 GB disk)

OS                     Linux-6.17.0-23-generic-x86_64-with-glibc2.39
Environment            Linux
Python                 3.13.9
Install                git
Path                   /home/myuser/projects/myproject/.venv/lib/python3.13/site-packages/ultralytics
RAM                    15.01 GB
Disk                   744.1/878.1 GB
CPU                    AMD Ryzen 5 5600G with Radeon Graphics
CPU count              12
GPU                    None
GPU count              None
CUDA                   None

numpy                  ✅ 2.4.4>=1.23.0
matplotlib             ✅ 3.10.9>=3.3.0
opencv-python          ✅ 4.13.0.92>=4.6.0
pillow                 ✅ 12.2.0>=7.1.2
pyyaml                 ✅ 6.0.3>=5.3.1
requests               ✅ 2.33.1>=2.23.0
scipy                  ✅ 1.17.1>=1.4.1
torch                  ✅ 2.11.0>=1.8.0
torch                  ✅ 2.11.0!=2.4.0,>=1.8.0; sys_platform == "win32"
torchvision            ✅ 0.26.0>=0.9.0
psutil                 ✅ 7.2.2>=5.8.0
polars                 ✅ 1.40.1>=0.20.0
ultralytics-thop       ✅ 2.0.19>=2.0.18
Export Code
from ultralytics import YOLO

# 1. Load the model weights
model_path = "my-yolo26m-model.pt"
model = YOLO(model_path)

# 2. Export the model
# Configured for OBB (Oriented Bounding Boxes) and legacy TensorRT compatibility
success = model.export(
    format="onnx",
    imgsz=1024,      # Target resolution
    opset=13,       # ONNX operator set version, also tried 12
    simplify=True,   # I hoped this would help
    task="obb",
    half=False,      # I tried this with True and False
    end2end=False    # For legacy TensorRT support...?
)

print(f"Export successful: {success}")
YOLO26m-obb summary (fused): 175 layers, 23,443,236 parameters, 0 gradients, 71.5 GFLOPs PyTorch: starting from 'my-yolo26m-model.pt' with input shape (1, 3, 1024, 1024) BCHW and output shape(s) (1, 6, 21504) (90.8 MB) ONNX: starting export with onnx 1.21.0 opset 13... ONNX: slimming with onnxslim 0.1.93... ONNX: export success ✅ 2.5s, saved as 'my-yolo26m-model.onnx' (81.3 MB) Export complete (4.3s)Old Container
Jut in case it is relevant, this is the yolo checks of my self-made container which is based on l4t-ml.
root@xaviernx-desktop:/app# yolo checks WARNING ⚠️ user config directory '/root/.config/Ultralytics' is not writable, using '/tmp/Ultralytics'. Set YOLO_CONFIG_DIR to override. Creating new Ultralytics Settings v0.0.6 file ✅ View Ultralytics Settings with 'yolo settings' or at '/tmp/Ultralytics/settings.json' Update Settings with 'yolo settings key=value', i.e. 'yolo settings runs_dir=path/to/dir'. For help see https://docs.ultralytics.com/quickstart/#ultralytics-settings. Ultralytics 8.4.49 🚀 Python-3.8.10 torch-2.0.0+nv23.05 CUDA:0 (Xavier, 6833MiB) Setup complete ✅ (2 CPUs, 6.7 GB RAM, 84.9/107.6 GB disk) OS Linux-5.10.216-tegra-aarch64-with-glibc2.29 Environment Docker Python 3.8.10 Install pip Path /usr/local/lib/python3.8/dist-packages/ultralytics RAM 6.67 GB Disk 84.9/107.6 GB CPU ARMv8 Processor rev 0 (v8l) CPU count 2 GPU Xavier, 6833MiB GPU count 1 CUDA 11.4 numpy ✅ 1.23.5>=1.23.0 matplotlib ✅ 3.7.5>=3.3.0 opencv-python ❌ (not installed)>=4.6.0 pillow ✅ 10.2.0>=7.1.2 pyyaml ✅ 5.3.1>=5.3.1 requests ✅ 2.32.4>=2.23.0 scipy ✅ 1.10.1>=1.4.1 torch ✅ 2.0.0+nv23.5>=1.8.0 torch ✅ 2.0.0+nv23.5!=2.4.0,>=1.8.0; sys_platform == "win32" torchvision ✅ 0.15.1a0+42759b1>=0.9.0 psutil ✅ 5.9.6>=5.8.0 polars ❌ (not installed)>=0.20.0 ultralytics-thop ❌ (not installed)>=2.0.18 Murat Raimbekov
Thanks for the detailed MRE. I reproduced the numpy failure end-to-end with
torch.save/torch.loadand have a verified fix. There are two independent issues here.1.
numpy._core/ "requires numpy>=1.26.1" — root cause and fixYour
.ptwas saved on your PC with numpy 2.x / Python 3.13, so the checkpoint pickle embeds the numpy-2numpy._coremodule path. JetPack 5 on Xavier NX runs Python 3.8, whose maximum numpy is 1.24.x, and Xavier cannot move to JetPack 6 (Orin-only). I verified that even numpy 1.26.x does not fully read such a checkpoint, so "upgrade numpy" is not a real option on JP5.The reliable fix is a small compatibility shim that aliases
numpy._coreto the legacynumpy.core, injected before the model is loaded. I confirmed this loads a numpy-2torch.savecheckpoint correctly under numpy 1.23.5 with the model and all fields intact. Put this at the very top of yourmain.py, beforefrom ultralytics import YOLO:import sys, numpy, numpy.core sys.modules["numpy._core"] = numpy.core for _s in ("multiarray", "numeric", "umath", "_multiarray_umath"): try: sys.modules[f"numpy._core.{_s}"] = __import__(f"numpy.core.{_s}", fromlist=[_s]) except Exception: passAlternatively, fix the checkpoint once on the PC (where numpy 2.x can read it) so the device never needs the shim — load it and re-save it after converting the auxiliary numpy fields, then copy the new
.ptto the Jetson.2. Empty boxes /
CUDA error: no kernel image is available for execution on the deviceThese are separate from numpy:
- The
trtexec-built engine produces no detections because a rawtrtexecengine carries none of the Ultralytics export metadata, so the OBB decoding/post-processing is never applied. Build the engine on the Jetson with Ultralytics directly from the.pt(after applying the shim above) so metadata is embedded:YOLO("model.pt").export(format="engine", imgsz=1024, half=True, device=0). no kernel image is availableis raised insidetorchvision.ops.nmson the GPU: the PyTorch/torchvision inultralytics/ultralytics:latest-jetson-jetpack5is built for Orin (SM 8.7), while Xavier NX is SM 7.2. That is exactly why YOLO11 OBB works in your older l4t-ml-based container (torch 2.0.0+nv23.5) but the official image fails. Recommended path: stay on the container that already works on your Xavier,pip install ultralytics opencv-python-headlessthere, and run the Ultralyticsexport(format="engine")+val()entirely on-device.
TL;DR: the numpy error is a pickle module-path mismatch from the numpy-2 export PC (fix with the shim above — verified), and the empty/CUDA errors are a raw-
trtexecmetadata loss plus a torch/torchvision build that doesn't target Xavier's SM 7.2.1- The
Hi there, thank you for the help! I just recently got around to trying out the shim and now everything works just fine, thank you for your help!
How to run deepstream for YOLO26 models in my jetson orin nano developer kit?
Is there any documentation for deepstream on jetson? I don't want any installation errors of version missmatch.
So give me any perfect guide link so that I will not miss anything while installation and run inference on live RTSP streams
githubwalt(수정됨)
Here you go: https://docs.ultralytics.com/guides/deepstream-nvidia-jetson/
Have a look in jtop (info) for your board compute capability (CUDA Arch BIN). If it's also 8.7, then see my posts here above to avoid problems with torch.
- Glenn JocherUltralytics
Adding one detail for
Jetson Orin Nano: keep the versions paired asJetPack 6.1+DeepStream 7.1from the Jetson quick-start and NVIDIA DeepStream getting started; for live RTSP, set theuriindeepstream_app_config.txtto your stream, and if you hit any mismatch please post the full text traceback plusyolo checksoutput here so the team can help. Thanks for your reply. Just onemore doubt to clear. docker pull nvcr.io/nvidia/deepstream:7.1-triton-multiarch
if I use above docker container for my jetpack6.1 so it there is no issue of version missmatch of deepstream right?
is it works very well with Yolo26 deepstream settings which is showing in this doc? https://docs.ultralytics.com/guides/deepstream-nvidia-jetson/
what is your recommendation to run Multiple RTSP streams with deepstream with docker containers or without docker containers manual installation?
- Glenn JocherUltralytics
Yes,
nvcr.io/nvidia/deepstream:7.1-triton-multiarchis the correct DeepStream 7.1 Jetson container forJetPack 6.1, but it still depends on the host having the JetPack BSP and NVIDIA container runtime installed, so it lowers mismatch risk rather than removing it completely; for YOLO26 + RTSP, the DeepStream multi-stream section is the right reference, and I’d suggest native setup first since that’s the install path used in the guide, then move to Docker once your pipeline is stable. (docs.ultralytics.com) Thanks. For native setup Is it good to install deepstream 7.1 while installing jetpack6.1 only?
- Glenn JocherUltralytics
Yes—on
Jetson Orin Nanonative setup,JetPack 6.1+DeepStream 7.1is the correct pairing; installJetPack 6.1first, boot and verify the system, then installDeepStream 7.1separately using the versions listed in the Jetson + YOLO26 guide and the DeepStream on Jetson guide to avoid mismatches.
Installing torch 2.11.0 from the official website pytorch.org on an AGX Orin 64Gb (dev kit) with JP6.2.2 or installing torch 2.10.0 and torchvision 0.25.0 following this page, give complaints about not being compatible with the Compute Capability (CC) of my machine which has 8.7, whatever that means. Only installing the previous versions torch 2.8.0 and torchvision 0.23.0 do work.
I understand that torch needs to be tailored specifically for the Jetson family and that is what this page is all about, so why do I have this issue if I follow the instructions given here? Is it because I am on Jetpack 6.2.2 and here it's 6.1?
I forgot the warning and error output when running a python test script:
UserWarning: Found GPU0 Orin which is of compute capability (CC) 8.7.The following list shows the CCs this version of PyTorch was built for and the hardware CCs it supports:- 8.0 which supports hardware CC >=8.0,<9.0 except {8.7}- 9.0 which supports hardware CC >=9.0,<10.0
torch.AcceleratorError CUDA error: no kernel image is available for execution on the device
- Glenn JocherUltralytics
Thanks, that traceback helps —
CC 8.7is the AGX Orin GPU architecture, andno kernel image is availablemeans the installed PyTorch wheel was built withoutsm_87support. So yes, this is most likely a JetPack/PyTorch wheel mismatch: the native steps in the JetPack 6.1 section don’t necessarily map cleanly toJP6.2.2, even though the page includesJP6.2benchmark coverage. For now I’d stick with the workingtorch 2.8.0+torchvision 0.23.0pair or use the JetPack 6 Docker setup; if you want us to check your exact environment, please postyolo checksand the full text traceback here in the discussion. Thanks, will stick to 2.8 🙂 👍 (I also posted on the guide page https://docs.ultralytics.com/guides/nvidia-jetson/#what-are-the-best-practices-for-maximizing-performance-on-nvidia-jetson-when-using-yolo26 , so you could ignore that if you like, can't delete my post there 😏 )
- Glenn JocherUltralytics
No worries — the duplicate is fine, and if you later confirm a stable
JP6.2.2+ PyTorch pairing on AGX Orin, please add it here so we can reflect it in the Jetson guide. Will do. Now trying to get the most out of the AGX. Experimenting with number of workers on a batch size of 16. So far 12 workers gave memory issues ... I chose 12 because of 12 cores, but that was a little too much. Now running with 8 workers ... so far so good. To be continued 🙂
Hi Glenn, I can confirm a stable JP6.2.2 + Pytorch (torch 2.8.0 and torchvision 0.23.0) on the AGX Orin.