Azure Blob Storage Integration
The Azure Blob Storage integration connects your storage account containers to Ultralytics Platform. Your images stay in your containers — Platform indexes them in place, so you can browse, annotate, and train YOLO models without uploading a copy. With AI features on, Platform can also use them for smart annotation, auto-annotation, similar-image search, and cloud training.
Azure Blob Storage datasets require a Pro or Enterprise plan. Free workspaces see the integration and are prompted to upgrade when connecting. Existing Azure Blob Storage datasets stay fully accessible if a subscription ends — only new connections and imports require Pro.
Get a Connection String#
Platform reads your blobs, and creates new ones only for image generation; it never modifies or deletes them. The current integration requires an account access-key connection string, which grants account-wide privileges:
- In the Azure portal, open your storage account.
- Go to Security + networking > Access keys.
- Copy a connection string.
The string must carry AccountName, AccountKey, and HTTPS as its protocol — the form Azure gives you under Access
keys. SAS-token connection strings, which contain SharedAccessSignature instead of AccountKey, are rejected.
Connections use the standard blob.core.windows.net endpoint. Sovereign clouds (Azure China, Azure Government) and custom blob endpoints are not supported.
Connect to Platform#
- Go to Settings > Integrations and select Azure Blob Storage from the integration list.
- Paste the connection string.
- Click Find available containers, then select the containers to connect. You can also enter a container name manually.
- Click Connect. Platform verifies it can list and read each selected container before saving anything. Account keys can always create blobs, so containers connected or reconnected since image generation launched can be written to.
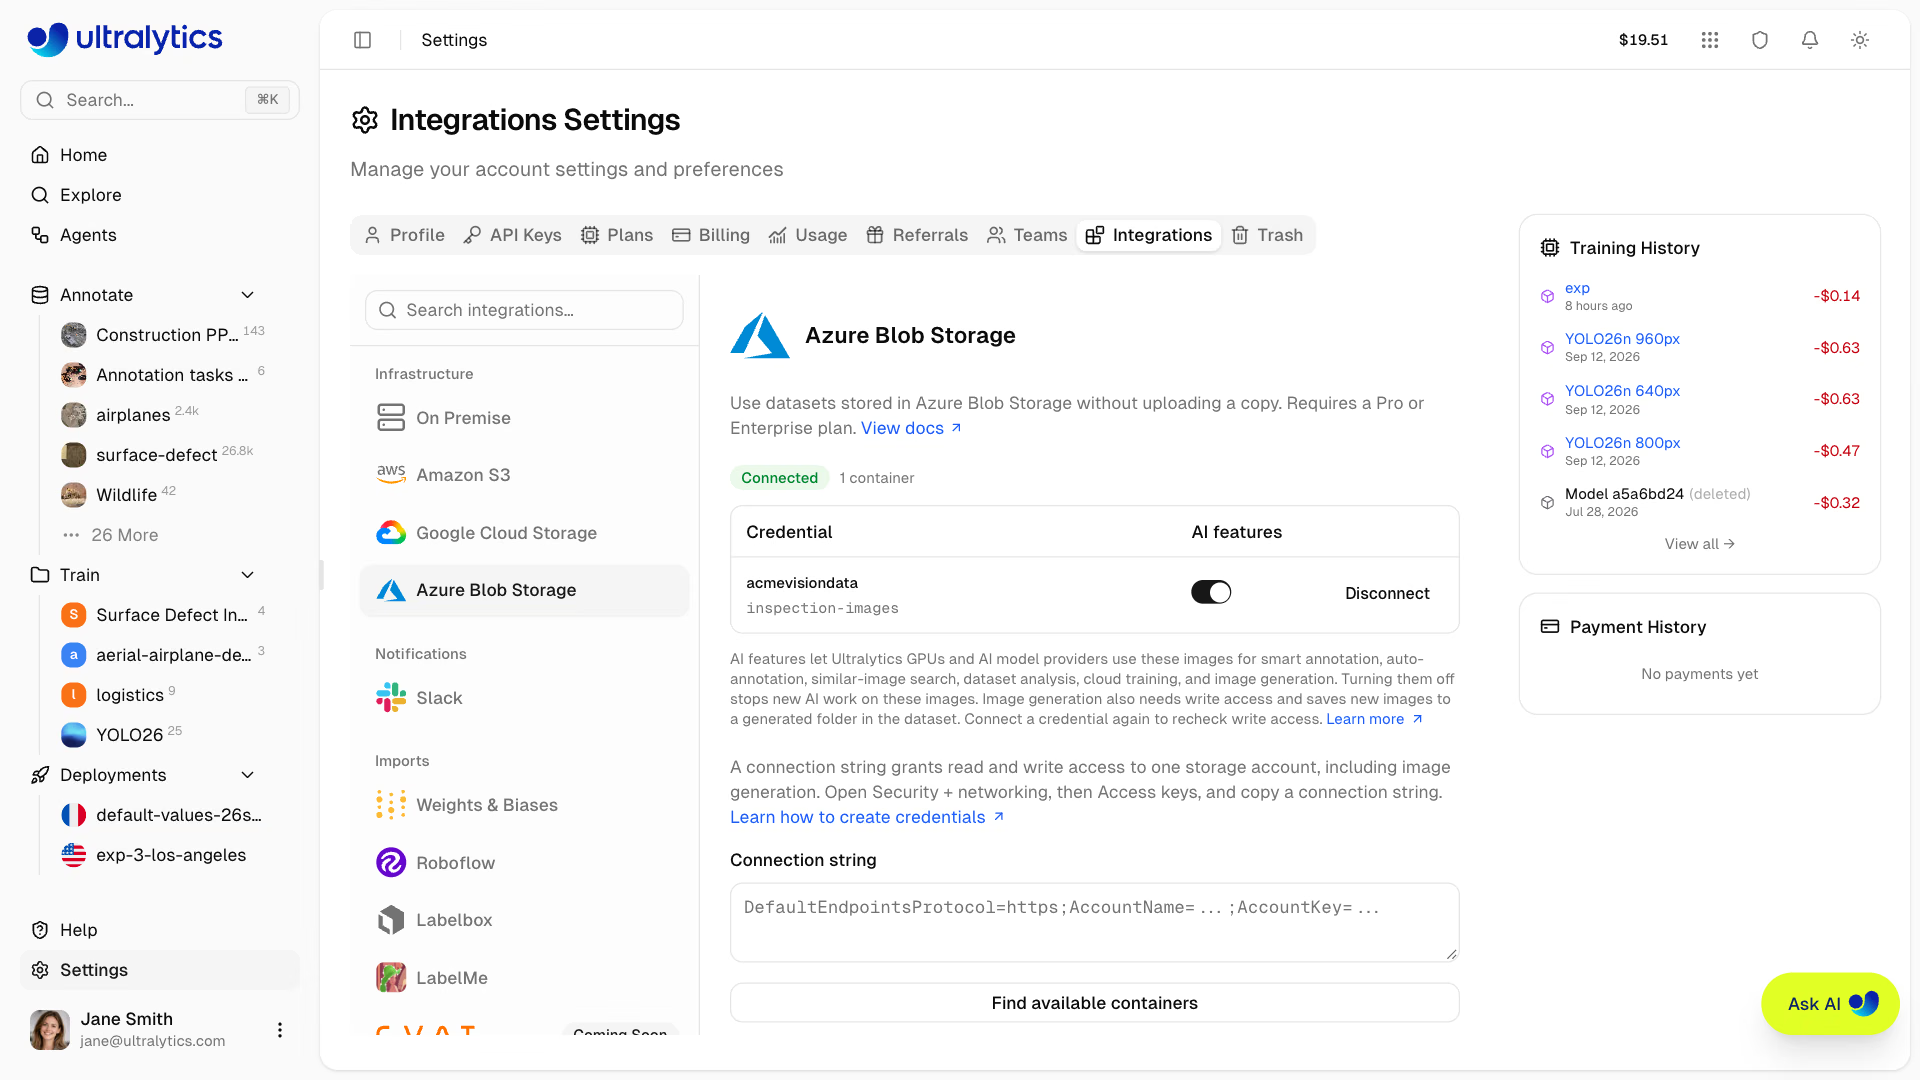
Each connected credential has an AI features switch.
You need the workspace admin or owner role to connect cloud storage. You can add up to 50 containers at a time, and discovery lists up to 300 containers in the storage account.
Reconnecting the same storage account later adds new containers to the existing integration. A saved credential is only replaced once its replacement can still read every container you've already connected. If any container can't be read, the error names it, including containers connected earlier with the same storage account.
An account key can authorize write and delete operations or create SAS tokens if it is exposed outside Platform. Credentials are encrypted at rest with AES-256-GCM, are never returned to the browser, and are never exposed to training workloads. Use a dedicated storage account where practical. To revoke access, rotate the storage account access keys in Azure.
AI Features#
Each connected credential has an AI features switch in Settings > Integrations, on by default. While it's on, Ultralytics GPUs and AI model providers may use that credential's images for:
- SAM smart annotation, and single-image and batch auto-annotation
- Similar-image search and clustering analysis
- Cloud training
- Image generation, on containers with write access
AI model providers are involved only for image generation, whose prompts Google Gemini plans from the source image, and for paid annotation models, which run on your workspace's own provider key. Platform keeps no copy of your images: features read them on demand, cloud training uses temporary copies for the duration of a run, and similar-image search keeps an embedding of each image, which is deleted when the image leaves Platform.
Turn the switch off to keep images off Ultralytics GPUs and AI model providers. Turning it off stops new AI work; work already running finishes. Datasets on that credential then show AI features off with a link back to these settings, and each unavailable feature explains why. Manual annotation, sharing, and local training keep working, and the labels, models, and search results you already created are kept.
You need the workspace admin or owner role to change the switch. You can also set it with the REST API, using the integration ID returned by GET /api/integrations/buckets:
curl -X PATCH \
  -H "Authorization: Bearer YOUR_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"processing": false}' \
  https://platform.ultralytics.com/api/integrations/buckets/INTEGRATION_ID
Image Generation#
Generate similar images works on Azure Blob Storage datasets while AI features are on. Images you add are written to a generated/ folder inside the dataset's folder, then added to the dataset like any other indexed image. Platform only creates new blobs there and never overwrites or deletes existing ones. If the action says it needs write access, connect the same storage account again in Settings > Integrations.
Create a Dataset from a Blob Container#
- Click New Dataset and open the Cloud tab.
- Pick a connected container and browse to the folder containing your data.
- Confirm the folder, adjust the dataset name, and create the dataset.
Platform lists the folder once and indexes what it finds:
- Images —
.jpg,.jpeg,.png,.webp, and.avifblobs are indexed with dimensions read through bounded requests. Platform does not persist a second copy of the source image. - Labels — YOLO
.txtsidecars are parsed into Platform annotations, matched by the standardimages/→labels/layout or as same-folder siblings. - Metadata — a YAML file provides class names and pose keypoint shape, exactly like an archive upload.
data.yamlanddata.ymlare preferred when the folder holds several. - Task — a sample of the label files decides the task, so segment, pose, and OBB folders are recognized from their label shape rather than the task you picked in the dialog.
- Splits —
train,val, andtestfolder names in the blob path assign splits automatically.
The dataset then behaves like any other: browse and annotate it, set it public or private, share it with your team, and train on it through managed training. Originals are streamed on demand, and indexed images do not consume your Platform storage quota.
A single import indexes up to 500,000 blobs, and label or YAML files up to 1 MB each. Larger containers should be split across multiple datasets.
Every indexed image is pinned to its blob ETag, and Platform fails closed if a blob changes underneath it. Add new blobs instead of overwriting existing ones.
Failed Imports#
If an import fails — an empty folder, a typo in the path, or revoked permissions — the dataset shows the error on its page. Editors can click Retry import to restart it with the stored container and folder, or create a new dataset pointing at the corrected path.
A retry re-lists the folder rather than resuming: blobs added since the first attempt are picked up, and blobs that are no longer there are dropped from the dataset.
Training#
Managed training works through the normal training flow while AI features are on. Training uses Platform's own copies of the pinned images for the duration of the run, and your Azure credentials are never exposed to training workloads. With AI features off, the training dialog explains why cloud training is unavailable and offers local training instead.
Disconnect a Connection#
Disconnecting deletes the stored connection string without touching anything in Azure. Datasets built from those containers stay in your workspace with their classes, labels, and annotations, but their images cannot be loaded, previewed, or trained on until the same storage account is connected again. You can still rename them, edit their labels, or delete them while disconnected.
To disconnect, go to Settings > Integrations, select Azure Blob Storage, click Disconnect next to the credential, and confirm. Opening one of its datasets then shows Azure Blob Storage Disconnected with a link back to these settings, and the dataset returns automatically once you reconnect.
You can also disconnect with the REST API, using the integration ID returned by GET /api/integrations/buckets:
curl -X DELETE \
  -H "Authorization: Bearer YOUR_API_KEY" \
  https://platform.ultralytics.com/api/integrations/buckets/INTEGRATION_ID
from ultralytics_platform import Platform
client = Platform() # reads ULTRALYTICS_API_KEY
integrations = client.storage_integrations.list()
client.storage_integrations.delete("INTEGRATION_ID")To revoke access at the source instead, rotate the storage account access keys in Azure.
Current Limitations#
Azure-backed datasets exclude features that need Platform-owned copies of your images: dataset cloning, immutable version snapshots, face blurring, and pasting images from other datasets. Smart annotation, auto-annotation, similar-image search, clustering, cloud training, and image generation need AI features on.
Deleting an Azure-backed dataset, or individual images from it, removes Platform's references only — your blobs are never touched.
Also see the Google Cloud Storage and Amazon S3 integrations.
FAQ#
No. Platform lists the container once and indexes the image dimensions and labels it finds. Originals are streamed on demand for browsing and annotation. With AI features on, Ultralytics GPUs read them on demand, managed training uses temporary copies for the duration of a run, and similar-image search keeps an embedding of each image, which is deleted with the image. The only blobs Platform ever writes are the generated images you add, under
generated/. Indexed images do not count against your storage quota.A dataset is indexed once when it is created. New blobs are not picked up until you create a new dataset or retry a failed import, and every indexed image is pinned to its version, so overwriting a blob makes Platform fail closed on that image. Add new blobs instead of replacing existing ones.
Only for image generation, and only while AI features are on. Platform creates new blobs under
generated/in the dataset's folder and never overwrites or deletes existing ones.Disconnect the integration in Settings > Integrations to delete the stored credentials, or rotate the storage account access keys in Azure. Neither action touches the data in your containers. To keep images off Ultralytics GPUs without disconnecting, turn off AI features.


Comments
Ask a question, share your results, or help someone else.